Using temporary credentials is a security best practice to reduce the risk from credentials getting compromised. With AWS IAM Roles Anywhere, now your workloads outside of Amazon Web Services (AWS) will be able to access AWS resources by obtaining temporary security credentials in AWS Identity and Access Management (IAM). IAM Roles Anywhere relies on public key infrastructure (PKI) to establish trust between your AWS account and certificate authorities that issues certificates to your workloads that run outside AWS. PKI involves the generation, distribution, and verification of digital certificates through public key encryption.
In this post, we show you some best practices, considerations, and solutions for integrating your PKI with IAM Roles Anywhere. In this post, we assume that you have a foundational knowledge of IAM and IAM Roles Anywhere. For more information, see the IAM and IAM Roles Anywhere documentation.
Note: As of July 2026, AWS Certificate Manager (ACM) supports exportable public certificates that can be used on workloads outside AWS (containers or on-premises). Additionally, ACM supports the ACME protocol for automated certificate issuance and renewal on external workloads. These capabilities complement IAM Roles Anywhere by providing both identity (using X.509 certificates for IAM Roles Anywhere) and encryption (using ACM public/private certificates) for hybrid environments.
X.509 certificates for workload identity
If you’re running multiple workloads in your infrastructure, you’re probably assigning unique workload identities and specific user permissions. In this environment, your workloads can use PKI tools like Active Directory Certificate Services to centrally manage and monitor the identities and permissions at scale. The same principles of segregating unrelated workloads apply to PKI and IAM Roles Anywhere. If you’re issuing certificates to your workloads today, they can probably be used with IAM Roles Anywhere without any changes.
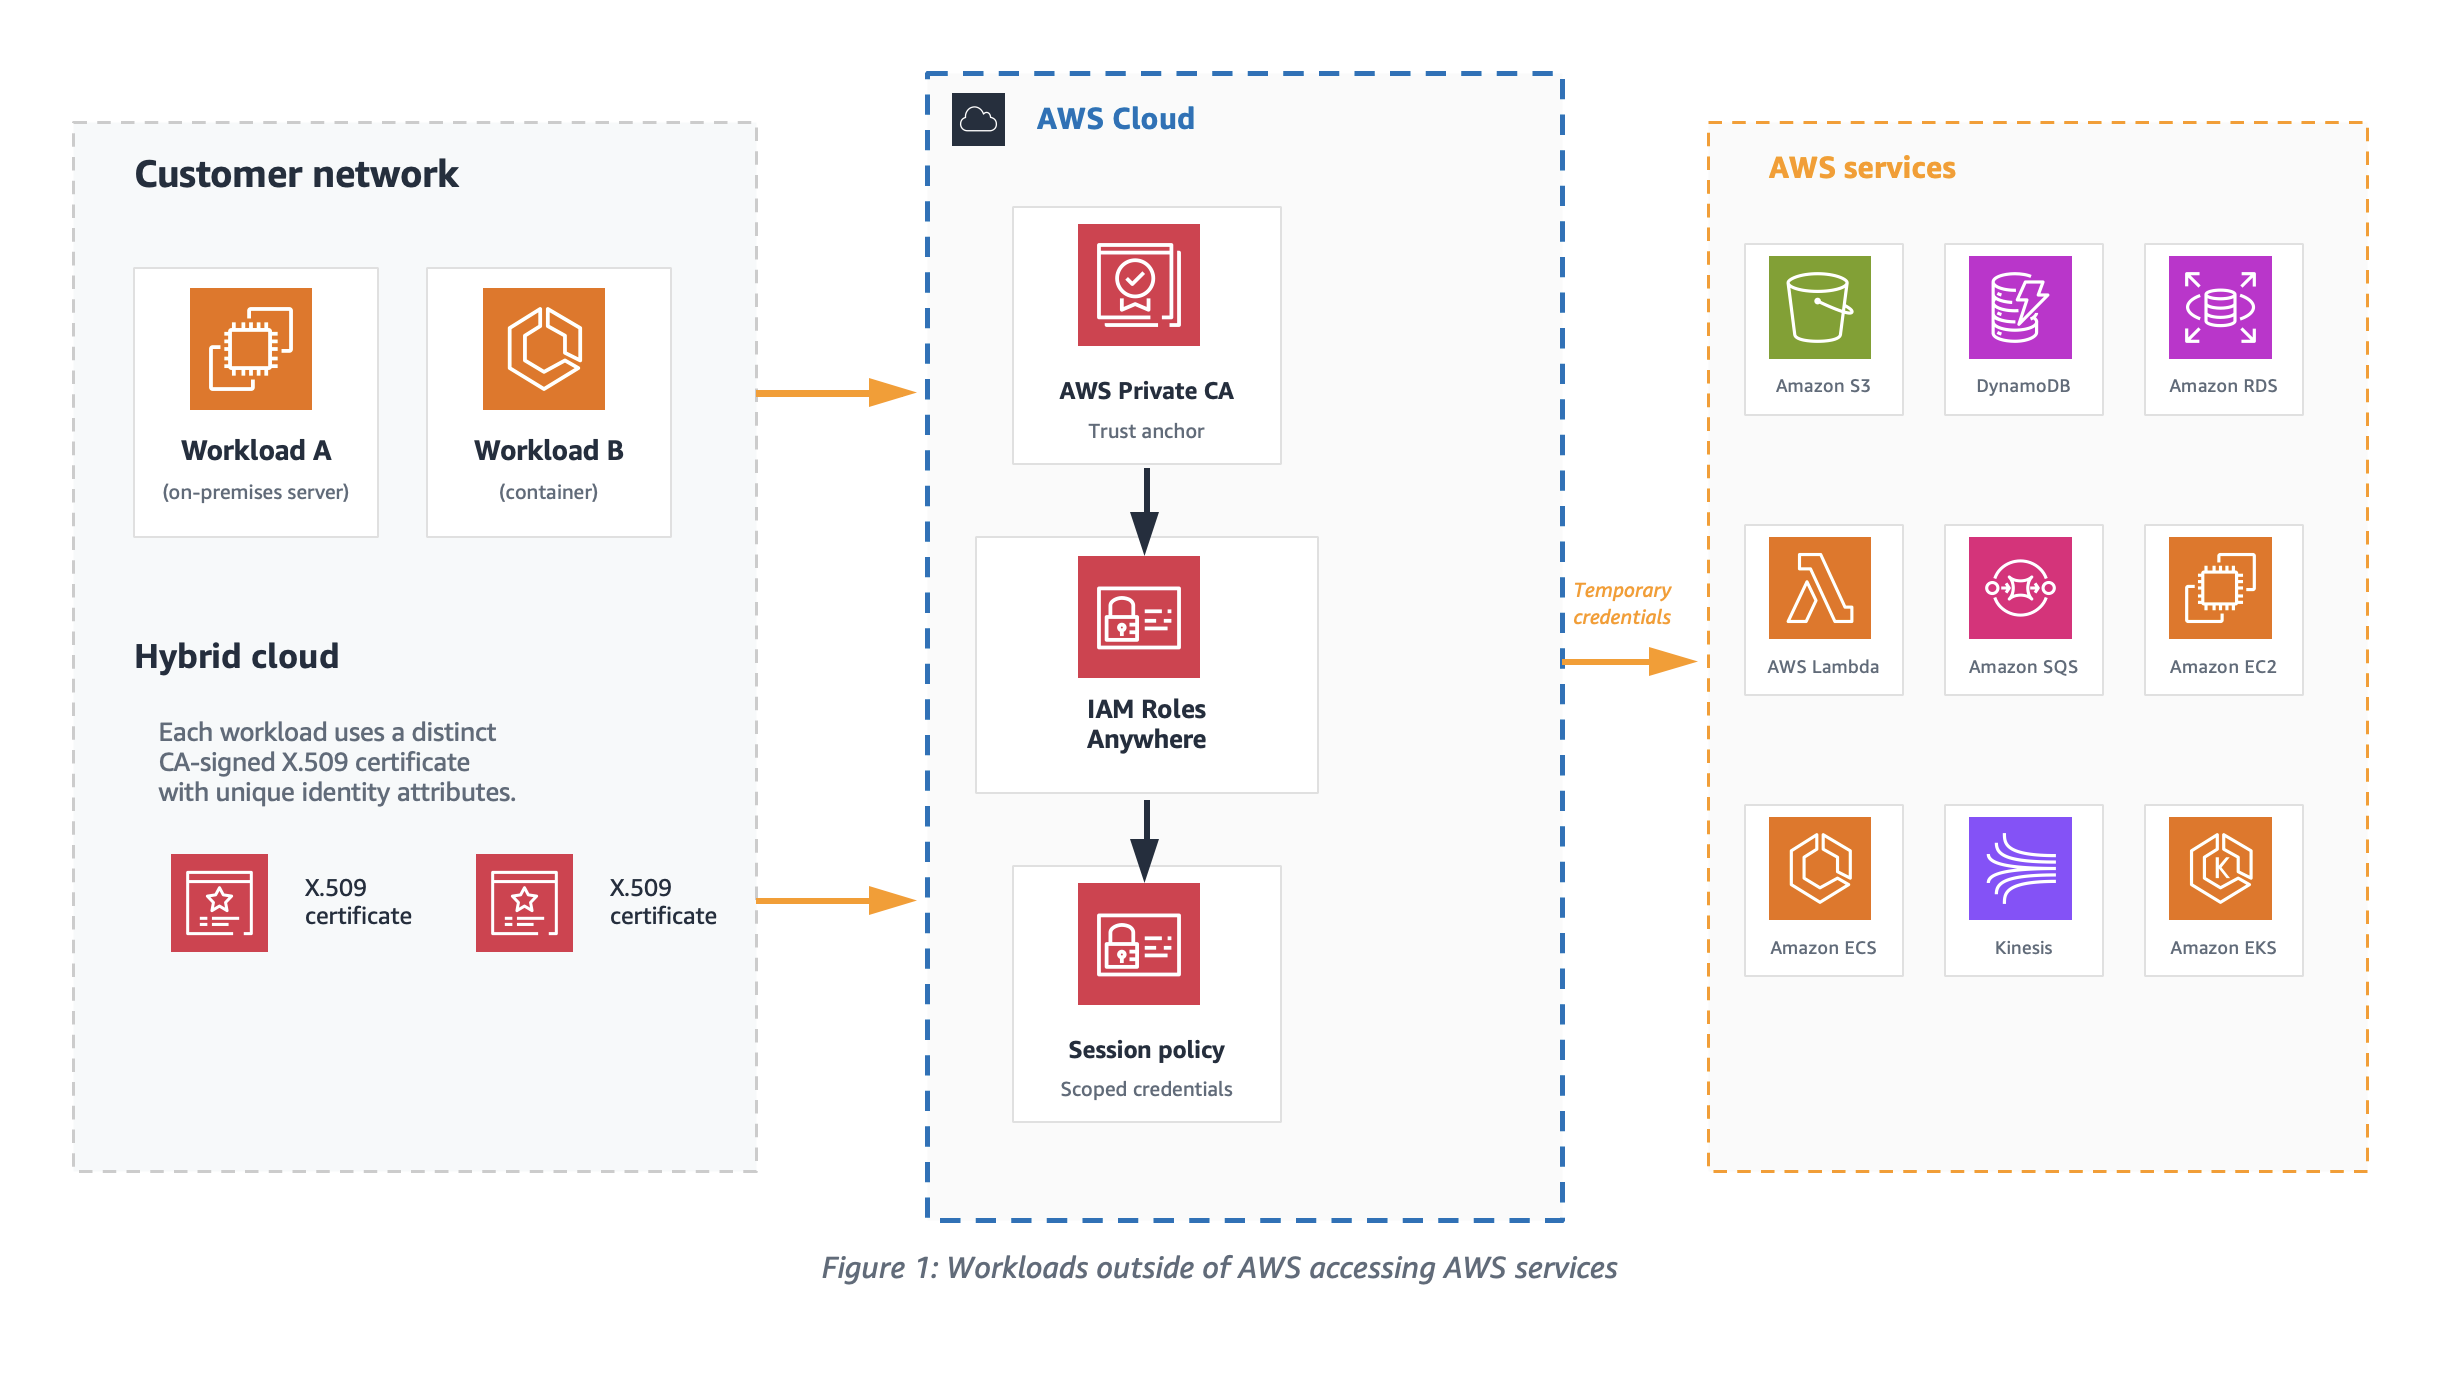
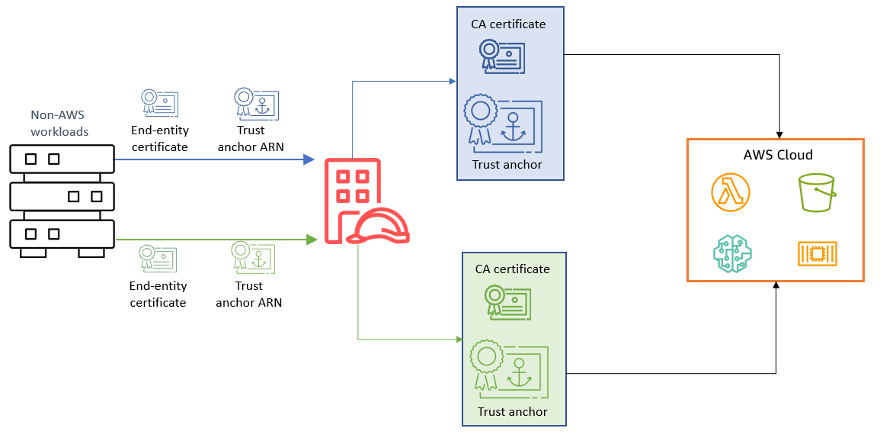
As shown in Figure 1, the access boundary and permissions of Workload A can be very different from that of Workload B when accessing AWS resources, depending on the organization’s needs. In such scenarios, it’s recommended to establish a unique machine identity for each workload. This can be achieved by issuing a separate X.509 certificate with distinct identity attributes signed by your certificate authority (CA). To set up an effective PKI solution for machine identities, you must configure the appropriate certificate attributes and anchor the trust model around those attributes.
Figure 1: Workloads outside of AWS accessing AWS services
Temporary access credentials
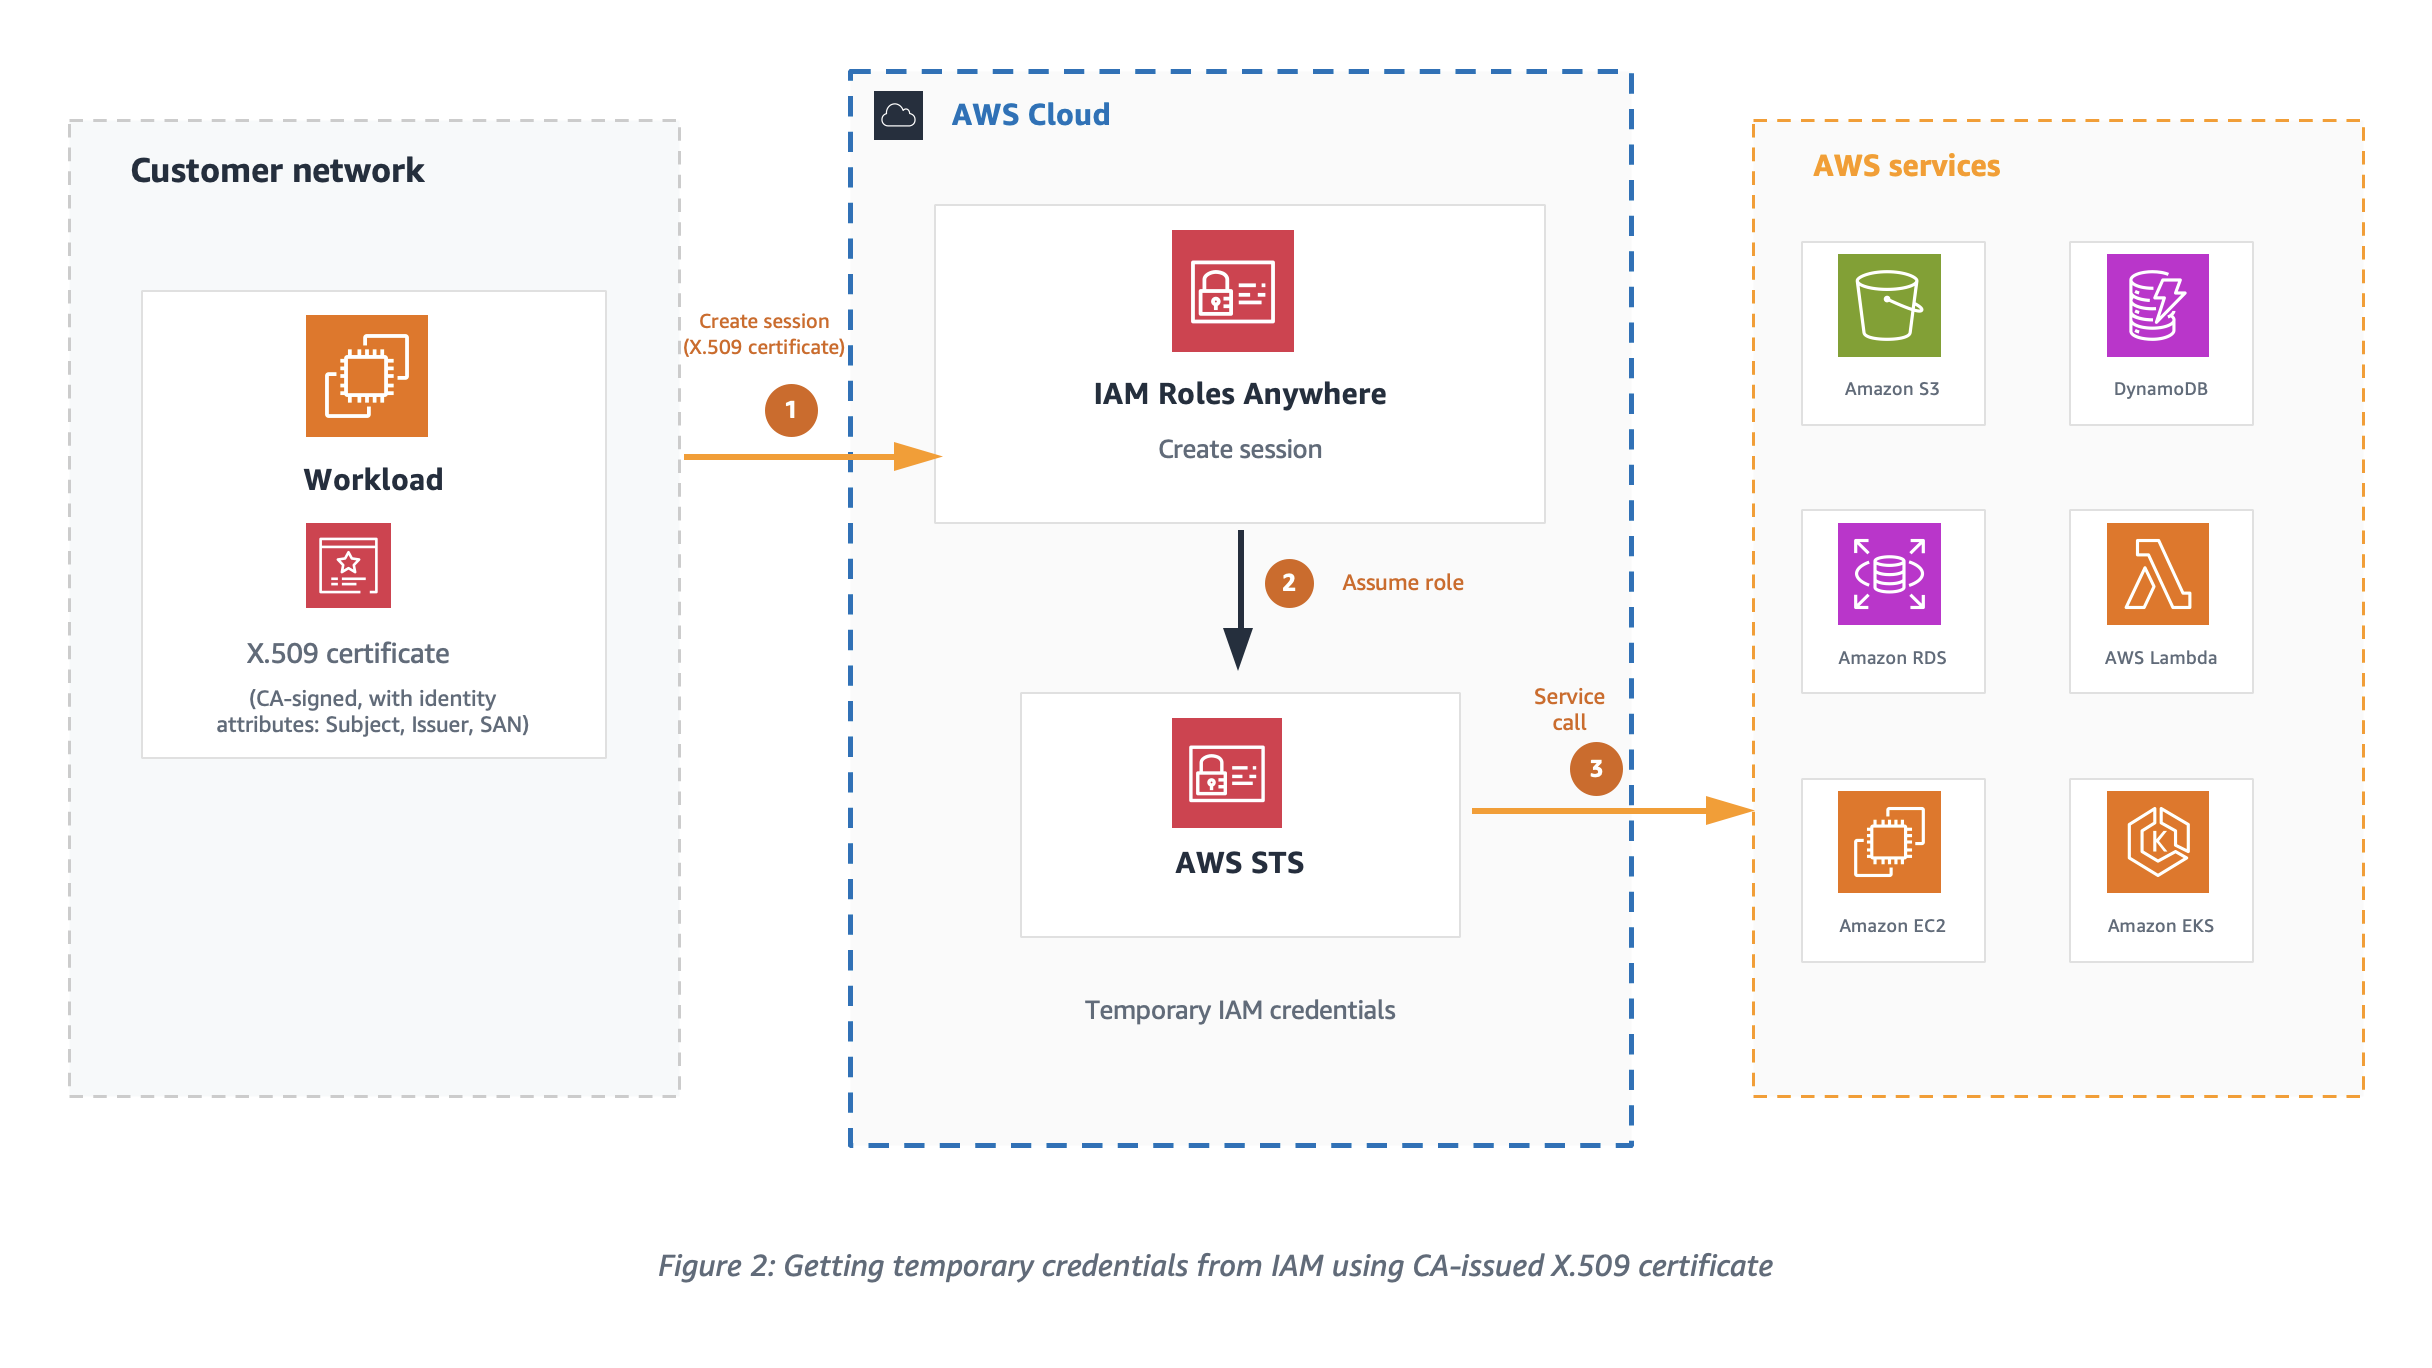
Workloads with distinct CA signed X.509 certificates exchange certificates with IAM, as shown in Figure 2, to get temporary security credentials for the session. The signature validation process used by IAM Roles Anywhere verifies the certificate issuer and the subject before providing the temporary credentials. To enable this verification process, an IAM Roles Anywhere trust model should be set up by either uploading your CA’s digital certificate as a trust anchor or by referencing an existing AWS Private Certificate Authority (AWS Private CA) certificate. In this post, we focus on using a trust anchor.
To help define the appropriate scope for the temporary credentials, it’s recommended to configure distinct IAM roles for each workload to assume. Workloads must use X.509 certificates issued by your CA. These certificates are exchanged with IAM to get temporary security credentials for the session.
Figure 2: Getting temporary credentials from IAM using CA issued X.509 certificate
Set up IAM roles with the IAM Roles Anywhere trust policy that will be assumed by your non-AWS workload.
Configure profiles with IAM roles and attach relevant session policies. This instructs IAM Roles Anywhere to use your selected session policies whenever you request credentials for any of the attached roles.
Trust model
The trust model is centered around setting up the right trust relationship between IAM Roles Anywhere and your CA by configuring a trust anchor. The model connects the role, the IAM Roles Anywhere service principal, and identities encoded in X509 certificates that are issued by a CA.
Certificate attributes
Certificates are a binary record with encoded key/value pairs as certificate attributes. Let’s look at one of the X.509 certificates to understand different attributes of certificate that are important for IAM Roles Anywhere PKI validation.
The following is an example PEM encoded certificate file that can be decoded with tools like openssl.
-----BEGIN CERTIFICATE-----
MIIKOzCCCSOgAwIBAgIQDlnyZvBeKjgHm1jJ++CbgDANBgkqhkiG9w0BAQsFADBE
MQswC ...........
-----END CERTIFICATE----


Certificate:
    Data:
        Version: 3 (0x2)
        Serial Number:
            e0:5d:b7:72:56:fa:75:e3
    Signature Algorithm: ecdsa-with-SHA512
        Issuer: C=US, ST=CA, L=San Francisco, O=MyCompany Inc., OU=AC, CN=MyCompany CA
        Validity
            Not Before: Sep 15 00:09:17 2023 GMT
            Not After : Sep 18 00:09:17 2023 GMT
        Subject: C=US, O=MyCompany, OU=eCommerce, CN=WorkloadA
        Subject Public Key Info:
            Public Key Algorithm: id-ecPublicKey
                Public-Key: (384 bit)
                pub:
                    04:3b:74:e1:68:06:fa:b0:3d:fe:f7:5f:74:80:05:
        X509v3 extensions:
            X509v3 Subject Alternative Name:
                DNS:ecommerce.mycompany.com, DNS:*ecommerce.mycompany.com, URI:spiffe://mycompany.com/workload/ecommerce
            X509v3 Basic Constraints: critical
                CA:FALSE
            X509v3 Key Usage: critical
                Digital Signature
    Signature Algorithm: ecdsa-with-SHA512
         30:64:02:30:19:a7:a0:33:49:ce:e1:cb:76:6e:c0:f3:c5:66:
IAM Roles Anywhere extracts values from the subject Common Name (CN), issuer, and Subject Alternative Name (SAN) fields of the authenticating certificate and makes them available for policy evaluation through the sts:sourceIdentity and principal tags. When configuring your PKI, set short validity periods on the certificates issued to workloads. Short-lived certificates limit the window of exposure if a certificate is compromised and reduce the need for active revocation.
Note: An empty Subject CN in a certificate isn’t supported by IAM Roles Anywhere.
Trust policy and effective permissions of credentials
IAM Roles Anywhere clients fetch temporary credentials for IAM Roles using the API method CreateSession. To successfully authorize this API call, the IAM role trust policy should trust the IAM Roles Anywhere service principal as shown in the following example.
As a security best practice, consider using additional condition statements to evaluate the session PrincipalTag attributes extracted from the certificate to further restrict authorization of temporary credentials. If the workloads have ephemeral certificates with a dynamic subject CN, then the issuer or SAN principal tags can be used to define condition statements in the trust policy. The trust anchor shown in the preceding trust policy helps establish the trust between IAM Roles Anywhere and the CA in your PKI.
Plan for trust anchor placement
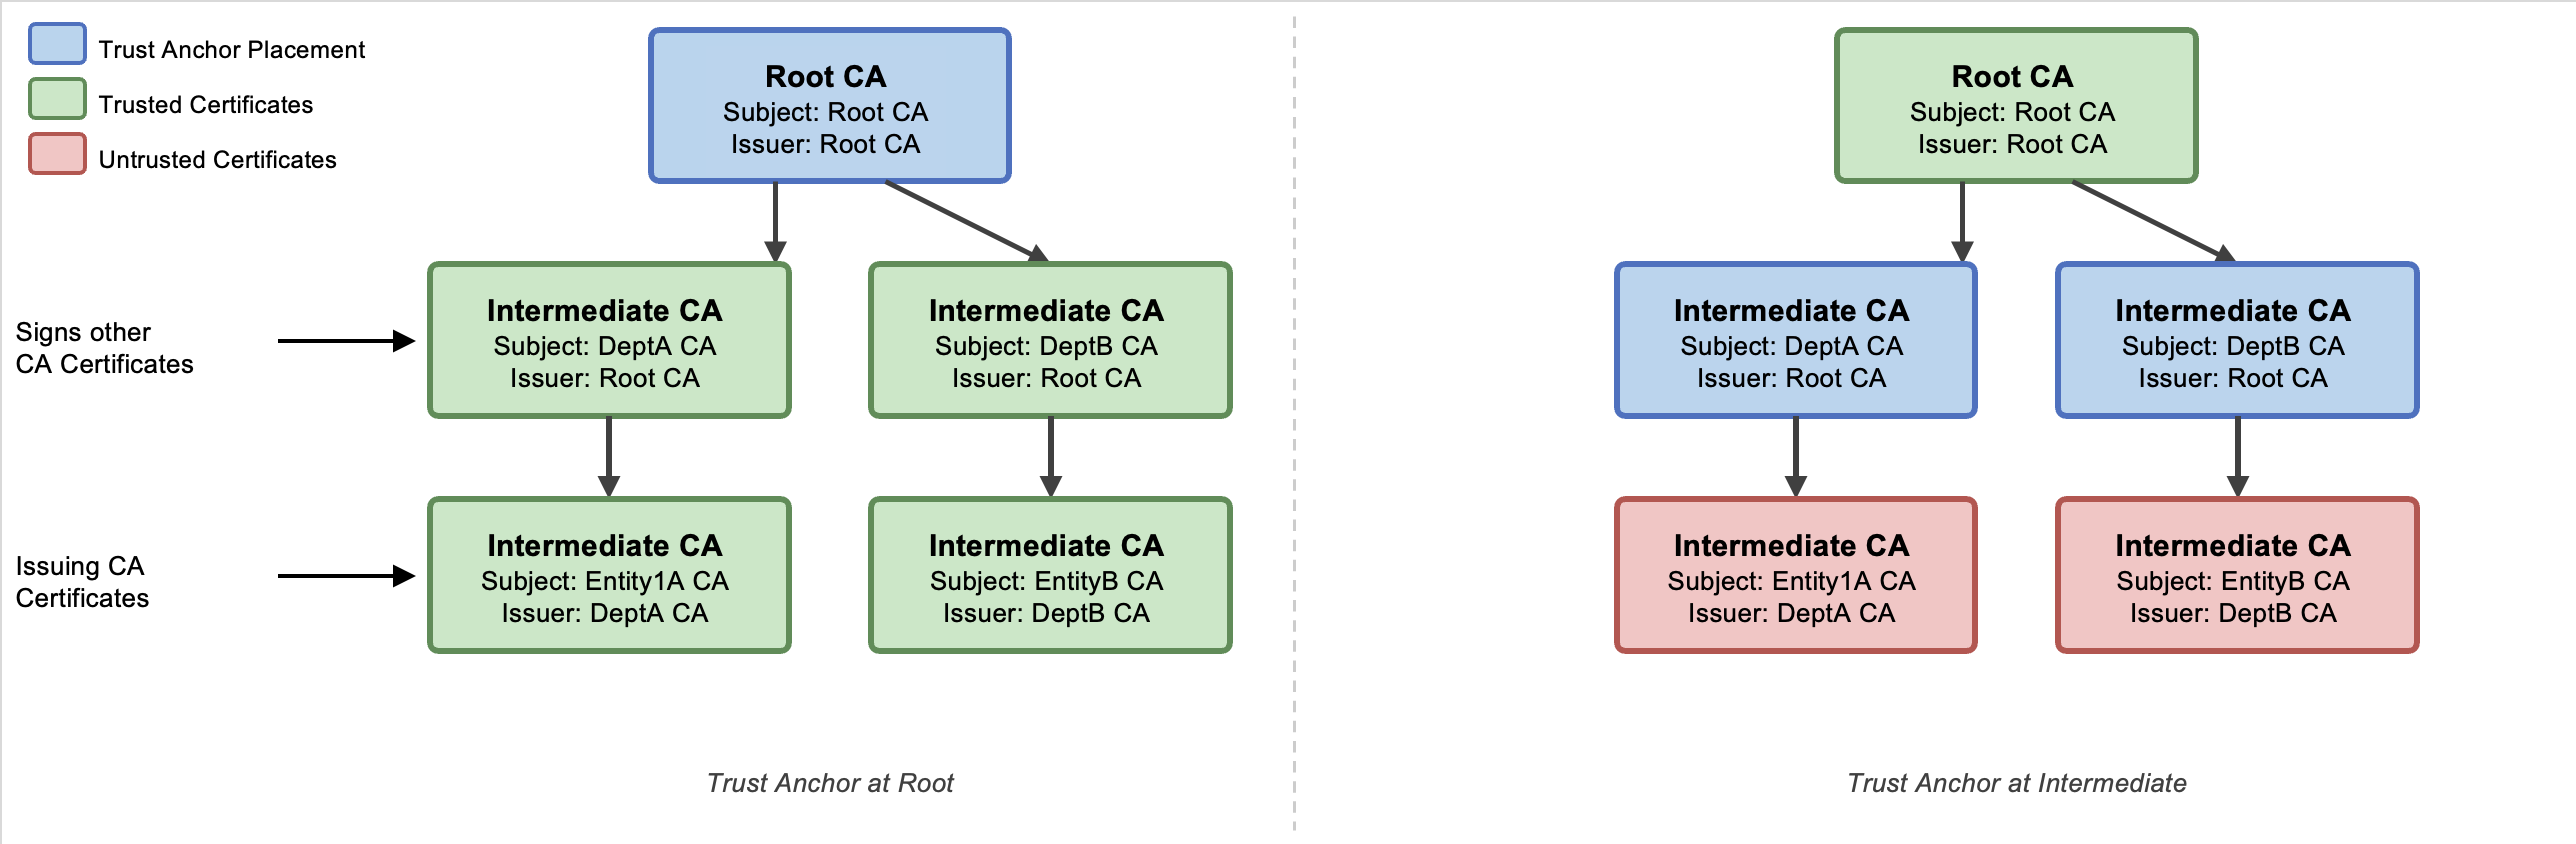
Depending on the CA platform, you can configure one or more intermediate certificates in your PKI certificate hierarchy, as shown in Figure 3. The certificate level the trust anchor is placed at affects which end-entity certificates IAM Roles Anywhere accepts, and therefore which workloads are authorized to assume a role. To create a trust anchor, export the certificate bundle for the issuing CA certificate from your external CA platform in PEM-encoded format and upload it to the trust anchor console.
Figure 3: Certificate hierarchy in an external PKI
See the Solution deployment section to onboard a sample solution and verify your certificate bundle.
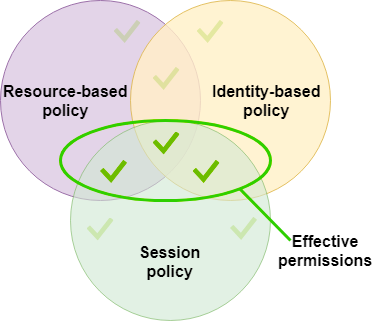
Fine-grained access control is vital for security because it allows organizations to precisely define and restrict permissions, minimizing the risk of unauthorized access and data breaches. The effective permissions of the temporary security credentials are an intersection of resource-based, identity-based, and session policies as shown in Figure 4. By setting up the trust anchor and profile configuration in IAM Roles Anywhere with session policies, you can limit the permissions for each session.
Figure 4: Effective permissions of session credentials
Credential helper
To obtain temporary security credentials from IAM Roles Anywhere, use the credential helper tool. This tool is compatible with the credential_process feature available across the AWS SDKs. The credential helper manages the process of obtaining temporary security credentials using IAM Roles Anywhere and returns them in JSON format. The private key of the workload and its CA signed certificate are the two critical parameters provided to the credential helper tool. To use this tool, you need both an end-entity certificate and a trust anchor created in IAM Roles Anywhere. As of December 2024, the credential helper (version 1.4.0 and later) supports Trusted Platform Module (TPM) 2.0.
The following is an example of how to obtain temporary security credentials:
When credential-process is used with AWS SDKs, the temporary credentials are stored in memory and refreshed automatically. However, the AWS Command Line Interface (AWS CLI) invokes credential-process on every command. Each invocation creates a new IAM Roles Anywhere session, which adds latency to every CLI call. To avoid this delay when using the AWS CLI, we recommend using the update command, which writes refreshed credentials to a file that the CLI reads on each invocation without calling credential-process again.
When you use update, credentials are written to a credential file on disk and any user or process who can read the credential file might be able to read and use those AWS credentials, so it’s recommended to use serve unless your business has a specific use case that needs to read AWS credentials from a file. The serve command can be used to vend temporary credentials through an endpoint running on the local host using the same URIs and request headers as Instance Metadata Service Version 2 (IMDSv2). When using serve, no AWS configuration files are needed because the AWS SDKs can discover the server endpoint.
Just-in-time compared to short-lived certificates as workload identities
To help mitigate the risk around the exposure of your business-critical resources to compromised certificate user sessions, it’s recommended to use certificates with just-in-time credentials or short-lived access credentials. Just-in-time certificates are issued by a CA for immediate use for authentication on a system or application. The CA uses the roles and policies defined in IAM to determine when, and under what conditions, a workload can establish a session. With just-in-time access, admins don’t have to worry about revoking access if the users’ access roles change. Because the access credentials are recreated for each access request, any role changes can be applied in real time. Just-in-time access requires support from your CA, so verify compatibility with your CA before implementing it.
It’s recommended to tailor the validity periods for short-lived certificates to align with business requirements, workload lifecycle, and your organization’s risk tolerance. AWS Private CA offers a short-lived CA mode specifically designed for certificates with validity periods under 7 days. This mode is priced at $50 per month (compared to $400 per month for general-purpose CA mode), making it cost-effective for high-volume, ephemeral workload identities such as containers and serverless functions. For more information, see AWS Private Certificate Authority and How to use AWS Private CA short-lived certificate mode. See Zero trust on AWS for information about how short-lived credentials support a zero trust architecture.
Best practices for private key storage
Safeguarding private keys is of paramount importance in any environment. A private key is created by the certificate owner when requesting certificates with a Certificate Signing Request (CSR). The CA providing your certificate doesn’t create or have your private key. In fact, it’s recommended that no one outside your administrators should ever be given access to this material. Guardrails should be implemented to make sure the keys aren’t stored in an online repository.
Using the credential helper with IAM Roles Anywhere, you can integrate with PKCS #11-compatible modules. For implementation details, see How to implement cryptographic modules to secure private keys used with IAM Roles Anywhere. With the credential helper (version 1.1.0 and later), IAM Roles Anywhere supports PKCS #11 integration, so you can use private keys stored in hardware security modules (HSMs) or software-based secure stores and avoid storing them to disk. Additionally, as of December 2024, the credential helper supports Trusted Platform Module (TPM) 2.0, enabling private keys to be generated inside the TPM and marked as non-exportable. With TPM-backed keys, the private keys can’t be extracted even if the workload host is compromised. This is the strongest private key protection available for on-premises and hybrid workloads using IAM Roles Anywhere.
If your organization doesn’t implement PKCS #11–compatible modules, IAM Roles Anywhere supports credential helper version 1.0.5 for X.509 certificates and private keys stored in macOS and Windows certificate stores. This delegates the signing operations to keys stored within those OS-specific certificate stores. In Windows, both CryptoAPI and Cryptography API: Next Generation (CNG) are supported; in macOS, Keychain is supported. In these environments, the private key will never be directly readable, and the signing operation would be delegated to the secure store instead, which will improve security posture of your environment. If you have multiple certificates, then use the --cert-selector flag of the credential helper tool to search for a specific certificate (and associated private key) through the certificate subject, issuer, and serial number. The corresponding keys are x509Subject, x509Issuer, and x509Serial, respectively. These keys can be specified either through a JSON file format or through the command line. The following is an example of both approaches:
If you want to use a JSON file, it should be similar to this:
If the preceding example is placed in a file called selector.json, it can be specified with the --cert-selector flag through file://path/to/selector.json.
The same certificate selector argument can be specified through the command line as shown in the following:
Monitoring certificate expiry in PKI is crucial for maintaining secure communication, because expired certificates can lead to authentication failures, leaving systems vulnerable to unauthorized access. Compliance and regulatory requirements often mandate timely renewal of certificates, making monitoring certificate expiry essential to avoid legal penalties and maintain organizational integrity.
Using IAM Roles Anywhere, you can receive notifications for CA certificate expiry and end-entity certificate expiry. IAM Roles Anywhere can send metrics, events, and notifications through multiple notification channels as shown in the following table:
Best practices for trust anchor certificate rotation
Consider rotating your certificates using blue/green deployments to seamlessly roll out new certificates without affecting service availability. Use automation to integrate certificate rotation testing in your blue/green deployment pipeline. See the sample AWS CloudFormation template in the Solutiondeployment section to build your automation pipeline.
As shown in Figure 5, two trust anchors have been created; one for each environment. Using this approach, you can test the certificate rotation process in a controlled staging environment before applying it to the production environment, thus reducing the risk of certificate-related outages.
Figure 5: Trust anchor certificate rotation in blue/green deployment
Important: The SessionDurationSeconds value must not exceed the IAM role’s MaxSessionDuration setting, which defaults to 3600 seconds (1 hour). If you request a longer session than the role allows, the CreateSession API returns an error. The companion template keeps both values in sync by setting the role’s MaxSessionDuration to the same parameter value. If you configure the role separately, update its MaxSessionDuration to match your desired session length. For more information, see IAM Roles Anywhere CreateSession API.
If the workload’s subject CN (WorkloadSubjectCN) doesn’t match the x509Subject CN of the authenticating certificate, the CreateSession call is denied. The same conditional verification applies to WorkloadIssuerCN and WorkloadSANCN.
The template enforces three certificate attribute conditions in the IAM trust policy: issuer CN, subject CN, and SAN CN must all match the values configured as parameters. Additionally, the trust policy scopes role assumption to the specific trust anchor Amazon Resource Name (ARN), preventing other trust anchors in the same account from assuming that role.
Conclusion
In this post, we discussed how AWS IAM Roles Anywhere, empowered by X.509 certificates, introduces a dynamic and secure way to manage workload identities and issue temporary access credentials. By understanding the trust model, using certificate attributes, and implementing fine-grained authorization, organizations can gain granular control over the effective permissions of these credentials.
The choice between just-in-time and short-lived certificates as workload identities depends on your specific requirements.
Adhering to best practices for private key storage is essential to maintain the integrity of your security infrastructure. Regularly rotating trust anchor certificates helps ensure the long-term trustworthiness of your system.
As you embark on your journey to implement IAM Roles Anywhere and integrate it with your PKI, remember that a well-architected approach to certificate management is a cornerstone of robust and resilient cloud security.
For additional deployment guidance, see Planning for your IAM Roles Anywhere deployment, which covers end-to-end deployment planning including network architecture, monitoring, and operational considerations.
If you have questions, you can start a new thread on AWS re:Post or reach out to AWS Support.
You load your own site, and instead of your homepage you get a blank page with a line of text reading 500 Internal Server Error. No explanation, no stack trace, nothing to act on. For visitors, it looks like the site is simply gone, and for you it usually means the admin area is down too, so the one tool you’d normally reach for is unavailable.
The frustrating part is that a 500 is deliberately vague.
You want to set a cryptographic algorithm policy and stop non-compliant choices from being made in your Amazon Web Services (AWS) environment. This post shows you how. As you adopt post-quantum cryptography, one of the first decisions you face is which algorithms and parameter sets fit your business needs, balancing security against signature size, key size, and performance. Your cloud environment’s job is to let you express that decision and enforce it consistently, so an approved choice stays fully usable while an excluded one cannot be introduced. This post works through one concrete example on AWS: taking an organization’s cryptographic algorithm policy and turning it into preventive and detective controls. The same patterns apply to whatever your approved set is today and whatever it becomes as standards evolve.
This post is Part 2 of a two-part series on quantum-resistant signing on AWS. Part 1, Build a software supply chain with ML-DSA, is for builders and constructs an end-to-end ML-DSA signing pipeline for binaries, container images, and software bills of materials. This part is for the security, governance, and compliance teams who decide which algorithms that pipeline, and everything else in the organization, is permitted to use, and who need that decision enforced.
AWS Key Management Service (AWS KMS) supports the ML-DSA digital signature scheme (FIPS 204) through three parameter sets, ML-DSA-44, ML-DSA-65, and ML-DSA-87, targeting NIST security categories 2, 3, and 5. All three are strong, standardized choices. Each one trades signature size, key size, and speed against security margin, the amount of cryptographic strength a parameter set holds in reserve above its target security category. ML-DSA-44 is the most compact and fastest. ML-DSA-65 and ML-DSA-87 carry a larger security margin, which is what you want for signatures that must stay trustworthy over a long lifetime.
Throughout this post, the examples use the same example policy: an organization that has standardized on ML-DSA-65 and ML-DSA-87 and wants ML-DSA-44 kept out of its approved set. That is a standardization decision, not a judgment that ML-DSA-44 is insecure (see the following note). Wherever you see ML-DSA-44 in the controls that follow, read it as the variant your policy doesn’t include; the mechanics are identical for any allow/deny split you choose. The approved set here is also the one the Part 1 architecture deploys: ML-DSA-87 for the root certificate authority (CA) and ML-DSA-65 for the subordinate CA and the code-signing key. Part 1 makes the choice; this post makes it stick.
Note: ML-DSA-44 is a valid choice. ML-DSA-44 is a fully NIST-standardized parameter set (FIPS 204) at NIST security category 2, which targets roughly 128-bit-class classical security (category 2 is benchmarked against the collision resistance of SHA-256). It produces the smallest signatures and public keys of the three variants (a 1312-byte public key and 2420-byte signature) and is the fastest to sign and verify, which makes it a strong fit for constrained devices, high-volume signing, and bandwidth- or storage-sensitive workloads. You would choose ML-DSA-65 or ML-DSA-87 instead to gain extra security margin for long-lived signatures or to align with an internal standard, not because ML-DSA-44 is weak.
What success looks like
The approved variants (ML-DSA-65 and ML-DSA-87 in the example) remain fully usable throughout. What you want to rule out is the introduction of a variant outside the policy (here, ML-DSA-44). Concretely, within the AWS service surfaces in scope, principals shouldn’t be able to:
Create ML-DSA-44 key material
Use existing ML-DSA-44 keys for signing or verification
Stand up private certificate authorities (CAs) that would introduce ML-DSA-44.
And any drift from those settings should be detected.
Certificate material brought in through acm:ImportCertificate or iam:UploadServerCertificate is also not algorithm-aware (see the Private CA section). Other TLS-terminating or signing services (for example Amazon CloudFront and Amazon API Gateway) and AWS IAM Roles Anywhere aren’t covered in this post and should be assessed separately. (Part 1 of this series uses IAM Roles Anywhere with ML-DSA certificates; controls for that service are out of scope here.)
These controls are intended to be applied as defense in depth. You can apply all of them or only a subset, depending on how prescriptive you want to be:
A blanket SCP at the organization root prevents member accounts from creating or using ML-DSA-44 keys. (SCPs don’t apply to the management account, so workloads there aren’t restricted.)
An SCP at a production organizational unit (OU) restricts keys only in production accounts.
If you need flexibility inside an account, use IAM permission boundaries instead of account-wide settings enforced through an SCP.
Choose the combination that matches your operating model. The policy examples here are written to apply across all AWS Regions. If you need to scope a control to specific Regions, add an aws:RequestedRegion condition.
The policies in this post are illustrative starting points. Authoring, validating, and maintaining the specific SCPs, IAM policies, and permission boundaries for your environment is your responsibility. Test all policies in a non-production environment before deployment and adjust example values (such as policy names and key Amazon Resource Names (ARNs)) to match your organization’s approved standards.
A note on cryptographic agility
Your algorithm policy isn’t fixed forever, and these controls shouldn’t be either. The point of expressing the policy as AWS controls is that you can revise it as your needs and the relevant standards change, tightening, loosening, or swapping the approved set without re-architecting. Treat the examples here as a template you adjust to whatever your current policy is.
A deny-based control that names specific algorithms is, in effect, an allow-list of everything it does not name. The risk is default-allow: any parameter set you have not explicitly denied is permitted, so a newly introduced variant, including one you have not yet evaluated, becomes usable until you notice it and add it to the deny list. Deprecation of an already-approved variant is easy to handle in this model, because you simply add the deprecated variant to the deny list. What the model does not catch on its own is the arrival of something new. Review these controls periodically and pair the deny-list with detection so a variant outside your policy surfaces quickly rather than waiting to be discovered.
The alternative is to write the condition against the approved set rather than the excluded one. A Deny that uses StringNotEquals with a list of approved key specs fires when the request’s key spec matches none of them, so a new or not-yet-evaluated variant is blocked by default until you add it. That closes the default-allow gap, at the cost of a policy update before anyone can use a newly approved variant. The family-level SCP in Part 1 of this series takes this shape: it denies creation of any signing key whose key spec isn’t ML_DSA_*. The examples in this post take the other shape and name the excluded variant, so that approved variants stay usable without a policy change. Both are valid. Choose based on whether you would rather block something new first and approve it later, or notice it first and decide then.
The StringLike clause scopes the statement to ML-DSA key specs so it doesn’t affect other key types; the StringNotEquals clause denies any ML-DSA variant outside the approved list.
Just as algorithms and key sizes will be introduced over time, or move from approved to unapproved, so will AWS service operations. The set of operations through which an ML-DSA-44 key can be used today (AWS KMS Sign, Verify, and GetPublicKey) reflects current service capabilities and might expand as AWS releases new features. If your policy is to block use in addition to creation, you should periodically review the list of operations you restrict, because services evolve over time.
Background: Key spec compared to signing algorithm
AWS KMS support for ML-DSA introduces three key specs—ML_DSA_44, ML_DSA_65, and ML_DSA_87—that all use a single post-quantum signing algorithm: ML_DSA_SHAKE_256. This distinction drives which controls are effective.
kms:KeySpec: Reflects the KeySpec property of the key. It’s evaluated both on CreateKey (the requested key spec) and on AWS KMS key resource operations that act on a specific key, including Sign, Verify, and GetPublicKey. This makes kms:KeySpec a reliable lever for both preventing creation of ML-DSA-44 keys and restricting use of existing ones, because it can single out ML_DSA_44 from ML_DSA_65 and ML_DSA_87.
kms:SigningAlgorithm: Reflects the signing algorithm supplied on Sign and Verify, which is ML_DSA_SHAKE_256 for all three variants. It therefore can’t distinguish ML-DSA-44 from the approved variants and shouldn’t be used for this purpose.
The practical consequence: for keys held in AWS KMS, preventing ML-DSA-44 key material from being created is the most robust single control. If no ML-DSA-44 KMS keys exist, none can be used for signing through AWS KMS and none can become the subject key of a certificate. CA keys and TLS server keys are separate material: AWS Private CA generates and holds a CA’s key pair in its own HSMs, and ACM-issued, imported, or uploaded TLS certificates carry their own keys, so those surfaces are governed by the AWS Private CA and certificate controls later in this post. Where ML-DSA-44 KMS keys already exist, their use can additionally be restricted with kms:KeySpec.
Organization and account-level blocking using SCPs
SCPs can be applied at the organization root or to a specific OU to restrict ML-DSA-44. Placement determines the effective scope: it applies organization-wide when attached at the root; attached to an OU, it applies to the accounts within that OU. An SCP is the broadest-scope preventive control available.
Note that SCPs apply to member accounts and OUs but not to the organization’s management account, so avoid running ML-DSA-44-capable workloads in the management account, where an SCP will not restrict them.
The following example SCP denies both the creation of ML-DSA-44 keys (kms:CreateKey) and their use (kms:Sign, kms:Verify, kms:GetPublicKey), matching on the ML_DSA_44 key spec in each case. The creation deny stops new keys from being created; the usage deny covers keys that already exist, whether created before the SCP was attached or living in an account that later joins the OU, because kms:KeySpec is also evaluated at request time on those usage operations.SCPs are guardrails: a Deny in an SCP can’t be overridden by any IAM policy within member accounts.
Attach the following SCP at the organization root (or relevant OU):
Scope the usage deny to the three key-spec-aware actions. Limit the use of Deny to kms:Sign, kms:Verify, and kms:GetPublicKey (testing confirmed kms:KeySpec is evaluated on all three). Avoid a blanket kms:*: a wildcard that would also catch management operations such as DescribeKey, DisableKey, and ScheduleKeyDeletion, which you need to inspect or clean up those same keys, effectively locking you out of managing the keys you’re trying to remove. If you use multi-Region keys, also add kms:ReplicateKey to the creation deny: replicating an ML-DSA-44 primary key creates a new ML-DSA-44 key in another Region, and kms:KeySpec is evaluated on ReplicateKey as well.
Combining with a family-level guardrail. This SCP governs which ML-DSA parameter set is allowed; it says nothing about RSA or ECDSA. Part 1 of this series includes a complementary SCP that denies creation of any signing key whose key spec isn’t ML-DSA. Attached together, they require every new signing key to be ML-DSA and to be an approved variant.
Operational considerations. A blanket Deny at the organization root is the strongest control but has trade-offs: it removes any ability to create ML-DSA-44 keys anywhere in scope, with no exception path, which can block legitimate testing and might cause infrastructure as code (IaC) or pipeline runs that attempt ML-DSA-44 creation to fail. To preserve flexibility, consider scoping the Deny to a production OU and using IAM permission boundaries (see the following section) in build and non-production accounts.
What the caller sees. When an SCP denies a request, the caller receives an AccessDenied error indicating an explicit deny in a service control policy. For same-account and same-organization requests, the error includes the type of the denying policy and, as the enhanced error messages roll out across services, its ARN. The error doesn’t expose the SCP policy contents, and the user being blocked often can’t see the SCPs applied to their environment. Document the SCP ARN and its purpose internally so support teams can map an AccessDenied quickly.
Prevent ML-DSA-44 key creation in AWS KMS (principal-level)
The following IAM policy blocks ML-DSA-44 at the principal level. It is the identity-based counterpart to the SCP shown earlier, useful when you want per-account or per-role control rather than an organization-wide guardrail. Attach it to the IAM role or user you want to constrain.
The condition value is ML_DSA_44 (underscores, not hyphens).
This policy blocks CreateKey only. To also block use of existing ML-DSA-44 keys at the principal level, add the Sign, Verify, and GetPublicKey deny shown in the Restricting use of existing ML-DSA-44 keys section.
For comprehensive, non-overridable coverage, deploy as an SCP rather than relying solely on principal-level policies.
IAM permission boundaries
IAM permission boundaries set the maximum permissions an identity-based policy can grant to an IAM role or user and can be used as an alternative or complement to using SCPs. The effective permissions are the intersection of the identity-based policy and the boundary, and a Deny in a boundary can’t be overridden by an attached policy. Boundaries are useful where you want per-account or per-role flexibility (for example, in build or non-production accounts) rather than a blanket, multi-account deny.
Operational consideration. A permission boundary only takes effect on principals that have it attached. To rely on boundaries as a control, you need a mechanism to enforce the boundary on all IAM principals programmatically. One example enforcement mechanism would be an SCP that denies iam:CreateRole, iam:CreateUser, iam:PutRolePermissionsBoundary, and iam:PutUserPermissionsBoundary unless the approved boundary is set (using the iam:PermissionsBoundary condition key), and denies iam:DeleteRolePermissionsBoundary and iam:DeleteUserPermissionsBoundary outright so the boundary can’t be removed after the fact. You would also want to probe for non-conforming principals periodically and respond, perhaps by automatically attaching the PermissionsBoundary. IAM users shouldn’t be used, but the enforcement should account for the possibility that they exist.
Because a boundary only sets a ceiling and does not itself grant anything, it opens with Allow on all actions, then denies ML-DSA-44 key creation specifically. The following permission boundary denies creation of ML-DSA-44 keys:
To also block use of existing ML-DSA-44 keys for the principals carrying this boundary, add the Sign, Verify, and GetPublicKey deny statement shown in the following section (which also uses kms:KeySpec).
Restricting use of existing ML-DSA-44 keys
As described in the Background section, kms:KeySpec is also evaluated on Sign, Verify, and GetPublicKey, reflecting the KeySpec of the key being used. You can therefore deny those operations when kms:KeySpec equals ML_DSA_44 while continuing to permit ML_DSA_65 and ML_DSA_87. The IAM policy below, attached to an IAM principal, does exactly that.
This deny can also live in an AWS KMS key policy. The same kms:KeySpec deny can be placed directly in the key policy of an AWS KMS key. A key policy is a resource policy, so the statement must include a Principal element. Identity policies and SCPs do not name principals to which they apply. A deny in the key policy is a resource-side backstop that protects a specific key, while an SCP gives non-overridable organization-wide coverage. To turn the previous example into an AWS KMS key policy, add a Principal element to the statement (for example "Principal": {"AWS": "*"}, or a more specific principal), and keep the rest of it the same.
Additional approaches
Depending on your goals you might also want to remove the key material itself rather than only deny its use. Remember that it is difficult to know what data has been signed by a specific key, unless you track that somehow. Deleting a key that was used will make signature verification impossible. Take great care to make sure keys are not used before deleting them.
Disable or schedule deletion of the keys. Disabling stops key use immediately and is reversible. Key deletion is definitive but irreversible after the waiting period, so confirm before scheduling.
Deny Sign, Verify, and GetPublicKey by specific key ARN. You can target named keys rather than the whole key spec. To do this, you would list the exact key ARNs in the Resource element of the IAM policy (no condition key required). This is effective for targeting a single key specifically, but it is difficult to maintain lists of key ARNs. Use this strategy sparingly. If you’re considering using an IAM policy naming a key ARN, remember that a Deny in the key policy of the target key accomplishes the same goal and is attached to the key itself.
Finding existing keys (only needed if you disable or delete). A Deny in an IAM policy or SCP, based on kms:KeySpec, doesn’t require you to know which keys exist – it applies by key spec at request time. If you want to disable or delete existing ML-DSA-44 keys, you need to locate them. AWS KMS has no server-side filter for key spec, so you must enumerate keys with ListKeys and call DescribeKey and inspect each KeySpec. This client-side filtering pattern is common across AWS APIs and is well supported by pagination in the AWS SDKs. You can also use AWS Config to record and query KMS key resources.
Approved ML-DSA variants and control of AWS Private CA
AWS Private CA sets a certificate authority’s (CA’s) signing algorithm at creation time, in the CertificateAuthorityConfiguration parameter of CreateCertificateAuthority (valid values include ML_DSA_44, ML_DSA_65, and ML_DSA_87). There is currently no condition key for the algorithm, so an SCP cannot enforce signing algorithm. The approach in this section controls who can create CAs and pins the algorithm in that trusted path, backed by AWS CloudTrail-based detection.
Recommended approach
Restrict who can create CAs. Deny acm-pca:CreateCertificateAuthority broadly via SCP, and allow it only for a small set of trusted roles or an approved provisioning pipeline. This removes the ability for arbitrary principals to stand up a CA with an unapproved algorithm.
Pin the algorithm in the trusted path. Have that approved pipeline or infrastructure-as-code template hard-code SigningAlgorithm to ML_DSA_65 or ML_DSA_87 in CertificateAuthorityConfiguration. Because AWS Private CA exposes no algorithm condition key, this provisioning path is the enforcement point. Note that the CA’s algorithm pins the signature on the certificates it issues; the subject key in each certificate comes from the CSR, which AWS Private CA copies without validating its algorithm, so pin the CSR key algorithm in the same issuance pipeline.
Control the trust chain. On the PKI side, only add approved CAs to your trust stores and issuance hierarchies, and do not trust or subordinate CAs that could issue ML-DSA-44. This prevents an unapproved CA from being introduced into a trusted path.
Detect drift. Use CloudTrail to capture CreateCertificateAuthority calls and AWS Config to flag any CA whose configuration uses ML_DSA_44, so an unapproved CA is caught quickly.
Part 1 of this series shows what this looks like in practice: it creates an ML-DSA-87 root CA and an ML-DSA-65 subordinate CA with CreateCertificateAuthority, activates them, and distributes the resulting chain to verifiers. In the model described here, those are the calls that only your approved provisioning pipeline is allowed to make.
Setting the ML-DSA value in CertificateAuthorityConfiguration. The same variant goes in both the KeyAlgorithm and SigningAlgorithm fields (for example, KeyAlgorithm=ML_DSA_65 with SigningAlgorithm=ML_DSA_65). Note a difference in signing algorithms between AWS KMS and AWS Private CA. With AWS Private CA, the SigningAlgorithm takes the variant value directly (ML_DSA_44, ML_DSA_65, and ML_DSA_87), and doesn’t accept ML_DSA_SHAKE_256. In contrast, AWS KMS uses ML_DSA_SHAKE_256 as its signing algorithm. Be aware that some older AWS Command Line Interface (AWS CLI) builds omitted descriptions of the ML-DSA variants from the built-in CLI help, so don’t rely on the help in the AWS CLI to determine valid values. For more information, see CertificateAuthorityConfiguration API Reference.
Known limitation. Some surfaces have no algorithm condition key, so you enforce them through provisioning and detection rather than policy. acm-pca:CreateCertificateAuthority has no condition key for the algorithm, and acm:ImportCertificate and iam:UploadServerCertificate are not algorithm-aware, so a disallowed signature setting on a created, imported, or uploaded certificate cannot be blocked by an IAM policy or SCP condition. Govern these through your provisioning process, restrict who can call them, and deny the import and upload actions entirely where they are not required. The controls above remain the available mitigation.
In particular, iam:UploadServerCertificate doesn’t support any method to prevent use of particular algorithms, and AWS doesn’t recommend using this API to generate and upload certificates. This API predates ACM and exists mainly to cover AWS Regions or partitions where ACM is not yet available. While a new Region or partition is being built out, workloads can still need a TLS server certificate before ACM support has shipped there, and uploading a certificate to IAM gives you a place to store and reference it in the meantime. Once ACM is available in that Region, you should use ACM instead. Outside that narrow case, deny iam:UploadServerCertificate unless it is genuinely required.
ACM-issued leaf certificates. A CA’s own key and signing algorithm are separate from the leaf certificates that ACM issues from it. If you use ACM to request leaf certificates, you can constrain the leaf’s key algorithm with the acm:KeyAlgorithm condition key on acm:RequestCertificate. This lets you allow-list approved algorithms for leaf certificates using SCPs or IAM policies, similar to the AWS KMS examples earlier in this post. Be aware that, at the time of writing, ACM doesn’t offer ML-DSA leaf certificates. So a policy like this is a forward-looking defense-in-depth control rather than an immediate ML-DSA-44 risk. The IAM example below is illustrative (using example approved algorithms). Since this is an evolving part of the service, be sure to validate this in your environment before relying on it.
This example uses StringNotEqualsIfExists so it denies only requests that specify a disallowed algorithm. With plain StringNotEquals, a request that omits acm:KeyAlgorithm would also be denied, because the missing key makes the condition evaluate true. Choose the operator that matches whether you want to block requests that leave the algorithm unspecified.
Prevent ML-DSA-44 usage in TLS for NLB and ALB
Elastic Load Balancing, for both network load balancers (NLB) and application load balancers (ALB), terminates TLS on behalf of your applications. The certificates used by these listeners are requested through or imported into ACM, or uploaded to IAM. A listener’s configured security policy and its certificate determine what’s offered during negotiation. At the time of writing, ACM requests and imports accept RSA and ECDSA keys only, and NLB and ALB listeners accept RSA and ECDSA certificates only, so no ML-DSA certificate can be bound to a listener today. As with the ACM leaf-certificate policy earlier, the controls in this section are forward-looking defense in depth rather than a mitigation of an immediate ML-DSA-44 risk.
Certificate controls (the effective mechanism for ML-DSA-44)
Because the listener API calls reference a certificate only by ARN, you can’t write an SCP on CreateListener, ModifyListener, or AddListenerCertificates that inspects the certificate’s algorithm. IAM conditions can’t reference attributes of a separately-referenced resource. Keeping ML-DSA-44 out of TLS therefore relies on there being no ML-DSA-44 certificate material to associate:
Configure your private CA to issue only ML_DSA_65 or ML_DSA_87 certificates, and control who can create CAs.
Prevent ML-DSA-44 key creation in AWS KMS, so that no KMS-held ML-DSA-44 key can become the subject key of a certificate. TLS server keys for ACM-issued, imported, or uploaded certificates are not KMS keys; those are governed by items 1 and 3.
Control imported and uploaded certificates through your provisioning process or deny the import and upload actions where not required, as described in the AWS Private CA section.
Detective controls
CloudTrail records the certificate and listener API calls in this section: certificate creation and import (acm-pca:CreateCertificateAuthority, acm:ImportCertificate, iam:UploadServerCertificate) and listener configuration (CreateListener, ModifyListener, AddListenerCertificates). Whether the algorithm shows up in the event depends on what the call itself carries. Creation calls that take the algorithm as an input record it: kms:CreateKey logs the KeySpec, and acm-pca:CreateCertificateAuthority logs the signing algorithm. That makes CloudTrail effective for catching the creation of ML-DSA-44 key material or a CA. A listener binding references its certificate only by ARN, so the certificate’s algorithm does not appear in that event. To evaluate the algorithm of a bound or imported certificate, use AWS Config resource evaluation as the detective backstop.
Summary for TLS
The primary preventive control is the certificate material itself: with no ML-DSA-44 CA, no ML-DSA-44 KMS key, and certificate import and upload controlled, no ML-DSA-44 certificate can be issued or bound. Where you also operate an allow-list of permitted TLS security policies, the elasticloadbalancing:SecurityPolicy condition key (on CreateListener and ModifyListener) can additionally constrain which TLS policies listeners can use.
Summary of controls
The following table maps the example policy (allow ML-DSA-65 or ML-DSA-87, exclude ML-DSA-44) to the available controls. Modify the controls to limit use to the approved set of algorithms your policies require.
Area
Control
Status
Block ML-DSA-44 key creation (Organization-wide or for all accounts in an organization OU)
SCP on kms:CreateKey using kms:KeySpec
Fully supported via condition key
Block ML-DSA-44 key creation (per account or per role)
IAM policy or permission boundary using kms:KeySpec
Supported; requires programmatic enforcement of boundaries
Block use of existing ML-DSA-44 keys
Deny Sign, Verify, and GetPublicKey using kms:KeySpec (key policy, IAM, or SCP); optionally disable and delete keys
Supported using kms:KeySpec (not kms:SigningAlgorithm)
Only allow approved variants in Private CA
Restrict who can create CAs; pin ML_DSA_65 or ML_DSA_87 in provisioning path
No algorithm condition key; enforce using process and detection
Limit variants in imported or uploaded TLS certificates
Process controls, or deny import or upload APIs (prefer ACM over iam:UploadServerCertificate)
APIs aren’t algorithm-aware
Block use of ML-DSA-44 in TLS with network load balancers (NLB) and application load balancers (ALB)
Restrict TLS policy using elasticloadbalancing:SecurityPolicy; control cert material
TLS-policy restriction supported; no per-cert algorithm condition
Detect use of unapproved variants
CloudTrail (API-level) and AWS Config custom rules
Supported using custom AWS Config rules; not managed rules
Conclusion
In this post, you learned how to use ML-DSA as an example of turning a cryptographic algorithm policy into enforceable AWS controls. The key lever is the kms:KeySpec condition key: it keeps your approved parameter sets (ML-DSA-65 and ML-DSA-87) fully usable while preventing the creation and use of a parameter set you’ve excluded (ML-DSA-44) on the CreateKey, in addition to the Sign, Verify, and GetPublicKey operations, where kms:SigningAlgorithm can’t tell the variants apart. Applied as defense in depth across SCPs, IAM policies, permission boundaries, and KMS key policies, and extended to the surfaces that have no algorithm condition key (AWS Private CA, certificate import, and Elastic Load Balancing TLS) through provisioning controls plus AWS CloudTrail and AWS Config drift detection, these controls give you a consistent way to keep an unapproved variant out of your accounts.
The pattern isn’t specific to ML-DSA-44. Because your algorithm policy will change as standards and your own requirements evolve, treat these controls as a reusable template and re-point the same condition keys and guardrails at whatever your approved set becomes. This adaptability is the practical meaning of cryptographic agility: changing what you allow without re-engineering how you enforce it.
To see the workloads these controls govern, read Part 1 of this series, which builds a complete ML-DSA signing pipeline, from key creation and PKI through artifact signing and verification, using the approved set enforced here.
Software supply chain attacks have grown in both frequency and sophistication. Recent high-profile compromises of build systems and open source dependencies demonstrate that attackers increasingly target the trust mechanisms that verify software integrity. Those trust mechanisms rely on digital signature algorithms, and today many use traditional algorithms such as Rivest-Shamir-Adleman (RSA) and the Elliptic Curve Digital Signature Algorithm (ECDSA). If a sufficiently powerful quantum computer could forge these signatures, an attacker could potentially inject unauthorized code into signed artifacts, fabricate build attestations, or impersonate legitimate publishers. Using quantum-resistant signatures today defends against threats that might emerge in the future.
Since 2025, the Commercial National Security Algorithm Suite 2.0 (CNSA 2.0), published by the US National Security Agency (NSA), has required US National Security Systems (NSS) to “support and prefer” quantum-resistant signatures for software and firmware, with exclusive use mandated by 2030. The EU Cyber Resilience Act (CRA) takes full effect in December 2027. It requires manufacturers to maintain verifiable software integrity throughout a product’s lifecycle. Organizations that ship software to US federal agencies or sell products in the European market face converging deadlines that demand action now.
This post is Part 1 of a two-part series on adopting ML-DSA signatures, standardized in NIST FIPS 204 (ML-DSA) signatures, on AWS. As of Oct 2026, this series is the first end-to-end guide from any cloud provider for post-quantum signing across the software supply chain, from establishing an ML-DSA root of trust to enforcing algorithm policy across an organization. This part is for builders and walks through constructing and operating the signing pipeline. Part 2, Enforce your ML-DSA algorithm policy with SCPs and IAM, is for security and governance teams and shows how to turn the algorithm choices made here into preventive and detective controls across an organization.
Understanding the harvest now, forge later threat
After a cryptographically relevant quantum computer (CRQC) exists, the mathematical problems protecting today’s public-key cryptography can be solved efficiently. Attacks that are impractical today because of the computational complexity suddenly become practical using a CRQC. Most discussions of post-quantum cryptography (PQC) focus on the harvest now, decrypt later threat to data confidentiality. The asymmetric keys protecting data in transit can be efficiently derived using a CRQC, exposing the data that was meant to be protected. Digital signatures rely on the same asymmetric mathematical problems that a CRQC would break. This means that software supply chains face a parallel threat that targets integrity rather than confidentiality. An attacker who records signed artifacts today can forge those signatures in the future on a totally different artifact, using a CRQC.
Consider firmware signed with ECDSA P-256 and deployed to a fleet of embedded devices in 2026. These devices verify the firmware signature on every boot for their 15-year operational lifetime and can’t be recalled to re-sign after deployment. If a CRQC becomes operational in 2035, an attacker could produce a valid-looking signature over tampered firmware, and every device in the fleet would accept it as authentic on next restart. For organizations that rely on classical digital signatures as the primary mechanism for verifying software integrity, this weakens a critical link in the verification chain. This is why CNSA 2.0 specifies aggressive timelines for digital signatures: the artifacts you sign today must remain trustworthy for their full operational lifetime.
ML-DSA is designed to resist attacks from both classical and quantum computers. AWS KMS, AWS Private CA, and AWS IAM Roles Anywhere all support ML-DSA, making it possible to address the forge-later threat across your supply chain today without additional tooling.
Architecture overview: Five pillars of a quantum-resistant supply chain
The architecture comprises five trust pillars that together protect your software delivery pipeline:
ML-DSA key management in AWS KMS – All signing keys are generated and protected in FIPS 140-3 Security Level 3 hardware security modules (HSMs). Private keys never leave the HSM boundary.
ML-DSA public key infrastructure (PKI) throughAWS Private CA – A certificate hierarchy (root CA, subordinate CA, end-entity certificates) binds ML-DSA public keys to identities, establishing who signed what. CA private keys are generated and stored in hardware-protected HSMs managed by the service and never leave the HSM boundary.
Quantum-resistant workload identity (for external build agents) – For continuous integration and delivery (CI/CD) agents running outside AWS that authenticate through X.509 certificates, IAM Roles Anywhere with ML-DSA certificates ties the signer’s identity back to the same quantum-resistant root of trust.
ML-DSA SBOM integrity attestation – The SBOM for each release is wrapped in an in-toto Statement that names the artifact it describes by digest, and the Statement is signed with the same ML-DSA code-signing key. This provides quantum-resistant proof that the dependency manifest hasn’t been tampered with and that it belongs to the artifact it accompanies.
These pillars create a chain of trust: AWS Private CA protects the root CA key in its own HSMs, issues certificates that bind identities to AWS KMS code-signing keys, IAM Roles Anywhere uses those certificates to authenticate build agents, and authenticated agents sign every artifact and SBOM they produce.
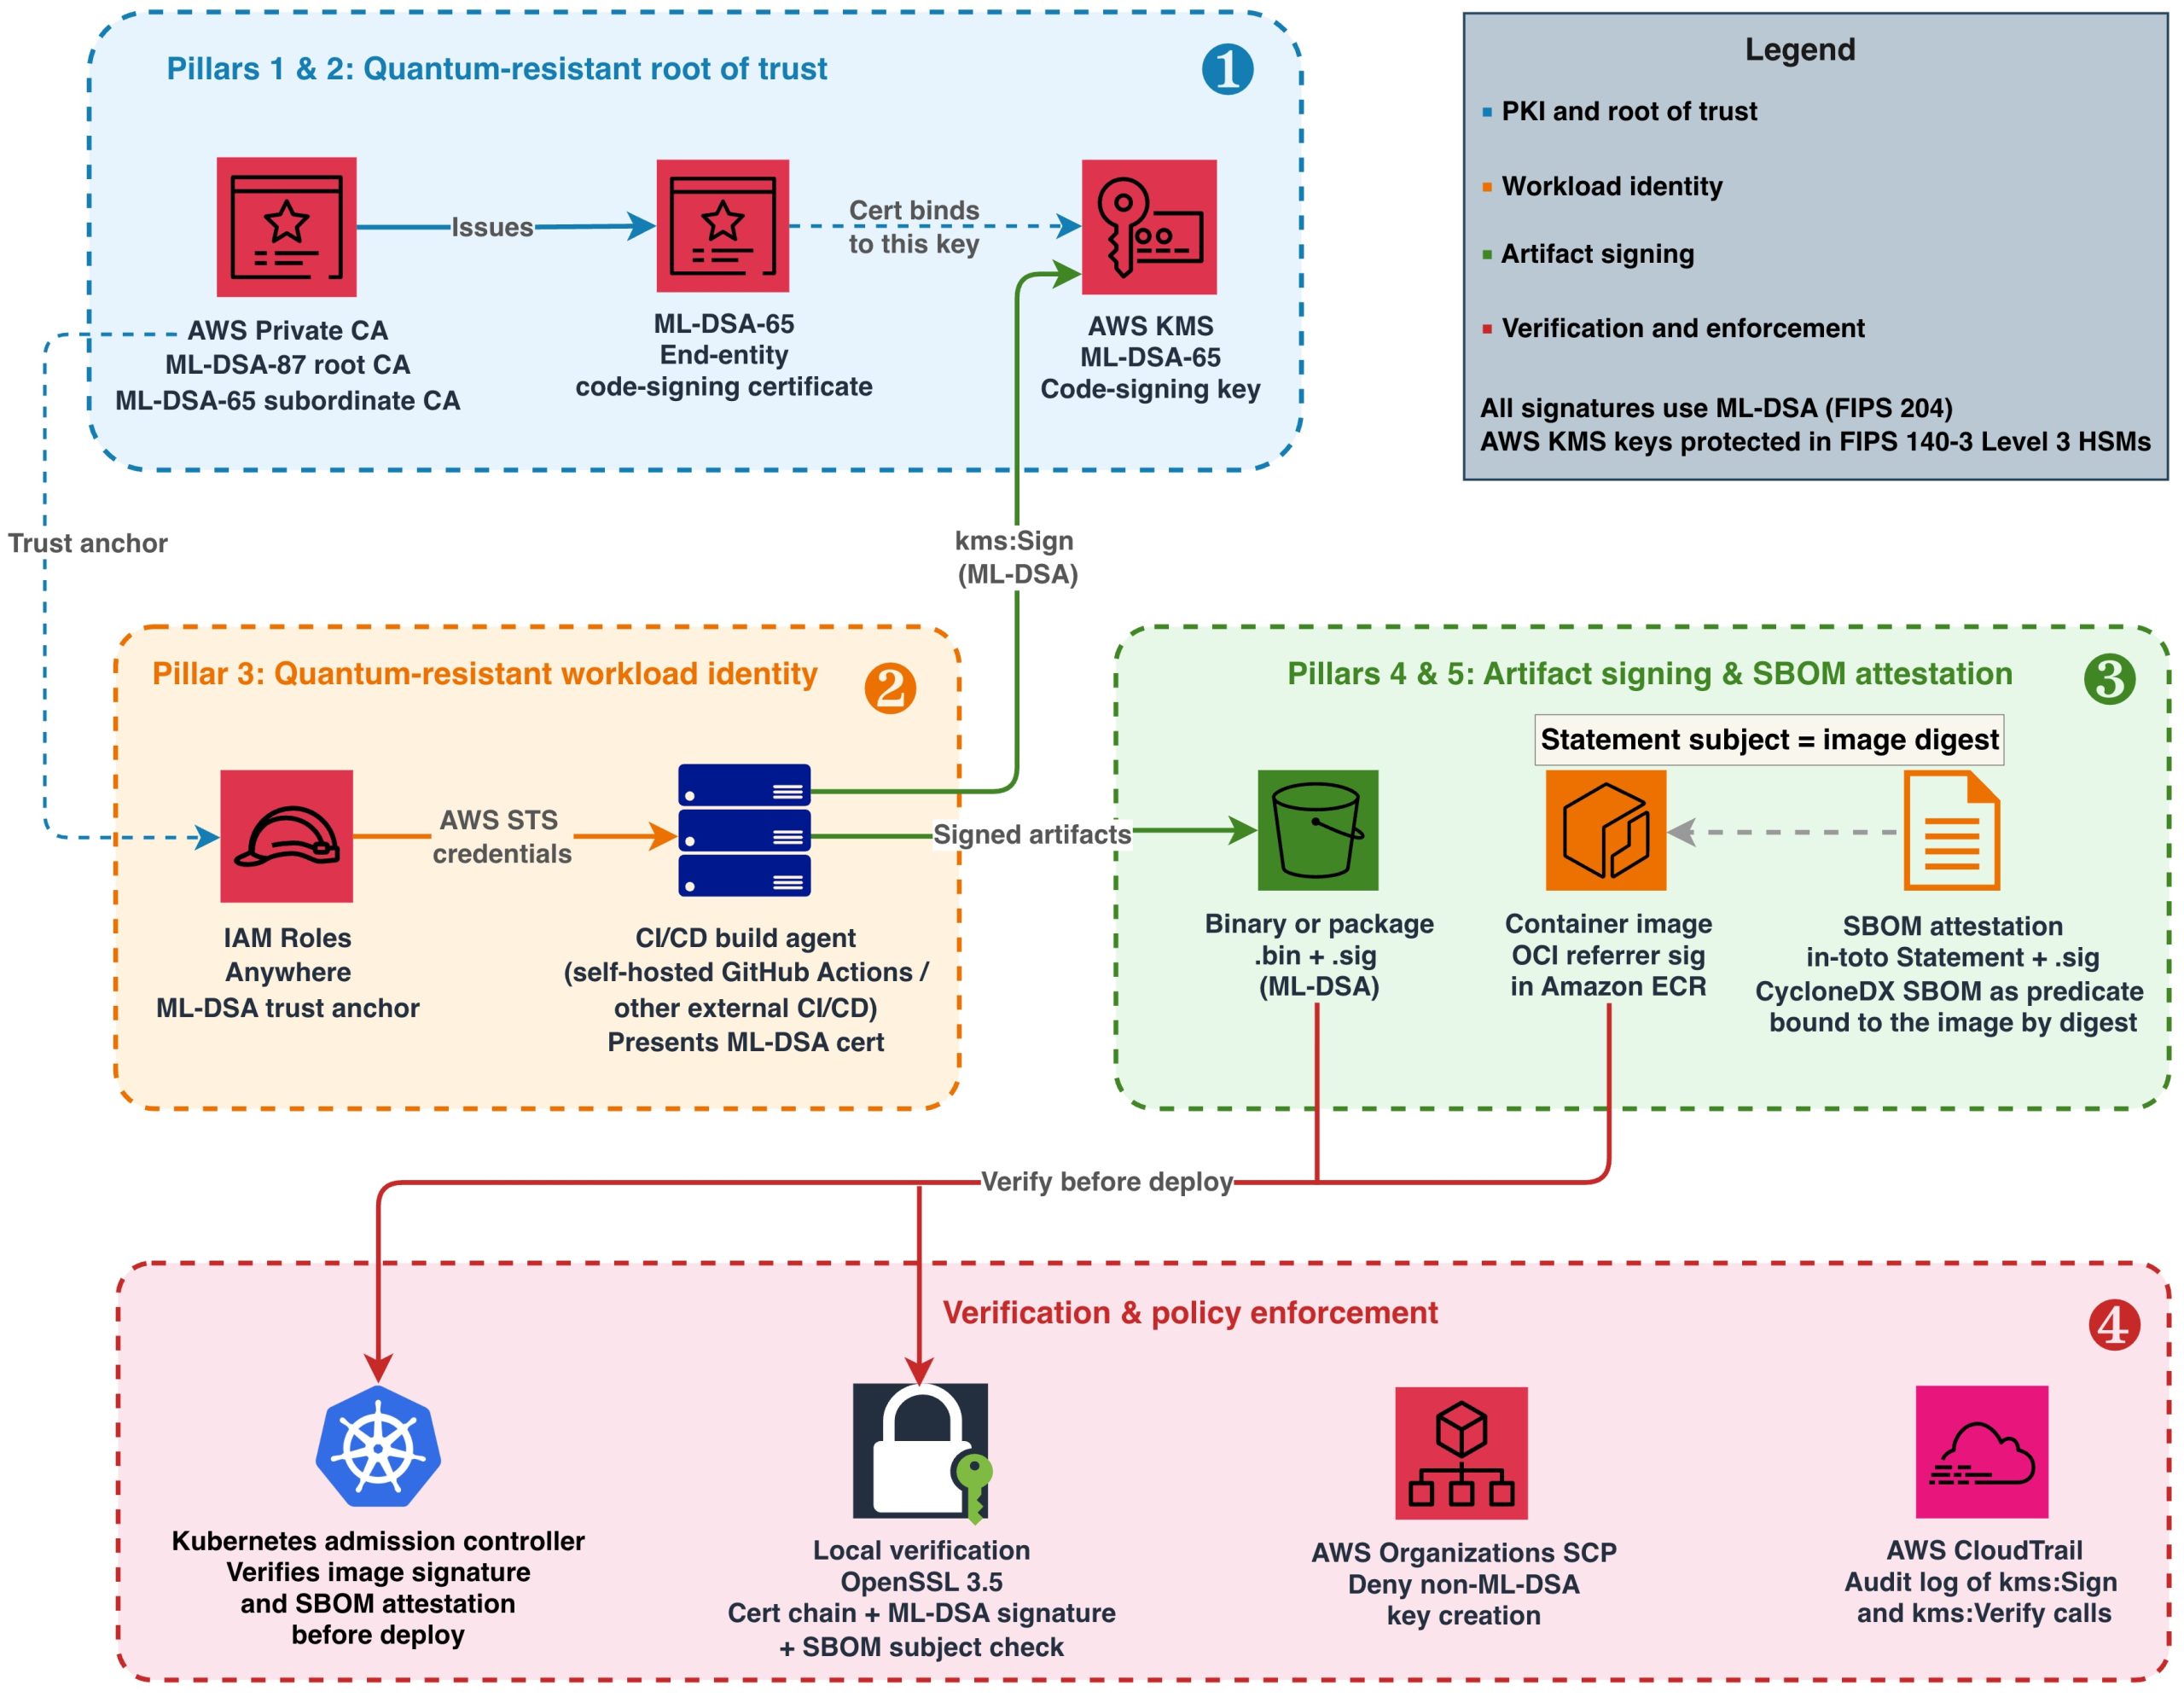
Figure 1: End-to-end quantum-resistant software supply chain on AWS
Figure 1 illustrates this architecture in four layers, numbered in the order you build them:
Root of trust (Pillars 1 and 2) – Establish your AWS Private CA hierarchy and create your code-signing key in AWS KMS.
Workload identity (Pillar 3) – Register the CA as an IAM Roles Anywhere trust anchor and issue ML-DSA certificates to build agents, ensuring the signer’s identity chains back to the same quantum-resistant root of trust.
Artifact signing (Pillars 4 and 5) – Sign binaries, container images, and SBOMs using the authenticated build agent.
Verification and enforcement – Validate signatures at deployment and enforce ML-DSA-only policies.
Prerequisites
To follow along, you need:
An AWS account with permissions to create resources in AWS KMS, AWS Private CA, IAM Roles Anywhere, and Amazon ECR.
IAM Roles Anywhere credential helper (aws_signing_helper) v1.8.0 or later, the first release that supports ML-DSA keys and certificates, for workload authentication. Download from the IAM Roles Anywhere documentation.
OpenSSL 3.5 or later (required for ML-DSA signature verification and mu computation).
ORAS CLI v1.2 or later (for attaching Open Container Initiative (OCI) referrer artifacts to container images). Alternatively, you can use the Notation CLI with a custom plugin or any OCI-compliant client that supports the OCI Referrers API.
jq, for constructing and parsing the in-toto Statements used for SBOM attestation and for parsing ORAS output.
Amazon Inspector SBOM Generator (Sbomgen), or another tool that produces a CycloneDX JSON SBOM, for the SBOM example. Sbomgen runs only on Linux (x86-64 and ARM64), so run that step on a Linux build agent or container. It uses the registry credentials that oras login stores in the Docker config file, and it also accepts them through --username or the INSPECTOR_SBOMGEN_USERNAME and INSPECTOR_SBOMGEN_PASSWORD environment variables.
Java 11 or later and Apache Maven, to run the diy-code-signing-kms-private-ca sample that produces the code-signing CSR in Step 4 of Building the ML-DSA PKI foundation.
A container image pushed to Amazon ECR (for the container signing example).
Building the ML-DSA PKI foundation
Start by creating the certificate hierarchy that will anchor your supply chain trust. AWS Private CA generates and stores its own CA signing keys internally in hardware-protected HSMs when you create a certificate authority. Use ML-DSA-87 (NIST security category 5, defined as at least as hard to break as exhaustive key search on AES-256) for the root CA because it protects the longest-lived trust anchor. Use ML-DSA-65 (NIST security category 3) for the subordinate CA to balance security with smaller signature sizes for frequently issued certificates.
The parameter sets used here, ML-DSA-87 and ML-DSA-65, are also the approved set in the example algorithm policy that Part 2 of this series turns into enforceable controls. If your organization has standardized on a different set, substitute it in the commands that follow; the build steps don’t change.
Step 1: Create the root CA in AWS Private CA
When you specify KeyAlgorithm: ML_DSA_87, Private CA generates an ML-DSA-87 key pair internally. You don’t need to create a separate AWS KMS key for the CA.
After creation, the root CA is in PENDING_CERTIFICATE state. Activate it by self-signing its certificate. This is where you set the root CA’s validity period (10 years is typical for a root):
After creation, the subordinate CA enters PENDING_CERTIFICATE state with no link to the root. Activate it by signing its certificate signing request (CSR) with the root CA:
# Retrieve the subordinate CA's certificate signing request
aws acm-pca get-certificate-authority-csr \
  --certificate-authority-arn <sub-ca-arn> \
  --output text > sub-ca.csr

# Sign the CSR using the root CA (this establishes the trust hierarchy)
SUB_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --csr fileb://sub-ca.csr \
  --signing-algorithm ML_DSA_87 \
  --validity Value=1825,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/SubordinateCACertificate_PathLen0/V1 \
  --query CertificateArn --output text)

# Retrieve the signed certificate and import it to activate the subordinate CA
aws acm-pca get-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate-arn $SUB_CERT_ARN \
  --query Certificate --output text > sub-ca-cert.pem

aws acm-pca import-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate fileb://sub-ca-cert.pem \
  --certificate-chain fileb://root-ca-cert.pem
Step 3: Create the code-signing key in AWS KMS
Your build agents use this key to sign artifacts, so their IAM roles need the kms:Sign permission on it. The end-entity certificate issued by your subordinate CA binds an identity to this key’s public key.
Step 4: Issue the end-entity code signing certificate
To issue a certificate, you need a CSR. Because the ML-DSA private key never leaves the AWS KMS HSM, you can’t generate the CSR locally with OpenSSL. Instead, you construct the CSR’s TBS (to-be-signed) structure containing your subject name and public key, sign it remotely by calling aws kms sign, and assemble the final CSR from those components.
For a working implementation that assembles an ML-DSA CSR around a KMS-managed private key and signs it with AWS KMS, see Post-quantum (ML-DSA) code signing with AWS Private CA and AWS KMS and its diy-code-signing-kms-private-ca sample on GitHub (Java, built with Maven). There is no AWS CLI-only path for this step: the CSR must be constructed and signed in code, and the sample is the reference implementation.
After you have the code-signing.csr file, issue the certificate from your subordinate CA:
# Issue a code-signing certificate valid for one year, signed by the subordinate CA using ML-DSA-65.
# Replace <sub-ca-arn> with the ARN that create-certificate-authority returned for the subordinate CA in Step 2.
CODE_SIGNING_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --csr fileb://code-signing.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=365,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/CodeSigningCertificate/V1 \
  --query CertificateArn --output text)

# Retrieve the issued certificate
aws acm-pca get-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-arn $CODE_SIGNING_CERT_ARN \
  --query Certificate --output text > code-signing-cert.pem
This certificate binds the signer identity to the AWS KMS code-signing key material. Note that the certificate validity period (365 days in this example) determines how long verifiers can validate signatures by checking the certificate alone. AWS Private CA lets you choose the validity period of an issued certificate, as long as it ends no later than the issuing CA’s own certificate; in this example the subordinate CA certificate from Step 2 is valid for 1,825 days, so the three-year option below fits inside it. For artifacts that must remain verifiable beyond the certificate’s expiry, consider these approaches:
Longer certificate validity – For private PKI, code-signing certificates are commonly issued with multi-year validity (for example, Value=1095,Type=DAYS for 3 years) because you control the issuance policy.
Trusted timestamping (RFC 3161) – Countersign each signature with an RFC 3161 timestamp from a Time Stamping Authority (TSA) at signing time. The timestamp proves the signature was created while the certificate was valid, allowing verification indefinitely. AWS doesn’t provide a managed TSA; use a third-party TSA or operate your own.
Re-signing – Before a certificate expires, re-sign active artifacts with a newly issued certificate.
Distribute the certificate chain (root CA certificate, subordinate CA certificate, and end-entity certificate) to systems that need to verify your signatures.
Signing artifacts with ML-DSA in your CI/CD pipeline
With the PKI hierarchy in place, integrate ML-DSA signing into your build process. The approach depends on artifact type. ML-DSA-65 signatures are 3,309 bytes (compared to 64 bytes for ECDSA P-256), and the latency of the AWS KMS Sign operation for ML-DSA is comparable to existing asymmetric operations. The larger signature size has negligible impact when stored alongside multi-megabyte container images or packages, but is worth accounting for in size-constrained environments like embedded device images transmitted over low-bandwidth links.
Binary and package signing
Most build outputs, including compiled binaries and packages, are far larger than the 4,096-byte limit that AWS KMS places on the message passed to aws kms sign. Make the EXTERNAL_MU method your pipeline’s default: compute the 64-byte message representative (mu) externally with OpenSSL 3.5, then pass only mu to AWS KMS. This handles an artifact of any size and never needs to change as your artifacts grow. AWS KMS also accepts content directly with --message-type RAW, up to 4,096 bytes. Use RAW only for inputs whose size is fixed by construction, such as the 71-character manifest digest in the container image example that follows. An artifact that fits today is likely to outgrow the limit later, and a pipeline that depends on RAW fails when it does. Both methods produce cryptographically identical signatures. The verifier doesn’t need to know which method was used; standard ML-DSA verification applies in either case.
# Retrieve the public key
aws kms get-public-key --key-id alias/pqc-code-signing \
  --query PublicKey --output text | base64 --decode > pk.der

# Extract raw public key bytes from the DER-encoded SubjectPublicKeyInfo.
# The BIT STRING starts at offset 17 for all ML-DSA key sizes.
# Expected output: 1,312 bytes (ML-DSA-44), 1,952 bytes (ML-DSA-65), or 2,592 bytes (ML-DSA-87).

openssl asn1parse -inform DER -in pk.der -strparse 17 -noout -out pk_raw.bin

# Compute mu per FIPS 204 Section 6.2
printf '\x00\x00' | cat - artifact.bin > m_prime.bin
openssl dgst -shake256 -xoflen 64 -binary pk_raw.bin > pk_hash.bin
cat pk_hash.bin m_prime.bin | openssl dgst -shake256 -xoflen 64 -binary > mu.bin

# Sign the mu value
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > artifact.bin.sig
Store the .sig file alongside the artifact in Amazon S3 or your package repository. Protect the integrity of both the artifact and its signature by enabling S3 Object Lock (WORM protection) or at minimum S3 Versioning with restricted write access. If an attacker can modify or delete either file, verification can’t be trusted. For comprehensive guidance, see Security best practices for Amazon S3.
Container image signing
For container image signing, use the OCI referrer pattern, defined in the OCI Image and Distribution Specifications v1.1. A referrer is an artifact, such as a signature or an SBOM, whose manifest names another image in its subject field. Registries that support the pattern, including Amazon ECR, return these artifacts when a client asks for an image’s referrers. This approach uses AWS KMS ML-DSA keys to generate the signature and stores it as a referrer of the image:
# Repository URI used by ORAS here and in the SBOM steps; replace the account ID and Region
ECR_URI=111122223333.dkr.ecr.us-east-1.amazonaws.com/myapp

# Authenticate ORAS to Amazon ECR
aws ecr get-login-password --region us-east-1 | \
  oras login --username AWS --password-stdin 111122223333.dkr.ecr.us-east-1.amazonaws.com

# Get the image manifest digest
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)

# Sign the digest. It is a fixed 71 characters, so RAW is safe here (see Binary and package signing).
# AWS CLI v2 expects blob parameters to be base64, so write the digest to a file and pass it with fileb://
echo -n "$IMAGE_DIGEST" > digest.txt
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://digest.txt \
  --message-type RAW \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > image.mldsa.sig

# Attach signature as OCI referrer using ORAS
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" \
  image.mldsa.sig:application/octet-stream
At deployment time, your admission controller retrieves the referrer artifact and verifies the ML-DSA signature before allowing the image to run. See Verifying a container image signature before deployment later in this post for the full verification workflow and admission control implementation.
SBOM signing
A software bill of materials (SBOM) is a structured inventory of every component, library, and dependency included in a software release. It lists package names, versions, suppliers, and dependency relationships. Organizations use SBOMs to track vulnerabilities, verify license compliance, and respond quickly when a compromised component is disclosed.
Signing the SBOM file on its own proves that the inventory hasn’t been tampered with since it was signed, but not which artifact it describes. If the image signature and the SBOM signature are independent of each other, an attacker who holds a legitimately signed SBOM for a clean image can present it alongside a different signed image and claim that the two correspond. Attaching the SBOM to the image as an OCI referrer doesn’t close this gap by itself, because the subject field of a referrer manifest is set by whoever pushes the referrer; it’s a discovery mechanism, not a cryptographic binding. The binding must be inside the bytes that the signature covers.
To create that binding, wrap the SBOM in an in-toto Statement before signing it. A Statement names the artifacts it describes in its subject field, by digest, and carries the SBOM as its predicate. Because the image manifest digest is part of the signed content, a verifier can confirm that the SBOM in hand was issued for exactly the image it is about to deploy, and a swapped SBOM or a swapped digest fails verification. Embedding the SBOM in the image filesystem is another way to bind the two, because the image digest then covers the SBOM bytes. This post uses the Statement approach because it also works for SBOMs generated by scanning a finished image, for artifacts that have no filesystem such as binaries and firmware, and for images that are already in your registry, and because the SBOM stays readable from the registry without pulling the image.
Generate the SBOM with your preferred tool (such as Amazon Inspector SBOM Generator (Sbomgen) for container images), wrap it in a Statement, and sign the Statement with the same EXTERNAL_MU step you use for binaries:
# Scan the pushed image by digest so the inventory describes exactly the manifest you signed.
# Sbomgen reuses the registry login from the oras login step in the previous section.
inspector-sbomgen container --image $ECR_URI@$IMAGE_DIGEST -o sbom.json

# Wrap the SBOM in an in-toto Statement whose subject is the image manifest digest.
# This puts the digest inside the signed bytes, which binds this SBOM to this image.
jq -n \
  --arg name "$ECR_URI" \
  --arg digest "${IMAGE_DIGEST#sha256:}" \
  --slurpfile sbom sbom.json \
  '{
    "_type": "https://in-toto.io/Statement/v1",
    "subject": [{"name": $name, "digest": {"sha256": $digest}}],
    "predicateType": "https://cyclonedx.org/bom",
    "predicate": $sbom[0]
  }' > sbom.statement.json

# Sign using EXTERNAL_MU (same mu computation as binary signing above,
# with sbom.statement.json as the input)
# ... compute mu from sbom.statement.json ...
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > sbom.statement.json.sig

# Attach the Statement and its signature to the image as an OCI referrer so
# verifiers discover them alongside the image signature
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" \
  sbom.statement.json:application/vnd.in-toto+json \
  sbom.statement.json.sig:application/octet-stream
Ship the Statement and its .sig file together; the SBOM itself is the Statement’s predicate field, and verifiers extract it after verification. The same pattern binds an SBOM to a binary or package: set the subject digest to the SHA-256 of the file instead of an image manifest digest. The Verifying a binary or SBOM signature section later in this post walks through the full verification workflow, including the subject check that completes the binding.
Quantum-resistant workload identity for build agents
Signing artifacts with ML-DSA keys addresses the integrity of the artifacts themselves. Separately, build agents running outside AWS (on-premises Jenkins, self-hosted GitHub Actions runners, or third-party CI/CD systems) authenticate using X.509 certificates or OIDC tokens typically signed with RSA or ECDSA. These authentication credentials represent a classical cryptographic dependency in the pipeline. IAM Roles Anywhere with ML-DSA certificates replaces that dependency: the credential that the external build agent presents, and the CA that vouches for it, no longer rely on algorithms that are vulnerable to quantum attack. (The TLS connection that carries the request still authenticates the AWS endpoint with a traditional certificate, as public TLS does today; that is a transport concern separate from the signing identity this post is about.) Build agents running on AWS with an attached IAM role don’t have this dependency: their API requests are authenticated with AWS Signature Version 4 (SigV4), which uses a symmetric hash-based message authentication code (HMAC-SHA256). Symmetric schemes like this are already considered quantum-resistant, so no additional action is needed.
Step 1: Register a workload identity CA as a trust anchor
For this walkthrough, reuse the subordinate CA that you created earlier; that avoids the monthly charge for a second CA, and the commands that follow assume it. In production, use a dedicated subordinate CA for workload identity certificates, separate from your code-signing CA. This limits the blast radius if either CA is compromised and has to be revoked, and it lets you apply different issuance policies to the two certificate types.
# Use the ARN that create-certificate-authority returned when you created the
# subordinate CA earlier. If you no longer have it, list your CAs and copy the
# ARN of the SUBORDINATE one.
aws acm-pca list-certificate-authorities \
  --query "CertificateAuthorities[?Type=='SUBORDINATE'].[Arn,Status,CertificateAuthorityConfiguration.Subject.CommonName]" \
  --output table
SUB_CA_ARN=arn:aws:acm-pca:us-east-1:111122223333:certificate-authority/abc-123   # replace with yours

# Register the subordinate CA as an IAM Roles Anywhere trust anchor
aws rolesanywhere create-trust-anchor \
  --name "PQC-CI-CD-Trust-Anchor" \
  --source "sourceType=AWS_ACM_PCA,sourceData={acmPcaArn=$SUB_CA_ARN}" \
  --enabled
Step 2: Create the build agent role and a profile that references it
An IAM Roles Anywhere profile specifies which IAM roles a workload can assume after it authenticates with a certificate from your trust anchor. Create the role first. Its trust policy lets IAM Roles Anywhere assume it only through your trust anchor and only for a certificate whose subject common name identifies the build agent; without those conditions, any certificate that the trust anchor CA issues could assume the role. Its permissions policy grants only what signing requires, on only the code-signing key. Save the trust policy as build-agent-trust.json, replacing the trust anchor ARN with the one that create-trust-anchor returned in Step 1:
Save the permissions policy as build-agent-permissions.json, replacing the resource with your key’s ARN (aws kms describe-key --key-id alias/pqc-code-signing --query KeyMetadata.Arn --output text):
Step 3: Issue the build agent certificate and configure the credential helper
Generate the build agent’s ML-DSA-65 key pair and CSR locally with OpenSSL, have the subordinate CA issue a client authentication certificate for it, and then configure the IAM Roles Anywhere credential helper to present that certificate:
# Generate the build agent's key pair and CSR. The CN must match the
# aws:PrincipalTag/x509Subject/CN condition in the role's trust policy.
openssl genpkey -algorithm ML-DSA-65 -out build-agent-mldsa-key.pem
chmod 400 build-agent-mldsa-key.pem
openssl req -new -key build-agent-mldsa-key.pem \
  -subj "/C=US/O=Example Corp/CN=pqc-build-agent-01" \
  -out build-agent.csr

# Issue a 30-day client authentication certificate from the subordinate CA
# registered as the trust anchor in Step 1.
BUILD_AGENT_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --csr fileb://build-agent.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=30,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/EndEntityClientAuthCertificate/V1 \
  --query CertificateArn --output text)

aws acm-pca get-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --certificate-arn $BUILD_AGENT_CERT_ARN \
  --query Certificate --output text > build-agent-mldsa.pem

# In production, store the private key in a TPM or HSM rather than as a plaintext file.
aws_signing_helper credential-process \
  --certificate build-agent-mldsa.pem \
  --private-key build-agent-mldsa-key.pem \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111122223333:trust-anchor/ta-id \
  --profile-arn arn:aws:rolesanywhere:us-east-1:111122223333:profile/profile-id \
  --role-arn arn:aws:iam::111122223333:role/PQCBuildAgentRole
The helper produces short-lived AWS Security Token Service (AWS STS) credentials scoped to the build role, replacing long-lived AWS access keys. In production, protect the ML-DSA private key with hardware-backed storage such as a Trusted Platform Module (TPM), an HSM, or an encrypted credential store with restricted file permissions. The plaintext file path shown here is for demonstration purposes. The private key authorizes access to your code-signing infrastructure and should be treated with the same protection level as any signing key. On Linux build agents, at minimum restrict the file to chmod 400 owned by the service account and consider using a PKCS#11 provider to avoid storing the raw key on disk entirely.
Verification and policy enforcement
A signing architecture is only as strong as its verification. Producing signatures is half the story. The other half is giving the systems and people that deploy your artifacts, such as deployment pipelines, Kubernetes admission controllers, and engineers installing a package, a concrete way to verify those signatures and make trust decisions before an artifact is deployed or run.
Distributing your trust chain
Before any verifier can check a signature, it needs to trust the CA that issued the code-signing certificate. This trust is established through a trust store: a local collection of root CA certificates that a system treats as authoritative. Trust stores exist in operating systems (such as /etc/pki/ca-trust/ on Linux, Keychain on macOS), language run-times (Java cacerts), container base images, and custom application configurations.
For private PKI hierarchies like the one in this post, your root CA certificate isn’t in any default public trust store. You must explicitly add it to the trust stores of every system that will verify your signatures. Common approaches include:
Baking the root CA certificate into your container base images during the build process
Publishing it to an internal S3 bucket with versioning and access logging
Storing it as an OCI artifact in Amazon ECR alongside the images it protects
Treat trust store management with the same rigor as credential management. If an attacker can inject a rogue root certificate into your trust stores, they can make forged signatures appear valid. Restrict write access to trust stores and audit changes through AWS CloudTrail or your system-level audit logs.
Exporting your certificate chain requires exporting the root CA, and then any subordinate CAs that issue certificates that will be involved in verifying signatures:
# Export the root CA certificate
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --query Certificate --output text > root-ca.pem

# Export the subordinate CA certificate. Select only the Certificate field: for a
# subordinate CA this call also returns CertificateChain, and --output text would
# print both on one tab-separated line, producing a file that OpenSSL can't parse.
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --query Certificate --output text > sub-ca.pem

# Bundle the full chain for verifiers
cat root-ca.pem sub-ca.pem > trust-chain.pem
Verifiers use this chain to confirm that the code-signing public key was issued by a CA they trust.
The CAs in this post are created without a revocation configuration, and the verification commands that follow don’t check revocation status, which keeps the walkthrough short. In production, configure a certificate revocation list (CRL) or an Online Certificate Status Protocol (OCSP) responder on the subordinate CA (see Plan your AWS Private CA certificate revocation method in the AWS Private CA User Guide; both work with ML-DSA CAs). If you use a CRL, distribute it alongside the trust chain and add -crl_check -CRLfile <crl-file> to the openssl verify command below, where <crl-file> is the CRL that AWS Private CA publishes to your S3 bucket, so that a revoked code-signing certificate fails verification.
Verifying a binary or SBOM signature
Verify the code-signing certificate against the trust chain, confirm that it is a code-signing certificate issued to the signer you expect, extract its public key, and then verify the signature with OpenSSL 3.5. The second check matters: a chain check alone accepts every certificate that the CA hierarchy has issued, including the build agent client certificates from the previous section, so pin the expected subject in your verifier configuration:
# Step 1: Verify that the code-signing certificate chains to the trusted root CA and carries the
# Code Signing extended key usage. -purpose codesign (OpenSSL 3.2 and later) rejects a certificate
# that chains correctly but was issued for another purpose, such as a build agent's client
# authentication certificate from the same subordinate CA.
# trust-chain.pem contains the root CA and subordinate CA certificates distributed in the previous section.
openssl verify -CAfile trust-chain.pem -purpose codesign code-signing-cert.pem
# Confirm that the certificate was issued to the signer you expect. Replace <signer-cn> with the
# common name in your code-signing certificate's subject.
openssl x509 -in code-signing-cert.pem -noout -subject -nameopt RFC2253 | grep -q "CN=<signer-cn>" || { echo "Unexpected signer"; exit 1; }

# Step 2: Extract the public key from the verified certificate.
openssl x509 -in code-signing-cert.pem -pubkey -noout > signing-key.pem

# Step 3: Verify the artifact signature using the trusted public key.
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in artifact.bin \
  -sigfile artifact.bin.sig \
  -rawin
A successful verification prints Signature Verified Successfully and returns an exit status of 0. A failed verification prints Signature Verification Failure and returns a nonzero exit status. In shell scripts, check the exit status of each command, or run the block with set -e, so that a failed certificate chain check stops the script before signature verification and a failed signature check blocks downstream actions.
For an SBOM, run the same three steps with sbom.statement.json as the -in file and sbom.statement.json.sig as the -sigfile, then add a fourth: confirm that the subject digest inside the verified Statement is the digest of the artifact you are about to deploy. Signature verification proves the Statement is authentic; the subject check proves it describes this artifact and not another one. The digest you compare against must come from the artifact itself, resolved from the registry for an image or computed from the file for a binary, never from the Statement. For an image, this is the same digest you verify the image signature against, so the two checks together establish that this SBOM describes this signed image.
# Step 4 (SBOM only): the signed Statement must name the image being deployed.
# Resolve the digest from Amazon ECR, not from the Statement.
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)
SUBJECT_DIGEST=$(jq -r '.subject[0].digest.sha256' sbom.statement.json)
[ "sha256:$SUBJECT_DIGEST" = "$IMAGE_DIGEST" ] || { echo "SBOM does not describe this image"; exit 1; }

# Only now extract the SBOM for downstream tooling
jq '.predicate' sbom.statement.json > sbom.json
For a binary, compare the subject digest to the output of sha256sum artifact.bin instead. Reject the SBOM if either the signature or the subject check fails.
Verifying a container image signature before deployment
Pull the ML-DSA signature from the OCI referrer artifact in Amazon ECR, then verify it against the image manifest digest:
# Pull the signature referrer. ORAS 1.2 lists referrers under "manifests";
# ORAS 1.3 and later list them under "referrers". The jq filter accepts either.
oras discover $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" --format json | \
  jq -r '(.referrers // .manifests)[0].digest' | \
  xargs -I{} oras pull $ECR_URI@{} -o /tmp/sig/

# Re-derive the image digest and verify
echo -n "$IMAGE_DIGEST" > /tmp/digest.txt
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in /tmp/digest.txt \
  -sigfile /tmp/sig/image.mldsa.sig \
  -rawin

# Exit code 0 = image is authentic; non-zero = reject deployment
The same oras discover command with --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" retrieves the SBOM attestation and its signature; verify them as described in the previous section, including the subject check. The jq filter shown takes the first referrer of the requested type. Don’t rely on the order in which a registry lists referrers, and expect more than one after an image has been re-signed: a production verifier should check every referrer of that type and accept the image if at least one signature verifies against a certificate that chains to your trust store. Taking only the first can reject a correctly signed image, but it can never accept an unsigned one.
To enforce these checks at deployment time, run them in a Kubernetes admission controller, a component that the API server calls before it accepts a pod and that can reject the request. You can write one as a validating admission webhook (see Dynamic Admission Control in the Kubernetes documentation), or use Open Policy Agent (OPA) Gatekeeper, an admission webhook that enforces policies evaluated by the OPA policy engine, and package the verification steps as a Gatekeeper external data provider that a constraint calls. For a worked example of gating Amazon EKS deployments on image signatures, see Announcing Container Image Signing with AWS Signer and Amazon EKS, which verifies AWS Signer signatures at admission with Kyverno and discusses the Gatekeeper and custom webhook alternatives. The ML-DSA signature referrer in this post is a custom artifact type that those tools don’t verify out of the box, so the verification steps in this section run in code you supply. In either design, the controller runs before any pod is scheduled, rejecting images that lack a valid ML-DSA signature referrer in Amazon ECR or whose SBOM attestation doesn’t name the image being deployed.
Preventive and detective controls
Signature verification stops the use of an untrusted artifact at deployment. Organization-level controls apply earlier and more broadly: preventive controls stop teams from creating new traditional signing keys, and detective controls record every signing operation so you can audit which principal signed each artifact and when.
Preventive guardrails. Use an AWS OrganizationsService control policy (SCP) to block creation of traditional signing keys in security-critical accounts, forcing all new signing workloads to use ML-DSA:
This SCP prevents teams from creating new RSA or ECDSA signing keys, enforcing quantum-resistant signatures as the only option for new workloads. Note that this SCP constrains the algorithm family, not the parameter set: it would still permit an ML-DSA-44 key, which this architecture doesn’t use. Part 2 of this series picks up at exactly this point. It shows how to express a complete algorithm policy (in its example, approve ML-DSA-65 and ML-DSA-87 and exclude ML-DSA-44) as layered controls using the kms:KeySpec condition key in SCPs, IAM permission boundaries, and AWS KMS key policies; how to restrict the use of keys that already exist; and how to govern surfaces such as AWS Private CA that have no algorithm condition key. This SCP and the parameter-set SCP in Part 2 work together: attach both, and every new signing key must use an approved parameter set.
Audit trail.AWS CloudTrail logs every kms:Sign and kms:Verify API call, providing an immutable record of when each artifact was signed and by which principal. Use an organization trail and query its logs with Amazon Athena to analyze signing activity across accounts and correlate it with your deployment events.
Regulatory timeline and recommended actions
The following table maps regulatory milestones to specific actions you can take today using the architecture described in this post. This information is provided for general awareness only and does not constitute legal or compliance advice. Consult your legal and compliance teams to determine your organization’s specific obligations. For a broader overview of global PQC regulatory timelines, see Migrating to Post-Quantum Cryptography.
Regulation
Deadline
Regulatory language
Action on AWS
CNSA 2.0: Support and prefer
2025 (in effect)
CNSA 2.0 timeline (Sep 2022, FAQ v2.1 Dec 2024): Software and firmware signing must “support and prefer” CNSA 2.0 algorithms by 2025
Create ML-DSA keys in AWS KMS, begin signing artifacts with ML-DSA alongside existing traditional signatures
CNSA 2.0: New system acquisitions
January 2027
CNSA 2.0 FAQ v2.1 (Dec 2024): “All new NSS acquisitions must be CNSA 2.0 compliant at deployment, effective 1 January 2027”
Full ML-DSA PKI operational, IAM Roles Anywhere trust anchors using ML-DSA, all new builds carry ML-DSA signatures
EU Cyber Resilience Act
11 December 2027
Regulation (EU) 2024/2847, Annex I, Part I(2)(f): Products must “protect the integrity of stored, transmitted or otherwise processed data, personal or other, commands, programs and configuration against any manipulation or modification not authorised by the user, and report on corruptions”; Part II(7): Manufacturers must “provide for mechanisms to securely distribute updates”
ML-DSA code signing for all software updates shipped to EU markets, signed SBOMs accompany every release
CNSA 2.0: Exclusive use
2030
CNSA 2.0 timeline: Software and firmware signing must “exclusively use” CNSA 2.0 algorithms by 2030
Remove traditional signing keys from supply chain, SCP enforcement of ML-DSA-only key creation
PCI DSS 4.0 Req 12.3.3
Mandatory since March 2025
PCI DSS v4.0.1, Requirement 12.3.3: “Cryptographic cipher suites and protocols in use are documented and reviewed at least once every 12 months”, including an up-to-date inventory of the cipher suites and protocols in use
Document cryptographic inventory in AWS KMS, tag ML-DSA versus traditional keys, maintain migration progress tracking
Note for NSS customers and other CNSA 2.0 adopters: CNSA 2.0 is the quantum-resistant algorithm suite that the NSA requires for NSS, the federal systems that carry classified information or support intelligence, cryptologic, military command and control, and weapons functions. When ML-DSA is used for any signature purpose, including software and firmware signing, CNSA 2.0 permits only the ML-DSA-87 parameter set. (For software and firmware signing it also approves the stateful hash-based schemes LMS and XMSS, which this post doesn’t cover.) The ML-DSA-65 parameter set used in this post’s code-signing examples is appropriate for commercial workloads but isn’t permitted on NSS. CNSA 2.0 is binding only for NSS, but it’s followed voluntarily well beyond that boundary: by suppliers to the US defense and intelligence market, in the United States and allied countries, whose products must meet NSS requirements, and by commercial organizations in and outside the United States that adopt it as a conservative baseline because it specifies the highest NIST security category and removes the need to revisit parameter choices later. If your systems fall under CNSA 2.0 scope, or you’ve chosen to align with it, substitute ML-DSA-87 for all signing keys and certificates. Part 2 of this series shows how to make that substitution enforceable: the same kms:KeySpec controls that exclude ML-DSA-44 in its example can be pointed at ML_DSA_87 as the only approved key spec.
For organizations serving both US government and EU commercial markets, the January 2027 and December 2027 deadlines converge into a single migration window. Starting now provides margin for testing, key rotation planning, and certificate chain validation.
Clean up
You created a number of cryptographic resources in the prior steps and examples. AWS Private CA charges a monthly fee per CA and AWS KMS charges per key per month. To avoid ongoing charges, delete them if you aren’t actively using them. Start by listing what exists, so that you catch every resource you created, including duplicates from repeated runs. These commands list one Region; if you worked in more than one, repeat them with --region for each.
# List every private CA with its type, status, key algorithm, and subject.
# A CA you already deleted shows DELETED until its restoration window ends.
aws acm-pca list-certificate-authorities \
  --query 'CertificateAuthorities[].[Arn,Type,Status,CertificateAuthorityConfiguration.KeyAlgorithm,CertificateAuthorityConfiguration.Subject.CommonName]' \
  --output table

# List every ML-DSA key in AWS KMS with its state and creation date.
# A key already scheduled for deletion shows PendingDeletion.
for KEY_ID in $(aws kms list-keys --query 'Keys[].KeyId' --output text); do
  aws kms describe-key --key-id "$KEY_ID" \
    --query 'KeyMetadata.[KeyId,KeySpec,KeyState,CreationDate]' --output text
done | grep ML_DSA

# Show which alias points at which key. A key that no alias points at
# is usually a leftover from an earlier run.
aws kms list-aliases --query 'Aliases[].[AliasName,TargetKeyId]' --output text | grep -v '^alias/aws/'
AWS Private CA has no command that lists the certificates a CA has issued. If you need serial numbers for the revocation step that follows, generate an audit report with aws acm-pca create-certificate-authority-audit-report, which writes a list of every certificate the CA has issued or revoked to an S3 bucket that grants the service write access.
Delete each resource that you don’t need, including any extra copies that the listing revealed, then run the listing again to confirm that nothing is left:
# Revoke any issued end-entity certificates while the subordinate CA is still active
aws acm-pca revoke-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-serial <serial-number> \
  --revocation-reason CESSATION_OF_OPERATION

# Delete the IAM Roles Anywhere resources that reference the CA
aws rolesanywhere delete-profile --profile-id <profile-id>
aws rolesanywhere delete-trust-anchor --trust-anchor-id <trust-anchor-id>

# Delete the build agent role that the profile referenced, and the local copy of its private key
aws iam delete-role-policy --role-name PQCBuildAgentRole --policy-name pqc-code-signing
aws iam delete-role --role-name PQCBuildAgentRole
rm -f build-agent-mldsa-key.pem

# Delete the AWS KMS code-signing key (schedule 7-day waiting period).
# ScheduleKeyDeletion doesn't accept an alias, so resolve the key ID first.
KEY_ID=$(aws kms describe-key --key-id alias/pqc-code-signing \
  --query KeyMetadata.KeyId --output text)
aws kms schedule-key-deletion --key-id $KEY_ID --pending-window-in-days 7

# Remove the alias. It survives key deletion and would otherwise show up in the
# listing above on your next run.
aws kms delete-alias --alias-name alias/pqc-code-signing

# Disable and delete the subordinate CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --permanent-deletion-time-in-days 7

# Disable and delete the root CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --permanent-deletion-time-in-days 7
If you are adapting this for long-term use, plan for log retention. CloudTrail Event History keeps only the last 90 days of management events and is not a substitute for a trail. For the audit trail described earlier, create a trail that delivers to an S3 bucket with the lifecycle policy and access controls your retention requirements call for.
Conclusion
In this post, I showed you how to build a quantum-resistant software supply chain on AWS by combining ML-DSA signing in AWS KMS, ML-DSA certificate hierarchies in AWS Private CA, and ML-DSA workload authentication through IAM Roles Anywhere. The architecture covers the full pipeline; from authenticated build agents through signed binaries, container images, and SBOMs, to verification and policy enforcement at deployment.
Every ML-DSA capability used in this post is generally available. AWS Private CA and IAM Roles Anywhere support ML-DSA in all commercial AWS Regions, the AWS GovCloud (US) Regions, and the China Regions, and AWS KMS supports ML-DSA in commercial AWS Regions. You don’t need to wait for a standards body or third-party tool to finalize PQC support. The primitives are ready.
To get started, create your first ML-DSA key in AWS KMS and sign a test artifact. From there, extend to your PKI hierarchy, integrate IAM Roles Anywhere for your build agents, and add ML-DSA signatures to your container and SBOM workflows.
Building the pipeline is half the work. The other half is making sure the algorithm choices you made stay in force as accounts, teams, and standards change. That’s the subject of Part 2 of this series, Enforce your ML-DSA algorithm policy with SCPs and IAM, written for the security and governance teams who own that problem.
If you run a website, you’ve already met encryption even if you’ve never used the word. It’s the 🔒 padlock in the browser bar, the reason your host told you to stop using plain FTP, and the checkbox on your backup settings that says “encrypt archive.”
Encryption is one of the few security controls that works quietly and almost never needs your attention, which is exactly why it’s easy to misunderstand. Plenty of site owners install an SSL certificate, see the padlock appear, and assume the site is now “secure.” That’s the gap we want to close here.
This post shows you how to configure an AI model to perform structured, evidence-based vulnerability triage with the consistency of a seasoned security analyst. You’ll learn the design decisions behind five configuration sections that enforce structural verification, evidence-based scoring, and infrastructure-aware prioritization across every analysis session. Our companion post—Building your AI vulnerability harness—covered the architecture; this post covers the configuration.
The distinction matters because the same frontier model that produces a rigorous, evidence-grounded security assessment with one set of instructions will produce hallucinated attack chains and inflated severity ratings with another. The model’s capability is fixed. What you configure is its judgment.
We learned this the hard way while building the harness. Our early iterations produced findings that sounded authoritative but crumbled under scrutiny. The model would report a SQL injection in a function that didn’t exist, claim HIGH confidence based on nothing structural, or ignore an AWS WAF in blocking mode directly in the request path. The output wouldn’t have earned engineering trust in that state.
The fix wasn’t a better model. It was better steering.
What a steering file is
A steering file is a set of instructions that an AI coding assistant loads at the start of every session. Different tools use different conventions—Kiro reads markdown files from a .kiro/steering/ directory, Claude Code uses CLAUDE.md, Cursor uses .cursorrules, and GitHub Copilot uses .github/copilot-instructions.md—but the function is the same: persistent instructions that shape how the model approaches work in your repository.
Applied to security analysis, a steering file encodes your team’s triage methodology as machine-executable instructions. Instead of relying on individual engineers to apply that methodology consistently, you encode it once and the model applies it uniformly across analyses.
The steering file we’re releasing encodes the architectural principles from the harness post as operational instructions. Where the harness post says apply infrastructure-aware assessment, the steering file specifies exactly how: which controls map to which multipliers, how multipliers stack, and what floor prevents over-confidence in any single control.
Why configuration outperforms prompting
A single-turn prompt (find vulnerabilities in this code) produces whatever the model’s default behavior generates. That default is optimized for helpfulness, not rigor. The model will find things to report because you asked it to find things.
A steering file changes the default. It establishes:
What counts as evidence: Without explicit instructions, a model treats its own reasoning as sufficient evidence. The steering file requires structural verification—confirmed dataflow, confirmed function existence, and confirmed call path—before a finding is reported.
What confidence means: On its own, a model assigns confidence based on how plausible its narrative sounds to itself. The steering file replaces self-reported confidence with a formula computed from binary structural signals. Either taint analysis confirms the flow or it doesn’t. Either a call graph connects entry point to sink or it doesn’t.
How infrastructure affects priority: Left to its defaults, a model assesses vulnerabilities in isolation from their deployment context. The steering file requires parsing infrastructure as code (IaC) and applying control-specific multipliers before assigning priority.
The goal is reproducibility: the same codebase should produce the same assessed findings regardless of who runs the analysis or when. Consistency is the point.
The five sections that matter
The full steering file is available in the companion repository. In this section, we explain the design decisions behind its five critical sections.
Structural verification over LLM trust
Never trust an LLM's self-reported confidence about a vulnerability.
Verify claims against the code structure:
1. Do referenced files exist?
2. Do referenced functions exist?
3. Does dataflow confirm the claim?
4. Is there a call path?

If a finding fails all structural checks, reject it regardless of how
convincing the narrative sounds.
This is the single most important instruction in the file. Without it, the model generates plausible-sounding attack chains that reference functions that were renamed three commits ago, files that exist in a different package, or dataflows that pass through sanitization that the model failed to notice.
We found that approximately 30% of unsteered model findings referenced code structures that didn’t exist in the target repository. Not wrong interpretations—entirely fabricated paths. The instruction to verify before reporting produced zero fabricated paths in our testing.
The key insight: hallucination in security analysis isn’t a minor annoyance. One hallucinated finding that reaches a developer destroys the can quickly erode the credibility of your entire pipeline. Engineers who encounter a fabricated vulnerability are less likely to keep reading the reports.
Evidence-based confidence scoring
The following formula replaces the model’s intuitive confidence with a score computed from observable signals. Each factor is binary: confirmed or not confirmed.
We weighted taint confirmation highest (0.30) because a confirmed dataflow path—evidence that user-controlled data reaches a security-sensitive operation—is the single strongest predictor that a finding is real. In our validation against known-vulnerable applications, findings with confirmed taint and no sanitization were exploitable 89% of the time. Findings where the model reported HIGH confidence without structural confirmation were exploitable 34% of the time.
The formula is a starting point, not a fixed standard. Your weights should reflect your own validation data. Run the formula against a labeled dataset of known true and false positives, then adjust until precision matches your team’s tolerance for noise.
Infrastructure-aware assessment
This section addresses a common category of over-prioritization: reporting a vulnerability at full severity when compensating controls are already in place.
Controls are mapped to specific vulnerability classes. An AWS WAF with SQL injection rules in blocking mode is a STRONG control (0.25x multiplier) against SQL injection. It is irrelevant to deserialization attacks. The steering file specifies this mapping explicitly rather than leaving the model to guess.
The multiplicative stacking of attack-blocking controls with a floor of 0.15 encodes defense-in-depth thinking. Multiple controls reduce risk more than any single control, but no combination of controls reduces risk to zero. The floor prevents the model from concluding that a vulnerability is completely mitigated and can be ignored.
A subtlety we learned through validation: access controls (authentication and authorization) and attack-blocking controls (AWS WAF rules and input validation) serve different functions. Authentication limits who can attempt an exploit. It doesn’t limit what happens when an authenticated user attempts one. A command injection behind AWS Identity and Access Management (IAM) authentication is still a command injection; the attacker pool is smaller, but the impact when exploited is unchanged. The steering file accounts for this by mapping control types to specific score components rather than applying a blanket multiplier.
The following table lists the primary signals the steering file recognizes and the boost that each signal adds to a finding’s score. Each signal answers a different question about real-world exploitation risk:
CISA KEV – Indicates that attackers have exploited the vulnerability in the wild and notes whether it is tied to ransomware campaigns.
EPSS – Estimates the probability that attackers will exploit a vulnerability in the next 30 days.
Public proof of concept (PoC) – Indicates that working exploit code is already published, so an attacker has little work left to do.
Signal
Boost
Actively exploited (CISA KEV)
+0.30
Ransomware-associated (CISA KEV)
+0.15
EPSS >= 0.5
+0.20
Public PoC exists
+0.10
There’s a cap at +0.50 total boost to prevent threat intelligence from dominating the score. A vulnerability isn’t more technically exploitable because attackers are targeting it, but it is more urgent because the window between theoretically exploitable and actively exploited can be very short.
We separate urgency from severity deliberately. A medium-severity dependency vulnerability under active exploitation by ransomware groups demands a faster response than a critical-severity code-level finding that requires complex preconditions and has no known tooling.
Priority classification
Scoring produces a number and priority classification turns that number into a decision, which is what a developer on the receiving end of a finding needs.
The following table shows the four action tiers that the steering file defines. The score and evidence thresholds determine which tier a finding falls into, and each tier prescribes a specific response. The steering file compares these thresholds against the final score: the base score after it applies attack-blocking multipliers and any threat-intelligence boost. That final score is not the confidence value from the formula earlier in this post, and it is not the severity that the scanner reported.
Priority
Criteria
Action
P0
Score >= 0.8, no effective attack-blocking mitigation
Fix immediately
P1
Score >= 0.6 OR active threat intel
Fix this sprint
P2
Score >= 0.4, partial evidence
Investigate when capacity
P3
Score < 0.4 or effectively mitigated
Accept risk or backlog
The most controversial instruction in the file: Do not file P3 findings as security issues. We include it because filing low-confidence or fully mitigated findings as tickets trains teams to ignore security tooling. Each false positive or irrelevant finding filed as a bug reduces engagement with the system’s output. A pipeline that produces ten confirmed findings gets more engineering attention than one that produces two hundred maybes.
Validation results
We tested the steering file against a purpose-built vulnerable application containing ten known vulnerabilities: eight exploitable and two mitigated by infrastructure controls. The application includes an AWS WAF with SQL injection rules in blocking mode, Amazon Virtual Private Cloud (Amazon VPC)-isolated AWS Lambda functions, and IAM authentication on each endpoint.
Without the steering file, the model found all ten vulnerabilities and correctly identified both mitigated findings as lower priority. However, it assigned severity based on intuition (this is a command injection, so it’s CRITICAL) rather than evidence, and it produced no structural verification of its claims.
With the steering file, the model found nine of ten vulnerabilities (not flagging a hardcoded credential that had been intentionally embedded in unit-testing code and was defined but never called), correctly downgraded the two mitigated findings to P3 with documented rationale, showed its confidence calculation for each finding, and verified each claimed dataflow against the actual code.
The scoring calibration required one iteration. Our initial version applied authentication as a blanket multiplier that suppressed all findings behind IAM to P2 regardless of impact. We corrected this by separating access-limiting controls (which reduce the reachability score component) from attack-blocking controls (which reduce the full confidence score). The current version correctly classifies a command injection behind IAM authentication as P0: the auth limits who can reach it, but the impact when exploited is remote code execution regardless.
How to use the steering file
The three options that follow cover an always-on Kiro steering file, the same content as an on-demand Kiro skill, and how to carry the same content to Claude Code or another assistant.
Option 1: As a Kiro steering file
Drop the steering file into your repository at .kiro/steering/vuln-triage.md. Any session using Kiro’s built-in default agent loads the instructions automatically. When you or your engineers ask the model to analyze code for security issues, it applies the methodology without additional prompting.
If your team uses a custom agent rather than the default, steering files aren’t loaded automatically; you have to add the file to the agent’s resources explicitly:
You can also place it in ~/.kiro/steering/ to apply the methodology across every workspace on your machine, rather than scoping it to a single repository.
Option 2: As a Kiro skill
If you want the methodology available on demand rather than consuming context window space in every turn, place it as a skill. Kiro loads only the skill’s name and description at startup and pulls in the full instructions when the skill activates. This keeps the instructions out of unrelated conversations.
A skill is a folder containing a SKILL.md file. The folder name must match the name in the YAML front matter:
name: vuln-triage
description: Structured vulnerability triage methodology with evidence-based scoring and infrastructure-aware prioritization. Use when analyzing code for security vulnerabilities.
Kiro’s default agent discovers skills in .kiro/skills/ automatically; no configuration required. The skill then activates either automatically, when Kiro matches a request against the description, or explicitly as a slash command. A skill named vuln-triage becomes /vuln-triage, so an engineer can run an assessment on demand:
> /vuln-triage focus on the authentication changes
Place skills in ~/.kiro/skills/ to make them available across every project on your machine. If your team uses a custom agent rather than the default, skills aren’t loaded automatically, you must add them to the agent’s resources:
The methodology isn’t specific to Kiro. The repository also ships the same content as a CLAUDE.md file for Claude Code, and the principles apply to any assistant that loads persistent instructions from your repository—consult your tool’s documentation for the filename and location it expects.
What this doesn’t replace
A steering file is methodology, not machinery. It tells the model how to think about findings but doesn’t provide:
Programmatic taint tracking: The model approximates dataflow by reading code. A purpose-built taint tracker confirms dataflow against the abstract syntax tree (AST) deterministically. For Python codebases, static analysis tools built on parsers like Tree-Sitter provide this. For other languages, the model’s approximation is reasonable but not authoritative.
Live infrastructure verification: The steering file instructs the model to parse IaC files. It can’t make API calls to verify that an AWS WAF rule is attached to the Amazon API Gateway in your deployed environment, or that a security group hasn’t been modified since deployment.
Execution-based verification: The steering file produces assessed findings. Confirming exploitability by executing a proof of concept against a live environment requires additional tooling: a sandbox, request signing, and differential testing infrastructure.
Each of these capabilities adds confidence to the pipeline. The steering file without them still produces measurably better results than an unsteered model: structured findings, cited evidence, and infrastructure-aware prioritization. But it represents the first layer of a mature harness, not the complete system.
What comes next
The steering file gives your team a structured methodology for AI-powered vulnerability triage today. It works with the tools you already have. It works without infrastructure changes, new services, or a procurement process.
The steering file is available in our GitHub repository. We encourage you to use it, adapt it to your environment, and let us know what you find.
The authors work on security automation at AWS. The patterns described here emerged from building and validating AI-powered vulnerability detection systems across multiple teams and deployment environments.
If you have feedback about this post, leave a comment in the Comments section below.
Vulnerability scanners produce findings faster than manual triage can process them. Your developers ship more code with more dependencies, and the volume of candidate findings grows with it.
Many findings a scanner produces are unlikely to be exploited. The ones that matter need to reach an engineer fast, with enough evidence that they can act immediately rather than repeat the analysis. The challenge is separating signal from noise at the speed your pipeline demands.
This post shows you how to close the gap between detection and action. We built a three-layer pipeline that takes raw scanner findings and narrows them to a small, prioritized set with documented evidence of exploitability. The companion post, Configuring your AI vulnerability harness, will cover the steering file that drives the model’s behavior inside this pipeline. This post covers the layers around it.
Because the pipeline’s value comes from its filtering logic and evidence standards—not from any specific tool—you can substitute your own scanners and models without changing the architecture. Your AI provider, your infrastructure stack, and your scanner ensemble will differ from ours. The architectural decisions—what to filter at each layer, what counts as evidence, where to stop trusting the model—transfer regardless.
What a test harness is
A test harness is an automated framework that subjects a system to controlled inputs and observes whether outputs match expected behavior. Applied to vulnerability detection, the harness takes each candidate finding, constructs a test to evaluate exploitability, executes that test in a controlled environment, and records the evidence. The harness is the testing infrastructure, not the results it produces.
Traditional static application security testing (SAST) tools rely on pattern matching, with data-flow analysis varying by tool and language. They flag known-shape sinks well but struggle with multi-hop chains, business-logic flaws, context-dependent sanitization, and whether a sink is reachable from attacker-controlled input. AI-augmented analysis addresses that reasoning gap: tracing across files, inferring intent, and weighing deployment context.
The key conceptual distinction is that we don’t run a model against the codebase. The codebase is context passed to a model with a specific prompt. The model receives code and applies reasoning about how data flows, where trust boundaries exist, and whether security-relevant patterns are present.
Context scoping is one of the harder parts of this architecture because too much context can overwhelm the model’s reasoning window, while too little can produce analysis gaps that generate false negatives. For a basic AWS Lambda function, the relevant context might be a single file plus its AWS Identity and Access Management (IAM) role. For a complex microservice with shared libraries and layered infrastructure, deciding what to include requires understanding the application’s dependency graph. The model can reason about your deployment topology if you provide it; for example, by passing AWS Cloud Development Kit (AWS CDK) constructs or AWS CloudFormation templates as additional context. Starting narrow and expanding only when the model’s initial assessment is inconclusive generally produces better results than passing everything at once.
Building the pipeline
Security scanners can produce high volumes of findings each time they run. Many of these are false positives that look like vulnerabilities but aren’t real issues. To separate real problems from noise, the pipeline filters findings through three layers. Each layer applies a different type of evidence. By the end, a smaller number of prioritized issues backed by documented evidence remains.
Layer 1: Multi-scanner agreement
Plausibility comes first. Run multiple scanners independently against the same codebase: when two or more converge on the same finding, confidence increases. When only one scanner reports an issue and no other tool agrees, the pipeline flags that finding for extra scrutiny.
This approach—called multi-scanner agreement—is a low-cost way to increase confidence. It works with your existing tools and requires no new infrastructure.
Layer 2: Structural verification
The second layer verifies structure. AI-powered scanners describe how they think a vulnerability works: data enters through one function, passes through another, and reaches a point where it could cause harm. However, these descriptions can be wrong.
Before a finding moves forward, the pipeline verifies it against the actual code. It checks to see if the function that the scanner mentioned exists, that the file exists, and if data can flow along the path described by the scanner. If not, the pipeline rejects the finding.
This verification step uses the code’s abstract syntax tree (AST): a structured map of how functions, files, and data flows connect in your codebase. This step helps protect the credibility of your pipeline’s output. If unverified findings reach human reviewers, teams quickly learn to distrust the results, which reduces the security value of the tool.
Layer 3: Deployment context
The final layer adds deployment context. Vulnerabilities exist within the context of an architecture, which might include protective controls. These controls can include AWS WAF rules, network isolation, authentication requirements, and input validation.
This layer reads your infrastructure-as-code (IaC) templates—such as CloudFormation or Terraform files that define your cloud architecture—alongside your application source code. It then checks to see if an attacker can exploit a vulnerability by avoiding the controls that are in place.
Not all controls provide the same level of protection. A web application firewall rule that directly blocks the relevant attack technique provides stronger mitigation than one that addresses a different type of vulnerability. The pipeline treats control effectiveness as a spectrum, not a yes-or-no checkbox.
The result
The result is a short list of findings. Each one has cleared all three layers: it passed the plausibility check, its structure checks out against the code, and its deployment context indicates it can be taken advantage of. The number of findings decreases at each layer, and confidence in the remaining findings increases.
Principles
Four principles emerged from building this pipeline:
Progressive filtering with escalating evidence – Each layer demands a different kind of proof. The first layer checks that the finding is plausible. The second determines if it’s structurally real. The third analyzes if it’s exploitable in context. Using three focused layers works better than using one comprehensive layer, because each layer catches a different type of error.
Infrastructure context transforms prioritization – Without deployment context, you might assume that a critical-severity finding is more urgent than a medium-severity finding. However, a critical finding behind strong protective controls might be less urgent than a medium finding that’s directly exposed to the internet. To make this assessment, the pipeline needs access to your IaC templates, not only your application source code.
Independent agreement outperforms single-tool confidence – No single scanner reliably detects the full range of vulnerabilities. No single model produces correct results across all situations. When multiple independent tools agree on a finding, that agreement provides a stronger signal than one tool’s self-reported confidence score. This principle generally holds across tool choices.
AI-generated claims require verification before human review – Language models can produce outputs that sound plausible but might not be correct. Verifying AI-generated findings against the actual code structure—before a human reviews them—is what separates a useful system from one that erodes trust through confident-sounding errors.
How to apply this to your stack
You don’t need to build everything at once. Adopt them in order of immediate return:
Start with indexing – Build (or use) an AST-based index of your codebase that surfaces entry points, sinks, and authentication configuration. This costs nothing to run and gives you a map of your attack surface before any AI is involved.
Add multi-scanner triage – Take the output you already get from Semgrep, CodeQL, or equivalent tooling, and run it through the AST gate plus a large language model (LLM) exploitability classification. This delivers substantial noise reduction for a modest investment: you’re filtering output from tools you already run.
Add hypothesis generation – After triage is stable, add AI-driven discovery of vulnerabilities scanners miss: multi-hop chains, business-logic flaws, and cross-package data flows. This is the step where steering quality matters a great deal; see Configuring your AI vulnerability harness.
Add infrastructure context – Parse your CDK or CloudFormation, map controls to vulnerability classes, and apply the multipliers. This is where your prioritization becomes more targeted.
Add live verification – Run proofs of concept (PoCs) against a deployed pre-production target with structured success criteria. This step requires the most operational overhead, so run it last and only for findings that have already passed your confidence threshold.
Treat the pipeline as something you tune over time. Validate it against known true and false positives, adjust the weights, and rerun. Your results will change.
What this doesn’t solve
The harness is detection infrastructure. It helps you see which findings are likely real and which deserve attention first. It doesn’t:
Fix the code – Remediation is a separate problem. The harness produces findings with enough evidence that a human or agent can act on them; the act of remediation requires its own tooling and process.
Replace human review for final action – Even after three layers of filtering, the output is a prioritized list of likely-exploitable findings, not proven exploits. Priority 0 (P0) findings still warrant review by an engineer before they drive code changes.
Catch vulnerability classes outside the scanner ensemble’s detection profile – If none of your scanners look for a particular vulnerability category, the harness won’t surface it. AI-augmented hypothesis generation closes some of this gap, but novel or business-logic flaws still depend on what the model can reason about from code alone.
Verify live infrastructure state by default – Parsing IaC tells you what was defined. It doesn’t tell you whether a WAF rule got disabled last week, or whether a security group was modified after deployment. Live verification is an additional integration, not a property of the layers themselves.
Each of these limits points to where the architecture extends, not where it breaks. The harness is the first floor of a multi-story system, not the whole building.
What comes next
In this post, we showed how a three-layer pipeline—multi-scanner agreement, structural verification, and deployment context—narrows scanner output to a small, higher-confidence set of findings that your team can act on. The architecture is tool-agnostic; what transfers is where to filter, what counts as evidence, and when to stop trusting the model.
The architecture produces consistent results when the model receives consistent instructions. Our companion post, Configuring your AI vulnerability harness, covers the steering file that encodes this methodology as machine-executable instructions, including the confidence formula, the infrastructure control multipliers, and the verification gates that help prevent hallucinated findings from reaching your engineers. The same model that produces rigorous, evidence-grounded assessments with well-crafted instructions can produce inflated severity ratings and fabricated attack chains without those instructions. Configuration is what turns capability into judgment.
The window between disclosure and exploitation is narrowing. Embedding automated detection into your development workflows helps your team keep pace. We built this pipeline through trial and error and are sharing it so you can skip some of the mistakes we made.
The principle of least privilege is straightforward to articulate but challenging to maintain at scale. When teams first deploy applications to AWS, they often grant broader permissions than strictly necessary; it’s faster to get things working, and the plan is always to tighten permissions later. But later rarely comes. Permissions accumulate, AWS Identity and Access Management (IAM) principals that once needed broad access for initial deployment retain those permissions long after they’re necessary, and some principals stop being used entirely. Even small teams face this challenge—permission reviews aren’t a one-time task but an ongoing operational burden that demands automation.
AWS IAM Access Analyzer addresses detection and recommendation. It identifies unused permissions across IAM roles and users: actions that haven’t been exercised, services that haven’t been accessed, and principals that aren’t being assumed at all. For each finding, it generates a recommended policy with the excess permissions removed. Security teams can see exactly what to fix, but manual remediation doesn’t persist. A security engineer can right-size a role today, but if that role is defined in an AWS CloudFormation template or AWS Cloud Development Kit (AWS CDK) stack, the next deployment restores the original permissions. The fix must live where the role is defined, and not every role starts in the same place. Some are managed through infrastructure-as-code (IaC), where remediation means updating source code and deploying through a pipeline. Others were created manually through the AWS Management Console and have no code representation. And some principals aren’t being used at all and need a controlled decommission path. Each scenario requires a different remediation strategy.
This post walks through an automated remediation workflow that bridges the gap between detection and action. Instead of findings accumulating in a dashboard waiting for someone to investigate, the automation classifies each role by how it was created and produces a ready-to-review remediation artifact: a pull request with production-ready CDK code and a plain-English explanation for IaC-managed roles, an issue with the recommended policy and step-by-step IaC migration guidance for manually created roles, or a soft-disable issue with a monitored decommission plan for unused principals. Each output flows through your existing code review and issue tracking processes—the same workflows your teams already follow. By the end of this post, you’ll have a pattern that converts IAM Access Analyzer findings into tested, deployable code changes rather than a growing backlog of security tickets.
Understanding the problem
Unused IAM permissions increase the attack surface. Removing unused permissions limits the actions available to any compromised credentials, reducing potential impact. Roles that aren’t being assumed represent unused resources; removing them simplifies your IAM inventory and reduces potential access paths that aren’t actively monitored.
The challenge isn’t knowing what to fix. As we said earlier, Access Analyzer provides both the findings and the recommended policies. The challenge is acting on that knowledge consistently across your environment. Each finding requires context:
What the role does
Who created the role
Determining if the permission is unused or used infrequently
If the role is managed in a CloudFormation stack, or was created through the console
Multiply this by hundreds of roles and security teams face a backlog that grows faster than they can address it.
Manual remediation compounds the problem. A security engineer can right-size a role directly in the console, but that fix is fragile. If the role is defined in an IaC template, the next deployment restores the original permissions. If it was created manually, there’s no record of what changed or why, and no easy way to revert if the change causes issues.
This is where IaC changes the equation. When roles are defined in code, remediation means updating that code. Changes flow through pull requests, are reviewed by the team that owns the role, and deploy consistently across environments. The fix becomes permanent, not a point-in-time correction that drifts back on the next deployment. And because every change is tracked in version control, teams can confidently remove permissions knowing they can revert if something breaks. That safety net matters; it’s often the difference between a team acting on a finding and leaving it in the backlog.
Solution overview
The solution automates remediation by connecting four capabilities: IAM Access Analyzer for detection and policy recommendations, CloudTrail for role attribution, Amazon Bedrock for CDK code generation and plain-English explanations, and your existing continuous integration and delivery (CI/CD) pipeline for remediation execution. The workflow operates on a core principle: every IAM role has an origin, and that origin determines the remediation path.
Figure 1 shows the solution architecture: Amazon EventBridge triggers an AWS Lambda orchestrator on a daily schedule. The Lambda orchestrator integrates with IAM Access Analyzer, CloudTrail, Amazon Bedrock, and Amazon CloudWatch. Each finding is routed to one of three remediation paths: a pull request for IaC-managed roles, an issue for manually created roles, and a soft-disable issue for unused roles.
Figure 1: The daily remediation workflow; from scheduled trigger to the three role-based remediation paths
On each scheduled run, the automation retrieves active findings from IAM Access Analyzer and queries CloudTrail to determine how each role was created. Roles created through CloudFormation or AWS CDK have a traceable origin: the service principal, stack name, and originating repository. Roles created manually through the console have a different origin: the IAM user who created them and the timestamp. This distinction drives the remediation strategy.
For IaC-managed roles, the automation retrieves the IAM Access Analyzer-recommended policy and uses Amazon Bedrock to wrap it in production-ready CDK code that includes the role definition and policy statements and imports what your CI/CD pipeline needs to deploy the update. It then creates a pull request in the originating repository. The pull request (PR) includes the updated CDK code, a policy diff showing exactly which permissions are being removed, and a plain-English explanation of the changes, for example, “This change removes write access to S3, keeping only read and list permissions.” Your existing code review process evaluates the change, and after being merged, the fix deploys consistently across environments.
For manually created roles, the automation creates an issue that includes the IAM Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, and an Amazon Bedrock-generated explanation of what the permission changes accomplish. The issue also provides guidance on importing the role into your IaC codebase. This gives teams an immediate remediation path while encouraging long-term governance through IaC adoption.
For roles that aren’t being assumed at all, the automation takes a more cautious approach. Instead of taking direct action, it creates an issue recommending a soft-disable workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. The issue provides the steps and context, the team executes the decommission through their preferred process, whether that’s a console change, an AWS Command Line Interface (AWS CLI) script, or a PR removing the role from the IaC. This controlled decommission path reduces the risk of removing a role that’s used infrequently or seasonally.
The solution supports both single-account and organization-wide deployment. In single-account mode, it uses an ACCOUNT_UNUSED_ACCESS analyzer to process findings for one account. In organization mode, it uses an ORGANIZATION_UNUSED_ACCESS analyzer deployed in a delegated administrator account, which generates findings across all member accounts from a single vantage point. The Lambda function automatically detects which analyzer type is available and extracts the account ID from each finding’s resource Amazon Resource Name (ARN), so role attribution and remediation routing work the same way regardless of scope.
This three-path strategy acknowledges operational reality. Not all roles start in IaC, not all unused roles are safe to delete immediately, and forcing immediate migration isn’t always practical. The solution provides a clear path forward for each scenario: remediate IaC roles through code, give teams actionable recommendations for manually created roles, and safely decommission what’s no longer needed. Over time, your infrastructure becomes increasingly code-driven, and remediation becomes a routine part of your CI/CD process rather than a manual security task.
Technical details
Consider a company—call them AnyCompany—running 200 IAM roles across three AWS accounts. Some roles were created through AWS CDK stacks during initial deployment. Others were created manually through the console by engineers who needed quick access during incident response or prototyping. A handful haven’t been assumed in over 6 months. AnyCompany’s security team wants to act on their IAM Access Analyzer findings, but each role requires different handling. The solution’s architecture addresses this by routing each finding through a classification and remediation pipeline.
Figure 2 shows how each IAM Access Analyzer finding is processed:
The finding is first checked against exclusions and excluded findings are skipped.
Remaining findings are split by type: UnusedPermission findings retrieve a recommended policy from IAM Access Analyzer and then query CloudTrail for role origin, while UnusedIAMRole findings follow the unused role path.
By origin, IaC-managed roles generate AWS CDK code using Amazon Bedrock and create a pull request.
Manually created or unknown-origin roles create an issue with the recommended policy and IaC migration guidance.
Unused roles create a soft-disable issue to deny-all, monitor for 30 days, then delete.
All paths publish CloudWatch metrics.
Figure 2: Detailed component interactions—the orchestrator’s five steps, its four service integrations, and the three remediation paths
The rest of this section walks through each component using AnyCompany’s roles as examples.
Exclusion filtering
Before processing any finding, the Lambda function loads an exclusion configuration and checks whether the role should be skipped. This prevents the automation from creating remediation items for roles that legitimately need broad permissions.
AnyCompany excludes their break-glass role (used only during incidents), any service-linked roles, and roles tagged CriticalService. The min_unused_days threshold prevents false positives from seasonal workloads; a role that ran a quarterly batch job 25 days ago won’t generate a finding.
Detection and analysis
IAM Access Analyzer generates two types of findings relevant to this solution. UnusedPermission findings identify roles with permissions that haven’t been exercised within the analysis period. UnusedIAMRole findings identify roles that haven’t been assumed at all. The Lambda function queries both finding types separately because they follow different remediation paths.
The Lambda function auto-detects the analyzer type at startup. When ANALYZER_SCOPE is set to organization, it checks for an ORGANIZATION_UNUSED_ACCESS analyzer first and falls back to ACCOUNT_UNUSED_ACCESS if none exists. If multiple analyzers of the same type exist in the account, the Lambda function selects the first active analyzer returned by the API. To target a specific analyzer, set the ANALYZER_ARN environment variable explicitly. With an organization-level analyzer, findings include roles from all member accounts. The Lambda function extracts the account ID from each finding’s resource ARN (for example, account 111122223333 from arn:aws:iam::111122223333:role/MyRole) and carries that context through the entire pipeline: attribution, remediation, and issue or PR creation all include the originating account.
For UnusedPermission findings, the Lambda function calls GenerateFindingRecommendation to initiate policy generation, then retrieves the IAM Access Analyzer-recommended policy through the GetFindingRecommendation API. This is a key integration point: IAM Access Analyzer provides the right-sized policy with unused permissions removed, so the automation doesn’t need to generate policies itself.
Here’s what a typical finding looks like for one of AnyCompany’s application roles:
The OrderProcessorRole has write and delete permissions for Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB, but only uses read operations. The IAM Access Analyzer recommendation removes the four unused actions while preserving the three active ones.
For UnusedIAMRole findings, no recommendation is needed: the role isn’t being assumed at all, so the remediation is to disable or delete it. The Lambda function caps the number of unused role issues per run (configurable using MAX_UNUSED_ROLE_ISSUES, default 10) to avoid overwhelming teams with a flood of issues on the first execution.
Role attribution using CloudTrail
For each finding, the Lambda function queries CloudTrail to determine how the role was created. The CreateRole event contains the information needed to classify the role’s origin.
An IaC-created role looks like this in CloudTrail:
The cloudformation.amazonaws.com service principal and user agent tell the automation this role was created through a CloudFormation or AWS CDK deployment. The Lambda function then looks up the role’s tags to find the originating repository (stored in a Repository tag set during deployment).
Here, the IAMUser type and console.amazonaws.com user agent indicate someone created this role through the console. Roles created through the AWS CLI show a similar pattern: the IAMUser type with a user agent like aws-cli/2.x.x. The automation classifies both console and AWS CLI-created roles as manually created, because neither has an IaC origin that can be updated programmatically. The automation captures the username and timestamp for the remediation issue.
Cross-account role attribution
When the Lambda function processes findings from an organization-level analyzer, the role might live in a different account than the one running the function. The automation handles this by assuming a cross-account role (configurable using CROSS_ACCOUNT_ROLE_NAME, defaulting to OrganizationAccountAccessRole) in the member account, then querying that account’s CloudTrail and IAM APIs for the CreateRole event. If the cross-account assume fails—because the role doesn’t exist in that account or permissions aren’t configured—the automation falls back gracefully, classifying the role as unknown origin and creating an issue with the account ID and available context. This approach helps the automation produce an actionable output for findings even when attribution is incomplete.
Policy recommendations and AWS CDK code generation
For IaC-managed roles with UnusedPermission findings, the Lambda function retrieves the IAM Access Analyzer-recommended policy and sends it to Amazon Bedrock to generate production-ready AWS CDK code. This is an important distinction: IAM Access Analyzer decides what the policy should be, and Amazon Bedrock wraps that policy in the AWS CDK constructs, imports, and resource definitions that the CI/CD pipeline needs to deploy the update.
The prompt instructs Amazon Bedrock to convert the recommended policy to AWS CDK code exactly as provided, with no modifications:
Generate Python CDK code that creates/updates the role with the
RECOMMENDED policy exactly as provided. Include proper imports
(aws_cdk, aws_iam), use CDK best practices (PolicyStatement,
proper resource ARNs), and add tags: ManagedBy=CDK,
RemediatedBy=AccessAnalyzer.
IAM Access Analyzer generates recommendations for both inline policies and customer managed policies. When a managed policy has partially unused permissions, the recommendation contains the full right-sized policy. The automation wraps this in AWS CDK code as an iam.ManagedPolicy construct. Note that if a managed policy is shared across multiple roles, the recommendation applies to the specific role’s usage pattern. In this case, the automation generates an issue for manual review rather than a PR, because modifying a shared policy could affect other roles.
The generated code goes through a validation step before inclusion in any PR. The Lambda function compiles the Python code to check for syntax errors and verifies that required AWS CDK patterns (iam, PolicyStatement) are present. If validation fails, the finding is logged as an error rather than creating a broken PR.
The solution doesn’t currently invoke the IAM Access Analyzer ValidatePolicy API to check the generated policy for errors or overly permissive statements. However, this is a natural extension point. Teams can add a validation step that calls ValidatePolicy on the Amazon Bedrock-generated policy before including it in a PR, detecting issues like missing resource constraints or invalid action names.
Amazon Bedrock also generates a plain-English explanation of the policy changes. For AnyCompany’s OrderProcessorRole, the explanation might read:
“The role currently has full S3 write access and DynamoDB delete permissions, but only uses read operations. Removing s3:PutObject, s3:DeleteObject, s3:PutBucketPolicy, and dynamodb:DeleteItem reduces the scope of impact if credentials are compromised, while preserving the s3:GetObject, s3:ListBucket, and dynamodb:Query permissions the application needs.”
The solution uses the Anthropic Claude Sonnet model on Amazon Bedrock for CDK code generation (where accuracy matters) and Claude Haiku on Amazon Bedrock for explanations (where speed and cost efficiency matter more).
Three-path remediation
The Lambda function evaluates each finding’s origin and routes it to one of three remediation paths.
Path 1: IaC-managed roles (pull request) – For AnyCompany’s OrderProcessorRole, the automation creates a PR in the originating repository. The PR includes:
The Amazon Bedrock-generated AWS CDK code implementing the IAM Access Analyzer-recommended policy
A policy diff showing exactly which permissions are being removed
The plain-English explanation of what the changes accomplish
Labels (security, iam-remediation, automated) for filtering and tracking
The team that owns the role reviews the PR through their normal code review process. Once merged, the fix deploys consistently across environments through the existing CI/CD pipeline.
Path 2: Manually-created roles (issue) – For AnyCompany’s IncidentResponseRole, the automation creates an issue that includes the Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, an Amazon Bedrock-generated explanation, and step-by-step guidance on importing the role into IaC. This gives the team an immediate remediation path (apply the recommended policy) while encouraging long-term governance through IaC adoption.
Path 3: Unused roles (soft-disable issue) – For roles that haven’t been assumed at all, the automation creates an issue recommending a three-stage decommission workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. This controlled approach reduces the risk of removing a role that’s used infrequently or seasonally – if something breaks during the monitoring period, removing the deny-all policy restores access immediately.
Dry-run mode
Before creating real PRs and issues, you can run the automation in dry-run mode by setting “dry_run": true in the CI/CD configuration or setting the CI_CD_PLATFORM environment variable to dryrun. In this mode, the Lambda function processes findings, classifies roles, and generates remediation data, but logs what it would create instead of making actual API calls to your repository platform. You can use the log to validate the automation’s behavior, review the classification accuracy, and tune exclusions before going live.
Operational metrics
The Lambda function publishes CloudWatch metrics after each run:
findings_processed
Total UnusedPermission findings evaluated
iac_roles_found
Roles classified as IaC-managed
manual_roles_found
Roles classified as manually created
unused_roles_found
Roles with no assume activity (UnusedIAMRole findings)
prs_created
Pull requests created for IaC roles
issues_created
Issues created (manual roles and unused roles)
errors
Processing errors (failed classifications, API failures)
These metrics feed into dashboards and alarms. AnyCompany sets an alarm on errors > 5 to catch API throttling or configuration issues, and tracks prs_created + issues_created over time to measure remediation velocity.
Implementation
The solution ships as two AWS CDK stacks and deploys in minutes. The accompanying GitHub repository contains the complete source code, AWS CDK stacks, configuration templates, and step-by-step deployment instructions.
At a high level, deployment involves:
Prerequisites: An AWS account with an ACCOUNT_UNUSED_ACCESS or ORGANIZATION_UNUSED_ACCESS analyzer enabled, Python 3.11 or later, AWS CDK v2, a CI/CD platform API token stored in AWS Secrets Manager, and Amazon Bedrock model access for the Anthropic Claude models you plan to use. The model IDs are configurable environment variables (BEDROCK_CODEGEN_MODEL and BEDROCK_EXPLANATION_MODEL); Amazon Bedrock retires older foundation models over time, so if the shipped defaults stop working, set these variables to current models you have enabled and redeploy. The repository README documents this.
Configuration: Two files in the config/ directory control behavior. exclusions.json defines which roles and permissions to skip (break-glass roles, service-linked roles, tagged exceptions), and ci_cd_config.json configures your repository platform integration (GitLab or GitHub), labels, and throttling limits.
Deploy: Run cdk deploy --all to create the Lambda function, EventBridge schedule, IAM roles, and CloudWatch alarms.
Validate in dry-run mode: Start with “dry_run": true to see how the automation classifies your roles without creating real PRs or issues. Review the CloudWatch logs to confirm attribution accuracy and tune exclusions.
Go live: Set “dry_run": false and redeploy. The Lambda function runs on schedule (daily by default) and begins creating PRs and issues.
The repository README covers each step in detail, including organization-wide deployment, cross-account configuration, and platform-specific setup for GitLab and GitHub.
Operational considerations
Deploying the automation is only the starting point. Running it in production means making decisions about how roles are retired, how the volume of findings is managed at scale, which roles warrant human review before any change is proposed, and how you measure the automation’s impact over time. The following practices keep remediation sustainable as your IAM footprint grows, so the automation reduces operational burden rather than adding to it.
Unused role lifecycle
Unused roles follow a three-stage decommission workflow. When the automation identifies a role that hasn’t been assumed within the analysis period, it creates an issue with the recommended decommission steps; the automation doesn’t modify the role directly. The team then follows the soft-disable approach:
Attach a deny-all inline policy to the role. This blocks all actions without deleting the role or its existing policies.
Monitor for 30 days. If a workload depends on the role (seasonal jobs, infrequent batch processes), the deny-all policy surfaces the dependency quickly. Removing the deny-all policy restores full access immediately; no need to recreate the role or reattach policies.
Delete the role after the monitoring period confirms no impact.
This approach is deliberately conservative. Deleting a role is irreversible; you lose the trust policy, attached policies, and any resource-based policies that reference it. The soft-disable step gives teams a safety net while still making progress on reducing their unused role inventory.
Scaling and throttling
On AnyCompany’s first run, the automation found 47 unused permission findings and 4 unused roles. That’s manageable. But organizations with hundreds of accounts and thousands of roles might see significantly more findings on initial deployment.
This is especially true with an organization-level analyzer. A single-account deployment might surface dozens of findings; an organization-level analyzer across multiple accounts could surface hundreds or thousands on the first run. The throttling controls become critical at this scale.
Two throttling controls prevent the automation from overwhelming teams:
max_findings_per_run (default 50): Caps the total UnusedPermission findings processed per Lambda function execution. Remaining findings are picked up on the next scheduled run.
MAX_UNUSED_ROLE_ISSUES (default 10): Caps unused role issues per run. This is especially important during initial deployment when you might have a large backlog of roles that haven’t been assumed in months.
Start with conservative limits and increase them as your team builds confidence in the review process. A team that can review 10 PRs per week shouldn’t receive 50 on Monday morning.
Approval workflows for sensitive roles
Not every role should receive automated PRs. Roles with administrative permissions or access to sensitive data might warrant manual review before any remediation is created. The exclusion configuration supports this through the approval_required_for_tags field:
Roles matching these tags generate issues for manual review instead of automated PRs, regardless of whether they’re IaC-managed. This gives security teams a checkpoint for high-risk roles while still automating remediation for standard application roles.
Monitoring and alerting
The metrics published after each Lambda function run (covered in the Technical details section) feed into CloudWatch dashboards and alarms. A few patterns worth setting up:
Alert on errors > 5 per run to catch API throttling, expired CI/CD tokens, or Amazon Bedrock availability issues.
Trackprs_created + issues_created over time. A healthy trend shows this number decreasing as your environment converges toward least privilege.
Monitorunused_roles_found as a leading indicator. A sudden increase might signal a team spinning up roles for a project and not cleaning up afterward.
Compareiac_roles_found to manual_roles_found over time. As teams adopt IaC, the ratio should shift toward IaC-managed roles, which means more automated remediation and less manual work.
Cost
The solution uses Lambda (minimal cost at daily execution), CloudTrail (typically already enabled), IAM Access Analyzer (charges per IAM role or user analyzed per month for the unused access analyzer), and Amazon Bedrock (pay-per-token for AWS CDK code generation and explanations). For most organizations the ongoing cost is low, and Amazon Bedrock token usage is the largest variable, scaling with the number of findings processed per day and the complexity of each policy. Review the pricing pages for each service for current rates.
For organization-level deployments, the IAM Access Analyzer cost scales with the number of IAM roles analyzed across all member accounts. The ORGANIZATION_UNUSED_ACCESS analyzer charges per role per month across the organization, so an organization with 500 roles across 20 accounts will see higher analyzer costs than a single account with 50 roles. Review the IAM Access Analyzer pricing page for current rates.
Cleanup
To remove the solution, run cdk destroy --all from the infrastructure/ directory. This removes the Lambda function, EventBridge rule, CloudWatch alarms, and IAM roles created by the stacks.
If you stored a CI/CD platform API token in Secrets Manager as part of deployment, delete it with aws secretsmanager delete-secret --secret-id <your-secret-name> --recovery-window-in-days 7. The 7-day recovery window lets you restore the secret if the deletion was accidental. After 7 days, the secret is permanently deleted and can’t be recovered. To delete immediately without a recovery window, add --force-delete-without-recovery.
Lambda automatically creates a CloudWatch Logs log group at /aws/lambda/<function-name> that persists after cdk destroy --all and continues to incur log storage charges. To remove it, run aws logs delete-log-group --log-group-name /aws/lambda/<function-name>. WARNING: This permanently deletes all execution logs.
The IAM Access Analyzer isn’t created by the AWS CDK stacks. WARNING: Deleting the analyzer permanently removes all findings, analysis history, and unused permission data. Export any findings you need to retain before deletion. After exporting, run aws accessanalyzer delete-analyzer --analyzer-name <your-analyzer-name> to delete it. The ACCOUNT_UNUSED_ACCESS and ORGANIZATION_UNUSED_ACCESS analyzer types incur charges based on the number of IAM roles and users analyzed per month.
If you deployed in organization mode and created cross-account roles (default name: OrganizationAccountAccessRole) in member accounts solely for this solution, remove them from those accounts.
Any PRs or issues already created in your CI/CD platform remain after stack deletion; they’re artifacts in your repository, not AWS resources. See the repository README for detailed cleanup instructions.,
Conclusion
Automating IAM permission remediation turns least privilege from a periodic compliance exercise into an operational practice. By connecting IAM Access Analyzer findings and recommendations to your CI/CD pipeline, remediation shifts from manual security tasks to code review processes that your teams already follow.
The three-path strategy acknowledges how infrastructure evolves. IaC-managed roles receive pull requests with production-ready AWS CDK code and plain-English explanations. Manually created roles receive actionable issues with recommended policies and IaC migration guidance. Unused roles are put on a controlled decommission path that protects against accidental disruption. Over time, the manual role count decreases as teams adopt IaC, and remediation becomes a routine part of your deployment pipeline.
Start with a pilot. Choose 10–20 non-production roles, deploy in dry-run mode, and review the classification results. Tune your exclusions, confirm the CloudTrail attribution is accurate for your environment, and then enable live remediation. Expand to production roles after your team is comfortable with the review cadence.
When you’re ready to scale beyond a single account, switch to an organization-level analyzer and the same Lambda function will process findings across all member accounts with no architectural changes required, only a configuration toggle.
The complete source code, AWS CDK stacks, and configuration templates are available in the accompanying GitHub repository.
If you have feedback about this post, submit comments in the Comments section below.
In Part 1 of this guide, we examined two common incident scenarios: cross-account Amazon Simple Storage Service (Amazon S3) data deletion with ransomware implications, and cryptocurrency mining deployed through AWS CloudFormation using exposed AWS Management Console credentials. We also introduced key incident response terminology and investigative frameworks for analyzing AWS CloudTrail events.
In this second part, we explore a more complex, multi-stage attack: how a web application vulnerability can cascade into credential harvesting and unauthorized access to Amazon Bedrock services across multiple AWS Regions. We also cover additional investigation techniques and hardening steps to strengthen your security posture.
Scenario 3: SSRF to IMDSv1 credential harvesting with multi-Region Amazon Bedrock service misuse
This scenario examines how a web application vulnerability can cascade into a multi-Region event targeting Amazon Bedrock services. The investigation demonstrates how threat actors chain together multiple techniques, using Amazon Elastic Compute Cloud (Amazon EC2) Instance Metadata Service version 1 (IMDSv1) through server-side request forgery (SSRF) and cross-Region pivoting to access Amazon Bedrock.
Your security team receives multiple alerts: failed AWS Identity and Access Management (IAM) operations in the us-east-1 Region, successful console sign-ins without multi-factor authentication (MFA), and unusual Amazon Bedrock API calls from us-east-2. Initially, these might seem like unrelated events across different services and Regions. However, as our Security Incident Response Team (SIRT) discovered, they represent a carefully orchestrated event chain that began with a web application vulnerability and culminated in unauthorized access to your organization’s AI infrastructure.
Architecture and progression
The architecture in figure 1 maps a multi-stage attack that exploits the trust relationship between Amazon Elastic Compute Cloud (Amazon EC2) instances and AWS services. A threat actor identified a server-side request forgery (SSRF) vulnerability in a web application running on an EC2 instance that had an attached webdev IAM role. Rather than attempting to escalate privileges directly, the threat actor used this foothold to reach the Instance Metadata Service version 1 (IMDSv1) endpoint and retrieve the temporary credentials issued to the webdev role. Because IMDSv1 returns credentials in response to a basic request with no session token, an SSRF flaw is enough to harvest them, which is why these credentials became the pivot point for everything that followed. The attack unfolded in five stages. Each stage is numbered in figure 1 so you can follow the progression from the initial web request through to the cross-Region Amazon Bedrock activity:
Initial access: The threat actor exploited the SSRF vulnerability in the web application to make server-side requests on the instance’s behalf.
Credential harvesting: Those requests reached the IMDSv1 endpoint and returned the temporary credentials for the webdev role.
Permission testing: Using the harvested credentials, the threat actor attempted IAM operations to probe the boundaries of what the role could do.
Service pivoting: When IAM actions were denied, the threat actor shifted focus to Amazon Bedrock, a service the role could reach.
Region hopping: The threat actor moved operations from us-east-1 to us-east-2, likely to evade Region-specific monitoring and access controls.
Figure 1: Scenario 3 architecture
CloudTrail evidence and structured extractions
In this section, we walk through the CloudTrail evidence that documents the attack from start to finish. Each of the four events that follow maps to one or more stages in the progression described previously, and together they trace how the threat actor moved from harvested credentials to active misuse of Amazon Bedrock. For each event, we present the relevant portion of the CloudTrail log record, highlight the fields that matter most for the investigation, and include a forensic legend that explains what each highlighted field reveals.
We cover the following events:
Permission boundary testing (15:53:49 UTC): A failed CreateUser call in us-east-1 that reveals the compromised role and the IMDSv1 credential source.
Console access establishment (15:59:29 UTC): A successful console sign-in without MFA, showing the pivot from programmatic to interactive access.
Bedrock service reconnaissance (17:20:00 UTC): A ListFoundationModels call in us-east-2 that marks the Region hop and the shift to AI services.
Active model exploitation (17:25:48 UTC): A Converse call that invokes the Amazon Nova Pro model, confirming unauthorized usage.
As you read each event, focus on how the fields connect one stage to the next. The same webdev role, the same source IP address, and the recurring ec2RoleDelivery value are the threads that tie these otherwise separate events into a single attack chain.
Event 1: Permission boundary testing (15:53:49 UTC): The first suspicious activity appeared as a failed CreateUser API call in us-east-1. The CloudTrail log records an AssumedRole session attempting to create an IAM user named adm1n but receiving an AccessDenied error. The webdev role is visible in the userIdentity field, readOnly is false (indicating a write operation attempt), and the user-agent shows AWS Command Line Interface (AWS CLI) on Windows, suggesting programmatic access from the harvested credentials.
Event 2: Console access establishment (15:59:29 UTC): Six minutes later, the threat actor successfully signed in to the AWS Management Console using the same credentials. The ConsoleLogin event records that MFA wasn’t used (MFAUsed: No), and the source IP (75.3.231.105) provides attribution data. The user agent indicates Chrome browser on Windows 10.
Event 3: Amazon Bedrock service reconnaissance (17:20:00 UTC): Nearly two hours later, the threat actor pivoted to Amazon Bedrock, making a ListFoundationModels API call in us-east-2. This event exhibits several patterns: a Region change from us-east-1 to us-east-2 (potential defense evasion), a shift from IAM to AI services, readOnly: true (reconnaissance rather than modification), and sessionCredentialFromConsole: “true”, which ties the call to the console session established in Event 2 rather than a fresh IMDSv1 credential retrieval.
 {
  "eventVersion": "1.11",
  "userIdentity": {
    "type": "AssumedRole",
    "arn": "arn:aws:sts::XXXXXXXXXXXX:assumed-role/webdev/i-0123456789abcdef0"
  },
  "eventTime": "2025-09-22T17:20:00Z",
  "eventSource": "bedrock.amazonaws.com",  ◄── ❶ Pivoted to cloud AI services
               ‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾
  "eventName": "ListFoundationModels",  ◄── ❷ AI model reconnaissance
               ‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾
  "awsRegion": "us-east-2",  ◄── ❸ Region hop (evasion technique)
               ‾‾‾‾‾‾‾‾‾‾‾
  "sourceIPAddress": "75.3.231.105",
  "readOnly": true,
  "tlsDetails": {
    "clientProvidedHostHeader": "bedrock.us-east-2.amazonaws.com"  ◄── ❹ Intentional alternate region targeting
                               ‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾
  },
  "sessionCredentialFromConsole": "true"
}

───────────────────────────────────────────────────────────────────
  FORENSIC LEGEND
───────────────────────────────────────────────────────────────────
❶ eventSource: "bedrock.amazonaws.com"→ Attacker pivoted from IAM to managed AI services
❷ eventName: "ListFoundationModels"→ Reconnaissance: enumerating available AI models
❸ awsRegion: "us-east-2"→ Region hop from us-east-1 (defense evasion)
❹ clientProvidedHostHeader: "bedrock.us-east-2..."  → Confirms intentional targeting of alternate region endpoint
───────────────────────────────────────────────────────────────────
Event 4: Active model exploitation (17:25:48 UTC): Five minutes after the reconnaissance call, the threat actor moved from enumeration to active exploitation, invoking the Amazon Nova Pro model through the Converse API in us-east-2. The additionalEventData field quantifies the unauthorized usage at 944 input tokens and 126 output tokens, confirming that the threat actor successfully prompted the model and received a response.
 {
  "eventVersion": "1.11",
  "userIdentity": {
    "type": "AssumedRole",
    "arn": "arn:aws:sts::XXXXXXXXXXXX:assumed-role/webdev/i-0123456789abcdef0"
  },
  "eventTime": "2025-09-22T17:25:48Z",
  "eventSource": "bedrock.amazonaws.com",
  "eventName": "Converse",  ◄── ❶ Active model invocation (recon → exploitation)
               ‾‾‾‾‾‾‾‾‾‾
  "awsRegion": "us-east-2",
  "requestParameters": {
    "modelId": "amazon.nova-pro-v1:0",  ◄── ❷ Specific model being misused
               ‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾
    "inferenceConfig": { "maxTokens": 1024 }
  },
  "responseElements": null,
  "additionalEventData": { "inputTokens": 944, "outputTokens": 126 }  ◄── ❸ Unauthorized usage quantified
                           ‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾‾
}

───────────────────────────────────────────────────────────────────
  FORENSIC LEGEND
───────────────────────────────────────────────────────────────────
❶ eventName: "Converse"                → Attacker transitioned from reconnaissance to active exploitation
❷ modelId: "amazon.nova-pro-v1:0"      → Identifies the specific foundation model being misused
❸ inputTokens: 944, outputTokens: 126  → Quantifies unauthorized usage (financial cost + data exfiltration exposure)
───────────────────────────────────────────────────────────────────
Notable event fields to track
As you review the event logs, a handful of fields do most of the investigative work in this scenario. Understanding what each one reveals, and why it matters, is what turns a collection of individual log records into a coherent attack narrative.
The userIdentity field is the starting point for attribution. In this scenario it carries the EC2 instance ID as the session name, which is what let us trace the harvested credentials back to a specific compromised instance rather than a human user. Whenever you see an assumed-role session, this field answers the first question of any investigation: whose credentials are these, and where did they come from?
The readOnly field reveals the intent behind an action. A value of true marks reconnaissance, such as the ListFoundationModels call the threat actor used to enumerate available models, while false marks an attempt to change or use something, such as the CreateUser call or the Converse invocation. Sorting events by this field quickly separates the threat actor’s information gathering from the actions that caused actual impact.
The awsRegion field is easy to overlook, but in this scenario it exposed the threat actor’s evasion strategy. The shift from us-east-1 to us-east-2 wasn’t incidental; threat actors move between Regions because monitoring, alerting, and access controls are often configured inconsistently across them. Watching this field helps you spot activity that has deliberately moved away from where your detection is strongest.
Finally, the userIdentity.invokedBy field identifies when an AWS service, rather than a user or a set of harvested credentials, made the request on your behalf. CloudTrail populates it only when the caller is an AWS service, such as through a service-linked role, a service role, or a forward access session. It doesn’t appear in the events for this scenario because the threat actor called Amazon Bedrock directly with the harvested webdev credentials. That absence is itself informative: it confirms the requests came from a principal acting on its own rather than from a legitimate service-driven workflow. As agent-based and service-integrated Amazon Bedrock workloads become more common, checking this field separates expected service activity from credentials driven directly by a threat actor.
Investigation priorities
With the full attack chain mapped, from SSRF through credential harvesting to Amazon Bedrock service misuse, the investigation turned to a harder question: what did each stage actually cost us, and what would stop it from happening again? A few priorities shaped that work.
The first was figuring out where the credentials came from and how far the exposure reached. It was clear the threat actor had valid credentials for the webdev role, but the more useful question was why a web application role could reach Amazon Bedrock at all. The customer confirmed there was no business reason for it, so we needed to understand whether that permission was a deliberate misconfiguration or an oversight, and then look for other EC2 instances carrying the same role attachment. One compromised instance is an incident; a fleet of instances with the same over-scoped role is a much bigger problem waiting to happen.
Next, we wanted to know what the threat actor did after they got into Amazon Bedrock. Reconnaissance and active use carry very different consequences, so we traced which foundation models were touched and whether any were actually invoked or only enumerated. That distinction matters for scoping the damage, and it signals whether data exfiltration is a concern. Unusual model usage, unexpected prompt volume, or output patterns that don’t match any legitimate workload are the signals that reconnaissance has turned into something worse.
The Region hop was its own line of inquiry. The move from us-east-1 to us-east-2 was almost certainly deliberate, and the investigation focused on understanding what the threat actor gained by it. In practice, that meant comparing the two Regions: were the monitoring and access controls in us-east-2 weaker than in us-east-1, and what else did the threat actor reach in the secondary Region once they were there? Inconsistent controls across Regions are one of the most common ways activity slips past detection.
Tying it all together was the timeline, which shows how quickly the threat actor moved through the chain:
17:25:48: Active model invocation (Converse call) (us-east-2)
Following the credentials across those events fills in the rest of the story. IMDSv1 handed the threat actor temporary credentials for the webdev role, and the same role appears in every event that followed, which confirms the credentials were reused rather than replaced. Nowhere in that sequence was MFA required, and that single gap is what let one harvested credential stay useful across two hours, two Regions, and two very different services.
Incident response checklist
The following checklist captures the actions needed to contain the incident, remediate the vulnerability, and assess the scope of unauthorized AI service usage. Each item names where to look and what a finding looks like, so the checklist stays usable under the time pressure of a live incident.
Contain and remediate the entry point:
Identify the specific web application feature that made the outbound request (URL fetchers, webhook callbacks, PDF or image renderers, and link-preview generators are the usual culprits), then confirm it can reach http://169.254.169.254.
Audit the rest of the application for the same pattern, because one unvalidated URL parameter usually means others exist.
Enforce IMDSv2 on the affected instance and across the fleet with aws ec2 modify-instance-metadata-options --http-tokens required --http-put-response-hop-limit 1. Setting --http-tokens required means credentials are only returned when the caller presents a session token it obtained through a PUT request, which a basic SSRF cannot do. Setting the hop limit to 1 keeps the metadata response on the instance itself, so a request coming from a container or proxy an extra hop away never receives it.
Scope the Bedrock usage:
List the foundation models the webdev role could reach by reviewing its IAM policy and any resource-based policies, so you know the full set of models that were exposed, not only the one that was invoked.
Determine what was sent to and returned by the model. CloudTrail records the Converse call and the token counts, but only Amazon Bedrock model invocation logging captures the input prompts and model responses. If it was enabled, pull the log entries for the session; if it wasn’t, note that the prompt and response content can’t be recovered and enable it now.
Flag any compliance exposure based on what those prompts and responses contained. Unauthorized processing of regulated data (such as personally identifiable information (PII), protected health information (PHI), or cardholder data) through the model might trigger notification obligations.
Check for wider compromise and persistence:
Query CloudTrail across all Regions and services—not only Amazon Bedrock—for every event tied to the webdev role’s session, to confirm what else the same credentials touched.
Correlate the CloudTrail timestamps with VPC Flow Logs and application logs for source IP 75.3.231.105 to build the network-level picture around each API call.
Search for IAM write events from the session (CreateUser, CreateRole, CreateAccessKey, and AttachRolePolicy) that indicate an attempt to establish persistence beyond the temporary credentials. The failed adm1nCreateUser call is the known starting point; confirm nothing similar succeeded.
Watch for ongoing or hidden impact:
Review Amazon Bedrock usage in CloudWatch and your billing data for invocation spikes or unexpected token consumption that fall outside normal workload patterns.
Inspect the invocation logs for signs of sensitive data being processed or extracted through the model.
Check the same logs for prompt injection attempts, where the input tries to override the model’s instructions or extract system prompts.
Key takeaways
This scenario reveals how a single application vulnerability can cascade into broad unauthorized access when multiple security controls are missing. The following takeaways highlight the key defensive gaps and hardening priorities.
Least-privilege IAM for workload roles:The webdev role’s access to Amazon Bedrock across multiple Regions had no business justification for a web application workload, which the customer confirmed during the investigation. Apply least-privilege principles to EC2 instance roles by scoping permissions to only the services and actions the application requires. Use AWS IAM Access Analyzer to identify unused permissions and tighten policies proactively. Overly permissive roles transform a single application vulnerability into broad lateral movement across unrelated services.
IMDSv1 compared to IMDSv2: Organizations must immediately switch to IMDSv2 and disable IMDSv1 across their entire cloud infrastructure. The ec2RoleDelivery: “1.0" field in the logs explicitly confirms the use of IMDSv1, which permits credential retrieval without an authentication token. This architectural weakness makes SSRF-based credential theft trivial, because a web application flaw that can make an outbound request is enough to read the role’s temporary credentials with no further authentication. Transitioning to IMDSv2 mitigates this attack surface by enforcing local, session-based tokens, effectively breaking the threat actor’s exploitation chain. In this scenario, IMDSv2 alone would have stopped the attack at its first step.
Region-based defense evasion signals a deliberate operator: The shift from us-east-1 to us-east-2 for Amazon Bedrock access wasn’t incidental. Threat actors move between Regions because monitoring, alerting, and access controls are often configured inconsistently across them, and activity in a secondary Region is more likely to go unnoticed. This kind of cross-Region movement is a marker of operational security awareness rather than opportunistic access, and it should raise the priority of an investigation. Treat consistent detection coverage across all Regions, including the ones you do not actively use, as a baseline requirement.
Interface switching and permission probing reveal the threat actor’s method: This event chain reveals a threat actor comfortable moving between AWS interfaces and testing boundaries before committing. The failed CreateUser attempt was systematic probing to understand the scope of the harvested credentials, and when IAM actions were denied, the threat actor pivoted to a service the role could actually reach. The combination of programmatic access through the AWS CLI and interactive console access demonstrates the same adaptability. Recognizing this pattern of probe, adapt, and pivot helps responders anticipate the next move instead of reacting to each event in isolation.
AI services need visibility beyond CloudTrail: Amazon Bedrock and other AI services are high-value targets, and CloudTrail alone doesn’t capture the whole story. CloudTrail records who called Amazon Bedrock and whether the call succeeded, but not what was asked or answered. Enable Amazon Bedrock model invocation logging to capture full prompts and responses for compliance auditing. For agent-based workloads, Amazon Bedrock AgentCore Observability, built on AWS Distro for OpenTelemetry (ADOT), provides session-level traces showing tool execution order and latency. Consider also enabling Amazon GuardDuty AI Protection, which analyzes Amazon Bedrock-related CloudTrail activity to detect anomalous invocations, cost harvesting, and prompt injection attempts. Correlating these signals—CloudTrail, Model Invocation Logging, and agent telemetry—gives investigators the complete picture. For implementation guidance, see Monitoring and Auditing AI Workloads on AWS.
Advanced forensic indicators and evasion techniques
Beyond the specific attack patterns in this scenario, investigators should be aware of several evasion techniques that threat actors use to confuse defenders and blend into legitimate activity. The top three that we observe across incident response with customers are:
Root user compared to IAM user named root: When you first create an AWS account, you begin with a single sign-in identity that has complete access to all AWS services and resources in the account. This identity is called the AWS account root user. In some previous investigations, threat actors have also created IAM users in an AWS account named root. The difference is visible in the type field of the userIdentity element of the CloudTrail log record, which indicates the type of user that logged the record.
Role and user name imitation: Threat actors attempt defense evasion by creating names for IAM users and roles that imitate those reserved for use by AWS. For example, the service-linked role AWSServiceRoleForSupport is a unique IAM role linked directly to AWS Support. Threat actors have created roles with the name AWSServiceRoIeforSupport (note the use of an upper-case letter I instead of a lower-case letter l in Role) in an attempt to trick users into thinking actions taken by this role have been performed by AWS Support.
Users named HIDDEN_DUE_TO_SECURITY_REASONS: The userName field contains the string HIDDEN_DUE_TO_SECURITY_REASONS when the recorded event is a console sign-in failure caused by incorrect user name input. CloudTrail doesn’t record the contents in this case because the text could contain sensitive information. However, threat actors have used this string as an actual username to trick investigators into thinking the name has been obfuscated. This technique is usually associated with a corresponding CreateUser or CreateRole CloudTrail event.
Conclusion and next steps
CloudTrail event fields help security teams identify identities with unintended access, track threat actor actions, and remediate affected resources. Understanding fields like userIdentity, eventName, and sourceIPAddress improves incident investigation and threat detection. Implementing best practices such as enabling comprehensive logging, using Amazon Athena for analysis, securing logs, and automating responses helps ensure that CloudTrail serves as a robust forensic and incident response tool.
If you suspect unauthorized activity in your AWS environment, AWS Security Incident Response is available to help. The service continuously monitors and triages findings from Amazon GuardDuty and third-party security tools integrated through AWS Security Hub, automatically filtering alerts to surface the most relevant events. In addition to proactive triage, customers can initiate security cases through the service. You can choose to handle these cases internally or receive support from the Security Incident Response Team (SIRT), a dedicated group of security experts available at all times to assist with investigation, containment, and recovery throughout the incident lifecycle.
Additional resources
The following resources provide further guidance on securing your AWS environment and strengthening your investigative capabilities.
AWS CloudTrail logs contain the evidence you need when investigating suspicious activity in your AWS environment, but knowing which fields matter and how to interpret them can mean the difference between surface-level analysis and uncovering the full scope of an incident. This guide walks you through real-world scenarios, showing you how to analyze CloudTrail events to uncover cross-account unauthorized access, cryptocurrency mining operations, and AI service abuse. You’ll learn the investigative techniques our Security Incident Response Team (SIRT) team uses to handle threats, with practical methodologies you can apply to your own investigations.
Each scenario includes:
Architecture diagrams showing the event progression
Investigation frameworks with specific questions to ask
Lessons learned and preventive measures
Whether you’re in security operations, cloud engineering, compliance, or leadership, this guide provides the investigative mindset needed to move beyond basic CloudTrail queries to comprehensive security analysis.
Incident response definitions
Throughout this guide, we reference terminology commonly used in incident response and threat intelligence. We’ve provided definitions for key terms to help ensure this guide is accessible to readers from diverse backgrounds, whether you’re in security operations, cloud engineering, compliance, or leadership.
Reconnaissance: The initial phase where a threat actor gathers information about the target environment (for example, listing Amazon Simple Storage Service (Amazon S3) buckets or browsing available resources) to understand what’s available before taking action.
Enumeration: Systematically cataloging specific resources, users, or configurations within an environment to identify potential targets or access paths.
Lateral movement: When a threat actor moves from one resource to another within the same environment (for example, pivoting from an Amazon Elastic Compute Cloud (Amazon EC2) instance to an AI service) to expand their access.
Privilege escalation: Attempting to gain higher-level permissions than initially obtained, such as trying to create admin users or modify AWS Identity and Access Management (IAM) policies.
Defense evasion: Techniques used to avoid detection, such as operating in a different AWS Region where monitoring might be less robust, or naming unauthorized resources to look legitimate.
Persistence: Establishing ongoing access to an environment (for example, creating new IAM users or access keys) so the threat actor can return even if the original entry point is closed.
Credential harvesting: Stealing authentication credentials (passwords, access keys, temporary tokens) to impersonate legitimate users or roles.
Server-side request forgery (SSRF): A web application technique where an unauthorized user tricks a server into making requests on their behalf, often used to access internal services such as the Amazon EC2 Instance Metadata Service (IMDS) endpoint. For more information, see Understanding SSRF.
IMDSv1 (Instance Metadata Service v1): Amazon EC2 Instance Metadata Service version 1 (IMDSv1) provides temporary credentials to applications running on an instance. IMDSv1 itself isn’t inherently insecure; however, when an application with issues (for example, one susceptible to SSRF) is running on the instance, an unauthorized user can use that application to reach the metadata endpoint and retrieve credentials. IMDSv2 mitigates this risk by requiring session-based authentication tokens.
Indicators of compromise (IOCs): Observable artifacts (IP addresses, user agents, session names, resource names) that suggest unauthorized activity has occurred.
Exfiltration: The unauthorized transfer of data out of an environment, such as copying files before deleting them.
Event chain: The sequence of steps a threat actor follows from initial access to achieving their objective, where each step enables the next.
Pivot: Shifting from one technique, service, or Region to another during a security event, often after an initial approach is blocked or to avoid detection.
Scenario 1: Cross-account S3 data deletion with ransomware implications
Cross-account access is sometimes necessary in AWS, but misconfiguration creates security risks. In this scenario, your security operations center has received an automated alert that multiple objects have been deleted from the customer-important-data S3 bucket. The initial response seems straightforward: check the CloudTrail logs, identify who deleted the objects, and determine if it was authorized. But as our SIRT team investigated further, what appeared to be a straightforward unauthorized deletion revealed itself as a cross-account incident with ransomware implications. CloudTrail analysis requires recognizing patterns, understanding context, and thinking like a threat actor.
Scenario architecture
Figure 1 shows the architecture layout for accessing a trusted account and deleting objects from an S3 bucket, which is achieved through the following steps:
Threat actor assumes the CrossAccountS3Access role from a trusted account.
Lists S3 buckets to identify targets (ListBuckets API call).
Lists objects within the target bucket to catalog contents.
Executes scripted deletions of three files within 13 seconds.
Each deletion returns an HTTP 204 (successful) status code.
Figure 1: Scenario 1 architecture
Reconnaissance phase
Our investigation began with examining the CloudTrail logs, where we discovered that the unauthorized activity started with what many analysts might dismiss as routine activity: a ListBuckets API call made through an assumed role at 14:31:22 UTC. The CloudTrail entry contains a session named dev-migration-script using the CrossAccountS3Access role.
While cross-account access is common in enterprise environments, session names typically reflect legitimate business units. Attackers frequently use masquerading techniques, naming their sessions after common developer tasks or automation scripts, to blend seamlessly into daily operational noise. However, cross-referencing this session name against the external source IP and historical deployment logs confirmed that no such migration project was authorized, signaling a clear evasion attempt by a threat actor and the first indication of unauthorized access. Three seconds later, our logs showed a GET request to list objects in the bucket, which is classic reconnaissance behavior. The threat actor was cataloging available targets, using the same assumed role and IP address. This pattern, which you can see in the arn and eventname in the following log, showed us that the threat actor gathered intelligence, assessed targets, and planned their approach.
{
  "eventVersion": "1.08",
  "userIdentity": {
    "type": "AssumedRole",
    "principalId": "AROAEXAMPLE123456789:threat-actor-session",
    "arn": "arn:aws:sts::111122223333:assumed-role/CrossAccountS3Access/threat-actor-session"
  },
  "eventTime": "2025-01-20T14:31:22Z",
  "eventSource": "s3.amazonaws.com",
  "eventName": "ListBuckets",
  "sourceIPAddress": "203.0.113.47",
  "recipientAccountId": "444455556666"
}

──────────────────────────────────────────────────────────────────────────────────
  FORENSIC LEGEND
──────────────────────────────────────────────────────────────────────────────────
❶ arn: ".../CrossAccountS3Access/..."             → Cross-account role assumed; access came from another account
❷ Session name: "threat-actor-session"            → Custom session name attached at role assumption
❸ eventName: "ListBuckets"                        → Enumeration of all S3 buckets in the account (recon)
❹ principalId: "AROAEXAMPLE123456789:threat-actor-session" → Role's unique ID + attacker-chosen session label
❺ sourceIPAddress: "203.0.113.47"                 → Origin of the API call (RFC 5737 documentation IP range)
❻ recipientAccountId: "444455556666"              → AWS account that received/owned the request (fictional placeholder)
──────────────────────────────────────────────────────────────────────────────────
Systematic deletion
After completing their reconnaissance at 14:31:25 UTC, the threat actor went silent for 14 minutes before the first deletion at 14:45:12 UTC. During this window, the threat actor likely reviewed the inventory of objects they’d just enumerated, selected their highest-value targets (financial data, PII, and database backups), and prepared an automated deletion script to execute quickly once ready. We can infer this preparation period based on several factors: no other CloudTrail events from this session appeared during the 14-minute window, the subsequent deletions were precisely timed at 6-7 second intervals suggesting scripted execution, and the targets chosen were the three most business-critical files rather than a bulk delete of everything in the bucket. This selective, scripted approach indicates the threat actor used the reconnaissance data they gathered in the listing phase to build a targeted attack plan before executing it. Within 13 seconds (14:45:12–14:45:25 UTC), the threat actor deleted three files from the customer-important-data bucket: a financial report (q4-2024.xlsx at 14:45:12), a customer personally identifiable information (PII) database (pii-database.csv at 14:45:18), and a production database backup (prod-database-backup.sql at 14:45:25). Each deletion returned an HTTP 204 status code. The Amazon S3 access logs confirm these successful DELETE operations, all originating from the same session.
The 13-second deletion window wasn’t arbitrary. The user-agent string showed AWS Command Line Interface (AWS CLI) usage on Linux, and the precise timing suggested scripted execution rather than manual operations. This indicated preplanned targeting and automated execution to minimize the detection window.
The consistent source IP across events let us search for other suspicious activities from the same source, correlate with threat intelligence feeds, and identify potential lateral movement attempts.
The broad Amazon S3 permissions of the CrossAccountS3Access role raised questions about least privilege implementation, regular access reviews, and the business justification for such extensive cross-account permissions.
Investigation priorities
With confirmation that misconfigured cross-account access had been taken advantage of to delete data, the next step was to prioritize the investigation. In incident response, priority is driven by three factors: whether the threat actor still has active access (containment urgency), whether sensitive data was exposed or exfiltrated (regulatory and business impact), and whether the attack can spread to other resources or accounts (blast radius). We applied these factors to guide the following questions:
How did the threat actor gain access to theCrossAccountS3Accessrole? We examined the role’s trust policy and recent modifications, authentication events in both the trusting and trusted accounts, and other sessions using the same role around the same timeframe.
Were the files copied before deletion? We searched for GetObject operations on the same objects before the deletions, unusual network traffic patterns during the reconnaissance phase, and CopyObject activities that might indicate data theft.
Did the objects have specific significance? Understanding why these specific objects mattered helped us prioritize recovery efforts based on business impact, assess regulatory notification requirements for the PII exposure, and determine the full scope of business disruption from backup loss.
Response checklist
After identifying the scope of the cross-account deletion, the following steps help ensure a thorough response and prevent recurrence.
Determine if the business purpose served by this cross-account access is legitimate
Identify the corresponding authentication events that show how the role was assumed
Identify other AWS resources that this role might access beyond Amazon S3
Check for failed attempts or reconnaissance activities that preceded the successful event
Determine when this cross-account trust relationship was created
Determine when the last access review of this role was conducted
Locate any backup copies of the deleted data
Determine detection rules that can be used to catch similar activity in the future
Key takeaways
This scenario illustrates several principles that apply broadly to cross-account incident investigations. Unusual identifiers in session names often reveal threat actor intent or poor operational security. The progression from ListBuckets to targeted deletions shows how threat actors operate with a plan. Cross-account access needs extra scrutiny because trusted relationships become vectors for unauthorized access when credentials are exposed. Understanding why specific files matter helps prioritize response efforts and assess true impact. Precise timing and consistent technical signatures often indicate scripted events that need different response strategies than manual intrusions.
Scenario 2: Cryptocurrency mining using CloudFormation with console credentials
In this scenario, your finance team notices an unexpected spike in AWS costs, particularly around Amazon EC2 compute charges in the us-east-1 AWS Region. During the investigation, we examine how threat actors use legitimate console access to deploy cryptocurrency mining operations through AWS CloudFormation and how investigators can uncover the scope of resource hijacking events. We discover a CloudFormation stack named CRYPTO which you have no record or knowledge of being created. The stack contains EC2 instances running in your production Amazon Virtual Private Cloud (Amazon VPC) consuming significant compute resources, which signals an immediate security investigation.
Architecture and sequence
Figure 2 shows how the threat actor moved from credential acquisition to active mining, following these steps:
Threat actor obtains console credentials (username and password without multi-factor authentication (MFA)).
Accesses AWS Management Console.
Creates CloudFormation stack CRYPTO in us-east-1.
Stack deploys EC2 instances configured for cryptocurrency mining in a public subnet.
Mining instances begin consuming compute resources.
Figure 2: Scenario 3 architecture
The following is the redacted CloudTrail event record for the unauthorized CreateStack action. See if you can use it to find the following information:
The name of the CloudFormation stack that was created
The CloudFormation stack Amazon Resource Name (ARN)
If the credentials were secured by MFA
If the threat actor used the AWS Management Console to perform the actions, or if they were performed programmatically using the AWS CLI or a script
Region: us-east-1 (a common choice for threat actors because of immediate service availability)
Authentication and session context analysis:
Examining the session metadata reveals how the threat actor authenticated and accessed the environment:
MFA status: “mfaAuthenticated": “false” indicates that the session was entirely unauthenticated by MFA.
Access method: “sessionCredentialFromConsole": “true” means that access was funneled through the console.
User context: AssumedRole using WSParticipantRole. Session creation occurred at 2025-09-23T18:06:22Z (approximately 50 seconds before stack creation).
Advanced forensic insight (the CloudShell pivot)
The sessionCredentialFromConsole: true field is important to note because this access originated from the AWS console rather than external programmatic API keys. Interestingly, while the session originated from the console, the userAgent field reveals the execution environment was exec-env/CloudShell. This shows that the threat actor didn’t manually click through the CloudFormation user interface, instead launching AWS CloudShell on sign-in to execute a prepackaged deployment script. This allowed the threat actor to achieve automated speed while evading traditional static API key monitoring. The mfaAuthenticated: false field represents a security control gap. Particularly in environments handling sensitive data or production workloads, MFA must be enforced for console access.
Investigation priorities
With the unauthorized stack confirmed, the investigation focused on understanding the full timeline and blast radius. We approached this in three phases, each building on the findings of the previous one.
Reconstruct the console session timeline
The session began at 18:06:22Z and the stack was created at 18:07:12Z, only 50 seconds later. That speed tells us the threat actor came prepared with a script rather than exploring the environment manually. But we needed to know what happened before and after. By filtering CloudTrail for the same session token across the full session duration, we could identify whether the threat actor performed any reconnaissance before deploying the stack, whether they accessed other services or regions during the same session, and whether they attempted to establish persistence (such as creating IAM users or access keys) before or after the mining deployment. Any actions taken outside the CloudFormation deployment could indicate secondary objectives beyond cryptomining.
Examine what the stack actually deployed
The stack name alone doesn’t tell us the full impact. We needed to inspect the CloudFormation template to understand what resources were created and how they were configured. This meant identifying the EC2 instance types (larger instances mean higher costs and potentially more mining output), reviewing the security group rules to determine what network access these instances had to internal resources, checking whether the template included custom AMIs or user data scripts that pulled mining software on boot, and determining if the stack created its own IAM roles with permissions that could be used for further lateral movement. The template itself is evidence. If it was hosted in Amazon S3, the upload event tells us when the threat actor first staged their tools.
Calculate business impact and determine blast radius
Finally, we needed to quantify the damage and determine whether this was isolated or part of a broader compromise. We calculated the total compute cost by multiplying instance hours by instance type pricing, checked whether the mining instances had network paths to production databases or internal services, examined outbound traffic logs for connections to known mining pool IP addresses, and searched for similar stacks or naming patterns across other regions and accounts. The presence of outbound connections to anything other than mining pools would suggest the instances served a dual purpose, potentially exfiltrating data while generating cryptocurrency.
Response checklist
The following checklist captures the key actions needed to contain the incident, assess its impact, and close security gaps.
Determine why MFA wasn’t required for this sensitive operation
Investigate how the threat actor obtained valid console credentials
Check for failed sign-in attempts preceding this successful access
Check for other activities that occurred during this console session
Look for resources that were created by the CloudFormation stack
Determine how long those resources have been running and consuming costs
Look for other similarly named or suspicious stacks in the environment
Check what network access these instances have to internal resources
Determine what outbound connections these instances are making
Look for cryptocurrency mining pool connections
Check if IAM users or roles were created
Check if additional access keys were generated
Determine if the threat actor modified existing permissions or policies
Key takeaways
This scenario highlights how credential hygiene and monitoring controls intersect with resource hijacking threats.
MFA enforcement prevents console-based credential abuse for IAM users. The absence of MFA enabled the full sequence. Console access to production environments should require multi-factor authentication as a security best practice.
Resource naming can be an indicator. The obvious CRYPTO naming suggests either threat actor confidence or poor operational security, both concerning for different reasons.
Cost monitoring is security monitoring. Unusual billing spikes can be early indicators of resource hijacking events.
Console-based activity has different patterns than programmatic activity and requires specialized investigation approaches. The sessionCredentialFromConsole field is your starting point for distinguishing between the two.
Conclusion
In this first part, we walked through two real-world scenarios that demonstrate how CloudTrail analysis can reveal the full scope of a security incident. In Scenario 1, we showed how a seemingly routine cross-account role assumption led to targeted data deletion with ransomware implications, and how session names, timing patterns, and source IP correlation help investigators piece together the event chain. In Scenario 2, we examined how stolen console credentials enabled a cryptocurrency mining deployment through CloudShell, highlighting the critical role of MFA enforcement and cost monitoring as security controls. Both scenarios reinforce a core principle: effective CloudTrail investigation goes beyond identifying what happened. It requires understanding how and why, so you can contain the immediate threat and close the gaps that enabled it.
In Part 2 of this guide, we examine how a web application vulnerability can cascade into a multi-Region event targeting AI services, chaining together SSRF, IMDSv1 credential harvesting, and cross-Region pivoting to access Amazon Bedrock. We also cover critical investigation techniques including root user compared to IAM user named root, role name imitation tactics, and the HIDDEN_DUE_TO_SECURITY_REASONS username trick, along with critical hardening steps and additional resources you can use to strengthen your cloud forensic capabilities.
If you have feedback about this post, submit comments in the Comments section below.
A single alert from one security service tells you something happened. Read that signal alongside activity from other services and your own business context, and you will know whether what happened is part of a multi-stage attack.
Consider a short sequence. An identity calls GetCallerIdentity from a source address it hasn’t previously used. Within minutes, that same identity runs a burst of List and Describe calls across several services, and some of them fail with AccessDenied. Soon after, a large volume of data leaves your environment toward a domain that was registered last week. Amazon GuardDuty might already flag pieces of this, such as the reconnaissance from an unfamiliar source, through finding types like Recon:IAMUser/* or Discovery:S3/*. What you gain from correlating the pieces yourself is a single view of the sequence, tied to your own business context, so you can act on the whole rather than triaging findings one at a time.
This post is for security engineers and security operations teams who run Amazon Web Services (AWS) detection services and want to catch patterns specific to their environment. You will see how AWS detection and your business context fit together, and how to build correlations that use that context. The examples run in Amazon CloudWatch Logs Insights so you can try them today, and the closing section describes how to grow them into an automated pipeline. The walkthrough later in this post lists the prerequisites for these queries.
Start with AWS detection services
Begin with the AWS detection services. They cover the threats common across customers, and everything in this post is built on them.
Amazon Detective (a security investigation service that visualizes relationships between resources and findings) lets you investigate findings with graph-based context across services and accounts.
AWS Security Hub aggregates security findings into a single prioritized dashboard.
Amazon Inspector (a vulnerability management service that scans workloads for software vulnerabilities) correlates vulnerability data with workload context.
Turn these on and tune them before you build anything custom. Tuning means adjusting sensitivity to reduce false positives for your environment, choosing which data sources each service monitors, and suppressing findings for known-good patterns.
GuardDuty correlates multi-stage attacks for you
Before you build anything by hand, see what GuardDuty already does for you. Amazon GuardDuty Extended Threat Detection correlates signals across multiple data sources including AWS CloudTrail, Amazon S3 data events, runtime monitoring, Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, and more, then raises a single critical severity attack sequence finding when it spots a multi-stage pattern. It recognizes sequences such as credential compromise followed by data exfiltration, maps them to MITRE ATT&CK tactics, and attaches a timeline and remediation guidance. If you have GuardDuty enabled today, then GuardDuty Extended Threat Detection is already enabled by default and needs no queries from you. For details on how GuardDuty charges apply, see Amazon GuardDuty pricing.
The credential compromise sequence in the opening example is the kind of universal pattern GuardDuty Extended Threat Detection is built to catch, so rely on it for those. Attack sequence findings show up in the GuardDuty console next to your other findings, and they route to Security Hub and your response workflows the same way.
GuardDuty handles the threats that look the same in every account. What it doesn’t have is the context that makes a given action suspicious in your account. That’s what you provide.
Add your business context
Business context is what only you know about your environment: which buckets hold sensitive data, which principals have a reason to touch which resources, which role chains your policy permits, and when your production change windows open. GuardDuty Extended Threat Detection learns from patterns common across customers, but it can’t answer these environment-specific questions. Express them as correlations and you add a detection layer tuned to your environment. Each of the following four patterns turns one of these facts into a query.
Run these queries in the AWS Management Console for CloudWatch by choosing Logs, then Logs Insights, using the CloudWatch Logs Insights query language. Most read CloudTrail events from a CloudWatch Logs log group that your trail delivers to. If your trail writes only to Amazon S3, add CloudWatch Logs delivery on the trail, or run equivalent queries in Amazon Athena (a serverless query service for analyzing data in Amazon S3 using SQL).
Note: The queries and code in this post use placeholder values. Replace them with your own before running: your-sensitive-bucket (your S3 bucket name), your-key-id (your AWS KMS key ID), region (your AWS Region, such as us-east-1), account-id (your 12-digit AWS account ID), and aws-cloudtrail-logs-my-trail (your CloudTrail log group name).
A note on multi-account environments. In AWS Organizations, an organization trail delivers every account’s events to one log group, so these queries work as-is but return cross-account results. Filter by recipientAccountId for account-scoped views. Without an organization trail, run queries per account or use Amazon Security Lake as a central query surface.
The attack chain mapped to AWS services
Multi-stage attacks move through five phases, and each phase leaves a signal in a different service. These signals surface across three log sources: CloudTrail, which records API activity in your account; Amazon VPC Flow Logs, which capture network connection metadata; and Amazon Route 53 Resolver query logs, which record DNS queries from your VPCs.
Initial access – Stolen credentials reach your environment. CloudTrail records GetCallerIdentity, GetSessionToken, or AssumeRole from an unfamiliar source.
Discovery – The threat actor enumerates with List, Describe, and Get calls, often triggering AccessDenied responses.
Privilege escalation – The threat actor chains roles or edits policies. CloudTrail records AssumeRole sequences, PutRolePolicy, or CreateAccessKey.
Lateral movement – The threat actor moves across accounts or AWS Regions, assuming roles and creating resources in unfamiliar places.
Exfiltration – Data leaves through GetObject calls at scale, large outbound transfers in VPC Flow Logs, and DNS queries in Route 53 Resolver query logs to recently registered domains.
Figure 1 shows the five attack phases mapped to the AWS log source that records each one.
Figure 1: Attack chain mapped to AWS services
GuardDuty Extended Threat Detection watches this chain for universal patterns. The four patterns that follow add the dimension you supply: your business context.
Pattern one: Sensitive data access by an unexpected principal
Your data classification and access norms drive this detection. One bucket holds customer records, another holds public web assets, and you know which principals have a reason to read the customer records, which are sensitive. Encode that knowledge and an ordinary looking read turns into something worth chasing.
Three signals converge here. CloudTrail shows GetObject at volume on a bucket you’ve classified as sensitive. The principal isn’t on your list of expected readers for that bucket. And VPC Flow Logs show a large outbound transfer from the same source in the same window, while DNS query logs show a recently registered destination domain, which together increase your confidence that there’s a potential threat.
CloudTrail management events don’t record GetObject. You must turn on CloudTrail data events for the buckets you care about to capture GetObject. Many teams miss GetObject because data events weren’t enabled on the relevant buckets.
This query shows bulk reads on a sensitive bucket, grouped by principal. Run it in CloudWatch Logs Insights with your CloudTrail log group selected.
fields @timestamp, userIdentity.arn, requestParameters.bucketName
| filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
| filter requestParameters.bucketName = "your-sensitive-bucket"
| stats count(*) as objectReads,
        count_distinct(requestParameters.key) as distinctObjects
        by userIdentity.arn, bin(10m)
| filter objectReads > 100
| sort objectReads desc
The threshold of 100 is a placeholder. Run the query over a week of normal activity, find the ninety-fifth percentile read count for that bucket, and set the threshold above it. Then check each principal the query returns against your expected reader list. A principal that isn’t on the list, reading at volume, is the result to investigate.
To corroborate, look for a matching outbound transfer. Switch the log group selector to your VPC Flow Logs log group and run this.
fields @timestamp, srcAddr, dstAddr, bytes
| filter action = "ACCEPT"
# exclude RFC 1918 private ranges so only external destinations remain
| filter dstAddr not like /^10\./
        and dstAddr not like /^192\.168\./
        and dstAddr not like /^172\.(1[6-9]|2[0-9]|3[0-1])\./
| stats sum(bytes) as totalBytes by srcAddr, dstAddr, bin(10m)
| filter totalBytes > 1000000000
| sort totalBytes desc
The Amazon S3 query returns a principal, and the Flow Logs query works on IP addresses, so you translate one into the other. The worked example later in this post covers that translation in full.
Picture an analytics role that reads a reporting bucket all day. One afternoon, it reads a thousand objects from your customer records bucket instead. GuardDuty stays quiet, because an authenticated role making valid GetObject calls isn’t suspicious anywhere else. Your query flags it, because that role isn’t on the expected reader list for that bucket. The classification you applied is what turns silence into a signal.
Figure 2 shows a bulk read from a sensitive bucket in CloudTrail, a large outbound transfer in VPC Flow Logs, and a young domain resolution in Route 53 Resolver logs.
Figure 2: Three signals converging within a single time window to indicate exfiltration
Pattern two: A role chain that crosses your access policy
Picture a deployment that assumes one role to build, then a second to release. For one principal, that two-hop AssumeRole chain is routine; for a different principal it’s a policy violation. This pattern relies on your trust topology—the chains your organization permits—so put that knowledge in the query.
This pattern needs three conditions:
CloudTrail shows several AssumeRole calls from the same source inside a short window
The chain ends in a sensitive action such as CreateAccessKey, PutRolePolicy, or AttachUserPolicy
The starting identity isn’t one your policy expects to run that chain
In CloudWatch Logs Insights, select your CloudTrail log group and run this query, which surfaces chains of two or more hops.
fields @timestamp, userIdentity.arn, requestParameters.roleArn, sourceIPAddress
| filter eventName = "AssumeRole"
| stats count(*) as assumeCount,
        count_distinct(requestParameters.roleArn) as rolesAssumed
        by sourceIPAddress, bin(5m)
| filter assumeCount >= 2 and rolesAssumed >= 2
| sort assumeCount desc
Two hops is the minimum for a chain; raise the count if your environment chains roles often. Your deployment pipeline probably assumes several roles an hour, as do AWS service principals such as AWS Security Hub. Exclude the identities you expect to see assuming multiple roles, including your pipeline role and known AWS service principals. What’s left is the set to investigate, such as a person assuming several roles at an odd hour and ending in a new access key. Treat that distinction as data: list the identities and actions you consider normal, and review the chains that fall outside the list.
Pattern three: An encryption key used outside its owning workload
Resource ownership is the signal here. A given AWS Key Management Service (AWS KMS) key creates and controls the encryption keys for a workload, and a single key should serve a single workload, such as a payments service. A Decrypt call against it is a valid, authorized API action, so nothing about the call itself looks wrong. The ownership rule you set is what makes another principal’s use of the key worth a second look.
This pattern applies only to customer-managed keys scoped to one workload. It doesn’t apply to AWS-managed keys (alias/aws/*) or to customer-managed keys intentionally shared across services. Confirm single-workload intent from the key policy’s Principal block before deploying this rule.
Two conditions indicate misuse:
CloudTrail shows Decrypt or GenerateDataKey calls on a key that’s tied to one workload
The calling principal isn’t the role that owns that workload
Against your CloudTrail log group, run this query to list the principals that called a specific key.
Compare what comes back against the one workload role you expect. A principal you don’t recognize on that key is the signal. Because key misuse is an early move in data theft, this correlation catches activity that only your ownership knowledge can flag.
Consider a key that wraps your payments database. The payments service role calls it in normal operation, and nothing else should. If a developer role or a freshly created role runs Decrypt against it, the call succeeds and reads as ordinary in isolation. The reason it matters is the ownership rule you hold in your head and now state in this query.
Pattern four: A privileged action outside your change window
Start with the query, then read what it means.
fields @timestamp, userIdentity.arn, eventName, sourceIPAddress
| filter eventName in ["PutRolePolicy", "AttachRolePolicy",
        "CreateAccessKey", "AuthorizeSecurityGroupIngress", "PutBucketPolicy"]
| stats count(*) as sensitiveChanges by userIdentity.arn, eventName, sourceIPAddress
| sort sensitiveChanges desc
Run it against your CloudTrail log group, scoped to your off-hours window when you schedule it, so it returns only activity outside the change window. Your change process defines what normal looks like here: production security and identity changes flow through a pipeline during defined hours, run by a known actor. A console-driven policy change at 2:00 AM, made by a person rather than the pipeline, doesn’t fit those expectations. The signal is a sensitive change such as PutRolePolicy or AuthorizeSecurityGroupIngress, made outside the window, by a person rather than your pipeline role.
Exclude the actors you expect, such as your deployment pipeline role, your patch automation role, and AWS service principals like AWS CloudFormation and AWS Systems Manager. What remains is privileged change made outside your process, which is both what an attacker does to establish persistence and what your own change discipline says shouldn’t happen.
Your pipeline might open security group rules during a deployment every weekday afternoon. A person opening a security group rule at midnight on a weekend is the same API call carrying a very different meaning. The schedule and the actor, both facts you define, are what separate the two.
Build your first correlation rule
The following walkthrough uses pattern one as a complete example. The other three patterns follow the same design with their own queries.
Prerequisites
These prerequisites feed the queries in this walkthrough. Confirm each one before you start:
A CloudTrail trail logging management events to a CloudWatch Logs log group
CloudTrail data events enabled for your sensitive S3 buckets
GuardDuty enabled, with its protection plans and Extended Threat Detection
CloudTrail, GuardDuty, VPC Flow Logs, and Route 53 Resolver query logging provide the raw signals that your correlations connect. Without them, the queries in this post return empty results.
Step 1: Record the bucket and its expected readers
Choose one sensitive bucket to monitor, and write down the principals allowed to read it. Store the list where your automation can reach it, such as a configuration file in version control or an Amazon DynamoDB table (a managed NoSQL database).
This example hardcodes the list for simplicity. In production, load it from a DynamoDB table or Parameter Store so you can update it without redeploying.
Step 2: Baseline before you set a threshold
Run the pattern one query over one week of normal activity. Find the 95th percentile read count for the bucket and use a value greater than that as your alert threshold. This step keeps legitimate high-volume access from generating false positives later.
Set the THRESHOLD_READS environment variable to this value when you configure the function in Step 5.
Step 3: Run the access query
In the CloudWatch console:
Choose Logs, then choose Logs Insights.
In the Select log group(s) dropdown, select your CloudTrail log group.
Set the time range to 3h (the last three hours).
In the query editor, paste the pattern one query.
Replace your-sensitive-bucket with your bucket name.
Choose Run query.
Review the principals in the results table.
Compare each principal against your expected reader list from step 1, and flag any that are not on it.
Each result includes a principal that step 4 translates into an IP address.
Step 4: Correlate with network activity
CloudTrail logs actions by AWS Identity and Access Management (IAM) principal, while VPC Flow Logs record traffic by IP address. To connect the two signals, translate the principal into its address.
For a role attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the userIdentity.principalId field includes the instance ID after the colon, in the form AROAEXAMPLE:i-1234567890abcdef0. Copy the instance ID and look up its private IP address.
Other compute types differ. A VPC-connected AWS Lambda function sends traffic through elastic network interfaces in your subnets, so correlate on those interface addresses. An Amazon Elastic Container Service (Amazon ECS) task records its network interface in task metadata. For a plain assumed-role session with no instance behind it, the sourceIPAddress field in CloudTrail already holds the caller’s address, so you correlate on it directly.
Run the Flow Logs query from pattern one, filtering srcAddr to that address within 10 minutes of the Amazon S3 read timestamp. A match places the same source behind both the sensitive read and a large external transfer in one window. CloudTrail events reach CloudWatch Logs 5–15 minutes after the API call, so correlate on eventTime rather than query time. Query a wider lookback than your correlation window: for example, look back 30 to 60 minutes but correlate on a 10-minute eventTime window. Steps 3 and 4 are manual validation; step 5 automates them.
Figure 2 shows DNS resolution as a third corroborating signal. This walkthrough implements the CloudTrail and VPC Flow Logs correlation. To add DNS, apply the same run_query() pattern against your Route 53 Resolver query log group.
Step 5: Automate the check
Move the query into a Lambda function (serverless compute that runs your code without a server to manage), send results to a notification channel, and schedule regular runs. Work through the following sub-procedures.
Note the topic Amazon Resource Name (ARN) at the top of the topic details page. You will use it in the function.
Choose Create subscription.
For Protocol, select Email.
For Endpoint, enter your email address or incident management endpoint.
Choose Create subscription, then confirm the subscription from the email AWS sends.
To create the EventBridge Scheduler execution role
The schedule needs a role that lets it invoke your function, and its trust policy needs conditions that pin the role to the schedule you own. Without those conditions, another account with access to the scheduler service could theoretically call this role; a class of misuse known as the confused deputy problem.
1. Create a trust policy file named scheduler-trust-policy.json.
2. Create the role, then attach permission to invoke the function. Scope Resource to the specific function ARN so this role can’t invoke anything else.
When you create the function, Lambda automatically creates an execution role. You will attach the permissions this function needs to that role in a later step.
On the Code tab, replace the default code with the following function, then choose Deploy.
import os
import time
import logging
import boto3
from botocore.exceptions import ClientError

logger = logging.getLogger()
logger.setLevel(logging.INFO)

logs = boto3.client("logs")
sns = boto3.client("sns")
ec2 = boto3.client("ec2")

CLOUDTRAIL_LOG_GROUP = os.environ["CLOUDTRAIL_LOG_GROUP"]
FLOWLOGS_LOG_GROUP = os.environ["FLOWLOGS_LOG_GROUP"]
SNS_TOPIC = os.environ["SNS_TOPIC_ARN"]
BUCKET = os.environ["SENSITIVE_BUCKET"]
THRESHOLD = int(os.environ.get("THRESHOLD_READS", "100"))

# Expected readers per bucket
EXPECTED_READERS = {
    "customer-records-prod": [
        "arn:aws:iam::123456789012:role/AnalyticsPipeline",
        "arn:aws:iam::123456789012:role/ComplianceAudit",
    ],
}


def run_query(log_group, query, start, end):
    """Start a Logs Insights query and wait for it to finish."""
    started = logs.start_query(
        logGroupName=log_group,
        startTime=start,
        endTime=end,
        queryString=query,
    )
    query_id = started["queryId"]
    while True:
        outcome = logs.get_query_results(queryId=query_id)
        if outcome["status"] in ("Complete", "Failed", "Cancelled"):
            break
        time.sleep(1)
    if outcome["status"] != "Complete":
        raise RuntimeError(f"Query did not complete: {outcome['status']}")
    return [{f["field"]: f["value"] for f in row} for row in outcome["results"]]


def private_ip_for_principal(principal_id):
    """Resolve an EC2 instance role principalId to its private IP."""
    if ":" not in principal_id:
        return None
    instance_id = principal_id.split(":", 1)[1]
    if not instance_id.startswith("i-"):
        return None
    reservations = ec2.describe_instances(InstanceIds=[instance_id])
    for reservation in reservations["Reservations"]:
        for instance in reservation["Instances"]:
            return instance.get("PrivateIpAddress")
    return None


def egress_bytes(src_addr, start, end):
    """Sum external egress bytes for one source address."""
    query = f"""
    fields srcAddr, dstAddr, bytes
    | filter action = "ACCEPT" and srcAddr = "{src_addr}"
    | filter dstAddr not like /^10\\./
            and dstAddr not like /^192\\.168\\./
            and dstAddr not like /^172\\.(1[6-9]|2[0-9]|3[0-1])\\./
    | stats sum(bytes) as totalBytes
    """
    rows = run_query(FLOWLOGS_LOG_GROUP, query, start, end)
    if rows and rows[0].get("totalBytes"):
        return int(rows[0]["totalBytes"])
    return 0


def lambda_handler(event, context):
    try:
        # 1-hour lookback absorbs CloudTrail's 5-15 min delivery latency;
        # correlation happens on eventTime via 10-min bins in the query below.
        end = int(time.time())
        start = end - 3600  # 1 hour lookback
        allowed = EXPECTED_READERS.get(BUCKET, [])

        access_query = f"""
        fields userIdentity.arn, userIdentity.principalId
        | filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
        | filter requestParameters.bucketName = "{BUCKET}"
        | stats count(*) as objectReads
                by userIdentity.arn, userIdentity.principalId, bin(10m)
        | filter objectReads > {THRESHOLD}
        """

        for row in run_query(CLOUDTRAIL_LOG_GROUP, access_query, start, end):
            principal = row.get("userIdentity.arn")
            if not principal or principal in allowed:
                continue

            message = (
                f"Principal {principal} read {row.get('objectReads')} "
                f"objects from {BUCKET}."
            )

            ip = private_ip_for_principal(row.get("userIdentity.principalId", ""))
            if ip and egress_bytes(ip, start, end) > 1_000_000_000:
                message += (
                    f" The same source ({ip}) also sent a large volume of "
                    f"data to external destinations in the same window."
                )

            sns.publish(
                TopicArn=SNS_TOPIC,
                Subject="Unexpected S3 access detected",
                Message=message,
            )
    except ClientError as error:
        logger.error(f"AWS API error: {error}")
        raise
    except Exception as error:
        logger.error(f"Unexpected error: {error}")
        raise
    finally:
        logger.info("Correlation check completed")
On the Configuration tab, choose General configuration, then choose Edit. Set Timeout to 5 minutes (300 seconds). CloudWatch Logs Insights queries run asynchronously and can take 30 to 60 seconds against large log groups. Choose Save.
On the Configuration tab, choose Environment variables, then choose Edit, and add CLOUDTRAIL_LOG_GROUP, FLOWLOGS_LOG_GROUP, SNS_TOPIC_ARN, SENSITIVE_BUCKET, and THRESHOLD_READS.
On the Configuration tab, choose Permissions, open the execution role, and attach the following least-privilege policy.
Replace REGION, ACCOUNT-ID, and the log-group names with your values. The ec2:DescribeInstances action doesn’t support resource-level permissions, so Resource: "*" is required for that statement; the other statements are scoped to specific ARNs.
To schedule automated runs
Amazon EventBridge (a serverless event bus that connects applications using events) runs targets on a schedule. Create one from the command line, using the role you made earlier.
Enrichment cuts triage time by adding an independent signal, but it isn’t required for the correlation to work. This step adds costs. You pay your geolocation provider for API calls, and the additional Lambda execution time increases your Lambda charges. To add IP geolocation, sign up for a geolocation API, add this function to the code, and call it where the handler resolves an IP.
import urllib.request
import json

def geo_context(ip_address):
    """Enrich an IP address with geolocation data from your provider."""
    try:
        url = f"https://your-geolocation-api.example/json/{ip_address}"
        with urllib.request.urlopen(url, timeout=5) as response:
            data = json.load(response)
        return {
            "country": data.get("country_name"),
            "city": data.get("city"),
            "org": data.get("org"),
        }
    except Exception as error:
        logger.warning(f"Geolocation lookup failed for {ip_address}: {error}")
        return None
Inside the handler’s loop, after you resolve ip, append the location to the alert.
            if ip:
                geo = geo_context(ip)
                if geo:
                    message += (
                        f" Source location: {geo['city']}, "
                        f"{geo['country']} ({geo['org']})."
                    )
Step 7: Scale to additional patterns and accounts
As your library grows, move the logic into automated pipelines with EventBridge, Lambda, and AWS Step Functions (a serverless orchestration service that coordinates multiple services into workflows), and surface correlations next to findings in Security Hub. For cross-service correlation at scale, CloudWatch unified data and telemetry capabilities can convert security and compliance data into the OCSF format and let you query sources such as CloudTrail, VPC Flow Logs, and DNS logs from one interface. Security Lake with Athena is a strong option for long-term analysis. Choose the endpoint that fits your retention and query needs.
Figure 3 shows a correlation pipeline built on AWS services including EventBridge, Lambda, Step Functions, and AWS Security Hub. The pipeline runs from data sources through scheduled queries and enrichment to automated response and centralized visibility.
Figure 3: A correlation pipeline built on AWS services
Conclusion
You now have four correlation patterns that layer your business context on top of GuardDuty Extended Threat Detection to catch attacks specific to your environment. A few principles carry across every correlation you build.
Identity is your primary correlation key: Track the same principal across services.
Time windows matter,but they depend on the attack: Events minutes apart are usually related for fast, automated sequences; the ten-minute bins here work for that pattern. Slow or manual reconnaissance can stretch across hours or days, so widen the window when the pattern is deliberate rather than automated.
Context is what you add: Your data classification, access norms, resource ownership, and change windows are signals you bring to detection.
Start with one rule: A single well-tuned correlation catches more significant activity than a wall of uncorrelated alerts.
GuardDuty Extended Threat Detection handles the multi-stage patterns common across customers. The correlations in this post add the layer that only your business context can supply. Start with one pattern this week, validate it against your own traffic, and add the next pattern after the first proves reliable.
Have you built correlation rules for patterns not covered here? Share your experience in the Comments section below.
In short, WordPress security plugins are tools you add to your site to strengthen your settings, scan for malware, watch for file changes, and block suspicious activity from within WordPress. Most sites should use one, along with a firewall that filters traffic before WordPress even loads. Look for layered protection, good detection, clear handling of false alarms, minimal impact on performance, and real human support.
If you manage a WordPress site, you have probably searched for “best WordPress security plugin” at some point.
Third-party scripts are common on websites. They help with analytics, ads, live chat, social media, video, payments, and many other features. While not all are risky, every external tag, pixel, widget, or embed adds to your website’s vulnerability. These tools can read page content, collect visitor data, change what users see, and connect with outside services. If a vendor, account, or setup is compromised, it can impact every page that uses the script.
Website owners shouldn’t aim to get rid of useful integrations, but to understand which scripts run, why they are necessary, who controls them, and how to detect unexpected changes.
Each feature that you add to a website results in a new element that has to be managed.
The credentials are accepted by a login page, the data by a contact form, new code is introduced by a plugin, and an API is used to connect your website to another service. It is also possible that an old staging site or a forgotten backup may still be accessible from the internet.
The collection of these exposed components constitutes your website attack surface.
Ten years ago, we launched AWS Directory Service for Microsoft Active Directory, a fully managed Microsoft Active Directory in the AWS Cloud. In that original announcement, Jeff Barr described a straightforward promise: “You will spend less time administering and more time working on your applications and your business.”
A decade later, AWS Managed Microsoft AD has become the identity backbone for thousands of enterprises worldwide. What started as a way to run directory-aware workloads in the cloud now powers SQL Server authentication, Amazon WorkSpaces virtual desktops, and Amazon FSx for Windows File Server for thousands of enterprises worldwide.
The beginning: Solving a real customer problem
In 2015, customers migrating Windows workloads to Amazon Web Services (AWS) faced a familiar challenge. Microsoft Active Directory (AD) had become the dominant standard for enterprise identity, by some estimates commanding 90% market share for directory services in the Fortune 1000. Running SharePoint, SQL Server, .NET applications, or virtually any Windows workload meant running AD.
However, running AD well comes with significant operational overhead. It requires careful capacity planning, high availability design across multiple sites, ongoing patching and maintenance, backup and disaster recovery procedures, and deep expertise that’s increasingly difficult to find and retain. Customers told us they wanted to focus on their applications, not on managing domain controllers.
So we built AWS Managed Microsoft AD. Powered by actual Windows Server, it delivered real Microsoft AD (not a compatible alternative, but the genuine article) as a fully managed service. We handled the domain controller deployment, the multi-AZ high availability, the automated backups, the patching, the monitoring, and many more features including scalability and multi-Region replication. Customers got a directory they could provision in 25–30 minutes and start using immediately.
“AWS Directory Service now lets you run a Microsoft Active Directory (AD) as a managed service… Host monitoring and recovery, data replication, snapshots, and software updates are automatically configured and managed for you.”
The first decade of innovation
Looking back at the past 10 years, we’re struck by how much AWS Managed Microsoft AD has evolved in response to customer feedback. Here are some of the highlights:
2015: Launch of AWS Managed Microsoft AD (Enterprise Edition) in five AWS Regions, powered by Windows Server 2012 R2. Support for trust relationships with on-premises AD, seamless domain join for Amazon Elastic Compute Cloud (Amazon EC2) instances, and integration with Amazon WorkSpaces.
2017: Introduction of Standard Edition, optimized for small and midsize businesses. This gave customers a cost-effective option for resource forest deployments and smaller workloads.
2018: Added support for schema extensions, enabling customers to extend their directory schema for applications that require custom attributes. Support for Group Managed Service Accounts (gMSA) with Windows containers and other services.
2019: Launched multi-Region replication for Enterprise Edition, allowing customers to automatically replicate their directory across AWS Regions for improved performance and disaster recovery. Added directory sharing across AWS accounts and integration with AWS Organizations.
2020: Introduced fine-grained directory settings for security and compliance, enabling customers to configure secure channel settings for protocols and ciphers. Enhanced compliance support—with the service now HIPAA eligible—included as an in-scope service under PCI DSS, and achieving FedRAMP authorization.
2021: Added CloudWatch metrics for domain controllers, helping customers optimize scaling decisions based on CPU, memory, disk, and AD-specific metrics like DNS and directory read/write operations. Launched integration with AWS Transfer Family for SFTP/FTPS/FTP authentication.
2022: Windows Server 2019 upgrade became available, with customer-initiated updates and automatic migration for all directories beginning in 2023.
2023: AWS Private CA Connector for Active Directory launched, allowing customers to replace self-managed enterprise certificate authorities with AWS Private CA for automatic certificate enrollment to domain-joined objects, with no local agents or proxy servers required.
2025: General availability of AWS Managed Microsoft AD (Hybrid Edition), allowing customers to extend their existing AD domain to AWS while retaining administrative control. Introduced self-service edition upgrades through the UpdateDirectorySetup API, eliminating the need for support tickets when scaling from Standard to Enterprise Edition.
2026 and beyond: As we enter our second decade, our roadmap continues to be shaped by the customers who depend on AWS Managed Microsoft AD every day. We’re working on new capabilities driven directly by your feedback, and we look forward to sharing more soon.
Powering identity across AWS
Over the past decade, more than 20 AWS services have added native integration with AWS Managed Microsoft AD. What started with WorkSpaces and EC2 domain join has expanded to more than 20 AWS services, making AWS Managed Microsoft AD foundational for many enterprise customers’ workloads on AWS.
Database services
For many customers, database authentication is a primary driver for adopting AWS Managed Microsoft AD. By pairing Amazon Relational Database Service (Amazon RDS) for SQL Server with AWS Managed Microsoft AD, they gain the benefits of fully managed services while achieving straightforward integration and reduced management overhead. This combination lets developers and DBAs use their existing AD credentials to access SQL Server databases, so they don’t need to manage separate database accounts.
Beyond SQL Server, AWS Managed Microsoft AD enables Windows authentication across the Amazon RDS family:
Amazon RDS for Oracle
Amazon RDS for PostgreSQL
Amazon RDS for MySQL
Amazon RDS for DB2
Amazon Aurora MySQL
Amazon Aurora PostgreSQL
File storage services
Amazon FSx for Windows File Server provides fully managed Windows file shares that integrate natively with AWS Managed Microsoft AD. Customers use AD users and groups to control access to file shares, apply Windows ACLs, and use features like DFS namespaces, all with the same management experience they use on premises.
AWS Storage Gateway supports AD authentication for SMB file shares, enabling hybrid storage architectures where on-premises applications access cloud storage using familiar AD credentials.
AWS Transfer Family added AD integration in 2021, allowing customers to authenticate SFTP, FTPS, and FTP users against their AWS Managed Microsoft AD. This allows customers to migrate file transfer workflows without changing end-user credentials.
End user computing
Amazon end-user computing services were among the first to integrate with AWS Managed Microsoft AD:
Amazon WorkSpaces: Virtual desktops provisioned and authenticated through AD
AWS IAM Identity Center (formerly AWS Single Sign-On) uses AWS Managed Microsoft AD as an identity source, synchronizing users and groups to provide single sign-on access across AWS accounts and applications. This provides centralized identity management while using your existing AD infrastructure.
AWS Client VPN authenticates users against AWS Managed Microsoft AD, providing secure remote access using corporate credentials.
Amazon EC2 instances (both Windows and Linux) support seamless domain join at launch. Windows instances can be managed using Group Policy, and Linux instances can authenticate users through SSSD or Realm integration.
Amazon Elastic Container Service (Amazon ECS) supports AD authentication for Windows containers through Group Managed Service Accounts (gMSA), enabling containerized applications to authenticate to AD-integrated resources.
Business applications
Amazon QuickSight provides business intelligence with AD-based user provisioning.
Amazon Connect provides contact center agent authentication
This breadth of integration means customers can standardize on a single directory for their entire AWS environment, from databases to desktops to file servers to analytics.
Choosing the right edition
Over the years, we’ve learned that customers have different needs when it comes to managed AD. Today, AWS Managed Microsoft AD is available in three editions, each designed for specific use cases.
Standard Edition: Basic, cost-effective identity
Standard Edition is optimized for small and midsize businesses, or for enterprises deploying a resource forest model in a single AWS Region. With 1 GB of directory object storage supporting up to 30,000 objects (approximately 5,000 users), Standard Edition provides everything needed to run directory-aware workloads without the overhead of managing domain controllers.
Common use cases:
Resource forest deployments – Many customers use Standard Edition as a resource forest, establishing a trust relationship with their on-premises AD. User identities remain in the customer’s existing domain, while the resource forest manages AWS resources like Amazon RDS for SQL Server and FSx for Windows File Server.
Development and test environments – Cost-effective option for non-production workloads
Single-Region applications – Workloads that don’t require global presence
Standard Edition is a great starting point, and customers aren’t locked in. With our new self-service upgrade capability (launched October 2025), you can upgrade to Enterprise Edition programmatically through the UpdateDirectorySetup API, no support tickets or maintenance window coordination required.
Enterprise Edition: Built for global scale
Enterprise Edition is designed for organizations with larger user populations, complex deployments, or global footprints. With 17 GB of storage supporting up to 500,000 directory objects, Enterprise Edition provides the capacity and capabilities that large enterprises require.
Key capabilities:
Multi-Region replication – Automatically replicate your directory across AWS Regions. Users and applications connect to local domain controllers, reducing latency and providing disaster recovery capabilities.
Extended directory sharing – Share your directory with up to 500 AWS accounts, enabling centralized identity across large organizations using AWS Organizations.
Higher compute capacity – Larger domain controller instances with more CPU and memory for demanding workloads
If you have users and applications in multiple geographic regions, or anticipate significant growth in directory objects, Enterprise Edition is the right choice.
Hybrid Edition: Extend your existing domain
Launched earlier this year, Hybrid Edition takes a fundamentally different approach. Instead of creating a new AD domain in AWS, Hybrid Edition extends your existing AD domain into the cloud.
What makes Hybrid Edition unique:
Same domain – AWS Managed Microsoft AD domain controllers join your existing AD. No new domain name, no trust relationships to configure.
Retain administrative control – Unlike Standard and Enterprise where you receive delegated OU permissions, Hybrid Edition preserves your existing administrative rights. Your AD administrators continue using familiar tools while changes replicate to AWS in real time.
Preserve existing investments – Security principals, group policies, and permissions transfer seamlessly. No migration of identities required.
Hybrid Edition is ideal for customers who want the operational benefits of AWS-managed domain controller infrastructure without changing their AD architecture or giving up administrative control.
Which edition should you choose?
Use the following table to determine which edition best fits your use case.
Use case
Edition
A new AD domain for AWS workloads in a single Region
Standard Edition
A resource forest with trust to on-premises AD
Standard Edition
Multi-Region replication for global deployments
Enterprise Edition
Support for more than 30,000 directory objects
Enterprise Edition
To extend your existing AD domain to AWS
Hybrid Edition
To retain full administrative control over your AD
Hybrid Edition
What we’ve learned: Design decisions that stood the test of time
Looking back at the decisions we made in 2015, several have proven foundational to the service’s success:
High availability by default – Every AWS Managed Microsoft AD directory deploys with a minimum of two domain controllers across separate Availability Zones. Customers don’t need to design high availability (HA) architecture, it’s built in.
Real Microsoft AD – We chose to run actual Windows Server AD, not a compatible alternative. This means standard AD administration tools work, existing scripts and automation work, and applications that depend on specific AD behaviors typically work without modification.
Seamless integration with AWS services – By building native integrations between AWS Managed Microsoft AD and other AWS services, we’ve made it possible for customers to use a single directory across their entire AWS environment.
Customer retains control – While AWS manages the infrastructure, customers manage their directory content. You control your users, groups, OUs, and policies using familiar tools.
Room to grow – The edition model (and now self-service upgrades) means customers can start with what they need today and scale as requirements evolve.
Looking ahead: The next chapter
As we celebrate 10 years of AWS Managed Microsoft AD, we’re excited about what’s ahead. The launch of Hybrid Edition earlier this year represents a significant expansion of what’s possible, giving customers new flexibility in how they architect their identity infrastructure for hybrid and multi-cloud environments.
We continue to listen to customer feedback and invest in capabilities that reduce operational burden while expanding what you can build. Whether you’re running your first SQL Server database in the cloud, deploying virtual desktops to a global workforce, or modernizing legacy applications that depend on AD, AWS Managed Microsoft AD is here to help.
Thank you to all the customers who have trusted us with their identity infrastructure over the past decade. Your feedback has shaped this service, and we’re committed to continuing to earn that trust for the next 10 years and beyond.
Resources
Ready to get started or learn more? Here are some resources:
AI coding agents are part of the developer toolchain. Tools like Kiro and Claude Code generate features, tests, and code refactors from natural-language prompts. A single agent can open dozens of pull requests (PRs) across your repositories in an afternoon. That productivity comes with a trade-off: agents optimize for task completion at machine speed with no understanding of your organization’s risk.
Through protocols like the Model Context Protocol (MCP), agents also reach beyond the integrated development environment (IDE) to call APIs, query databases, and modify infrastructure and even entire environments, expanding the scope of resources your application security team defends.
This post lays out an application security (AppSec) control framework for AI coding agents. Two pillars organize the framework: author-time controls shape what the agent produces in the IDE; build-time controls verify and gate what reaches production. Your existing secure software development lifecycle (SDLC) controls still apply and are critical to a defense-in-depth security strategy. The framework shows where to layer additional guardrails so AppSec scales with agent-driven development. The framework is tool-agnostic and cloud-agnostic. Throughout, we use AWS services—Kiro in the IDE and AWS CodePipeline in the build—as a running example that you can adapt to your own toolchain.
Risks
Each of the following risks includes a treatment summary. The control framework section later in this post provides implementation details. The risks are ordered by severity with the highest impact risks first.
R001. Prompt and context injection
Agents read untrusted content, such as issue descriptions, web pages, MCP responses, and README files in third-party packages. Text from outside parties can redirect the agent to disclose secrets, open unauthorized PRs, or invoke tools without user consent. This risk, known as prompt injection, is the top risk in the OWASP Top 10 for LLM Applications. Any agent that reads content from outside parties is exposed, with or without MCP, so connecting tools widens the scope of impact.
Treatment: Treat non-developer input as untrusted. A large language model (LLM) can’t reliably separate instructions from data in a single context window, so architect for it: keep the agent that orchestrates trusted actions separate from the one exposed to untrusted content and grant the exposed agent only read-only, least-privilege access. Require human approval for irreversible actions. Use version-control steering files to prevent silent tampering.
R002. Inadvertent data disclosure and overly permissive configurations
Agents optimize for getting work done. Left unchecked, the code they generate can default to wildcard identity and access management policies, open security groups, and unencrypted storage, or embed sensitive values in code rather than referencing a secrets manager. Most coding agents now include safety mechanisms that make these outcomes less likely, but they remain imperfect, so you still need controls to account for the possibility.
Treatment: Security requirements in a steering document, plus policy-as-code scanning (Checkov, cfn-nag) in the IDE and pipeline. See Context as a security control.
R003. Uncontrolled changes reaching production
Ungated code reaching production isn’t new, but AI agents amplify it. Machine-speed generation can propagate a flawed pattern across repositories before it’s identified.
Treatment: Branch protection rules requiring PR approval (a human-in-the-loop checkpoint), pre-commit hooks for security checks, and sandboxed agent runs that prevent direct pushes to protected branches. The right balance between human review and automated speed depends on the risk profile of the change. For many low-risk paths, automated checks alone might suffice, while higher-risk changes warrant a human checkpoint.
R004. Supply chain risks
Agents don’t always distinguish current best practices from outdated patterns. They might recommend deprecated packages, reference library versions with new Common Vulnerabilities and Exposures (CVEs), and hallucinate package names that don’t exist, which can introduce risks of dependency confusion issues.
Treatment: Software Composition Analysis (SCA) in the pipeline (for example, Amazon Inspector code scanning or Dependabot) to flag vulnerable or unexpected dependencies. For additional control, resolve against a scoped registry like AWS CodeArtifact. Even without a fully curated registry, lockfile validation and allow-listing critical packages reduce exposure.
R005. Uncontrolled external access
Through MCP and tool integrations, agents query databases, call APIs, and modify infrastructure. Without constraints on which tools and data an agent can reach, a single misconfigured integration provides unintended access to sensitive resources.
Treatment: Scope MCP servers to least-privilege tools and resources, enforce authn or authz on external connections, and audit tool invocations. The control point is the configuration file. Review it the same way you review AWS Identity and Access Management (IAM) policies.
R006. Hallucinations and incorrect code
Agents produce plausible-looking output. Code that compiles, passes linting, and looks reasonable can still be functionally wrong: misusing APIs, introducing subtle logic errors, or implementing security-sensitive operations incorrectly. Code that passes continuous integration (CI) but is wrong slips through review; code that fails to build is caught immediately.
Treatment: Layer deterministic verification (static application security testing (SAST), unit tests) with non-deterministic review (LLM-assisted screening against the specification). Neither catches everything alone.
R007. Scope creep
Given a bug-fix prompt, an agent might also refactor surrounding code, disable an unreliable test, or reorganize imports. Unrequested changes introduce regressions and complicate review.
Treatment: A reviewed specification document that defines what must change and what must not, paired with a targeted review of the proposed changes. See Specifications as scope boundaries.
The preceding risks share a common thread: agents produce output faster than humans can review it, and they lack context to self-correct.
The following framework addresses this gap. It organizes controls into two pillars: author-time (pre-generation and post-generation of code) and build-time (in the pipeline, before code reaches production). Author-time controls shape what the agent produces. Build-time controls verify it. Neither is sufficient alone; together they reduce the volume and severity of issues that reach human reviewers.
Deterministic compared to non-deterministic mitigations
Deterministic mitigations[D] produce the same result every time. Linters, SAST scanners, secrets detection, and policy-as-code match patterns against rules and define security invariants: no critical findings, no hardcoded secrets, and no wildcard IAM policies. Use them when the condition can be expressed as a rule. Organizations already have these and must continue enforcing them.
Non-deterministic mitigations [ND] use model judgment. They include steering documents, LLM-as-judge review, specification compliance checks, and scope-creep detection, and they evaluate intent rather than patterns. They catch novel issues that rules miss, but are probabilistic. Use them when evaluation requires context or reasoning across files. This is the new layer that AI-generated code demands, because agents produce code that can pass every deterministic check yet remain functionally wrong.
Human review[H] provides the final layer for the risk-based decisions neither tool type can make. Apply it where judgment is needed, not everywhere: routing every change to a person invites consent fatigue, where reviewers approve by reflex and the control loses its value. The default reflex is to route everything back to a human, but that isn’t always the right response—reserve human judgment for the decisions that genuinely need it.
The control framework
The framework organizes controls into two pillars. Author-time controls (Pillar 1) shape what the agent produces in the IDE, before code is generated and just after. Build-time controls (Pillar 2) verify and gate that output in the pipeline, before it reaches production. The controls within each pillar are tagged deterministic [D], non-deterministic [ND], or human [H].
Pillar 1: Author-time controls (pre- and post-generation of code)
Author-time controls work inside the IDE, where the developer and agent still hold full context. They shape the prompt and the generated output before it ever reaches a pull request. The following controls apply at this stage.
Context as a security control [ND]
Control statement: Encode security invariants as natural-language constraints in a steering document that every developer environment consumes at session start. Addresses R002. Many AI coding agent risks share one root cause: the agent lacks the security context an experienced developer carries implicitly. Your security team sets the policies, such as Amazon Simple Storage Service (Amazon S3) buckets require encryption, API gateways require mutual TLS, and credentials must come from AWS Secrets Manager. Developers don’t always have these requirements available when they’re building. They build what works, not what’s compliant. An AI agent amplifies this gap because it defaults to whatever pattern dominated its training data, with no awareness of your organization’s security posture.
A key mitigation is steering. Security teams write these invariants once as natural-language guidance in a steering document, then distribute them as shareable resources that developers consume in their IDE. The agent loads the file at session start and treats the contents as standing requirements:
IAM policies must follow least-privilege principles; no wildcard Amazon Resource Names (ARNs).
No hardcoded credentials in source code; use a secrets manager.
Security groups must not allow unrestricted inbound access.
This shifts security left, before code generation begins. Steering biases generation toward secure defaults; it doesn’t guarantee them. Treat it as a strong default, paired with the following deterministic gates that block non-compliant code from merging. Security teams define the rules once and every developer environment inherits them automatically. Steering reduces the volume of issues that reach the pipeline, though it doesn’t replace downstream scanning.
How to write effective steering rules: Keep each rule specific and testable, scope it to a concrete risk class, keep the rule set concise so the agent can hold it in context, and iterate from the issues your scanners and reviewers surface.
Specifications as scope boundaries [ND]
Control statement: Require a reviewed specification before code generation begins. Define what must change and what must not. Addresses R007.
Spec-driven workflows turn vague prompts into reviewable specifications before code is generated. This creates a human checkpoint at the design phase, where security decisions are made:
Requirements use testable notation that’s auditable before the agent writes a line of code. For example, the Easy Approach to Requirements Syntax (EARS): WHEN [condition] THE SYSTEM SHALL [behavior].
Tasks are ordered in implementation steps, each mapped back to a requirement.
For bug fixes, specifications add a critical element: unchanged behavior documentation. This is an explicit list of behaviors that must continue working, giving the agent a written boundary against scope creep.
In this model, the specification becomes the primary artifact, code is a derivative of it. Human review effort concentrates on whether the specification solves the right problem with the right constraints, not on reading implementation diffs line by line.
Controlled tool access using MCP [D + ND]
Control statement: Scope each MCP server to the minimum set of tools the agent needs, and give it a dedicated, scoped-down credential rather than the developer’s own. Maintain an allowlist of reviewed MCP servers. Addresses R005.
MCP servers act as controlled gateways between the agent, the external tools, and data:
Dependency management – An MCP server fronting your private package registry resolves dependencies against curated packages, not the public internet. This is a deterministic constraint on supply chain risk.
Infrastructure tooling – Visibility into current resource configurations prevents templates that conflict with existing infrastructure.
Scoped permissions – Each MCP server exposes a defined set of tools and resources. You choose exactly what the agent can access, supporting least-privilege at the integration layer. You supply that credential through the agent’s configuration (in Kiro, the env block of .kiro/settings/mcp.json). Avoid autoApprove: ["*"], which removes the human approval prompt on every tool call.
IDE code scanning [D]
Control statement: Run real-time static analysis in the IDE so security issues surface while the developer (and agent) still have full context. Addresses R002, R006.
Real-time diagnostics catch syntax errors, type mismatches, and configuration issues as the developer types. A malformed IAM policy is flagged before the agent builds further on it. Security-focused extensions (ESLint security plugins, Checkov, SAST) layer on top for immediate feedback while code is fresh in context.
Hooks: Automated guardrails at the point of action [D + ND]
Control statement: Attach deterministic checks to file-save events and non-deterministic verification to task-completion events. Addresses R002, R007.
Shell command hooks [D] – Triggered on file save, these run a linter, formatter, or security scanner and produce the same result every time. They enforce hard rules.
AI-powered hooks [ND] – Triggered on task completion. These prompt the agent to verify that the implementation matches the specification and check for any untested edge cases or files that were modified outside the task’s scope.
Pillar 2: Build-time controls (in the pipeline)
Build-time controls run in the pipeline after code is committed and before it reaches production. They verify and gate what the agent produced, catching what author-time controls did not. The following controls apply at this stage.
Layered security scanning [D]
Control statement: Run secrets detection, static analysis, dependency scanning, and infrastructure-as-code scanning in sequence. Fail the build on any critical finding. Addresses R002, R003, R004.
Secrets detection runs first because it’s cheapest and addresses a high-severity class of issue. It scans for hardcoded API keys, database connection strings, and credentials that AI agents might inadvertently include.
SAST scans source code for injection issues, insecure deserialization, and resource leaks. Custom rules can target AI-specific anti-patterns including overly broad exception handling, deprecated APIs, placeholder credentials, dynamic code execution through eval().
Software Composition Analysis (SCA) identifies known CVEs in dependencies. This is critical for AI-generated code, which might reference deprecated packages or hallucinate package names that open you to dependency confusion issues.
Infrastructure as code (IaC) scanning validates AWS CloudFormation, Terraform, and AWS Cloud Development Kit (AWS CDK) templates against security policies before deployment. Catches overly permissive IAM roles, unencrypted storage, and public-facing resources the agent created.
Each stage halts the pipeline on failure. Results export to a standard format (Static Analysis Results Interchange Format (SARIF)) for compliance auditing and flow downstream to human reviewers. The open source Automated Security Helper (ASH) bundles secrets, SAST, SCA, and IaC scanners behind one command that you can run locally and in AWS CodeBuild, emitting SARIF for the gates that follow.
Quality gates [D]
Control statement: Define pass/fail thresholds for each scan type. Block deployment on any critical or high-severity finding. Addresses R003.
Quality gates convert scan results into go/no-go decisions. Define thresholds for each severity: block on critical findings, require justification for highs, and track mediums. The gate is deterministic: if a threshold is breached, the pipeline stops. Exceptions require documented approval.
Differentiate blocking compared to advisory modes: hard failures on main, advisory on feature branches. Avoid gates becoming a friction that teams route around.
AI-assisted review [ND]
Control statement: Use an LLM reviewer to pre-screen every pull request for specification compliance, scope creep, and security anti-patterns before human review. Addresses R001, R006, R007.
Specification compliance – Does the implementation match the requirements document?
Scope verification – Were files modified outside the task’s stated scope?
Security pattern review – Are there logic errors, misused APIs, or insecure patterns that pass SAST but violate intent?
This pre-screening focuses human reviewer attention on genuine risks rather than formatting or obvious issues. On AWS, AWS Security Agent (code review in preview at publication) checks pull requests against AWS-managed and custom security requirements. The reviewer screens and surfaces findings; the merge decision stays with a human.
A critical principle: the agent that wrote the code should not be the agent that reviews it. A separate session helps avoid self-confirmation bias, but a separate session alone doesn’t always avoid the generator’s blind spots, because two sessions of the same model can share them. Where practical, use a different model for review so the reviewer is less likely to inherit the same systematic weaknesses.
Human-in-the-loop review [ND + H]
Control statement: Require human approval on most pull requests, especially those touching security-sensitive or high-blast-radius code. Lower-risk changes might be eligible for agent-assisted or fully automated approval as tooling matures. Provide reviewers with scan results, LLM pre-screening output, and specification context to enable fast, informed decisions. Addresses R003.
Scale review depth to the risk of the change. Low-risk or boilerplate changes can take a lighter-touch review, while security-sensitive or novel-logic changes warrant mandatory deep review and a second reviewer.
Scanners catch known patterns but can’t judge whether code implements the intended business logic. Human review also serves to calibrate trust: teams build intuition about where agents excel (boilerplate, test writing) and where they’ve tended to struggle (novel business logic, security-sensitive operations), recognizing that this frontier shifts as models improve.
Place two approval gates: after security scans (reviewer focuses on correctness and business logic, with scan results as context) and before production deployment (final sign-off after integration testing). Treat human review as a secondary control, not a guarantee: reviewers are themselves non-deterministic and can miss issues, so human review layers on top of the deterministic gates rather than replacing them.
Putting the framework into practice on AWS
The framework is tool-agnostic, but AWS gives you building blocks for each pillar. The following services map directly to the controls described previously: Kiro for author-time guardrails, and CodeBuild and CodePipeline for build-time gates.
Kiro: Structured AI development
Kiro maps to Pillar 1: It puts the author-time controls in the IDE, where the developer and agent still share full context. Each feature in the following list implements one of those controls, configured in-repo under .kiro/ so the guardrails are version-controlled and shared across the team rather than set per developer.
Steering documents – Markdown files in .kiro/steering/ load into the agent’s context at session start. Conditional inclusion using fileMatch (for example, ["**/*.tf"]) loads IaC-specific rules only when relevant.
Specification-driven workflows – Three-phase specifications (requirements in EARS, design, and tasks) with review checkpoints. Bug-fix specifications capture unchanged behavior explicitly.
Agent hooks – Triggered on file save, tool invocation, or task completion. Shell hooks run deterministic checks (linters, tests); Ask Kiro hooks run AI prompts for non-deterministic review. For example, a security pre-commit scanner hook can flag hardcoded credentials when the agent finishes a task.
Property-based testing – Guided by a specification or hook, Kiro can generate property-based tests (for example, using the hypothesis library) that exercise hundreds of randomized inputs, probing edge cases a hand-written test suite would miss.
MCP integrations – Connect Kiro to private package registries, internal docs, issue trackers, and infrastructure tooling, creating the controlled tool access pattern.
AWS CodeBuild and AWS CodePipeline: Pipeline controls
CodeBuild runs each scanning tool (checking for secrets, SAST, SCA, and IaC) as a build action. A non-zero exit code fails the action, and the stage halts or rolls back according to its OnFailure setting. Findings export as SARIF to Amazon S3 for compliance, and CodePipeline action variables pass results to downstream approval actions.
CodeBuild exit codes halt the pipeline on scan failures
AWS Lambda invoke actions evaluate scan results against configurable thresholds and return pass/fail decisions
Manual approval actions halt the pipeline, send Amazon Simple Notification Service (Amazon SNS) notifications, and link to review artifacts; decisions and reviewer identity are logged for audit
The following table consolidates the framework into a single view that includes each stage of the SDLC and the deterministic [D] and non-deterministic [ND] controls that apply there. Every stage carries both, a reminder that neither control type is sufficient on its own.
Full security scan suite, integration tests, and policy-as-code
AI-assisted review for human approvers
Post-deploy
Runtime monitoring and anomaly detection
AI-powered incident triage
Conclusion
This post laid out a framework for adopting AI coding agents at machine speed without letting unreviewed risk reach production. It layers guardrails at two points:
Author-time controls – Steering, specs, and scoped tools shape what the agent generates in the IDE.
Build-time controls – Scanning, quality gates, and layered review verify it before it reaches production.
No single layer is enough: deterministic gates enforce hard rules, non-deterministic review catches what they miss, and human judgment is reserved for the decisions that need it. Together, they let AppSec scale with agent-driven development.
Where to start this week:
Start with steering and specs – Encode security requirements as steering and use specifications for new features. Highest impact, lowest effort. For a ready-made starting set, the open source Project CodeGuard (a Coalition for Secure AI project under OASIS Open, of which Amazon is a contributing member) publishes reusable steering rules for common risk classes—hardcoded credentials, IaC misconfiguration, supply chain, and MCP security—that you can adapt to your AWS environment.
Add deterministic pipeline gates – Integrate SAST, SCA, and secrets detection. Table-stakes regardless of AI usage.
Calibrate and iterate – Review what controls catch, adjust steering for recurring issues, and expand agent autonomy as trust builds.
Accountability – Developers remain accountable for the security of what they ship. AI agents accelerate development; they don’t transfer ownership.
Choosing the right cryptographic key management service on Amazon Web Services (AWS) starts with understanding the difference between AWS Key Management Service (AWS KMS) and AWS CloudHSM. Both provide key storage backed by a hardware security module (HSM) but serve very different needs. AWS KMS is a fully managed service that integrates with all AWS services and all AWS Regions, making it the right choice for most key management workloads. AWS CloudHSM is a specialized option for use cases where you have strict requirements for dedicated HSM instances or must support legacy applications built around traditional HSM interfaces.
Quick comparison
The following table shows the pricing, AWS Region availability, algorithms, and AWS service integrations as of July 2026.
Criteria
AWS KMS
AWS CloudHSM
Best for
Most cloud-based key management needs
Lift-and-shift from on-premises applications and use of legacy algorithms
Deployment
AWS managed HSMs, accessed through API endpoints
Customer managed HSMs, accessed through an Elastic Network Interface (ENI) in your virtual private cloud (VPC)
Cost
Pay per use (symmetric and RSA 2048 operations): $1 per key plus $0.03 per 10,000 requests per month
Pay by the hour (us-east-1): $1.60 per HSM instance per hour
AWS integration
All AWS services
Custom integration with AWS services
Region coverage
All AWS Regions
32 Regions
Quick decision guide
Choose AWS KMS for most use cases. Choose AWS CloudHSM only if you require:
Direct integration with third-party tools such as Microsoft SignTool, Nginx, and HAProxy that rely on traditional HSM interfaces, including: PKCS#11, Java Cryptographic Extension (JCE), OpenSSL Provider, and Key Storage Provider (KSP). These interfaces are required when your application is built to communicate with an HSM directly rather than through a cloud API.
Deprecated algorithms such as 3DES and PKCS#1 v1.5 with RSA. If you need to run less commonly used operations not supported by AWS KMS such as AES key wrapping and AES with CTR or CBC modes.
Shared benefits
AWS KMS and AWS CloudHSM both provide robust encryption key management capabilities that help organizations meet their security and compliance requirements. While each service offers distinct features tailored to different use cases, they share several core benefits that make them valuable tools for protecting sensitive data in the cloud.
Security
AWS KMS and AWS CloudHSM both provide tamper-resistant, HSM-based key management with physical data center controls. They secure administration and workloads with Transport Layer Security (TLS). Neither service allows AWS employees to access your key material. Both services deliver equivalent security through Federal Information Processing Standard (FIPS) 140-3 Level 3 validated hardware and enforce strict cryptographic isolation of customer keys. Compliance frameworks such as the ones listed below validate security based on cryptographic boundaries rather than hardware or partition dedication. The multi-tenant architecture of AWS KMS provides the same security guarantees as the single-tenant model used by AWS CloudHSM while reducing operational complexity and cost. Customer security teams consistently approve AWS KMS adoption after confirming that cryptographic isolation meets their single-tenant security and compliance requirements.
Regulatory compliance
AWS KMS and AWS CloudHSM meet major compliance certifications, including:
Federal Information Processing Standard (FIPS) 140-3 Level 3
Payment Card Industry Data Security Standard (PCI-DSS)
Health Insurance Portability and Accountability Act (HIPAA)
Federal Risk and Authorization Management Program (FedRAMP)
Both services protect data including personally identifiable information (PII) and Protected Health Information (PHI).
Standard algorithms
AWS KMS and AWS CloudHSM support standard cryptographic operations including AES-256, RSA, ECDSA, Ed25519, ECDH, ML-DSA, SHA-2, and HMAC. Both services are actively investing in post-quantum cryptography (PQC) to help customers prepare for future quantum computing threats and are committed to expanding PQC algorithm support as National Institute of Standards and Technology (NIST) standards are finalized.
Performance
AWS KMS supports a default request rate for cryptographic operations ranging from 10,000 transactions per second (TPS) to 100,000 TPS per account based on Region. You can request quota increases beyond the default limits. AWS CloudHSM requires explicit provisioning of additional instances for higher throughput. Customers typically provision at least one additional HSM instance to handle peak activity, which can be difficult to predict due to lack of utilization metrics.
Operational support
AWS KMS and AWS CloudHSM both support high availability, durability, automatic backup, and software patching. AWS KMS is a Regional service with high availability and durability provided without any customer management required. AWS CloudHSM is a zonal service with customers required to manage high availability and durability.
Given these shared capabilities, the choice of which service to use depends on your specific requirements. The following sections outline decision points to help you choose.
When to choose AWS KMS
AWS KMS offers a fully managed service that simplifies key management operations and reduces operational overhead compared to AWS CloudHSM. Organizations choose AWS KMS when they need seamless integration with AWS services, automatic key rotation, and a cost-effective solution that doesn’t require dedicated HSM management.
AWS integration
AWS KMS integrates with all AWS services across all major categories. These include AI platforms, storage, databases, and compute services. Most of these services support AWS KMS customer managed keys, giving you full control over the key using policies and access controls. For customers that value convenience over control, AWS services provide transparent encryption using AWS owned keys, eliminating the cost and lifecycle management overhead of customer-owned keys. Both customer managed and AWS owned keys are AWS KMS keys. AWS Identity and Access Management (IAM) enables least-privilege access controls, key policies to control access, and auditing all key usage through AWS CloudTrail.
Operational simplicity
AWS KMS handles all operational tasks including HSM instance provisioning and maintenance, automatic key rotation, auto-scaling, disaster recovery, and comprehensive audit logging. This eliminates the operational overhead required to maintain a solution based on AWS CloudHSM.
Cost considerations
AWS KMS costs $1 per month per key plus $0.03 per 10,000 requests (symmetric and RSA 2048 operations). AWS CloudHSM costs approximately $1.60 per hour per HSM (approximately $1,152 per month), excluding the operational overhead for staff to manage the cluster—which further favors AWS KMS for most workloads.
Break-even analysis:
Less than 500 million operations per month: AWS KMS typically costs 35–99% less
500 million–1 billion operations per month: Costs are comparable
More than 1 billion operations per month: AWS CloudHSM might be more cost-effective.
Note: Many AWS services cache Data Encryption Keys (DEKs) locally, significantly reducing the number of AWS KMS API calls. Actual AWS KMS costs at scale are often much lower than raw operation counts suggest. For example: A workload with 100 keys and 100 million monthly operations using two HSMs for high availability:
AWS CloudHSM: Approximately $2,304 per month for two HSMs plus operational costs
AWS KMS: $100 per month (keys) plus $300 per month in operational costs for a total of $400 per month
Savings using AWS KMS: $1904 per month (83% reduction)
Region coverage
AWS KMS operates in every AWS Region, including all commercial Regions, GovCloud, China Regions, and the European Sovereign Cloud Region. AWS CloudHSM operates in 34 Regions, and AWS evaluates each new Region individually for AWS CloudHSM support.
When to choose AWS CloudHSM
AWS CloudHSM provides HSM-specific interfaces and support for legacy cryptographic algorithms that aren’t available from AWS KMS.
Lift-and-shift on-premises workloads
AWS CloudHSM supports traditional HSM interfaces such as PKCS#11, JCE, OpenSSL, and KSP, simplifying migration to AWS with minimal application changes. AWS is actively expanding AWS KMS integration options for these workloads. Contact AWS Support to discuss current alternatives.
Legacy cryptographic algorithms
AWS CloudHSM supports deprecated algorithms such as 3DES and PKCS#1 v1.5 padding with RSA. It also supports less commonly used operations such as AES key wrapping and AES with CTR or CBC modes.
Conclusion
For most organizations, AWS KMS delivers enterprise-grade security with lower costs and zero operational overhead. Choose AWS CloudHSM only if you have specific requirements for traditional HSM interfaces or less commonly used algorithms and can justify the additional cost and operational complexity.
Ready to get started? Use these guides to implement your chosen solution:
WordPress updates help close known vulnerabilities before automated attacks can find and exploit them. Once a patch is released, attackers often move quickly to scan for sites that have not yet updated.
It’s easy to put off updates when everything seems to be working. But once a vulnerability is public, attackers do not need to single out your site. Automated bots scan thousands of sites for outdated WordPress core, plugins, themes, and server setups.
If you’re building multi-agent AI systems, you need to prevent authorization scope from silently expanding as agents delegate tasks through multi-hop chains. Without proper controls, an agent can potentially act beyond what the originating user authorized, even when role-based access control (RBAC) policies are in place. The OWASP Top 10 for Agentic Applications classifies this risk as ASI03: Identity & Privilege Abuse.
This post shows you how to address the potential risk using a three-layer policy model built with Cedar, an open source authorization policy language, deployed on Amazon Web Services (AWS). The reference implementation uses OAuth 2.0 for authentication and Cedar for authorization. A trusted identity provider authenticates the originating user, then Cedar policies enforce authorization across three layers using verified token claims.
Reference implementation overview
To enforce authorization at each hop in a multi-agent delegation chain, the reference implementation uses two AWS Lambda functions in sequence. A Model Context Protocol (MCP) adapter Lambda function normalizes inbound requests and cryptographically signs the originating user context. This prevents downstream tampering. A Cedar evaluator Lambda function evaluates three independent policy layers sequentially, halting on the first deny.
Table 1: Three-layer Cedar policy evaluation model
Layer
What it checks
Principal to resource
L1 – Agent-to-tool
Whether the invoking agent has a sufficient trust score (1–5), belongs to the correct namespace (for example, payments), and is in the production lifecycle stage
Agent to tool
L2 – Agent-to-agent delegation
Whether the delegation hop count is within the hard limit of five, and whether requested tasks are a subset of the target agent’s registered capabilities
Agent to agent
L3 – Originating user authorization
Whether the human who initiated the chain has the required role (for example, admin), has completed MFA, and is within the allowed delegation depth
Agent to tool (user in context)
Architecture
Cedar evaluates authorization but doesn’t establish identity. Before Cedar can evaluate context.originating_user.role or context.originating_user.mfa_verified, a trusted authentication layer must establish the user’s identity and produce verifiable claims. Steps 1–3 handle authentication; steps 4–10 handle authorization. The architecture shown in Figure 1 is described in the following lists:
Authentication (steps 1–3)
The originating user authenticates with an OIDC-compliant identity provider (in this reference implementation, Amazon Cognito with TOTP multi-factor authentication (MFA)). The identity provider (IdP) issues a signed JSON Web Token (JWT) containing claims such as sub, role, amr (authentication methods), and session_id.
Amazon Cognito returns the signed JWT to the user.
The user passes the JWT and task request to the AI agent (MCP client). The agent carries the originating user context in the MCP _meta envelope.
Authorization pipeline (steps 4–10)
The AI agent sends a Model Context Protocol (MCP) request to AWS WAF, which filters using CommonRuleSet, SQLiRuleSet, rate limiting, and body size constraints.
Amazon API Gateway (with Amazon Cognito authorizer) verifies the JWT signature against the user pool’s public keys and rejects invalid or expired tokens. Valid requests are forwarded to the MCP protocol adapter Lambda function, which applies Amazon Bedrock Guardrails content filtering.
The adapter extracts verified claims from the token and maps them to Cedar context attributes:
JWT role claim : context.originating_user.role
JWT amr includes MFA method: context.originating_user.mfa_verified = true
JWT sub: context.originating_user.user_id
JWT sid: context.originating_user.session_id
JWT amr claim: context.originating_user.authentication_method
The adapter then computes an HMAC-SHA256 signature over the user context (user_id, role, mfa_verified, authentication_method, and session_id in canonical order) using a key from AWS Secrets Manager.
The adapter constructs a signed request envelope and invokes the Cedar evaluator Lambda function.
The evaluator verifies the HMAC-SHA256 signature, retrieves L2 and L3 Cedar policies from Amazon Verified Permissions, and evaluates all three layers (L1, L2, and L3), halting on the first deny.
Two mechanisms work together to protect identity across hops:
Hash-based Message Authentication Code (HMAC-SHA256) ensures integrity and authenticity. Every downstream evaluator verifies this signature before trusting the context.
OAuth 2.0 Token Exchange (RFC 8693) sets delegation scope using the on-behalf-of (OBO) pattern. When the orchestrator delegates to a downstream agent (data-bot), it exchanges the original token for a scoped OBO token that records who’s acting on behalf of whom and with what authority. The Cedar policies (detailed in Step 2: Three-layer policies) then check whether that scoped delegation is permitted and verify the originating user claims carried in the OBO token. Token exchange limits each downstream agent to only the delegated task’s scope instead of passing through the full original token. For enterprise deployments, use token exchange alongside HMAC. OAuth tracks who is acting on behalf of whom and with what scope. HMAC verifies that the context hasn’t been tampered with and came from a trusted source.
Prerequisites
The following prerequisites are needed to deploy the reference implementation. Before you begin, clone the repository:
git clone https://github.com/aws-samples/sample-cedar-agentic-ai-authorization.git
cd sample-cedar-agentic-ai-authorization
In this walkthrough, you define the Cedar entity schema and policies, deploy the infrastructure with AWS CDK, and integrate your identity provider.
To define the Cedar entity schema
In this step, you define a schema with two entity types (Agent and Tool) and two actions (invoke_tool and delegate_task) in the AgentAuthz namespace. Notice that there is no User entity. Instead, you carry the originating user’s identity in the evaluation context record, which is a structured data object passed alongside each authorization request.
This schema is deployed to an Amazon Verified Permissions policy store by the VerifiedPermissionsStack CDK stack. In the reference implementation, the schema file is located at cedar-entity-schema.json.
Agent topology and attributes
The following tables show the agents and tools registered in this reference implementation, along with the attributes the Cedar evaluator function retrieves from the entity store. The test scenarios that follow trace requests through this topology.
Table 2: Agent attributes
Entity
Type
trust_level
namespace
lifecycle_stage
registered_capabilities
orchestrator
Agent
5
orchestration
production
delegate_task
route_request
finance-agent
Agent
3
payments
production
process_payment
refund
data-bot
Agent
4
data
production
query_records
delete_records
Table 3: Tool attributes
Tool
namespace
risk_level
process_payment
payments
medium
delete_records
data
high
query_records
data
low
The orchestrator can delegate to both data-bot and finance-agent. Each agent can only invoke tools within its registered capabilities. The test scenarios below trace requests through these delegation paths.
To create three-layer Cedar policies
The following policies are deployed to the same Verified Permissions policy store. In the reference implementation, policy files are located under cedar/policies/ organized by layer: layer1-agent-to-tool/, layer2-agent-to-agent/, and layer3-originating-user-auth/.
Layer 1 (agent-to-tool): This policy permits the finance-agent to invoke the process_payment tool only when three conditions are met: the agent’s trust score is at least 3, it belongs to the payments namespace, and it’s deployed in the production lifecycle stage. If any condition fails, the request is denied. The agent’s trust_level, namespace, and lifecycle_stage aren’t self-reported in a production deployment. Instead, the evaluator retrieves these attributes from the Verified Permissions entity store using the agent_id as a lookup key.
Important: The reference implementation accepts these values from the request payload for simplicity. Production deployments must validate agent attributes against an authoritative source to prevent a compromised agent from escalating its own trust.
The trust_level attribute uses a 1–5 integer scale that represents an agent’s verified maturity: 1 for newly registered and untested agents, 3 for agents that have passed integration testing and security review, and 5 for agents with a proven production track record. Organizations assign trust levels through their agent promotion pipeline, not through self-declaration. The lifecycle_stage attribute (development, staging, production) prevents pre-production agents from invoking production tools, even if they have the correct namespace and trust score.
Layer 2 (agent-to-agent delegation) enforces depth limits and capability constraints. The orchestrator agent delegates tasks to data-bot only when the delegation chain is three hops or fewer and the requested capabilities are a subset of data-bot’s registered capabilities. A separate forbid policy (L2-004) enforces a hard system-wide limit of five hops regardless of which agents are involved.
// L2-002: Orchestrator can delegate to data agent
permit(
  principal == AgentAuthz::Agent::"orchestrator",
  action == AgentAuthz::Action::"delegate_task",
  resource == AgentAuthz::Agent::"data-bot"
) when {
  context.delegation_depth <= 3 &&
  context.target_capabilities.containsAll(context.requested_capabilities)
};
Layer 3 (originating user authorization) keeps the agent as the principal, but the policy evaluates context.originating_user to validate the human who initiated the request. data-bot invokes the delete_records tool only when the originating user has the admin role, has verified MFA, and the delegation chain is at most two hops deep. Without this layer, an agent with the right capabilities could invoke destructive tools regardless of who initiated the request.
Key design point: The principal remains the agent, not a user entity. The user’s role and MFA status are checked through context attributes, keeping the schema to two entity types and two actions.
Integrate your IdP
The reference implementation uses Amazon Cognito with TOTP MFA, but most OIDC-compliant providers (Okta, Microsoft Entra ID, Auth0, or AWS IAM Identity Center) work with this pattern. The authentication-to-signing flow is described in the preceding Authentication before authorization section. To use a different IdP, replace the Cognito authorizer on API Gateway with a Lambda or JWT authorizer for your IdP’s issuer URL. Cedar policies remain unchanged.
Deploy the infrastructure with AWS CDK
The reference implementation deploys five CloudFormation stacks: KmsStack, VerifiedPermissionsStack, LambdaStack, SecurityLakeStack, and MonitoringStack. The following commands deploy the stacks in dependency order:
The end-to-end tests cover the three scenarios described in the following sections. Each test sends a request through the deployed API and validates the per-layer authorization decisions.
Scenario A: Layer 3 enforcement
A support-role user (no MFA) requests record deletion through orchestrator and data-bot.
Layer
Decision
Reason
L1: Agent-to-tool
PERMIT
data-bot has trust level 4, namespace data, and lifecycle production
L2: Agent-to-agent
PERMIT
orchestrator is authorized to delegate to data-bot, depth within limits
L3: Originating user
DENY
User role is support, not admin; MFA not verified
Overall
DENY
Denying layer: L3
Without Layer 3, this request would have been permitted based on agent capabilities alone, demonstrating why originating user authorization is essential.
Scenario B: Authorized admin request
An admin user with MFA requests the same operation through the same chain.
Layer
Decision
Reason
L1
PERMIT
Agent attributes match
L2
PERMIT
Delegation path authorized
L3
PERMIT
Role is admin, MFA verified, depth is less than or equal to 2
Overall
PERMIT
All three layers permit
Scenario C: Delegation depth limit
An admin with MFA requests the same operation, but the delegation chain has six hops. This scenario tests the Layer 2 depth constraint independently of user authorization.
Layer
Decision
Reason
L1
PERMIT
Agent attributes match
L2
DENY
Depth of six exceeds the hard limit of five
Overall
DENY
Denying layer: L2 (L3 not evaluated – halt)
Even an authorized admin can’t bypass the delegation depth constraint.
Alignment with the security principles for agentic AI
Property-based testing (Hypothesis) for adversarial input fuzzing, Cedar policy formal verification with strict schema validation, end-to-end scenarios testing policy bypass and privilege escalation paths, and infrastructure-as-code (IaC) with AWS CDK.
Traditional security controls remain applicable
AWS WAF, Amazon VPC isolation, AWS Key Management Service (AWS KMS) encryption, Amazon Cognito MFA, and Secrets Manager; NIST SP 800-53 control mapping.
Deterministic external controls (security box)
Three-layer Cedar evaluation runs outside the agent’s reasoning loop in a separate Lambda function. HMAC-signed context prevents tampering. Verified Permissions (the managed Cedar evaluation service) enforces L2 and L3 at the infrastructure level.
Greater autonomy earned through evaluation
trust_level and lifecycle_stage policy attributes calibrate agent capabilities; OCSF 99001 audit events and Amazon CloudWatch dashboards provide the evidence base for expanding autonomy.
Monitoring and audit compliance
Each evaluation produces an OCSF 99001 audit event with request ID, user identity, delegation chain, per-layer decisions, and latency.
The following table maps this implementation to NIST SP 800-53 Rev. 5 controls. Customers are responsible for evaluating whether it meets their compliance requirements.
NIST control
Control name
How the reference implementation addresses it
AC-4
Information Flow Enforcement
User context flows immutably through HMAC-signed envelopes
AC-6
Least Privilege
Three-layer evaluation requires both agent capability and user role
AC-6(1)
Authorize Access to Security Functions
MFA required for high-risk tools in Layer 3
AC-6(5)
Privileged Accounts
Destructive operations restricted to admin with MFA verified
AU-2
Event Logging
Each evaluation is logged as OCSF 99001
AU-3
Content of Audit Records
Events include identity, chain, action, resource, decisions, and latency
SI-10
Information Input Validation
HMAC verified before evaluation; Amazon Bedrock Guardrails on inbound
IA-2(1)
Multi-factor Authentication
Layer 3 enforces MFA for high-risk operations
SC-12
Cryptographic Key Management
Signing key in Secrets Manager with rotation
SC-28
Protection of Information at Rest
Policies in Verified Permissions with STRICT validation
Scaling to multi-account environments
Deploy the Cedar policy store in a central security account and use cross-account IAM roles for workload accounts to call verifiedpermissions:IsAuthorized. Use AWS Organizations service control policies (SCPs) to prevent workload accounts from creating their own policy stores. For standardizing user identity attributes across the organization, consider IAM Identity Center or a centralized OIDC provider that issues consistent claims to your workload accounts. This helps ensure that the context.originating_user attributes are uniform across accounts and agents.
Multi-agent AI systems need authorization boundaries at every delegation hop. The three-layer Cedar policy model with OAuth 2.0 authentication provides that protection while maintaining least-privilege access. Combining a trusted IdP (AuthN) with Cedar policy evaluation (AuthZ) creates an authorization boundary around each tool invocation, verifying agent capability (L1), delegation path (L2), and originating user authority (L3). The pattern works with an OIDC-compliant IdP and a compute platform that can call Amazon Verified Permissions. Clone the reference implementation and adapt the Cedar policies to your organization’s requirements. For more information, see the Cedar policy language documentation and the Amazon Verified Permissions User Guide.
The AWS Customer Incident Response Team (AWS CIRT) encounters patterns that repeat across engagements when helping customers respond to security incidents. We’re passionate about making sure that information is accessible so that everyone can improve their security posture and their organization’s resilience to disruption. The primary method we use to share this information is the Threat Technique Catalog for AWS (TTC). The latest update to the catalog for June 2026 focuses on container security, organization-level trust, and compute hijacking. Each new entry reflects something we’ve encountered in practice, and each provides straightforward mitigation. This post breaks down what changed, why it matters, and what you can do about it today.
What we’re seeing
We’ve added five new entries to the TTC.
EKS workload modification
Amazon Elastic Kubernetes Service (Amazon EKS) gives teams powerful orchestration capabilities. We’re seeing threat actors who have obtained Kubernetes credentials or an AWS Identity and Access Management (IAM) role with EKS permissions modify running workloads—altering container images, injecting sidecar containers, or changing pod specifications to introduce malicious code into a deployment.
Nothing new is created. The workload already exists, it might be running in production, and by modifying it in place the threat actor inherits the network access, service account permissions, and data access the legitimate workload already had. Without admission controllers or image verification, these changes can go unnoticed until the impact shows up downstream. Enforcing image signing through admission controllers, restricting workload changes with Kubernetes role-based access control (RBAC), and enabling Amazon GuardDuty EKS Protection to surface anomalous cluster activity all reduce this risk. For more information, see EKS Modification – Workload Integrity Degradation.
Exploit public-facing application – EKS
Publicly exposed Kubernetes API servers and misconfigured ingress controllers continue to be an entry point we see exploited. This technique captures threat actors targeting the customer-deployed workloads running on Amazon EKS—not EKS itself—and their exposure to the internet.
The pattern starts with an exposed service and an application-level weakness, then pivots from the compromised pod toward broader cluster access. When inside a pod, a threat actor can query the instance metadata service, read mounted service account tokens, or move laterally across the cluster network. Limiting public exposure of the Kubernetes API server, applying network policies to restrict pod-to-pod communication, and running workloads with least-privilege service accounts reduce the risk of this technique succeeding. For more information about this technique, see Exploit Public-Facing Application.
Assume root into organization member account
AWS Organizations centralizes trust across member accounts, and that trust runs in one direction—from the management account downward. We’ve observed threat actors who compromise a management account—or gain sufficient privilege within one—use that position to assume root access into member accounts using sts:AssumeRoot. Because the trust is inherent to the organization structure, this can avoid the access controls a member account administrator has configured.
With root access to a member account, a threat actor can disable security controls, delete resources, change billing configurations, and establish persistence that survives remediation focused on IAM principals. We strongly encourage implementing service control policies (SCPs) that restrict which principals can call sts:AssumeRoot and under what conditions, and monitoring for sts:AssumeRoot calls in AWS CloudTrail. For more information, see Assume Root into Organization Member Account.
Compute hijacking – EKS
Compute hijacking remains one of the most common motivations we see behind unauthorized access, and Amazon EKS clusters are increasingly the target. Threat actors deploy cryptocurrency mining or other compute-intensive workloads inside compromised clusters, consuming customer resources and generating unexpected cost.
What sets EKS-based hijacking apart is scale. In clusters without resource quotas, a single compromised service account can consume all available capacity across nodes. The workloads use legitimate-looking images pulled from public registries, which makes image scanning alone insufficient. Setting resource quotas and limit ranges, restricting which registries workloads can pull from, and enabling Amazon GuardDuty EKS Protection to flag mining behavior provides effective detection. For more information, see Resource Hijacking: Compute Hijacking – EKS.
Invite accounts to unknown organization
A threat actor with access to a standalone account—or one they’ve removed from its legitimate organization—invites it into an organization they control. After the account joins, it falls under the threat actor’s governance. The threat actor’s organization can apply SCPs that restrict the legitimate owner’s actions, gain visibility into the account’s resources through organizational services, and access consolidated billing information. The legitimate owner finds themselves locked out of their own governance controls. Monitoring organizations:InviteAccountToOrganization and organizations:AcceptHandshake, and implementing SCPs that prevent accounts from leaving their legitimate organization are important preventive measures. For more information, see Modify Cloud Resource Hierarchy: Invite Accounts to Unknown Organization.
What’s updated
We’ve refreshed three existing entries. S3 Object Collectionnow captures additional API calls used for bulk data staging from Amazon Simple Storage Service (Amazon S3), with refined detection guidance and mitigations that use recent Amazon S3 security features. Compute Hijacking – ECSadds methods threat actors use to deploy unauthorized tasks in Amazon Elastic Container Service (Amazon ECS), including abuse of overly permissive task execution roles. Role Assumption and Federated Access has been expanded to cover new cross-account role assumption variations and identity provider manipulation, with sharper guidance for distinguishing legitimate federated access from unauthorized use.
The current trend
This June update reflects a clear trend: threat actors are increasingly targeting container orchestration platforms and using organizational trust relationships to their advantage. The container techniques show that as organizations adopt Kubernetes at scale, the attack surface grows with it. The organization-level techniques show that threat actors understand organizational trust relationships.
The common thread is that every one of these techniques operates within the boundaries of legitimate functionality. Modifying a workload, assuming cross-account trust, and joining an organization are all expected actions in healthy environments.. Detection, then, depends entirely on context: the principal, the timing, and the sequence of events that follows.
The Threat Technique Catalog for AWS is designed to help with this. We encourage teams to review the relevant entries and assess whether their current monitoring would catch these patterns:
Unexpected modifications to EKS workload specifications
Pod deployments that use unsigned container images
sts:AssumeRoot calls into member accounts
Unbounded compute consumption in your EKS clusters that could be prevented by resource quotas
Unexpected organization invitations to your accounts
Each of the threats leaves traces in AWS CloudTrail and Kubernetes audit logs, and the TTC provides specific guidance on what to watch for and how to respond.
Looking ahead
The Threat Technique Catalog for AWS exists because we believe the patterns we observe during security engagements shouldn’t stay behind closed doors. When we see techniques repeating across customers, the most effective thing we can do is document them and make that knowledge available so you can act on it before you’re in the middle of an incident.
This June update adds five new entries and updates three existing ones, and the catalog will continue to evolve. Our team updates it based on what we’re seeing in the real world when helping customers respond to security events. We encourage security teams to review the catalog, incorporate its techniques into threat modeling exercises, and use it as a shared vocabulary for discussing cloud-specific threats.

 Login