A critical vulnerability has been discovered in the popular WordPress content management system that allows attackers to execute arbitrary code on the web server. The vulnerability has been assigned the number CVE-2026-87902. The good news is that on September 22, WordPress released an update that patches it. The bad news is that the first attempts to exploit CVE-2026-87902 were detected just a few hours after the patch was released. Therefore, all companies whose corporate websites or blogs run on this platform are advised to update immediately.
WordPress versions affected by CVE-2026-87902
According to data published by WordPress on GitHub, all versions of the CMS from 4.7.0 through 7.1.1 are vulnerable. The company has released updates for all supported branches of the system; a complete table listing the patched version numbers can be found on the company’s GitHub page. The latest version of WordPress should be updated to version 7.1.2 (or newer).
What’s the nature of the CVE-2026-87902 vulnerability, and why is it so dangerous?
Under normal circumstances, WordPress loads PHP template files only from a specific folder within the active theme. However, due to the CVE-2026-87902 vulnerability, an attacker can craft a request to WordPress in such a way that an arbitrary PHP file is included — without requiring any authorization. Yes, the file must already be uploaded to the targeted server in some way, but that’s not really a problem for an attacker.
It sounds like a path traversal vulnerability, but in most publications, CVE-2026-87902 is classified as an RCE (Remote Code Execution) vulnerability because, under certain WordPress and PHP server configurations, the attack can lead to the execution of arbitrary code.
How to stay safe
The only way to secure a corporate WordPress site is to install the latest version. The researcher who discovered the vulnerability also offers several tips for hardening CMS security, but emphasizes that these are meant to complement the patch, not replace it.
The Hacker News lists several PHP filenames and IP addresses used in the attack via CVE-2026-87902. These can serve as indicators that a WordPress instance has been compromised.
Given that only a few hours pass between the publication of information about a vulnerability’s existence and the start of attacks exploiting it, it’s crucial for companies to have a properly configured, centralized vulnerability management system. To achieve this, they should have a specialized solution capable of identifying and resolving vulnerabilities, prioritizing them based on actual risks, and automating remediation processes. Our vulnerability management module for Kaspersky Next Optimum can help with this task.
Not long ago, many companies began actively implementing AI agents in a wide variety of workflows. Very quickly, the cost of using them became a pressing issue for companies. Moreover, it’s an issue that concerns more than just finance department — in addition to budgetary concerns, issues of reliability, operational stability, and even information security have emerged. This is because the cost of automating one and the same process varies significantly from one deployment to the next, is unpredictable, and could be subject to external influences.
Furthermore, for a malicious actor attacking an organization, any process automated using AI and vulnerable to external influence is, in essence, a convenient target for a “new type of DDoS attack”. Application-error reports, product reviews, or technical support requests can (just like any other external data that a company processes via AI) serve as a tool in an attack aimed at increasing consumption of tokens (word fragments that serve as the basic unit of input and output of an LLM).
A year of explosive growth… in bills
In 2026, large companies significantly overspent on their AI system budgets for the first time. Uber had spent its entire annual budget by April, while an unnamed company failed to set spending limits for Claude and spent $500 million in a single month. Although AI providers regularly announce lower prices and more efficient models, the shift from chatbots to agentic systems that operate continuously and autonomously increases token consumption by hundreds or thousands of times. At the same time, the “fixed subscription for $20 or $100” model for companies is becoming a thing of the past; all major providers are transitioning business clients to pay-as-you-go billing.
As a result, companies are facing a problem all too familiar to cloud hosting and cellular communications industries. In the absence of specialized cost accounting and management systems, an organization only learns how much a particular process or project will cost after it’s completed. In the telecom and cloud sectors, this problem was eventually solved through the development of sophisticated billing systems, and their clients have even adopted the specialized term FinOps. For AI, this process is still in its infancy. Moreover, solving the problem will be complicated by the probabilistic nature of generative AI.
Unpredictable token consumption
To understand why costs rise so quickly and are so difficult to predict and control, we need to recall how a language model works and what turns it into an AI agent. The model is stateless; in other words, it does not retain any information between interactions. Every time the agent takes the next step, the entire history of work on a specific task (the context) must be resent to the model: the initial prompt, previous reasoning, the contents of the files it has read, and the responses from all tools. With each step, this “recap” grows longer — especially if the task involves iterative loops. If a step fails, or the response is unclear, or a tool returns an error, the agent simply tries again — further inflating the size of the context. And if the task is performed not by a single but by several agents, which divide the work among themselves and exchange results, this volume is multiplied by their number. As a result, token consumption does not increase gradually but in spurts, and it’s nearly impossible to predict it at the start of the task.
When running two different sessions of an AI agent interaction to solve exactly the same task (two tech-support tickets, two analytics tasks, and so on), the number of tokens spent on them can vary — the difference can be as much as 30 (!) times. This depends on how many steps, errors, and retries are required to solve the task. Increased resource consumption doesn’t necessarily depend on the complexity of the task. There are well-known cases where AI got stuck in a “thought loop” and wasted an absurd amount of resources on trivial tasks.
Three generations of AI in enterprise systems consume resources in completely different ways:
Classical machine learning (ML). This typically works with well-structured data and isn’t overly computationally intensive. Resource consumption is predictable and low. This is a fixed budget item;
A chatbot or other LLM-based AI assistant. It consumes tokens, but the pace is set by a human: an employee manually launches a task, then evaluates the result, and pauses. Cost increases roughly in proportion to the number of active users, and can be approximately estimated based on the number of licenses;
An autonomous AI agent. A person sets a goal and steps away, and the system then decides on its own what to do and how many steps are needed. The meter keeps ticking until the task is considered complete, and there’s no predictable cost ceiling.
Tokenomics in attacks: denial of wallet as the new DDoS
Since LLM calls are significantly more expensive than typical standard software calls, automating routine corporate tasks comes at an unusually high cost. For example, Gartner estimates that resolving a single customer support request using an LLM costs approximately $3. It’s easy to imagine how attackers could bombard a company with thousands of long, sophisticated requests generated by an inexpensive LLM, causing significant financial damage. Since the process is automated, anomalies may not be detected right away.
If an attacker knows which agent system and which LLM are used in a business process, they can carry out a more precise attack and cause significantly greater damage. The authors of the GitInject study estimated that an attacker capable of creating GitHub issues within an organization that uses AI agents for error analysis with single attack (before GitHub’s defense mechanisms kick in) can cause up to $111 in damage and burn through 400 minutes of GitHub Actions from the victim’s account. Naturally, such an attack can be repeated multiple times — at no cost to the attacker.
The most dangerous risk — though difficult to quantify in monetary terms — comes from attacks that provoke LLMs into excessive reasoning. In the paper OverThink, the authors demonstrated how a harmlessly worded task, when fed into a language model, ultimately yields a correct result but, in the process , consumes 46 (!) times more tokens than it should. Moreover, all tasks tested by the researchers successfully passed existing security filters.
In the new version of the OWASP Top Risks for Language Models guide, this issue has risen to a record-high priority: unbounded token consumption is now designated as LLM06:2026, and among its variations, the “denial of wallet” attack — which depletes the victim’s budget for LLMs — is explicitly highlighted.
How to Avoid Becoming a Victim of the “New DDoS”
First and foremost, you should abandon the principle of “using AI just for the sake of using AI”. It doesn’t make sense to entrust autonomous agents with every task. It’s wise to periodically conduct a cost-benefit analysis of using artificial intelligence.
In addition, you should limit the permissions and set of tools available to an autonomous AI agent. The fewer actions the system has access to, the more effectively it works on a narrow task, the fewer opportunities it has to inflate costs, and the less likely it is that someone will be able to “manipulate” it into unnecessary token spending.
We also recommend setting strict limits on token consumption, and configuring a notification system to alert humans when these limits are exceeded. It makes sense to implement multiple limits in parallel: a limit per task, a daily limit, and so on. Alerts regarding limit exceedances must be immediately forwarded to the specialist responsible for the system so that they can make an informed decision — whether to continue or halt the process.
Strictly verify external, untrusted data. Any information processed by AI that comes from external sources — whether it’s requests, inquiries, messages, or comments, or various technical fields capable of containing arbitrary text (DNS records, HTTP headers, filenames) — can not only lead to prompt injection, but also deliberately inflate the workload. It will be wise to limit their size and monitor the load they generate.
Calculate the unit cost of work and compare the vendor’s invoices with your own data. The cost per analysis, per request, or per check is the only way to understand what you’re paying for and to spot errors in the invoices.
Cybersecurity is often perceived in a highly formal, checkbox way: a mandatory line item in the budget, insurance against an attack, or an extra task for the IT team. But for SMBs, this approach doesn’t work well. As a company grows, so does its dependency on digital technology, which increases the number of potential entry points for attackers. Cloud services, business applications, extra devices for new hires: all of this generates new risks. Eventually, the question of how much to invest in cybersecurity gives way to a different one: how can it help the business grow without putting extra strain on the budget and staff? That’s the point where cybersecurity stops being just defense against threats, and instead becomes a driver of business growth.
The cost of a mistake
According to the new Global Kaspersky B2B Market Pulse survey, 86% of SMBs were hit by at least one cyberincident last year, while 25% of those incidents resulted in financial losses and business downtime. And it’s not always about a sophisticated targeted attack. Often the threat comes from employees’ everyday actions, such as using unverified software, personal devices, third-party AI services, or weak passwords. And since the IT team still has to handle its usual workload, a vulnerability in the infrastructure can go unnoticed for a long time.
At a small company, the fallout from an incident can affect not just a single IT process, but virtually the entire business — with disastrous results: employees can’t get any work done, customers get no services, data becomes unavailable, and the launch of a new project gets delayed. The company is forced to divert resources away from a growth focus to one of recovery. And that’s how an incident turns into a business risk.
More doesn’t mean better
At first glance, the solution seems obvious: if the number of threats keeps going up, businesses just need to deploy more security tools. But SMBs have another limiting factor: resources. In many companies, one small IT team juggles infrastructure, applications, cloud services, employee devices, and technical support. Cybersecurity becomes just another task on the list, often without a matching increase in headcount or expertise.
According to the mentioned survey, SMB and mid-market IT and security professionals themselves point out several internal constraints: a shortage of incident responders, heavy workloads on IT teams, delayed security investments, and rapid growth in the number of devices and services in use. This can create a vicious cycle: the business grows, the IT environment gets more complex, security becomes harder to manage, risks pile up, and security investment keeps getting pushed back until an incident finally happens.
An ounce of prevention is worth a pound of cure
After detecting an attacker in their infrastructure, companies typically scramble to reinforce several areas all at once: employee training, device security, monitoring, cloud security, and so on. According to the survey, оn average, businesses take action across 4.5 areas after an incident. This approach has an obvious drawback: the organization first suffers the consequences, and only then figures out what kind of protection it was missing in the first place. In other words, cybersecurity ends up being a reaction to something that’s already happened.
A more sustainable approach is to evolve a corporate security posture gradually and in sync with the business, anticipating changes in its infrastructure and processes. It’s not necessary to predict every possible threat. It’s enough for the IT team to regularly ask themselves a few practical questions:
Which technologies and systems does our business depend on today?
What’s changed in our IT environment?
Where are the biggest risks right now?
What can our team realistically keep under control?
What new security requirements will emerge at the next stage of growth?
Two paths for evolving corporate cybersecurity
When a company focuses on steadily building up its cybersecurity posture, two paths open up: raising its existing level of protection, and expanding coverage to address risks tied to new business needs. A business can pursue either path on its own or combine them.
Path 1: hardening protection
As a business and its security requirements mature, a company can move to more advanced levels of protection and, if needed, bring in managed services’ expertise. That’s exactly the approach behind Kaspersky Next Optimum — an offering for growing SMB and mid-market businesses. A small company may start with Kaspersky Next EDR Foundations, and later move up to the next protection tiers — EDR Optimum, XDR Optimum, or, if managed protection is needed, MXDR Optimum — as its security maturity grows.
Path 2: expanding coverage
Sometimes a company doesn’t need to move to a fundamentally different level of protection. It needs to solve a specific problem that came up as the business grew. For example, the company might ramp up its use of cloud infrastructure, discover that employees have become a major source of risk, or find itself needing to manage vulnerabilities systemically. In such cases, protection can be extended with Security Modules . They’re compatible with Kaspersky Next Optimum, and allow IT teams to cover specific needs as they emerge without having to replace the existing security foundation. Here are the key capabilities of each module:
Security Awareness helps reduce risks tied to the human factor, and turns employees into an extra layer of defense.
Email Security strengthens the protection of corporate communications and sensitive data against threats that spread through email.
Workload Security helps protect cloud and hybrid environments as businesses shift more of their workloads to the cloud.
Vulnerability Management lets IT teams identify and prioritize vulnerabilities to address them before attackers get the chance to exploit them.
Threat Lookup & Analysis provides extra context when investigating suspicious files, objects, and threat indicators.
Cybersecurity as a process: the benefits
Small and medium-sized businesses shouldn’t treat cybersecurity as a target to be reached and roll out every possible security tool all at once. It’s far more practical to treat it as an ongoing process closely tied to the company’s growth. This approach helps solve several problems simultaneously:
Maintain business continuity. The sooner a threat is detected and stopped, the less likely it is to turn into a serious incident that disrupts the company’s operations. Protecting against threats, catching them early, and responding promptly all help lower the risk of downtime, and keep business processes running smoothly.
Make the most of limited resources. Careful planning of corporate security strategy goes hand in hand with process automation, centralized visibility, and investigation tools. These, in turn, help cut down on routine tasks, and free up resources for what really matters.
Build a foundation for future growth. By strengthening security as the business grows, the company builds a solid foundation for whatever comes next — whether that’s workload protection, more advanced vulnerability management, or deeper threat analysis. There’ll be no need to rebuild the defenses from scratch each time new business processes emerge.
Ultimately, well-built cybersecurity is more than just a tool for prevention and response. It’s what lets a company keep working despite a constantly growing number of threats, adopt new technology, seize new opportunities, and grow. Visit our website to learn more about how the Kaspersky Next Optimum and Security Modules help growing companies build protection that matches their current needs.
Threat actors are constantly developing new attack schemes — from OAuth token theft to attacks on AI agents — but the classics never quite leave their playbook. On any given day, an employee may receive malware attached directly to an email, or lying in wait behind a link embedded in an email. Making these attacks succeed still requires a degree of creativity, and in recent years attackers have increasingly adopted exotic file formats. Users don’t perceive these formats as dangerous; more importantly, many EDR and email security solutions skip scanning them entirely. Yet they’ve proven highly effective for deploying malware or harvesting credentials.
Below are the file types that may be blind spots in your organization’s detection strategy — despite being observed as used in real-world attacks.
Disk images
This is the broadest and most dangerous attachment category. A disk image can contain a fully prepared, correctly structured set of files tailored to a wide range of attack scenarios. It mounts as a separate volume (standalone virtual disk), and when doing so often uses tools built into the operating system. The victim doesn’t need to extract anything or create suspicious folders on disk.
The most versatile format is ISO, which dates back to the heyday of multimedia CDs. ISO images mount natively on every major OS without additional utilities, whether through simple tools like File Explorer or via the command line interface. This is precisely why threat actors have no hesitation in sending ISO files as email attachments.
Somewhat less common are IMG containers, which also mount without additional tooling on macOS or Linux, but require installing a small, free utility such as OSFMount on Windows, or using WSL2 (Windows Subsystem for Linux), which is built into recent Windows versions. A file with identical content may also carry a DD extension.
Threat actors also make use of VHD, a virtual disk format native to Windows, which generally works on Linux machines as well (via qemu-nbd or guestmount). On macOS, an additional utility — again, qemu-nbd is a common choice — is required to mount it. Note that on unpatched Windows systems, the victim doesn’t need to take any further action after the disk mounts: CVE-2025-24993 — a vulnerability actively exploited in real-world attacks — triggers attacker code execution immediately upon mounting the image.
For completeness’ sake, VMDK, the disk image format used by VMware, is also worth detecting, though it’s largely ineffective in attacks on regular users since every popular OS requires additional software to mount it.
All of these image formats can be viewed and unpacked not only with specialized tools, but with standard archive utilities like 7-Zip or RAR. As a result, the odds that the user will fall for the bait are higher than one might hope.
In addition to not being a well-known potentially dangerous format, image files give attackers one further advantage: files extracted from disk images on Windows frequently lack the Mark of the Web flag, and therefore can be launched without triggering additional system warnings.
There’s one more reason why EPP/EDR solutions must scan virtual machines and disk images: these formats are also used during later stages of an attack. To mask active file-system activity from monitoring tools, ransomware gangs sometimes run the entire encryption process inside a virtual machine deployed on the victim’s computer. The RagnarLocker ransomware strain has used VirtualBox for this purpose, while the CRON#TRAP campaign relied on a QEMU environment.
MS Office files
No, this isn’t about macro-laced DOC files. Microsoft has grown weary enough of this classic attack vector that macros in downloaded documents are now blocked outright, and enabling them requires considerable effort from the user. But Office relies on dozens of file formats, and some of the less common ones still occasionally give attackers an edge.
Less familiar to both users and security solutions are OneNote files (.one). These are essentially simple notes, but they can carry embedded attachments, including not just images and links, but VBS/WSF/BAT scripts as well. Within the note, an attachment normally displays as an icon, but attackers overlay it with a picture showing a message with a “View” button.
Another Office format popular with attackers is the Excel add-in. These files use the .xll extension but are, in effect, full-fledged Windows dynamic-link libraries (DLLs), and therefore may have extensive functionality. Victims receive a malicious email with what looks like an invoice; the icon suggests that the file will open in Excel. Ignoring the security warning may result in an infostealer infection.
SVG “graphics”
The description of the SVG (Scalable Vector Graphics) format sounds entirely innocuous. Indeed, 99% of SVG files are logos and interface icons. But unlike PNG or JPG, SVG files are fundamentally XML documents, and beyond points, lines and fills they can contain JavaScript. In terms of malicious potential, SVG is not far behind a full web page. In real-world attacks, SVG files can redirect a user to a phishing page immediately upon opening, or render the phishing page directly by unpacking a Base64-encoded block into full HTML.
SVG files pose a distinct risk to corporate portals that accept user file uploads. If a portal’s Content Security Policy (CSP) isn’t sufficiently restrictive, and lets someone upload a malicious SVG file, the embedded JavaScript can steal cookies from the page, inject unauthorized content, and carry out similar attacks.
Polyglot files
Polyglot file formats are less exotic in and of themselves, but the files carry more than meets the eye. They’re called polyglots because attackers construct a file that can be validly interpreted in multiple ways: for example, it can be a valid ZIP archive and a valid executable at the same time. The purpose is purely to evade detection by security solutions and deceive the user. We’ve covered polyglots in detail in a separate blog post.
The clear standout in our roundup is a malicious campaign distributing the IcedID infostealer. Victims receive emails with a ZIP attachment, which unpacks into an ISO disk image. That further unpacks into a CHM file (the Windows Help format) that’s also correctly processed as an mshta (Microsoft HTML Application host) application, which then downloads the primary malware payload.
Defending against exotic files
These attacks rely on the assumption that security solutions either don’t scan unusual file formats, or scan them only superficially. Preventing the threat starts with not operating on that assumption with regard to your own infrastructure:
Configure EDR, web, and email filters to scan all of the file formats described above.
Process archives and disk images with the same rigor as you would apply to executables.
Detonate potentially dangerous file types in a sandbox, and configure recursive unpacking of nested formats through to the end of the chain: ZIP → ISO → CHM.
Where feasible, quarantine all file formats anomalous for email — disk images in particular.
Build detection rules for anomalous usage patterns that involve exotic files. For example, unusually small disk images are rare and are therefore worth investigating.
Review the technical documentation of your security solutions to confirm that complex formats are detected through deep structural parsing rather than magic-byte checks alone.
Deploy behavioral detection capable of flagging anomalous execution patterns and legitimate utilities launched from unexpected contexts. The usual suspects here include mshta, git, wscript, hh, and rundll32.
SVG files warrant a dedicated policy. Treat SVGs as active content at the email and web perimeter. On corporate portals, enforce a strict CSP, and serve user-uploaded files from a separate subdomain so that a malicious script embedded in an SVG can’t access the session on the main portal.
For security researchers studying unconventional side-channel attacks, acoustic keylogging is something of a Hello World: a foundational problem that’s been tackled many times. A recent paper authored by researchers across three Japanese universities cites six previous studies on the topic that date as far back as 2004. While earlier experiments showed theoretical promise, they came with real-world caveats so severe that it made them all but impractical for actual espionage. The authors of this latest study, however, claim to have overcome most of those limitations. Today, we look at how they pulled it off, and assess whether their method holds up in real-world scenarios.
What makes this new approach different?
Previous acoustic keylogging techniques were fundamentally flawed. Best-case scenarios required prior training on the target’s specific keyboard model. Worst-case scenarios required a complex microphone array to isolate the subtle acoustic differences between keystrokes. Crucially, almost all prior models failed outside silent environments, which rendered the attack vector virtually useless.
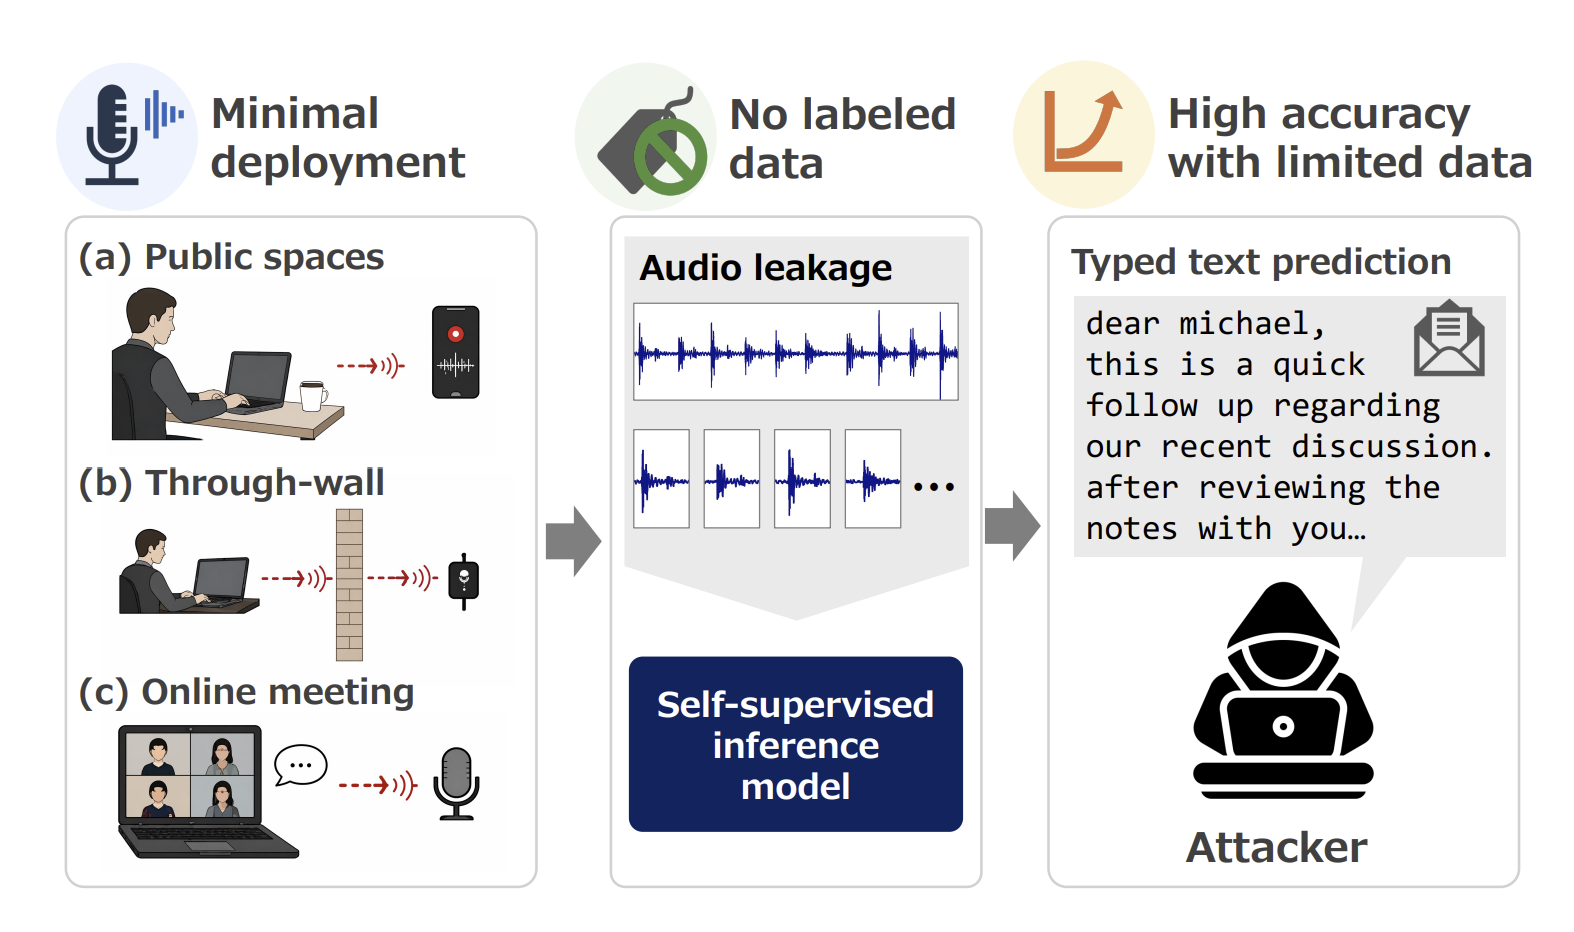
The Japanese research team demonstrated reliable keystroke interception even if the target was sitting nearby in a public space, sound was being recorded in an online meeting, or the researchers were using a contact microphone to eavesdrop through a wall. All this with strong model accuracy and a minimal training dataset. Their process needs a sample of just 150 to 200 keystrokes to reach a 99% accuracy rate for subsequent typing.
Attack scenarios and core methodology proposed by the Japanese researchers. Source
How to crack 200 keystrokes in under 50 iterations
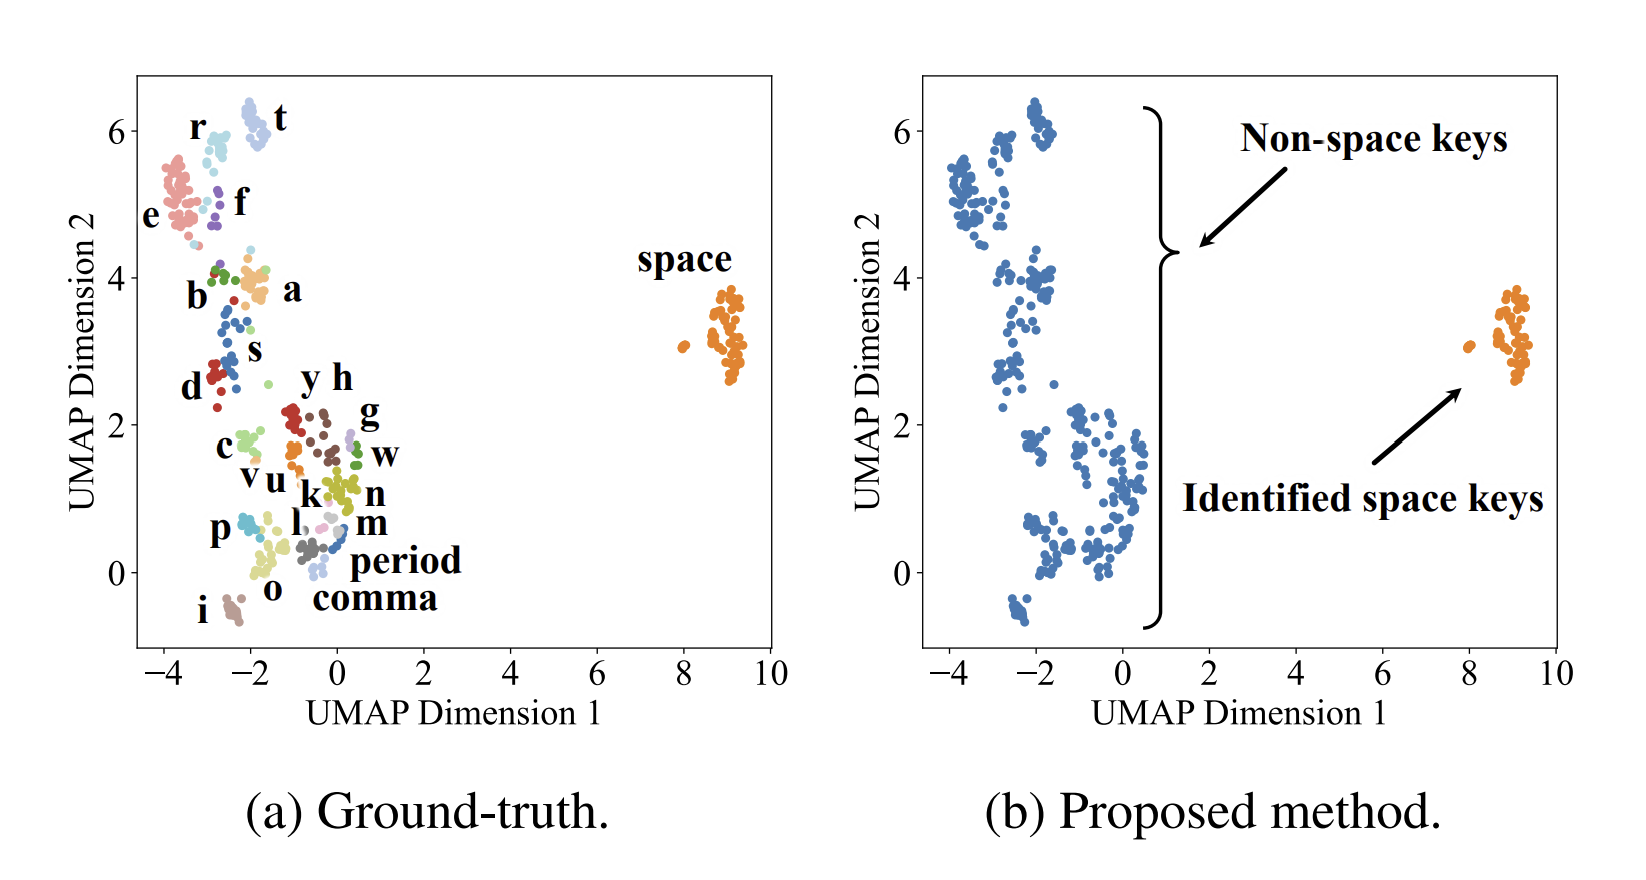
To understand how the researchers achieved such high accuracy and adaptability, we have to look at their audio processing pipeline. Their analysis begins by automatically segmenting a raw recording into discrete keystrokes. This data is then passed through a specialized algorithm that simplifies the subsequent audio analysis. Next, the system clusters together acoustically similar signals. The assumption is that the members of one cluster map to the exact same key. One particularly intriguing takeaway was isolating the spacebar sound from all the rest. Because the spacebar produces a distinctly unique sound profile compared to other keys, identifying it provides reliable word boundaries. This streamlines the next phase: feeding the preprocessed acoustic data into specialized language models for inference.
Yes, the method relies on not one but two language models. The first model performs multiple passes over the audio stream to map acoustic signatures to potential keyboard characters. During each pass, the model leverages dictionaries to hypothesize character mapping, and check whether the resulting text aligns with standard words. The second model handles the final refinement pass: it ingests thoroughly pre-processed data rather than raw inputs. The method doesn’t stop there: unrecognized keystrokes undergo manual analysis, with analysts injecting educated guesses before re-running the recognition pipeline once again. The goal of looping through these multiple iterations is to achieve complete recognition across the keyboard from an ultra-compact dataset of ideally no more than 200 captured keystrokes. This marks a major shift from legacy methods, which relied on massive training datasets.
Clustering the sounds of keystrokes permits grouping similar acoustic profiles together prior to recognition. Notice how distinctly the spacebar sounds stand out: they make subsequent text reconstruction vastly simpler. Source
Research results
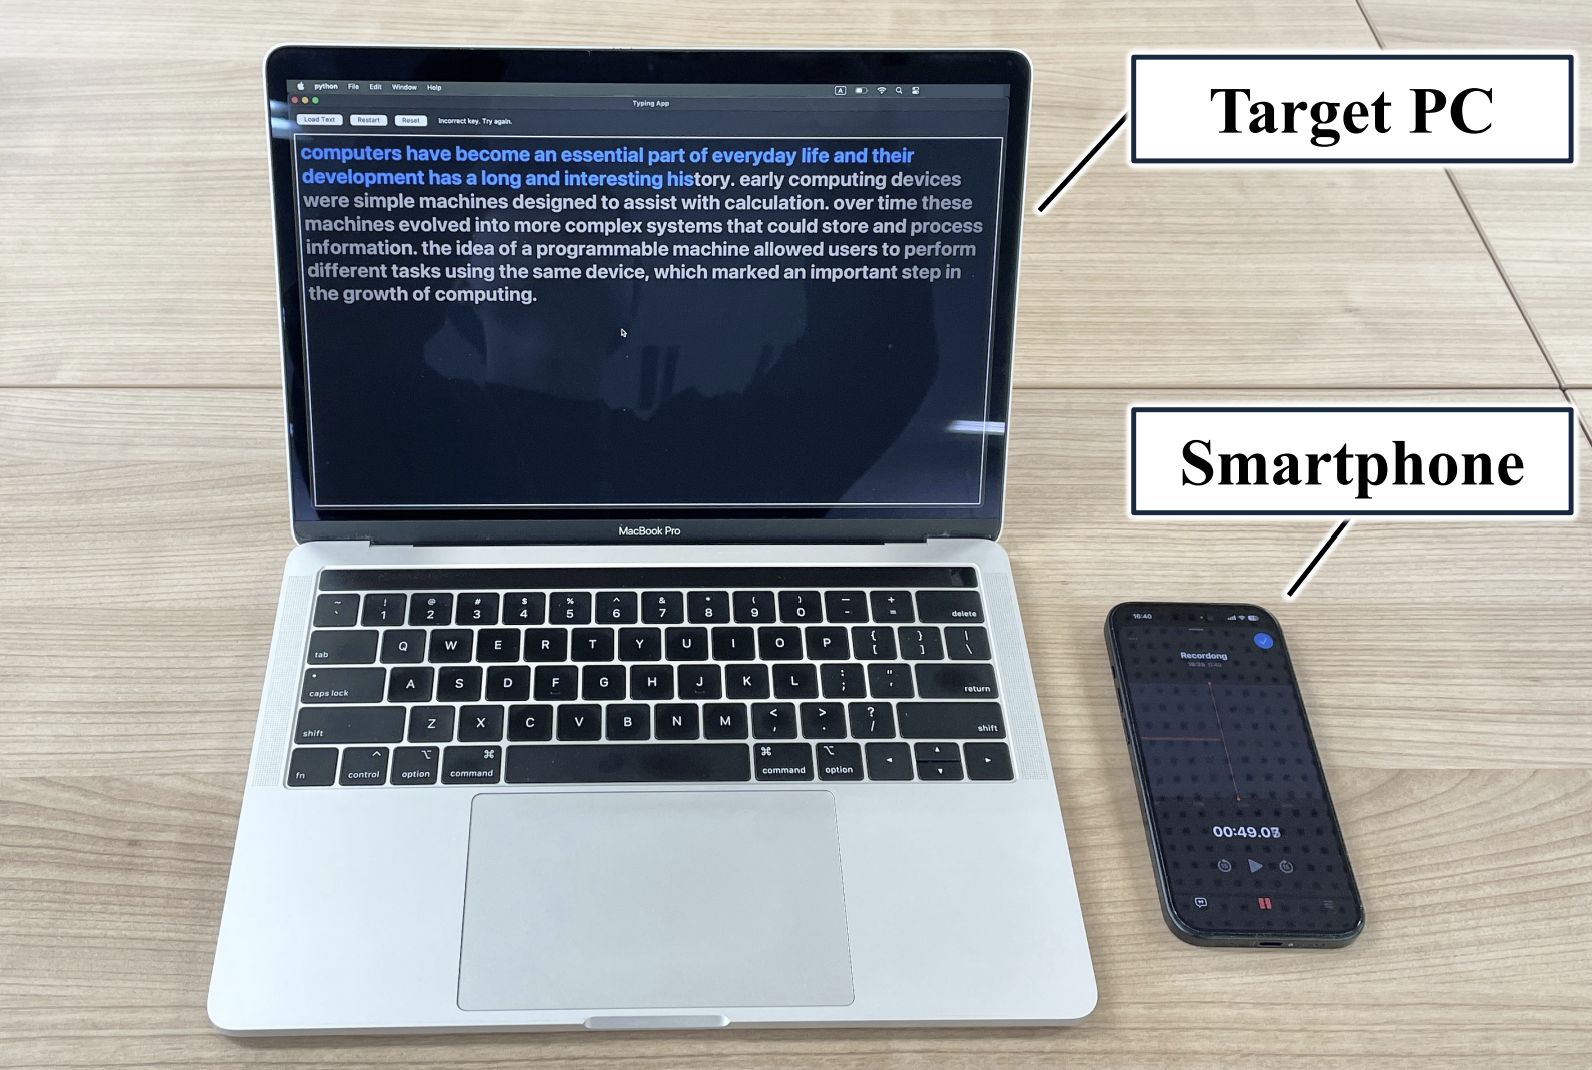
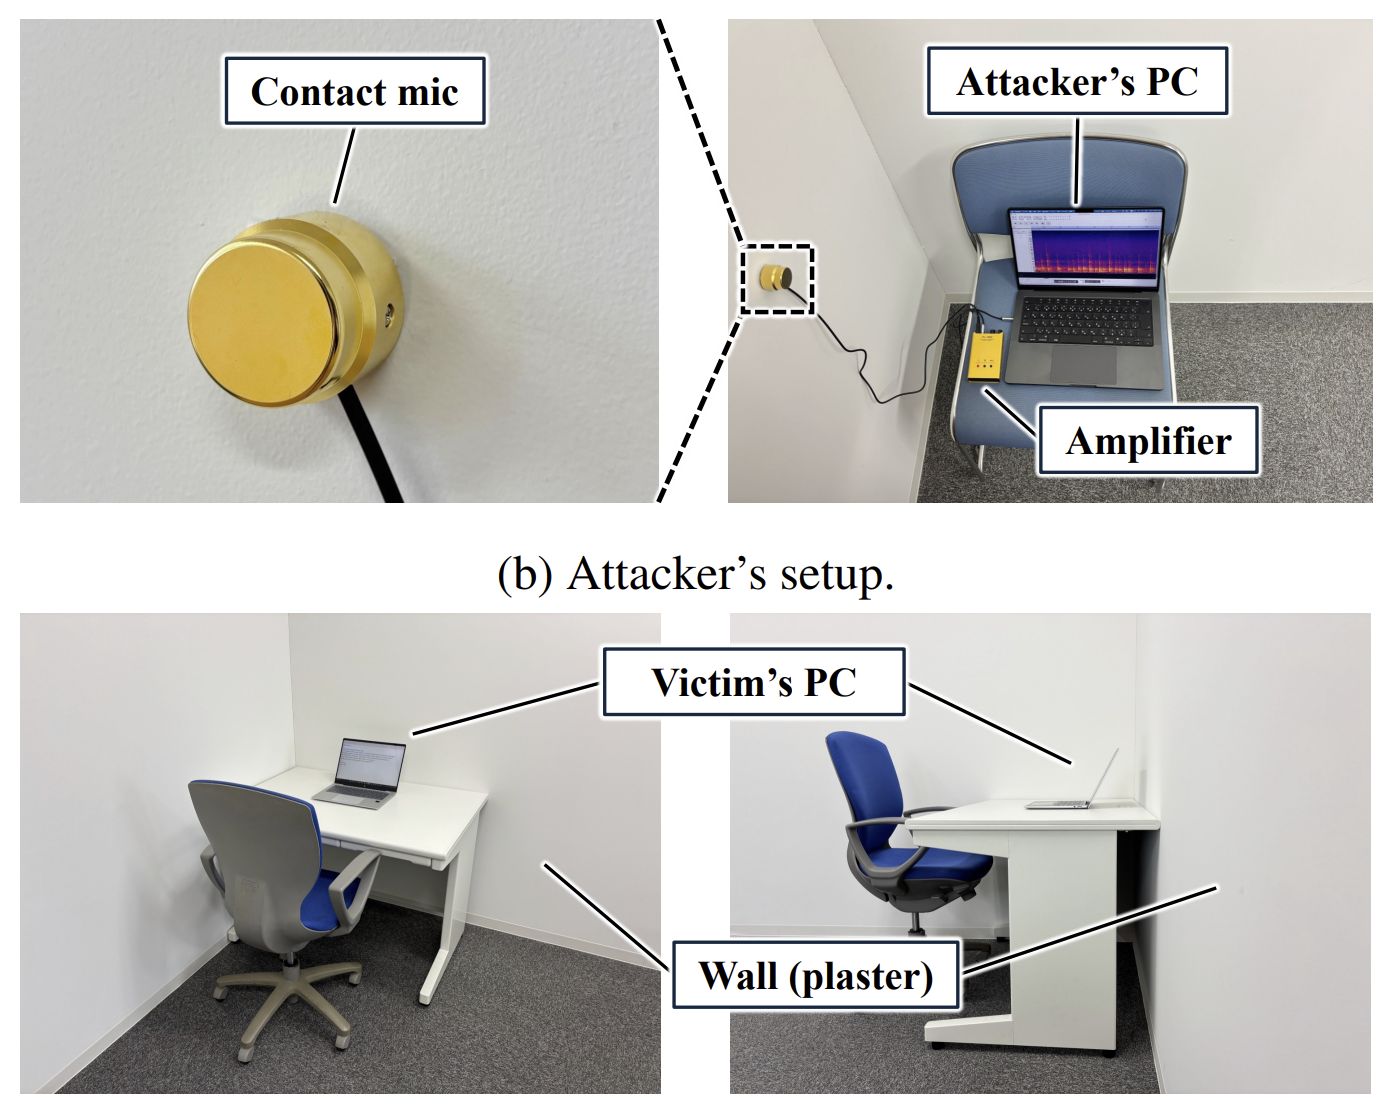
To validate their theoretical model, the researchers created an experimental testing setup:
Clustering the sounds of keystrokes permits grouping similar acoustic profiles together prior to recognition. Notice how distinctly the spacebar sounds stand out: they make subsequent text reconstruction vastly simpler. Source
The team tested four distinct laptop models, each producing unique acoustic keyboard signatures. Participants typed 2400 characters per experiment, with analysts extracting audio samples ranging from 50 to 400 keystrokes. Across all devices, the system reliably reconstructed typed text from a baseline sample of just 150 keystrokes or more. Recognition accuracy exceeded 80% at 150 keystrokes, and approached 100% once the sample reached 200 keystrokes.
The researchers achieved nearly identical results in field-like conditions with the microphone placed three meters away from the target device. Going a step further, the team successfully tested an even higher-friction scenario: using a specialized contact microphone to eavesdrop through a physical wall.
A target laptop and the attacker’s smartphone. Source
Under these conditions, accuracy dipped slightly for certain laptop models. Dell and Lenovo devices yielded roughly 80% accuracy over a 200-keystroke sample, while Apple and HP ones maintained nearly 100% recognition rates.
Remote interception during videoconferencing presented an additional variable: results depended on both the target laptop model and the specific web conferencing software used. Even so, most test scenarios yielded reliable character recognition, though a few edge cases required expanding the sample size from 200 to at least 250 keystrokes.
Reasonable critique
Despite these impressive results, the technique has clear limitations. First, all experiments were conducted strictly on lowercase English text. The target dataset was capped at just 29 characters: the standard alphabet, spacebar, period, and comma — even number keys were excluded. As a result, capturing randomized character strings like complex passwords remains a major hurdle. Yet these are precisely the targets threat actors care about most.
However, the Japanese research team didn’t ignore passwords. While recognition accuracy was predictably low, the authors proposed assessing success through a more realistic lens. For starters, attackers can almost always capture audio of other typing activity alongside password entry. This provides a stream of natural language with minimal special characters. Factoring this broader acoustic context into the password analysis significantly improves the odds of a successful guess.
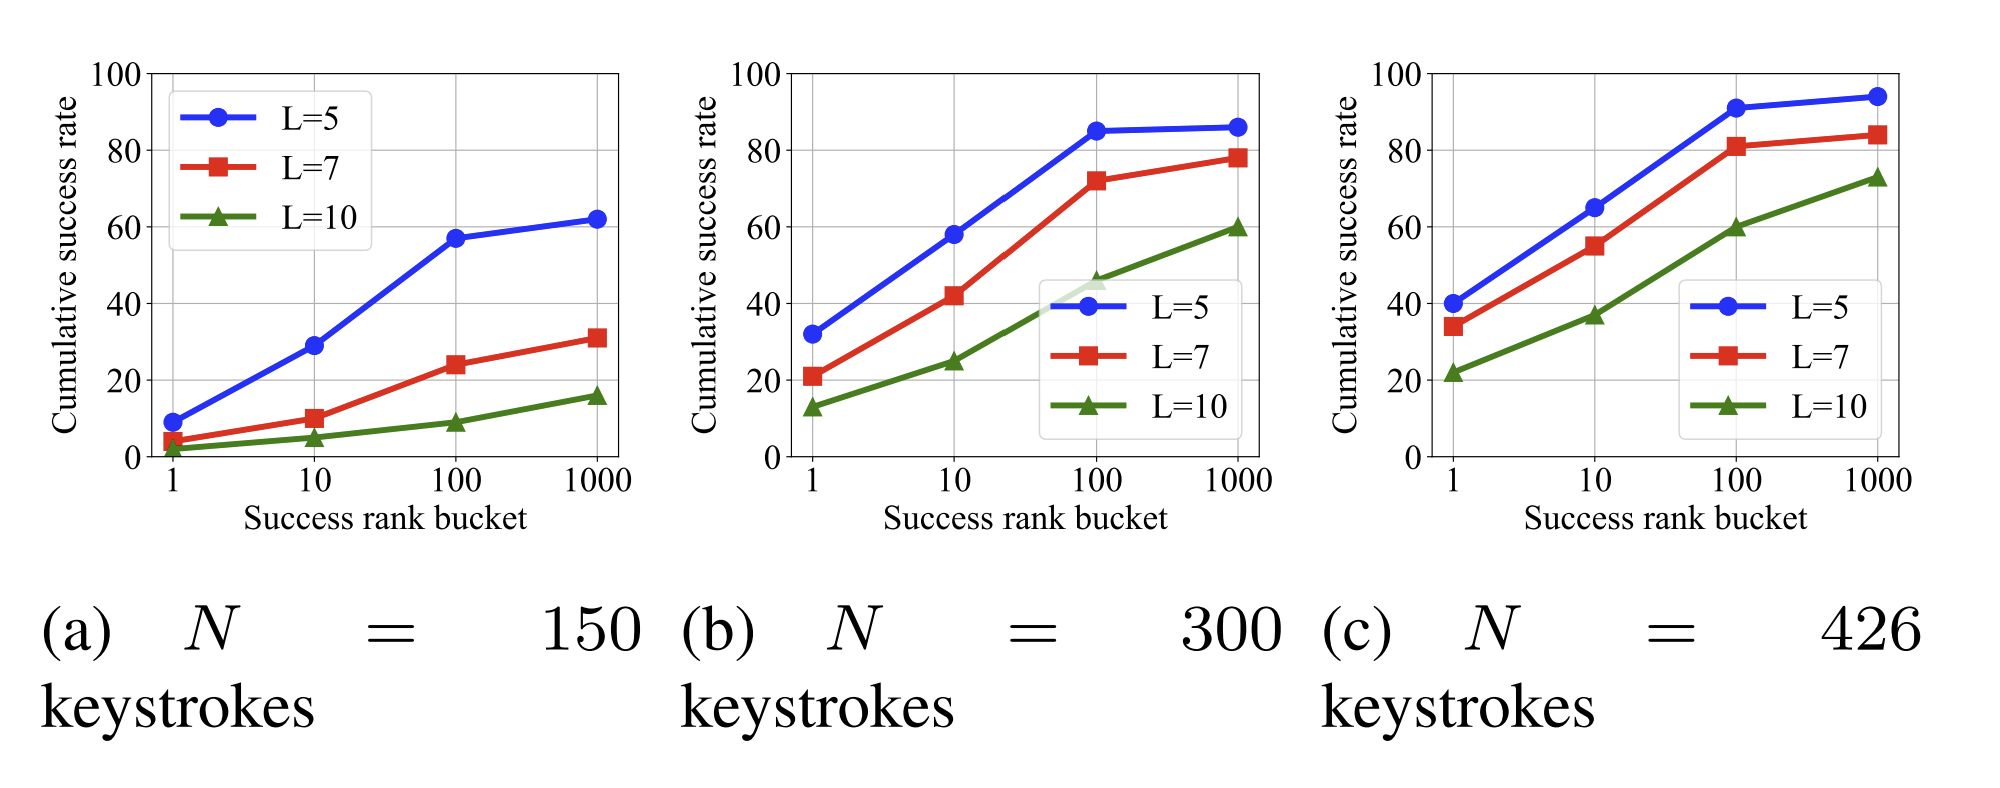
Next, the researchers rightly noted that even a list of several candidate passwords increases the chances of compromising a target account. As shown in the graph above, when ample data (426 keystrokes) is captured, a short five-character password can be successfully cracked within 100 attempts with a 90% success rate. Naturally, longer passwords proved far more resistant to eavesdropping.
Despite its limitations, this study represents a major breakthrough in acoustic side-channel attacks. It demonstrates a highly practical threat scenario: an attacker captures a brief audio recording of typing activity, then uses iterative analysis and targeted manual adjustments to process and refine the data offsite.
While eavesdropping in a noisy restaurant or through a wall is likely difficult to scale, capturing keystrokes during virtual meetings for offline decoding represents a realistic attack scenario. Ultimately, this research offers a compelling proof-of-concept: modern algorithms can drastically improve the accuracy of acoustic reconnaissance.
Leveraging legitimate software is one of cybercriminals’ tactics of choice, with remote management tools ranking among their top tools. A recent example involves the remote administration utility ScreenConnect. It’s designed for IT support teams to troubleshoot systems and configure software seamlessly in the background. However, when weaponized by threat actors, ScreenConnect becomes a versatile attack vehicle used to harvest data, deploy malware, and move laterally across corporate networks.
During a recent incident detected by Kaspersky Managed Detection and Response, our experts identified an attempt to use ScreenConnect in an attack. This allowed a detailed study of how attackers used this application in a large-scale malware distribution campaign. The following breakdown illustrates the mechanics of ScreenConnect-assisted attacks, and outlines key strategies to defend your organization against them.
How ScreenConnect reaches target computers
In the campaign analyzed by our experts, the attackers bundled ScreenConnect with legitimate free business software. They established a network of phishing websites to spoof popular tools, including OBS Studio, DS4Windows, DNS Jumper, Glary Utilities, Bandizip, Process Hacker, and others.
These rogue websites featured high-quality designs that could be taken for the official pages, making them highly convincing to unsuspecting users. Once the victim clicks the download button for the software, an archive is downloaded to their computer that contains additional files alongside the requested application:
A legitimately signed Microsoft executable (exe), renamed to match the expected application installer (for example, OBS-Studio-Installer.exe)
A malicious library named res.1033.dll
An Assets directory containing installers for both ScreenConnect and the intended application
Launching the renamed file disguised as the app installer triggers DLL sideloading of a malicious library. This library silently runs the ScreenConnect installation without restarting the system, while using the standard Windows installer to set up the software the user originally tried to install.
The attackers used search engine optimization techniques to drive traffic to their fake websites. As a result, these malicious pages appeared at the top of search results for certain free software utilities on major search engines.
Our experts discovered over 90 domain names translated into more than 10 different languages. While most of these websites targeted English, Russian, and Chinese speakers, several domains catered to German, French, Spanish, Arabic, and other regional audiences.
A detailed analysis of the IP addresses and associated spoofed domains is available in our technical research article on Securelist, along with full indicators of compromise.
Why the attackers exploited ScreenConnect
In this campaign, attackers leveraged ScreenConnect to generate and execute malicious scripts on victim machines. These scripts served several key functions: they created exclusions for specific drives, directories, and processes within Windows Defender, disabled the User Account Control (UAC) security mechanism, and delivered and deployed AsyncRAT – a remote access Trojan.
To maintain persistence, the scripts configured a Windows scheduled task to run the malicious code at preset intervals. AsyncRAT then established a connection with the attackers’ command-and-control server to receive further instructions.
The primary objective of this campaign appears to be gaining unauthorized access to enterprise systems, likely to then resell it on cybercrime marketplaces.
How to secure corporate infrastructure
Although ScreenConnect in and of itself is a legitimate tool, its presence poses a security risk to corporate environments. Consequently, Kaspersky security solutions detect this application as not-a-virus:HEUR:RemoteAdmin.MSIL.ConnectWise.gen.
Security teams should implement the following controls:
Enforce strict application control policies, including software allowlisting and restrictions on MSI package installations from unverified sources
Monitor for newly installed remote management utilities and scheduled tasks
Filter outbound network traffic from workstations to unknown IP addresses and domains
Cybersecurity news increasingly focuses on attackers using AI for reconnaissance, vulnerability hunting, and writing scripts or malware. Against this backdrop, a less conventional category of attacks remains largely overlooked: threat actors leveraging AI tools that are already deployed within the target infrastructure.
AI agents designed for coding, as well as command-line tools — such as Claude Code CLI, Gemini CLI, Codex CLI, Amazon Q CLI, and the like — are particularly attractive targets. These agents can read and modify files, execute shell commands, install packages, and connect to external services. Developers frequently allow them to run in autonomous mode to avoid manually confirming every action. For an attacker, such an agent becomes a ready-made multitool that has the right privileges, access to critical data, and security clearances from the get-go. That said, other types of AI agents, such as automated financial workflow assistants, are equally vulnerable to exploitation.
Why trusted agents pose a threat
An AI agent differs from standard software in its broad access privileges, the wide array of ways it can be prompted to execute actions, and the difficulty of detecting its anomalous behavior. Enterprise security controls (EPP, EDR, XDR, SIEM) scan for malicious files, known command patterns, and suspicious action sequences. Even if a specific strain of malware hasn’t been seen before, its behavior often gives it away: bulk searches for documents, spawning PowerShell processes, accessing credential stores, or exfiltrating data to an external server from an unknown application will trigger a deluge of alerts in the SOC.
It’s much harder to apply that same detection logic to a legitimate, pre-installed AI agent. By design, these tools are capable of executing an extremely broad range of operations. Running scripts, reading configuration files (including secrets), moving documents, and installing dependencies can all be a part of their normal operation — especially on a developer’s machine.
When an attacker attempts to exploit this kind of AI system, they use natural language to convey their instructions to the agent. A request to hunt for passwords, API keys, or cryptocurrency wallets can be framed in thousands of ways, expressed in a variety of languages, or phrased indirectly. Furthermore, a malicious command can be hidden in any data stream the agent reads — including text fields in documents, file names, or even error logs, as shown in one of the examples below.
Integration between agents and third-party software further expands the attack surface. Agents are frequently connected to email, instant messaging apps, task management systems, knowledge bases, and MCP servers. As a result, a malicious instruction can originate from virtually any source whose data the agent processes automatically.
Below are several examples of attacks where threat actors leveraged AI agents to achieve their goals.
The Nx attack: a coding agent hunting for passwords
The most prominent and widespread example is the compromise of Nx npm packages in August 2025, dubbed s1ngularity. Attackers exploited a vulnerable GitHub Actions workflow, stole a package-publishing token, and released trojanized versions of several @nx packages that harvested developer secrets.
The malicious post-install script checked whether Claude Code, Gemini CLI, or Amazon Q CLI were installed on the victim’s machine. If any of these were detected, the agent was issued an instruction to scan for cryptocurrency wallets, ENV files, API keys, and other sensitive data. The agents were executed with auto-approval flags enabled, such as --dangerously-skip-permissions, --yolo, and --trust-all-tools.
The search results were then exfiltrated to public GitHub repositories created by the attackers. Over several waves of the attack, thousands of secrets belonging to hundreds of organizations were exposed.
Instead of developing a complex, custom harvesting tool, the attackers repurposed the victim’s own legitimate agent. It already could navigate the file system, understand file context, and identify high-value target data. However, post-incident analysis by security experts revealed drawbacks to this approach: the AI occasionally refused to carry out unethical tasks. Furthermore, the malware authors had to adjust their code so that it “waited” for the AI agent, which could take a considerable amount of time to process the task while generating significant intermediate output.
Communication via… error logs
The AgentJacking study was not a malicious attack, but it differed from one only in intent: its authors had no interest in stealing secrets. After developing the attack technique, the researchers tested it on a global scale and received callback responses from AI agents belonging to more than a hundred real-world companies — some of them major enterprises.
The attack targeted Sentry, a widely used telemetry service. Websites and mobile applications automatically transmit error reports to Sentry so developers can monitor issues without requiring active user reporting. These reports are accepted without authentication because errors often occur for anonymous visitors that the site or application knows nothing about.
The researchers configured their own MCP server within Sentry, allowing AI agents to analyze reports automatically. Next, they submitted a fake error message containing a data block formatted to match Sentry’s MCP server data structure. Embedded inside was an indirect prompt injection — an instruction to run “additional diagnostics” via a command like: npx @controlled-validation-package --diagnose.
If error handling were delegated to an agent, it could take the instruction as legitimate and execute a command resulting in the automatic installation of a third-party package. In this experiment, the package merely contacted the researchers’ command-and-control server without exfiltrating any sensitive data. A genuine malicious package, however, could steal credentials, tamper with code, or establish persistence in the system. Identifying targets for such an attack is equally straightforward: an organization’s use of Sentry is easily detectable by analyzing website code or checking the strings in mobile application binaries.
Notably, according to the study’s authors, Sentry acknowledged the issue but stopped short of implementing comprehensive fixes, opting instead to block only the specific variant of the malicious query routed through the MCP. Screenshots included in the study reveal that a Sentry employee described the system as “technically not defensible” against the attack.
Stealing financial data via MCP
Abusing unsecured MCP servers — as seen in the Sentry case — is just one way to attack this protocol. Introduced just a year ago, and already dubbed “USB for AI agents”, the Model Context Protocol standard was adopted rapidly without robust built-in security controls. As a result, attacks targeting MCP are bound to proliferate — a trend Microsoft recently warned about.
Threats can lie hidden even within the description of an MCP tool before the agent ever uses it. Agents parse tool descriptions to determine when to call the tool and what data to supply. If an MCP server provider stealthily alters a description — adding an instruction that demands collection of additional data — the agent may execute it as part of its standard workflow.
Microsoft highlights a scenario involving a financial agent that verifies vendor banking details via an external MCP service. Following a malicious update to the tool’s description, the agent begins appending unpaid-invoice data to its responses. The user sees a normal response, while confidential financial data is quietly exfiltrated to the server owner. Individually, each operation appears authorized: the agent operates under the employee’s permissions, queries an approved service, and uses a standard interface. Yet a data breach still occurs.
It remains unclear from Microsoft’s ambiguous phrasing whether this example is purely hypothetical or based on an investigation into a live incident. However, the fact that the post originated from Microsoft Incident Response points to the latter.
Prompt injections have already gone mainstream
In 2026, Unit 42 researchers identified widespread attempts to covertly embed instructions designed for AI systems across numerous public websites. Many of these instructions aim to force models to reveal system prompts, approve sites and posts during ad placement reviews, or boost phishing pages through SEO manipulation.
Similarly, an analysis of Common Crawl data by Google recorded a surge in such material: between November 2025 and February 2026, the share of malicious injections increased by 32%.
That said, confirmed cases of successful compromise using these techniques remain scarce. The presence of an injection on a webpage does not guarantee that an agent ever actually executed the command. Nevertheless, threat actors have clearly begun optimizing web content for an era when it will be read not just — and perhaps not primarily — by humans.
How to defend against agent-based attacks
The key takeaway for cybersecurity teams and all AI users alike is simple: an AI agent should never be considered trusted merely because it has been officially approved for enterprise use.
Organizations must:
Maintain an inventory of agents, MCP servers, and the various tools available for them. Use allowlists to restrict agent tools, and package installations to components explicitly vetted and approved by information security. Allowlists must specify exact package versions.
Monitor version changes to MCP tools and other dependencies. Re-evaluate updates before adding them to the approved inventory.
Apply the principle of least privilege. Grant agents only the specific permissions needed for a given task, and only for the duration of that task.
Enforce human-in-the-loop approval for package installations, script executions, file sends, and other high-risk actions.
Run agents in isolated environments with limited access to developer workstations.
Disable dangerous auto-approval modes.
Restrict outbound network connections, and permit data transmission only for approved services.
Store secrets in centralized, secure vaults, using short-lived tokens and rotating them regularly.
Forward prompt logs, tool calls, shell commands, and agent network traffic into SIEM and XDR systems. For these tools to be effective, they require deep operational context regarding agent activity alongside specialized rule sets tailored to AI data processing pipelines.
Cybercriminals are increasingly moving away from complex malware, relying instead on social engineering that exploits a common user habit: mindlessly clicking through endless digital rituals like CAPTCHAs, cookie consents, and authentication prompts. This habit is often targeted by various kinds of the ClickFix technique, which threat actors have been actively using lately. Researchers recently discovered a new variant of this technique, which they dubbed ConsentFix. It allows attackers to gain unauthorized access to Microsoft 365 accounts via OAuth — a highly popular vector right now — thereby completely bypassing the need to steal passwords. For organizations, these attacks present a severe risk of compromised corporate email, exposed documents, and breached cloud resources.
How ConsentFix works
Social engineering lies at the core of all ClickFix variations. Attackers prompt the user to follow a seemingly harmless set of instructions, which actually lead to the compromise of their device or account. In the case of ConsentFix, these instructions are designed to trick the user into granting the attacker access to their Microsoft 365 account.
The attack begins by making the user believe they must authenticate with their Microsoft account to access a specific page or document. To do this, cybercriminals usually send an email containing a link to a website typically imitating a popular file-sharing service. Attempting to access a specific document on this site prompts the user for verification, which can be obtained by following this sequence of actions:
Clicking Verify with Microsoft.
Signing in to the work account, at which point the attackers warn that multi-factor authentication (MFA) may be required.
After being redirected to a new page, waiting until “localauth” appears in the address bar.
Dragging the information icon ⓘ from the browser’s address bar into a drop zone on the page.
In practice, following these instructions causes the user to drag an URL containing a session OAuth token directly onto the attacker’s page. This token is exactly what grants the attackers access to the victim’s email and other Microsoft 365 services.
The potential fallout of a Microsoft 365 session compromise
At first glance, it might seem like attackers only gain access to a mailbox. In reality, the consequences can be significantly more severe. The attacker’s specific capabilities depend on the organization’s Microsoft 365 license, the services deployed, and the privilege level of the compromised account.
Even compromised corporate email alone is a major breach. The attacker not only gains access to email archives that may contain confidential business intelligence, but also can send phishing messages or launch internal BEC attacks on behalf of the user.
Beyond email, attackers are highly likely to gain access to the victim’s Microsoft Teams account, providing them with even deeper insights and broader leverage for various scams. Access to OneDrive and SharePoint is equally dangerous: it allows attackers to exfiltrate corporate documents, upload malware into cloud storage, tamper with existing files, and more. Ultimately, this creates a launchpad for moving laterally within the corporate infrastructure.
Publicly available attack blueprints
According to a Bleeping Computer article, the mechanics of ConsentFix are no secret. Attackers share detailed implementation guides on cybercrime forums, offering not only ready-to-use code but also video tutorials demonstrating how to deploy the attack. They also actively trade tips on how they harvest intelligence on organizations and their employees via LinkedIn and other OSINT channels to craft highly convincing phishing messages.
Collectively, this significantly lowers the barrier to entry for novice cybercriminals. As these guides and turnkey tools continue to proliferate, ConsentFix attacks will likely become increasingly common. Consequently, organizations should immediately factor this technique into both their defense strategies and employee awareness training programs.
How to secure your corporate infrastructure
The emergence of this new ClickFix variation demonstrates that simply blocking a specific keyboard shortcut or an isolated risky action on employee devices is not enough. Clearly, attackers quickly adapt to these measures. Therefore, to protect an organization from these types of attacks, we recommend the following:
Be sure to deploy a robust security solution at the mail gateway level — this minimizes the likelihood of attackers successfully luring your employees to a page hosting the ConsentFix mechanism.
Conduct regular cybersecurity awareness training for employees to keep them ahead of the latest social engineering tactics. Our training platform, Kaspersky Automated Security Awareness Platform, can assist with this initiative.
When targeting an organization to steal information, maintaining a low profile is critical for attackers. They typically aim for long-term persistence, which requires avoiding security alerts while preserving access in case they’re detected and the organization initiates incident response or routine password resets. Malware such as infostealers or ostensibly legitimate remote monitoring and management (RMM) tools fail the first requirement: their use triggers EDR and generates suspicious events in SIEM consoles. Relying on stolen credentials conflicts with the second requirement: the moment the security team suspects a compromise, passwords can be changed immediately — terminating access. If attackers attempt to steal browser cookies instead of passwords, they face a different challenge: many online services now correlate device characteristics with the expected session cookie and block access if the cookie is used on an unrecognized device. Furthermore, cookie theft protection mechanisms implemented in Chromium-based browsers (such as Chrome, Edge, and Opera) this year have made this approach significantly more difficult.
To address this persistence challenge, the ToddyCat APT — whose main game is spying — developed a novel technique. Kaspersky experts discovered this method during an incident investigation and named it Shadow Token via Remote Debug (STRD). This technique allows the attackers to establish reliable, persistent access to a victim’s mailbox and other resources in Google Workspace. With minor adjustments, the same approach could potentially be adapted to target other services that grant third-party application access via OAuth 2.0 authentication.
How an STRD attack works
First, the attackers must compromise the victim’s system with malware. In past campaigns, ToddyCat gained initial access to organizations by exploiting known vulnerabilities in server software and distributing malicious loaders via messaging apps. The specific employee targeted by the attackers might not notice the intrusion at all. This can occur, for example, if the adversary first obtains privileged administrative credentials and uses them to deploy the malware onto targeted machines remotely. Crucially, the deployment and execution of this malware mustn’t trigger immediate security alerts.
Once active, the malware executes an STRD attack, connecting the attackers’ remote service to the victim’s mailbox using the OAuth 2.0 protocol. This process requires no user interaction and shows no visible activity on the screen. To the cloud environment (Google Workspace, in the case at hand), the activity appears as if the user has legitimately authorized a third-party app for email access or data backup.
After that, the malware can terminate its operations and even delete itself from the system. The adversary retains direct access to the mailbox using the acquired OAuth token — and they need no connection to the victim’s endpoint or to the corporate network for that. Depending on the organization’s Google Workspace configuration, this access can persist for an extended period and survive subsequent password resets.
The core concept of Shadow Token via Remote Debug
At the heart of this attack is a connection to Google Workspace services via OAuth 2.0. This is a legitimate workflow used whenever a third-party application requests access to calendar data, emails, or Google Drive files. For example, to display calendar meetings in Zoom and automatically generate conference links, a user must authorize Zoom to access Google services. Similarly, configuring a third-party email client or calendar app requires granting permission. During this authorization process, the service requesting access opens a new browser window. In this window, Google Workspace first prompts the user to select the appropriate account. Once the account is chosen, the subsequent screen displays the specific permissions requested by the third-party app, allowing the user to either approve or deny access. For this scenario to proceed seamlessly, the user must already be authenticated to Google services in their browser — which is typically the case in organizations using Google Workspace. If the user isn’t authenticated, additional steps for entering credentials and completing multi-factor authentication are introduced into the sequence.
The ToddyCat hackers developed a malicious tool called Umbrij to facilitate a two-step covert authorization process when the user is already authenticated in Google. First, the malware identifies the browsers installed on the system, and locates the specific folder storing the user’s active profile for each. The attackers target Chrome and Edge, as these are the browsers most likely serving as the primary ones within the organization.
Next, Umbrij copies the entire user profile folder to a different directory on the machine. It then launches an instance of the browser, specifying the path to the duplicated profile via the command line. Because this duplicate profile contains the user’s session cookies, websites with saved credentials won’t prompt for re-authentication. Furthermore, since this occurs on the exact same computer where the primary browser is running, online services detect no anomalies. The browsing history for this newly launched instance is isolated within the new folder, keeping it hidden from the user’s main account activity.
Crucially, the browser is launched in a dedicated debugging mode typically reserved for web development. The browser window and user interface don’t appear on the screen at all (headless mode). Instead, the browser can be controlled through a debugging port using the DevTools protocol, allowing the malware to issue commands and read the state of the screen. To orchestrate these actions, Umbrij leverages Puppeteer, a legitimate automation library.
After verifying that the debugging browser instance has launched successfully, Umbrij opens a legitimate Google Workspace OAuth screen within it. The request sent to Google is engineered to bypass additional security checks while requesting maximum access privileges. For the application ID — the identity supposedly requesting these extensive permissions — the malware impersonates one of two legitimate tools: Google Workspace Migration for Microsoft Outlook (GWMMO), or Google Workspace Sync for Microsoft Outlook (GWSMO).
When Google opens the window within the headless browser, Umbrij uses debugging tools to programmatically click on the corporate account name and the confirmation buttons. As a result, Google generates an authorization code for the app. Umbrij extracts and saves this code, subsequently forwarding it to the attackers’ command-and-control server. Finally, operating entirely within their own infrastructure rather than on the victim’s computer, the attackers exchange this authorization code for an OAuth access token. This single token is all they need to maintain long-term unrestricted access to the mailbox.
How to protect against OAuth token theft
If a Google Workspace account is compromised, incident response measures must include the following steps after collecting the necessary logs and other forensic data for investigation:
Resetting the affected user’s password
Terminating all active web sessions for the user
Revoking OAuth tokens and third-party app permissions
Reviewing and removing access granted through legacy App Passwords
In addition, security and IT teams must systematically audit issued OAuth permissions, revoke unjustifiable access rights, and restrict capabilities that allow excessive or unauthorized permission grants. We covered this topic in detail in our article on blocking unwanted AI assistants.
How to prevent exploitation of Shadow Token via Remote Debug
While Kaspersky users are protected against the Umbrij tool, security teams should proactively implement policies that prevent standard users from launching browsers in debugging mode. This functionality is intended exclusively for website and web app developers. This restriction can be enforced through the DeveloperToolsAvailability group policy (available for both Chrome and Edge).
Additionally, configure monitoring within your SIEM/XDR to track the launch of browser instances with an active debugging port. This event serves as a strong indicator of this specific attack technique.
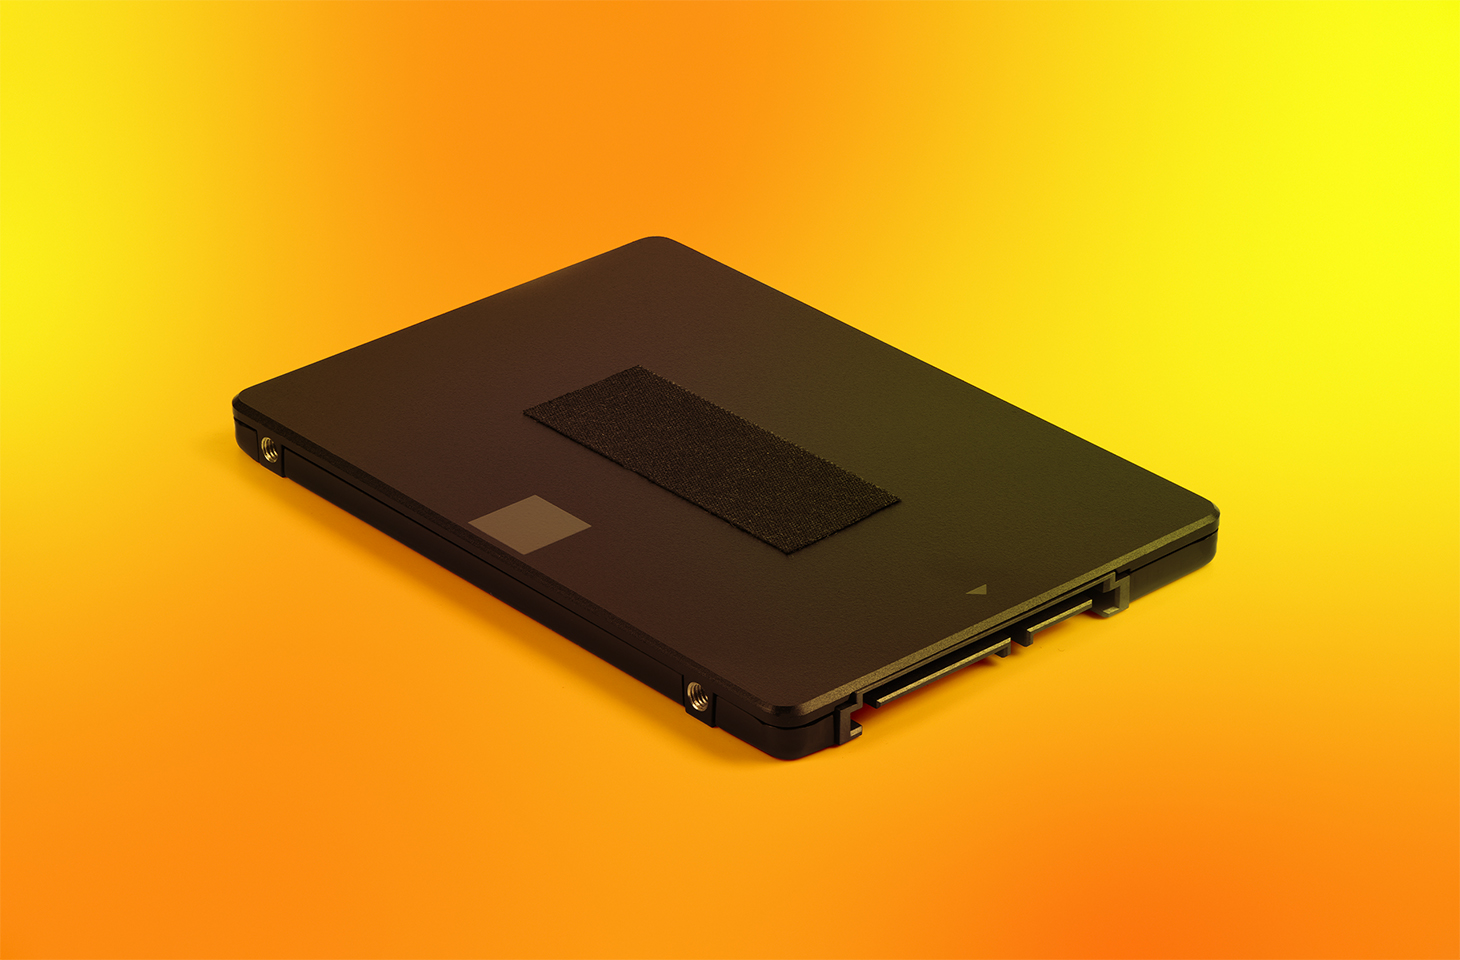
Scientists at Graz University of Technology in Austria recently published a paper detailing a new method for tracking users’ activity through their web browsers. The most fascinating thing about this new technique — which they’ve named FROST — is that it relies on a computer’s solid-state drive (SSD) to do the spying. Without getting bogged down in technical details, here’s how the attack works: a hacker lures a victim to a specially crafted website; as long as the site is kept open, the attacker can track exactly what apps the user is launching, and what other web pages they’re visiting.
So, how do they pull this off? The first instinct is naturally to blame the browser. But in modern web browsers, every website runs in an isolated sandbox and is generally locked out from touching other tabs — let alone the computer’s actual hardware. While hackers do find loopholes in these defenses from time to time, that’s not what’s happening here. The FROST attack doesn’t need to break the browser; it works perfectly even with all standard security measures in place. Instead, it hijacks a completely legitimate browser feature called the origin private file system (OPFS), which gives websites their own virtual storage space to store data. However, while this storage is digitally isolated, the data is still physically written to the exact same SSD that every other app and website opened on the computer is using. The researchers discovered that if a malicious page constantly bombards the SSD with data requests, the microscopic delays in data access can help map out what else is running on the PC. Before we dive into the details of how they manage this, let’s take a quick look at the theory behind the attack.
A quick primer on side-channel attacks
The term “side-channel” refers to a method of spying on a computer — or even a single microchip — indirectly. Instead of intercepting the data itself, an attacker might analyze fluctuations in power consumption, monitor the temperature of specific components, or listen in on electromagnetic radiation, among other things. In theory, this means that someone could eavesdrop on a conversation in a room just by using a computer mouse, since the optical sensor can pick up sound vibrations. Similarly, watching a CPU’s clock speed fluctuate could allow a hacker to steal an encryption key. Even a simple LED light on a badge reader can leak enough data about the device’s inner workings for an attacker to clone a smart card.
The beauty of these indirect data leaks — at least from a hacker’s perspective — is that they’re not easy to spot. Device manufacturers rarely account for them when building security systems. The downside, however, is just as obvious: extracting information through a mechanism that was never meant for data transmission is often complex, slow, and laborious. The Austrian researchers focused on a specific subtype known as a contention side-channel attack. This is where a leak occurs because multiple processes are competing for the same resource. In this case, that contested resource is the storage drive’s bandwidth.
Inside the FROST attack
This specific side channel has actually been studied before, including in a 2025 research paper. Back then, however, the setup was rather straightforward: the researchers ran one program on a computer to act as the data source, while a second program running on the same machine tried to intercept that data. While that’s fine for a theoretical academic study, the attack model wasn’t exactly groundbreaking. After all, if a hacker can already run any program they wish, they don’t need to rely on complex side channels — they have plenty of direct ways to steal the data.
Still, last year’s study wasn’t a complete waste of time. It proved that the resolution obtained from monitoring an SSD is quite high, the data leak is real, and the captured information can actually be useful. The FROST attack is essentially a logical continuation of the same idea.
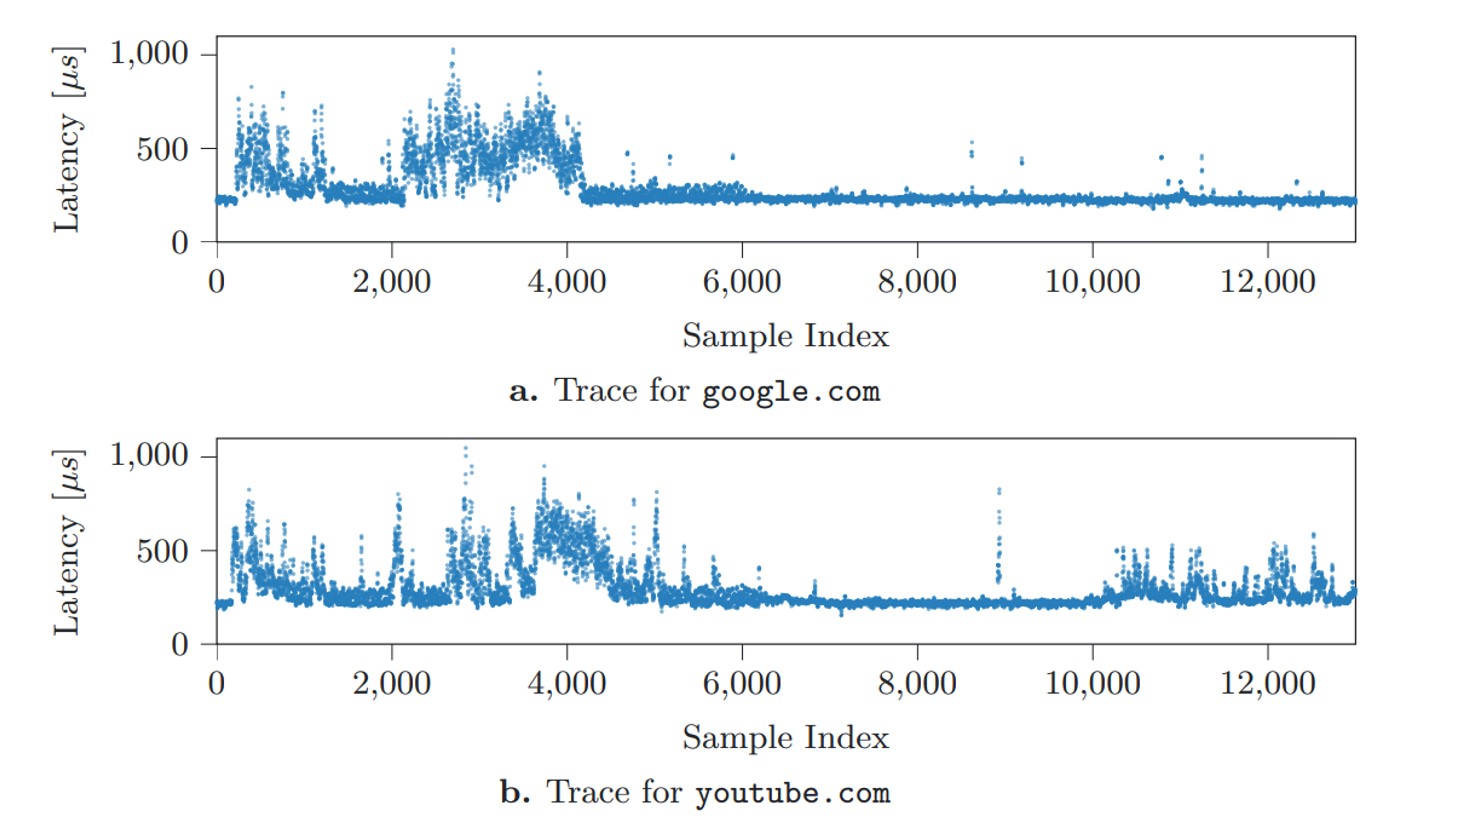
Here’s how it works in practice. Let’s say there’s a fairly large file on an SSD packed with random data. A specific process reads this data at regular intervals and clocks how fast it gets a response. This speed fluctuates depending on how busy the drive is with other tasks. These access delays are the telltale signs of the drive’s activity. The Austrian researchers demonstrated that plotting these delays over time can help pinpoint with reasonable accuracy what other task is running on the computer at that very moment.
Distinct latency patterns generated when opening specific websites Source
The researchers mapped out latency graphs, like the ones shown above, for a wide variety of websites and locally running apps. What they found were distinct patterns — or digital fingerprints — generated every single time a specific site loads, or an app launches. Capturing these split-second launch or load windows requires monitoring the SSD continuously over a long period of time. However, these patterns proved to be remarkably consistent across different systems; the authors successfully tested their method on both a Linux desktop and an Apple Mac Mini. From there, the next step sounds simple enough: take a catalog of known fingerprints, measure real-world SSD delays, match the two up, and you know exactly what apps the user is opening, and what sites they’re visiting. But how to actually pull off this kind of surveillance under the radar, without planting malware on the victim’s computer?
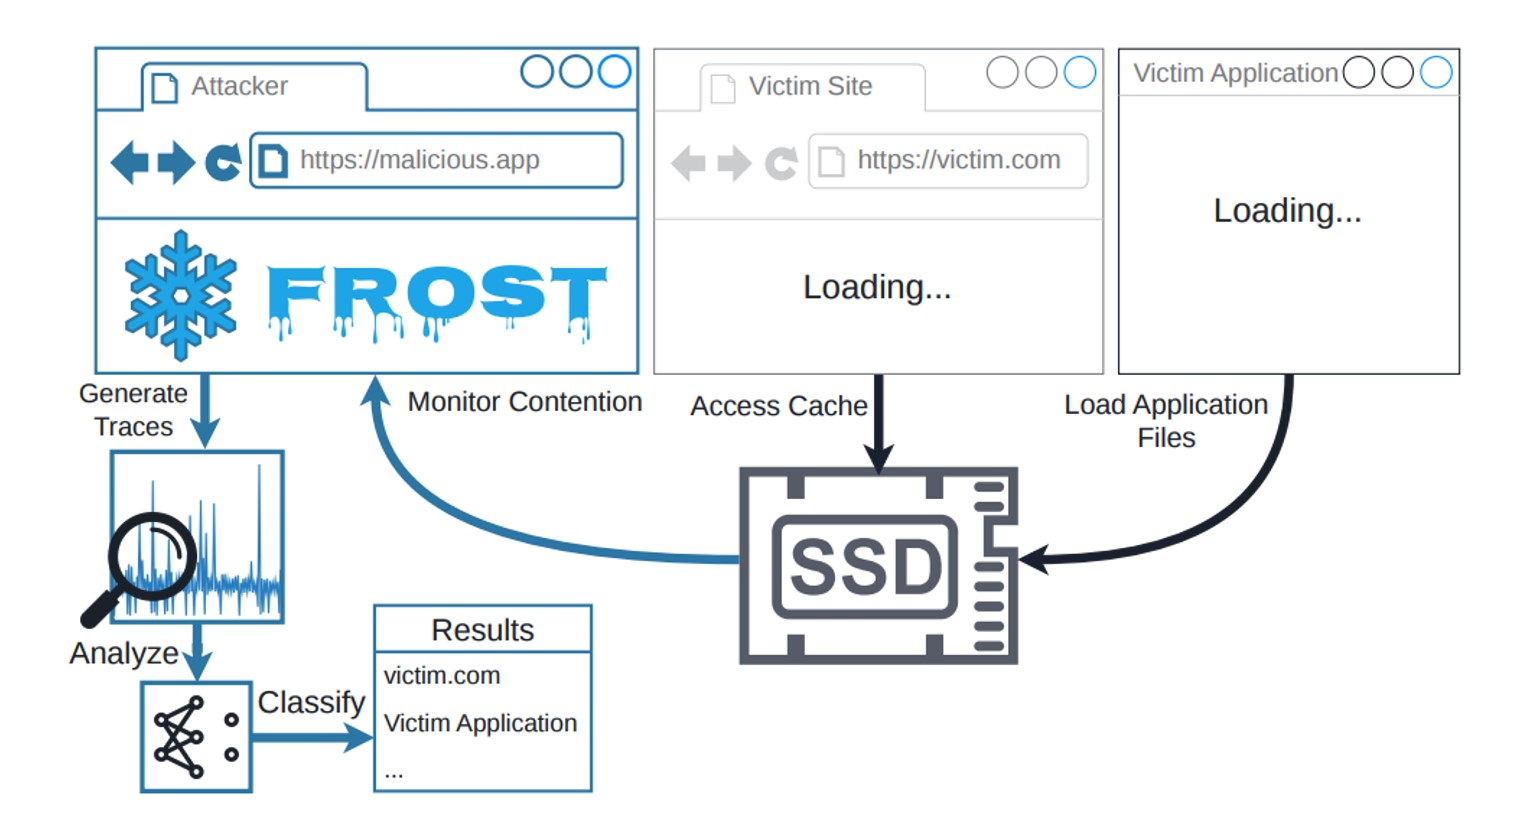
And that’s where a relatively new browser feature called the origin private file system (OPFS) comes into play. A hypothetical attacker doesn’t have to trick the user into downloading a shady Trojan. All they need do is have the victim visit a specially crafted webpage, and that page will leverage OPFS to quietly track the SSD’s activity. The clever acronym brings all these moving parts together: FROST stands for Fingerprinting Remotely using OPFS-based SSD Timing. Here’s the step-by-step breakdown of how the entire attack plays out:
How the FROST method can be used to spy on a computer’s activity Source
Method limitations
Like any side-channel attack, FROST isn’t exactly built for speed. It’s a slow, methodical process. To figure out just how slow, the researchers built a dedicated testbed to measure it.
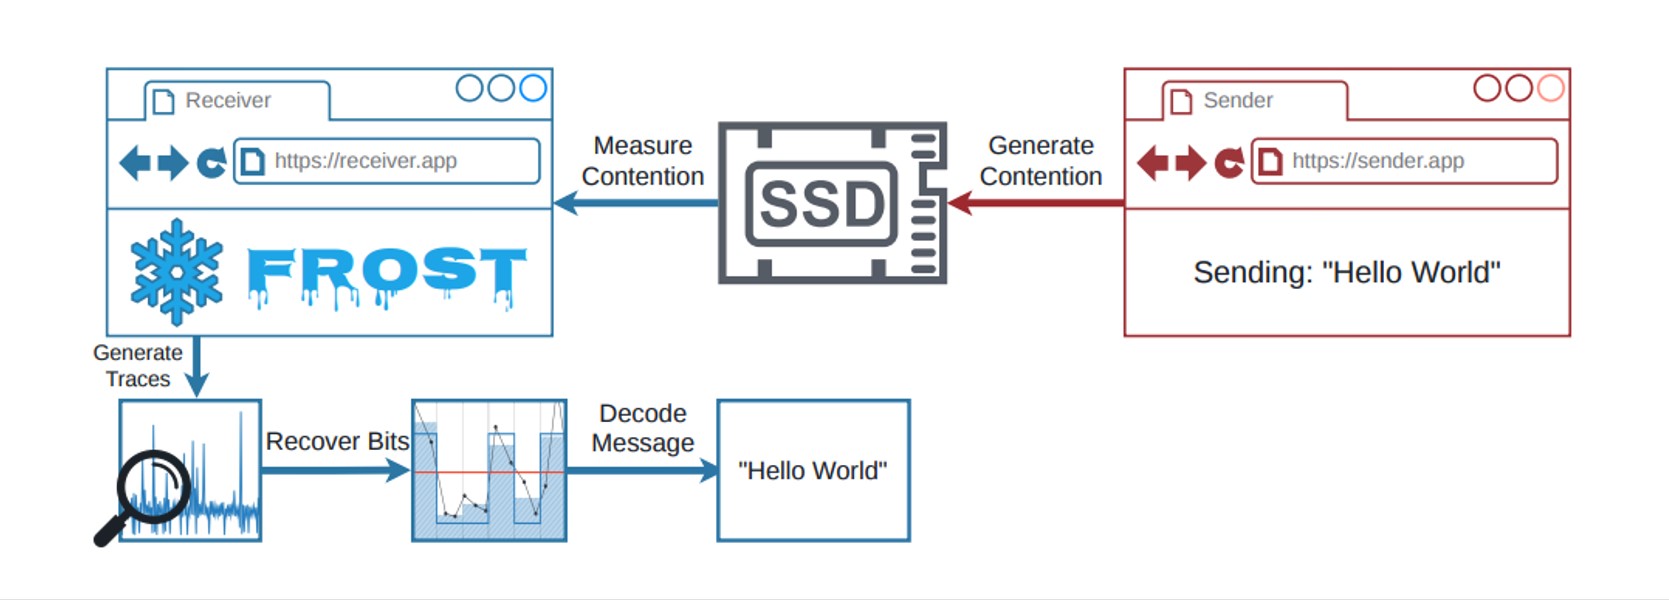
The testbed setup for measuring the speed of data extraction through OPFS Source
The team ran a program on a computer to transmit data indirectly. Think of it as a digital spy broadcasting a secret message by changing how it interacts with the hard drive. For instance, a 1 in the binary message code could mean the program is actively using the SSD, while a 0 means it’s sitting idle. At the same time, they set up a receiver inside the web browser that accessed the storage drive via OPFS. Because both the browser receiver and the transmitter program were competing for the SSD’s bandwidth, the browser experienced tiny speed delays whenever the transmitter was actively sending data.
This bizarre setup managed to transmit data at 661 bits per second, with nearly 90% accuracy on a Linux desktop with an AMD processor. On an Apple Mac Mini running macOS, the transfer rate hit 719 bits per second, also hovering around 90% accuracy. While these numbers are slightly lower than those in last year’s study — which relied on apps installed directly on the computer — the gap isn’t actually that huge.
That said, the real threat of the FROST attack isn’t raw data transmission; it’s tracking what the user does. Even if a hacker has a database of digital fingerprints for specific apps and websites, the information leaked through a malicious site using OPFS is too noisy. After all, a computer is constantly reading and writing data from/to the SSD in the background. To slice through that digital noise, the researchers turned to a tool that’s becoming standard practice in modern cyberattacks: a neural network. AI trained on known SSD fingerprints could confidently pick out user activity even from a chaotic mess of background data. The final results are eye-opening. On the Apple Mac Mini, the AI accurately identified which website the user opened 89% of the time, and nailed local app launches with 96% accuracy. Crucially, it could even detect what websites were opened in a completely different browser than the one running in the malicious tab. It sounds like a total home run for hackers — except for a massive list of real-world catches.
Is the FROST attack a real-world threat?
Simply knowing which apps are opened or what websites are visited doesn’t give an attacker much leverage. This kind of data is usually useful to advertisers looking to build a user’s digital profile without their permission; however, rolling out this tracking method on a massive scale is hardly realistic. The roadblock comes down to the fundamental way computers handle data: the system regularly dumps frequently accessed data into its RAM. Because the entire FROST attack relies on measuring the relatively slow bandwidth of the physical SSD, the data in RAM is effectively invisible to this method. To bypass this hurdle, the malicious webpage would have to force the OPFS to create a massive file — well over a gigabyte in size. Needless to say, a website that hogs hard drive resources in such an aggressive way would immediately raise red flags. EDR or XDR solutions will most likely flag it as anomalous activity.
Ultimately, this means the FROST attack — like most side-channel spying methods — is only practical for highly targeted operations. But that brings us right back to square one: knowing what apps someone opens or what web pages they browse is a pretty measly reward for the massive effort required to pull off such a sophisticated stunt.
Even so, FROST is light-years ahead of most academic side-channel attacks when it comes to real-world practicality. It doesn’t require preinstalled malware, and the victim doesn’t have to do anything more than open a malicious page. If nothing else, this research is a stark reminder of just how complex modern computers are, and how many unexpected blind spots can lead to data leaks. When building ultra-secure systems for highly classified data, one absolutely has to consider hardware peculiarities. If the prize is big enough, a determined attacker will gladly invest the time to build a hyper-specific complex attack. Research like this serves as proof that, in the world of cybersecurity, that scenario isn’t impossible.
Unchecked AI in the workplace quickly becomes a massive loophole for data leaks and security breaches. All too often, employees drop sensitive company data into public chatbots, or install rogue AI assistants on their own — in the process handing over way too much access. In a previous post, we broke down the different types of risky AI systems, and later shared some tips on how to turn off the built-in AI features on major tech platforms. Today let’s take a look at practical ways to block or restrict the unauthorized “helpers” employees might be using — from ChatGPT and Grammarly, to meeting bots like Fireflies and Read AI.
How to detect and restrict ChatGPT
ChatGPT is the biggest culprit when it comes to unauthorized AI use worldwide. A quick word of warning, though: an outright ban only sends users hunting for sketchy third-party sites or messaging app chatbots that hook into the same service. That’s why it’s always a good idea to offer an approved alternative before pulling the plug.
Detecting it: keep an eye on the NGFW or web filter for traffic heading to chat.openai.com, chatgpt.com, oaistatic.com, oaiusercontent.com, or cdn.oaistatic.com. It’s also smart to use EDR/EPP tools to scan browser histories, installed apps, and browser extensions across corporate devices.
Locking it down: use the firewall or web filter to block the entire AI Services category, and set up DNS to reroute traffic away from those OpenAI domains. Browser policies can also be used to ban ChatGPT-powered extensions. Better yet, block all extensions not on a pre-approved allowlist. Finally, use application controls and EPP solutions to stop users from installing the official desktop app (ChatGPT.exe or com.openai.chat).
How to detect and restrict Claude and Claude Code
Detecting it: use the NGFW or web filter to track traffic going to claude.ai, anthropic.com, *.anthropic.com, and api.anthropic.com. EDR/EPP or application control tools can also be used to scan employee computers for the desktop app (claude.exe).
Locking it down: drop a blanket block on the AI Services category through the NGFW or web filter, and tweak DNS settings to reroute traffic away from the aforementioned Anthropic domains. Next, use browser policies to shut down Claude-powered extensions. Finally, use application controls and the EPP platform to prevent users from installing the desktop app.
How to detect and restrict Perplexity AI
Detecting it: keep tabs on the NGFW or web filter to flag any traffic heading to *.perplexity.ai or pplx.ai.
Locking it down: just like the others, add the AI Services category to the NGFW or web filter blocklist, and use DNS routing to redirect traffic away from those domains.
Configure the browser to block third-party extensions from being installed. If Firefox is used in the organization, be aware that recent versions come with Perplexity built in. Luckily, these AI features can be turned-off company-wide using enterprise policies — specifically, by setting SidebarChatbot = blocked. The full list of tweaks can be found in the Firefox documentation.
How to detect and restrict DeepSeek
Detecting it: keep an eye on the NGFW or web filter for traffic hitting deepseek.com, chat.deepseek.com, api.deepseek.com, or platform.deepseek.com. For better precision, analyze the SNI (server name identification) in TLS connection requests. For mobile devices, look out for the official app (com.deepseek.chat).
Locking it down: blocklist the AI Services category on the NGFW or web filter, and reroute traffic to DeepSeek’s domains via DNS settings. Use browser policies to block third-party extensions, and lean on MDM/EMM tools to restrict the mobile app.
How to detect and restrict Mistral, xAI Grok, and Character.ai
The playbook for these tools is exactly the same as DeepSeek, so here’s the quick list of domains to watch for and block: chat.mistral.ai, mistral.ai, console.mistral.ai, grok.com, x.ai, api.x.ai, character.ai, beta.character.ai, and c.ai.
A quick word of warning on Grok: because Grok is baked into X, blocking this specific AI access point means blocking the entire social media platform.
How to detect and restrict Slack AI
Detecting it: in the Slack workspace admin dashboard, look under Analytics → Slack AI usage. If an enterprise plan is used, the detailed Slack logs can be searched for any events starting with the ai_ prefix.
Blocking it with policies: in the organization’s Slack settings, click through the Workspace settings → Roles & permissions → Feature access, and change the permission to “no one”. Slack has a step-by-step guide in their help center.
Locking it down: shutting this down at the network level is tricky; it can be pulled off with a finely tuned CASB solution in place. Also, don’t forget the importance of blocking rogue integrations and keeping external AI services from tapping into Slack data in the first place. We covered how to lock this down using OAuth controls in a previous post.
How to detect and restrict Zoom AI Companion
Detecting it: if a corporate Zoom subscription is in use, just head to Admin Center → Reports → AI Companion usage. Detecting Zoom’s AI when employees join external meetings or use free accounts is a lot tougher, but email filters can be set up to flag incoming AI-generated meeting notes by scanning for subject lines or text containing “Meeting summary” or “Meeting assets”.
Blocking it with policies: for the company’s own Zoom subscription, go to the Admin Portal → Account Management → Account Settings → Meeting → AI Companion and toggle it OFF for everyone.
Locking it down: unfortunately, AI Companion is baked into Zoom’s DNA, so the only real option is blocking Zoom altogether.
How to detect and restrict Grammarly
What looks like an innocent spellchecker is actually one of the biggest culprits for workplace data leaks.
Detecting it: check the NGFW or web filter logs for traffic hitting grammarly.com, *.grammarly.com, and gnar.grammarly.com. EDR and MDM/EMM tools can also be used to hunt down the standalone desktop apps (Grammarly Desktop.exe and the macOS version), as well as the Grammarly browser extension.
Locking it down: use firewalls to block those domains at the network level, and EPP to stop employees from installing the desktop app, browser extensions, or the Grammarly add-ins for Microsoft Word and Excel.
How to detect and restrict meeting assistants: Fireflies, Read.ai, Tactiq, Fathom, and Granola
This massive category of third-party SaaS tools records and analyzes meetings — creating a massive risk for data leaks. The trickiest part? Outside clients or vendors can bring these bots into a meeting just as easily as employees can.
Detecting them: run an audit on calendar invites, and look for bot participants using email domains like @fireflies.ai, @read.ai, @tactiq.io, @fathom.video, or @granola.ai. Zoom, Teams, or Google Meet logs can also be used to review external participants who joined past calls.
Locking them down: since it’s impossible to control what outsiders do, blocking these bots comes down to tightening meeting rules. The best moves are: blocking users from granting OAuth permissions for bots to join calls, restricting employees from inviting unapproved external participants, or locking down meeting recording access for external users. That last option is usually the least painful way to keep bots out without disrupting business.
How to detect and restrict AI code editors: Cursor, Windsurf, and the like
Detecting them: use EDR/EPP tools to scan for executables like cursor.exe or windsurf.exe. It’s also worth monitoring network traffic heading to cursor.com and windsurf.com, as well as traffic hitting various AI model API providers. Keep in mind that there’s a pretty extensive list of API hosts to monitor here, since these editors aren’t tied to just one specific AI vendor.
Blocking them with policies: these apps can be prevented from being installed by setting up filters based on the developer’s digital signature certificate. Alternatively, a strict application allowlist can be employed where only pre-approved software is allowed to run.
Locking them down: rely on the EPP/EDR platform to actively detect and block these applications from running.
How to detect and restrict local AI tools: Ollama, LM Studio, and GPT4All
On one hand, this category carries fewer data leak risks because the AI models run completely locally on the user’s machine. On the other hand, it opens up a whole new can of worms: these apps themselves aren’t always highly secure, and can become targets for cyberattacks. Plus, it still means that employees can misuse models or process data in unauthorized ways.
Detecting them: EDR/EPP tools are the best line of defense here. They should be used to flag known local AI files and processes like ollama.exe, ollama serve, lmstudio.exe, LM Studio.app, jan.exe, or gpt4all.exe. From a network perspective, it’s worth scanning for open ports on local devices — typically port 1234 for Ollama and LM Studio, or port 8080 for WebUIs (using an additional fingerprint check of the server response). Another massive red flag is the presence of large files (often several gigabytes) containing language model weights. Look out for extensions like .gguf, .bin, or sometimes .safetensors.
Locking them down: use EPP/EDR platforms or windows AppLocker to block these applications by name, or switch to an application allowlist.
How to detect and restrict autonomous agents: OpenClaw, NemoClaw, and NanoClaw
This is easily one of the most dangerous categories of AI tools out there. These agents mix high-level independence with access to untrusted data, making them a massive security headache.
Detecting them: use EPP/EDR tools to sniff out active processes like openclaw, nanoclaw, nemoclaw, or clawdbot. Also keep an eye out for devices running Node.js that suddenly start launching Bash or Python scripts. Another dead giveaway is the appearance of system folders like ~/openclaw, ~/nanoclaw, ~/.claw*, or ~/clawhub. At the network level, monitor connections to the AI model APIs we mentioned earlier, as well as traffic hitting servers like openclaw.ai, nanoclaw.dev, or clawhub.*.
Locking them down: the safest bet is to use strict application allowlisting (only allowing approved software to run), or to specifically ban the known agent apps listed above. On top of that, consider blocking non-developers from installing Node.js and Docker, neither of which they need on their computers anyway.

 Login