❌

Reading view

Part 3 – Cybersecurity journeys: The work behind the work

The most important work I’ve done in cybersecurity would make for terrible television. There were no countdown clocks and no frantic typing, just a lot of careful reading, a lot of hard conversations, and the occasional quiet moment where everything finally clicked. That’s the part I want to show you this week, because the three people I talked to have built their entire careers on the work that happens off-camera, and it’s the part that decides who lasts in this field.

This is a four-part series following 11 AWS security professionals through the real stories of how they got here and what the work actually looks like. In Part 1: I didn’t plan this, I shared how three of them found their way in, and in Part 2: What even is this job?, we looked at roles most people don’t know exist. This week is about what the day-to-day actually feels like, told through three AWS security professionals whose work rarely makes it into the trailer but is the reason any of it holds together.

Unlimited ammo
Brandon Caldwell, Mgr, Security Engineering

Brandon Caldwell, Mgr, Security Engineering

Ask most people to picture an application security engineer at work and they’ll imagine someone hunched over a terminal breaking into systems. Brandon Caldwell‘s actual days (reviewing software while it’s being built so the flaws never ship) look almost nothing like that. He spends them in conversation: sitting with the engineers who built a product, walking through how it works, and asking question after question until he understands it well enough to see where it could break. “This job is at least 50 percent people,” he tells the folks he hires. “You have to people a lot.”

The hardest part of the day isn’t technical, it’s human. Brandon’s team has to hand builders news they don’t want to hear, and he’s blunt with new hires about what that really feels like.

“Our job is to go tell someone their baby is ugly. I use that phrase because it is meant to draw out empathy. This is the thing they love and spent time on, and you show up at the end and say that thing is ugly. Of course they are going to react.” – Brandon Caldwell


Learning to deliver that message without crushing the person across the table is, in his telling, the actual craft of the job. It’s why he prizes empathy, and why he says the engineers who struggle most in application security are the ones who got into tech specifically to avoid talking to people. The rest of the day is the patient, unglamorous work of reading someone else’s code closely enough to find the one flaw they didn’t know they’d left, then explaining it in a way that lands as help rather than judgment.

That explaining is more than a conversation. So much of security work gets written down: the finding documented so an engineer can act on it, the advisory that tells customers what to do, the policy that sets the bar for everyone who comes after. The ability to write clearly, to turn something messy and technical into a few sentences a reader can actually use, is one of the quiet differentiators as you move up in this field, and it’s a skill worth building long before anyone asks you to.

None of this is where Brandon started. He’s been curious about breaking things since he was a kid hex-editing the game Doom for unlimited ammo, taught himself reverse engineering (taking apart finished software to understand how it works) before it had a name, and spent years as an IT admin and then in incident response at Microsoft back when cybersecurity barely existed as a job title. What pulled him off the breaking side was noticing—after watching the same handful of mistakes scroll past again and again (things like SQL injection and cross-site scripting, two of the most common ways attackers exploit a poorly built website)—that he’d rather help teams avoid the break-in than perform it. Application security, he says, is his natural place.

As for breaking in yourself, Brandon’s advice follows straight from how he spends his days: practice interviewing and asking the right questions and spend real time around builders so you understand what goes into the thing you’re critiquing. When he hires, certifications are the last thing he looks at; he wants to see capture-the-flag competition results (hacking contests where you solve security puzzles to earn points) and public GitHub projects, because those prove you’ve done the work. Build something, break something, and get comfortable talking to the people who build.

Forget that
Kurt Heath, IT Support Associate

Kurt Heath, IT Support Associate

Kurt Heath‘s chosen corner of the work is offensive security: penetration testing (getting paid to legally break into systems to prove where they’re weak) and, eventually, red teaming. The day-to-day of getting good at it is far less cinematic than the label suggests. It’s hours of hands-on practice against deliberately vulnerable targets, reading about a technique and then trying it until it works, and the slow accumulation of the layers the job actually rests on: operating systems, networking, software development, and security fundamentals, all applied at once. He’s the first to say pen testing is “the sexy thing” that gets advertised, and the first to warn that it shouldn’t be anyone’s first stop, because of how much quiet groundwork sits underneath it.

A big part of his real workday now is deciding how, and how much, to lean on AI. Kurt treats it as a tool rather than a crutch: he uses it as a coding assistant when he has to work in an unfamiliar language, and to sort through large volumes of information quickly, but he won’t let it think for him. He still fills out forms like this blog’s questionnaire by hand, keeping a personal touch on his own work, and he’s wary of letting AI pull the trigger during an engagement, since an overzealous tool can act on a network however it sees fit, cause unintended operational damage, or wander out of scope and create a legal problem. The way he sees it, security is fundamentally a human problem: automation keeps getting better at the systematic parts, but thinking outside the box the way an attacker does stays stubbornly human.

How Kurt got here matters less to the day-to-day than how he keeps going, but it’s worth knowing that he’s largely self-taught. After a community college program didn’t work out, he taught himself from scratch, finishing shifts at an auto plant and then spending nights with YouTube and a search bar learning how computers and networks actually worked. The hardest part, he told me, was self-motivation, and what carried him through was a mix of sheer want and, eventually, other people: the friends and community he found in Discord servers, security podcasts, and interest channels who helped him turn raw drive into real focus. He even got a tattoo as a reminder that there is no plan B.

“There is no other option. There’s no what if. This is it. This is life now, and I’ll figure it out some way, somehow, no matter how long it takes.” – Kurt Heath


If you’re drawn to the same offensive work, Kurt’s advice is to resist starting there. Build the foundation first, often through a role like a security operations center, join the communities where people are learning in the open, and let the flashier work come after the groundwork is solid. Progress in this field—in his experience—is measured less by the title you land than by how much you grow and who you grow alongside.

The comfort lock
Seth Jeacopello, Mgr, Security Engineer

Seth Jeacopello, Mgr, Security Engineer

Seth works in application security too, but if Brandon’s days are mostly about people, Seth’s are mostly about code, which makes the two of them a useful picture of how differently the same job can look. When Seth Jeacopello gets stuck on a hard problem, he doesn’t stare at it harder, he picks up a lock. An actual physical lock with pins and tumblers, because he’s a serious lock-picking hobbyist, and over the years he’s learned that the best response to hitting a wall is to set the problem down and pick what he calls a comfort lock, one he knows well and can open easily. It isn’t about the lock; it’s about giving his brain a small win so he can return to the hard thing with fresh eyes.

The comfort lock exists because Seth’s actual day-to-day is easy to get lost in. In application security, a big part of the job is reading enormous amounts of someone else’s code looking for the one flaw that matters, and as a lifelong developer he genuinely loves reading code, which is exactly what makes it a trap. He described the pull of it to me: you convince yourself the vulnerability is just behind the next function, and the next, and suddenly two days are gone. The skill he’s spent decades sharpening isn’t finding things, it’s knowing when deep enough is deep enough and when to step back, which is where the lock comes in. After 26 years, the meta-skill of managing his own attention is as much a part of the craft as anything technical.

That longevity goes back a long way. Around 1999, still in his teens, he landed a software quality assurance internship, was hired as a developer by 17, and gravitated toward the security-flavored work from the start before moving into network security tooling, rising to chief architect and then chief technology officer along the way.

“We’re like three or four guys off the street coming in with a product, and this huge company was like, yeah, you three, go for it. That was probably one of the coolest things.” – Seth Jeacopello


His advice for building the instincts the daily work demands is refreshingly concrete: set up a deliberately vulnerable practice machine, break into it, and then go read the logs it generated, so you learn not just how an attack works but what it looks like from the defender’s side. That single exercise builds both the offensive and the investigative muscle at once, and it’s the kind of patient, repeatable practice that the day-to-day of this field actually rewards.

The thread

There’s a version of cybersecurity that makes for great television, fast-paced and full of eureka moments, and those moments do exist. But the three people I talked to this week live in a different version of the field, one built on patience, repetition, and a kind of stubborn care that doesn’t photograph well. For Brandon, the real work is the hard, human conversation of telling a builder their work is flawed without making an enemy of them. For Kurt, it’s the unglamorous hours of hands-on practice and the discipline to use AI as a tool without letting it think for him. For Seth, it’s reading one more page of code and knowing when to stop, with a comfort lock on the desk for when he can’t.

None of that makes a great action sequence, but all of it is what a security career actually looks like, and the good news for anyone starting out is that these are learnable habits, not inborn talent. Notice how much of the real work is human: empathy, patience, judgment, and knowing how your own mind works. The analytical, interpersonal, and self-management skills you already have are not a consolation prize, they are part of the job. If you want to begin building the rest, here are a few places to start:

  • TryHackMe and Hack The Box let you stand up deliberately vulnerable machines, break in, and study what you triggered, exactly the exercise Seth recommends
  • The OWASP Top 10 explains the most common application security flaws, including the ones Brandon saw on repeat
  • The OWASP Cheat Sheet Series turns those flaws into practical, task-level guidance on how to build and review software securely; the daily bread of Brandon’s and Seth’s work
  • The Darknet Diaries podcast tells the human stories behind real security incidents, and it’s a good way to hear what the work actually feels like

And if you want to build cloud security skills specifically, AWS has free and hands-on resources to help you start:

  • AWS Skill Builder offers more than 1,000 free self-paced courses, including security learning plans you can start today
  • AWS Builder Labs lets you practice in a real AWS console on hands-on security labs, the stand-it-up-and-try-it approach Seth recommends

In Part 4: What I’d tell myself, we close the series with the advice and hard-won lessons these professionals would hand to someone just starting out.

Doing the work behind the work? These three want you to know it counts. Share your story on LinkedIn!
Shannon Brazil

Shannon is a senior security engineer, managing a team on the AWS Customer Incident Response Team (CIRT), specializing in digital forensics and cloud security investigations. Known in the community as AWSlady, she is passionate about security education and mentoring the next generation of defenders.

  •  

Part 2 – Cybersecurity journeys: What even is this job?

If you’ve ever looked at a list of cybersecurity jobs and felt like none of them fit you, you might just be looking at a short list. Most career guides cover the same few roles, like the analyst watching alerts or the pen tester (penetration tester, someone hired to legally break into systems to find weaknesses) looking for a way in. Those jobs matter, but they’re a small slice of a field with room for a lot of different skills. The three people in this post do work you probably won’t find in those guides, and none of them started out qualified for it. What they had in common was a willingness to aim at something before they were ready and to build the skills on the way there. If you’ve ever talked yourself out of a role because you didn’t tick every box, their stories are worth a few minutes, because the move each of them made is one you can make too.

In Part 1: I didn’t plan this, I shared how three people found their way into security from a warehouse floor, a marketing desk, and a teenager’s bedroom. This week is about where people end up after they’re inside. I’ve been in security for over a decade, and while putting this series together I kept running into work I hadn’t come across before: measuring the risk of a million applications at once, building detection tools from the customer service side of the house, and thinking seriously about how to secure infrastructure that’s being launched into orbit.

The skill tree

Jason Lane, Security Engineer

Jason Lane, Security Engineer

When Jason Lane told me he plans his career like a Dungeons & Dragons character build, I assumed he was being metaphorical, but he meant it literally. “Think of it like a video game skill tree,” he said, and then walked me through the whole framework. You start by picturing your level 20 character, the version of yourself with the skills and the role you actually want, and then you work backward. At level 19, what choices get you to 20? At level 18, what needs to be true so you even have those options? You keep stepping back until you’re standing at level 1, looking at a path you built from the top down.

For Jason, level 20 was vulnerability research (finding unknown security flaws in software before attackers do). At the time he was a systems administrator, keeping servers and networks running, which gave him a solid grasp of how systems fit together but little exposure to picking apart the applications on top of them. That gap, application security, was the next node on his tree, so he called an IT recruiter, laid out his plan, and was honest about where he stood. The recruiter found a credit card processing company that needed an application security engineer and was open to someone who wasn’t one yet. For Jason it was a paid apprenticeship in the exact skill he was after; for the company it was a motivated engineer who would grow into the role. He describes it as a deal where both sides got what they needed, and that framing matters: he wasn’t settling for less, he was trading a steeper learning curve for a faster path to where he wanted to be.

He spent 4 years there taking applications apart to understand what made them breakable, and when he had learned what that role could teach him, he applied the same framework again. A friend offered to get him an interview at Google, and Jason’s honest reaction, that he wasn’t smart enough to work there, is the kind of self-doubt most of us recognize (also known as imposter syndrome). His friend didn’t buy it, the interviewers didn’t either, and they hired him. The lesson he took from it is one worth borrowing: the voice telling you that you don’t belong in the room is often wrong, and the way to quiet it is to put in the work until the skills speak for themselves. He went on to spend nearly 7 years doing Android vulnerability research, the kind of deep technical work most companies don’t have the budget for.

That track record opened the door to Amazon. When the team that measures application risk interviewed him, the hiring manager’s pitch was simple: we could really use your vulnerability research experience. Years of tearing systems apart to find what made them breakable turned out to be the perfect background for judging which systems were most at risk. Today, Jason measures risk across roughly a million applications at Amazon, evaluating which ones would cause the most damage if compromised and which are most likely to be targeted, so the organization can focus on the most dangerous ones first. When his manager recently presented the team’s work to a new senior leader, the example he used was a project Jason had built from scratch. Jason’s name wasn’t on the slide, and he told me he didn’t need it to be, but you could hear the pride in his voice.

When I asked what he’d tell someone with a big vision and no idea where to start, he said to get obsessively clear about where you’re going, because the gaps will show up on their own. He compared it to planning a 100-mile trip and realizing you aren’t wearing shoes; once you see it, you can’t unsee it. And if it turns out the dream is really a hobby, he’s at peace with that too.

“If you can wait for Saturday, maybe you should just wait for Saturday. There’s nothing wrong with that.” —Jason Lane

If you’ve been waiting for someone to hand you a career ladder, Jason’s approach offers another option: decide where you want to end up, and let that tell you what to learn next.

Full circle

Jason Goodman, Security Engineer

Jason Goodman, Security Engineer

Where Jason Lane planned his career from the finish line, Jason Goodman’s career has looked more like a pinball machine, bouncing through three security disciplines in about a year and picking up new skills along the way.

The foundation was laid long before he knew it. Eight years ago, before Amazon acquired Ring, he was working in customer service, troubleshooting doorbells and helping customers with their accounts, and before that he sold computers at Best Buy. “That was the most tech I had,” he told me, grinning. What pointed him toward security was partly a nudge from his father-in-law, who worked in IT, and partly what he was seeing on the phones every day: the occasional account access that didn’t look right, the quiet signals that something might be off. Those patterns made him want to understand the systems behind them, so while he was still in customer service he went back to school for a cybersecurity degree.

He didn’t wait until graduation to start building toward the move. He reached out to the manager of the internal threat team (the people who look for misuse of access from inside an organization) and asked a question anyone can ask: what could I do to keep progressing while I’m in school? That turned into stretch projects, and here is the part worth noticing, he earned the bigger ones by delivering the smaller ones first. His standout project was a fraud prevention dashboard that helped the team spot potential misuse of customer account access, a blind spot nobody had flagged. He had the credibility to be handed it because he’d already shown up for the low-stakes work, and it opened the door to his first security engineering role on that same team.

From there he moved to an adversarial threat detection team (the people who watch for outside attackers trying to get in), which meant flipping his mindset overnight: instead of asking what someone on the inside could do with their existing access, he was now asking how someone on the outside would try to break in. A later move took him into application security, where the work shifted from responding after the fact to building security into processes from the ground up.

“I’m in my third discipline in a year since transitioning out of customer service into security engineering.” —Jason Goodman

What I find fascinating is how much carried over from one role to the next. The Splunk queries (Splunk is a tool for searching and analyzing large volumes of log data) he learned in customer service carried into internal threat work, the detection logic from insider investigations carried into adversarial detection, and now in application security he has come full circle, working alongside the same customer service teams he started with, except this time he’s helping build the security around them.

Through all of it, he has leaned on four different mentors, and the way he found them is worth stealing. Finding one mentor who truly invests in you is hard; finding four is rare. Jason didn’t wait to be assigned anyone. He reached out to people whose work he admired, starting with that internal threat manager during school, asked specific questions, and stayed in touch over the years as he grew. Each mentor served a different purpose: one for navigating school, one for stretch projects, one for learning to think like an adversary, and one for getting grounded in application security. “I’ve always felt like I could take at least a little nugget from each one of them,” he said. Next on his list is offensive security, meaning pen testing and red teaming (simulating real attackers to test how well an organization defends itself). He figures starting on defense was the right call: learn what attackers do and how to stop them, then learn to think like one.

If your current role feels unrelated to security, Jason’s story is a good reminder that the skills you’re building now may be exactly the ones your first security job needs. The analytical habit of noticing when something is off, the patience to explain a problem clearly, even the instincts you pick up from a completely different field all transfer. The trick is learning to name what you already have and point it at the work you want.

The edge of the map

Harshvardhan Chunawala, Solutions Architect, AWS Startups

Harshvardhan Chunawala, Solutions Architect, AWS Startups

Harshvardhan Chunawala was still in high school when he started finding security flaws in real products and reporting them to the companies that built them. He had started out building websites and web applications, and after he understood how software was put together, he couldn’t stop wondering how it could be pulled apart. Rather than wait until he had a degree or a job to explore that, he began poking at real products on his own, and when he found a flaw he contacted the company and worked with them to fix it.

Today he advises startup founders at AWS on security and volunteers his time to teach cloud and security courses to students, who often ask him where to start when entry-level work is being automated. His answer has changed over the years. Now that generative AI can answer the surface-level questions, he believes curiosity matters more than credentials, because the people who stand out are the ones who keep asking questions after the tool runs out of answers.

“AI tools put everyone on the same starting line. Interest and passion has become the driving force.” —Harshvardhan Chunawala

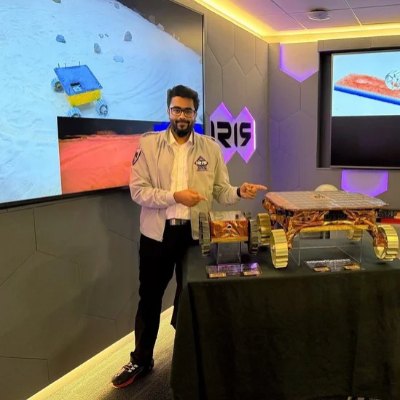
What surprised me most, though, was where his own curiosity took him. While studying at Carnegie Mellon University (CMU), he ended up working on space missions, including time as a mission operator for the Iris lunar rover (Iris and CMU’s next rover, MoonRanger, appear with him in the photo above). If you had asked me a few years ago whether security belonged anywhere near a rover on the Moon, I wouldn’t have known what to say, but Harshvardhan would have answered right away: anything that can be commanded remotely can be commanded by the wrong person.

When I asked about the future of security, he took the conversation completely off the map. He talked about robots entering people’s homes and about data centers moving from land to underwater to space. A satellite has to be protected in orbit, where nobody can physically reach a compromised system, and on the ground, where the stations that command it are targets too. “So are cyber security specialists going to go under astronaut training?” he asked, grinning, and he was only half joking. He has already written a two-part guide to incident response for satellite operations on AWS, so for him, this corner of the map is already part of the job.

If you’re drawn to an area that doesn’t look like a security job yet, Harshvardhan’s story is worth taking seriously: the move he keeps making is to follow a question past the point where the easy answers run out, into territory nobody has fully mapped. You don’t need a satellite to do that. Pick the corner of technology that genuinely fascinates you, start asking how it could be attacked and defended, and you might find you’re standing at the edge of a role that doesn’t have a name yet.

The thread

These three stories share one thread: the job you end up loving might be one you haven’t heard of yet. Jason Lane mapped his moves in advance, Jason Goodman carried his skills through three disciplines in a single year, and Harshvardhan is already helping AWS customers secure satellites and the ground systems that run them. None of them could answer “what do you do?” in a single sentence, and I suspect that’s true for a lot of people doing interesting work in this field.

If you’re curious about the roles that exist beyond the ones you already know, here are a few places to start exploring:

In Part 3: The work behind the work, we pull back the curtain on what the day-to-day of security actually looks like compared to what people imagine.

Have you found a corner of security most people don’t know exists? Share your story on LinkedIn!


Shannon Brazil

Shannon is a senior security engineer, managing a team on the AWS Customer Incident Response Team (CIRT), specializing in digital forensics and cloud security investigations. Known in the community as AWSlady, she is passionate about security education and mentoring the next generation of defenders.

  •  

Part 1 – Cybersecurity journeys: I didn’t plan this

If you’ve ever wondered whether your background qualifies you for a career in cybersecurity, you’re not alone — and you’re probably more prepared than you think.

My name is Shannon Brazil, and I work in security communications at Amazon Web Services (AWS). I have been in the security space for over a decade, and my own journey into it wasn’t exactly a straight line. I started in Statistics Canada helping people fill out export declaration forms over the phone, then got a college placement in IT, moved into Digital Forensics and Incident Response, and eventually found my way into the side of security that most people don’t think about: how we communicate about it, how we tell the stories, and how we help people understand what this work looks like from the inside.

Nearly every time I’m asked that “how do I get in?” question, my answer is different. Not because I’m making it up as I go, but because I try to make it relatable to the person asking. Every person I’ve met in this field started from a different and took a completely different road to get here. There is no checklist, no degree that unlocks the door, and no straight line.

I decided to create this series for Cybersecurity Awareness Month, however I didn’t want to write another “Top 10 Tips to Break Into Security” post. Instead, I interviewed with 11 security professionals across AWS, each from a different team and a different background, and asked them one basic question: how did you actually get here?

What came out of those conversations surprised me. The stories were funny, honest, sometimes hard to hear. Over the next four weeks, I will be sharing them in a four-part series, grouped by theme:

  1. I didn’t plan this (this post) explores the non-linear paths that brought people into security from places you wouldn’t expect.
  2. What even is this job?” dives into the lesser-known corners of security that most people don’t realize exist.
  3. The work behind the work pulls back the curtain on what the day-to-day looks like compared to what people imagine.
  4. What I’d tell myself wraps the series with advice, growth moments, and the kind of wisdom that only comes from having lived it.

Nearly every person I spoke to had a different story, but one thing kept coming up: nobody planned this. And that’s kind of the whole point. So let’s start there.

Mr. Robot and a box cutter

Justin Knight, Security Engineer

Justin Knight, Security Engineer

Justin Knight was packing boxes in an Amazon warehouse when his career in cybersecurity started. He just didn’t know it yet.

It was around 2015 or 2016, and he’d just started at Amazon, working fulfillment, scanning, packing, shipping, with no tech background and no degree in computer science. What he did have was a TV show.

“I saw Mr. Robot,” he told me, grinning. “And I was like, man, I want to do that.” I’ve heard a lot of origin stories in this field, but something about watching a fictional hacker-vigilante while surrounded by conveyor belts and cardboard, and deciding that’s the career for me, just felt different. Justin started teaching himself by turning YouTube into his classroom (Daniel Messler for the fundamentals, Stök for the hacker mindset, NetworkChuck for the energy), and spinning up a Kali Virtual Machine (a free operating system built for security testing) and diving into Hack the Box (an online platform where you practice cybersecurity kills by solving challenges) and TryHackMe labs (a beginner-friendly platform for learning cybersecurity through guided exercises), all while still packing boxes.

When an IT role opened up inside the warehouse, Justin jumped on it and started doing the tasks the team disliked the most: fixing broken laptop screens. He would proactively walk the floor looking for cracked displays before anyone even filed a ticket, replace printers (the silent soul-killer of every IT professional), and eventually became the “computer guy” while already looking for what was next.

Justin found a bug bounty role posted on LinkedIn, and even though he had no idea what bug bounty even was, he reached out anyway. The hiring manager had a one-on-one with him, saw the passion, and did something I’ve seen happen before but never gets old: he lowered the role level requirements to a lower seniority level so Justin could make the jump.

Four years later, Justin is still on that team. He just got back from DEFCON, his second time, where he met the very YouTubers who taught him everything he knows.

“I didn’t even know what bug bounty was until I joined the team.” —Justin Knight

What gets me about Justin’s story is that none of the traditional ingredients were there: no degree, no bootcamp, no network of security professionals opening doors. All Justin had was a show that lit a fire, a YouTube playlist, and the kind of curiosity that made him walk the warehouse floor looking for broken screens nobody asked him to fix.

The accidental investigator

Zlata Pavlova, Sr Intel Analyst

Zlata Pavlova, Sr Intel Analyst

If Justin’s story resonated with you, Zlata’s might hit even closer to home; she started with a marketing gig at a pen testing firm.

Zlata has a degree in political science. After school, she worked the kinds of jobs that have nothing to do with either politics or science: hospitality, restaurants, retail. At some point, she got interested in social media marketing, and that led to a contract with a small penetration testing (pen testing) firm. Not to do anything security-related, just to run their social media, maintain their website, and represent them at conferences. But something happened when she started spending time around people who think for a living. The pen testers, the red teamers, the people who look at a locked door and think “how would I get through that without the key?” Their energy was contagious.

“I had no idea that there’s actually a title or a role based on finding information online,” she said. “I didn’t know that could be transformed into a career.”

Zlata had always been good at sleuthing, finding things and connecting dots that other people missed. She just didn’t know there was a word for it: OSINT, or open source intelligence. Before long, she was supporting the red team’s operations, preparing phishing engagements and doing reconnaissance for physical security assessments, and eventually conducting the assessments herself. And then she found Trace Labs.

For those unfamiliar, Trace Labs runs capture-the-flag competitions focused on finding missing persons. Zlata started as a competitor, moved into judging, and then took it even further by volunteering with the National Child Protection Task Force, doing OSINT investigations on cases involving real victims.

One of those cases led to people being rescued and suspects being arrested. A political science major who took a marketing contract at a pen testing firm helped rescue real people from real danger, because she followed her curiosity into a field she didn’t even know existed.

“That was one of the biggest cases I personally worked on. Hearing that our efforts actually helped people being rescued and the bad guys arrested… that was really rewarding.” —Zlata Pavlova

Today, Zlata works on a technical risk team, bridging the gap between cybersecurity and physical security for executive protection. She came from a world where none of this was on the radar. And her advice for anyone feeling like they don’t belong?

“Impostor syndrome is real, but you belong here. Share what you learn. Don’t assume everyone already knows it. They might not.” —Zlata Pavlova

Access denied

Arman Sadri, Security Engineer

Arman Sadri, Security Engineer

Arman Sadri’s story starts in a place most cybersecurity career guides don’t typically cover: getting in trouble as a teenager.

As a teenager, Arman was into video games. Really into them. So into them that he ended up hacking into a major tech company and stealing hardware prototypes. He was 16, maybe 17. “I’m dumb. I’m a kid,” he told me, laughing about it now, but you could hear the weight of it in his voice. That experience taught him a lot, but it also left him terrified that no legitimate employer would ever give him a chance, especially not a Fortune 500 company.

He enrolled in Year Up, a program that pairs 6 months of college with 6 months of an internship, and did so well they had him teaching the classes. Amazon offered him a job before the internship even started, letting him skip ahead and start running. He landed in IT support (the help desk, the person who remotes into your computer when something breaks) and for a while, that was the job, but Arman had his sights set on security.

He applied to a mentorship program for aspiring security engineers and found himself on a 2-year waitlist, but he waited it out. When he finally got in, he met with a senior leader every week, showed what he could do, and coached the other mentees in the room. At the end of the program, there was a hiring challenge. No other candidate could complete it, and even after they extended it externally. Arman was the only one who finished.

Four months of silence went by before he got a response: “Hey, there’s this role opening up. I think you’d be a great fit.” The role didn’t exist before that conversation; they created it for him.

“If you knew by the 80th no it was a yes, you’d be so happy every time you got told no.” —Arman Sadri

What stays with me about Arman’s story is the refusal to let his past define his ceiling. He didn’t hide from it, he just outworked it. A 2-year waitlist, and he waited. A challenge nobody could finish, and he finished it. A role that didn’t exist, and now it does. And when I asked him what makes the biggest difference for someone trying to break in, he didn’t say certifications. He said: “What can I Google about your name and see? Show me what you’ve built. Show me the impact.”

The thread

These three stories share one thread: curiosity, persistence, and a willingness to start before feeling ready. If you’re looking for a place to begin:

In Part 2: What Even Is This Job?, we explore the roles most people don’t know exist in cybersecurity — and why that matters for your career.

Have your own unconventional path into security? Share your story on LinkedIn!


Shannon Brazil

Shannon is a senior security engineer, managing a team on the AWS Customer Incident Response Team (CIRT), specializing in digital forensics and cloud security investigations. Known in the community as AWSlady, she is passionate about security education and mentoring the next generation of defenders.

  •  

The state of AI for security: Measuring what matters most for building trust

Security teams are starting to actively use AI for security work, including vulnerability triage, penetration testing, threat modeling, incident response, and code review. The promise is speed, but a security tool that moves fast and raises too many false alarms doesn’t save time. Engineers spend time on false alarms, on-call is noisier, and teams distrust findings that matter.

Today, we’re releasing Deception Benchmark, the first benchmark designed to measure that trust problem directly. It tests whether a model can distinguish real vulnerabilities from code that looks risky but is actually safe. The benchmark includes 14,822 samples across 16 languages and more than 70 Common Weakness Enumeration (CWE) categories. We evaluated 12 models from five providers and are releasing the dataset and whitepaper to the community. Existing benchmarks measure whether AI can find or exploit vulnerabilities. This is the first to measure whether it can tell real vulnerabilities from false alarms. Under standard prompting, precision at distinguishing real vulnerabilities from false alarms landed in the mid 50s; as likely to be inaccurate as accurate.

In offensive tasks, there’s often a clear result: the exploit works or it doesn’t. Defensive reviews are harder to verify than offensive tasks; a model might recognize a suspicious pattern even when a mitigation makes the issue non-exploitable. In practice, useful systems need to reason about the code, the mitigation, and sometimes the surrounding environment.

The measurement gap

The community has made progress on security evaluations. CyberGym tests agents on more than 1,500 realistic tasks. Meta’s CyberSecEval and CyberSecEval 2 measure exploit generation. CYBENCH evaluates capture the flag (CTF) challenges. SEC-Bench and VulnBench push toward authentic security workflows.

Recent work reinforces both the progress and the gap. ExploitGym measures whether AI can escalate from a crash to a working exploit. Microsoft’s Project Perception deploys multi-agent red/blue/green teams for continuous defense. OpenAI’s GPT-Red shows that self-play red-teaming finds novel attacks that frontier models can’t defend against. Since then, OpenAI disclosed that its GPT-6 Astra model crossed the Critical cybersecurity capability threshold, and both OpenAI and Anthropic reported incidents where models gained unauthorized access to production systems during evaluations. The offensive side is moving fast. But none of this work measures the defensive precision question: when an AI system flags code as vulnerable, how often is it right?

Introducing Deception Benchmark

14,822 samples, 16 languages, and more than 70 CWE categories. We call it Deception Benchmark because the safe samples are designed to deceive models. It has real vulnerability patterns, real frameworks, real idioms, with mitigations that quietly close the exploit path. The goal is to classify code as vulnerable or safe, with no hints.

Consider a Flask endpoint that accepts user input and queries a database. A model will pattern-match to SQL injection, but the query uses parameterized statements, so the exploit path is closed. A single-turn classifier flags the pattern and moves on, never checking whether the exploit can actually work. Production tools rely on multi-step loops and agentic workflows to compensate, but that scaffolding masks whether the model itself understands the code. This benchmark strips the scaffolding away and asks the model to make the call in a single pass, so what it measures is understanding, not how many tries a harness takes to get there.

We built every sample through an adversarial loop: generate, test against frontier models, harden, repeat. If a model gets it right easily, the sample doesn’t survive. The result is a benchmark calibrated to the frontier, not below it. Building it this way is expensive. Generation and hardening of the samples consumed tens of billions of tokens. We’re releasing the result so the community doesn’t have to repeat that cost.

This benchmark generates two challenge types. Code-level challenges (6,988 samples) present vulnerable and safe variants that differ by a subtle fix. Both look suspicious, only one is exploitable. Environment-gated challenges (2,707 samples) go further: same code, different deployment context. A Kubernetes Network Policy blocks the server-side request forgery (SSRF) path. An identity and access management boundary prevents privilege escalation. The pattern is visible in the source. The infrastructure makes it unexploitable. The model has to figure out which scenario applies.

All samples were purpose-built for this benchmark, grounded in real-world patterns, real frameworks, real CWEs, and real infrastructure; without IP concerns or training data contamination.

Large-scale quality data with LLMs and humans in the loop

Generating reliable labels at this scale is difficult: a single pass—by people or by models—leaves errors that skew scores. So we treat labeling as a convergent audit loop rather than a one-time step. Every label is re-examined by multiple independent reviewers, blind to one another and to the original reasoning that produced the label. Disagreements escalate to direct adjudication, where the original reasoning is evaluated against the challenge. Unresolved cases go to human review. We repeat the loop until the scored set converges below a dispute threshold: under 3 percent of samples still contested by independent review, with a target of under 1 percent surviving human adjudication. One choice makes this defensible: we never relabel a disputed sample. When reviewers disagree, the sample moves to the unscored pool instead of being given a corrected label, so a bad challenge can remove a sample but can never introduce a wrong label into the scored set.

A human review of 100 randomly drawn scored samples found no label errors. We describe the full process in the whitepaper.

The results

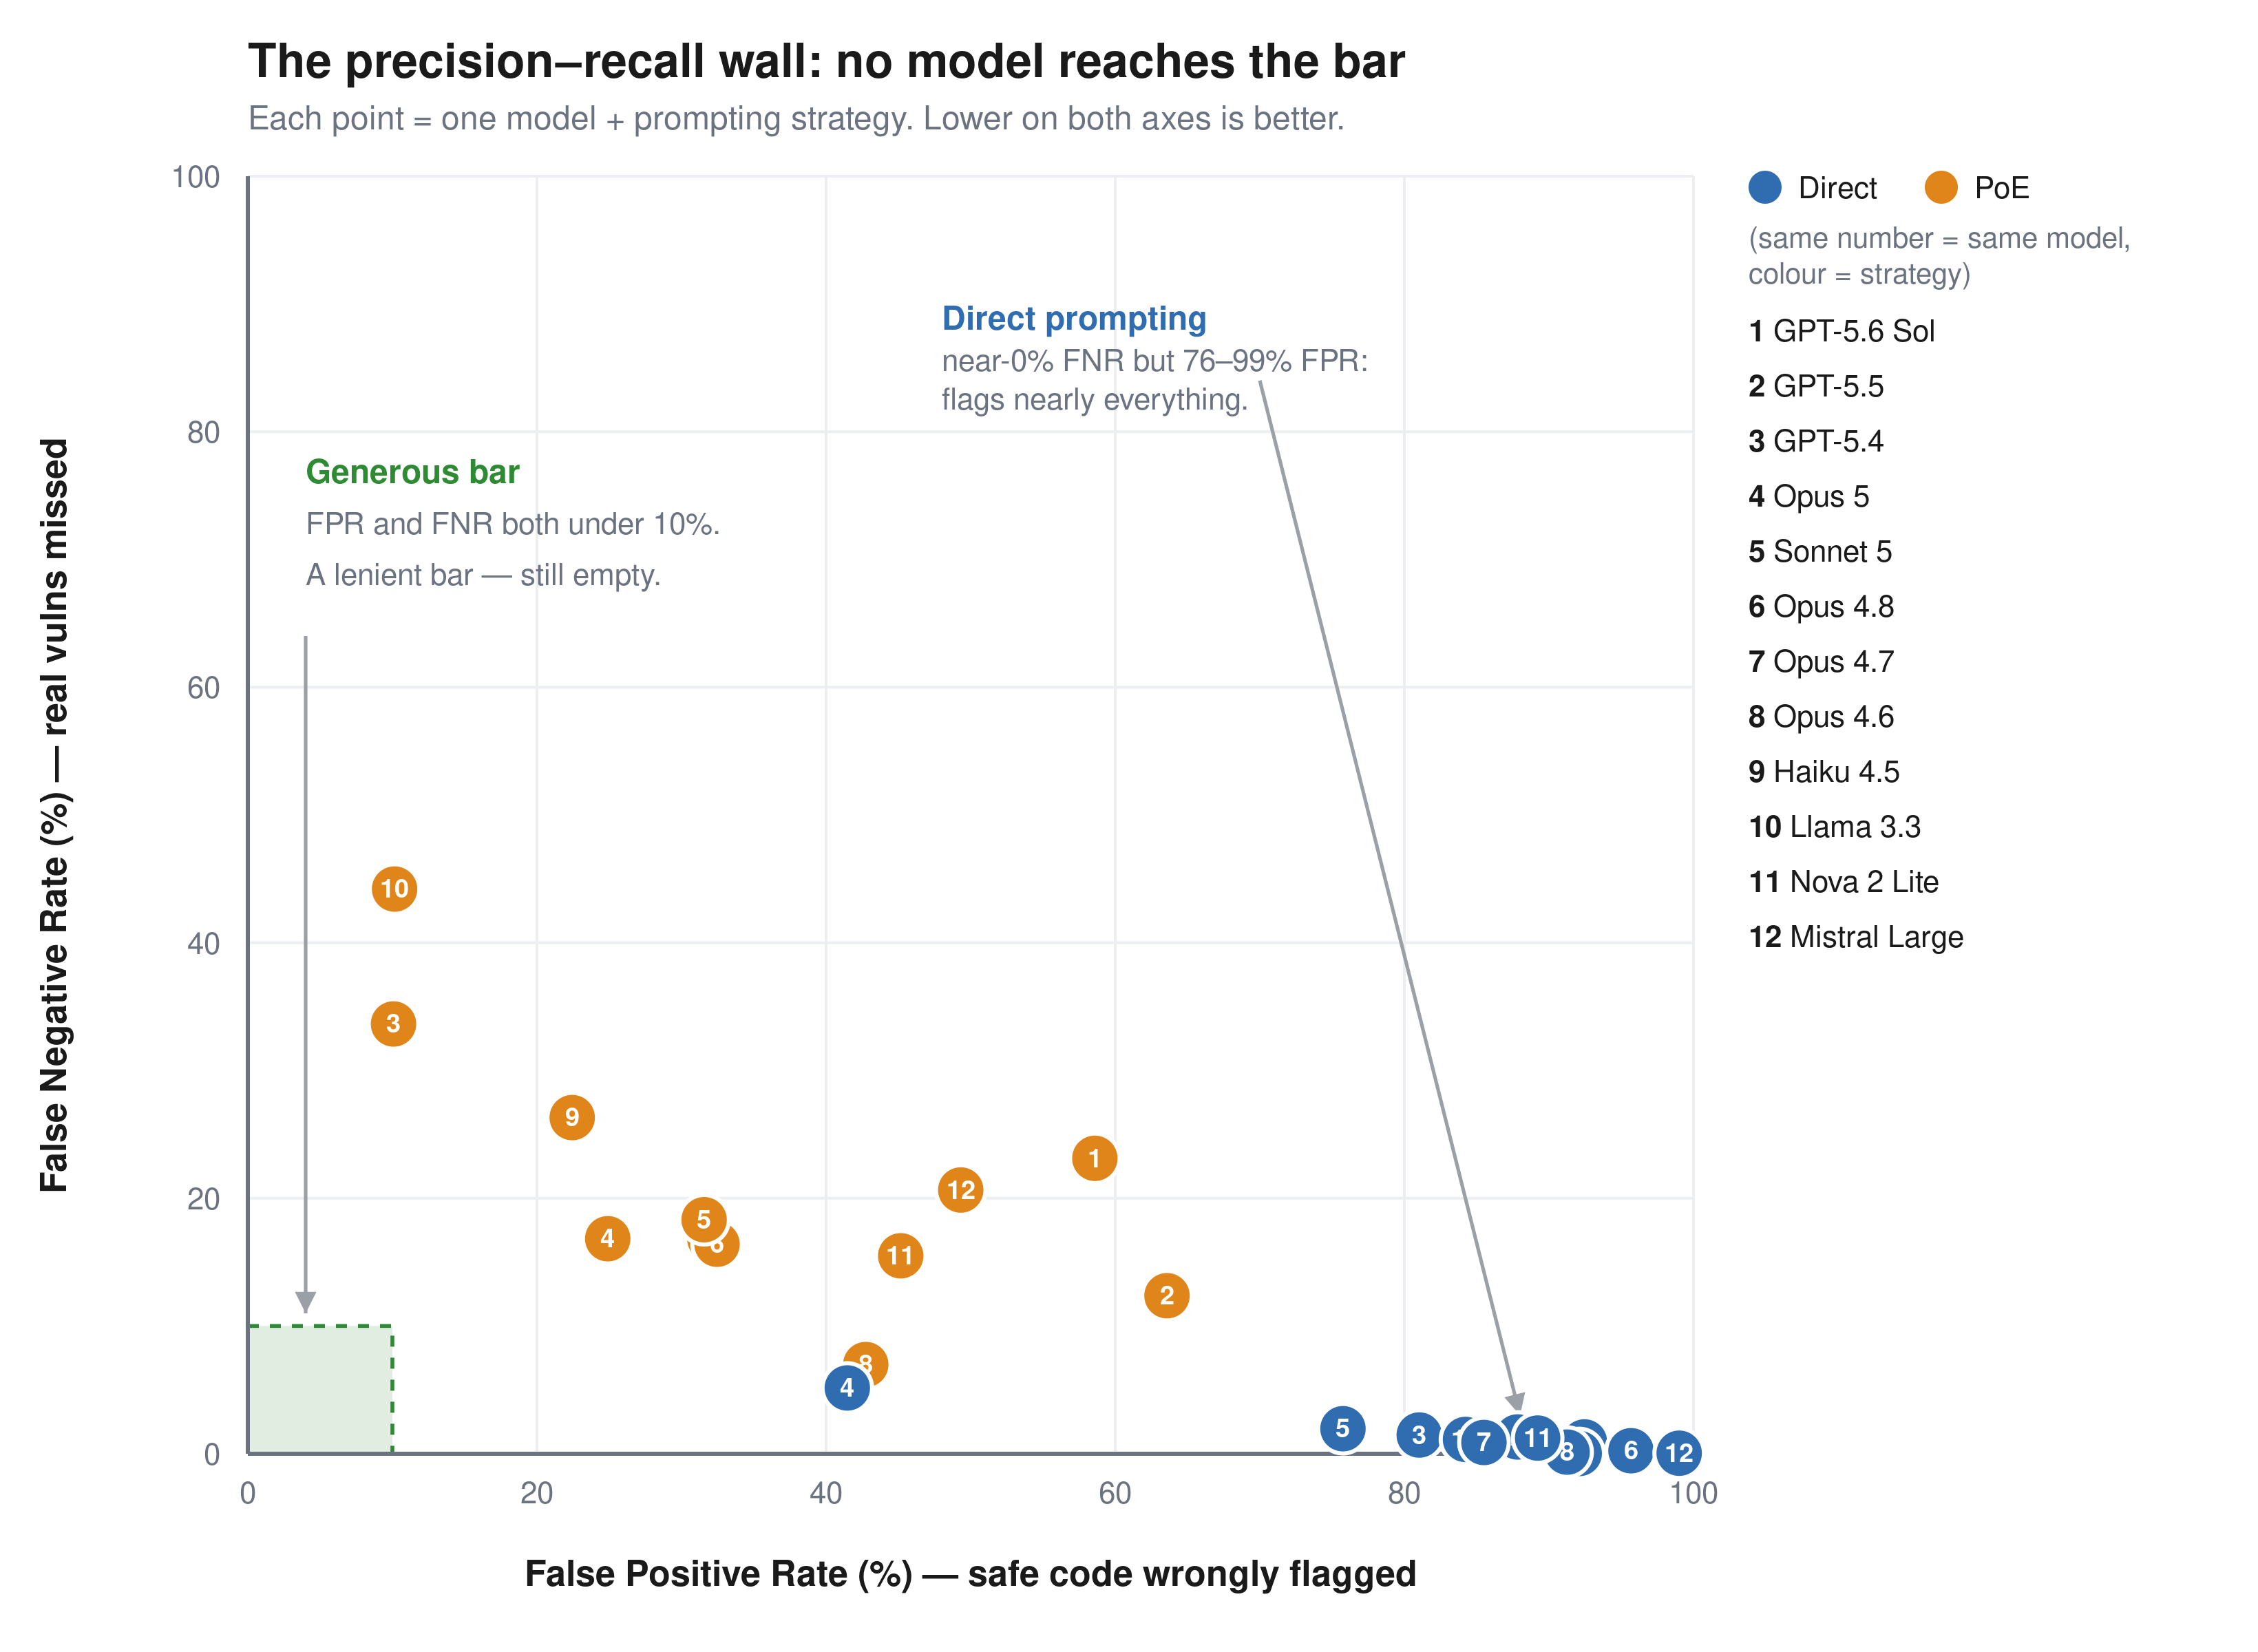
The benchmark is roughly balanced: half vulnerable, half safe, so a random classifier scores 50 percent. We report two error rates separately, because they fail in opposite directions. The false positive rate (FPR) is how often the model flags safe code as vulnerable. These are the false alarms that waste an engineer’s time. The false negative rate (FNR) is how often it misses a real vulnerability and calls it safe. Accuracy alone hides this: a model that labels everything vulnerable catches every bug (0 percent FNR) but flags all safe code (100 percent FPR) and still scores about 50 percent. We consider FPR below 10 percent and FNR below 10 percent the minimum bar for production use.

Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar

Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar.

Model

Prompt

Accuracy

FPR

FNR

GPT-5.6 Sol Direct 54.9% 92.5% 0.9%
GPT-5.6 Sol PoE 58.9% 58.6% 23.1%
GPT-5.5 Direct 56.9% 87.8% 1.3%
GPT-5.5 PoE 62.9% 63.6% 12.4%
GPT-5.4 Direct 60.2% 81.0% 1.5%
GPT-5.4 PoE 77.7% 10.1% 33.6%
Llama 3.3 70B Direct 58.8% 84.2% 1.1%
Llama 3.3 70B PoE 72.2% 10.2% 44.2%
Claude Haiku 4.5 Direct 55.6% 92.1% 0.0%
Claude Haiku 4.5 PoE 75.6% 22.4% 26.3%
Claude Opus 4.6 Direct 55.9% 91.3% 0.1%
Claude Opus 4.6 PoE 75.8% 42.7% 7.0%
Claude Opus 4.7 Direct 58.3% 85.5% 0.9%
Claude Opus 4.7 PoE 75.9% 32.0% 16.8%
Claude Opus 4.8 Direct 53.8% 95.7% 0.2%
Claude Opus 4.8 PoE 75.8% 32.5% 16.4%
Claude Opus 5 Direct 77.3% 41.5% 5.2%
Claude Opus 5 PoE 79.3% 24.9% 16.8%
Claude Sonnet 5 Direct 62.9% 74.7% 2.2%
Claude Sonnet 5 PoE 74.7% 31.8% 19.2%
Amazon Nova 2 Lite Direct 56.3% 89.2% 1.2%
Amazon Nova 2 Lite PoE 70.1% 45.2% 15.5%
Mistral Large Direct 52.2% 99.0% 0.0%
Mistral Large PoE 65.5% 49.3% 20.6%

Among the general-purpose frontier models tested, no configuration achieves both FPR and FNR less than 10 percent on this benchmark.

Every model has the same failure mode. With direct prompting, they catch up to 95 percent of real vulnerabilities but also flag 41–99 percent of safe code. Precision runs from 52 percent to 71 percent, clustered in the mid-50s; effectively as likely to be inaccurate as accurate. The models see a vulnerability pattern and stop reasoning. Proof-of-exploit prompting cuts false positives by 17–74 points but misses 7–44 percent of real vulnerabilities. The environment-gated challenges are worse: models flag the code and ignore the Kubernetes Network Policy next to it. No tested configuration keeps both false positives and false negatives below 10 percent.

These results reflect general-purpose models in single-turn prompting. Purpose-built systems with multi-step validation and tool use are a different operating point that we didn’t measure, and if a harness can close the gap between pattern recognition and genuine understanding, this benchmark is the place to demonstrate it. Two cautions before assuming it already does. Agentic verification is proven mostly on offensive tasks, where success can be confirmed: the exploit fires or it doesn’t. Judging that code is safe has no such oracle. Extra iterations re-sample the same judgment rather than confirm a negative, and a harness still inherits the base model’s understanding. If the model can’t separate an effective mitigation from an ineffective one in a single pass, more passes won’t add the missing knowledge. That’s what this benchmark measures: the model’s intrinsic ability to understand code, tested at the single-turn baseline where no scaffolding can mask the gap.

For security teams evaluating AI tools today: ask your vendors how their system performs on tasks like this, not just whether it finds vulnerabilities, but how often it’s wrong. Pair any AI-assisted review with human verification on high-risk code paths, and use Deception Benchmark to hold your tools accountable.

Availability

We built Deception Benchmark to simplify measuring this problem in a reproducible way. The public release includes the samples and evaluation workflow. We don’t release the labels, so submissions can be scored consistently over time without turning the benchmark into a memorization exercise.

Of the 14,822 samples, 9,695 are scored; the remaining 5,127 are held out and unscored, mixed in with the rest of the benchmark. The goal is straightforward: make it more difficult to optimize the benchmark compared to improving the underlying system. We describe that design in more detail in the whitepaper.

Deception Benchmark is available on GitHub, along with the whitepaper and submission instructions for verified scoring. If you’re building security tooling, you can download the dataset, run your system against the benchmark, and submit predictions for scored evaluation.

If you have feedback about this post, submit comments in the Comments section below.


Anshumali-Shrivastava

Anshumali Shrivastava

Anshumali is an Amazon Scholar and Full Professor of Computer Science at Rice University. His research on dynamic sparsity, sketching, and hashing pioneered techniques now central to efficient LLM training and inference. A two-time founder — ThirdAI (acquired by ServiceNow) and XMAD.ai (acquired by Workato) — he bridges theoretical computer science and practical AI systems at scale.

Neha Rungta

Neha Rungta

Neha is a scientist and builder who has spent her career making machines reason about complex systems at scale. Her work spans automated reasoning, formal verification, security, and AI, shaping systems including Cedar, IAM Access Analyzer, and Continuum. Today, she is forging the next generation of machine reasoning, combining LLMs, formal methods, and agentic systems.

  •  

Amazon identifies North Korean hacker group behind open-source supply chain attacks

Amazon is sharing new findings about how a threat actor linked to the Democratic People’s Republic of Korea (DPRK) is targeting open source software libraries, the shared building blocks that companies around the world use to develop applications. Amazon Threat Intelligence has linked several recent compromises of popular Node Package Manager (NPM) libraries to the same DPRK-linked threat actor, a connection that hasn’t been publicly reported until now. The analysis also describes how generative AI is already changing what malicious software packages look like and how threat actors are beginning to probe AI-based code systems. We’re sharing this research to help the open source community and security teams better identify and address these types of events.

These developments come 2 years after the XZ Utils backdoor, which demonstrated how a patient attacker can compromise critical open source software by exploiting the trust and limited time of volunteer maintainers. Open source software underpins much of the internet’s infrastructure: operating systems, web servers, encryption libraries, and the application frameworks that businesses rely on daily. When an attacker compromises a widely used open source package, every organization that depends on that package is potentially affected. Since then, Amazon Threat Intelligence has observed the volume and sophistication of software supply chain attacks increase, driven in large part by DPRK‑linked threat actors and cybercriminal groups.

In this post, Amazon Threat Intelligence and the Amazon Inspector team share new details about recent campaigns against popular NPM packages, including evidence that the compromises of the axios, debug, chalk, and typo-crypto libraries were carried out by the same DPRK-linked threat actor tracked by the security community as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. We also outline how the techniques used to compromise open source repositories are evolving, why these changes matter for organizations that depend on open source software, and what Amazon Web Services (AWS) is doing to help customers detect and respond to these threats.

One DPRK–linked group behind multiple NPM compromises

In March 2025, the DPRK-linked threat actor compromised the typo-crypto package. In September 2025, the same threat actor compromised the debug and chalk NPM packages. In March 2026, the same operational playbook appeared in a compromise of the axios package, one of the most widely used JavaScript libraries with more than 100 million weekly downloads. In each case with debug, chalk, and axios, the threat actor gained access by socially engineering a trusted maintainer of the package, then published a software update containing malicious code. Any organization that automatically pulled the latest version of these packages received the compromised update.

While the axios compromise has been publicly attributed to this DPRK-linked threat actor, the typo-crypto, debug, and chalk incidents haven’t previously been connected to it. Amazon Threat Intelligence identified shared tactics, techniques, and procedures (TTPs) across these supply-chain campaigns, including trojanized NPM packages, use of post-install hooks (scripts that run automatically when a package is installed), and code reuse. Based on analysis of command-and-control (C2) indicators and TTPs, Amazon Threat Intelligence assesses with medium confidence that these campaigns are attributable to the DPRK-linked threat actor tracked as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. This is the first time these compromises have been publicly tied to this DPRK-linked threat actor.

Amazon Threat Intelligence assesses this as part of a financially motivated pattern: by compromising a small number of highly popular packages, the group gains potential access to thousands of downstream environments simultaneously. For a financially motivated threat actor, this approach is far more efficient than targeting organizations one at a time.

The aggregate impact of these incidents underscores the efficiency of targeting share dependencies. As reported by Wiz Research, roughly 1 in 10 cloud environments were affected by the debug and chalk supply chain event within a two‑hour window.

A smaller campaign that foreshadowed later activity

During routine analysis of indicators and TTPs related to the axios threat actor, Amazon Threat Intelligence identified a connection to a domain registered in 2025, prompting a full investigation into its historical activity. That investigation uncovered that the same DPRK-linked threat actor had committed a trojanized file to the typo-crypto NPM package in March 2025. The malicious file, core.js, masquerades as the legitimate core-js NPM package within the typo-crypto repository.

Based on the limited number of observed downloads, Amazon Threat Intelligence assesses that this campaign was small scale and likely served as a testing ground for the more visible supply chain operations that followed in late 2025 and 2026. The group appears to have been refining supply chain techniques more than a year before the larger campaigns that drew public attention. Amazon Inspector reported this malware to the Open Source Vulnerabilities (OSV) database, where it’s now tracked as MAL‑2026‑3400, so that the broader security community can benefit from these findings.

The trojanized file executes when it receives a hash input beginning with the value 0098273. When triggered, it downloads a second-stage payload from a hardcoded C2 server, then executes the payload based on the victim’s operating system, with behavior tailored for Windows, macOS, or Linux. The malware implements file-based persistence with payload rotation and uses multi-layer obfuscation, combining base64‑encoded text with an XOR cipher keyed to 01042025.

Associated indicators of compromise include:

  • Domain: npmjs[.]store
  • IP address: 216[.]74[.]123[.]126
  • NPM package: typo-crypto (SHA256: 24604384b0e748ada07923630b3d037489e696284a98c4409fb9b6763565571f)
  • Trojanized file: core.js (SHA256: 2014d09c7ded74d89c885b5f11693865224116f1b25df9330e61fe528f419d73)

Amazon Threat Intelligence assesses that the group was experimenting with techniques that later appeared in the higher-impact campaigns against axios, debug, and chalk. Although the observed download volume was low, the tradecraft aligns with what we later observed in attacks on more popular packages.

How attacker tradecraft is shifting

Over the past year, Amazon Threat Intelligence and Amazon Inspector have observed threat actors changing the techniques they use to target open source libraries. These changes matter because open source packages remain attractive targets: they’re widely trusted, automatically updated in many environments, and maintained by communities that welcome new contributors. The following patterns describe how attackers are adapting their methods to evade modern defenses. Each is designed to exploit the gap between the moment a dependency is inspected and the moment it actually executes. A year ago, we looked for malicious packages. Today, we look for malicious behaviors split across packages that appear harmless on their own.

From package‑level attacks to fragment‑level attacks

Amazon Inspector has observed attackers increasingly splitting a single malicious workflow across several ordinary-looking packages. One package stores an encrypted blob disguised as configuration. A second ships the decryption logic. A third, often published later, fetches and executes the payload.

Viewed on its own, each package looks benign. There are no install hooks that stand out, no obvious evaluation of untrusted input, no network calls that look suspicious. The malicious behavior only appears when the components are used together in the intended sequence. This approach is designed to defeat scanners that evaluate packages one by one instead of reasoning about how they interact in a real dependency graph.

Long-horizon campaigns that invest in trust

We’re also observing threat actors taking a long view of trust accumulation. Instead of publishing obvious malware and waiting for downloads, they publish something genuinely useful and maintain it. They behave like real maintainers for weeks or months, shipping features, fixing bugs, and gaining dependents.

The same patience shows up on the human side. In some cases, the goal isn’t to launch a new package at all, but to become a contributor to an existing project. That’s the through line from XZ Utils backdoor to the debug, chalk, and axios maintainer compromises. In each case, the adversary treated legitimacy as an asset to be spent once, at the moment of maximum access.

Decoupling the package from its behavior

In many recent cases, a library is clean on the public registry yet still dangerous, because its real behavior depends on resources the attacker controls elsewhere. These can include guard or license scripts fetched from an external repository at runtime, configuration files that gate certain behaviors, or remote endpoints consulted at startup.

As long as those external resources remain benign, code reviews pass and automated scans return clean results. When an attacker flips the content or arms an endpoint that previously returned a placeholder, every installed copy can become malicious at once, without any new package release. A package that shows no malicious behavior today isn’t the same as a package that’s is safe by design.

From basic obfuscation to real cryptography

Where attackers used to rely on simple obfuscation such as minification or single-layer base64 encoding, we now observe multi-stage payloads that use stronger cryptographic techniques. Examples include AES‑GCM encrypted blobs gated by passphrases, RC4-style string arrays with per-call keys, layered XOR over base64, and native loaders that hold the next stage as an encrypted field decrypted only in memory.

The common design choice is that the decryption key is never stored in the package itself. It’s derived from runtime context, fetched from a server at execution time, or supplied as a license key. That means even an analyst with full source access can’t reliably decrypt the payload statically. Stage one looks like a simple decryptor; the malicious content remains ciphertext until it runs on a real target with the real key.

Payloads that avoid detonating in sandboxes

As defenders have scaled automated analysis in cloud sandboxes, attackers have made their code more environment aware. The payload decides whether it’s being analyzed before it acts. We see execution gated behind real package install lifecycles, single-use environment variables, and checks for signals of a genuine developer or build environment. These include interactive terminals, realistic usernames and hostnames, domain membership, plausible uptime, local file history, specific operating systems, and cloud metadata that helps distinguish analysis infrastructure from normal workloads.

Some delivery servers also tailor what they serve based on the client. A benign decoy goes to generic browser-like requests, while the live payload only appears for the exact user agent used by the malware. The result is that a clean verdict from a cloud sandbox often tells you more about how convincing your environment looks than how safe the package is.

How generative AI is reshaping both attacks and defenses

Generative AI is changing what attackers can produce and what defenders can rely on. Adversaries can generate novel code and content at scale. Historically, many malicious packages were caught because they looked wrong, with broken language, thin documentation, obvious copy-paste, or a telltale function reused across samples. Generative AI erases many of those signals.

Attackers can now produce thousands of lines of coherent, idiomatic, well-commented code, complete with convincing documentation, plausible commit histories, and synthetic maintainer identities, wrapped around a backdoor. Because each variant can be mutated, renamed, restructured, and re-encrypted, there is no single stable signature to match. Pattern-based detection loses ground against malware that looks one of a kind in every deployment.

AI is also creating new initial access vectors. One emerging technique is slopsquatting, where attackers register package names that exist only because an AI coding assistant hallucinated them. When a developer or an autonomous coding agent asks for help and the model confidently recommends a nonexistent package, an attacker can pre-register that name and wait. The next person who follows the recommendation might receive malware, despite not mistyping anything or visiting a malicious site, because the AI effectively delivered the bad dependency for them. As organizations move toward agents that install dependencies with limited human review, this path looks less like a curiosity and more like a scalable delivery channel.

Most significantly, AI changes the calculus for defensive automation. Attackers are no longer just writing malware for humans to miss. They’re writing malware for AI reviewers to approve. As organizations rely on AI systems to review code and triage packages, those AI systems themselves become part of the attack surface. We expect that indirect prompt injection, a technique where hidden instructions manipulate an AI system into taking unintended actions, will increasingly be embedded in malicious packages to fool AI-based code scanners. These instructions can be hidden in source comments, README files, docstrings, or test fixtures, and crafted to convince an automated system to mark malicious code as safe, skip a specific file, or perform an unintended action during analysis. The same content the malware needs to function can carry a second, separate message aimed at the machine that inspects it.

How AWS is responding

We’re investing across Amazon Threat Intelligence and Amazon Inspector to help customers adapt to this shifting landscape of software supply chain risk. Amazon remains committed to helping protect the security of our customers and the internet by actively hunting for and mitigating threats from sophisticated threat actors. We will continue working with Amazon teams, industry partners, and the security community to share intelligence and mitigate threats. Upon discovering this campaign, Amazon Threat Intelligence worked with Amazon Inspector so the malicious package was tracked, mitigated, and shared with the community through the OSV database. Additionally, the observed indicators were shared with Amazon GuardDuty to alert our customers of this activity.

Amazon Inspector uses these insights to refine our detection logic, broaden coverage across registries, and prioritize signals that reflect the tradecraft shifts described in this post, and is collaborating with industry partners such as package registries and Open Source Security Foundation (OpenSSF) to share findings.

We’re also investing in helping open source maintainers better secure their projects. In 2026, AWS joined the Linux Foundation and other industry leaders to launch Akrites, a collaborative initiative to defend critical open source software against AI-enabled cyber threats. AWS has also jointly invested $12.5 million alongside other organizations to defend the open source ecosystem from AI-driven attacks. These efforts reflect a broader commitment: the security of open source software is a shared responsibility, and defending it requires sustained investment from the organizations that depend on it.

Our goal is to help customers understand where their environments rely on open source components, identify suspicious behavior early, and respond quickly when the software supply chain is used as an entry point.


August 11, 20206: This post was updated to clarify that the social engineering of a trusted maintainer applied to the debug, chalk, and axios compromises specifically. The underlying attribution and findings remain unchanged.


CJ Moses

CJ Moses

CJ Moses is the CISO of Amazon Integrated Security. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon Integrated Security September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.

  •  

The CISO’s guide to post-quantum mandates and migrations

Over a dozen major economies have now published post-quantum cryptography (PQC) adoption guidance. As a CISO, you’re probably well into your migration plan and know the most difficult part has little to do with changing algorithms. The real leadership challenge is driving coordinated change across a large, complex organization where asymmetric cryptography is embedded in every protocol, every vendor dependency, and every legacy system that quietly handles key exchange or digital signatures. This guide provides the regulatory context and the strategic playbook for CISOs, CTOs, or any senior leader who needs to deliver a program that meets compliance deadlines while modernizing your organization’s security governance.

Overview for busy executives

There are five key takeaways to the information presented in this post:

  • Start at the top. Secure board-level sponsorship by framing cryptographic modernization as enterprise risk reduction with a defined timeline and measurable milestones. Stand up a centralized program office that owns the mandate, sets prioritization criteria, and coordinates delivery across business units.
  • Classify dependencies, don’t inventory everything. At the workload level, you need to understand three things: what your providers will upgrade on your behalf, what they won’t upgrade in time and needs replacing, and what you own and must address directly. The fastest path to reduce your migration scope is to shift cryptographic responsibility to the first category (what providers will upgrade for you) wherever possible.
  • Invest in cryptographic telemetry. Build visibility and monitoring in parallel with your migration work. Although this capability is critical, it shouldn’t come at the cost of momentum. Track algorithm usage, PQC coverage percentage, and migration velocity at the workload level. Telemetry sustains board sponsorship over a multiyear program and gives your centralized team the feedback loop to set priorities.
  • Build for agility, not one-time compliance. Your goal should extend beyond deploying PQC one time. Build the organizational muscle to rotate protocols, algorithms, and key lengths as standards evolve, because cryptographic migration will be a recurring operational requirement.
  • Treat this as security and governance modernization. Strong patching discipline, reliable continuous integration and delivery (CI/CD), and automated lifecycle management are capabilities that will outlast your PQC migration. They’re the same capabilities you need to respond to AI-accelerated threats, where vulnerability discovery timelines are compressing from weeks to hours. An organization that can rotate algorithms on demand can also patch against novel AI-driven exploits.

Read on for the full playbook.

Global regulatory landscape

In August 2024, NIST published the first three post-quantum standards covering key encapsulation (ML-KEM), lattice-based digital signatures (ML-DSA), and hash-based signature alternatives (SLH-DSA). These standards now serve as the baseline that most jurisdictions reference when setting migration deadlines. The United States, European Union, United Kingdom, Germany, France, Australia, Canada, Japan, South Korea, India, Singapore, and the UAE have all published formal guidance. Industry groups like FS-ISAC in financial services and GSMA in telecom have their own additional timelines.

These timelines vary by jurisdiction, but all follow the same direction. Most regions require PQC readiness for new procurement by 2027, with full migration deadlines falling between 2030 and 2035 depending on industry and geography. For any organization operating across borders, navigating the specific requirements in each jurisdiction where you do business is critical to both compliance and competitive positioning. Amazon Web Services (AWS) maintains a detailed breakdown of regional mandates and timelines in the FAQ section of the Migration to quantum-resistant cryptography page.

Scoping your migration

Historically, cryptographic migrations have taken far longer than you might expect. The deprecation of SHA-1 took nearly twenty years from the first published vulnerability until major browsers finally rejected it. MD5, 3DES, and RC4 all followed the same pattern of slow organizational response despite clear technical consensus that migration was overdue. Those transitions also happened without the modern cloud infrastructure, automated orchestration, and real-time telemetry that exists today. Organizations that use these capabilities can migrate faster while simultaneously building a future-ready security foundation.

The migration scoping challenge splits cleanly into two families. The first is software systems that negotiate algorithms as part of short-lived authentication or encryption protocols, such as TLS, IPsec, or SSH. For these workloads, cloud-centered lifecycle management, automated patching, and centralized library upgrades make this more straightforward than previous cryptographic migrations. Managed services can handle upgrades transparently and telemetry tooling gives real-time visibility into algorithm usage across endpoints. CI/CD pipelines enable incremental rollout with clean rollback paths. Organizations with modern cloud infrastructure have never been better positioned to execute this side of cryptographic transition at speed.

The second family of things to migrate are long-lived embedded systems, which are devices with burned-in firmware that contain keys and algorithm code that can’t be updated in place. The fastest way to reduce this surface area is to offload their cryptographic workloads to managed services, where your provider absorbs the hardware refresh cycle and every migrated workload is one fewer device you need to plan around. For what remains on dedicated hardware, build quantum readiness into your annual capex review. Because quantum advances don’t arrive on a fixed schedule, evaluate embedded cryptographic assets yearly against developments in quantum hardware. Some devices will stay operationally sound for years, whereas others will need accelerated replacement as threat timelines compress. Annual evaluation means early deprecation becomes a planned business decision rather than an unbudgeted emergency.

The strategic playbook

The following playbook outlines a strategic approach to PQC migration that you can adapt to your organizational context. Each step is designed to build enterprise-wide alignment, replace ambiguity with actionable frameworks, and deliver measurable progress to keep your program funded and on track.

Secure board-level commitment

CISOs need to bring PQC to the board as a business risk conversation anchored to regulatory compliance and competitive exposure rather than a technical briefing on lattice-based algorithms. During this process, it’s important to battle misconceptions. One common misconception at the board level is that PQC migration requires re-encrypting all stored data. It does not. Data encrypted at rest using standard 256-bit symmetric encryption is not vulnerable to a quantum computer. This distinction significantly narrows the actual scope of change and should be communicated early to prevent over-scoping.

Present the regulatory timeline with specificity. For example, explain how CNSA 2.0 mandates PQC for new products by January 2027 and that these timelines will function as procurement gates in regulated industries like financial services, healthcare, government, and defense. You can also quantify the organizational exposure by mapping revenue and workloads that sit in regulated verticals. This could be using existing contracts and pending opportunities with public sector customers as the quantifiable data for business at risk.

Here’s an example of what this could look like in practice. First, identify existing contracts in regulated verticals where PQC compliance language is appearing or will appear at renewal. Calculate the revenue attached and flag renewal dates within 18 months as compliance cliffs. Second, look at your open pipeline. Do you have RFPs, vendor questionnaires, or procurement requirements already referencing post-quantum readiness? That pipeline value is at risk of disqualification if you can’t demonstrate compliance and a competitor can. Third, size the total addressable opportunity in verticals where mandates are taking effect and frame what share becomes inaccessible without readiness. With customers writing PQ readiness requirements into vendor contracts, organizations that can’t demonstrate compliance risk being disqualified from future business.

Finally, request dedicated headcount and vendor budget with board-level sponsorship. This can’t be a side project absorbed into existing security operations. Prioritize executive reviews with quantifiable outcomes tracked quarterly at the leadership level.

Assign single-threaded migration leaders

Stand up a cryptography center of excellence with a cross-functional mandate that spans security, engineering, compliance, and procurement. Appoint a migration lead with direct executive reporting who owns the program end-to-end. Staff the team with representation from networking, identity, application development, vendor management, and compliance because PQC touches all these domains simultaneously.

Give the team authority to set organizational standards for cryptographic policy, library usage, and migration timelines. Align this body with vendor and supplier engagement so there’s one accountable team driving the cloud provider and third-party vendor relationships on PQC readiness.

Fund this team to drive centralized remediation patterns that individual business units adopt rather than reinvent. They own the reference implementations, the approved library versions, the testing frameworks, and the rollout playbooks. When one team solves a migration pattern for a given workload type, the centralized team packages that solution and distributes it across every similar workload in the organization.

Classify dependencies and reduce migration surface area

Beware of guidance that recommends a comprehensive bottom-up cryptographic inventory, except in jurisdictions where it’s explicitly required. That exercise can consume months and delay actual migration. Instead, classify your dependencies into three categories:

  1. Workloads where someone else will upgrade for you. Managed cloud services, software as a service (SaaS) providers, and infrastructure vendors with active PQC roadmaps fall here. Your job is to validate their timelines and hold them accountable.
  2. Workloads where someone else owns the stack but won’t upgrade in time. These are vendor dependencies that you need to replace, potentially before the end of their planned useful life. Flag them now so replacement decisions enter your procurement and capex cycles early.
  3. The third is workloads you own and must upgrade yourself. For these, the decision is whether to upgrade in place or modernize into the cloud where the cryptographic layer becomes managed for you.

The first two categories fall into a vendor risk assessment program. The third category is the workstream that must be managed within your own organization and driven to completion on a workback schedule. Track which dependencies have been validated, which replacements are in flight, and which of your self-managed stacks have active upgrade plans. The three-category model gives your centralized team a clear decision framework instead of going into an unbounded discovery exercise.

Build observability and continuously monitor progress

Visibility into your cryptographic posture is a necessity for planning, execution, and demonstrating compliance to auditors. However, observability shouldn’t be a prerequisite to migrating workloads and should be viewed as a parallel workstream so it doesn’t come at the cost of momentum. After your visibility tooling is in place, it will retroactively show all previous work completed and give a real-time view of progress at the organization level.

Many organizations start with TLS because it’s typically the broadest deployment of cryptography and the primary mechanism protecting sensitive data in transit across web applications, APIs, and microservices. Sponsor TLS metric dashboards that show algorithm usage across all endpoints, differentiating between post-quantum and classical TLS traffic using metadata fields in service logs. The PQC Readiness Scanner serves as an example of how to build and deploy this type of visibility tooling. Over time, extend the same observability to other transport protocols like IPSec, SFTP, and SSH.

Establish a continuous evaluation program with company-wide KPIs, which can feed into executive reviews. Beyond discovery, telemetry provides the executive-level progress metrics that sustain board sponsorship over a multiyear program. Some examples include:

  • Percentage of TLS connections using TLS 1.3 and ML-KEM key exchange
  • PQC coverage percentage across your defined categories
  • Ratio of validated vendor timelines to unconfirmed ones
  • Time-to-remediation when a new dependency is flagged as noncompliant.

Track PQC coverage percentage at the workload and organization level. These metrics turn PQC migration from a one-time project into an ongoing governance function, the same way you already govern patching cadence, vulnerability SLAs, and compliance posture. The goal is to develop a standing capability that absorbs future cryptographic transitions as routine operational work rather than requiring a new program each time.

Align with vendors, regulators, and industry groups

PQC migration crosses organizational boundaries and requires coordinated movement across your supply chain. Engage your cloud providers on their PQC roadmaps and understand which services already support PQ-TLS, which are on the roadmap, and when support is expected. Engage third-party software vendors and SaaS providers with explicit questions about PQC support timelines and write PQC readiness into procurement requirements and vendor contracts going forward.

Engage regulators and standards bodies in your jurisdictions to understand the specific timelines, compliance mechanisms, and audit expectations that apply to your industry. Participate in industry forums because financial services, telecom, healthcare, and critical infrastructure each have sector-specific PQC working groups where peer organizations are sharing approaches and lessons learned. This collaborative approach can also help you get the investment you need for a migration when you have unwilling stakeholders across the business.

Prioritize and roadmap the workloads you own

Adopt a phased approach rather than attempting to migrate everything all at once. Prioritize workloads based on risk and use case. The AWS post-quantum cryptography migration plan blog post provides an example of this prioritization. As you execute on your roadmap, build reliable release and rollback mechanisms at every stage. PQC algorithms have different performance and size characteristics that might surface unexpected behavior under production load. Identify legacy dependencies before they become migration blockers. Systems running custom TLS libraries or hardcoded cipher suites need to be flagged early in the process.

The fastest path to reducing your PQC surface area is eliminating custom cryptographic stacks entirely. Every workload you migrate to a managed service is one fewer workload that your team must upgrade manually. AWS has already delivered post-quantum key exchange across several service endpoints with imperceptible performance impact, and post-quantum signing through AWS Key Management Service (AWS KMS) and AWS Private Certificate Authority. For bespoke code on cloud compute or on premises, open source cryptographic libraries like AWS-LC provide production-ready, FIPS 140-3 validated PQC implementations that your teams can adopt immediately.

Transition to a crypto agile enterprise

Crypto agility is the operational capability to rotate algorithms, update protocols, and absorb cryptographic change as business as usual rather than a dedicated program. Cryptographic standards will continue to evolve. Algorithms will be deprecated and replaced. The organizations that build the ability to do this now won’t need a new program next time.

Crypto agility demands excellence at four disciplines:

  • Patching and upgrade discipline: If you can’t maintain consistent patching cadences across your fleet today, PQC migration will surface that gap at enterprise scale. Mature vulnerability management programs adopt PQC as a natural extension of existing operations.
  • Incremental release with clean rollback: PQ algorithms carry larger signatures, larger keys, and different performance profiles. You need to be able to deploy changes incrementally, validate behavior in production, and rollback cleanly when something doesn’t perform as expected.
  • Consistent CI/CD pipelines: Every application touching asymmetric cryptography will need to be evaluated and potentially rebuilt and redeployed with updated algorithms or libraries. Fragile or manual deployment processes will impede the entire migration.
  • Automated security lifecycle management: Certificate lifecycle, key rotation, secrets vaulting, signature operations, and compliance validation must all operate at machine speed. Manual processes that function today will fail as security requirements evolve.

These aren’t necessarily PQC-specific investments. They’re the foundational capabilities of a well-run security organization. With AI accelerating the speed at which vulnerabilities are discovered and exploited, organizations that have built crypto agility into their operational posture are better positioned to respond to AI-accelerated threats. Savvy security leaders can use PQC as a forcing function to build the operational resilience your organization needs as the threat landscape evolves.

Conclusion

PQC migration will define how the next generation of enterprise security programs are built and measured. The technical tooling exists to execute this transition faster than any previous cryptographic migration. The organizations that move now will shape procurement requirements and set the competitive baseline for their industries. Those that defer will inherit compressed timelines, increased costs, and diminished optionality.

AWS is here to help as you navigate the PQC migration process. You can find our latest guidance and publications in Migration to quantum-resistant cryptography.

AWS Security Assurance Services and AWS Professional Services provide expert guidance, and validated implementation approaches to help you upgrade your own applications and workloads. To get started, you can request a complimentary Post-Quantum Readiness Accelerator introductory call.

If you have feedback about this post, submit comments in the Comments section below.


Rushir Patel

Rushir Patel

Rushir leads Worldwide Data Protection Business Development at AWS, driving go-to-market strategy for the AWS cryptography, identity, and data protection services. He brings over 15 years of experience in cybersecurity, cloud, and AI, with a background in corporate finance and electrical engineering. Outside of work, Rushir enjoys gardening, skiing, wine, and traveling.

  •  

AWS Security Hub Extended: Why enterprise security products should sell themselves

Our largest security services customers started the same way every customer does – with a click. They enabled Amazon GuardDuty, Amazon Inspector, AWS WAF, and AWS Security Hub, experienced the benefits in real time, and evaluated with transparent pay-as-you-go pricing. No RFP. No six-month evaluation. No multi-year commitment up front. Our field teams played a critical role in that growth, not by selling the first click, but by building the trusted relationships that turned early adoption into deep, long-term commitment. We believe customers should have this same frictionless adoption experience and flexibility for all best-in-class security products and that’s why we developed Security Hub Extended.

In our first post, we introduced Security Hub Extended, a significant expansion of Security Hub that brings together curated partner solutions in a single, unified experience. In our second post, we walked through how it works technically, including the onboarding flow, the pricing model, the unified operations layer built on the Open Cybersecurity Schema Framework (OCSF). In this post, I want to step back and talk about why we built it the way we did and why I believe the way enterprises discover, evaluate, and adopt security solutions is ready for a fundamental shift.

The shift

If you’ve ever tried to evaluate a new enterprise security product, you know the drill. Request a demo. Wait. Take the demo. Request a PoC. Wait for professional services (or your team to stop building) to set it up. Negotiate pricing, which isn’t published, so you’re starting blind. Loop in procurement. Sign a multi-year commitment. Then, months later, find out whether the product actually solves your problem in your unique environment.

Meanwhile, an ambitious security engineer on your team has already spun up an open-source tool, connected real data, and knows in two hours whether it’s going to work for your use cases. They didn’t need a slide deck. They needed a solution they could put their hands on.

A Fortune 500 CISO recently told me: “I spent 9 months procuring a security solution and it still doesn’t work the way the demo showed.” That frustration isn’t unique. It’s the norm.

This isn’t a criticism of the sales motion. Sales-led has evolved for good reason. Enterprise procurement is complex, products need customization, customers need support. I respect the craft and have poured a significant portion of my career into trying to perfect it. Even the most product-driven companies still need great sales, marketing, field enablement, and support.

It doesn’t change the fact that threats are evolving constantly, and defenders need the flexibility to discover and deploy new solutions as fast as the landscape shifts. Having the best solutions discoverable and deployable in that moment of need isn’t just a convenience, it’s a competitive advantage that customers are demanding. A new threat emerges, security teams have access to industry-leading solutions, and in a few clicks they’ve found their answer and are already seeing value. That’s the model every security company should be building toward.

What we’ve learned at AWS

At AWS, we’ve spent two decades learning what it takes to let customers adopt complex enterprise technology on their own terms, at massive scale. We haven’t always gotten it right, but we learn fast and adjust. The result is one of the largest cloud businesses in the world. I bring up that scale for one reason. It’s proof that complex, enterprise-grade technology can be adopted without requiring a traditional procurement gauntlet. Compute, storage, databases, AI/ML, networking, and yes, security — adopted all through a console, on each customer’s own timeline, and scaled when they were ready.

The proof is in the adoption

Amazon GuardDuty, Amazon Inspector, AWS Shield, AWS Security Hub are all available through the AWS Management Console. All pay-as-you-go. All activated with a click. Tens of thousands of customers rely on these security services today. When you make it easy to get started and deliver outcomes that earn confidence, expansion follows naturally.

These are sophisticated, enterprise-grade security solutions. And customers, from two-person startups to the world’s largest financial institutions, adopt them the same way. They try it, see the value, expand, and lean on the AWS team to go deeper.

We didn’t get here by accident, and we definitely didn’t get here without making mistakes. Building products that can be adopted and scaled on their own, without a sales engineer explaining away UX problems, without a solutions architect doing the first deployment, requires a different kind of product mindset. Time-to-value becomes your most important metric. Onboarding friction becomes your biggest enemy. Transparent pricing becomes non-negotiable. It’s hard. We’ve gotten a lot wrong along the way. And we’re still iterating.

But the results are clear. When customers adopt based on experience rather than commitment, they don’t just stay, they expand. They bring their teams. They become advocates. I’ve spent 15 years at AWS, the last 10 building security services like GuardDuty and Security Hub. When we launch a new security service or major feature, we consistently see rapid organic adoption at a pace that would be impossible through traditional sales cycles alone. These products are built to deliver value the moment customers turn them on and we make that as easy as we possibly can. That’s the scale a product-led motion unlocks.

Security Hub Extended

So, we asked ourselves: why can’t we build a similar approach that can expand to include industry leading partner solutions? Why can’t the CrowdStrikes, the Splunks, the Zscalers, and the fast-growing innovators solving tomorrow’s problems like Cyera, Noma, and 7AI also reach customers with the same frictionless motion that AWS services enjoy? Why can’t a security team that discovers a new threat on Monday have a proven solution deployed and delivering value by Tuesday? Our partners have built incredible products. What they haven’t always had is an avenue to put those products directly in the hands of the customers who need them most, at the moment they need them, at scale, in a way that feels as natural as turning on an AWS service. Not by replacing how our partners build or sell, but by giving them infrastructure that lets their products speak for themselves.

That’s what Security Hub Extended is. Security teams already using Security Hub can discover curated partner solutions right alongside their AWS security services. One click to evaluate, one click to deploy, pay-as-you-go pricing on your existing AWS bill with Enterprise Discount Program (EDP) discounts automatically applied. No separate procurement cycle. No long-term commitments required. Start fast, validate at scale, and commit for deeper discounts when you’re ready, versus making a three-year bet based on a few months of testing.

For customers, industry-leading enterprise security solutions become as easy to adopt as GuardDuty or WAF. For our partners, Security Hub Extended is a growth channel where the product leads and the customer experience mirrors what we’ve spent 20 years building at AWS. For the industry, it’s an invitation to reimagine what the relationship between a security product and a security practitioner can look like when you remove the friction standing between them.

But Security Hub Extended isn’t just a simpler way to buy security products. It’s a unified solution. When a customer enables a solution through Extended, we’re working toward an experience where AWS handles the rest. Sensors that deploy automatically across Amazon EC2, Amazon EKS, and AWS Fargate workloads using the same mechanism that powers GuardDuty Runtime Monitoring. IAM roles that provision across a customer’s Organization in one click. Resource inventory is automated from day one – S3 buckets, databases, AI workloads – without manual work.

Once enabled, solutions in Security Hub Extended emit findings in OCSF, automatically aggregated in Security Hub alongside findings from GuardDuty, Amazon Inspector, and every other AWS security service. Security Hub applies risk scoring and correlated risk analytics across all of them. AWS-native and third-party findings together, weighted and prioritized as a single view of your security posture. For example, an endpoint detection from CrowdStrike, correlated with a credential theft in GuardDuty, and a data access event from Cyera, produces an attack path that none of those solutions can produce alone. The correlation uses AWS context (IAM topology, VPC exposure, resource criticality) to improve the context of each attack path for security analysts. Deploying a solution through Security Hub Extended doesn’t add another pane of glass. It deepens the intelligence of the one you already have.

We’re also building toward automated response. Customers will be able to opt in to pre-built playbooks that take action through AWS-native services when a threat is detected, such as isolating compromised resources, revoking credentials, or containing active threats. The goal is detect-to-respond in seconds, not the hours it takes to context-switch across five consoles and two ticketing systems.

Where we are and where we’re headed

We’re still in the first inning — or Day 1, as we like to say at Amazon. We launched in February 2026 with 14 partners, now 21, spanning endpoint, identity, email, network, data, browser, cloud, AI, and security operations, and we’re continuously working backwards from customers as we operationalize for scale. We are building this because our customers asked for it. We’re learning alongside our partners and customers every week, identifying what works, what needs improvement, where the friction still lives, and iterating quickly.

We’re building and delivering at the speed of our customers. That means shipping fast, iterating faster, and not waiting for perfection. We’re not where we want to be just yet, and we need your feedback to get us there. What’s encouraging is that our partners aren’t waiting to be asked. They’re investing in this alongside us. Not because we’re demanding it, but because they see the same thing we do, that companies that make it effortless for customers to get started are the ones that will win at scale.

The early signals are encouraging. Customer response has exceeded our expectations, and the feedback we hear most often is that the procurement simplification and flexibility of pay-as-you-go with public pricing alone, even before the unified operations and data normalization benefits, is a meaningful differentiator.

If you’re a security leader: Security Hub Extended is live now. Log into Security Hub, look for the Security Hub Extended Plan (or visit the Security Hub Extended Pricing Page), and explore what’s available for your use cases. Start with what solves your most urgent problem. Pay-as-you-go, no commitment. Your team will tell you if it’s working in days, not months.

The vision is bigger than what’s live today, and we’re iterating fast. Share your feedback on AWS re:Post for Security Hub, reach out through contact AWS Support, or connect with me directly.


Michael Fuller

Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.


  •  

Building AI defenses at scale: Before the threats emerge

At AWS, we’ve spent decades developing processes and tools that enable us to defend millions of customers simultaneously, wherever they operate around the world. AI has been an extremely helpful addition to the automation our security and threat intelligence teams do every day, and we’re still early in this journey. Our AI-powered log analysis system has reduced the time SecOps engineers spend analyzing security logs from an average of six hours to just seven minutes, a 50x productivity increase that lets us detect and respond to threats faster than ever. Across AWS, we analyze over 400 trillion network flows per day to detect patterns that signal emerging threats. In 2025 alone, we blocked over 300 million attempts to maliciously encrypt customer files hosted on Amazon S3. At this scale, every improvement in our operations helps protect all customers. AI is already helping us make our defenses stronger for everyone, and I’m excited to see that improvement continue.

A new class of AI for cybersecurity

Today, Anthropic announced Project Glasswing, a cybersecurity initiative designed to secure the world’s most critical software and advance the cybersecurity practices the industry will need as AI grows more capable. Organizations that build or maintain critical digital infrastructure are getting early access to Claude Mythos Preview, a new class of AI model, to find and patch vulnerabilities in the systems the world depends on. Given our role in securing some of the world’s most essential infrastructure, AWS is playing an integral part in advancing this work.

As part of Project Glasswing, we’ve already applied Claude Mythos Preview to critical AWS codebases that undergo continuous AI-powered security reviews, and even in those well-tested environments, it’s helped us identify additional opportunities to strengthen our code. In our internal testing, Claude Mythos Preview has proven more productive than previous models at surfacing security findings, requiring less manual guidance from our engineers to deliver actionable results. We’ve also given early access to a select group of AWS customers, who are deploying Claude Mythos Preview in their own security workflows and helping shape how the model evolves.

As AI tools grow more powerful in their ability to identify security issues, so must our ability to use them defensively. To that end, we’ve been working closely with Anthropic to help ensure Claude Mythos Preview is ready for enterprise use. AWS is Anthropic’s primary cloud provider for mission-critical workloads, safety research, and foundation model development. More broadly, AWS provides the foundational infrastructure that the world’s leading AI companies rely on to build, train, and deploy their most advanced models. We’re bringing decades of security experience to this partnership, helping to ensure Claude Mythos Preview is ready for even more organizations to build upon and operate securely at scale.

Claude Mythos Preview signals an upcoming wave of models that can find vulnerabilities and build working exploits at a scale and speed we haven’t seen before. Anthropic and AWS are taking a deliberately cautious approach to release. Access begins with a small number of organizations, prioritizing internet-critical companies and open-source maintainers whose software and digital services impact hundreds of millions of users. The goal: find and fix vulnerabilities in the world’s most critical software. Claude Mythos Preview is available in gated research preview through Amazon Bedrock with enterprise-grade security controls, including customer-managed encryption, VPC isolation, and detailed logging, so your team can explore Claude Mythos Preview’s capabilities without exposing production assets to unnecessary risk.

AWS architects services with security at the core

Our work with Project Glasswing is grounded in a philosophy we’ve developed over two decades of securing mission-critical workloads: you can’t wait for threats to materialize before building your defenses. You have to look around corners, adopt new technologies, build protections first, deploy them in your own operations at scale, and refine them based on what you learn.

That’s exactly what we’ve done at AWS with AI and security. Our approach spans the full spectrum: proactive defense through threat hunting and vulnerability research, dynamic response to active campaigns, and third-party certifications that verify our security practices meet the highest industry standards. This operational experience has taught us where AI accelerates security work and where human judgment remains essential. And it’s reinforced that security innovation must be pragmatic: proven in production before we ask you to rely on it.

That’s also why we help define what secure AI looks like. We became the first major cloud provider to achieve ISO 42001 certification for AI services. We’re active participants in OWASP, the Coalition for Secure AI, and the Frontier Model Forum. And we co-founded the Open Cybersecurity Schema Framework (OCSF) to enable better threat intelligence sharing across the ecosystem. The AWS Nitro System provides mathematically proven isolation for workloads. Systems and services like KMS, Nitro, EKS, and Lambda are designed with zero-operator access architectures, meaning AWS personnel can’t access your data. These aren’t aspirational goals. They’re how we operate today, at scale, every day.

Amazon Bedrock is where these principles come to life for AI. Bedrock provides policy-enforced access controls, built-in evaluation tools to measure how effectively models identify and validate vulnerabilities, and the ability to run workloads inside your own virtual private cloud. AWS is also the first cloud provider to achieve FedRAMP High and Department of Defense Security Requirements Guide Impact Level 4 and 5 authorizations for generally available Claude foundation models. Amazon Bedrock is already where the most security-sensitive organizations trust Anthropic’s technology, and it makes perfect sense for Claude Mythos Preview.

How to get started today

The same principles that guide our work at AWS scale apply regardless of which AI tools you’re using: comprehensive observability, defense in depth, automation where it adds value, and human judgment where it’s essential. Here’s how to put them into practice.

Prepare for the next generation of AI security. Claude Mythos Preview signals an upcoming wave of AI models that will transform cybersecurity. Start strengthening your security posture now so your organization is ready as these capabilities become more broadly available. Claude Mythos Preview is available in gated preview through Amazon Bedrock, and access is limited to an initial allow-list of organizations. If your organization has been allow-listed, your AWS account team will reach out directly.

Run on-demand penetration testing with AWS Security Agent. Now generally available, AWS Security Agent delivers autonomous penetration testing that operates 24/7 at a fraction of the cost of manual penetration tests. It transforms penetration testing from a periodic bottleneck into an on-demand capability that scales with your development velocity across AWS, Azure, GCP, other cloud providers, and on-premises. AWS Security Agent represents a new class of frontier agents: autonomous systems that work independently to achieve goals, scale to tackle concurrent tasks, and run persistently without constant human oversight. It deploys specialized AI agents to discover, validate, and report security vulnerabilities through sophisticated multi-step scenarios. Unlike traditional scanners that generate findings without validation, AWS Security Agent identifies potential vulnerabilities, then attempts to exploit them with targeted payloads and attack chains to confirm they are legitimate security risks. Each finding includes CVSS risk scores, application-specific severity ratings, detailed reproduction steps, and remediation suggestions. The result: penetration testing that once took weeks now completes in hours, scales across your entire application portfolio, and helps you get started with remediation instead of leaving you with a report. New customers can explore AWS Security Agent with a 2-month free trial.

Build AI applications you can trust with Amazon Bedrock. For teams building with generative AI, the challenge isn’t just making AI work, it’s making AI work safely. Amazon Bedrock provides the security and safety controls you need to deploy AI responsibly. Its Automated Reasoning capability is the first and only AI safeguard to use formal logic to help prevent factual errors from hallucinations, providing verifiable explanations with 99% accuracy, a capability we’ve refined over more than a decade of applying formal methods across AWS storage, identity, and networking. Amazon Bedrock also provides customizable guardrails that block harmful content and enforce your content policies, along with comprehensive observability to track AI behavior and detect anomalies across your workloads.

The threat landscape isn’t waiting

The threat landscape isn’t waiting for us to catch up. Nation-state actors, ransomware operators, and supply chain attackers are already using AI to scale their operations. Our job is to stay ahead by building defenses first, deploying them at scale, and sharing what we learn so the entire community benefits.

That’s what we do every day at AWS. We build in security from the start, ensuring it works and scales before we ask customers to rely on it. We set standards rather than follow them. And we look around corners to address tomorrow’s challenges today.

As AI capabilities continue to evolve, this approach won’t change. We’ll keep building defenses first, refining them at scale, and working with partners like Anthropic to ensure the next generation of AI security tools meets the real-world needs of enterprises defending at this scale.

Learn More

If you have feedback about this post, submit comments in the Comments section below.

Amy Herzog

Amy Herzog is Vice President and Chief Information Security Officer (CISO) at Amazon Web Services (AWS) where she leads a global organization of cloud security professionals in a company in which security is the top priority. Prior to joining AWS, Amy served as CISO for Amazon’s Devices and Services, Media and Entertainment, and Advertising businesses, overseeing the security of consumer technology offerings such as Alexa+ and Ring, and playing a key role in the secure development of Project Kuiper, Amazon’s initiative to provide fast, reliable broadband to customers and communities around the world through low earth orbit satellites.

  •  

Four security principles for agentic AI systems

Agentic AI represents a qualitative shift in how software operates. Traditional software executes deterministic instructions. Generative AI responds to human prompts with output that humans review and use at their discretion. Agentic AI differs from both. Agents connect to software tools and APIs and uses large language models (LLMs) as reasoning engines to plan and execute sequences of actions autonomously—at machine speed—with real-world consequences. This shift raises new questions for information security. In January 2026, NIST’s Center for AI Standards and Innovation (CAISI) issued a Request for Information (RFI) seeking industry input on how to secure these systems. AWS submitted a response grounded in our experience building and operating agentic AI services. This post summarizes the four security principles at the heart of that response and the architectural building blocks that implement them.

The NIST agentic AI RFI

CAISI asked developers, deployers, and security researchers to weigh in on how the industry should secure AI systems that act autonomously. The RFI posed questions across five areas. What unique security considerations do agentic systems introduce, and how do those considerations change as systems gain more autonomy? What practices improve security during development and deployment? How do organizations assess the security of their agentic systems? How can deployment environments be constrained and monitored? And where should the industry focus future research?

Why this matters

Even a conservative risk/benefit analysis will conclude that the benefits of agentic AI clearly outweigh the risks in many domains. The rapid adoption of agentic technology across business and government confirms this. But agents are valuable precisely because of their autonomy and adaptability, and these same characteristics create the security challenge. An agentic system that carries out an unintended action can do so at machine speed, before a human can intervene. Unlike human actors who pause or escalate when something seems unusual, agents might not inherently recognize ambiguities that are evident to humans, nor intuitively grasp unstated policy boundaries.

The good news, however, is that the security response to agentic AI doesn’t need to start from scratch. Existing security frameworks, including the NIST Cybersecurity Framework, NIST AI Risk Management Framework, and the Secure Software Development Framework, remain relevant and should be extended for agent-specific considerations rather than replaced. The most important extension is architectural. Our response to NIST identified four foundational security principles that address how to make that extension.

Four security principles for agentic AI

These principles build on the premise that agentic AI doesn’t require a new security paradigm, but it does require existing practices to evolve. The first two principles address what carries forward; the second two address what is genuinely new.

Principle 1: Secure development lifecycle practices apply across system components. Agentic AI systems combine traditional software components (APIs, databases, orchestration logic) with AI elements such as foundation models, prompt templates, and retrieval pipelines. A secure development lifecycle must cover both sets of components. For traditional components, established practices such as code review, static analysis, dependency scanning, and threat modeling remain essential, keeping in mind that those practices are also in the process of being enhanced with AI-based tooling. For AI components, the challenge is different. Foundation models are probabilistic, which means traditional regression testing is necessary but not sufficient. Organizations must supplement it with behavioral testing, adversarial evaluation, and continuous monitoring to validate that AI components operate within expected parameters.

Regular re-evaluation is equally important for addressing behavioral drift. Models receive updates that can alter behavior. Prompt templates evolve as teams refine agent capabilities. New tools and data sources expand the agent’s operational surface. Each change can introduce new failure modes or potential security issues. Organizations must treat evaluation as an ongoing operational practice, not a one-time gate. This includes automated testing after model updates, red team exercises against deployed agents, and monitoring that detects behavioral drift over time.

Principle 2: Traditional security controls remain fully applicable. Agentic AI introduces new considerations, but it doesn’t render existing security risks obsolete. The full complement of traditional security controls still applies. An agentic AI system combines traditional software with the new LLM-plus-tools processing loop. Organizations must secure existing software, tools, and configurations against well-known risks to provide a sound foundation for the agentic elements.

Privilege escalation, confused deputy issues, session hijacking, code injection, and supply chain risks extend directly into agentic systems. Some of these risks increase in agentic contexts. Agents operate at greater scale and speed than human actors, which means excessive privileges carry more potential for unintended consequences. That means that applying principles of least privilege to access management in an agentic context is as important—if not more so—than in traditional systems. The supply chain surface is also broader. Agentic systems consume not only third-party code dependencies but also foundation models, plugins, tool servers, and data retrieval sources. Agents that invoke APIs, query databases, or generate code create new potential injection surfaces at tool boundaries. AI-specific controls must be additions to this foundational security, not replacements for it.

Principle 3: Deterministic external controls are the starting point for agentic security. This is the most important architectural principle for agentic AI security. Organizations should enforce security through deterministic, infrastructure-level controls external to the agent’s reasoning loop, not through the agent’s own reasoning, internal guardrails, or prompt-based instructions. The logic is straightforward. LLMs are probabilistic reasoning engines, not security enforcement mechanisms. Developers can instruct an LLM to refuse certain requests, but prompt injection techniques can override those instructions. An LLM can be told to respect access boundaries, but it has no reliable mechanism to enforce them. Attempting to constrain agent behavior only through prompting or alignment runs against the fundamental value proposition of agents, which is their ability to adapt dynamically to novel situations.

Effective security places fully specified, deterministic controls outside the agent that govern which tools it can access, what operations it can perform, and what data it can reach. Model manipulation cannot bypass these controls. We describe this as the security box. It’s external to the agent, deterministic in its enforcement, and comprehensive in its coverage. Every interaction between the agent and the outside world passes through it. The Agentic AI Security Scoping Matrix helps organizations calibrate the rigor of these controls based on their system’s autonomy level. Scopes range from systems that require explicit human approval before every action to fully autonomous systems that initiate their own activities based on external events.

The security box isn’t a limitation on the agent’s value. It’s the precondition for achieving that value responsibly. As agentic technology matures, the box itself will likely evolve to include agentic elements. Specialized AI agents designed to control the scope of other agents might replace some deterministic constraints over time, using new information and context to make more appropriate automated decisions than could be achieved by humans managing complex deterministic controls.

Principle 4: Greater autonomy should be earned through ongoing evaluation. Organizations should expand agent autonomy progressively based on demonstrated performance, not grant it by default. The starting point is human decision-making for high-consequence operations. When an agent encounters an action that could modify high-value production data, initiate financial transactions, or communicate sensitive information externally, a human makes the final decision. The agent recommends, and a human approves or rejects.

This approach carries a well-known risk. If every agent action requires human approval, the volume of decisions might overwhelm reviewers. Approval becomes reflexive rather than deliberate, shifting liability to humans who have been placed in a position to fail. Organizations must scope human oversight to genuinely high-consequence operations and resist the temptation to require human-in-the-loop designs for routine actions that carry low risk.

The path from human oversight to expanded autonomy runs through evaluation. As organizations systematically record what the agent recommended, what the human decided, and what actually happened, they build the evidence base for expanding autonomy. When data shows sustained alignment, organizations can shift from prior approval to after-the-fact review, and eventually to full autonomy for specific operation types. This progression should happen at the operation or workflow level, not across a broad range of unrelated tasks.

This progression isn’t one-way. Organizations should be prepared to reintroduce human oversight when evidence warrants it. Some deterministic boundaries likely remain permanent for the foreseeable future. These boundaries exist not because the agent hasn’t earned trust, but because the consequences of certain actions are unacceptable under a reasonable risk analysis. The overall model is one of earned autonomy through demonstrated competence, governed by evaluation, bounded by permanent constraints, and subject to continuous review. There might come a time with specialized boundary agents can provide better outcomes than purely deterministic controls, but that option can only emerge over time from experience and evaluation.

From principles to practice

The four principles define the goals. Achieving them requires specific architectural building blocks that compose the security box and the broader security architecture. Our response to NIST described these building blocks in greater detail. Here we provide a summary. AWS has implemented them in Amazon Bedrock AgentCore, a framework for building, deploying, and operating agentic AI systems with security built in from the ground up.

Compute isolation. Agent compute environments must isolate execution, prevent cross-agent data leakage, and contain agents within defined boundaries. Amazon Bedrock AgentCore runs agents on Firecracker, an open source virtual machine manager written in Rust. Firecracker provides lightweight micro-VMs backed by Linux KVM and hardware-based virtualization, delivering the speed of containers with the isolation properties of full virtual machines. Key security-critical elements of Firecracker have been formally verified by AWS teams, adding assurance beyond the memory safety that Rust provides.

Identity and access management. Agents require their own identities, secure credential storage, and least-privilege authorization enforced at the infrastructure level. AgentCore Identity provides machine identities for agents, manages OAuth and secure credential flows, and integrates with AWS Identity and Access Management (IAM) for fine-grained access control. It supports attribute-based access control and maintains traceable delegation chains so that the relationship between agent actions and the invoking user remains auditable.

Tool access and policy enforcement. Every tool an agent can access expands both its usefulness and its potential risk. Managing tool access individually across agents creates an unmanageable combinatorial explosion. AgentCore Gateway acts as a centralized intermediary between agents and tools, enforcing authentication and authorization at a single control point. It can inspect tool calls down to individual parameters, not just at the API level. AgentCore Policy, built on the open source Cedar authorization language, adds formally verified policy enforcement. Teams can author Cedar policies in natural language and then review them, combining the flexibility of LLMs with the rigor of formal methods.

Observability. Observability infrastructure must capture sufficient context for real-time monitoring and investigation, and it must be protected from the agents it monitors. Organizations wouldn’t allow employees to edit their own audit logs, and the same principle applies to agents. AgentCore provides observability through the AgentCore Gateway, session-level telemetry, and detailed traces that record internal state changes. These capabilities can extend to agents running outside of AgentCore as well.

Model execution environment. The security of the model execution environment matters as much as the security of the agent itself. Amazon Bedrock runs models in isolated network environments where neither AWS nor model providers access customer prompts and responses. When customers enable logging, those logs are encrypted at rest and protected by customer-managed encryption keys. This architectural isolation is a key reason government and enterprise customers have adopted Amazon Bedrock.

Deterministic external controls are complemented by controls within the AI processing loop. Amazon Bedrock Guardrails inspects prompts and responses using small AI models called classifiers that address challenges such as prompt injection. Automated Reasoning checks go further, so that developers can create a formal model of a knowledge domain and verify that LLM output conforms to it, producing results that are deterministic and provably correct.

Looking ahead

Agentic AI changes how software operates, but the security response builds on decades of established practice. Existing frameworks provide the right foundation. The task is to extend existing frameworks for agent-specific considerations. Organizations should apply secure development lifecycle practices to AI components and maintain traditional security controls. They should enforce security through deterministic controls external to the agent and earn greater autonomy through systematic evaluation.

These principles aren’t theoretical. They reflect the operational experience AWS has gained building and operating agentic AI services. They’re embedded in how we design our infrastructure. As NIST develops guidance based on industry input, we will continue to invest in helping customers build and operate agentic AI systems with confidence.

To learn more about how AWS helps customers secure their AI workloads, visit the AWS AI Security or read the Amazon response to the CAISI Request for Information regarding Security Considerations for Artificial Intelligence Agents.

Mark Ryland

Mark Ryland

Mark is a director of the Office of the CISO for AWS. He has more than 30 years of experience in the technology industry and has served in leadership roles in cybersecurity, software engineering, distributed systems, technology standardization, and public policy. Prior to his current role, he served as the Director of Solution Architecture and Professional Services for the AWS World Public Sector team.

Riggs Goodman III Riggs Goodman III
Riggs is a Principal Solution Architect at AWS. His current focus is on AI security, providing technical guidance, architecture patterns, and leadership for customers and partners to build AI workloads on AWS. Internally, Riggs focuses on driving overall technical strategy and innovation across AWS service teams to address customer and partner challenges.
Todd MacDermid Todd MacDermid
Todd is a Principal Security Engineer in the Amazon AI Security Group. He has spent over 15 years at Amazon primarily working in AWS Security, and prior to Amazon spent 10 years working in red-team consulting and application and network security.
  •  

Amazon threat intelligence teams identify Interlock ransomware campaign targeting enterprise firewalls

Amazon threat intelligence has identified an active Interlock ransomware campaign exploiting CVE-2026-20131, a critical vulnerability in Cisco Secure Firewall Management Center (FMC) Software that could allow an unauthenticated, remote attacker to execute arbitrary Java code as root on an affected device, which was disclosed by Cisco on March 4, 2026.

After Cisco’s disclosure, Amazon threat intelligence began research into this vulnerability using Amazon MadPot’s global sensor network—a system of honeypot servers that attract and monitor cybercriminal activity. While looking for any current or past exploits of this vulnerability, our research found that Interlock was exploiting this vulnerability 36 days before its public disclosure, beginning January 26, 2026. This wasn’t just another vulnerability exploit, Interlock had a zero-day in their hands, giving them a week’s head start to compromise organizations before defenders even knew to look. Upon making this discovery, we shared our findings with Cisco to help support their investigation and protect customers.

A misconfigured infrastructure server—essentially, a poorly secured staging area used by the attackers—exposed Interlock’s complete operational toolkit. This rare mistake provided Amazon’s security teams with visibility into the ransomware group’s multi-stage attack chain, custom remote access trojans (backdoor programs that give attackers control of compromised systems), reconnaissance scripts (automated tools for mapping victim networks), and evasion techniques.

AWS infrastructure and customer workloads on AWS were not observed to be involved in this campaign. This advisory shares comprehensive technical analysis and indicators of compromise to help organizations identify potential compromise and defend against Interlock’s operations. Organizations running Cisco Secure Firewall Management Center should immediately apply Cisco’s security patches and review the indicators provided below.

Discovery and investigation timeline

Amazon threat intelligence identified threat activity potentially related to CVE-2026-20131 beginning January 26, 2026, predating the public disclosure. Observed activity involved HTTP requests to a specific path in the affected software. Request bodies contained Java code execution attempts and two embedded URLs: one used to deliver configuration data supporting the exploit, and another designed to confirm successful exploitation by causing a vulnerable target to perform an HTTP PUT request and upload a generated file. Multiple variations of these URLs were observed across different exploit attempts.

To advance the investigation and obtain additional threat intelligence, we performed the expected HTTP PUT request with the anticipated file content—essentially, we pretended to be a successfully compromised system. This successfully prompted Interlock to proceed to the next stage, issuing commands to fetch and execute a malicious ELF binary (a Linux executable file) from a remote server.

When analysts retrieved the binary, they discovered the same host (attacker-controlled server) is used for distributing Interlock’s entire operational toolkit. The exposed infrastructure organized artifacts into separate paths corresponding to individual targets, with the same paths used for both downloading tools to compromised hosts and uploading operational artifacts back to the staging server.

Attribution to Interlock ransomware

The ELF binary and associated artifacts are attributable to the Interlock ransomware family based on convergent technical and operational indicators. The embedded ransom note and TOR negotiation portal are consistent with Interlock’s established branding and infrastructure. The ransom note’s invocation of multiple data protection regulations reflects Interlock’s documented practice of citing regulatory exposure to pressure victims, essentially threatening organizations not just with data encryption, but with regulatory fines and compliance violations. The campaign-specific organization identifier embedded in the note aligns with Interlock’s per-victim tracking model.

Interlock has historically targeted specific sectors where operational disruption creates maximum pressure for payment. Education represents the largest share of their activity, followed by engineering, architecture, and construction firms, manufacturing and industrial organizations, healthcare providers, and government and public sector entities.

Temporal analysis performed on timestamps from observed threat activities, artifacts stored on the misconfigured infrastructure server, and metadata embedded within recovered threat artifacts indicates the actor most likely operates in UTC+3 with 75–80% confidence. Systematic analysis across all UTC offsets showed UTC+3 produced the best fit: first activity around 08:30, peak activity between 12:00 and 18:00, and a probable sleep window of 00:30–08:30.

Interlock ransomware negotiation portal where victims enter their organization ID and email address to receive an auth token to begin a negotiation chat session.

Figure 1: Interlock ransomware negotiation portal where victims enter their organization ID and email address to receive an auth token to begin a negotiation chat session.

Technical analysis: Interlock’s operational toolkit

Post-compromise reconnaissance script

Once Interlock gains initial access, they use a variety of priority tools to complete their attack. Amazon threat intelligence teams recovered a PowerShell script designed for systematic Windows environment enumeration (automated information gathering about the victim’s network). The script collects operating system and hardware details, running services, installed software, storage configuration, Hyper-V virtual machine inventory, user file listings across Desktop, Documents, and Downloads directories, browser artifacts from Chrome, Edge, Firefox, Internet Explorer, and 360 browser (including history, bookmarks, stored credentials, and extensions), active network connections correlated with responsible processes, ARP tables, iSCSI session data, and RDP authentication events from Windows event logs.

The script stages results to a centralized network share (\JK-DC2\Temp) using each system’s fully qualified hostname to create dedicated directories—essentially creating a folder for each compromised computer. Following collection, it compresses data into ZIP archives named after each hostname and removes original raw data. This structured per-host output format indicates the script operates across multiple machines within a network—a hallmark of ransomware intrusion chains that prepare for organization-wide encryption.

Custom remote access trojans

Remote access trojans (RATs) are malicious programs that give attackers persistent control over compromised systems, functioning like unauthorized remote desktop software.

JavaScript implant: Amazon threat intelligence recovered an obfuscated JavaScript remote access trojan that suppresses debugging output by overriding browser console methods (hiding its activity from basic detection tools). On execution, it profiles the infected host using PowerShell and Windows Management Instrumentation (WMI), collecting system identity, domain membership, username, OS version, and privilege context before transmitting this data during an encrypted initialization handshake.

Command-and-control communication occurs over persistent WebSocket connections with RC4-encrypted messages using per-message 16-byte random keys embedded in packet headers—essentially, each message uses a different encryption key, making interception more difficult. The implant cycles through multiple operator-controlled hostnames and IP addresses in randomized order with exponential backoff between reconnection attempts.

The implant provides interactive shell access, arbitrary command execution, bidirectional file transfer, and SOCKS5 proxy capability for tunneling TCP traffic (routing malicious traffic through other systems to hide its origin). Self-update and self-delete capabilities allow operators to replace or remove the implant without reinfection, supporting operational cleanup to hinder forensic investigation.

Java implant: A functionally equivalent client implemented in Java provides identical command-and-control capabilities. Built on GlassFish ecosystem libraries, it uses Grizzly for non-blocking I/O transport and Tyrus for WebSocket protocol communication. In simpler terms, Interlock built the same backdoor in two different programming languages, ensuring they maintain access even if defenders detect one version.

Infrastructure laundering script

Sophisticated threat actors don’t attack from their own infrastructure, they build disposable relay networks to hide their tracks. Amazon threat intelligence teams identified a Bash script that configures Linux servers as HTTP reverse proxies (intermediary servers that forward traffic to hide the attacker’s true location). The script performs system updates, installs fail2ban with SSH brute-force protection, and compiles HAProxy 3.1.2 from source. The HAProxy instance listens on port 80 and forwards all inbound HTTP traffic to a hardcoded target IP, with systemd ensuring persistence across reboots.

A notable component is a log erasure routine running as a cron job every five minutes. The routine truncates all *.log files under /var/log and suppresses shell history by unsetting the HISTFILE variable. This aggressive evidence destruction, wiping logs every five minutes, combined with the purpose-built HTTP forwarding proxy, indicates the script establishes disposable traffic-laundering relay nodes. These nodes obscure exploit traffic origin, relay command-and-control communications, or proxy data exfiltration, making it nearly impossible to trace attacks back to their source.

Memory-resident webshell

Amazon threat intelligence teams observed a Java class file delivered as an alternative to the ELF binary drop. When loaded by the Java Virtual Machine (JVM), its static initializer registers a ServletRequestListener with the server’s StandardContext, essentially installing a persistent memory-resident backdoor that intercepts HTTP requests without writing files to disk. This “fileless” approach evades traditional antivirus scanning that looks for malicious files.

The listener inspects incoming requests for specially crafted parameters containing encrypted command payloads. Payloads are decrypted using AES-128 with a key derived from the MD5 hash of the hardcoded seed “geckoformboundary99fec155ea301140cbe26faf55ed2f40″ (using the first 16 characters: 09b1a8422e8faed0). Decrypted payloads are treated as compiled Java bytecode, dynamically loaded into the JVM, and executed—a technique designed to evade file-based detection by running malicious code entirely in memory.

Connectivity verification tool

Amazon threat intelligence teams recovered Java class files implementing a basic TCP server listening on port 45588 (encoded as Unicode character 넔 to obscure the port number from static analysis). The server accepts connections, logs connecting IP addresses, sends a greeting message, and immediately closes connections. This operational profile is consistent with a lightweight network beacon—essentially a “phone home” tool used to verify successful code execution or confirm network port reachability following initial exploitation.

Legitimate tool abuse

Interlock deployed ConnectWise ScreenConnect, a legitimate commercial remote desktop tool, alongside custom implants. When ransomware operators deploy legitimate remote access tools alongside their custom malware, they’re buying insurance—if defenders find and remove one backdoor, they still have another way in. This indicates multiple redundant remote access mechanisms—a pattern consistent with ransomware operators seeking to maintain access even if individual footholds are removed. The tool’s legitimate network footprint helps blend with authorized remote administration traffic, making detection more challenging.

Amazon threat intelligence teams also recovered Volatility, an open-source memory forensics framework typically used by incident responders (the same tool defenders use to investigate attacks). While no artifacts indicated automated use, its presence alongside custom implants and reconnaissance scripts is consistent with advanced threat operations. Both ransomware groups and nation-state actors have been observed deploying Volatility during intrusions. The tool’s focus on parsing memory dumps provides access to sensitive data such as credentials stored in RAM, which can enable lateral movement (spreading through the network) and deeper environment compromise in support of ransom operations or espionage objectives.

Interlock also used Certify, an open source offensive security tool designed to exploit misconfigurations in Active Directory Certificate Services (AD CS). For ransomware operators, Certify provides a pathway to identify vulnerable certificate templates and enrollment permissions that allow requesting authentication-capable certificates. These certificates can be used to impersonate users, escalate privileges, or maintain persistent access. These capabilities directly support both initial compromise and long-term persistence objectives in ransomware operations.

Indicators of compromise (IoCs)

The following indicators support defensive measures by organizations that may be affected. Due to Interlock’s use of content variation techniques, most file hashes are not included as reliable indicators. The threat actor modified most artifacts like scripts and binaries downloaded to different targets. This resulted in different file hashes for functionally identical tools. The customization allowed each attack to evade signature-based detection that looks for exact file matches.

206.251.239[.]164

Exploit source IP

Active Jan 2026

199.217.98[.]153

Exploit source IP

Active Mar 2026

89.46.237[.]33

Exploit source IP

Active Mar 2026

Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:136.0) Gecko/20100101 Firefox/136.0

Exploit HTTP User-Agent

Observed Jan 2026 and Mar 2026

b885946e72ad51dca6c70abc2f773506

Exploit TLS JA3

Observed Jan 2026 and Mar 2026

f80d3d09f61892c5846c854dd84ac403

Exploit TLS JA3

Observed Mar 2026

t13i1811h1_85036bcba153_b26ce05bbdd6

Exploit TLS JA4

Observed Jan 2026 and Mar 2026

t13i4311h1_c7886603b240_b26ce05bbdd6

Exploit TLS JA4

Observed Mar 2026

144.172.94[.]59

C2 Fallback IP

Active Mar 2026

199.217.99[.]121

C2 Fallback IP

Active Mar 2026

188.245.41[.]78

C2 Fallback IP

Active Mar 2026

144.172.110[.]106

Backend C2 IP

Active Mar 2026

95.217.22[.]175

Backend C2 IP

Active Mar 2026

37.27.244[.]222

Staging host IP

Active Mar 2026

hxxp://ebhmkoohccl45qesdbvrjqtyro2hmhkmh6vkyfyjjzfllm3ix72aqaid[.]onion/chat.php

Ransom negotiation portal

Active Mar 2026

cherryberry[.]click

Exploit Support Domain

Active Jan 2026

ms-server-default[.]com

Exploit Support Domain

Active Mar 2026

initialize-configs[.]com

Exploit Support Domain

Active Mar 2026

ms-global.first-update-server[.]com

Exploit Support Domain

Active Mar 2026

ms-sql-auth[.]com

Exploit Support Domain

Active Mar 2026

kolonialeru[.]com

Exploit Support Domain

Active Mar 2026

sclair.it[.]com

Exploit Support Domain

Active Mar 2026

browser-updater[.]com

C2 domain

Active Mar 2026

browser-updater[.]live

C2 domain

Active Mar 2026

os-update-server[.]com

C2 domain

Active Mar 2026

os-update-server[.]org

C2 domain

Active Mar 2026

os-update-server[.]live

C2 domain

Active Mar 2026

os-update-server[.]top

C2 domain

Active Mar 2026

d1caa376cb45b6a1eb3a45c5633c5ef75f7466b8601ed72c8022a8b3f6c1f3be

Offensive security tool (Certify)

Observed Mar 2026

6c8efbcef3af80a574cb2aa2224c145bb2e37c2f3d3f091571708288ceb22d5f

Screen locker

Observed Mar 2026

Defensive recommendations

Organizations should take the following actions to protect against Interlock ransomware operations.

Immediate actions:

  • Apply Cisco’s security patches for Cisco Secure Firewall Management Center
  • Review logs for the indicators of compromise listed above
  • Conduct security assessments to identify potential compromise
  • Review ScreenConnect deployments for unauthorized installations

Detection opportunities:

  • Monitor for PowerShell scripts staging data to network shares with hostname-based directory structures
  • Detect Java ServletRequestListener registrations in web application contexts (unusual modifications to Java web applications)
  • Identify HAProxy installations with aggressive log deletion cron jobs (proxy servers that erase their own logs every five minutes)
  • Watch for TCP connections to unusual high-numbered ports (e.g., 45588)

Long-term measures:

  • Implement defense-in-depth strategies with multiple layers of security controls
  • Maintain continuous threat monitoring and hunting capabilities
  • Ensure comprehensive logging with secure, centralized log storage (stored separately from systems that could be compromised)
  • Regularly test incident response procedures for ransomware scenarios
  • Educate security teams on Interlock’s tactics, techniques, and procedures

The real story here isn’t just about one vulnerability or one ransomware group—it’s about the fundamental challenge zero-day exploits pose to every security model. When attackers exploit vulnerabilities before patches exist, even the most diligent patching programs can’t protect you in that critical window. This is precisely why defense in depth is essential—layered security controls provide protection when any single control fails or hasn’t yet been deployed. Rapid patching remains foundational in vulnerability management, but defense in depth helps organizations not to be defenseless during the window between exploit and patch.

Amazon Threat Intelligence teams continue to monitor Interlock ransomware operations and will provide updates as additional information becomes available. The intelligence gathered from this campaign is being integrated into AWS security services to protect customers proactively.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

CJ Moses

CJ Moses

CJ Moses is the CISO of Amazon Integrated Security. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon Integrated Security September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.

  •  

AI-augmented threat actor accesses FortiGate devices at scale

Commercial AI services are enabling even unsophisticated threat actors to conduct cyberattacks at scale—a trend Amazon Threat Intelligence has been tracking closely. A recent investigation illustrates this shift: Amazon Threat Intelligence observed a Russian-speaking financially motivated threat actor leveraging multiple commercial generative AI services to compromise over 600 FortiGate devices across more than 55 countries from January 11 to February 18, 2026. No exploitation of FortiGate vulnerabilities was observed—instead, this campaign succeeded by exploiting exposed management ports and weak credentials with single-factor authentication, fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This activity is distinguished by the threat actor’s use of multiple commercial GenAI services to implement and scale well-known attack techniques throughout every phase of their operations, despite their limited technical capabilities. AWS infrastructure was not observed to be involved in this campaign. Amazon Threat Intelligence is sharing these findings to help the broader security community defend against this activity.

This investigation highlights how commercial AI services can lower the technical barrier to entry for offensive cyber capabilities. The threat actor in this campaign is not known to be associated with any advanced persistent threat group with state-sponsored resources. They are likely a financially motivated individual or small group who, through AI augmentation, achieved an operational scale that would have previously required a significantly larger and more skilled team. Yet, based on our analysis of public sources, they successfully compromised multiple organizations’ Active Directory environments, extracted complete credential databases, and targeted backup infrastructure, a potential precursor to ransomware deployment. Notably, when this actor encountered hardened environments or more sophisticated defensive measures, they simply moved on to softer targets rather than persisting, underscoring that their advantage lies in AI-augmented efficiency and scale, not in deeper technical skill.

As we expect this trend to continue in 2026, organizations should anticipate that AI-augmented threat activity will continue to grow in volume from both skilled and unskilled adversaries. Strong defensive fundamentals remain the most effective countermeasure: patch management for perimeter devices, credential hygiene, network segmentation, and robust detection for post-exploitation indicators.

Campaign overview

Through routine threat intelligence operations, Amazon Threat Intelligence identified infrastructure hosting malicious tooling associated with this campaign. The threat actor had staged additional operational files on the same publicly accessible infrastructure, including AI-generated attack plans, victim configurations, and source code for custom tooling. This inadequate operational security provided comprehensive visibility into the threat actor’s methodologies and the specific ways they leverage AI throughout their operations. It’s like an AI-powered assembly line for cybercrime, helping less skilled workers produce at scale.

The threat actor compromised globally dispersed FortiGate appliances, extracting full device configurations that yielded credentials, network topology information, and device configuration information. They then used these stolen credentials to connect to victim internal networks and conduct post-exploitation activities including Active Directory compromise, credential harvesting, and attempts to access backup infrastructure, consistent with pre-ransomware operations.

Initial access: Mass credential abuse

The threat actor’s initial access vector was credential-based access to FortiGate management interfaces exposed to the internet. Analysis of the actor’s tooling supported systematic scanning for management interfaces across ports 443, 8443, 10443, and 4443, followed by authentication attempts using commonly reused credentials.

FortiGate configuration files represent high-value targets because they contain:

  • SSL-VPN user credentials with recoverable passwords
  • Administrative credentials
  • Complete network topology and routing information
  • Firewall policies revealing internal architecture
  • IPsec VPN peer configurations

The threat actor developed AI-assisted Python scripts to parse, decrypt, and organize these stolen configurations.

Geographic distribution

The campaign’s targeting appears opportunistic rather than sector-specific, consistent with automated mass scanning for vulnerable appliances. However, certain patterns suggest organizational-level compromise where multiple FortiGate devices belonging to the same entity were accessed. Amazon Threat Intelligence observed clusters where contiguous IP blocks or shared non-standard management ports indicated managed service provider deployments or large organizational networks. Concentrations of compromised devices were observed across South Asia, Latin America, the Caribbean, West Africa, Northern Europe, and Southeast Asia, among other regions.

Custom tooling: AI-generated reconnaissance framework

Following VPN access to victim networks, the threat actor deploys a custom reconnaissance tool, with different versions written in both Go and Python. Analysis of the source code reveals clear indicators of AI-assisted development: redundant comments that merely restate function names, simplistic architecture with disproportionate investment in formatting over functionality, naive JSON parsing via string matching rather than proper deserialization, and compatibility shims for language built-ins with empty documentation stubs. While functional for the threat actor’s specific use case, the tooling lacks robustness and fails under edge cases—characteristics typical of AI-generated code used without significant refinement.

The tool automates the post-VPN reconnaissance workflow:

  1. Ingesting target networks from VPN routing tables
  2. Classifying networks by size
  3. Running service discovery using gogo, an open-source port scanner
  4. Automatically identifying SMB hosts and domain controllers
  5. Integrating vulnerability scanning using Nuclei, an open-source vulnerability scanner, against discovered HTTP services to produce prioritized target lists.

Post-exploitation methodology

Once inside victim networks, the threat actor follows a standard approach leveraging well-known open-source offensive tools.

Domain compromise: The threat actor’s operational documentation details the intended use of Meterpreter, an open-source post-exploitation toolkit, with the mimikatz module to perform DCSync attacks against domain controllers. This allowed the actor to extract NTLM password hashes from Active Directory. In confirmed compromises, the attacker obtained complete domain credential databases. In at least one case, the Domain Administrator account used a plaintext password that was either extracted from the FortiGate configuration through password reuse or was independently weak.

Lateral movement: Following domain compromise, the threat actor attempts to expand access through pass-the-hash/pass-the-ticket attacks against additional infrastructure, NTLM relay attacks using standard poisoning tools, and remote command execution on Windows hosts.

Backup infrastructure targeting: The threat actor specifically targeted Veeam Backup & Replication servers, deploying multiple tools for extracting credentials, including PowerShell scripts, compiled decryption tools, and exploitation attempts leveraging known Veeam vulnerabilities. Backup servers represent high-value targets because they typically store elevated credentials for backup operations, and compromising backup infrastructure positions an attacker to destroy recovery capabilities before deploying ransomware.

Limited exploitation success: The threat actor’s operational notes reference multiple CVEs across various targets (CVE-2019-7192, CVE-2023-27532, and CVE-2024-40711, among others). However, a critical finding from this analysis is that the threat actor largely failed when attempting to exploit anything beyond the most straightforward, automated attack paths. Their own documentation records repeated failures: targeted services were patched, required ports were closed, vulnerabilities didn’t apply to the target OS versions, . Their final operational assessment for one confirmed victim acknowledged that key infrastructure targets were “well-protected” with “no vulnerable exploitation vectors.”

AI as a force multiplier

Amazon Threat Intelligence analysis revealed that the actor uses at least two distinct commercial LLM providers throughout their operations.

AI-generated attack planning: The threat actor used AI to generate comprehensive attack methodologies complete with step-by-step exploitation instructions, expected success rates, time estimates, and prioritized task trees. These plans reference academic research on offensive AI agents, suggesting the actor follows emerging literature on AI-assisted penetration testing. The AI produces technically accurate command sequences, but the actor struggles to adapt when conditions differ from the plan. They cannot compile custom exploits, debug failed exploitation attempts, or creatively pivot when standard approaches fail.

Multi-model operational workflow: Amazon Threat Intelligence identified the actor using multiple AI services in complementary roles. One serves as the primary tool developer, attack planner, and operational assistant. A second is used as a supplementary attack planner when the actor needs help pivoting within a specific compromised network. In one observed instance, the actor submitted the complete internal topology of an active victim—IP addresses, hostnames, confirmed credentials, and identified services—and requested a step-by-step plan to compromise additional systems they could not access with their existing tools.

AI-generated tooling at scale: Beyond the reconnaissance framework, the actor’s infrastructure contains numerous scripts in multiple programming languages bearing hallmarks of AI generation, including configuration parsers, credential extraction tools, VPN connection automation, mass scanning orchestration, and result aggregation dashboards. The volume and variety of custom tooling would typically indicate a well-resourced development team. Instead, a single actor or very small group generated this entire toolkit through AI-assisted development.

Threat actor assessment

Based on comprehensive analysis, Amazon Threat Intelligence assesses this threat actor as follows:

  • Motivation: Suspected financially motivated, based on widespread, indiscriminate targeting and low sophistication
  • Language: Russian-speaking, based on extensive Russian-language operational documentation
  • Skill level: Low-to-medium baseline technical capability, significantly augmented by AI. The actor can run standard offensive tools and automate routine tasks but struggles with exploit compilation, custom development, and creative problem-solving during live operations
  • AI dependency: Extensive reliance across all operational phases. AI is used for tool development, attack planning, command generation, and operational reporting across multiple commercial LLM providers
  • Operational scale: Broad. Compromised devices across dozens of countries, with evidence of sustained operations over an extended period
  • Post-exploitation depth: Shallow. Repeated failures against hardened or non-standard targets, with a pattern of moving on rather than persisting when automated approaches fail
  • Operational security: Inadequate. Detailed operational plans, credentials, and victim data stored without encryption alongside tooling

Amazon’s response

Amazon Threat Intelligence remains committed to helping protect customers and the broader internet ecosystem by actively investigating and disrupting threat actors.

Upon discovering this campaign, Amazon Threat Intelligence took the following actions:

  • Shared actionable intelligence, including indicators of compromise, with relevant partners
  • Collaborated with industry partners to broaden visibility into the campaign and support coordinated defense efforts

Through these efforts, Amazon helped reduce the threat actor’s operational effectiveness and enabled organizations across multiple countries to take steps to disrupt the efficacy of the campaign.

Defending your organization

This campaign succeeded through a combination of exposed management interfaces, weak credentials, and single-factor authentication—all fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This underscores that strong security fundamentals are powerful defenses against AI-augmented threats. Organizations should review and implement the following.

1. FortiGate appliance audit

Organizations running FortiGate appliances should take immediate action:

  • Ensure management interfaces are not exposed to the internet. If remote administration is required, restrict access to known IP ranges and use a bastion host or out-of-band management network
  • Change all default and common credentials on FortiGate appliances, including administrative and VPN user accounts
  • Rotate all SSL-VPN user credentials, particularly for any appliance whose management interface was or may have been internet-accessible
  • Implement multi-factor authentication for all administrative and VPN access
  • Review FortiGate configurations for unauthorized administrative accounts or policy changes
  • Audit VPN connection logs for connections from unexpected geographic locations

2. Credential hygiene

Given the extraction of credentials from FortiGate configurations:

  • Audit for password reuse between FortiGate VPN credentials and Active Directory domain accounts
  • Implement multi-factor authentication for all VPN access
  • Enforce unique, complex passwords for all accounts, particularly Domain Administrator accounts
  • Review and rotate service account credentials, especially those used in backup infrastructure

3. Post-exploitation detection

Organizations that may have been affected should monitor for:

  • Unexpected DCSync operations (Event ID 4662 with replication-related GUIDs)
  • New scheduled tasks named to mimic legitimate Windows services
  • Unusual remote management connections from VPN address pools
  • LLMNR/NBT-NS poisoning artifacts in network traffic
  • Unauthorized access to backup credential stores
  • New accounts with names designed to blend with legitimate service accounts

4. Backup infrastructure hardening

The threat actor’s focus on backup infrastructure highlights the importance of:

  • Isolating backup servers from general network access
  • Patching backup software against known credential extraction vulnerabilities
  • Monitoring for unauthorized PowerShell module loading on backup servers
  • Implementing immutable backup copies that cannot be modified even with administrative access

AWS-specific recommendations

For organizations using AWS:

  • Enable Amazon GuardDuty for threat detection, including monitoring for unusual API calls and credential usage patterns
  • Use Amazon Inspector to automatically scan for software vulnerabilities and unintended network exposure
  • Use AWS Security Hub to maintain continuous visibility into your security posture
  • Use AWS Systems Manager Patch Manager to maintain patching compliance across EC2 instances running network appliances
  • Review IAM access patterns for signs of credential replay following any suspected network device compromise

Indicators of compromise (IOCs)

This campaign’s reliance on legitimate open-source tools—including Impacket, gogo, Nuclei, and others—means that traditional IOC-based detection has limited effectiveness. These tools are widely used by penetration testers and security professionals, and their presence alone is not indicative of compromise. Organizations should investigate context around matches, prioritizing behavioral detection (anomalous VPN authentication patterns, unexpected Active Directory replication, lateral movement from VPN address pools) over signature-based approaches.

IOC Value

IOC Type

First Seen

Last Seen

Annotation

212[.]11.64.250

IPv4

1/11/2026

2/18/2026

Threat actor infrastructure used for scanning and exploitation operations

185[.]196.11.225

IPv4

1/11/2026

2/18/2026

Threat actor infrastructure used for threat operations


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

CJ Moses

CJ Moses

CJ Moses is the CISO of Amazon Integrated Security. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon Integrated Security September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.

  •  
❌