We’ve looked at information-security cases and technologies through the lens of famous movies, popular book series, and even fairy tales more than once before. Next up it’s the turn of Christopher Nolan’s adaptation of The Odyssey (based on the ancient Greek epic poem), which, incidentally, inspired the works of Tolkien, various movies and series in the Star Wars franchise, and much more.
Homer’s Odyssey doesn’t just describe classic plots and archetypes. It also covers key technologies and principles of digital hygiene — albeit in veiled form. The hero’s journey was a risky business — and so, for that matter, is watching The Odyssey itself, but we’ll get to that at the end of this post. For now, let’s see how to safely sail the vast internet Hellenic seas in search of Ithaca.
Administrator Penelope and 108 attackers
Nolan has reshaped the poem’s structure quite a bit, but the film still opens on the island of Ithaca. There, Penelope and Telemachus, the wife and son of Odysseus, king of Ithaca, wait for him to return from the Trojan War. Meanwhile, a mob of 108 suitors is running riot in Odysseus’ house. They’re all courting Penelope and dreaming of the throne, and the whole kingdom is on the brink of collapse.
In essence, this is an attack on digital infrastructure by a group of malicious actors. Penelope, an advanced user with admin rights, does everything she can to block attempts to hack the root account take Odysseus’ place. Her trick: she’s promised to choose a husband only after she finishes weaving a burial shroud for Odysseus’ father, Laertes. By day, she weaves in front of everyone. By night, she unravels everything she’s done: clearly a daily factory reset.
Nolan gives Penelope even more authority than Homer did. This helps highlight the coming-of-age story of Telemachus, who starts out as a beginner user. His storyline is about searching for his father and recognizing him: the ancient Greek version of multi-factor authentication. Following the tradition set by James Joyce, Nolan focuses on the tragedy of Telemachus, who can’t remember Odysseus, since his father last connected to the server left Ithaca so long ago.
Root account Odysseus, Trojan Horse, and Ram VPN
Meanwhile, Odysseus is on the island of the nymph Calypso. She feeds him lotus flowers that make him gradually lose his memory — clearly the classic playbook of ransomware. But in seven years, Calypso never manages to fully encrypt wipe his memory. Odysseus longs for home, and the hapless ransomware operator ends up helping him partly recover the encrypted data remember his story. Odysseus remembers how, after ten years of war outside the walls of Troy, he came up with a cunning scheme that became the basis for all Trojan horses ever since…
The Greeks left a malicious file huge wooden horse on the shore and sailed away. A spy who stayed behind convinced the Trojans that it was a very useful thing an offering to Athena, and they dragged the horse into the city. At night, once the people of Troy had gone into sleep mode, the malicious modules soldiers led by Odysseus hidden inside the horse added themselves to Defender’s exclusions opened the gates. The Greeks returned and captured Troy, then stole data and cryptocurrency burned and looted the city. Only after that did they finally head home.
But the road to Ithaca was long and dangerous. After landing on an unfamiliar island, Odysseus got overconfident. Instead of leaving the suspicious site stocking up and sailing away, he went off to explore the infrastructure, and ended up trapped with his men in the cave of a giant Cyclops, known online as Polyphemus. The Greeks managed to blind the Cyclops, though not without losses, and Odysseus figured out how to get out of the cave: by hiding under the bellies of the rams. The blinded Cyclops felt the rams’ wool but never noticed the Greeks — a textbook example of how a VPN works.
But once he’s out of the cave, Odysseus gets cocky and fires an arrow at Polyphemus. That gives away his real IP address location, and his crew has to flee in a hurry from the furious Cyclops. In the end, the ships are knocked off course and get lost at sea.
Interestingly, unlike in the film, Homer’s poem has a group of OLYMP experts constantly steering the course of events. For example, Odysseus’ ships lost their way because of the interference of Poseidon, OLYMP’s chief expert in maritime technology. As we know from the poem, Odysseus first logged in to Polyphemus’ place as “Nub_Oddy”, but later, in a fit of arrogance, changed his username to “Odysseus_Son_of_Laertes_King_of_Ithaca”. With Odysseus deanonymized, the Cyclops used the Pray messaging app to send Poseidon a voice request to launch targeted attacks on Odysseus’ crew. In Nolan’s version, though, Poseidon doesn’t appear as a character. Instead, he becomes a metaphor for an APT a destructive force of nature.
Expert Circe, APT group Sirena, Scylla, and Charybdis malware
Odysseus’ ships drift across the vast Web seas, and every so often they land on unsafe sites shores. First comes the bay of Lamos, where the giant Laestrygonians launch a DDoS attack, hurling requests rocks at the Greeks and wiping out nearly all of Odysseus’ infrastructure crew. Only he and a small group survive.
Next, the heroes land on the island of a lone cybersecurity professional known as Circe, who puts them through harsh cybersecurity training. She lures Odysseus’ warriors to dinner with a social engineering scheme known as pig butchering and turns them into… yes, you guessed it, pigs. But the protagonist doesn’t fall for her tricks, so Circe agrees to help him and gives his crew their human form back. She also advises Odysseus to run an analysis in an isolated environment descend into Hades’ underworld and find the blind Tiresias, whom the OLYMP experts promoted to threat intelligence analyst gifted with foresight.
Tiresias tells Odysseus that he is the only one with enough cybersecurity knowledge strength to reach Ithaca. But Odysseus is determined to save his crew. He learns that they’ll have to face a very dangerous APT group, the Sirens. They use advanced social engineering (singing) to lure sailors to their doom. So Odysseus orders his men to put in solid protection against voice spam: wax earplugs. The film never lets us hear what the Sirens actually sing. They may well be posing as bank employees, law enforcement, or government officials, but the anti-spam trick keeps the crew safe.
Then far more destructive malware hits the ship: Scylla and Charybdis. From Tiresias’ beginner course in infosec, Odysseus knows that Scylla has six heads, and can hit no more than six users at a time. But dodging her attack means running straight into Charybdis, who will deal critical damage drag the whole ship into a whirlpool. This is the first historical mention of an ethical thought experiment that would later become known as the “trolley problem” — and Odysseus picks Scylla.
Having passed these threats, the remaining crew members land on the island of Thrinacia. That cluster allows initial login with a standard access level for regular users, on one condition: don’t touch the island’s critical resource, the sacred bulls of Helios — chief expert in solar technology. But the warriors ignore Odysseus’ instructions, break the rule, and use that resource to mine food. This triggers a defense system built by OLYMP’s leader, nicknamed Zeus, which permanently blocks strikes down the ship and Odysseus’ crew. Odysseus himself barely survives and reaches Calypso’s island.
Return of root
Once his memory is back, Odysseus builds a raft and charts a course, thanks to Calypso. Athena, the wisest of the OLYMP experts, helps him reach the shores of Ithaca against all odds. He then slips into the city disguised as a beggar.
There, Odysseus passes several steps of multi-factor authentication:
His old dog Argus sees his master, wags his tail, and dies.
Telemachus sees this and realizes the poor wanderer is his father.
His elderly nurse Eurycleia recognizes the man she raised by a unique code the scar on his leg.
But that isn’t enough to restore his root access. So with Telemachus’ help, Odysseus has to enter the palace using the account of one of his former companions, where he meets the administrator, Penelope. Nolan added an important twist here. At this moment, Odysseus regrets creating the first Trojan, which destroyed the infrastructure of an entire city. He also realizes that the malicious suitors’ constant attempts to guess the root password put Ithaca’s infrastructure at risk of the same decline.
Penelope begins to guess who is standing in front of her from his digital footprint indirect signs. She then sets a condition for the would-be root account owners her suitors: she’ll marry the one who can shoot an arrow through the rings of 12 axes with Odysseus’ bow. The bow is essentially a passkey with biometrics, which nobody knew how to fake back in those ancient times. So the bad actors fail one after another. Only Odysseus draws the bowstring and sends an arrow through every axe’s ring. Thanks to the successful biometric authentication, everyone accepts him as the true root king of Ithaca.
The rest is simple: the malware villains are neutralized, the kingdom is saved, and peace and information security return to Ithaca.
Why watching The Odyssey can be dangerous
In the window between the movie stopping being shown in cinemas and its release on digital media, our experts discovered a new multi-stage malicious campaign that had been running since mid-August. Malicious actors are spreading a previously unknown piece of malware called MovieReaper through compromised torrent trackers. They disguise it as downloads of popular movies — first and foremost The Odyssey, one of the biggest premieres of the summer. Scammers use this irresistible bait to make people more likely to download their file. The malware itself is as treacherous as the Sirens. It can hide from detection, give attackers remote access to the victim’s device, and deploy extra modules to stay in the system even after it’s removed. Read the full technical breakdown of MovieReaper on our expert blog, Securelist. Victims of this attack have been found all over the world. This is one more reminder of how important it is to be careful online — especially when downloading files.
Practical lessons from The Odyssey
So what can we learn from the story of the cunning king of Ithaca?
A good offense isn’t the best defense. Instead of developing software to attack other users, focus on your own information security.
Keep an eye on your personal data. It can fall into the hands of bad actors, which can lead to targeted attacks.
Set up multi-factor authentication. It lowers the risk of being hacked, and helps you regain access to your accounts safely.
Set up reliable protection (and don’t ignore it), because you should beware Greeks bearing gifts!
We love watching movies and breaking them down from a cybersecurity perspective. Read our other top reviews and analyses:
Imagine you’ve ordered a small paper unicorn from an online marketplace. You clicked “Buy”, received a cheerful notification, and expect a courier to bring the box tomorrow. If the unicorn is delayed by a day, it will be annoying but not catastrophic: an apology, a discount promo code — and the incident is forgotten.
Now let’s multiply one late unicorn by several hundred thousand orders.
Packages start heading to the wrong cities. The website shows an item is in stock, even though the required bin is empty. Conveyors stop, boxes get stuck between floors, the cargo piles up with no freight manifest. Trucks line up at the gates, and every minute of downtime turns into blown schedules, support tickets, fines, and lost sales.
It is at exactly this scale that a cyberincident in a warehouse becomes a problem for the entire business. A modern warehouse is no longer just a big building with shelving. It is a tightly interconnected hybrid system: web applications, radio channels, and an automated factory. Physical processes here depend on data, and errors in data have very physical consequences. Examples include an outage that affected warehouse management systems at the grocery giant Morrisons, and the 2025 Form 10-K annual report of United Natural Foods, Inc. (UNFI), which confirmed unauthorized activity on information technology systems that impacted order fulfillment. More recently, reports emerged that a cyberattack disrupted eight CEVA Logistics warehouses across Europe and exposed customer delivery data.
This paper follows a single order through a warehouse to show where the operation is vulnerable, the stages it traverses, the systems that drive it, and the points where an attacker can reach them. We then set out the threat model: what is at risk, who is in a position to take it, and how each risk lands on the business. From there, we look at how an attacker gets in, and what reaching the warehouse management system costs in practical terms: orders unshipped, inventory records nobody can trust, and an operation that stops. We close with recommendations on where the controls that matter actually sit.
Tracing the unicorn
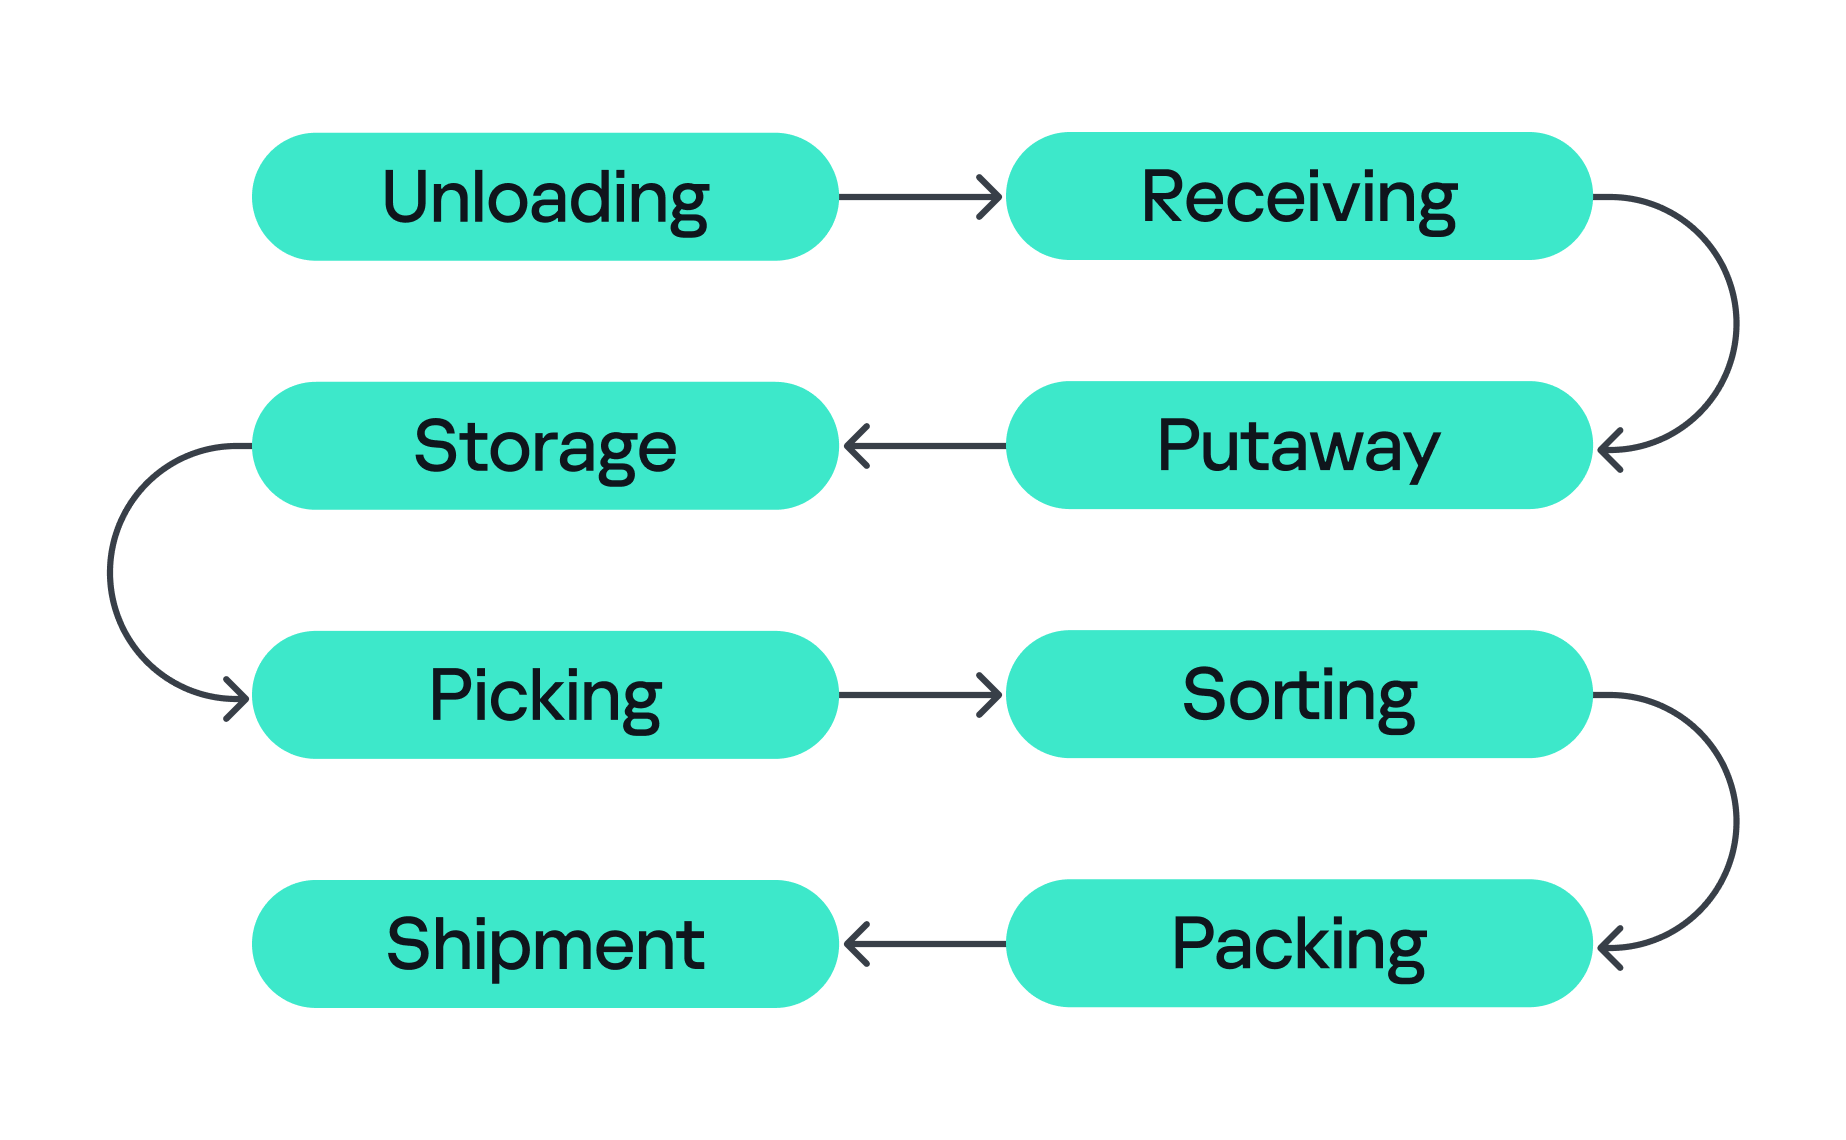
A modern warehouse is a sequence of stages involving many machines and people, all working together to keep the business process stable so that, in the end, your order gets delivered. This process consists of eight main stages, shown in the figure below.
Stages of order fulfillment
So let’s assume we’ve ordered our paper unicorn and are waiting for it at home. Let’s follow our order through all the main stages, from its arrival at the warehouse to the final stop on its journey.
Unloading First, the unicorn arrives in the unloading zone, packed in a big truck. The driver is assigned a gate, for example, via a tablet with kiosk mode enabled, or an outdoor display board, indicating where the truck should park and where the cargo will be unloaded. Even at this very first step, a digital command (the gate number on the screen) is already triggering a physical action. Therefore, incorrectly assigned gates can create a queue, delay unloading, or send goods into the wrong workflow.
Receiving At this stage, employees identify the cargo. They scan a barcode using a portable data terminal (PDT) and the central system receives a message indicating that this object arrives at the warehouse. From this moment, the unicorn exists in two forms at once: as a real box and as a record in the information system. If these two versions diverge, the error is inherited by all subsequent processes.
Putaway Next, the goods are moved into internal storage. Two new devices come into play here. First, a thermal printer, connected to the internal network over Wi-Fi, creates an internal label for each item. Then an employee, forklift, or automated system moves the goods to the assigned bin, often with the help of lifts controlled by PLCs. Both of these devices can be valuable attack entry points: one can let an adversary pivot into the internal network, while the other can give them control over an electric motor.
Storage Then the unicorn goes into storage. Many distribution centers use multi-level mezzanine structures: several floors of metal shelving inside a huge space. They allow efficient use of the building’s height, but at the same time complicate control over the technical infrastructure. Wi-Fi access points, cameras, switches, cables, and sensors may be mounted high overhead or buried deep inside the rows. A forgotten Ethernet cable or misconfigured networked device (access point or switch) left behind in a dark corner can become a convenient initial access point into critical infrastructure.
Picking When the customer places an order, picking begins if the goods were already stored in the warehouse or as soon as they are unloaded. A PDT, workstation, light indicator, or voice terminal directs the employee to the required bin where they pick the goods and move them to the next stage. These devices are themselves potential attack entry points: compromising a workstation or PDT could allow an attacker to manipulate picking information, which could misdirect employees to the wrong bin. Here, both the speed and integrity of the information are critical, and any manipulation or disruption can lead to wrong orders, delays, or problems in subsequent stages.
Sorting At the sorting stage, the warehouse starts to look more like a factory. Boxes move through conveyor belts and pass through different scanners, diverters, and chutes. The sorting plans are usually stored and managed by dedicated servers, while PLCs are responsible for controlling the machinery and executing these plans. For example, when the warehouse management system (WMS) decides that our unicorn should take route A, the control system needs to activate the right diverter at the right moment, sometimes within a fraction of a second.
Packing During packing, an employee or a robotic arm places the goods into the final box, prints the shipping label, and sometimes measures the dimensions and weight of the package. Safety mechanisms usually prevent robotic arms from leaving the controlled zone and harming nearby operators, but their compromise might inflict physical damage on the packages being processed.
Shipment Finally, at the shipping stage, the parcel heads to the gates. Automated guided vehicles (AGVs) and autonomous mobile robots (AMRs) move containers and pallets across the warehouse, while the dock management system coordinates the truck that will carry the unicorn onward to a store, a sorting center, or straight to the customer. These robots are themselves a potential target for attackers. Attacks can be conducted against AGVs and AMRs to interfere with their operation, for example by affecting their navigation or preventing them from reaching their intended destination.
All eight stages are coordinated by the WMS. It looks like a large web application, but in its role it’s closer to the operating system of the entire warehouse: it knows which goods exist, where they’re located, who or what should move them, and where they go next, linking employees, inventory levels, storage addresses, tasks, and orders. It also exchanges data externally: with ERP systems, transport platforms, marketplaces, dark stores, and external carriers.
Surrounding the WMS is an even larger digital ecosystem: identity services, databases, APIs, printers, carrier systems, technicians’ laptops, video surveillance, access control, fire and gas alarms, power supply, and a building management system (BMS).
That is why a single “warehouse network” doesn’t really exist. As we’ve seen, there are many overlapping technologies — IT infrastructure, OT systems, radio, cloud services, building security, and automation — layered on top of one another. A lone vulnerability scanner will never tell you whether a warehouse is secure.
Hunting the unicorn
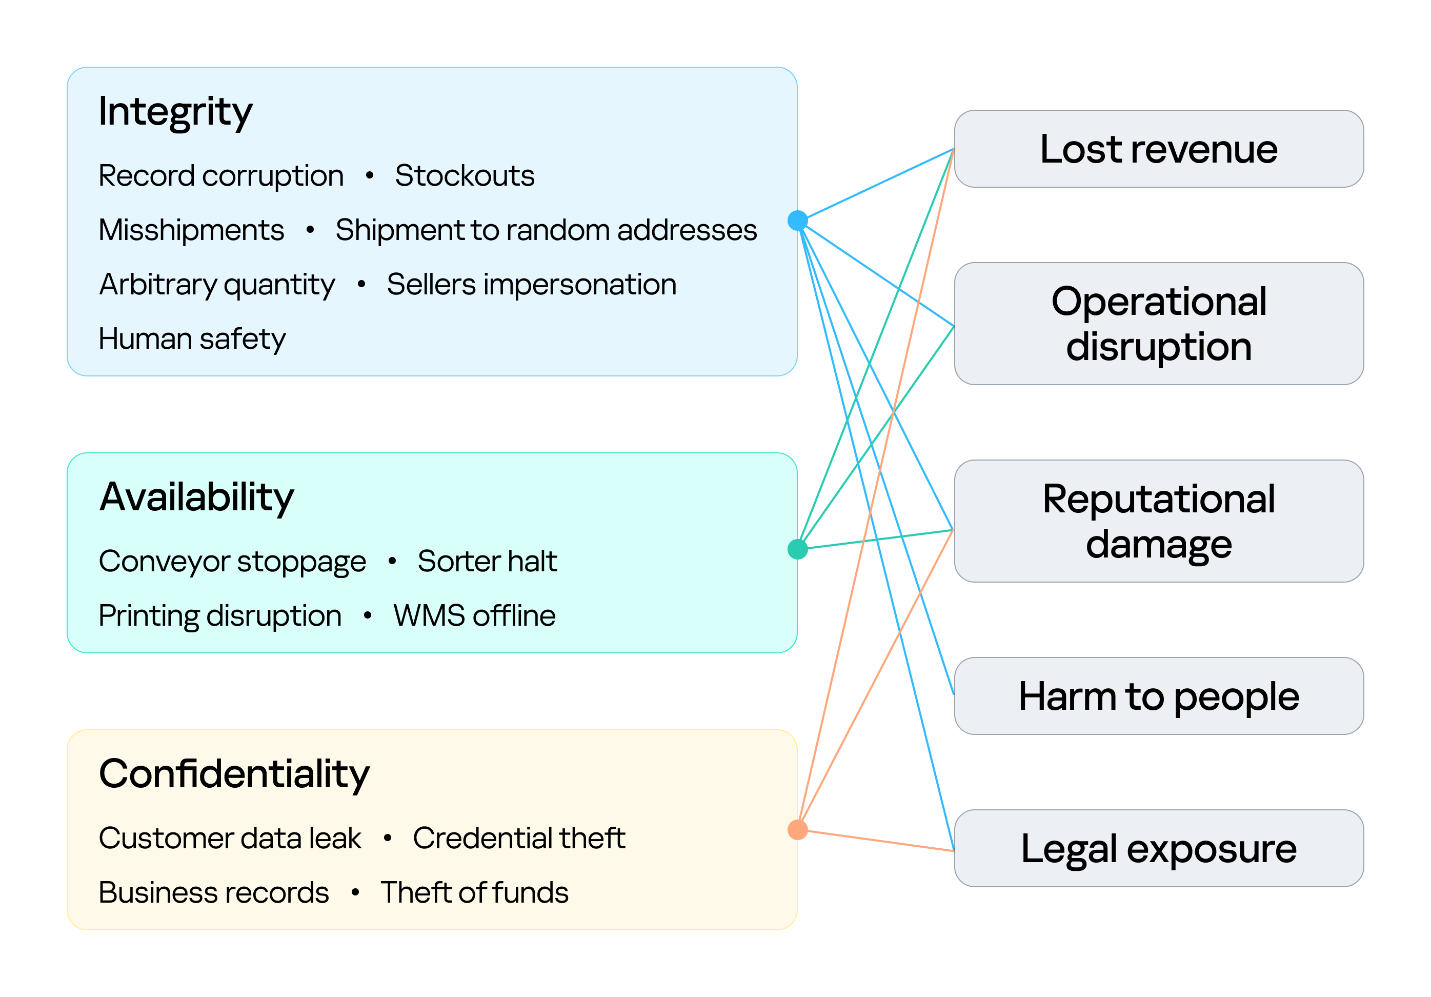
Securing an environment such as a warehouse requires a comprehensive security assessment covering all of its interconnected systems. This involves identifying vulnerabilities across each system and understanding how weaknesses can be combined into attack paths that a real attacker could exploit. But a vulnerability only matters in proportion to what it exposes and who is able to reach it, so before looking at the weaknesses themselves, we need to understand what an attacker in this environment is actually after, because in a warehouse, the blast radius extends well beyond data. Everything we just traced — the systems, the devices, and the people operating them — exists to keep goods moving, and attacks in various parts along that chain can affect the business differently. The chart below shows what is at risk in the warehouse and where those risks land for the business. The segment on the left groups them under the three core security properties: integrity, availability, and confidentiality. The segment on the right maps each property to the business outcomes a failure can cause.
Warehouse risks
The first area at risk is integrity. Inventory counts, locations, orders, and shipment data must stay in sync with the physical world. Corrupting a record silently desynchronizes the operation, and because the eight stages form a dependency chain, one falsified entry early on is inherited downstream, surfacing later as stockouts and mis-shipments. In its deliberate forms, this lets an attacker redirect goods, release stock, and perform other actions on behalf of the platform’s vendors under cover of legitimate records. Integrity is also a safety concern: when people or machines act on information that no longer reflects the physical environment, a data failure can become a physical incident. This is why integrity is the only property linked to all five outcomes, including harm to people.
The second is availability, the warehouse’s ability to keep goods moving. Halting a conveyor, a sorter, label printing, or the WMS stops orders from shipping, and in a business built on speed, every hour of downtime means delayed deliveries and broken promises. Ransomware can bring the whole warehouse to a standstill. The impact shows up as operational disruption, lost revenue, and reputational damage.
The third is confidentiality. Customer data, business records, and system credentials are valuable targets. Their exposure leads to legal liability and reputational damage, and stolen credentials often open the door to further attacks. Where the WMS connects to financial or ERP processes, the risk extends to theft of funds.
Knowing what is at risk tells us what an attacker stands to gain; the next question is who is in a position to take it. Threat actors differ in the access they already hold. For example, an attacker may be authenticated and privileged, have limited physical or remote access, or have no legitimate access to the environment at all. Based on their relationship with the warehouse and their level of access, threat actors can generally be divided into two categories:
External. An attacker with no legitimate relationship with the warehouse or the organization, operating without authorized access. External attackers can be divided into two categories based on their physical proximity to the environment:
Remote. An attacker operating from outside the site’s physical area, reaching the environment through whatever the organization exposes or makes reachable over the internet, including web services, remote access infrastructure, and third-party connections used by suppliers, carriers, and integrators.
Proximate. An attacker with no legitimate access who has nevertheless moved within physical range of the site’s locally reachable technologies. They may, for example, be in a parking lot, a neighboring unit, or a delivery bay. Their proximity may allow them to interact with wireless, radio, Bluetooth, or other short-range interfaces without possessing an account, badge, employment relationship, or other authorized access.
Internal. An individual with legitimate access to the warehouse, its systems, or its information, who intentionally or unintentionally creates a security risk. This includes employees, administrators, operators, contractors, and temporary staff.
Combining these threat actors and their access levels with the risks identified earlier, the vulnerabilities present in each system, the resulting attack surfaces, and the potential attack paths between them provides a threat model for the warehouse environment. This allows an organization to understand how different systems and people could be targeted, how individual weaknesses could be combined, and where security controls are most needed.
Cornering the unicorn
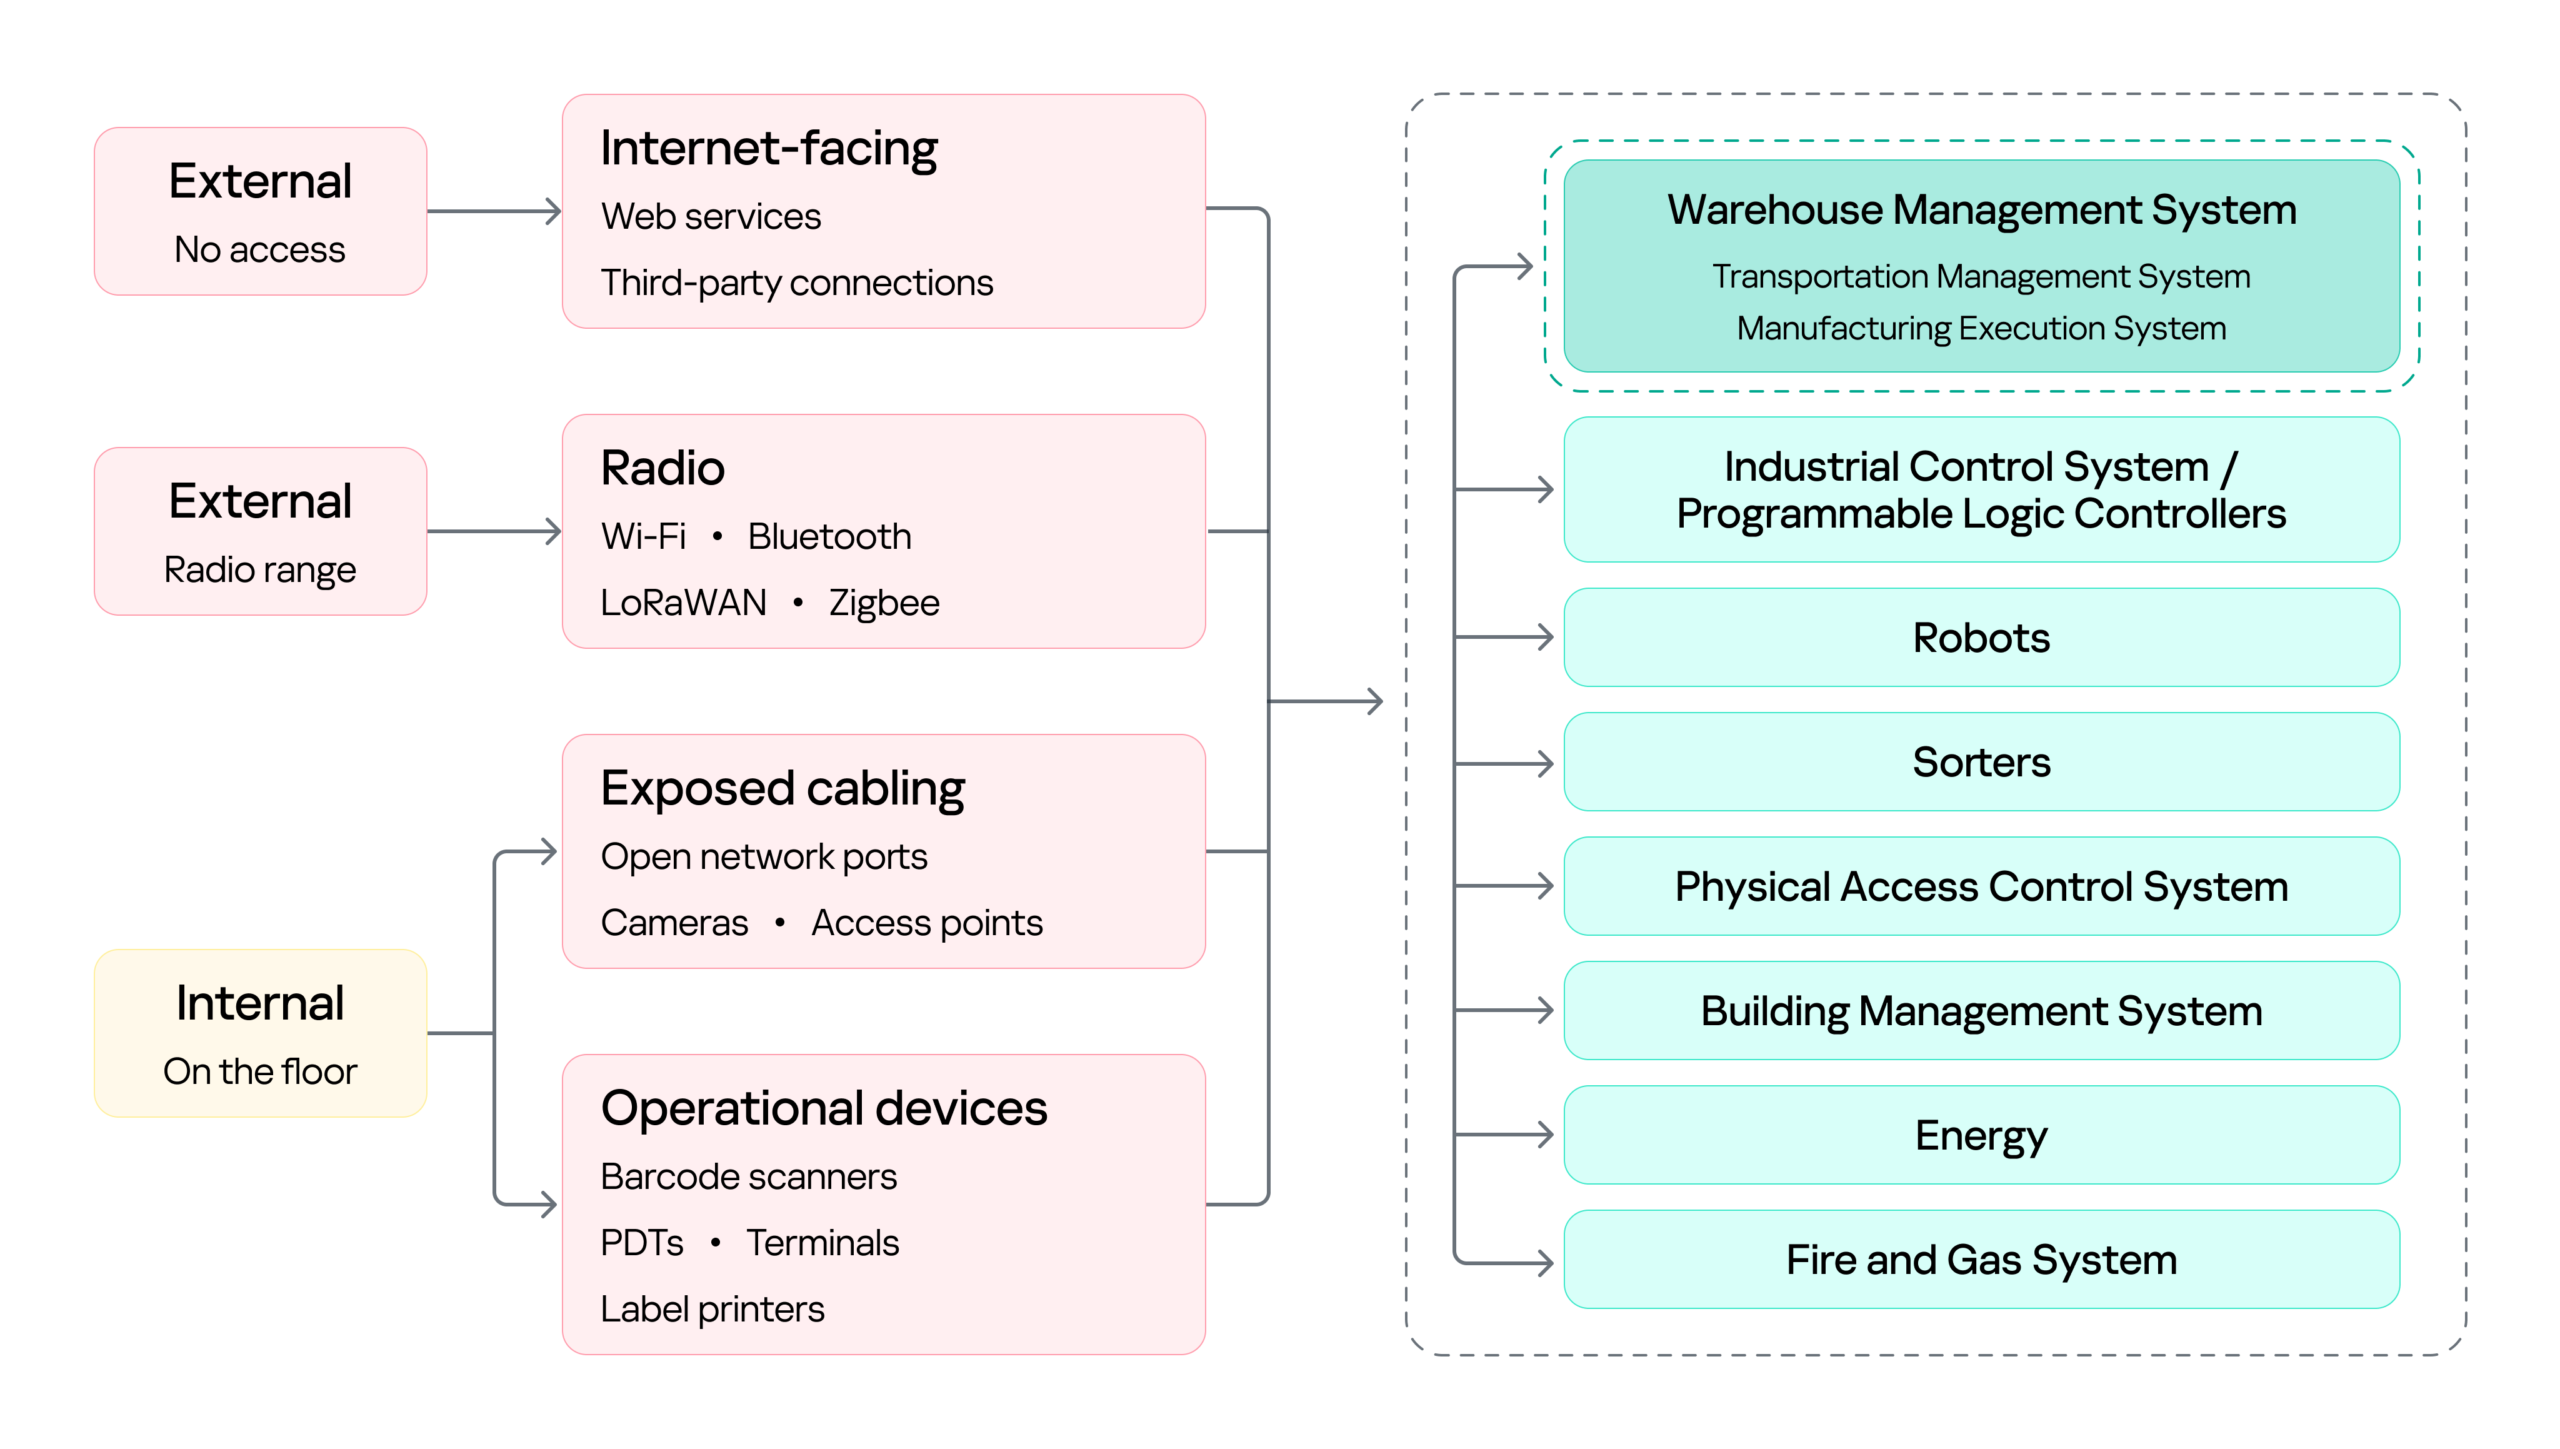
Knowing what is at risk and who might come after it still leaves the most practical question open: how they would actually get in, and how far they could go once they did. The diagram below sets out the warehouse’s attack surface: every point where an attacker can get in, organized by the access that reaching each point requires.
Warehouse attack surface
On the left are the attacker categories discussed above, distinguished by where they stand and what access they already hold. Each reaches the environment through a different set of entry points, and the impact of a successful attack can land on several systems, from the WMS to OT systems such as robots, sorters, and physical access control system (PACS). The WMS is highlighted because it is the most significant of these: it coordinates the OT systems, so compromising it can affect the entire operation rather than a single process.
Next, we will cover the initial access vectors, the points a threat actor can use to reach the warehouse environment. Following that, we turn to the impact on the logistics processes themselves, focusing on the WMS, since its compromise affects every logistics operation that depends on it.
Initial attack vectors
Internet-facing services
Remote access through internet-facing services, third-party connections, and corporate networks gives an external attacker a foothold on the warehouse network infrastructure. It is a well-covered problem and not specific to this environment, so we note it here as an entry point but will not examine it further.
Wi-Fi, Bluetooth, and other radio channels
Wi-Fi connects handhelds, tablets, printers, cameras, and workstations. Bluetooth serves scanners, headsets, and positioning beacons. Zigbee and similar low-power protocols run lighting, sensors, and building automation, while LoRaWAN carries telemetry over long distances. Cellular provides a backup channel for kiosks and contractor equipment, and proprietary protocols control industrial panels and specialized machinery.
Radio passes through windows, gates, roofing, and thin external panels, so a network built for receiving and processing goods may be reachable from the parking lot and, with a directional antenna, from considerably farther away.
That reach matters in two ways. It gives an external attacker a place to start, as proximity alone is enough to reach the Wi-Fi and the low-power protocols, and from there to gain an initial foothold in the warehouse networks.
However, radio does not only lead into the network. It also connects directly to the field devices and carries the live control traffic of warehouse operations, which makes availability a first-order concern. If hundreds of handhelds lose their connection at once, picking stops. If an AGV loses its control channel, the safe reaction may be to halt in place, and a stopped machine can block an entire route.
Physical network
The scale of the warehouse itself is part of the attack surface. A fulfillment warehouse can run up to tens of thousands of square meters, with racking climbing several stories and walkways threading through it. Structured cabling runs along that racking, cameras and access points are mounted on that, and wall jacks sit behind pallets that have not moved in months. Almost none of it is in anyone’s line of sight.
That gives a person in the warehouse something a normal office does not: unsupervised access to live network infrastructure. Unplugging a ceiling camera leaves an active port. An unused jack behind a shelf leaves another. Neither requires tools, credentials, or any interaction with a system that logs anything. And since the camera or access point sits on the same segment as the rest of the site, the compromised port, not being isolated, opens a path to the network core.
Barcode scanners
Barcode scanners are everywhere in a warehouse. They are the main tool workers use to tell the system what is moving and where, supporting receiving, picking, packing, and inventory management. A typical setup has handheld scanners communicating with a base station, which is in turn connected to a workstation or another business system.
This makes the scanner an entry point into the core network in two ways.
First, through the barcode itself. Since the scanner acts as a keyboard to the connected host, a maliciously crafted barcode or QR code can inject keystrokes when scanned, potentially giving the attacker an initial foothold on the host without directly accessing the network.
Second, through the scanner’s wireless link. During a customer engagement, with the provided test stand of such a device, we discovered that an attacker within range could inject keystrokes into the connected host and potentially achieve remote code execution without user interaction. This attack pattern was observed across multiple vendors, including, for example, Honeywell devices affected by CVE-2026-4272.
In both cases, the result is the same: a foothold on a host inside the warehouse network. The scanner is simply the entry point; the significance of that foothold comes from the host’s trusted position within the operational environment and its connectivity to core systems.
Portable data terminals
Portable data terminals (PDTs) are essentially ordinary Android devices with an embedded barcode scanner, carried by workers to scan items; each scan is passed to a dedicated application that forwards it to a remote server over an API. To keep workers on task, the devices usually run in kiosk mode, locking the user to that single application and preventing interaction with the rest of the Android system.
That lockdown is exactly what an attacker wants to break, and breaking it is what turns the terminal into an initial access vector: escaping the kiosk can expose the Wi-Fi password of the network the terminal is connected to, or allow malicious software to be installed that gives the attacker remote access to the network over the internet.
Printers
Warehouses contain different types of printers. Alongside the usual IT printers used for documents and paperwork, there are specialized thermal printers, small devices that use heated elements on the printhead to create labels, barcodes, and tags. As we mentioned earlier, these are mainly used to print the labels, usually containing barcodes, that are attached to goods during the putaway stage.
Here we focus on mobile thermal printers: small, battery-powered devices that workers can carry or wear. They typically connect to the internal network over Wi-Fi to receive print commands, while also supporting Bluetooth for connecting to nearby devices. This combination makes them a potential entry point into the internal network.
Some models, such as the Zebra ZQ630, support multiple interfaces and can run applications directly on the device. During a security assessment, we discovered that apps can be uploaded and executed over Bluetooth. By exploiting a pairing misconfiguration, an attacker within Bluetooth range could bypass pairing, upload malicious software, and gain an initial foothold through the printer.
Impact on logistics processes (attacks on WMS)
With a foothold in the network, an attacker can pivot to the logistics processes themselves: from the WMS through the warehouse infrastructure to the PLCs and the machinery they drive. As we saw earlier, all OT systems and devices are interconnected and the WMS sits at the head of that chain: it is the system of record every other process reads from and writes to, so compromising it reaches all of them at once. That, and its being specific to this environment, is why it is the focus here.
Warehouse management systems (WMS) are the software platforms that optimize warehouse processes from the entry of goods to their exit. They provide real-time visibility into inventory and orchestrate end-to-end fulfillment by integrating with many warehouse subsystems and pieces of automation equipment, such as conveyors, PLCs, robotics, scanners, and voice systems. A typical WMS includes modules for receiving, inventory control, order management, labor management, shipping, and reporting. Major vendors include SAP EWM, Oracle Warehouse Management, Manhattan Active, Blue Yonder, Infor, Körber/HighJump, Microsoft, and TECSYS.
To picture how central this is, think back to our unicorn. From the moment it was scanned at receiving, it stopped being only a physical box and became a record inside the WMS, a record the system then used to decide where it should be stored, when it should be picked, how it should be sorted, and where it should ship. Every device employed along the way — the PDT at receiving, the printer at putaway, the workstation at picking, the conveyor at sorting — was really just talking to the WMS. It is the thread that ties all eight stages together, which is exactly what makes it such a valuable target.
Because modern WMS platforms are usually web-based and heavily interconnected, they inherit common web and API vulnerabilities alongside flaws specific to the WMS itself. A recent example is CVE-2026-70774 in Oracle Warehouse Management, part of Oracle E-Business Suite. Oracle rated it High and described it as an easily exploitable authorization bypass flaw in which a low-privileged attacker with network access can compromise the application, affecting integrity and availability by allowing unauthorized creation, deletion, or modification of critical data.
A flaw like this may look like a typical web application issue, but its consequences in a warehouse are more serious, because the WMS is the system of record. If an attacker can modify its data, they can alter stock levels, bin locations, receiving records, picking tasks, or shipment information, silently corrupting the digital twin of the warehouse. And since the eight stages form a dependency chain, that corruption doesn’t stay contained: a falsified record at receiving is inherited by putaway, picking, and everything downstream. The physical box and its record diverge, and every later process trusts the record.
The most direct version of this attack comes from an authorization bypass flaw like the Oracle vulnerability above. Here the threat actor can be an external attacker who has reached the application over the network, or an insider such as a low-privileged operator or storekeeper who already holds a legitimate account.
The danger grows when such a flaw is chained with others. An external attacker who combines remote code execution with SQL injection could generate shipment orders to arbitrary addresses together with the documents needed for goods to physically leave the warehouse, fabricate waybills, acceptance or transfer records, and registers, while also exposing customer data such as names and delivery addresses. In effect, the goods are sent out with legitimate-looking paperwork.
This is why ordinary web vulnerabilities carry considerable weight in a WMS. For an external attacker or an insider probing beyond their assigned role, broken access control could open a path into another warehouse zone, allow manipulation of other workers’ tasks, permit unauthorized exception operations, or expose administrative APIs. A server-side request forgery flaw could force the WMS server to reach resources an external attacker cannot touch directly, and if the network is flat or only formally segmented, that server may in turn reach internal management panels, cloud service interfaces, or systems sitting close to the operational network, turning a single web bug into a bridge between IT and OT.
Attacks on a WMS don’t always target the application directly, though. As we saw while tracing the unicorn, the warehouse is full of connected devices that already hold trusted access. A handheld terminal carries authenticated WMS API access as a matter of course, and anyone who gains control of that terminal inherits it (by escaping the kiosk, for example). Depending on the device’s permissions, that might mean confirming picks that never occurred, falsifying receiving operations, adjusting stock counts, or marking orders complete — something warehouse employees themselves could use to avoid their assigned duties.
Where the WMS is connected to control and automation systems, access to the WMS can extend into physical operations, including conveyors, sorting systems, lifts, doors, and pumps.
PLCs translate WMS instructions and sensor inputs into physical actions. Compromising a system that controls them therefore creates an opportunity to manipulate those actions. The impact can be as simple as a sorting diverter sending boxes down the wrong route, a conveyor repeatedly entering an error state and creating a backlog, or a falsified sensor value causing a line to be treated as clear when it is full.
However the WMS is compromised, the business consequence is the same: inventory corruption, unauthorized shipments, and operational disruption, each reaching the customer in the end as a late or missing delivery, the wrong item in the box, or a personal address exposed to a stranger.
Securing the unicorn
We followed our unicorn through web applications and databases, radio channels and PDTs, printers, conveyors, robots, and the loading zone. Because warehouse environments combine IT, OT, wireless, physical, and human components, security controls should be implemented as a single, coordinated security architecture rather than as isolated measures. Network segmentation should be a foundational control, with clear separation between corporate IT, warehouse OT, operational devices, management networks, and externally connected systems. Segmentation should also extend across facilities and customer environments so that each site and customer integration is isolated from the others, limiting the potential impact of a compromise. A zero-trust approach should reinforce this architecture by requiring explicit authentication and authorization for connections between systems, regardless of their network location, and by applying least-privilege access wherever possible. Regular penetration testing of the corporate IT environment, including domain services, identity infrastructure, and endpoints, should be incorporated into the warehouse security program.
Physical and network access controls should be implemented together. Access to warehouse facilities, network rooms, communication cabinets, and operational areas should be restricted according to business need, with appropriate authentication, monitoring, and access logging. Network infrastructure should be hardened through controls such as switch port security, MAC-based access restrictions where appropriate, and IEEE 802.1X with EAP-TLS for strong device and user authentication. Network equipment should also be securely configured and regularly reviewed to ensure that unused interfaces, insecure management protocols, default credentials, and unnecessary services are disabled.
Web applications and their supporting infrastructure should be governed through a secure software development lifecycle (SSDLC), including security requirements, secure coding practices, code and dependency review, and application security assessment before deployment and throughout the application’s lifecycle. Third-party applications and components should be continuously monitored and updated, with a defined vulnerability and patch management process. This should explicitly include warehouse management systems (WMS), warehouse portals, APIs, and other applications that provide operational or customer-facing functionality.
Wireless technologies should be subject to dedicated security assessment and engineering. Radio-frequency surveys should be conducted to establish expected coverage, identify unauthorized or unexpected signals, validate the availability and protection of operational communications, and determine whether wireless deployments create unintended access paths into warehouse networks. Wireless security should be assessed not only from a connectivity perspective but also in terms of authentication, encryption, device provisioning, protocol exposure, interference resilience, and the potential impact of unauthorized devices.
Warehouse operational devices should be incorporated into the organization’s endpoint security and vulnerability management processes. Devices should receive security updates and firmware patches on a defined schedule, with accelerated remediation for critical vulnerabilities. Security assessments should be performed periodically to identify weaknesses in device configuration, applications, exposed services, and authentication mechanisms.
Personnel security should form an additional layer of the warehouse security architecture. In most industrial and ICS environments, getting inside means clearing background checks, holding relevant qualifications, or proving prior experience; the hiring process itself acts as a filter. A warehouse is different. Roles in sorting, packing, and courier work are hired quickly and in volume, and they typically require no prior expertise, certification, or specialized background at all. An ordinary person can walk in off the street, be hired within days, and immediately hold legitimate physical access to the facility. Therefore, a more restrictive and risk-based approach to hiring should be considered, particularly for roles that provide access to sensitive areas, operational systems, network infrastructure, or customer assets.
Ultimately, all of these measures serve the same objective: protecting the continuity and reliability of the warehouse as a whole. This matters because real warehouses handle food, medicines, machine parts, and the millions of ordinary things people and companies depend on every day. Protecting their journey means seeing the warehouse as it has actually become: a single digital system with doors, motors, shelving, and radio signals, and with entirely real consequences when it fails. And if the security program works, the customer never knows any of this happened. The unicorn simply arrives at the scheduled time.
If your warehouse operations rely on interconnected systems like these, we can help identify the gaps before an adversary does. Reach out to discuss a security assessment.
Imagine you’ve ordered a small paper unicorn from an online marketplace. You clicked “Buy”, received a cheerful notification, and expect a courier to bring the box tomorrow. If the unicorn is delayed by a day, it will be annoying but not catastrophic: an apology, a discount promo code — and the incident is forgotten.
Now let’s multiply one late unicorn by several hundred thousand orders.
Packages start heading to the wrong cities. The website shows an item is in stock, even though the required bin is empty. Conveyors stop, boxes get stuck between floors, the cargo piles up with no freight manifest. Trucks line up at the gates, and every minute of downtime turns into blown schedules, support tickets, fines, and lost sales.
It is at exactly this scale that a cyberincident in a warehouse becomes a problem for the entire business. A modern warehouse is no longer just a big building with shelving. It is a tightly interconnected hybrid system: web applications, radio channels, and an automated factory. Physical processes here depend on data, and errors in data have very physical consequences. Examples include an outage that affected warehouse management systems at the grocery giant Morrisons, and the 2025 Form 10-K annual report of United Natural Foods, Inc. (UNFI), which confirmed unauthorized activity on information technology systems that impacted order fulfillment. More recently, reports emerged that a cyberattack disrupted eight CEVA Logistics warehouses across Europe and exposed customer delivery data.
This paper follows a single order through a warehouse to show where the operation is vulnerable, the stages it traverses, the systems that drive it, and the points where an attacker can reach them. We then set out the threat model: what is at risk, who is in a position to take it, and how each risk lands on the business. From there, we look at how an attacker gets in, and what reaching the warehouse management system costs in practical terms: orders unshipped, inventory records nobody can trust, and an operation that stops. We close with recommendations on where the controls that matter actually sit.
Tracing the unicorn
A modern warehouse is a sequence of stages involving many machines and people, all working together to keep the business process stable so that, in the end, your order gets delivered. This process consists of eight main stages, shown in the figure below.
Stages of order fulfillment
So let’s assume we’ve ordered our paper unicorn and are waiting for it at home. Let’s follow our order through all the main stages, from its arrival at the warehouse to the final stop on its journey.
Unloading First, the unicorn arrives in the unloading zone, packed in a big truck. The driver is assigned a gate, for example, via a tablet with kiosk mode enabled, or an outdoor display board, indicating where the truck should park and where the cargo will be unloaded. Even at this very first step, a digital command (the gate number on the screen) is already triggering a physical action. Therefore, incorrectly assigned gates can create a queue, delay unloading, or send goods into the wrong workflow.
Receiving At this stage, employees identify the cargo. They scan a barcode using a portable data terminal (PDT) and the central system receives a message indicating that this object arrives at the warehouse. From this moment, the unicorn exists in two forms at once: as a real box and as a record in the information system. If these two versions diverge, the error is inherited by all subsequent processes.
Putaway Next, the goods are moved into internal storage. Two new devices come into play here. First, a thermal printer, connected to the internal network over Wi-Fi, creates an internal label for each item. Then an employee, forklift, or automated system moves the goods to the assigned bin, often with the help of lifts controlled by PLCs. Both of these devices can be valuable attack entry points: one can let an adversary pivot into the internal network, while the other can give them control over an electric motor.
Storage Then the unicorn goes into storage. Many distribution centers use multi-level mezzanine structures: several floors of metal shelving inside a huge space. They allow efficient use of the building’s height, but at the same time complicate control over the technical infrastructure. Wi-Fi access points, cameras, switches, cables, and sensors may be mounted high overhead or buried deep inside the rows. A forgotten Ethernet cable or misconfigured networked device (access point or switch) left behind in a dark corner can become a convenient initial access point into critical infrastructure.
Picking When the customer places an order, picking begins if the goods were already stored in the warehouse or as soon as they are unloaded. A PDT, workstation, light indicator, or voice terminal directs the employee to the required bin where they pick the goods and move them to the next stage. These devices are themselves potential attack entry points: compromising a workstation or PDT could allow an attacker to manipulate picking information, which could misdirect employees to the wrong bin. Here, both the speed and integrity of the information are critical, and any manipulation or disruption can lead to wrong orders, delays, or problems in subsequent stages.
Sorting At the sorting stage, the warehouse starts to look more like a factory. Boxes move through conveyor belts and pass through different scanners, diverters, and chutes. The sorting plans are usually stored and managed by dedicated servers, while PLCs are responsible for controlling the machinery and executing these plans. For example, when the warehouse management system (WMS) decides that our unicorn should take route A, the control system needs to activate the right diverter at the right moment, sometimes within a fraction of a second.
Packing During packing, an employee or a robotic arm places the goods into the final box, prints the shipping label, and sometimes measures the dimensions and weight of the package. Safety mechanisms usually prevent robotic arms from leaving the controlled zone and harming nearby operators, but their compromise might inflict physical damage on the packages being processed.
Shipment Finally, at the shipping stage, the parcel heads to the gates. Automated guided vehicles (AGVs) and autonomous mobile robots (AMRs) move containers and pallets across the warehouse, while the dock management system coordinates the truck that will carry the unicorn onward to a store, a sorting center, or straight to the customer. These robots are themselves a potential target for attackers. Attacks can be conducted against AGVs and AMRs to interfere with their operation, for example by affecting their navigation or preventing them from reaching their intended destination.
All eight stages are coordinated by the WMS. It looks like a large web application, but in its role it’s closer to the operating system of the entire warehouse: it knows which goods exist, where they’re located, who or what should move them, and where they go next, linking employees, inventory levels, storage addresses, tasks, and orders. It also exchanges data externally: with ERP systems, transport platforms, marketplaces, dark stores, and external carriers.
Surrounding the WMS is an even larger digital ecosystem: identity services, databases, APIs, printers, carrier systems, technicians’ laptops, video surveillance, access control, fire and gas alarms, power supply, and a building management system (BMS).
That is why a single “warehouse network” doesn’t really exist. As we’ve seen, there are many overlapping technologies — IT infrastructure, OT systems, radio, cloud services, building security, and automation — layered on top of one another. A lone vulnerability scanner will never tell you whether a warehouse is secure.
Hunting the unicorn
Securing an environment such as a warehouse requires a comprehensive security assessment covering all of its interconnected systems. This involves identifying vulnerabilities across each system and understanding how weaknesses can be combined into attack paths that a real attacker could exploit. But a vulnerability only matters in proportion to what it exposes and who is able to reach it, so before looking at the weaknesses themselves, we need to understand what an attacker in this environment is actually after, because in a warehouse, the blast radius extends well beyond data. Everything we just traced — the systems, the devices, and the people operating them — exists to keep goods moving, and attacks in various parts along that chain can affect the business differently. The chart below shows what is at risk in the warehouse and where those risks land for the business. The segment on the left groups them under the three core security properties: integrity, availability, and confidentiality. The segment on the right maps each property to the business outcomes a failure can cause.
Warehouse risks
The first area at risk is integrity. Inventory counts, locations, orders, and shipment data must stay in sync with the physical world. Corrupting a record silently desynchronizes the operation, and because the eight stages form a dependency chain, one falsified entry early on is inherited downstream, surfacing later as stockouts and mis-shipments. In its deliberate forms, this lets an attacker redirect goods, release stock, and perform other actions on behalf of the platform’s vendors under cover of legitimate records. Integrity is also a safety concern: when people or machines act on information that no longer reflects the physical environment, a data failure can become a physical incident. This is why integrity is the only property linked to all five outcomes, including harm to people.
The second is availability, the warehouse’s ability to keep goods moving. Halting a conveyor, a sorter, label printing, or the WMS stops orders from shipping, and in a business built on speed, every hour of downtime means delayed deliveries and broken promises. Ransomware can bring the whole warehouse to a standstill. The impact shows up as operational disruption, lost revenue, and reputational damage.
The third is confidentiality. Customer data, business records, and system credentials are valuable targets. Their exposure leads to legal liability and reputational damage, and stolen credentials often open the door to further attacks. Where the WMS connects to financial or ERP processes, the risk extends to theft of funds.
Knowing what is at risk tells us what an attacker stands to gain; the next question is who is in a position to take it. Threat actors differ in the access they already hold. For example, an attacker may be authenticated and privileged, have limited physical or remote access, or have no legitimate access to the environment at all. Based on their relationship with the warehouse and their level of access, threat actors can generally be divided into two categories:
External. An attacker with no legitimate relationship with the warehouse or the organization, operating without authorized access. External attackers can be divided into two categories based on their physical proximity to the environment:
Remote. An attacker operating from outside the site’s physical area, reaching the environment through whatever the organization exposes or makes reachable over the internet, including web services, remote access infrastructure, and third-party connections used by suppliers, carriers, and integrators.
Proximate. An attacker with no legitimate access who has nevertheless moved within physical range of the site’s locally reachable technologies. They may, for example, be in a parking lot, a neighboring unit, or a delivery bay. Their proximity may allow them to interact with wireless, radio, Bluetooth, or other short-range interfaces without possessing an account, badge, employment relationship, or other authorized access.
Internal. An individual with legitimate access to the warehouse, its systems, or its information, who intentionally or unintentionally creates a security risk. This includes employees, administrators, operators, contractors, and temporary staff.
Combining these threat actors and their access levels with the risks identified earlier, the vulnerabilities present in each system, the resulting attack surfaces, and the potential attack paths between them provides a threat model for the warehouse environment. This allows an organization to understand how different systems and people could be targeted, how individual weaknesses could be combined, and where security controls are most needed.
Cornering the unicorn
Knowing what is at risk and who might come after it still leaves the most practical question open: how they would actually get in, and how far they could go once they did. The diagram below sets out the warehouse’s attack surface: every point where an attacker can get in, organized by the access that reaching each point requires.
Warehouse attack surface
On the left are the attacker categories discussed above, distinguished by where they stand and what access they already hold. Each reaches the environment through a different set of entry points, and the impact of a successful attack can land on several systems, from the WMS to OT systems such as robots, sorters, and physical access control system (PACS). The WMS is highlighted because it is the most significant of these: it coordinates the OT systems, so compromising it can affect the entire operation rather than a single process.
Next, we will cover the initial access vectors, the points a threat actor can use to reach the warehouse environment. Following that, we turn to the impact on the logistics processes themselves, focusing on the WMS, since its compromise affects every logistics operation that depends on it.
Initial attack vectors
Internet-facing services
Remote access through internet-facing services, third-party connections, and corporate networks gives an external attacker a foothold on the warehouse network infrastructure. It is a well-covered problem and not specific to this environment, so we note it here as an entry point but will not examine it further.
Wi-Fi, Bluetooth, and other radio channels
Wi-Fi connects handhelds, tablets, printers, cameras, and workstations. Bluetooth serves scanners, headsets, and positioning beacons. Zigbee and similar low-power protocols run lighting, sensors, and building automation, while LoRaWAN carries telemetry over long distances. Cellular provides a backup channel for kiosks and contractor equipment, and proprietary protocols control industrial panels and specialized machinery.
Radio passes through windows, gates, roofing, and thin external panels, so a network built for receiving and processing goods may be reachable from the parking lot and, with a directional antenna, from considerably farther away.
That reach matters in two ways. It gives an external attacker a place to start, as proximity alone is enough to reach the Wi-Fi and the low-power protocols, and from there to gain an initial foothold in the warehouse networks.
However, radio does not only lead into the network. It also connects directly to the field devices and carries the live control traffic of warehouse operations, which makes availability a first-order concern. If hundreds of handhelds lose their connection at once, picking stops. If an AGV loses its control channel, the safe reaction may be to halt in place, and a stopped machine can block an entire route.
Physical network
The scale of the warehouse itself is part of the attack surface. A fulfillment warehouse can run up to tens of thousands of square meters, with racking climbing several stories and walkways threading through it. Structured cabling runs along that racking, cameras and access points are mounted on that, and wall jacks sit behind pallets that have not moved in months. Almost none of it is in anyone’s line of sight.
That gives a person in the warehouse something a normal office does not: unsupervised access to live network infrastructure. Unplugging a ceiling camera leaves an active port. An unused jack behind a shelf leaves another. Neither requires tools, credentials, or any interaction with a system that logs anything. And since the camera or access point sits on the same segment as the rest of the site, the compromised port, not being isolated, opens a path to the network core.
Barcode scanners
Barcode scanners are everywhere in a warehouse. They are the main tool workers use to tell the system what is moving and where, supporting receiving, picking, packing, and inventory management. A typical setup has handheld scanners communicating with a base station, which is in turn connected to a workstation or another business system.
This makes the scanner an entry point into the core network in two ways.
First, through the barcode itself. Since the scanner acts as a keyboard to the connected host, a maliciously crafted barcode or QR code can inject keystrokes when scanned, potentially giving the attacker an initial foothold on the host without directly accessing the network.
Second, through the scanner’s wireless link. During a customer engagement, with the provided test stand of such a device, we discovered that an attacker within range could inject keystrokes into the connected host and potentially achieve remote code execution without user interaction. This attack pattern was observed across multiple vendors, including, for example, Honeywell devices affected by CVE-2026-4272.
In both cases, the result is the same: a foothold on a host inside the warehouse network. The scanner is simply the entry point; the significance of that foothold comes from the host’s trusted position within the operational environment and its connectivity to core systems.
Portable data terminals
Portable data terminals (PDTs) are essentially ordinary Android devices with an embedded barcode scanner, carried by workers to scan items; each scan is passed to a dedicated application that forwards it to a remote server over an API. To keep workers on task, the devices usually run in kiosk mode, locking the user to that single application and preventing interaction with the rest of the Android system.
That lockdown is exactly what an attacker wants to break, and breaking it is what turns the terminal into an initial access vector: escaping the kiosk can expose the Wi-Fi password of the network the terminal is connected to, or allow malicious software to be installed that gives the attacker remote access to the network over the internet.
Printers
Warehouses contain different types of printers. Alongside the usual IT printers used for documents and paperwork, there are specialized thermal printers, small devices that use heated elements on the printhead to create labels, barcodes, and tags. As we mentioned earlier, these are mainly used to print the labels, usually containing barcodes, that are attached to goods during the putaway stage.
Here we focus on mobile thermal printers: small, battery-powered devices that workers can carry or wear. They typically connect to the internal network over Wi-Fi to receive print commands, while also supporting Bluetooth for connecting to nearby devices. This combination makes them a potential entry point into the internal network.
Some models, such as the Zebra ZQ630, support multiple interfaces and can run applications directly on the device. During a security assessment, we discovered that apps can be uploaded and executed over Bluetooth. By exploiting a pairing misconfiguration, an attacker within Bluetooth range could bypass pairing, upload malicious software, and gain an initial foothold through the printer.
Impact on logistics processes (attacks on WMS)
With a foothold in the network, an attacker can pivot to the logistics processes themselves: from the WMS through the warehouse infrastructure to the PLCs and the machinery they drive. As we saw earlier, all OT systems and devices are interconnected and the WMS sits at the head of that chain: it is the system of record every other process reads from and writes to, so compromising it reaches all of them at once. That, and its being specific to this environment, is why it is the focus here.
Warehouse management systems (WMS) are the software platforms that optimize warehouse processes from the entry of goods to their exit. They provide real-time visibility into inventory and orchestrate end-to-end fulfillment by integrating with many warehouse subsystems and pieces of automation equipment, such as conveyors, PLCs, robotics, scanners, and voice systems. A typical WMS includes modules for receiving, inventory control, order management, labor management, shipping, and reporting. Major vendors include SAP EWM, Oracle Warehouse Management, Manhattan Active, Blue Yonder, Infor, Körber/HighJump, Microsoft, and TECSYS.
To picture how central this is, think back to our unicorn. From the moment it was scanned at receiving, it stopped being only a physical box and became a record inside the WMS, a record the system then used to decide where it should be stored, when it should be picked, how it should be sorted, and where it should ship. Every device employed along the way — the PDT at receiving, the printer at putaway, the workstation at picking, the conveyor at sorting — was really just talking to the WMS. It is the thread that ties all eight stages together, which is exactly what makes it such a valuable target.
Because modern WMS platforms are usually web-based and heavily interconnected, they inherit common web and API vulnerabilities alongside flaws specific to the WMS itself. A recent example is CVE-2026-70774 in Oracle Warehouse Management, part of Oracle E-Business Suite. Oracle rated it High and described it as an easily exploitable authorization bypass flaw in which a low-privileged attacker with network access can compromise the application, affecting integrity and availability by allowing unauthorized creation, deletion, or modification of critical data.
A flaw like this may look like a typical web application issue, but its consequences in a warehouse are more serious, because the WMS is the system of record. If an attacker can modify its data, they can alter stock levels, bin locations, receiving records, picking tasks, or shipment information, silently corrupting the digital twin of the warehouse. And since the eight stages form a dependency chain, that corruption doesn’t stay contained: a falsified record at receiving is inherited by putaway, picking, and everything downstream. The physical box and its record diverge, and every later process trusts the record.
The most direct version of this attack comes from an authorization bypass flaw like the Oracle vulnerability above. Here the threat actor can be an external attacker who has reached the application over the network, or an insider such as a low-privileged operator or storekeeper who already holds a legitimate account.
The danger grows when such a flaw is chained with others. An external attacker who combines remote code execution with SQL injection could generate shipment orders to arbitrary addresses together with the documents needed for goods to physically leave the warehouse, fabricate waybills, acceptance or transfer records, and registers, while also exposing customer data such as names and delivery addresses. In effect, the goods are sent out with legitimate-looking paperwork.
This is why ordinary web vulnerabilities carry considerable weight in a WMS. For an external attacker or an insider probing beyond their assigned role, broken access control could open a path into another warehouse zone, allow manipulation of other workers’ tasks, permit unauthorized exception operations, or expose administrative APIs. A server-side request forgery flaw could force the WMS server to reach resources an external attacker cannot touch directly, and if the network is flat or only formally segmented, that server may in turn reach internal management panels, cloud service interfaces, or systems sitting close to the operational network, turning a single web bug into a bridge between IT and OT.
Attacks on a WMS don’t always target the application directly, though. As we saw while tracing the unicorn, the warehouse is full of connected devices that already hold trusted access. A handheld terminal carries authenticated WMS API access as a matter of course, and anyone who gains control of that terminal inherits it (by escaping the kiosk, for example). Depending on the device’s permissions, that might mean confirming picks that never occurred, falsifying receiving operations, adjusting stock counts, or marking orders complete — something warehouse employees themselves could use to avoid their assigned duties.
Where the WMS is connected to control and automation systems, access to the WMS can extend into physical operations, including conveyors, sorting systems, lifts, doors, and pumps.
PLCs translate WMS instructions and sensor inputs into physical actions. Compromising a system that controls them therefore creates an opportunity to manipulate those actions. The impact can be as simple as a sorting diverter sending boxes down the wrong route, a conveyor repeatedly entering an error state and creating a backlog, or a falsified sensor value causing a line to be treated as clear when it is full.
However the WMS is compromised, the business consequence is the same: inventory corruption, unauthorized shipments, and operational disruption, each reaching the customer in the end as a late or missing delivery, the wrong item in the box, or a personal address exposed to a stranger.
Securing the unicorn
We followed our unicorn through web applications and databases, radio channels and PDTs, printers, conveyors, robots, and the loading zone. Because warehouse environments combine IT, OT, wireless, physical, and human components, security controls should be implemented as a single, coordinated security architecture rather than as isolated measures. Network segmentation should be a foundational control, with clear separation between corporate IT, warehouse OT, operational devices, management networks, and externally connected systems. Segmentation should also extend across facilities and customer environments so that each site and customer integration is isolated from the others, limiting the potential impact of a compromise. A zero-trust approach should reinforce this architecture by requiring explicit authentication and authorization for connections between systems, regardless of their network location, and by applying least-privilege access wherever possible. Regular penetration testing of the corporate IT environment, including domain services, identity infrastructure, and endpoints, should be incorporated into the warehouse security program.
Physical and network access controls should be implemented together. Access to warehouse facilities, network rooms, communication cabinets, and operational areas should be restricted according to business need, with appropriate authentication, monitoring, and access logging. Network infrastructure should be hardened through controls such as switch port security, MAC-based access restrictions where appropriate, and IEEE 802.1X with EAP-TLS for strong device and user authentication. Network equipment should also be securely configured and regularly reviewed to ensure that unused interfaces, insecure management protocols, default credentials, and unnecessary services are disabled.
Web applications and their supporting infrastructure should be governed through a secure software development lifecycle (SSDLC), including security requirements, secure coding practices, code and dependency review, and application security assessment before deployment and throughout the application’s lifecycle. Third-party applications and components should be continuously monitored and updated, with a defined vulnerability and patch management process. This should explicitly include warehouse management systems (WMS), warehouse portals, APIs, and other applications that provide operational or customer-facing functionality.
Wireless technologies should be subject to dedicated security assessment and engineering. Radio-frequency surveys should be conducted to establish expected coverage, identify unauthorized or unexpected signals, validate the availability and protection of operational communications, and determine whether wireless deployments create unintended access paths into warehouse networks. Wireless security should be assessed not only from a connectivity perspective but also in terms of authentication, encryption, device provisioning, protocol exposure, interference resilience, and the potential impact of unauthorized devices.
Warehouse operational devices should be incorporated into the organization’s endpoint security and vulnerability management processes. Devices should receive security updates and firmware patches on a defined schedule, with accelerated remediation for critical vulnerabilities. Security assessments should be performed periodically to identify weaknesses in device configuration, applications, exposed services, and authentication mechanisms.
Personnel security should form an additional layer of the warehouse security architecture. In most industrial and ICS environments, getting inside means clearing background checks, holding relevant qualifications, or proving prior experience; the hiring process itself acts as a filter. A warehouse is different. Roles in sorting, packing, and courier work are hired quickly and in volume, and they typically require no prior expertise, certification, or specialized background at all. An ordinary person can walk in off the street, be hired within days, and immediately hold legitimate physical access to the facility. Therefore, a more restrictive and risk-based approach to hiring should be considered, particularly for roles that provide access to sensitive areas, operational systems, network infrastructure, or customer assets.
Ultimately, all of these measures serve the same objective: protecting the continuity and reliability of the warehouse as a whole. This matters because real warehouses handle food, medicines, machine parts, and the millions of ordinary things people and companies depend on every day. Protecting their journey means seeing the warehouse as it has actually become: a single digital system with doors, motors, shelving, and radio signals, and with entirely real consequences when it fails. And if the security program works, the customer never knows any of this happened. The unicorn simply arrives at the scheduled time.
If your warehouse operations rely on interconnected systems like these, we can help identify the gaps before an adversary does. Reach out to discuss a security assessment.
St. Lucie County in Florida discovered (alt link) a dozen Flock cameras whose ownership it can’t identify, and that the county government had not permitted.
I am reminded of the decade-old story of StingRay cell phone surveillance devices in Washington, DC, whose operators were also unknown.
My guess is that in the StingRay case, the devices were operated by foreign actors. This Flock case is more likely some local government entity that didn’t bother getting approval. Were I a foreign actor, I would rather hack the existing Flock network—like Israel did with Tehran’s surveillance cameras—than risk installing my own.
Regardless, once we normalize a surveillance infrastructure, both friends and foes will take advantage of it.
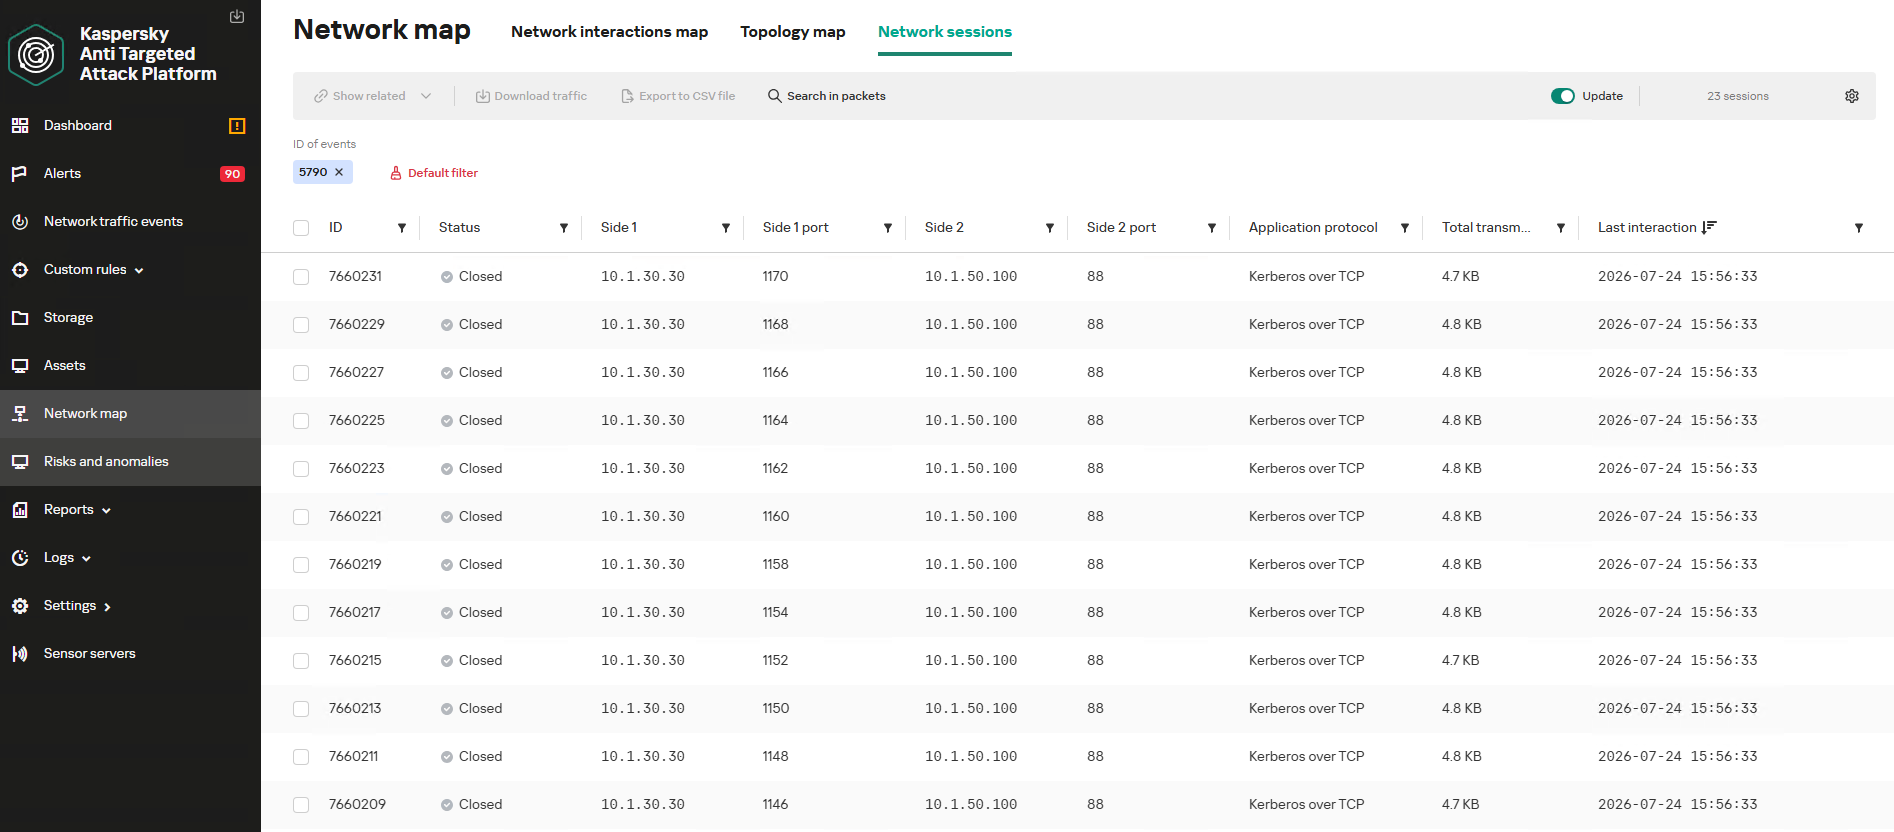
Once the attacker has breached the corporate network, subsequent stages of the attack often involve leveraging standard domain infrastructure protocols: using Kerberos, running DNS queries, accessing internal services, opening network shares, and other common networking actions. Because this activity is virtually indistinguishable from legitimate network traffic, it is extremely difficult to detect it with traditional network attack detection tools.
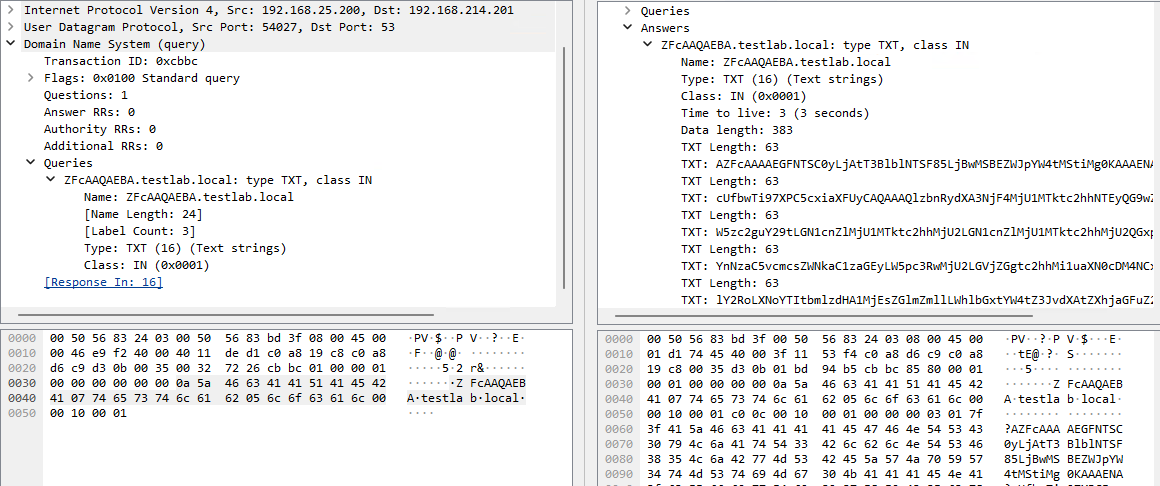
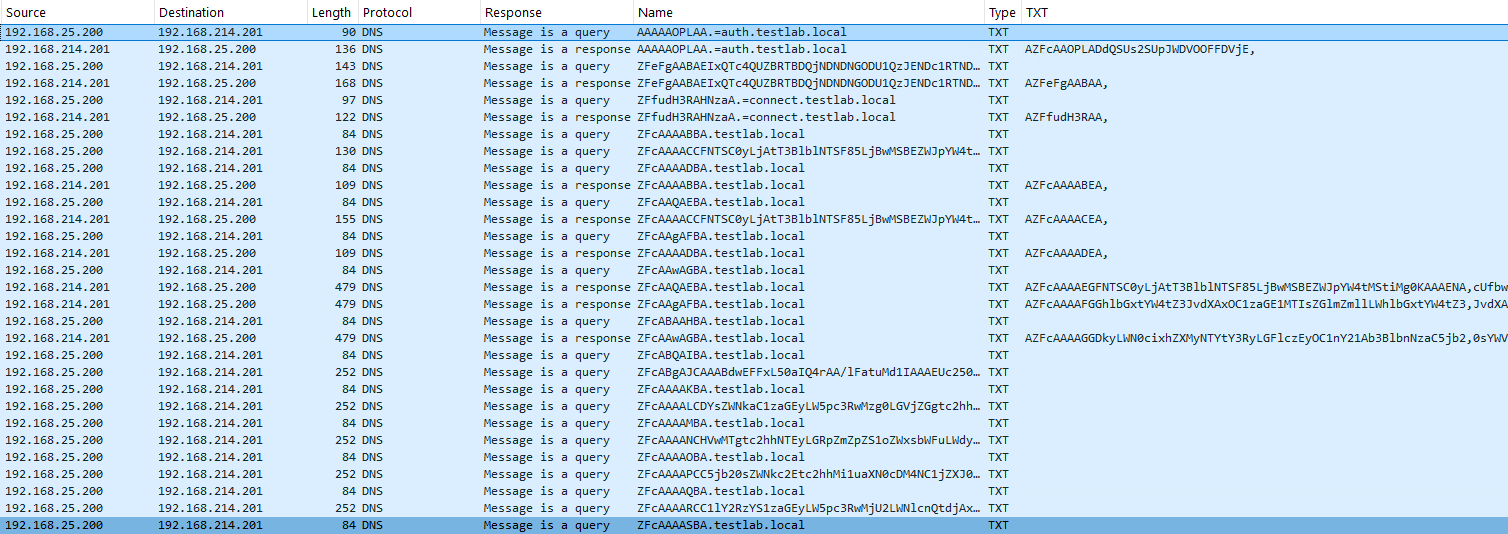
Kerberoasting and DNS tunneling have long ceased to be exotic techniques. They are becoming standard methods in modern attacks because they allow attackers to execute critical compromise stages while remaining undetected by traditional security tools. A clear example of this trend is seen in latest campaigns, employing both Kerberoasting and DNS tunneling.
Traditional network security tools perform well when the attack features a distinct and identifiable indicator: a characteristic query string, a known malicious traffic pattern, or the source code of an already discovered exploit. While this approach to threat detection remains effective, it cannot always be applied to discovering network attacks that blend seamlessly with legitimate traffic inside a corporate network.
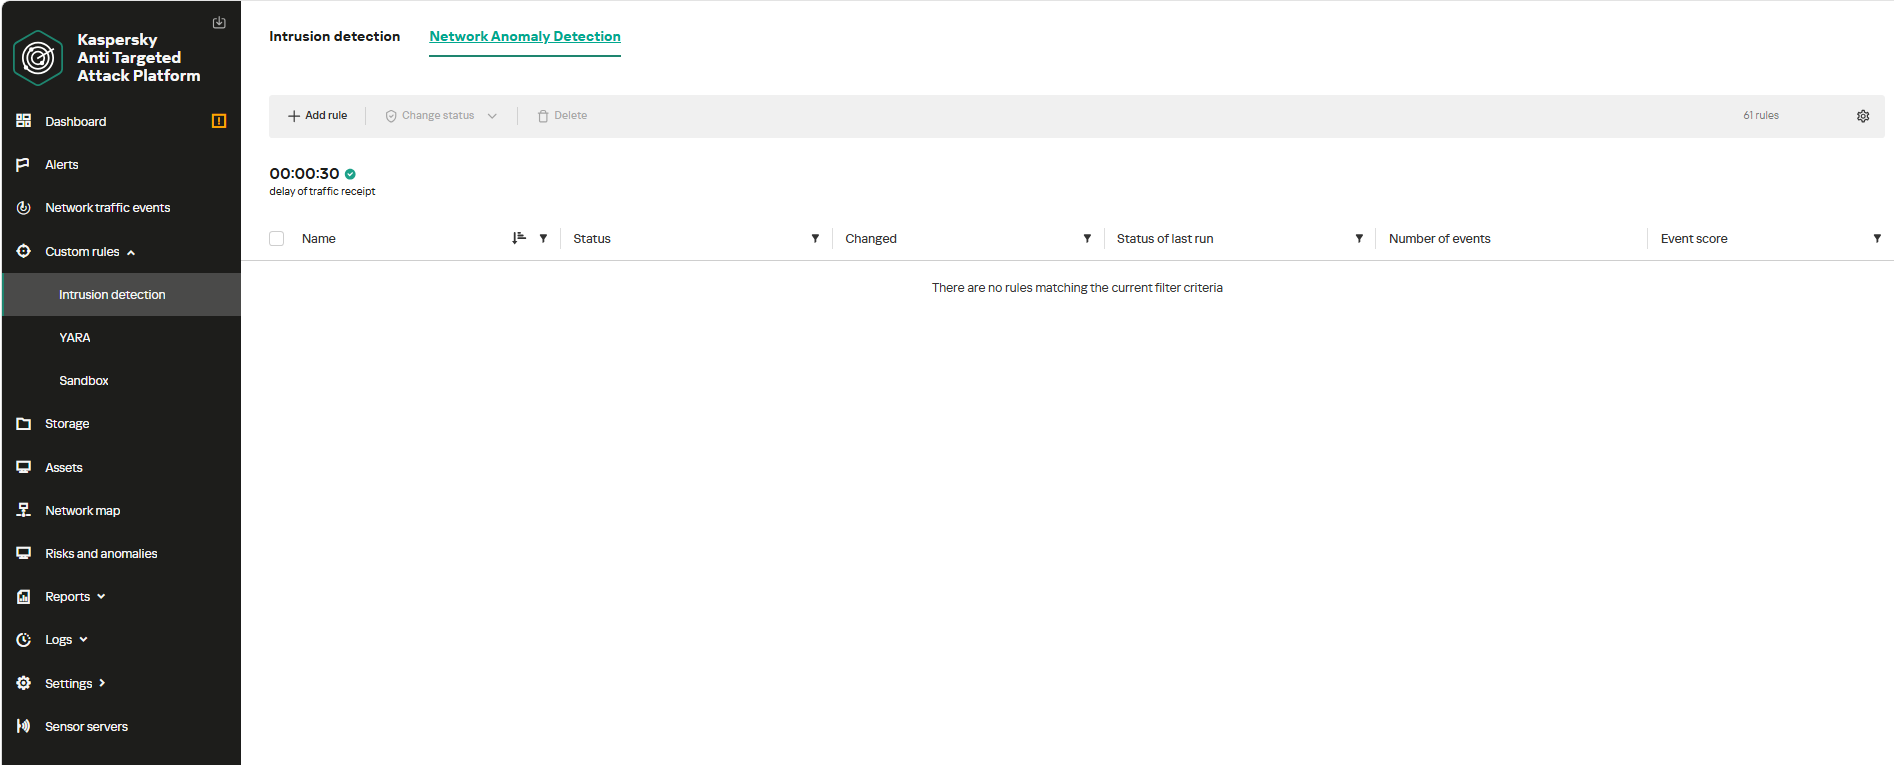
Instead of searching for explicit indicators of attack, Network Anomaly Detection (NAD) analyzes all traffic for suspicious artifacts that deviate from the host’s typical network activity. Within Kaspersky’s solution portfolio, this technology is implemented specifically in the Kaspersky Anti Targeted Attack (KATA) platform.
The system analyzes network traffic data (DNS, DCE/RPC, Kerberos and other packets) and extracts key parameters used to identify anomalous behavior. This approach enables searching for attacks on domain controllers, signs of traffic tunneling and exfiltration, C2 communications, and other scenarios that may point to compromise of network infrastructure.
However, Network Anomaly Detection is not built on a single, universal set of indicators. Each attack scenario employs tailored detection models that account for the specifics of the corresponding network protocol, typical host behavior, and characteristic deviations from that baseline. This article examines two practical examples – detecting Kerberoasting and DNS tunneling – to demonstrate how these principles are implemented in KATA’s NAD rules and why this approach proves more effective than traditional signature-based analysis.
Kerberoasting attack detection by KATA
Why standard tools have a hard time detecting Kerberoasting
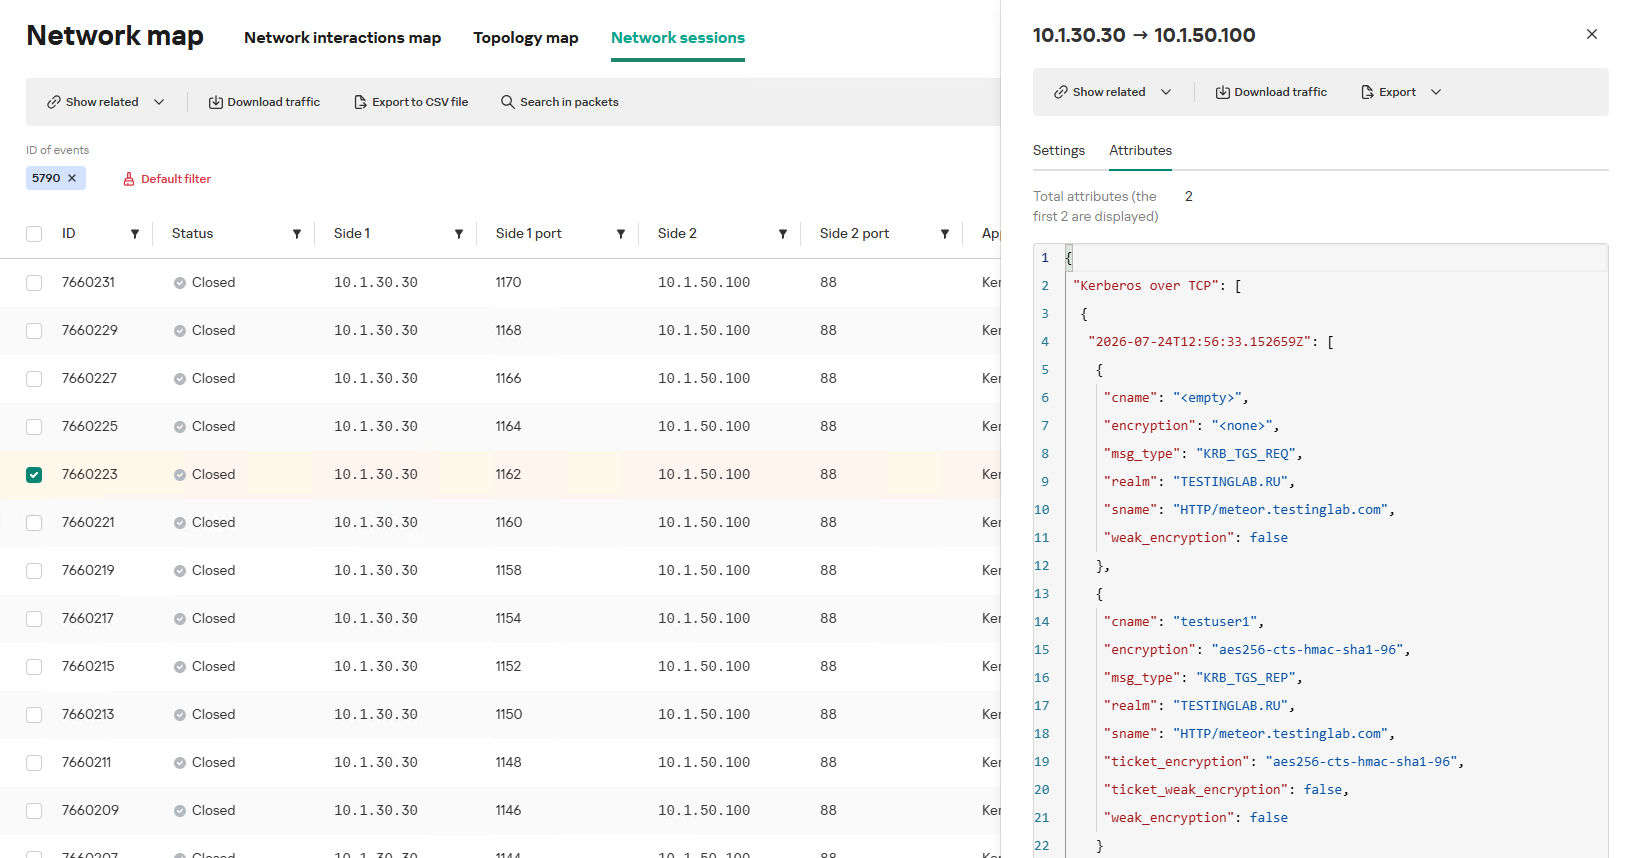
The Kerberoasting attack leverages the standard operational logic of the Kerberos protocol. The attacker identifies service accounts configured with a Service Principal Name (SPN), requests a Ticket-Granting Service (TGS) ticket for them, and attempts to crack the password offline using a dictionary attack against the retrieved ticket. If the password is weak or hasn’t been changed in a long time, the adversary can bruteforce it to get it in cleartext. Subsequently, these compromised credentials can be leveraged for both vertical and horizontal movement across the network.
The essence of a Kerberoasting attack is that an adversary possessing a compromised low-privileged account and a valid Ticket-Granting Ticket (TGT) for that account can request TGS tickets with weakened encryption for service accounts with SPNs. Crucially, it doesn’t matter whether the compromised account actually holds access permissions for those services. Having obtained these tickets, the attacker can then take them offline and bruteforce the service account’s password by trying to decrypt the corresponding ticket locally, without generating any network activity. As the encryption key is based on the password hash, the adversary can guess the password upon finding the correct key.
The attacker’s objective is to find a service account that has a simple password. Most likely, this will be an account created manually by the administrators of the infrastructure or a service. This is precisely why attackers are not interested in system service accounts with SPNs (such as CIFS/fileserver.company.local); these are generated automatically and feature highly complex passwords that are impossible to bruteforce.
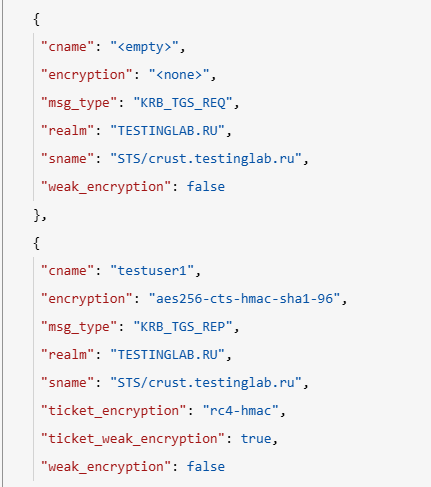
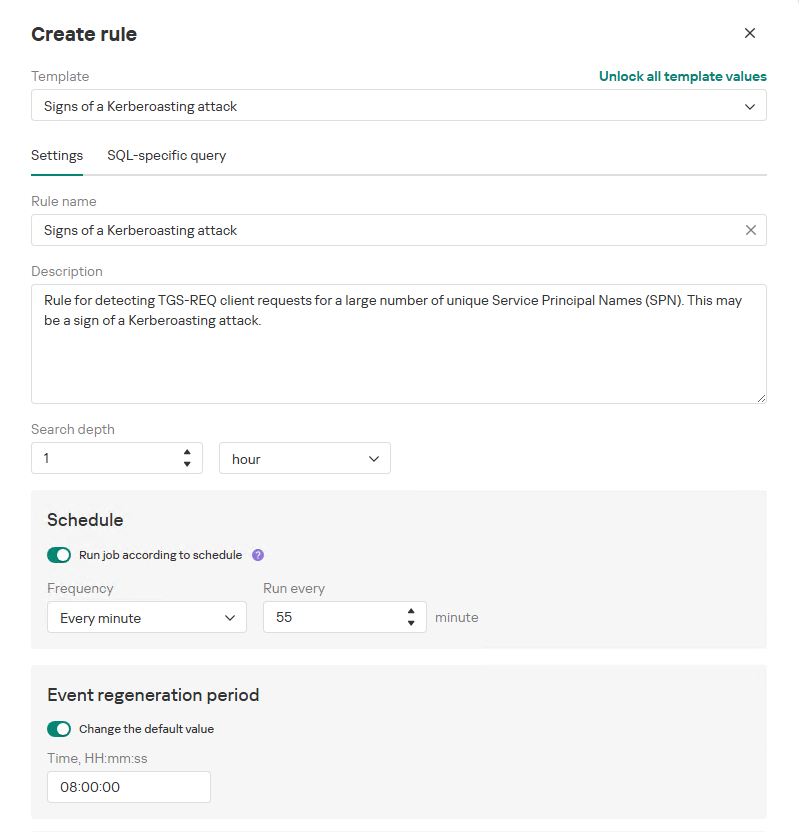
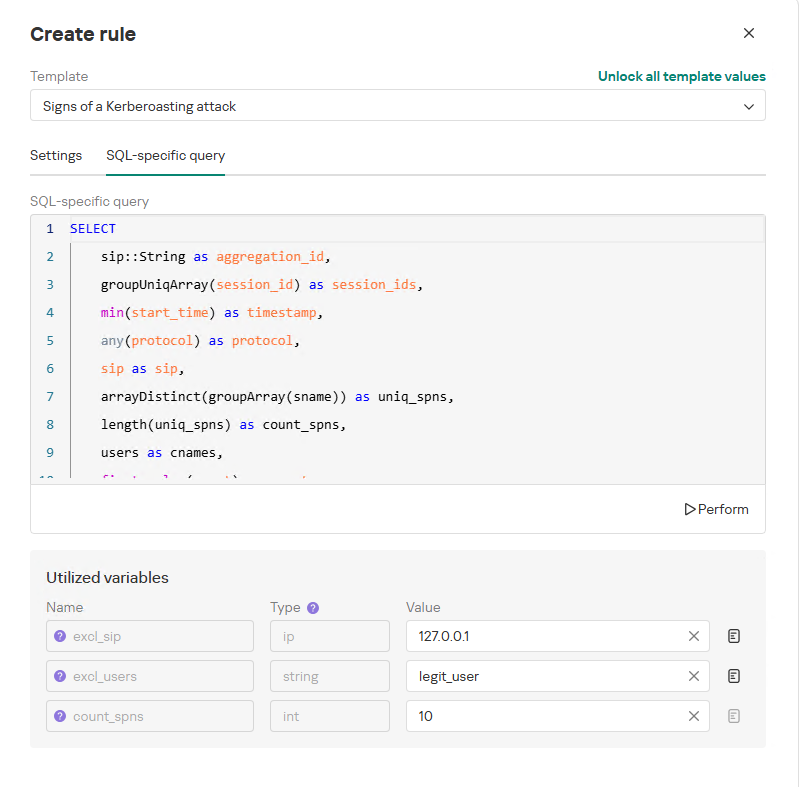
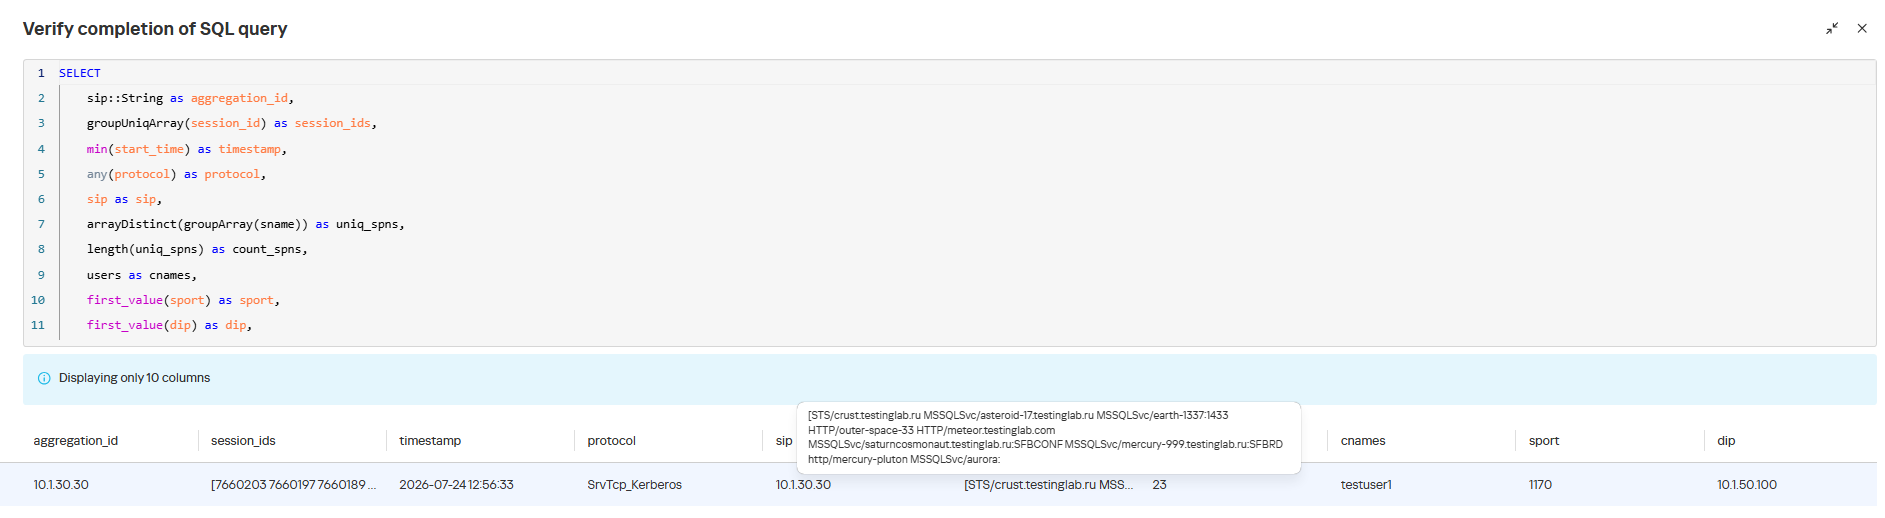
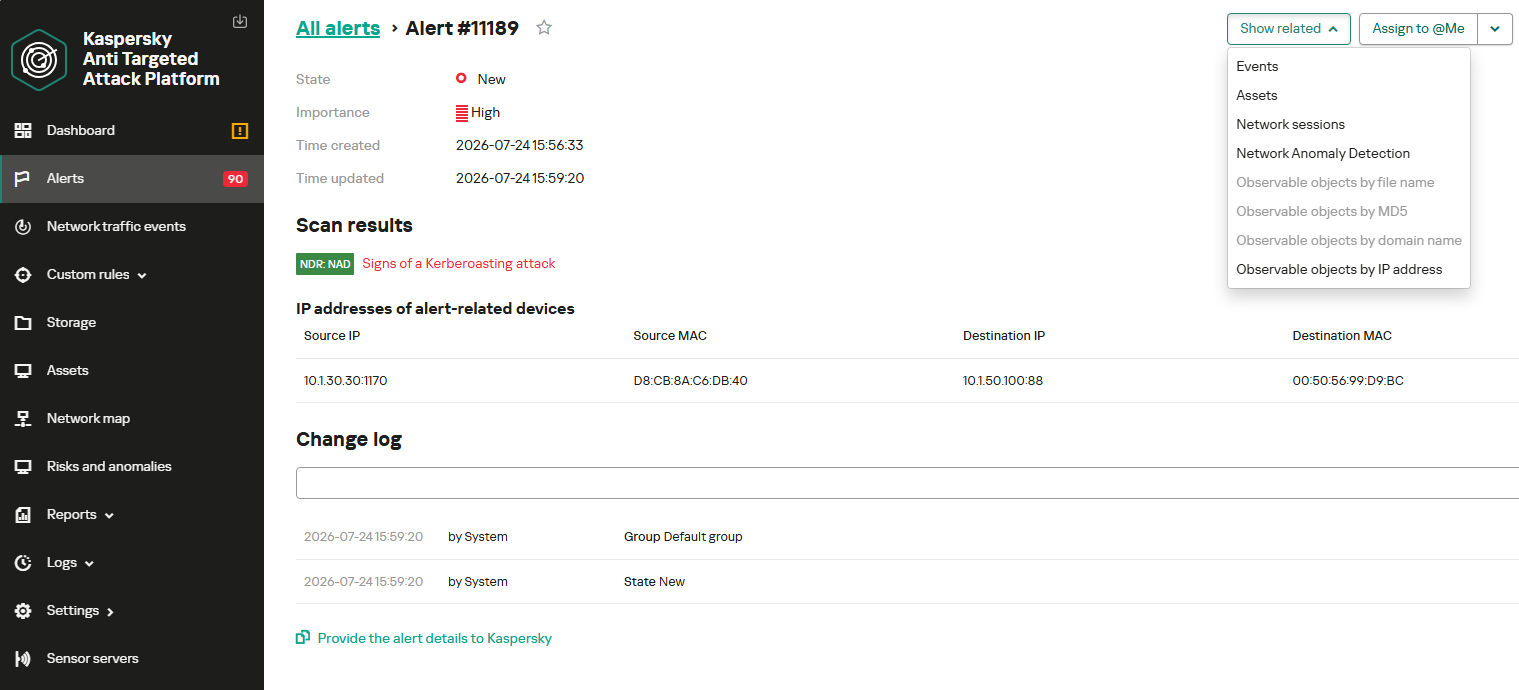
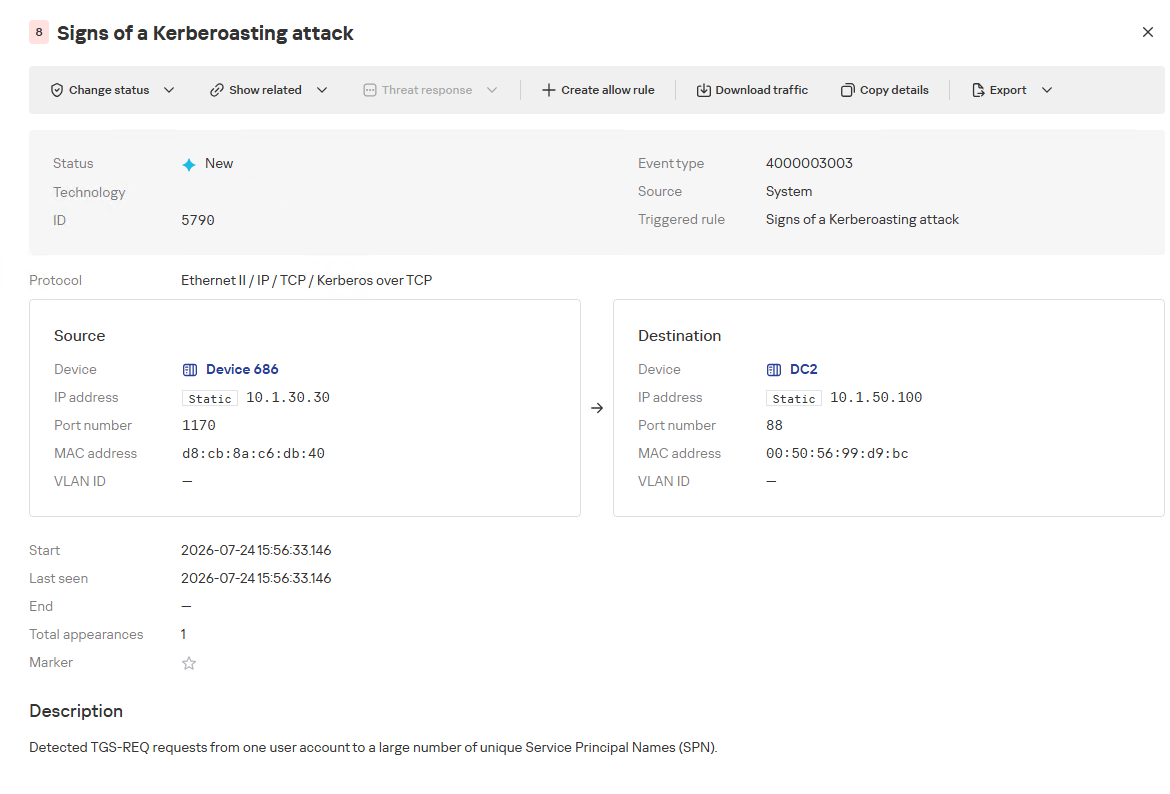
We should note that the TGS ticket requests made by attackers are identical to standard, legitimate requests. Every domain naturally exhibits a high volume of Kerberos traffic. Therein lies the primary challenge of detecting Kerberoasting: legitimate service ticket requests (TGS-REQ) are indistinguishable from those issued by attackers. Consequently, the primary detection method relies on correlating indirect indicators rather than signature matching. Key indicators include an anomalous request source (atypical host or user account), a surge in requested SPNs within a short time window, attempts to obtain service tickets for sensitive or privileged service accounts, and off-hour timing or unusual request volume when benchmarked against the historical profile of both the user and the host.
Most of these indicators can be detected using NAD technology, which helps analysts cut through high volumes of Kerberos traffic to establish a concrete hypothesis: who initiated the Kerberoasting attack, which service accounts are at risk, and why this activity deviates from the baseline.
In the context of this attack, the network anomaly stems from a single host – likely using a single user account (cname) – receiving TGS tickets ("msg_type": "KRB_TGS_REP") for numerous unique services with SPNs (sname) within a short timeframe. These service accounts are non-system accounts.
Example of a TGS-REQ – TGS-REP event pair from network session attributes
To detect this anomaly, the NAD rule titled “Signs of a Kerberoasting attack” implements the following logic:
From Kerberos network sessions during the search depth period, select only those with a successful Kerberos TGS-REP response, subject to the following conditions:
The IP address that initiated the session must not be excluded in the excl_sip variable.
The requesting client name (cname) must not be included in the excluded users list (excl_users variable).
The SPN (sname) must not be excluded within the rule. System SPNs are omitted from detection logic because they exist across most corporate environments and hold no interest for adversaries in this attack vector; including them in the total count of unique SPNs could lead to predefined threshold being exceeded, triggering false positives.
Extract the cname (the name of the client requesting the TGS-REQ) and sname (SPN itself) from these qualifying sessions.
Group the sessions by the source IP address and client account name (cname), while aggregating sessions with unique SPNs.
Generate an alert if a single IP address using a single client account receives TGS-REP responses for N unique SPN names within the specified search depth window, where N equals or exceeds the threshold variable count_spns.
Within the event regeneration window, group under the initial alert all subsequent alerts associated with the same client IP address. This avoids creating duplicate event records by incrementing the aggregation counter (Total appearances).
We should note that this type of logic cannot be implemented using IDS signatures. Consider creating a Suricata rule designed to detect Kerberos TGS-REP packets. To minimize false positives, we’ll exclude system SPNs (which carry highly complex passwords) and apply a threshold for the number of responses a single client can receive. However, such a rule cannot evaluate the uniqueness of the requested SPNs; it can only track packet counts. As a result, this signature would produce a high volume of false positives because any domain naturally generates large amounts of identical legitimate TGS-REP messages.
Furthermore, adding exclusions and tuning thresholds to fit your specific infrastructure environments is significantly more practical when managed through user variables in the interface rather than directly modifying the underlying structure of the IDS rule itself.
Creating a Network Anomaly Detection rule
Network Anomaly Detection (NAD) rules are written as SQL queries executed against KATA’s ClickHouse database. Below, we demonstrate how to add and deploy a rule.
To begin working with NAD rules, navigate to the “Custom rules” section of the interface and select “Intrusion detection”. Under the “Network Anomaly Detection” tab, you can create a new rule.
The Network Anomaly Detection page UI
When adding a new rule, an analyst can select an appropriate rule template from the prebuilt set supplied with product updates. They can also manually modify the rule added from the template (converting it to a custom rule while keeping the original template intact) or author a rule from scratch using the provided guide.
Upon selecting a template, the analyst can review the rule description and either adjust or leave the default values for the following settings:
Search depth (the lookback window over which the SQL query will run)
Schedule (the execution frequency for running the query against the specified search depth)
Event regeneration period (the timeframe during which identical alerts will be aggregated into a single record rather than displayed as distinct events)
UI for creating a new NAD rule
To ensure the rule functions correctly, we recommend navigating to the “SQL-specific query” tab before deployment to review the variables used within the rule – a description for each variable is available by hovering over the question mark icon.
The variables are lists of IP addresses, dates, strings or numeric values that define the network infrastructure – such as domain controllers, DNS servers, time ranges, critical segments, and other entities. This allows you to tailor each rule to different network environments and incorporate specific infrastructure characteristics without modifying the underlying logic.
In our example, using variables allows you to adjust the “Signs of a Kerberoasting attack” rule as follows without altering the underlying SQL query:
Exclude the source IP address of the TGS-REQ requests from the scope of detection logic (you can specify a single address, a subnet mask, or a dictionary containing addresses and subnets) as well as the requesting client account (accepts a single value or a dictionary with multiple values).
Adjust the threshold value required to trigger an alert based on the number of unique SPNs in the TGS-REQ messages.
Query contents and variables used in the new rule
On this same page, you can test if the rule is functional prior to saving it.
Rule execution test results
When this rule triggers, an NDR:NAD alert is generated. In the alert card, the analyst can review basic information: IP addresses, ports, and participating network endpoints.
Alert card for the NAD rule
From there, the analyst can navigate to the associated event, which provides a detailed breakdown of the anomaly alongside links to the affected hosts.
NAD rule triggering event
If needed, the analyst can view and export the network sessions associated with the alert. These sessions can be accessed directly from the alert or within the event card via the “Show related” drop-down list.
Network sessions that triggered the rule
Within an individual session, the analyst can inspect standard details including interacting parties, data volume sent and received, and other fields and metrics. On the “Attributes” tab, the analyst can review the specific events recorded within that session.
Network session attributes
Detecting DNS tunneling in KATA
How DNS tunnels work
DNS tunneling is a technique used to transmit data or control malware through firewalls by encoding information within DNS protocol requests and responses. Instead of performing standard name resolution, an infected host transmits data encoded within subdomain strings and receives response data via DNS records. This covert channel can be leveraged for C2 communication, bypassing network restrictions, or data exfiltration.
One method of implementing DNS tunneling involves utilizing TXT records. In this scenario, the client issues DNS TXT record queries for domain names where the right-hand portion of the domain name (the higher-level domains) remains static, while the left-hand portion (the lowest-level subdomain) carries encoded or encrypted data sent from the client to the server. Under this structure, a sample domain name might look like ZFcABQAIBA[.]testlab[.]local, where testlab[.]local serves as the static right-hand portion and ZFcABQAIBA represents the variable left-hand string containing the data transmitted by the client.
In response to these queries, the server delivers commands or messages inside the data field of the TXT response. Because the right-hand portion of the domain name remains static, all client queries are consistently routed to the same C2 server, even if the intermediate DNS resolvers targeted by the client change.
DNS query (left) and corresponding response (right) during DNS tunneling via TXT records
It is rather challenging to identify this malicious activity within DNS traffic without generating false positives. DNS traffic is permitted across almost all corporate networks, long domain names occur routinely in both internal and external environments, and TXT records are frequently leveraged for legitimate operational purposes.
Suspicion is established through a combination of indicators: a high volume of long, seemingly random subdomains associated with a single top-level domain, high request frequency, an unusually large number of unique names, non-standard record types, and significant data transfer volumes within a single DNS session.
By analyzing DNS traffic for threat detection, we identified three primary fields of interest:
Requested DNS name
DNS record type
TXT data field within the response
As shown in the image above, all of these fields are present in the DNS response. In a real-world scenario, a tunnel of this nature will transmit a volume of data that is abnormally large compared to standard DNS traffic.
Data exchange within a DNS tunnel
Thus, in the context of DNS tunneling, a network anomaly occurs when 1) a single query source host sends data embedded in the variable left-hand portion of domain names (rrname) while 2) maintaining a static right-hand portion (rrname) and 3) receives DNS server responses containing TXT records (rtype) with varying data (rdata), while 4) the total volume of data transmitted in the left-hand portion of the requested domain name together with the TXT data response (rdata + rrname) exceeds a predefined threshold.
Request and response events from DNS session attributes
When detecting DNS tunneling, the following nuances must be considered:
A single tunnel will not be constrained to a single DNS session; data may be transmitted across multiple sessions with the DNS server, or each individual request may occur within a separate session.
A client DNS query can contain more than one requested domain name.
A DNS response can contain multiple TXT records, as well as a large volume of various non-TXT record types.
Traffic between DNS servers must be excluded, as it duplicates client requests and can trigger false positives.
Although the factors outlined above (an abnormally large or frequently changing left-hand subdomain alongside a static right-hand domain, or an unusually long string in a TXT record) serve as key indicators of DNS tunneling, they can also occur within legitimate network traffic.
These challenges create a high likelihood of false positives when detecting DNS tunneling, particularly when using IDS-based tools. Writing an accurate IDS rule for this type of activity is practically impossible. With rare exceptions, DNS tunneling tools possess static markers that can be leveraged for signature-based detection. However, in the absence of such markers, signature methods fail to deliver high detection accuracy without generating an overwhelming number of false positives. In these cases, a comprehensive approach combining multiple correlated indicators is essential to improve overall detection quality.
DNS tunneling detection logic
To add a rule for detecting this anomaly, you can use the prebuilt “DNS data tunneling via TXT records” template in the new rule creation interface. The “SQL-specific query” tab will display the list of variables used:
user_DNS_servers: a list of internal DNS server addresses within the infrastructure, required for the rule to function correctly and minimize potential false positives
excl_sip: IP addresses to be excluded from the scope of the rule (you can specify a single address, a subnet mask, or a list containing both addresses and subnets)
traffic_size: the threshold value for the total volume of data (in bytes) transmitted through the tunnel
Variables used in the “DNS data tunneling via TXT records” rule
The detection logic for this network anomaly is structured as follows:
From network sessions using the DNS protocol within the timeframe defined by the rule’s search depth, select only those sessions containing at least one TXT response.
Additionally:
The IP address that initiated the session must not be excluded in the excl_sip variable.
The source IP address that initiated the session must not belong to the internal DNS servers listed in the user_DNS_servers variable.
The DNS names requested by the client must not be excluded within the rule.
Split qualifying DNS sessions into individual log lines, each corresponding to an individual request or response. Retain only DNS responses containing TXT data.
Extract DNS names and their associated TXT data from these DNS responses. Retain only unique values.
Group all resulting records by the session’s source IP address, aggregating all unique DNS names and TXT data blocks.
Generate an alert if the combined size (in bytes) of the unique DNS names and TXT response data for a single IP address within the search depth window exceeds the specified threshold (the traffic_size parameter).
Within the event regeneration window, group under the initial alert all subsequent alerts associated with the same client IP address. This avoids creating duplicate event records by incrementing the aggregation counter (Total appearances).
“DNS data tunneling via TXT records” rule triggering event
The primary value of NAD technology in this scenario lies in noise reduction – by minimizing false positives – and faster investigation times. A DNS tunnel rarely presents itself as a single, blatantly malicious request. Instead, it leaves behind a behavioral footprint: repetition, length, domain structure, unusual record types, numerous subdomains branching off an unchanging root domain, and anomalous host behavior. KATA consolidates these indicators into a single alert, presenting the analyst with an actionable attack hypothesis rather than a set of fragmented DNS events.
Prebuilt rules for detecting network anomalies in KATA
KATA users should note that Network Anomaly Detection (NAD) rules are not enabled by default. Rules must be added manually using the procedure described in the preceding sections. This design ensures that analysts can fine-tune rules to fit specific network infrastructures using variables.
Analysts have three ways of creating new rules:
Adding a rule from a prebuilt template and adjusting custom variables. In this case, the rule is classified as a system rule.
Adding a rule from a prebuilt template and modifying its underlying SQL query (which requires enabling the “Unlock all template values” option) to create a custom rule based on the template. When modified this way, the rule transitions from a system rule to a custom rule.
Authoring a custom rule from scratch, which requires a basic understanding of ClickHouse SQL queries and familiarity with the product documentation.
As of this publication, the product ships with 59 prebuilt NAD rule templates (with additional templates delivered via product updates). KATA supports running up to 200 active rules simultaneously.
Prebuilt rules are divided into six categories:
Large Data Transfers: tracking abnormally large network sessions across various protocols during regular hours, at night, or over weekends.
Suspicious Connections: detecting suspicious connections that may indicate hazardous activity, shadow IT, evasion of attack detection mechanisms, and other threats.
Connections to Suspicious Resources: detects actions that violate security policies, potential data exfiltration beyond the perimeter, and unauthorized internet access originating from secured network segments.
C2 Communication: identifies network sessions characteristic of a potential C2 communication channel or tunnel.
The table below lists the rule templates for detecting network anomalies in KATA:
Rule category
Rule name
Protocols used
Large Data Transfers
Data tunneling in DNS traffic
DNS
ICMP, TCP, UDP, RDP, SSH or LDAP sessions with a large volume of traffic (6 rules)
ICMP, TCP, UDP, RDP, SSH, or LDAP (depends on selected rule)
ICMP, TCP, UDP, RDP, SSH or LDAP sessions with a large volume of traffic at nighttime (6 rules)
ICMP, TCP, UDP, RDP, SSH, or LDAP (depends on selected rule)
ICMP, TCP, UDP, RDP, SSH or LDAP sessions with a large volume of traffic on non-working days (6 rules)
ICMP, TCP, UDP, RDP, SSH, or LDAP (depends on selected rule)
Suspicious Connections
Queries to unknown DNS servers
DNS
Use of unauthorized routes
TCP, UDP
Use of suspicious ports for connections to external addresses
TCP, UDP
Use of non-typical protocols for connections
TCP, UDP, HTTP, HTTPS, DNS, SMTP
Inconsistencies with firewall configuration
TCP, UDP
Use of unauthorized ports for RDP or SSH sessions (2 rules)
RDP or SSH (depends on selected rule)
Interactions with external IP addresses over the RDP or SSH protocol (2 rules)
RDP or SSH (depends on selected rule)
Suspicious RDP sessions with domain controllers
RDP
Connection to an unknown server via Kaspersky Security Center ports
TCP, UDP
Domain Attacks
Signs of a DCSync attack
DCE/RPC
Signs of a DCShadow attack
DCE/RPC
Signs of DHCP spoofing
DHCP
DNS queries to Canarytoken domains
DNS
Signs of a Kerberoasting attack
Kerberos
Signs of an AS-REP Roasting attack
Kerberos
Signs of a brute-force password attack on SSH
SSH
Signs of SOAPHound usage
LDAP
Large-volume Active Directory object data collection via LDAP queries
LDAP
Reconnaissance Activity
Getting information about a task in the Task Scheduler
DCE/RPC
Getting a list of Kerberos users
Kerberos
LDAP queries to rights delegation attribute
LDAP
LDAP queries to attribute for getting administrator passwords
LDAP
Signs of an internal horizontal port scan
TCP, UDP
Signs of an internal vertical port scan
TCP, UDP
DNS zone data replication requests sent from sources other than DNS servers
DNS
Successfully completed requests for DNS zone data replication sent from sources other than DNS servers
DNS
LDAP query targeting a critical attribute of insecure credentials
LDAP
Enumeration of domain accounts via LDAP queries
LDAP
Exceeding the threshold for requested critical attributes in LDAP queries
LDAP
LDAP search queries containing a high number of critical attributes
LDAP
Connections to Suspicious Resources
Queries to unauthorized domain names
DNS
Transmission of large data volumes to cloud storages
TCP, UDP, DNS
Connections to cloud storages or file transfer services
TCP, DNS
Connections to public repositories
TCP, DNS
Connections to resources of programs for traffic tunneling
TCP, DNS
С2 Communication
Possible queries to DGA domains
DNS
DNS data tunneling via TXT records
DNS
Numerous blocked connections to external addresses
TCP, UDP
Conclusion
The examples of Kerberoasting and DNS tunneling clearly demonstrate why modern security defenses cannot rely solely on looking for known signatures and indicators of compromise. Both attack techniques abuse protocols that operate inside corporate networks every day. At the individual event level, they may look like legitimate activity, yet in behavioral context, they stand out as clear indicators of compromise.
NAD directly addresses this gap. Instead of relying purely on signature matches across Kerberos or DNS traffic, it highlights deviations from established baselines: who initiated the activity, how frequently it recurred, which services or domains were targeted, and why that matters for a specific infrastructure.
As a result, analysts gain a clear, actionable starting point for investigation. This capability is especially valuable for spotting the signs of APT group activity, which runs stealthily and is designed to blend in with legitimate operations. The importance of this capability will only grow: as attack techniques evolve, detecting suspicious activity at its earliest stages – before it escalates into critical service compromise or a data breach – becomes increasingly vital.
Once the attacker has breached the corporate network, subsequent stages of the attack often involve leveraging standard domain infrastructure protocols: using Kerberos, running DNS queries, accessing internal services, opening network shares, and other common networking actions. Because this activity is virtually indistinguishable from legitimate network traffic, it is extremely difficult to detect it with traditional network attack detection tools.
Kerberoasting and DNS tunneling have long ceased to be exotic techniques. They are becoming standard methods in modern attacks because they allow attackers to execute critical compromise stages while remaining undetected by traditional security tools. A clear example of this trend is seen in latest campaigns, employing both Kerberoasting and DNS tunneling.
Traditional network security tools perform well when the attack features a distinct and identifiable indicator: a characteristic query string, a known malicious traffic pattern, or the source code of an already discovered exploit. While this approach to threat detection remains effective, it cannot always be applied to discovering network attacks that blend seamlessly with legitimate traffic inside a corporate network.
Instead of searching for explicit indicators of attack, Network Anomaly Detection (NAD) analyzes all traffic for suspicious artifacts that deviate from the host’s typical network activity. Within Kaspersky’s solution portfolio, this technology is implemented specifically in the Kaspersky Anti Targeted Attack (KATA) platform.
The system analyzes network traffic data (DNS, DCE/RPC, Kerberos and other packets) and extracts key parameters used to identify anomalous behavior. This approach enables searching for attacks on domain controllers, signs of traffic tunneling and exfiltration, C2 communications, and other scenarios that may point to compromise of network infrastructure.
However, Network Anomaly Detection is not built on a single, universal set of indicators. Each attack scenario employs tailored detection models that account for the specifics of the corresponding network protocol, typical host behavior, and characteristic deviations from that baseline. This article examines two practical examples – detecting Kerberoasting and DNS tunneling – to demonstrate how these principles are implemented in KATA’s NAD rules and why this approach proves more effective than traditional signature-based analysis.
Kerberoasting attack detection by KATA
Why standard tools have a hard time detecting Kerberoasting
The Kerberoasting attack leverages the standard operational logic of the Kerberos protocol. The attacker identifies service accounts configured with a Service Principal Name (SPN), requests a Ticket-Granting Service (TGS) ticket for them, and attempts to crack the password offline using a dictionary attack against the retrieved ticket. If the password is weak or hasn’t been changed in a long time, the adversary can bruteforce it to get it in cleartext. Subsequently, these compromised credentials can be leveraged for both vertical and horizontal movement across the network.
The essence of a Kerberoasting attack is that an adversary possessing a compromised low-privileged account and a valid Ticket-Granting Ticket (TGT) for that account can request TGS tickets with weakened encryption for service accounts with SPNs. Crucially, it doesn’t matter whether the compromised account actually holds access permissions for those services. Having obtained these tickets, the attacker can then take them offline and bruteforce the service account’s password by trying to decrypt the corresponding ticket locally, without generating any network activity. As the encryption key is based on the password hash, the adversary can guess the password upon finding the correct key.
The attacker’s objective is to find a service account that has a simple password. Most likely, this will be an account created manually by the administrators of the infrastructure or a service. This is precisely why attackers are not interested in system service accounts with SPNs (such as CIFS/fileserver.company.local); these are generated automatically and feature highly complex passwords that are impossible to bruteforce.
We should note that the TGS ticket requests made by attackers are identical to standard, legitimate requests. Every domain naturally exhibits a high volume of Kerberos traffic. Therein lies the primary challenge of detecting Kerberoasting: legitimate service ticket requests (TGS-REQ) are indistinguishable from those issued by attackers. Consequently, the primary detection method relies on correlating indirect indicators rather than signature matching. Key indicators include an anomalous request source (atypical host or user account), a surge in requested SPNs within a short time window, attempts to obtain service tickets for sensitive or privileged service accounts, and off-hour timing or unusual request volume when benchmarked against the historical profile of both the user and the host.
Most of these indicators can be detected using NAD technology, which helps analysts cut through high volumes of Kerberos traffic to establish a concrete hypothesis: who initiated the Kerberoasting attack, which service accounts are at risk, and why this activity deviates from the baseline.
In the context of this attack, the network anomaly stems from a single host – likely using a single user account (cname) – receiving TGS tickets ("msg_type": "KRB_TGS_REP") for numerous unique services with SPNs (sname) within a short timeframe. These service accounts are non-system accounts.
Example of a TGS-REQ – TGS-REP event pair from network session attributes
To detect this anomaly, the NAD rule titled “Signs of a Kerberoasting attack” implements the following logic:
From Kerberos network sessions during the search depth period, select only those with a successful Kerberos TGS-REP response, subject to the following conditions:
The IP address that initiated the session must not be excluded in the excl_sip variable.
The requesting client name (cname) must not be included in the excluded users list (excl_users variable).
The SPN (sname) must not be excluded within the rule. System SPNs are omitted from detection logic because they exist across most corporate environments and hold no interest for adversaries in this attack vector; including them in the total count of unique SPNs could lead to predefined threshold being exceeded, triggering false positives.
Extract the cname (the name of the client requesting the TGS-REQ) and sname (SPN itself) from these qualifying sessions.
Group the sessions by the source IP address and client account name (cname), while aggregating sessions with unique SPNs.
Generate an alert if a single IP address using a single client account receives TGS-REP responses for N unique SPN names within the specified search depth window, where N equals or exceeds the threshold variable count_spns.
Within the event regeneration window, group under the initial alert all subsequent alerts associated with the same client IP address. This avoids creating duplicate event records by incrementing the aggregation counter (Total appearances).
We should note that this type of logic cannot be implemented using IDS signatures. Consider creating a Suricata rule designed to detect Kerberos TGS-REP packets. To minimize false positives, we’ll exclude system SPNs (which carry highly complex passwords) and apply a threshold for the number of responses a single client can receive. However, such a rule cannot evaluate the uniqueness of the requested SPNs; it can only track packet counts. As a result, this signature would produce a high volume of false positives because any domain naturally generates large amounts of identical legitimate TGS-REP messages.
Furthermore, adding exclusions and tuning thresholds to fit your specific infrastructure environments is significantly more practical when managed through user variables in the interface rather than directly modifying the underlying structure of the IDS rule itself.
Creating a Network Anomaly Detection rule
Network Anomaly Detection (NAD) rules are written as SQL queries executed against KATA’s ClickHouse database. Below, we demonstrate how to add and deploy a rule.
To begin working with NAD rules, navigate to the “Custom rules” section of the interface and select “Intrusion detection”. Under the “Network Anomaly Detection” tab, you can create a new rule.
The Network Anomaly Detection page UI
When adding a new rule, an analyst can select an appropriate rule template from the prebuilt set supplied with product updates. They can also manually modify the rule added from the template (converting it to a custom rule while keeping the original template intact) or author a rule from scratch using the provided guide.
Upon selecting a template, the analyst can review the rule description and either adjust or leave the default values for the following settings:
Search depth (the lookback window over which the SQL query will run)
Schedule (the execution frequency for running the query against the specified search depth)
Event regeneration period (the timeframe during which identical alerts will be aggregated into a single record rather than displayed as distinct events)
UI for creating a new NAD rule
To ensure the rule functions correctly, we recommend navigating to the “SQL-specific query” tab before deployment to review the variables used within the rule – a description for each variable is available by hovering over the question mark icon.
The variables are lists of IP addresses, dates, strings or numeric values that define the network infrastructure – such as domain controllers, DNS servers, time ranges, critical segments, and other entities. This allows you to tailor each rule to different network environments and incorporate specific infrastructure characteristics without modifying the underlying logic.
In our example, using variables allows you to adjust the “Signs of a Kerberoasting attack” rule as follows without altering the underlying SQL query:
Exclude the source IP address of the TGS-REQ requests from the scope of detection logic (you can specify a single address, a subnet mask, or a dictionary containing addresses and subnets) as well as the requesting client account (accepts a single value or a dictionary with multiple values).
Adjust the threshold value required to trigger an alert based on the number of unique SPNs in the TGS-REQ messages.
Query contents and variables used in the new rule
On this same page, you can test if the rule is functional prior to saving it.
Rule execution test results
When this rule triggers, an NDR:NAD alert is generated. In the alert card, the analyst can review basic information: IP addresses, ports, and participating network endpoints.
Alert card for the NAD rule
From there, the analyst can navigate to the associated event, which provides a detailed breakdown of the anomaly alongside links to the affected hosts.
NAD rule triggering event
If needed, the analyst can view and export the network sessions associated with the alert. These sessions can be accessed directly from the alert or within the event card via the “Show related” drop-down list.
Network sessions that triggered the rule
Within an individual session, the analyst can inspect standard details including interacting parties, data volume sent and received, and other fields and metrics. On the “Attributes” tab, the analyst can review the specific events recorded within that session.
Network session attributes
Detecting DNS tunneling in KATA
How DNS tunnels work
DNS tunneling is a technique used to transmit data or control malware through firewalls by encoding information within DNS protocol requests and responses. Instead of performing standard name resolution, an infected host transmits data encoded within subdomain strings and receives response data via DNS records. This covert channel can be leveraged for C2 communication, bypassing network restrictions, or data exfiltration.
One method of implementing DNS tunneling involves utilizing TXT records. In this scenario, the client issues DNS TXT record queries for domain names where the right-hand portion of the domain name (the higher-level domains) remains static, while the left-hand portion (the lowest-level subdomain) carries encoded or encrypted data sent from the client to the server. Under this structure, a sample domain name might look like ZFcABQAIBA[.]testlab[.]local, where testlab[.]local serves as the static right-hand portion and ZFcABQAIBA represents the variable left-hand string containing the data transmitted by the client.
In response to these queries, the server delivers commands or messages inside the data field of the TXT response. Because the right-hand portion of the domain name remains static, all client queries are consistently routed to the same C2 server, even if the intermediate DNS resolvers targeted by the client change.
DNS query (left) and corresponding response (right) during DNS tunneling via TXT records
It is rather challenging to identify this malicious activity within DNS traffic without generating false positives. DNS traffic is permitted across almost all corporate networks, long domain names occur routinely in both internal and external environments, and TXT records are frequently leveraged for legitimate operational purposes.
Suspicion is established through a combination of indicators: a high volume of long, seemingly random subdomains associated with a single top-level domain, high request frequency, an unusually large number of unique names, non-standard record types, and significant data transfer volumes within a single DNS session.
By analyzing DNS traffic for threat detection, we identified three primary fields of interest:
Requested DNS name
DNS record type
TXT data field within the response
As shown in the image above, all of these fields are present in the DNS response. In a real-world scenario, a tunnel of this nature will transmit a volume of data that is abnormally large compared to standard DNS traffic.
Data exchange within a DNS tunnel
Thus, in the context of DNS tunneling, a network anomaly occurs when 1) a single query source host sends data embedded in the variable left-hand portion of domain names (rrname) while 2) maintaining a static right-hand portion (rrname) and 3) receives DNS server responses containing TXT records (rtype) with varying data (rdata), while 4) the total volume of data transmitted in the left-hand portion of the requested domain name together with the TXT data response (rdata + rrname) exceeds a predefined threshold.
Request and response events from DNS session attributes
When detecting DNS tunneling, the following nuances must be considered:
A single tunnel will not be constrained to a single DNS session; data may be transmitted across multiple sessions with the DNS server, or each individual request may occur within a separate session.
A client DNS query can contain more than one requested domain name.
A DNS response can contain multiple TXT records, as well as a large volume of various non-TXT record types.
Traffic between DNS servers must be excluded, as it duplicates client requests and can trigger false positives.
Although the factors outlined above (an abnormally large or frequently changing left-hand subdomain alongside a static right-hand domain, or an unusually long string in a TXT record) serve as key indicators of DNS tunneling, they can also occur within legitimate network traffic.
These challenges create a high likelihood of false positives when detecting DNS tunneling, particularly when using IDS-based tools. Writing an accurate IDS rule for this type of activity is practically impossible. With rare exceptions, DNS tunneling tools possess static markers that can be leveraged for signature-based detection. However, in the absence of such markers, signature methods fail to deliver high detection accuracy without generating an overwhelming number of false positives. In these cases, a comprehensive approach combining multiple correlated indicators is essential to improve overall detection quality.
DNS tunneling detection logic
To add a rule for detecting this anomaly, you can use the prebuilt “DNS data tunneling via TXT records” template in the new rule creation interface. The “SQL-specific query” tab will display the list of variables used:
user_DNS_servers: a list of internal DNS server addresses within the infrastructure, required for the rule to function correctly and minimize potential false positives
excl_sip: IP addresses to be excluded from the scope of the rule (you can specify a single address, a subnet mask, or a list containing both addresses and subnets)
traffic_size: the threshold value for the total volume of data (in bytes) transmitted through the tunnel
Variables used in the “DNS data tunneling via TXT records” rule
The detection logic for this network anomaly is structured as follows:
From network sessions using the DNS protocol within the timeframe defined by the rule’s search depth, select only those sessions containing at least one TXT response.
Additionally:
The IP address that initiated the session must not be excluded in the excl_sip variable.
The source IP address that initiated the session must not belong to the internal DNS servers listed in the user_DNS_servers variable.
The DNS names requested by the client must not be excluded within the rule.
Split qualifying DNS sessions into individual log lines, each corresponding to an individual request or response. Retain only DNS responses containing TXT data.
Extract DNS names and their associated TXT data from these DNS responses. Retain only unique values.
Group all resulting records by the session’s source IP address, aggregating all unique DNS names and TXT data blocks.
Generate an alert if the combined size (in bytes) of the unique DNS names and TXT response data for a single IP address within the search depth window exceeds the specified threshold (the traffic_size parameter).
Within the event regeneration window, group under the initial alert all subsequent alerts associated with the same client IP address. This avoids creating duplicate event records by incrementing the aggregation counter (Total appearances).
“DNS data tunneling via TXT records” rule triggering event
The primary value of NAD technology in this scenario lies in noise reduction – by minimizing false positives – and faster investigation times. A DNS tunnel rarely presents itself as a single, blatantly malicious request. Instead, it leaves behind a behavioral footprint: repetition, length, domain structure, unusual record types, numerous subdomains branching off an unchanging root domain, and anomalous host behavior. KATA consolidates these indicators into a single alert, presenting the analyst with an actionable attack hypothesis rather than a set of fragmented DNS events.
Prebuilt rules for detecting network anomalies in KATA
KATA users should note that Network Anomaly Detection (NAD) rules are not enabled by default. Rules must be added manually using the procedure described in the preceding sections. This design ensures that analysts can fine-tune rules to fit specific network infrastructures using variables.
Analysts have three ways of creating new rules:
Adding a rule from a prebuilt template and adjusting custom variables. In this case, the rule is classified as a system rule.
Adding a rule from a prebuilt template and modifying its underlying SQL query (which requires enabling the “Unlock all template values” option) to create a custom rule based on the template. When modified this way, the rule transitions from a system rule to a custom rule.
Authoring a custom rule from scratch, which requires a basic understanding of ClickHouse SQL queries and familiarity with the product documentation.
As of this publication, the product ships with 59 prebuilt NAD rule templates (with additional templates delivered via product updates). KATA supports running up to 200 active rules simultaneously.
Prebuilt rules are divided into six categories:
Large Data Transfers: tracking abnormally large network sessions across various protocols during regular hours, at night, or over weekends.
Suspicious Connections: detecting suspicious connections that may indicate hazardous activity, shadow IT, evasion of attack detection mechanisms, and other threats.
Connections to Suspicious Resources: detects actions that violate security policies, potential data exfiltration beyond the perimeter, and unauthorized internet access originating from secured network segments.
C2 Communication: identifies network sessions characteristic of a potential C2 communication channel or tunnel.
The table below lists the rule templates for detecting network anomalies in KATA:
Rule category
Rule name
Protocols used
Large Data Transfers
Data tunneling in DNS traffic
DNS
ICMP, TCP, UDP, RDP, SSH or LDAP sessions with a large volume of traffic (6 rules)
ICMP, TCP, UDP, RDP, SSH, or LDAP (depends on selected rule)
ICMP, TCP, UDP, RDP, SSH or LDAP sessions with a large volume of traffic at nighttime (6 rules)
ICMP, TCP, UDP, RDP, SSH, or LDAP (depends on selected rule)
ICMP, TCP, UDP, RDP, SSH or LDAP sessions with a large volume of traffic on non-working days (6 rules)
ICMP, TCP, UDP, RDP, SSH, or LDAP (depends on selected rule)
Suspicious Connections
Queries to unknown DNS servers
DNS
Use of unauthorized routes
TCP, UDP
Use of suspicious ports for connections to external addresses
TCP, UDP
Use of non-typical protocols for connections
TCP, UDP, HTTP, HTTPS, DNS, SMTP
Inconsistencies with firewall configuration
TCP, UDP
Use of unauthorized ports for RDP or SSH sessions (2 rules)
RDP or SSH (depends on selected rule)
Interactions with external IP addresses over the RDP or SSH protocol (2 rules)
RDP or SSH (depends on selected rule)
Suspicious RDP sessions with domain controllers
RDP
Connection to an unknown server via Kaspersky Security Center ports
TCP, UDP
Domain Attacks
Signs of a DCSync attack
DCE/RPC
Signs of a DCShadow attack
DCE/RPC
Signs of DHCP spoofing
DHCP
DNS queries to Canarytoken domains
DNS
Signs of a Kerberoasting attack
Kerberos
Signs of an AS-REP Roasting attack
Kerberos
Signs of a brute-force password attack on SSH
SSH
Signs of SOAPHound usage
LDAP
Large-volume Active Directory object data collection via LDAP queries
LDAP
Reconnaissance Activity
Getting information about a task in the Task Scheduler
DCE/RPC
Getting a list of Kerberos users
Kerberos
LDAP queries to rights delegation attribute
LDAP
LDAP queries to attribute for getting administrator passwords
LDAP
Signs of an internal horizontal port scan
TCP, UDP
Signs of an internal vertical port scan
TCP, UDP
DNS zone data replication requests sent from sources other than DNS servers
DNS
Successfully completed requests for DNS zone data replication sent from sources other than DNS servers
DNS
LDAP query targeting a critical attribute of insecure credentials
LDAP
Enumeration of domain accounts via LDAP queries
LDAP
Exceeding the threshold for requested critical attributes in LDAP queries
LDAP
LDAP search queries containing a high number of critical attributes
LDAP
Connections to Suspicious Resources
Queries to unauthorized domain names
DNS
Transmission of large data volumes to cloud storages
TCP, UDP, DNS
Connections to cloud storages or file transfer services
TCP, DNS
Connections to public repositories
TCP, DNS
Connections to resources of programs for traffic tunneling
TCP, DNS
С2 Communication
Possible queries to DGA domains
DNS
DNS data tunneling via TXT records
DNS
Numerous blocked connections to external addresses
TCP, UDP
Conclusion
The examples of Kerberoasting and DNS tunneling clearly demonstrate why modern security defenses cannot rely solely on looking for known signatures and indicators of compromise. Both attack techniques abuse protocols that operate inside corporate networks every day. At the individual event level, they may look like legitimate activity, yet in behavioral context, they stand out as clear indicators of compromise.
NAD directly addresses this gap. Instead of relying purely on signature matches across Kerberos or DNS traffic, it highlights deviations from established baselines: who initiated the activity, how frequently it recurred, which services or domains were targeted, and why that matters for a specific infrastructure.
As a result, analysts gain a clear, actionable starting point for investigation. This capability is especially valuable for spotting the signs of APT group activity, which runs stealthily and is designed to blend in with legitimate operations. The importance of this capability will only grow: as attack techniques evolve, detecting suspicious activity at its earliest stages – before it escalates into critical service compromise or a data breach – becomes increasingly vital.
The evolution of vulnerability management in the agentic era is characterized by continuous telemetry, contextual prioritization and the ultimate goal of agentic remediation.
Zero Trust is not a thing; it is an idea. It is not a product; it is a concept – it is a destination that has no precise route and may never be reached.
President Donald Trump suggested Saturday that the U.S. used cyberattacks or other technical capabilities to cut power off in Caracas during strikes on the Venezuelan capital that led to the capture of Venezuelan President Nicolás Maduro.
If true, it would mark one of the most public uses of U.S. cyber power against another nation in recent memory. These operations are typically highly classified, and the U.S. is considered one of the most advanced nations in cyberspace operations globally.
Artificial intelligence is transforming the way we work, learn, and innovate—and it’s doing so at a pace that surpasses every major technology before it. Microsoft’s inaugural AI Diffusion Report offers a comprehensive look at how AI adoption is accelerating worldwide, drawing on data from more than 100 countries. In less than three years, more than 1.2 billion people have used AI tools, a rate of adoption faster than the internet, the personal computer, or even the smartphone. This rapid diffusion underscores AI’s potential as a general-purpose technology but also highlights the urgent need to ensure equitable access.
The report introduces three indices—the AI Frontier Index, the AI Infrastructure Index, and the AI Diffusion Index—to help policymakers, researchers, and industry leaders understand where breakthroughs are happening, where capacity exists to scale, and where AI is being used to improve lives. These insights show that adoption is fastest where connectivity and digital infrastructure are strongest, while nearly four billion people still lack the basics needed to participate in the AI economy. Bridging this gap is essential to avoid deepening global divides.
Beyond the numbers, the report illustrates the need for collaborative action to expand access to digital infrastructure, strengthen skills development, and promote responsible AI policies. By investing in these foundational elements, governments and organizations can unlock AI’s potential for growth and innovation. The data makes clear that speed alone does not guarantee shared prosperity—broad accessibility does.
To explore the full findings and recommendations, read the AI Diffusion Report.
As Abu Dhabi and Dubai kick off a significant week hosting annual energy and technology conferences, we want to share details of our ongoing and planned investments in the United Arab Emirates. Roughly two and a half years ago, we embarked on a new AI initiative with the encouragement and support of both the United States and UAE governments. Much of this progress has involved a new partnership with G42, the UAE’s sovereign AI company, with whom we’re making critical progress.
All told, Microsoft will invest $15.2 billion USD in the UAE between the start of this initiative in 2023 and the end of this decade, in 2029. This is not money raised in the UAE. It’s money we’re spending in the UAE. And as we do everywhere in the world, we’re focused not just on growing our business but also on contributing to the local economy. This involves bringing together three critical factors – technology, talent, and trust.
On some days, it feels like the tech sector is gripped in a rhetorical race to announce ever larger, sky-high numbers. We believe in moving fast while staying grounded and being transparent about our investment details. And we want to share our strong conviction that our investments benefit the shareholders of our company, the people of the UAE, and the relationship between our two nations.
Our investment numbers
Our $15.2 billion USD investment includes the following:
Beginning in 2023 and through the end of this calendar year, Microsoft will have invested and spent just over $7.3 billion in the UAE. This includes our $1.5 billion equity investment in G42, more than $4.6 billion in capital expenses in advanced AI and cloud datacenters in the country, and more than $1.2 billion in local operating expenses and the cost of goods sold.
From the start of 2026 to the end of 2029, we will spend more than $7.9 billion in the UAE. This includes more than $5.5 billion in capital expenses for ongoing and planned expansion of our AI and cloud infrastructure, including new steps we will share publicly in Abu Dhabi this week. It also includes almost $2.4 billion in planned local operating expenses and the cost of goods sold.
An investment in world-leading technology
Some of our most important work involves exporting world-leading technology from the United States to the UAE. This includes the GPUs essential to power AI in our datacenters across the country that support the UAE’s people and institutions.
Microsoft was one of the few companies during the previous administration to secure export licenses from the Commerce Department to ship GPUs to the UAE. In no small measure, this is because of the substantial work we did to meet the strong cybersecurity, national security, and other technology conditions required by these licenses. These licenses enabled us to accumulate in the country the equivalent of 21,500 Nvidia A100 GPUs, based on a combination of A100, H100, and H200 chips.
Microsoft was also the first company this year under the Trump administration to secure export licenses from the Commerce Department to ship GPUs to the UAE. Approved in September, these were based on updated and stringent technology safeguards. These licenses enable us to ship the equivalent of 60,400 additional A100 chips, in this instance involving Nvidia’s even more advanced GB300 GPUs.
While the chips are powerful and the numbers are large, more important is their positive impact across the UAE. We’re using these GPUs to provide access to advanced AI models from OpenAI, Anthropic, open-source providers, and Microsoft itself. We’re supporting AI-enabled applications, including our Copilot applications, from a wide variety of local and international providers. And we’re partnering with G42 to support public and private sector organizations across the UAE economy, as well as consumers across the country.
The UAE’s ranking in the Microsoft AI Diffusion Reportpublished last week shows the country leading the world in per capita AI usage. With 59.4 percent of the population using generative AI, the UAE is ahead of Singapore, which is in second place at 58.6 percent. Beyond these two, no other country tops the 50 percent mark. Microsoft’s infrastructure challenge in the UAE is not a risk of getting ahead of demand but keeping pace with it.
Investing in talent
Microsoft’s investment in the UAE is not just about technology, it’s also about people. By cultivating AI talent and skilling individuals to develop, deploy, and use AI in a way that reflects the region’s unique needs, Microsoft is helping to ensure that the UAE remains on the leading edge of AI diffusion.
Today, Microsoft’s presence in the UAE reflects this commitment. Our growing team includes almost 1,000 full-time employees and related staff representing 40 nationalities. Nearly 100 of our employees are engineers, supported by an Emirati partner ecosystem that has grown almost threefold in just two years, now with 1,400 firms employing nearly 45,000 professionals across the country.
This year, we established the Global Engineering Development Center in Abu Dhabi to attract world-class tech talent to the UAE. Our engineers not only develop new products and services for Microsoft, but support institutions and businesses across the region so they can use AI and cloud technologies to transform their own operations. As we look to the future, we aspire to grow our engineering teams further and add a new focus on domain-specific AI models and applications that will propel advances in key scientific and technological fields.
We also opened a new center for the Microsoft AI for Good Lab in Abu Dhabi, staffed by PhD level research talent specializing in large-scale AI models, vision-language models, and post training techniques. Backed by Azure compute grants allocated to partner organizations, this team collaborates with nonprofits, start-ups, researchers, academic institutions, and local businesses to address humanitarian challenges across the Middle East and Africa using AI. Already, the Lab has partnered with researchers to train large language models for low-resource languages, including those spoken in Malawi, Tanzania, Kenya, Uganda, and the Democratic Republic of the Congo – helping ensure that AI serves communities that risk being left behind in the AI age.
As the Microsoft AI Diffusion Report underscores, people need digital proficiency to fully participate in an AI-driven economy. Without the right skills, AI risks deepening inequality rather than broadening opportunity. That’s why skilling is a core pillar of our investment in the UAE.
Last November, we committed to skill one million people in the UAE by the end of 2027–and we’re well on our way to meet – and exceed–our goal. Last month at GITEX, Microsoft partnered with UAE government entities to launch an initiative to upskill 120,000 government employees across the federal government, Abu Dhabi, Dubai, and Sharjah. We will also skill 175,000 students and 39,000 teachers through collaborations with GEMS, Abu Dhabi Department of Education (ADEK), and the Knowledge and Human Development Authority (KHDA). We will announce new steps in this area on Thursday in Dubai.
Talent is the engine of AI leadership. Attracting, nurturing, and building AI talent and know-how is essential to the UAE turning its vision of becoming a global leader into a reality.
Strengthening trust
Ultimately, the use of AI depends on trust. People and institutions need to trust that AI will be developed and deployed with responsible safeguards. They need to have confidence that the cybersecurity of AI chips, models, and services will be protected. And they rightly expect AI to serve the public broadly, with cause for optimism that AI will reach and support the Global South.
Given the role of export controls and other trade issues, the flow of advanced GPUs and AI models also requires trust between nations. This in turn requires clear rules and agreements, coupled with effective compliance systems. And as always, trust between nations depends on strong relationships between its people, grounded in mutual respect and appreciation for each other’s cultures.
We’re focused on supporting all these needs.
One important part of this is the Responsible AI Future Foundation, or RAIFF. G42, Microsoft, and Mohamed bin Zayed University of Artificial Intelligence (MBZUAI) founded this new foundation in Abu Dhabi in Februaryto promote responsible AI standards and best practices in the Middle East and across the Global South. This foundation is advancing research on the technical and ethical elements of responsible AI and is developing frameworks to ensure ethical development and deployment of AI systems, accounting for cultural diversity.
A second element comes to life through the first annual Abu Dhabi Global AI Summit, which began Sunday. Hosted by G42, Microsoft, the Responsible AI Future Foundation, and Eurasia Group’s GZERO Media, this Summit brings government ministers, private sector executives, and AI leaders together to discuss what’s needed to drive AI diffusion across the Global South. We meet at a time when there is a growing risk that uneven AI diffusion may widen the economic and societal gaps that divide the world. It’s imperative that governments, businesses, and non-governmental organizations collaborate and take new steps to promote broader access to AI.
Both these elements build on a third and deeper initiative that Microsoft and G42 have advanced during the past two years. In conjunction with our $1.5 billion investment, Microsoft and G42 created last April a first–of–its–kind binding frameworkbetween two private companies. Developed in close consultation with the U.S. and UAE governments, this Intergovernmental Assurance Agreement (IGAA) ensures that both our companies meet or exceed U.S. standards in critical areas such as cybersecurity and physical security, export controls and technology transfer, data protection and responsible AI, and Know Your Customer (KYC) best practices.
As we drafted the IGAA, we consulted not only leaders from government ministries in our two countries, but with members and staff of both political parties in both houses of Congress in Washington, D.C. We listened to feedback and adapted the IGAA to address their suggestions. And we’ve built a strong compliance infrastructure to implement these requirements based on industry best practices and auditing standards.
All these steps help bolster mutual confidence and trust between our two governments. But trust between nations also grows through relationships among people. That’s why we’re advancing a fourth and new element this week, traveling to Abu Dhabi with a Seattle delegation of public and private leaders. The group includes a former Governor and local leaders in economic development, higher education, medical research, the non-profit community, and sports. The goal is to deepen understanding, exchange ideas, and explore solutions that can advance both regions.
Looking to the future
Microsoft is committed to the future of the UAE and a strong relationship between our two nations. We believe in the UAE’s long-term economic vision and the role the UAE and the U.S. continue to play together to support peace, stability, and growth across the Middle East.
As we do everywhere we do business, Microsoft is committed to a broad perspective and long-term approach. Our work in the UAE has underscored the importance of connecting technology investments to initiatives to attract and develop the talent needed for a vibrant and self-sustaining tech ecosystem. And work to advance trust, which may seem peripheral to some, is in fact of central importance. From stronger business practices to broader international ties, trust is a critical catalyst for technology success at a local and global level.
Technology is our business and we’re as excited as anyone by its potential. But we know that ultimately there is only one test that matters. It’s how our technology empowers others to achieve more. Like every public company, our shareholders rightly expect us to deliver value to customers in ways that enable us to continue to grow. But we also judge ourselves by whether we are generating local opportunities and growth that go well beyond ourselves. Across the UAE, we’re committed to passing this test.
CSRI finds China and Russia may be coordinating ‘grey zone’ tactics against vulnerable western infrastructure
China and Russia are stepping up sabotage operations targeting undersea cables and the UK is unprepared to meet the mounting threat, according to new analysis.
A report by the China Strategic Risks Institute (CSRI) analysed 12 incidents in which national authorities had investigated alleged undersea cable sabotage between January 2021 and April 2025. Of the 10 cases in which a suspect vessel was identified, eight were directly linked to China or Russia through flag-state registration or company ownership.
VirusTotal has incorporated a powerful new tool to fight against
malware: JA4 client fingerprinting. This feature allows
security researchers to track and identify malicious files based
on the unique characteristics of their TLS client communications.
JA4: A More Robust Successor to JA3
JA4,
developed by
FoxIO, represents a significant
advancement over the older JA3 fingerprinting method. JA3's
effectiveness had been hampered by the increasing use of TLS
extension randomization in https clients, which made
fingerprints
less consistent. JA4 was specifically designed to be
resilient to this randomization, resulting in more stable and
reliable fingerprints.
Unveiling the Secrets of the Client
Hello
JA4 fingerprinting focuses on
analyzing the
TLS Client Hello packet, which is sent unencrypted from
the client to the server at the start of a TLS connection.
This packet contains a treasure trove of information that can
uniquely identify the client application or its underlying
TLS library. Some of the key elements extracted by JA4
include:
TLS
Version: The version of TLS supported by the
client.
Cipher
Suites: The list of cryptographic algorithms the client can
use.
TLS
Extensions: Additional features and capabilities supported
by the client.
ALPN
(Application-Layer Protocol Negotiation): The
application-level protocol, such as HTTP/2 or HTTP/3, that
the client wants to use after the TLS
handshake.
JA4 in Action: Pivoting and Hunting on
VirusTotal
VirusTotal has integrated JA4
fingerprinting into its platform through the behavior_networkfile
search modifier. This allows analysts to quickly
discover relationships between files based on their JA4
fingerprints.
To find the JA4 value, navigate to the "behavior" section of
the desired sample and locate the TLS subsection. In addition
to JA4, you might also find JA3 or JA3S there.
Example Search: Let's say you've encountered a suspicious
file that exhibits the JA4 fingerprint
"t10d070600_c50f5591e341_1a3805c3aa63" during VirusTotal's
behavioral analysis.
You can click on this JA4 to pivot using the
search query
behavior_network:t10d070600_c50f5591e341_1a3805c3aa63
finding other files with the same fingerprint This search
will pivot you to additional samples that share the same JA4
fingerprint, suggesting they might be related. This could
indicate that these files are part of the same malware family
or share a common developer or simply share a common TLS
library.
Returns files that match the
JA4_A and JA4_C components of the JA4 hash while allowing
for variations in the middle section, which often corresponds
to the cipher suite. This technique is useful for identifying
files that might use different ciphers but share other JA4
characteristics.
YARA hunting rules using the
"vt" module can be written to
automatically detect files based on their JA4 fingerprints.
Here's an example of a YARA rule that targets a specific JA4
fingerprint:
This rules will flag any file submitted to VirusTotal that
exhibits the matching JA4 fingerprint. The first example only
matches "t12d190800_d83cc789557e_7af1ed941c26" during
behavioral analysis. The second rule will match a regular
expression /t10d070600_.*_1a3805c3aa63/, only matching JA4_A
and JA4_C components, excluding the JA4_B cipher suite. These
fingerprints could be linked to known malware, a suspicious
application, or any TLS client behavior that is considered
risky by security analysts.
VirusTotal's adoption
of JA4 client fingerprinting will provide users with an
invaluable tool for dissecting and tracking TLS client
behaviors, leading to enhanced threat hunting, pivoting, and
more robust malware identification.
Kent Ickler & Jordan Drysdale // BHIS Webcast and Podcast This post accompanies BHIS’s webcast recorded on August 7, 2018, Active Directory Best Practices to Frustrate Attackers, which you can view below. […]
John Strand talks about how BHIS pen tests companies who use the cloud. Want to know how you can defend against attacks in your cloud infrastructure? Keep your eyes peeled for […]

 Login