Two critical PHP vulnerabilities (CVE-2026-109618 and CVE-2026-109619) can allow unauthenticated attackers to execute code on affected web servers. Both carry a CVSS v4.0 score of 9.2, and exploitation attempts are already being observed in the wild.
PHP has released the following fixed versions:
PHP branch Fixed version
PHP 8.5
8.5.12
PHP 8.4
8.4.27
PHP 8.3
8.3.36
PHP 8.2
8.2.35
If you manage your own server or VPS, install the appropriate update immediately.
Expect to see quite a few websites serving error pages today: Nearly 70 percent of websites need to update their core software to fix a pair of vulnerabilities that allow an attacker to seize full control over affected servers. Experts say there are working exploits for the flaws, and that these critical bugs are already being exploited in the wild.
Image: Shutterstock.com, Sashkin.
The flaws at issue are present in PHP, the programming language that powers sites running on a large number of web publishing systems, including Drupal, Magento, Joomla and WordPress. Earlier today, PHP released an emergency security update to fix two critical bugs that can allow an attacker to execute code of their choosing on a vulnerable server.
Reutersreports that government websites in Europe and elsewhere went offline today after the PHP vulnerabilities were disclosed. Cloudflare said it has already detected some exploitation of the flaw, and that at 3:02 am (UTC) it implemented web application firewall rules to protect websites from attack traffic seeking to exploit the bugs, which could cause a denial of service condition, remote code execution, and data exposure.
OpenAI, which was involved in the vulnerability research and outreach, said “given the severity of these flaws and PHP’s widespread use, we consider this one of the most impactful security issues in recent memory.”
Censys, a company that tracks the technology used by Internet hosts, said a recent scan identified approximately 2.58 million Internet facing hosts and 54.9 million web properties running PHP.
Security experts at Wiz said every PHP version released in the last decade is affected by at least one of these vulnerabilities [full disclosure: Wiz is an advertiser on this blog].
“These findings rank among the most severe vulnerabilities discovered in PHP, and arguably in software history,” reads a blog post published today by a team of researchers at Wiz, which was one of several organizations credited with discovering the vulnerabilities. “The underlying flaws had been present for decades, but demonstrating their exploitability required an exceptionally complex chain of steps, at the edge of what human researchers could practically achieve. Frontier AI models substantially reduced that barrier, turning a longstanding flaw into an exploit.”
The Wiz researchers say it is likely the PHP vulnerabilities will be mass-exploited to install web-based backdoors or “web shells,” which give attackers a web-based panel that allows them to remotely control infected sites. Wiz said that prior to the PHP bugs being publicly disclosed, the company worked with the PHP team, Calif and OpenAI to measure the size of the problem and coordinate patch verification and disclosure.
The PHP zero-day vulnerabilities are being tracked by their CVE numbers, CVE-2026-109618 and CVE-2026-109619, and they affect all web servers running PHP 5.4 or later. The bugs are fixed in PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35.
According to Wiz, PHP is so deeply embedded in many web applications that we are likely to see organizations struggling to patch these vulnerabilities for some time to come, comparing this PHP vulnerability pair with the Log4Shell weakness that emerged in 2021 — a widespread, severe-as-it-gets security flaw in Log4j, a popular Java logging framework.
“A vulnerability in core PHP reaches far beyond a single application,” the Wiz researchers wrote. “PHP runs across clouds, hosting providers, content-delivery networks and millions of independently managed servers. Reducing exposure before the technical details became public required coordinated work across that entire ecosystem.”
The SANS Internet Storm Center is keeping an eye on major software platforms that are shipping updates to deal with these PHP flaws. For example, Ubuntu just released updated PHP packages. For a technical deep-dive on these vulnerabilities that tells the timeline of the discovery of these bugs in a comic book style, check out this post from Calif, another technology company credited with finding the PHP flaws.
A snapshot of php2shell.censys.com, the website Censys set up to track the PHP vulnerabilities.
This is a fast-moving story. Updates will be noted here with timestamps.
Update, 2:30 pm ET: Add figures from Censys and a link to Calif’s writeup.
The mission of Microsoft Security’s Frontier Offensive Research & Generative Exploitation (FORGE) Lab is to advance the frontier of autonomous security engineering. We’re building a team that enables AI-native vulnerability research at Microsoft, pushing the boundaries of finding and fixing zero-day vulnerabilities. Four principles guide that work: autonomy over labor, defense through offense, building ecosystems over individual examples, and understanding over findings. This post reflects those principles in practice across Windows, the Linux kernel, and widely used open-source projects.
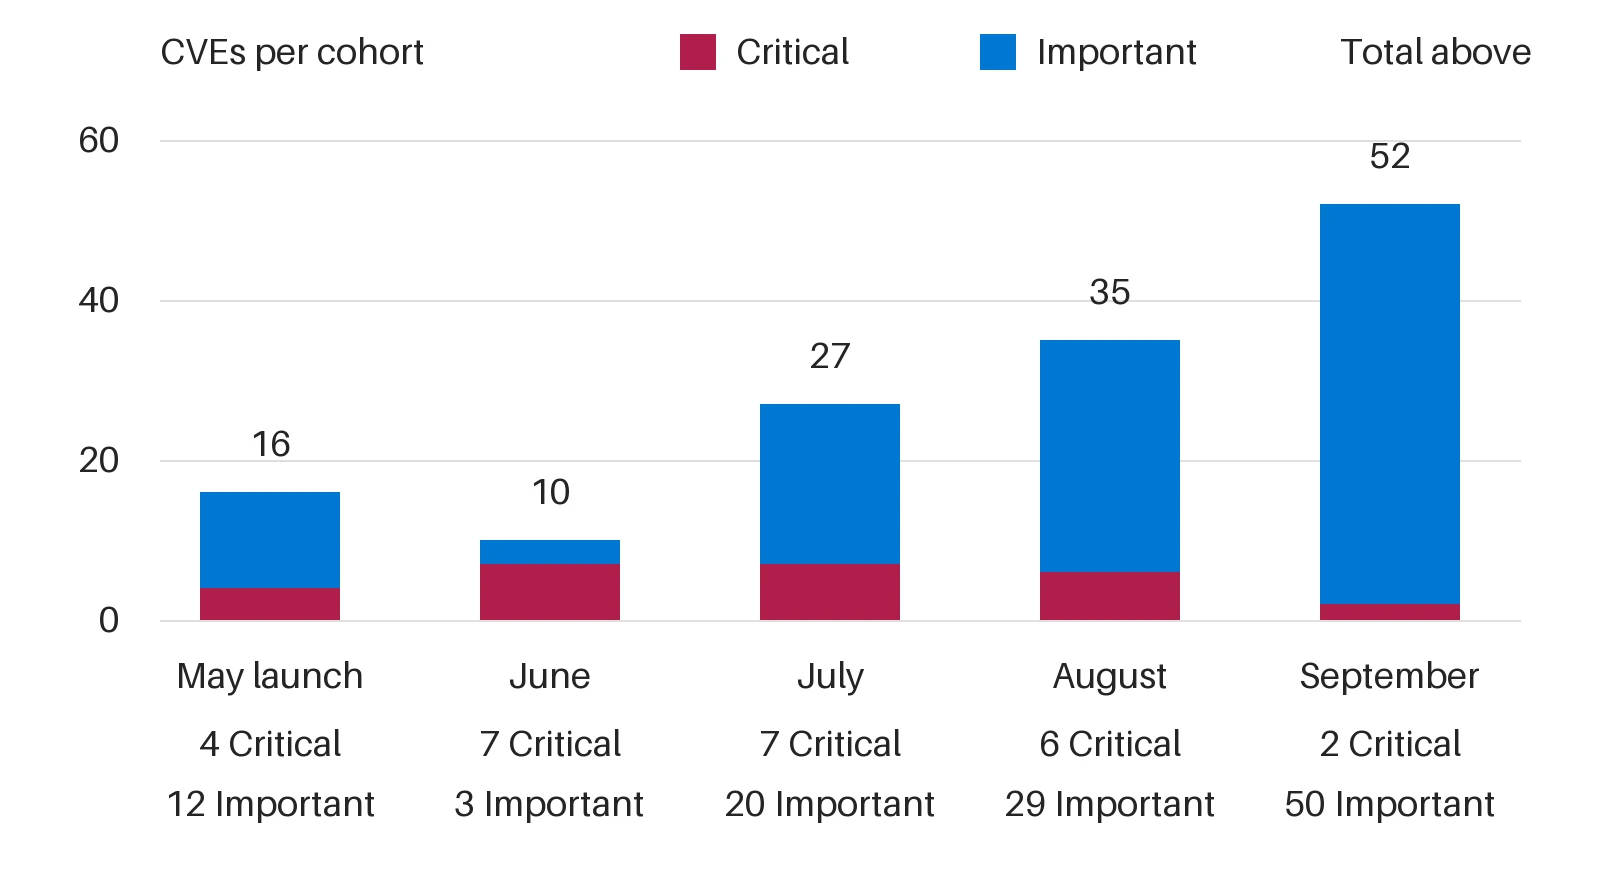
From May 2026 through September 2026, FORGE helped discover Windows vulnerabilities assigned 140 common vulnerabilities and exposures (CVEs), including 52 addressed in September 2026’s security release alone. The work reaches well beyond Windows. FORGE members submitted 155 internally validated reports across 23 open-source projects, including the Linux kernel. And through Akrites, a Linux Foundation initiative that coordinates confidential remediation and disclosure for vulnerabilities in critical open-source software, one of our Linux reports became the first Akrites submission to result in a patch merged into the Linux kernel.
These results demonstrate that agentic discovery can operate at meaningful volume, but they also expose the next constraint. Finding a difficult vulnerability proves an agent’s frontier capability. Repeatedly converting such findings into security updates requires a different kind of system—one that can move credible work through validation, remediation, and release. Discovery creates security value only when validation and remediation can keep pace. For security leaders, the question is no longer only whether AI can find vulnerabilities, but whether an organization can validate and fix them as fast as they are found.
Three lessons follow, each marking a shift in how we approach vulnerability research:
From frontier capability to scale.
From token consumption to reasoning economics.
From isolated discovery to coordinated validation and remediation.
The scarce resource is not always model intelligence. It can be a working build and deployment, a reproducible trigger, or even an engineer’s time.
At FORGE Lab, we use the multi-model agentic scanning harness, codename MDASH, to organize this work. Our May 2026 introduction detailed its design, while the June 2026 update covered pipeline improvements and benchmark analysis. Here, we focus on what those experiences teach us about operating vulnerability research at scale—across Windows and open-source projects.
140 CVEs addressed through Microsoft Patch Tuesday since May 2026. Monthly totals reflect announcement and servicing cohorts, not discovery dates or scan throughput. Source: Microsoft FORGE Lab study, May 2026 to September 2026.
Shift 1. From frontier capability to scale
The frontier question is whether a system can find a bug that demands deep reasoning, as we explored in our early work on the CyberGym benchmark. The scale question is whether it can repeat that result across targets without rebuilding every environment, investigation, and review process from scratch. Better models still matter, especially for difficult or unfamiliar bug classes. But once discovery becomes repeatable, model capability is only one constraint on useful output.
Adding auditors can increase candidate volume without increasing the rate of validated findings or shipped fixes. If reports arrive faster than reviewers—in our case, Microsoft Security Response Center (MSRC)—can resolve them, the immediate result is a growing queue. A larger search budget can even reduce useful throughput when duplicate or poorly supported reports consume attention that stronger findings need.
The unit to optimize, therefore, is neither the scan nor the report. It is a reproducible finding that advances with enough evidence for the next stage to act. Reusable preparation, deduplication, and review capacity are therefore core components of the research system.
As agentic systems produce more candidates, the bottleneck shifts from discovery to determining which reports are real, reachable, and security-relevant. Project-specific automated provers—such as proof of vulnerability (PoV)/proof of concept (PoC) generators, harness builders, and trigger-input finders—turn plausible reports into reproducible evidence that engineers and maintainers can act on. By finding crashing inputs, confirming reachable execution paths, and producing regression-ready triggers within each project’s build and test environment, these tools can help reduce human triage, accelerate remediation, and make vulnerability research sustainable at scale. For example, by leveraging deterministic algorithms such as abstract syntax tree (AST), one of our internal projects reduced about 45% duplicate findings across multiple scans of the same code which reduced the load on the PoC generator and subsequently human triage effort.
More candidates do not create more throughput when the review queue grows faster than fixes ship.
Shift 2. From token consumption to reasoning economics
At scale, every repeated orientation, speculative branch, and redundant debate carries a cost. But minimizing tokens alone is the wrong objective. A short, ambiguous report may be cheap to generate yet expensive to investigate; a longer analysis that establishes the missing execution path may reduce total system cost.
The key question is where the next unit of reasoning will change a decision. If an index can identify callers, asking a frontier model to rediscover them wastes capacity. If the uncertainty is whether two lifetime conditions can coexist across callbacks, deeper reasoning may be warranted. If the question is whether an input triggers the failure, an executable check can provide evidence that more prose cannot.
MDASH combines frontier and distilled models, specialized auditors, and code-analysis tools, enabling work to be allocated by task. That flexibility does not guarantee optimal allocation. Routing routine work to cheaper models, reusing verified context, and escalating unresolved questions to stronger reasoning are hypotheses to test—not efficiency gains to assume.
A useful allocation policy starts by identifying what remains unknown: a caller, a build configuration, a reproducer, or a causal explanation. The next action should close that specific evidence gap. Repeating a review without adding evidence spends more tokens while preserving the same uncertainty. Early filtering can also discard real bugs, so any savings must be measured against coverage and missed findings.
Scan outcomes can also become training data. At scale, vulnerability scanning should become a training loop, not only a discovery pipeline. Each MDASH run produces signals that can improve future models: true-positive and false-positive verdicts, duplicate findings, failed reachability claims, reviewer feedback, verifier results, severity assessments, patch outcomes, and regression-test evidence. Capturing those signals with the code context and causal argument behind each candidate creates the dataset needed for reinforcement learning and fine-tuning specialized cyber models. The goal is for future models to learn not just what a vulnerability looks like, but which findings survive validation, which explanations help humans and provers act, and which patterns lead to useful remediation.
Spend reasoning to remove uncertainty, not simply to produce more analysis.
Shift 3. Validation and remediation as a continuous learning loop
Validation and remediation are not downstream cleanup; they are part of the discovery loop. Each candidate should move through automated verification, human review, patch development, and regression testing, with every stage returning evidence to the system. A reproducible trigger strengthens the report, guides the fix, and can seed a regression test. A failed validation is also useful when it records why: an unreachable path, missing precondition, incorrect build configuration, insufficient attacker control, duplicate report, or incomplete causal explanation.
That evidence is how the system improves. Project-specific provers, harnesses, and trigger generators accumulate operational knowledge about how each target builds, runs, fails, and accepts fixes. Remediation outcomes show the discovery pipeline which evidence changed a decision, which assumptions failed, and which bug patterns warrant more or less attention. The objective is to make every investigation leave reusable capacity behind: a validated trigger, clearer invariant, better harness, stronger regression test, or routing rule that prevents the same mistake.
Human attention remains essential, but it should concentrate where judgment has the highest leverage: assessing security impact, reviewing patches, and determining whether a change restores the component’s intended invariant. Automation can handle the repeatable work of establishing reachability, reproducing behavior, and preserving evidence. Over time, this loop converts individual findings into system knowledge—raising the quality of future discovery while shortening the path from credible report to shipped fix.
A reproducible defect is not yet a serviced fix. To shorten the path from discovery to remediation, MDASH needs to operate as part of the engineering loop: continuously scanning code, connecting findings to the builds and artifacts produced by continuous integration and continuous delivery (CI/CD), and feeding validation results back into development, as described in the Windows team’s blog post. Broad analysis can identify suspicious code paths, but component-specific proving needs the right binaries, symbols, configurations, harnesses, and runtime conditions to reproduce a candidate defect against the version that matters for customers and releases. Each handoff should be both owned and machine-usable: research supplies the candidate claim, causal path, and uncertainty; proving supplies execution evidence from the relevant build artifact; component teams assess the violated invariant, repair strategy, compatibility risk, and related variants; and servicing connects the approved change to release validation. A failed reproduction, rejected finding, incomplete patch, or regression result should feed back into MDASH as structured evidence, not simply move a ticket into another queue. The goal is not to remove human code review or release validation, but to automate the repeatable work around them—finding candidates, selecting artifacts, reproducing behavior, preserving evidence, suggesting related paths, and returning what was learned to the next scan.
The goal is to build an organization-wide system that automates repeatable work while preserving clear engineering accountability.
Transferring security research to help open source projects
In open source, all three constraints apply at once. Each project has its own setup costs, mix of analysis and execution work, and maintainer workflows and review capacity. Within Windows, vulnerability research connects to established component owners and servicing infrastructure. Across open-source projects, reusable methods can reduce repeated setup, but they cannot replace the technical and human context required to move a finding toward a fix.
Open-source vulnerability reporting snapshot
Over three months, FORGE members audited open-source projects spanning kernels, runtimes, networking libraries, container technologies, and media parsers. The team submitted 155 internally validated reports across 23 projects. At the time of writing, 93 reports across 14 projects or project families had documented maintainer acknowledgement or acceptance: apple/container, apple/containerization, curl, Escargot, FFmpeg, Hyperlight, Linux, llama.cpp, Node.js, PyRIT, Rust, SQLite, vLLM, etc.
Since the reports are at different stages of that process, only subsets are publicly disclosed today, such as curl’s CVE-2026-9545 and CVE-2026-13608, Node.js’s CVE-2026-56848, and Linux kernel CVE-2026-64563. Our public CVE index lists the CVEs currently cleared for disclosure, and you can find all our public channel Linux kernel reports through lore.kernel.org query.
Measured costs of automated validation
MDASH surfaced thousands of suspicious locations in the Linux kernel, and our validation agents produced supporting evidences for 627 findings. The figures below summarize automated validation costs for a subset of these efforts. Across 182 confirmed crash findings, generating a PoC averaged $3.61 in model cost and 21.5 minutes. For six selected cases, using automatic exploit generation (AEG) to test local privilege-escalation potential averaged $8.56 and 25.4 minutes.
Average model and time cost for Linux kernel automated validation. Per-case averages reflect all attempts for successful cases using GPT-5.5. Source: Microsoft FORGE Lab Linux kernel automated validation study, 2026.
These evaluations used GPT-5.5, without extensive task-specific tuning of either the model or the harness. These averages include all attempts associated with the successful cases shown, but exclude initial screening, candidates that failed or were filtered out, and human investigation and patch preparation. Within those limits, the results still strongly indicate that automated validation can produce useful results at practical cost and latency, even at Linux-kernel scale. Tighter co-design of models and agent harnesses could improve both validation yield and efficiency. If costs fell by another order of magnitude, for example, 10x or even 50x, the range of findings that could be economically validated would expand substantially, further reshaping vulnerability research.
FORGE OSS Bug Hunt Party: Human coordination at scale (Hackathon)
Looking back to those efforts, technical evidence was only part of the job. Getting it fixed also required understanding and respecting each project’s context and workflow: some required a patch while others did not; some preferred private disclosure while others used public channels; and maintainers sometimes differed on whether an issue crossed a security boundary. In practice, this meant adapting to each project’s submission requirements, working with maintainers to reproduce the issue, and, where applicable, refining and retesting a proposed fix. As AI-assisted discovery increases report volume, open-source security research can scale only if research teams absorb the resulting complexity rather than pass it on to maintainers.
Scaling this work also requires more developers who understand the full security workflow. At Microsoft’s annual Hackathon, we hosted the FORGE Open Source Software (OSS) Bug Hunt Party (Project Sunshine) as a forum where developers across Microsoft could exchange security research practices and gain hands-on experience with vulnerability investigation, validation, and responsible reporting. With MDASH and supporting guidance, 50 participants produced 39 reports across six projects, including Microsoft’s open-source Hyperlight project, Linux, vLLM, Gemini CLI, and llama.cpp. Those 39 reports are included in the 155-report snapshot above. Project Sunshine has continued beyond the Hackathon as a forum for open-source security collaboration within Microsoft.
Akrites: Coordinated effort to remediate vulnerabilities
Akrites is a Linux Foundation initiative that coordinates confidential remediation and disclosure for vulnerabilities in critical open-source software. FORGE has submitted nine Linux findings with internally assessed common vulnerability scoring system (CVSS) scores above 7.0. Together with submissions from other participants, including Google, these cases helped test and refine Akrites’ early Coordinated Vulnerability Disclosure (CVD) workflow. One of those reports was the first Akrites submission to result in a patch merged into the Linux kernel. FORGE will keep contributing to those responsible disclosure efforts.
The work also showed that a systematic approach is not just a larger scan. It is a repeatable path from a finding to an upstream fix and coordinated disclosure. Each case needs reproducible evidence, a clear causal explanation, a severity assessment, and an understanding of which downstream projects may be affected. The right owners and collaborators can then be brought in at the right time and on a need-to-know basis.
What’s next for FORGE Lab?
In a matter of months, FORGE Lab has helped discover Windows vulnerabilities and assigned 140 CVEs, including 52 in September 2026’s security release. Beyond Windows, FORGE submitted 155 internally validated reports across 23 open-source projects—93 of which had documented maintainer acknowledgement or acceptance at the time of writing—and one of our Linux reports became the first Akrites submission to result in a patch merged into the Linux kernel. Our Linux kernel results also indicate that automated validation can work at practical cost, with proofs of concept averaging $3.61 in model cost and 21.5 minutes per successful case. The lesson behind those numbers: once agents can find difficult bugs, progress depends on the system around them, how it scales, where it spends reasoning, and how quickly it turns discoveries into validated fixes.
These three lessons are becoming foundational guidelines for FORGE’s next phase of research:
Moving from frontier capability to scale means measuring the full pipeline, not just the number of findings: candidate arrivals, duplicates, rejected reports, validated defects, queue age, unresolved cases, and time through each stage.
Moving from token consumption to reasoning economics means evaluating model and execution cost alongside human review time, and asking whether each additional pass removes uncertainty, improves coverage, or produces independently validated findings.
Moving from isolated discovery to continuous validation and remediation means tracking reproduction success, patch rework, regression evidence, and elapsed time from validated defect to approved fix and release.
For security leaders evaluating AI-powered vulnerability discovery, these are useful measures too: count validated fixes, not just findings, and weigh model cost alongside the human review time it takes to act on them.
The next advance won’t come from a better model alone. It will come from research systems that combine frontier capability, systems engineering, and reasoning economics, focusing machine reasoning and human attention on turning credible findings into validated fixes.
To learn more about Microsoft Security solutions, visit our website. Bookmark the Security blog to keep up with our expert coverage on security matters. Also, follow us on LinkedIn (Microsoft Security) and X (@MSFTSecurity) for the latest news and updates on cybersecurity.
On October 20, the PHP security team announced an out-of-band security release for Wednesday, October 21, 2026 at 14:00 UTC, fixing two critical vulnerabilities rated CVSS v4.0 9.2 (CVE-2026-109618 and CVE-2026-109619). Hours before the release, technical details leaked publicly. They point to the session.upload_progress feature, which has been part of PHP since 5.4.0 and is enabled by default. The community quickly converged on an interim mitigation: set session.upload_progress.enabled = Off in php.ini.
That leaves defenders with two questions: how big is the exposed surface, and where should they start? We used Internet Scanning in VirusTotal to answer both.
Note: Official details, affected versions and fixed versions are published by the PHP project with the release. The figures below describe the Internet-facing PHP footprint, not confirmed vulnerable hosts.
Most PHP servers don't say they are PHP
VirusTotal fingerprints roughly 5.1 million IP addresses running PHP (port_service_cpe:php), about 3.8 million of them with at least one port open today. Only around 1.1 million of those announce a version in an HTTP header such as X-Powered-By: PHP/8.3.35.
In other words, roughly four out of five PHP servers hide their version (expose_php = Off, stripped headers, reverse proxies). VirusTotal still identifies them as PHP through other signals: the application on top (WordPress, Laravel, Nextcloud...), PHPSESSID cookies and framework-specific headers. If you only search for a version string, you only see the fraction of the problem that volunteers it.
The version picture: the long tail of end-of-life PHP
Among the servers that do disclose their version, the split is stark:
~272K run a supported branch (8.2 to 8.5), the only branches that receive security fixes from the PHP project.
~758K run an end-of-life branch between 5.4 and 8.1. These branches have session.upload_progress enabled by default and no longer receive security fixes. PHP 7.4 alone accounts for ~187K IPs and PHP 5.4 for ~119K.
~88K run PHP 5.2 or 5.3, which predate session.upload_progress.
Being up to date doesn't buy much time either: about 85K IPs run the exact releases published on September 24 (8.3.35, 8.2.34, 8.4.26 and 8.5.11), the latest available before this fix.
What runs on top, and where
Apache (~2.9M) and nginx (~1.48M) are the web servers most often seen on PHP hosts, followed by LiteSpeed (~90K). On the application side, WordPress dominates with ~538K IPs, followed by Laravel (~141K) and Nextcloud (~107K). Webmail (Roundcube) and database admin panels (phpMyAdmin) add another ~25K high-value targets.
The geography is concentrated: the United States accounts for ~920K PHP hosts with at least one open port, and a handful of cloud and hosting providers (AWS, DigitalOcean, Alibaba, OVHcloud, Hetzner) concentrate a large share. That concentration is good news for remediation: a few providers that push a configuration change or a WAF rule can cover a lot of ground.
Going beyond the web port
PHP rarely travels alone. ~394K PHP hosts also have port 22 open (SSH by default), ~233K port 3306 (MySQL) and ~68K port 3389 (RDP). Those co-exposed services are useful for something else: identifying the exact build behind the web server.
The leaked material references LiteSpeed lsphp82 8.2.34 builds for Debian 12, Ubuntu 22.04 and Ubuntu 24.04, and notes that HTTP headers alone don't tell those builds apart. The OpenSSH package on port 22 does. With the bracket syntax, every condition is pinned to its port:
Of the ~3.5K IPs whose banners show both LiteSpeed and PHP 8.2.34, about 500 also have port 22 open. Across all PHP 8.2.34 hosts, the OpenSSH package on port 22 matches Ubuntu 24.04 on 269 IPs, Ubuntu 22.04 on 112 and Debian 12 on 65. For a defender, that is the difference between "patch everything" and "these are the machines that match the leaked target profile, patch them first". Keep in mind that port 22 reveals the host operating system: PHP may still run inside a container built on a different base image.
Adversaries run PHP too
The exposed surface also includes attacker infrastructure. Around 5.7K PHP hosts with at least one open port have five or more detections in VirusTotal, 729 of them disclosing PHP 8.x. One of them is an old acquaintance: the NOX Stealer panel (rebranded as BOMBAY) on 5.175.221[.]206:8443, which we profiled in our Internet Scanning post, runs nginx 1.24.0 with PHP/8.3.33.
What the VirusTotal corpus saw
The leak left traces across VirusTotal. The archive referenced in the write-up was first submitted at 02:29 UTC on October 21, less than 15 minutes after the first submission of the write-up URL. By the time of writing, 21 crowdsourced reports covering the vulnerabilities had been ingested as collections. Following entity:collection collection_type:report "CVE-2026-109618" is the fastest way to keep up with new reporting as it appears.
What to do now
Patch. Upgrade to the fixed release of your branch (8.2, 8.3, 8.4 or 8.5) as soon as it is available on php.net or through your distribution.
Plan the EOL migration. PHP 8.1 and older no longer receive security fixes. If you are on 5.4 to 8.1, upgrade the branch or check whether your distribution or vendor ships a backport.
Disable upload progress until you patch. Set session.upload_progress.enabled = Off in php.ini (or the pool configuration) and reload PHP-FPM, Apache or LSAPI. It only breaks upload progress bars that rely on the feature. Community analysis suggests it may not cover every vector, so treat it as a stopgap, not a fix.
Filter multipart at the edge. Where an application doesn't need file uploads, block or inspect multipart/form-data requests before they reach PHP. Cloudflare shipped emergency rules to its Managed and Free rulesets on October 21, and its CTO stated that they cover known payloads, while stressing that only updating PHP fully protects a site.
Make sure the WAF can't be bypassed. Edge rules only help if the origin is not directly reachable. Search your own ranges in VirusTotal (for example, entity:ip port_service_cpe:php asn:<your ASN>) to find origins that expose PHP directly to the Internet.
Don't rely on hiding the version.expose_php = Off hides the header, not the vulnerability.
Queries used in this post
Query
What it finds
entity:ip port_service_cpe:php
All IPs where VirusTotal fingerprinted PHP on any port
entity:ip port_service_cpe:php port_status:open
PHP hosts with at least one port currently open
entity:ip port_service_cpe:php port_banner:"PHP/"
PHP hosts that disclose their version in an HTTP header
Note: All counts in this post were taken on October 21, 2026. For large result sets VirusTotal returns estimated totals that vary between runs, so we report the median of seven runs, rounded. Port modifiers without a port in brackets match per IP, not per port: port_service_cpe:php port_status:open means PHP was fingerprinted on the IP and at least one of its ports is open.
Recently, somebody from a fairly mature security team told me something I did not want to hear: if software vendors run “Mythos-class” models on their own code and fix what they find, they must publish a CVE for every fixed vulnerability.
CVE art
My first reaction (vendor hat firmly on, since I now work at Cisco) was: huh? Why? These bugs were found by the vendor, fixed by the vendor and were never public. A vast majority (but not all!) are not exploited. CVE CNA rules make assignment a SHOULD, not a MUST, and whether a quietly shipped fix even counts as “publicly disclosed” is something considered debatable. Why would anybody want it?
My second reaction, a bit later in the conversation was: oh, that!
They have a point. Sort of. They were simply describing how their vulnerability management program works. And, I suspect, how many of yours work too. Their problem is about to become everybody’s problem; they just noticed it first.
The Problem In One Sentence
Many VM programs start with a vulnerability scan, not with a patch, a vendor release or … a news headline about a new terrible security issue.
The chain looks like this:
old sad VM
Note what is not on this list: the vendor advisory. It is not an input in their case.
Before anybody snickers or ROFLs about it: this was a sound design for about 20 years. In the 2000s and 2010s, an issue that mattered usually got a CVE (yes, before the “vuln-purists” tear me to shreds, there were some exceptions to this even back then!). And a CVE got a check from your vulnerability scanner vendor, usually within days (in my Gartner days, we called them “Q/R/T” for the reasons you can easily guess…). Auditors want evidence, ticketing systems need an ID, and SLAs need an event that starts the clock. A “scan-first” program is what you get when you optimize for all of that at scale. It is a property of the pipeline, not a failure of the people running it.
So a software or an OS vendor can shout “URGENT, upgrade now!” all it wants. If the fix has no CVE, the scanner (usually) has no finding, there is no ticket, no SLA clock, no change request, and no patch (at the companies that follow that model).
Here are the two paths side by side:
Paths table
Why This Matters Now: Hello, Vulnerability Apocalypse
I hate the “post-Mythos” label as much as the next person, but these numbers are not marketing. (BTW, every time you say “post-Mythos” for marketing purposes, Claude kills a kitten.)
In Patch Sound Barrier Part 2 I defined the “vulnerability apocalypse” as four things arriving together: massive vulnerability volume, fast exploit development, exploitation at scale and resulting incident damage. Factor #1 is no longer theoretical: high and critical CVEs from notable vendors ran at roughly 3.5x the prior monthly record in June 2026, and at about 5x in July.
Now the twist: those charts only count the fixes that got a CVE. The pile of internally found, internally fixed, never-CVE’d bugs is not on any chart. For scale: Anthropic said in May that Mythos Preview had been used to find more than 10,000 high- or critical-severity bugs, not all of them publicly reported.
That is the part of the iceberg your scanner cannot see (usually). So a big chunk of the AI era’s fixes may be exactly the ones that scan-first programs miss! Your patch SLA dashboard stays green while your actual exposure grows. Green-but-wrong is worse than red.
BTW, “internally found” does not mean “nobody else knows.” Attackers have access to capable models too, AI makes patch diffing cheap, and some vendor advisories now list “internally discovered” bug classes that also contain actively exploited bugs. Found internally means “we found it too,” not “we found it first and only.” Yes, I know, Captain Obvious strikes again, but a scan-first program behaves as if this were not obvious at all.
Timing makes it worse. Here is one real example (via X post): CVE-2026–72529, a remote, unauthenticated script execution bug in TrueConf Server. The issue was found in June, the patch was also released in June, exploitation was spotted in July, and the CVE was assigned in August, by Kaspersky as a third-party CNA, not by the vendor. For a scan-first program, that bug did not exist for about two months, including the month it was being exploited. Note that even the “exploited bugs get a CVE” metric ran a month behind the exploitation here — away too slow. (Yes, it is a niche product. Niche is exactly where scanner coverage is thinnest.)
Who Taught Us to Think This Way?
Naturally, I also asked on X, and I got my share of thoughtful responses like “ask if adversaries will delay exploitation until a CVE and severity score exist”, “FYI, vulnerabilities without CVEs, or with low scores, regularly cause damage” and a reminder that “a CVE reflects severity after discovery, not exploit probability.” All true, all ignored by scan-first vulnerability management programs…
The best answer IMHO was this point: somewhere along the way, “a lookup key [CVE] became a proxy for risk.” Indeed, how did that happen?
“Scan-first” did not appear out of nowhere. Scanner vendors taught the market to think this way, and the market went along happily.
Some of the blame here is well deserved:
Coverage was sold in CVEs. For years, the headline number in every bake-off was how many CVEs a product detects and how fast a new check ships. Many customers learned that the CVE list is the threat model.
The CVE became the unit of work. Dashboards, risk scores, SLA reports and ticketing integrations were all built around CVE IDs. Anything without one is a second-class citizen in the product, and therefore in the program.
“Clean scan” became audit evidence. Compliance scanning made “the scan report is clean” the proof that auditors still ask for. In PCI DSS ASV scanning, pass or fail is largely decided by the CVSS scores of the findings. (Yes, I co-wrote a book on PCI, so I am not innocent here either.)
Non-CVE coverage exists, but nobody marketed and sold it. Many scanners do have checks keyed to vendor bulletins, and most flag outdated or unsupported versions. In practice, those often land as low-priority findings that no SLA tracks. They were never the thing on the slide…
And before you say “just use KEV and EPSS”: both are keyed on … CVE IDs. KEV only lists vulnerabilities that have an assigned CVE, and EPSS only scores CVEs. “Risk-based” Vulnerability Management built on CVE-keyed inputs inherits the exact same blind spot. Not very risk-aware, that is.
To be fair, all of this was once rational. A CVE is a clean, shared, countable unit, and you can build a product (and a business) on countable units. This worked kinda OK in 2015, worked poorly in 2021, and really, really does not work in 2026.
So a market that was essentially taught “if it’s not in the scanner, it didn’t happen” now needs to learn something new, and the people who taught the first lesson are best placed to teach the next one.
The Three Obvious Fixes Are Suboptimal
CVEs are not only a scanner input; they are also a public accountability ledger. This industry has a long and not very proud history of silent patching, and “trust us, we fixed it, this matters to you” has earned all the skepticism it gets.
At the same time, the vendor-side point also stands. Defenders at software companies will use those models to fix their code, and their code is getting better and more secure. Flooding the market with huge piles of CVEs will not help anybody. Both things are true at once, and that is what makes this problem interesting.
So, the quick fixes, each with a catch:
Option 1: A CVE for every internally found bug. At AI scale, this floods scanner queues with hundreds of findings that a single upgrade closes. We have actually run this experiment: after the Linux kernel became a CNA in 2024, it started assigning CVEs for thousands of backported fixes, and people have complained about the noise ever since. Even Epoch had to footnote it as noise in their CVE charts.
Option 2: Bundled CVEs. Cisco now ships scheduled security releases with CVEs bundled by weakness type (CWE), and still assigns an individual CVE when a bug is exploited or needs a compensating control. It is a pragmatic middle path. If a bundle is scored by its worst member, it also pushes you toward handling exceptions per release rather than per CVE, which, as you will see below, is exactly where I think you should end up anyway…
Option 3: Read vendor advisories manually. Ah, the good old days! Mapping advisories from hundreds of vendors onto thousands of assets by hand does not scale, and frankly never did.
Note that Option 3 is wrong about the how, not the what. The advisory does need to reach your program. A human with a browser and 200 vendor websites just cannot be the delivery mechanism.
So What Would Actually Work? Make the Advisory an Input
In my strictly private opinion, the vendor advisory must become a first-class input to vulnerability management, next to the scan, not behind it. Not “instead of the scan,” and not “if the scanner vendor gets around to it.”
The chain should look like this:
new cooler VM
Obviously, better programs do this today, so for a decent percentage of this blog’s readers this should really not be news. This blog is not for you.
Getting there needs three parties to move, not one (plus your auditor):
Vendors: publish machine-readable advisories (CSAF much?) with fixed versions, urgency and exploitation status. And keep the accountability ledger honest: assign an individual CVE the moment a bug is exploited or needs a compensating control. (Yes, this is close to what my employer committed to in June. This is the easy part; the next bullets are the hard ones.)
Scanner vendors: you taught the market that the scanner is the source of truth, so you get the first job. Ingest those feeds and create findings under your own IDs, no CVE required, at real severity rather than as an informational footnote. You already flag “outdated version”; this is the same idea, driven by vendor data. (Yes, the risk is that coverage follows market share. Niche OT vendors, I am looking at you.)
VM programs: add a currency metric next to CVE closure, e.g., percent of assets within N releases of the vendor’s latest security release. In other words, patch the release, not just the CVE. If your remediation speed is capped by the patch sound barrier, spend that limited throughput on upgrades, not on ticket accounting.
Your auditor: if audit accepts only CVE closure as evidence, nothing above will change. Bring them in early and show them the currency metric before it shows up in an audit finding.
What To Do This Week
Run the 30-minute self-test:
Pick your top vendor by asset count (or by internet exposure).
Pull their last three security releases and count the security fixes vs. the CVEs. (If the release notes just say “multiple security fixes” with no count, congrats, that is a finding too.)
Check what your scanner flagged for those releases.
The difference between what the vendor fixed and what your scanner flagged is your blind spot, in numbers.
Ask your scanner vendor:
What do you do with a vendor advisory that has no CVE?
Do you ingest CSAF advisories, and from which vendors?
What is your median lag from a vendor advisory to a detection?
Can you show me every asset more than N releases behind the vendor’s latest security release, and at what severity?
Change your program:
For edge and crown-jewel asset classes, start the SLA clock at the vendor security release, not at the scanner finding.
Grant exceptions per release, not per CVE.
Report a currency metric next to CVE closure, e.g., “percent of internet-facing assets on the vendor’s latest security release within 30 days.”
Put it in contracts: vendors provide machine-readable advisories with fixed versions and exploitation status, and scanner vendors cover non-CVE vendor fixes at real severity.
So?
With my vendor hat on, I still don’t think every internally found bug needs its own CVE. With my VM hat on, it should not matter: your program should not need one to act. Patch the release, not just the CVE. If the gap is zero, congrats, and please tell me how you did it. If it is not, you have found your blind spot… have fun!

 Login