- AI, supply-chain exposure, quantum computing and geopolitical conflict are testing security programs. Preparing for disruption must become part of day-to-day operations.
Cyber Asset Attack Surface Management (CAASM) solved a significant problem. Security teams can now say with confidence what they own. But, two things separate a CAASM tool that stops there from one that actually moves the needle on risk. The first is what the inventory itself carries. The second is what it connects to. 1. An inventory needs to do more than list what exists A list of assets is just the beginning. The tools worth building on now attach criticality and connection data to every asset from day one, so a security team isn’t just looking at a spreadsheet […]
Check Point uncovers thousands of fake support accounts, with hundreds more appearing every day A delayed flight. Missing luggage. A refund that never arrived. For frustrated customers, social media has become a direct route to customer support. They tag the company, explain the problem, and wait for a response. However, threat actors are watching those same conversations. A Check Point Exposure Management investigation uncovered a coordinated social engineering campaign in which scammers monitor public complaints, impersonate customer support accounts, and approach customers seeking help. Researchers engaged directly with the scammers and followed the attack from the first social media interaction […]
We analyzed ongoing conversations with prospective customers to find out what buyers ask most. Below are those questions, covering how Check Point Exposure Management helps teams validate risk, cut noise, coordinate remediation, and report progress. Part 1 covered how security leaders think about asset discovery, cloud visibility, threat intelligence, credential exposure, and integrations. Once teams know what’s exposed, the conversation shifts to prioritization and response. 1. How do you prioritize which exposures matter? Security teams often manage thousands of vulnerabilities across applications, endpoints, cloud resources, and internet facing infrastructure. A severity score alone does not provide enough context to determine […]
Security teams are starting to actively use AI for security work, including vulnerability triage, penetration testing, threat modeling, incident response, and code review. The promise is speed, but a security tool that moves fast and raises too many false alarms doesn’t save time. Engineers spend time on false alarms, on-call is noisier, and teams distrust findings that matter.
Today, we’re releasing Deception Benchmark, the first benchmark designed to measure that trust problem directly. It tests whether a model can distinguish real vulnerabilities from code that looks risky but is actually safe. The benchmark includes 14,822 samples across 16 languages and more than 70 Common Weakness Enumeration (CWE) categories. We evaluated 12 models from five providers and are releasing the dataset and whitepaper to the community. Existing benchmarks measure whether AI can find or exploit vulnerabilities. This is the first to measure whether it can tell real vulnerabilities from false alarms. Under standard prompting, precision at distinguishing real vulnerabilities from false alarms landed in the mid 50s; as likely to be inaccurate as accurate.
In offensive tasks, there’s often a clear result: the exploit works or it doesn’t. Defensive reviews are harder to verify than offensive tasks; a model might recognize a suspicious pattern even when a mitigation makes the issue non-exploitable. In practice, useful systems need to reason about the code, the mitigation, and sometimes the surrounding environment.
The measurement gap
The community has made progress on security evaluations. CyberGym tests agents on more than 1,500 realistic tasks. Meta’s CyberSecEval and CyberSecEval 2 measure exploit generation. CYBENCH evaluates capture the flag (CTF) challenges. SEC-Bench and VulnBench push toward authentic security workflows.
Recent work reinforces both the progress and the gap. ExploitGym measures whether AI can escalate from a crash to a working exploit. Microsoft’s Project Perception deploys multi-agent red/blue/green teams for continuous defense. OpenAI’s GPT-Red shows that self-play red-teaming finds novel attacks that frontier models can’t defend against. Since then, OpenAI disclosed that its GPT-6 Astra model crossed the Critical cybersecurity capability threshold, and both OpenAI and Anthropic reported incidents where models gained unauthorized access to production systems during evaluations. The offensive side is moving fast. But none of this work measures the defensive precision question: when an AI system flags code as vulnerable, how often is it right?
Introducing Deception Benchmark
14,822 samples, 16 languages, and more than 70 CWE categories. We call it Deception Benchmark because the safe samples are designed to deceive models. It has real vulnerability patterns, real frameworks, real idioms, with mitigations that quietly close the exploit path. The goal is to classify code as vulnerable or safe, with no hints.
Consider a Flask endpoint that accepts user input and queries a database. A model will pattern-match to SQL injection, but the query uses parameterized statements, so the exploit path is closed. A single-turn classifier flags the pattern and moves on, never checking whether the exploit can actually work. Production tools rely on multi-step loops and agentic workflows to compensate, but that scaffolding masks whether the model itself understands the code. This benchmark strips the scaffolding away and asks the model to make the call in a single pass, so what it measures is understanding, not how many tries a harness takes to get there.
We built every sample through an adversarial loop: generate, test against frontier models, harden, repeat. If a model gets it right easily, the sample doesn’t survive. The result is a benchmark calibrated to the frontier, not below it. Building it this way is expensive. Generation and hardening of the samples consumed tens of billions of tokens. We’re releasing the result so the community doesn’t have to repeat that cost.
This benchmark generates two challenge types. Code-level challenges (6,988 samples) present vulnerable and safe variants that differ by a subtle fix. Both look suspicious, only one is exploitable. Environment-gated challenges (2,707 samples) go further: same code, different deployment context. A Kubernetes Network Policy blocks the server-side request forgery (SSRF) path. An identity and access management boundary prevents privilege escalation. The pattern is visible in the source. The infrastructure makes it unexploitable. The model has to figure out which scenario applies.
All samples were purpose-built for this benchmark, grounded in real-world patterns, real frameworks, real CWEs, and real infrastructure; without IP concerns or training data contamination.
Large-scale quality data with LLMs and humans in the loop
Generating reliable labels at this scale is difficult: a single pass—by people or by models—leaves errors that skew scores. So we treat labeling as a convergent audit loop rather than a one-time step. Every label is re-examined by multiple independent reviewers, blind to one another and to the original reasoning that produced the label. Disagreements escalate to direct adjudication, where the original reasoning is evaluated against the challenge. Unresolved cases go to human review. We repeat the loop until the scored set converges below a dispute threshold: under 3 percent of samples still contested by independent review, with a target of under 1 percent surviving human adjudication. One choice makes this defensible: we never relabel a disputed sample. When reviewers disagree, the sample moves to the unscored pool instead of being given a corrected label, so a bad challenge can remove a sample but can never introduce a wrong label into the scored set.
A human review of 100 randomly drawn scored samples found no label errors. We describe the full process in the whitepaper.
The results
The benchmark is roughly balanced: half vulnerable, half safe, so a random classifier scores 50 percent. We report two error rates separately, because they fail in opposite directions. The false positive rate (FPR) is how often the model flags safe code as vulnerable. These are the false alarms that waste an engineer’s time. The false negative rate (FNR) is how often it misses a real vulnerability and calls it safe. Accuracy alone hides this: a model that labels everything vulnerable catches every bug (0 percent FNR) but flags all safe code (100 percent FPR) and still scores about 50 percent. We consider FPR below 10 percent and FNR below 10 percent the minimum bar for production use.
Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar.
Model
Prompt
Accuracy
FPR
FNR
GPT-5.6 Sol
Direct
54.9%
92.5%
0.9%
GPT-5.6 Sol
PoE
58.9%
58.6%
23.1%
GPT-5.5
Direct
56.9%
87.8%
1.3%
GPT-5.5
PoE
62.9%
63.6%
12.4%
GPT-5.4
Direct
60.2%
81.0%
1.5%
GPT-5.4
PoE
77.7%
10.1%
33.6%
Llama 3.3 70B
Direct
58.8%
84.2%
1.1%
Llama 3.3 70B
PoE
72.2%
10.2%
44.2%
Claude Haiku 4.5
Direct
55.6%
92.1%
0.0%
Claude Haiku 4.5
PoE
75.6%
22.4%
26.3%
Claude Opus 4.6
Direct
55.9%
91.3%
0.1%
Claude Opus 4.6
PoE
75.8%
42.7%
7.0%
Claude Opus 4.7
Direct
58.3%
85.5%
0.9%
Claude Opus 4.7
PoE
75.9%
32.0%
16.8%
Claude Opus 4.8
Direct
53.8%
95.7%
0.2%
Claude Opus 4.8
PoE
75.8%
32.5%
16.4%
Claude Opus 5
Direct
77.3%
41.5%
5.2%
Claude Opus 5
PoE
79.3%
24.9%
16.8%
Claude Sonnet 5
Direct
62.9%
74.7%
2.2%
Claude Sonnet 5
PoE
74.7%
31.8%
19.2%
Amazon Nova 2 Lite
Direct
56.3%
89.2%
1.2%
Amazon Nova 2 Lite
PoE
70.1%
45.2%
15.5%
Mistral Large
Direct
52.2%
99.0%
0.0%
Mistral Large
PoE
65.5%
49.3%
20.6%
Among the general-purpose frontier models tested, no configuration achieves both FPR and FNR less than 10 percent on this benchmark.
Every model has the same failure mode. With direct prompting, they catch up to 95 percent of real vulnerabilities but also flag 41–99 percent of safe code. Precision runs from 52 percent to 71 percent, clustered in the mid-50s; effectively as likely to be inaccurate as accurate. The models see a vulnerability pattern and stop reasoning. Proof-of-exploit prompting cuts false positives by 17–74 points but misses 7–44 percent of real vulnerabilities. The environment-gated challenges are worse: models flag the code and ignore the Kubernetes Network Policy next to it. No tested configuration keeps both false positives and false negatives below 10 percent.
These results reflect general-purpose models in single-turn prompting. Purpose-built systems with multi-step validation and tool use are a different operating point that we didn’t measure, and if a harness can close the gap between pattern recognition and genuine understanding, this benchmark is the place to demonstrate it. Two cautions before assuming it already does. Agentic verification is proven mostly on offensive tasks, where success can be confirmed: the exploit fires or it doesn’t. Judging that code is safe has no such oracle. Extra iterations re-sample the same judgment rather than confirm a negative, and a harness still inherits the base model’s understanding. If the model can’t separate an effective mitigation from an ineffective one in a single pass, more passes won’t add the missing knowledge. That’s what this benchmark measures: the model’s intrinsic ability to understand code, tested at the single-turn baseline where no scaffolding can mask the gap.
For security teams evaluating AI tools today: ask your vendors how their system performs on tasks like this, not just whether it finds vulnerabilities, but how often it’s wrong. Pair any AI-assisted review with human verification on high-risk code paths, and use Deception Benchmark to hold your tools accountable.
Availability
We built Deception Benchmark to simplify measuring this problem in a reproducible way. The public release includes the samples and evaluation workflow. We don’t release the labels, so submissions can be scored consistently over time without turning the benchmark into a memorization exercise.
Of the 14,822 samples, 9,695 are scored; the remaining 5,127 are held out and unscored, mixed in with the rest of the benchmark. The goal is straightforward: make it more difficult to optimize the benchmark compared to improving the underlying system. We describe that design in more detail in the whitepaper.
Deception Benchmark is available on GitHub, along with the whitepaper and submission instructions for verified scoring. If you’re building security tooling, you can download the dataset, run your system against the benchmark, and submit predictions for scored evaluation.
If you have feedback about this post, submit comments in the Comments section below.
Cybercrime at Machine Speed: Key Takeaways from Flashpoint’s 2026 Midyear Threat Intelligence Briefing
Threat actors are no longer just using automation to execute tasks, they are leveraging prepackaged, safeguard-free AI, weaponizing stolen session data, and directly targeting defenders’ security stacks.
The threat landscape has developed at a striking pace with Flashpoint tracking over 22 million illicit AI discussions, 7.4 million compromised hosts yielding 1.7 billion stolen credentials, and over 21,600 disclosed vulnerabilities in just six months. Beyond these staggering numbers, the on-demand session detailed something even more alarming: a fundamental shift in adversary operational tradecraft.
Here are the five critical shifts every cyber threat intelligence (CTI), Vulnerability Management, and SOC team needs to know.
The Death of Signal: Threat Actors are Shifting to “Private AI”
The public discussion surrounding criminal artificial intelligence (AI) has reached a critical inflection point. Early in the AI boom, Flashpoint observed threat actors collaboratively experiment across underground forums, jailbreaking commercial frontier models or advertising surface-level tools like WormGPT and DarkGPT.
Today, adversaries are shifting from public forums to running fine-tuned, open-source models locally on private servers, which greatly hampers traditional signature-based detection. Flashpoint analysts are now seeing attackers generate unique, highly tailored malware variants, flawless phishing lures, and custom exploit scripts at extremely low costs—completely offline and shielded from public monitoring.
“A few months ago, a lot of this was collaborative… public outsourcing. Now what we’re seeing is scarier: pre-packaged cybercrime models run locally on private infrastructure. Malicious code, exploit scripts, and targeted phishing are all being generated inside closed environments.”
Ian Gray, VP of Intelligence, Flashpoint
Weaponizing the Defender’s Own Tooling
Another eye-opening tactical insight shared during the session was how threat actors are repurposing defender infrastructure for automated initial access and extortion. In the webinar, we pointed to recent campaigns where adversaries specifically targeted misconfigurations and zero-day vulnerabilities inside open-source vulnerability scanners, secrets-detection tools, Kubernetes clusters, and Infrastructure-as-Code(IaC) environments.
What this means for defenders is that the attack surface is no longer bounded by traditional enterprise network boundaries: it extends directly into CI/CD pipelines, security orchestration tooling, and third-party SaaS integrations. Security teams are finding themselves in a race against attackers who use automated scanning scripts to weaponize vulnerabilities in the security tools themselves.
The Global Infostealer Threat and Identity-First Attacks
Flashpoint tracked 7.4 million hosts compromised by infostealers in H1 2026—a 27% increase period-over-period—harvesting 1.7 billion credentials and identity information.
While the top infostealer strains remain familiar, law enforcement operations have created vacuums that competitors rapidly fill.
Threat actors are leveraging drive-by downloads, watering holes, and pirated software packages to plant stealers. Once a machine is compromised, the logs capture corporate SSO credentials, active browser cookies, VPN keys, and SaaS session tokens. This enables adversaries to simply log in without having to leverage complex technical exploits.
The Structural Failure of CVE/NVD and the Importance of KEV
The Common Vulnerabilities and Exposures (CVE) and National Vulnerability Database (NVD) have failed to keep pace with the velocity of AI-assisted vulnerability discovery. As such, vulnerability management teams are facing significant operational delays.
Metric
Flashpoint GTIR Midyear H1 2026 Data
Operational Impact
Total Disclosures
21,667
Remediation volume exceeds defender bandwidth.
Exploit Availability
19% (4,015 CVEs)
Functional code is ready before patches are deployed.
Public Catalog Lag
Growing Backlog (NVD/KEV)
Delay in official scoring leaves teams blind to active risk.
Therefore, waiting for NVD enrichment before prioritizing a patch is a dangerous strategy. To compensate, security teams require Vulnerability Intelligence (VI) that provides primary-source confirmation of weaponization, exploit availability, and actionable mitigation guidance long before public databases update.
Ransomware Evolution: From Encryption to Cloud Extortion
Ransomware-as-a-Service (RaaS) activity surged by 45% period-over-period, reaching 6,256 verified victim postings on data leak sites. However, total on-chain payout revenue dropped by 8% to $820 million, with victim pay-rates hitting a record low of 28%.
Faced with declining payouts and resilient enterprise backups, extortion syndicates are adapting. Rather than relying exclusively on technical file-encrypting malware, groups are executing pure data extortion campaigns—frequently targeting cloud platforms or extracting data through third-party vendor access.
Protect Your Organization Using Flashpoint
Defending against machine-speed attacks requires moving beyond reactive, post-incident telemetry. Flashpoint arms security, CTI, and vulnerability management teams with the primary-source intelligence required to preempt adversary operations:
Unrivaled Deep & Dark Web Visibility: Flashpoint’s Primary Source Collection actively monitors closed criminal communities, illicit Telegram channels, and private forums, giving you early warning when threat actors build custom AI toolkits or trade credentials targeting your organization.
Comprehensive Vulnerability Intelligence (VI): Flashpoint tracks zero-days and vulnerability disclosures independently, delivering immediate exploit availability data and threat-informed prioritization so you patch what actually matters.
Continuous Compromised Credential Monitoring: Instantly surface exposed enterprise credentials, active session tokens, and stealer logs tied to your domain or third-party supply chain before they lead to an account takeover (ATO).
In the first half of 2026, the global threat landscape reached a clear operational inflection point: threat operations have fundamentally transitioned from human-led campaigns to machine-speed, AI-driven exploitation. As threat actors gain commoditized access to open-source AI technologies and actively deploy automated, safeguard-free tooling locally on private infrastructure, organizations face an accelerating hybrid risk environment.
Flashpoint’s Global Threat Intelligence Report: 2026 Midyear Edition
The Flashpoint Global Threat Intelligence Report: 2026 Midyear Edition anchors security leaders—from threat intelligence, vulnerability management, to executive leadership—in the data required to navigate this evolving threat landscape. Covering the period from January 1 to June 30, 2026, the report delivers timely insights backed by Flashpoint’s proprietary primary-source collection from over 3.9 petabytes of continuously monitored illicit sources.
Our midyear findings reveal several key metrics that highlight the speed and scale of the H1 2026 threat landscape:
22M+ threat actor posts discussed, shared, or advertised artificial intelligence toolkits for criminal deployment.
1.7B credentials and identity data points extracted across more than 7.4M unique compromised hosts globally.
Nearly one-in-five (19%) of all vulnerability disclosures dropped with ready-made, functional exploit code.
45% period-over-period surge in Ransomware-as-a-Service (RaaS), with total victim volume reaching 6,256 even as victim payout rates dropped to a historic low of 28%.
A Clear Understanding of the Convergence Between AI and Cyber Threats From generating flawless phishing campaigns to automating vulnerability scanning and code obfuscation, discover how adversaries are optimizing for speed and cost-efficiency — utilizing AI as a force multiplier in their various illicit campaigns.
A Comprehensive Top-Down View of the Evolving Threat Landscape Gain full visibility of the threat landscape with Flashpoint’s primary-source collections and real-time threat intelligence.
Strategies for Proactive Defense and Risk Mitigation Move your organization beyond reactive incident response by leveraging Flashpoint’s comprehensive threat intelligence. Gain the foresight needed to strengthen defenses and optimize your security posture.
“AI is compressing the time between opportunity and exploitation. Capabilities that once took significant expertise, coordination, and time to develop are becoming faster to build, easier to scale, and harder to detect. Security teams are facing an adversary ecosystem that can use AI to iterate at unprecedented speed — the only way to keep pace is with primary-source intelligence that surfaces adversary behavior before attacks unfold.”
Josh Lefkowitz, Flashpoint Co-Founder & CEO
The Four Driving Themes Shaping the 2026 Threat Landscape
Artificial Intelligence (AI) Threats
During the first half of 2026, Flashpoint captured over 22M illicit posts discussing or advertising AI for criminal-related activities. By stripping ethical safeguards, custom malicious LLMs allow unsophisticated threat actors to automate complex phases of the attack lifecycle, including target profiling, malware evasion script creation, and zero-day exploit generation.
Information-Stealing Malware Threats
Infostealer malware harvested 1.7 billion credentials across 7.4 million compromised systems in H1 2026 alone, turning digital identity into the main entry point for enterprise intrusions.
Vulnerability Intelligence and Patching Management
19% (4,015) of all H1 2026 vulnerability disclosures arrived with ready-made exploit code. Adversaries deploy automated replication scripts almost immediately upon disclosure, eliminating manual remediation windows.
Ransomware Operations, Multi-Extortion Cartels, and Financial Risk
Despite a 45% surge in victim volume (6,256 overall), total on-chain revenue fell by 8% to $820M. Improved enterprise backups and incident response have driven payout rates down to 28%, prompting syndicates to demand larger sums from paying victims.
Proactive Security in 2026 and Beyond
The data shows that traditional enterprise security organizations are struggling to keep pace with modern threat cycles that are accelerated by illicit uses of AI. This continued convergence of AI engines and initial access vectors have further compressed attack timelines, making it nearly impossible for security teams to defend against them—especially if they are limited by traditional approaches to threat intelligence.
Equipping your team with primary-source threat intelligence is critical for protecting critical assets in 2026. Download the Flashpoint Global Threat Intelligence Report: 2026 Midyear Edition to gain the visibility and strategic clarity required to defend your organization.
Security teams don’t lose ground because they lack tools. They lose ground because they can’t see everything an attacker can.
This is the challenge we addressed in our latest Demo Day webinar introducing Flashpoint External Attack Surface Management (EASM), a new module inside our Ignite platform that gives security teams a continuous, attacker’s-eye view of their external attack surface, mapped directly to our proprietary vulnerability intelligence.
The Problem: Too Much Noise, Not Enough Context
Most security teams are dealing with three compounding problems:
Disconnected Data: Vulnerability data lives isolated from actual infrastructure. Knowing a CVE exists doesn’t tell you whether it affects your active environment.
Alert Fatigue: CVSS-only prioritization treats every “critical” score as an emergency, even when an asset isn’t internet-facing or exploitable.
Accelerated Threat Cycles: AI is speeding up how quickly threat actors discover and exploit vulnerabilities, making manual tracking impossible.
Layer on top of that the reality that most teams still track their perimeter with spreadsheets or a static CMDB, and you get a widening gap between what security teams think they own and what is actually exposed. This gap has a name: shadow IT.
Shadow IT Is a Growing Blind Spot
Shadow IT covers the domains, subdomains, and cloud instances that get spun up to get work done, without IT’s knowledge or approval. It’s not a fringe issue. According to Gartner, by next year, 75% of employees will be acquiring, modifying, or creating technology outside their IT department’s visibility, up from 41% just a few years ago.
These unmanaged assets sit outside inventory and outside the reach of any scanner that only looks at what’s already known. That makes them exactly the kind of infrastructure an attacker finds first, and exactly the blind spot Flashpoint EASM is built to close.
What is Flashpoint EASM?
Flashpoint EASM gives security teams a continuous, attacker’s-eye view of their external attack surface and maps that view directly to Flashpoint’s vulnerability intelligence. Instead of your team asking “are we affected by this?”, every time a new vulnerability is disclosed, EASM answers that question continuously, often before the answer is obvious anywhere else.
Flashpoint EASM is built on three capabilities that work together:
Continuous Asset Discovery
Flashpoint EASM continuously discovers and monitors internet-facing assets: domains, subdomains, and IPs. New discoveries flow into a dedicated triage inbox, so security teams can quickly accept and focus on what’s actually relevant instead of drowning in noise.
Vulnerability Mapping
Every discovered exposure is mapped to Flashpoint’s proprietary vulnerability intelligence, including our pre-NVD findings, KEV (Known Exploited Vulnerabilities) status, ransomware likelihood, and exploit maturity. This provides organizations with immediate context into the vulnerabilities that pose the most risk.
Customizable Alerting
Using EASM, security teams get alerted to the exact moment a new asset or vulnerability is detected. This alert is fully customizable by severity and is available inside one unified workflow via Flashpoint Ignite.
Discover, map, and alert. This loop gives organizations an intelligence-led view of their perimeter, so they can proactively outpace threat actors instead of being forced to react.
How Flashpoint EASM Works
In our live demo, Flashpoint walked through the EASM workflow, which can be found under “Assets and Identifiers” in the Ignite Platform.
Here’s how it works:
Step 1: Submit Seed Keywords
Onboarding starts with keywords, meaning domain and IP address assets your organization actually owns. Any already set up asset is automatically surfaced in Flashpoint Ignite—such as through our compromised credential monitoring—ensuring no duplicated setup work.
Step 2: Triage Discovered Assets
Once keywords are approved, EASM iterates on them to surface additional related infrastructure, domains and IPs alike, along with a discovery graph showing exactly how each asset was found. That traceability makes it easy to judge relevance at a glance.
Every discovered asset lands in one of three statuses:
Owned: Assets in your tech stack. EASM continues discovering related infrastructure from these and links vulnerabilities to them.
External: Assets relevant to you, but where you don’t need further discovery, just vulnerability linkage.
Discarded: Assets you don’t need, removed from the triage feed entirely.
Step 3: Review the Vulnerable Assets Overview
In the main dashboard, the Vulnerable Assets page, security professionals can view total asset count, number of exposures, unique vulnerabilities affecting them, and total potentially vulnerable assets—in addition to criticality breakdowns for both domains and IPs.
From there, security teams can drill into:
Unique vulnerabilities, filterable by CVE or severity
Domains with vulnerabilities, showing exposure counts by severity and the last exposure date
Individual asset detail pages, showing products, versions, vendors, and ports, with vulnerabilities linked directly to the specific product version affected
Diving deeper into a surfaced vulnerability provides technical descriptions, solution information, and other affected products. Additionally, Flashpoint’s vulnerability database includes over 105,000 pre-NVD vulnerabilities, giving vulnerability management teams actionable indicators well before they show up in public sources.
Step 4: Set Up Alerting
Flashpoint EASM gives teams full control over signal versus noise. Whether that means getting notified the moment a critical vulnerability is disclosed, or reviewing a daily summary of your own schedule, EASM offers two alert types:
Asset discovery alerts, either per-asset or as a daily rollup
Vulnerability alerts, filterable by criticality (critical, high, medium, low), with the option for in-app only or in-app plus email, and available as a daily rollup
Why Flashpoint EASM Matters
Flashpoint EASM isn’t just another scanning tool. The intelligence underneath it is the differentiator: discovery tells you what’s out there, Flashpoint provides the much-needed context to tell you what’s dangerous right now.
The intelligence includes coverage that can’t readily be found elsewhere: Flashpoint’s independently researched data includes pre-NVD findings, improved KEV coverage, ransomware risk scoring, and exploit maturity.
It closes a blind spot teams have quietly lived with: EASM closes shadow IT gaps and surfaces assets sitting outside inventory entirely.
Flashpoint External Attack Surface Management gives security teams a continuous, intelligence-led view of everything a threat actor sees, so organizations can find and fix exposures before they’re exploited. To see it in action in a personalized walkthrough of your own environment, reach out to schedule a demo.
EASM Frequently Asked Questions (FAQs): What Security Teams Want to Know
What makes Flashpoint EASM different from other EASM solutions?
Most EASM tools stop at raw discovery, telling you an asset exists without telling you whether it matters. Flashpoint EASM pairs continuous asset discovery with a triage inbox to cut noise, then maps every asset directly to Flashpoint’s proprietary vulnerability intelligence, all natively inside Ignite alongside CTI and Vulnerability Intelligence. That combination means prioritization is based on real attacker activity, not just an asset inventory, giving remediation teams the exact context they need to proactively address risk.
What makes Flashpoint’s vulnerability intelligence unique?
Flashpoint’s database covers 400,000+ vulnerabilities, including 105,000+ not found in NVD or CVE, often surfaced up to two weeks earlier than public sources. Every entry is enriched with threat-informed context like EPSS scores, ransomware likelihood, exploit maturity, and MITRE ATT&CK mapping, then reviewed by human analysts, not just automated feeds. The result is prioritization based on real-world exploitation risk rather than CVSS alone.
Can existing monitored assets be imported into Flashpoint EASM? Yes. EASM integrates closely with Flashpoint’s existing assets module, so assets already set up (for example, for compromised credential monitoring) surface automatically during onboarding.
Is there a limit on discovered assets, beyond the 30-keyword cap? No. The 30-keyword limit only applies to initial seed keywords, to keep that starting set relevant. Once assets are marked owned or external, there’s no cap on ongoing discovery.
How does continuous polling compare to traditional scanning? Traditional scanners give you a point-in-time snapshot. EASM continuously discovers assets and vulnerabilities, giving you a moving view of your exposure, essentially the same view an attacker would have in real time.
Does EASM identify compound risk, where multiple weaknesses increase exploitability together? The Vulnerable Assets view surfaces how many vulnerabilities are tied to a given asset, so teams can quickly spot assets carrying disproportionate risk and prioritize accordingly.
Does EASM overlap with SBOM alerting? Not exactly. SBOM alerting monitors vulnerabilities in assets you already know about. EASM is focused on discovering the assets you don’t know about yet. Most mature security programs benefit from running both in tandem.
Ransomware kept its grip on organizations through the second quarter of 2026, and the headline number barely moved. What changed underneath that number is more interesting: new research gave us a rare look inside a top tier operation as it was being built, and it revealed just how little it now takes for a small and skilled group to reach the top of the field. Here’s what the quarter actually showed, and what it means for how you defend against it. Key takeaways Data leak sites recorded 2,139 ransomware victims in Q2 2026, essentially flat versus Q1 and up 33% […]
Security leaders evaluating Check Point Exposure Management tend to ask the same questions: how the solution discovers assets, what intelligence it provides, and how well it fits their existing tools and workflows. Below, we answer the questions that come up most often in product evaluations, offering a practical look at how organizations discover, understand, and reduce cyber risk. 1. How does the platform discover my assets? Every exposure management program starts with knowing what you own. Security teams cannot assess, prioritize, or remediate exposures tied to systems they do not know exist. Check Point Exposure Management begins by continuously discovering […]
AI coding agents are part of the developer toolchain. Tools like Kiro and Claude Code generate features, tests, and code refactors from natural-language prompts. A single agent can open dozens of pull requests (PRs) across your repositories in an afternoon. That productivity comes with a trade-off: agents optimize for task completion at machine speed with no understanding of your organization’s risk.
Through protocols like the Model Context Protocol (MCP), agents also reach beyond the integrated development environment (IDE) to call APIs, query databases, and modify infrastructure and even entire environments, expanding the scope of resources your application security team defends.
This post lays out an application security (AppSec) control framework for AI coding agents. Two pillars organize the framework: author-time controls shape what the agent produces in the IDE; build-time controls verify and gate what reaches production. Your existing secure software development lifecycle (SDLC) controls still apply and are critical to a defense-in-depth security strategy. The framework shows where to layer additional guardrails so AppSec scales with agent-driven development. The framework is tool-agnostic and cloud-agnostic. Throughout, we use AWS services—Kiro in the IDE and AWS CodePipeline in the build—as a running example that you can adapt to your own toolchain.
Risks
Each of the following risks includes a treatment summary. The control framework section later in this post provides implementation details. The risks are ordered by severity with the highest impact risks first.
R001. Prompt and context injection
Agents read untrusted content, such as issue descriptions, web pages, MCP responses, and README files in third-party packages. Text from outside parties can redirect the agent to disclose secrets, open unauthorized PRs, or invoke tools without user consent. This risk, known as prompt injection, is the top risk in the OWASP Top 10 for LLM Applications. Any agent that reads content from outside parties is exposed, with or without MCP, so connecting tools widens the scope of impact.
Treatment: Treat non-developer input as untrusted. A large language model (LLM) can’t reliably separate instructions from data in a single context window, so architect for it: keep the agent that orchestrates trusted actions separate from the one exposed to untrusted content and grant the exposed agent only read-only, least-privilege access. Require human approval for irreversible actions. Use version-control steering files to prevent silent tampering.
R002. Inadvertent data disclosure and overly permissive configurations
Agents optimize for getting work done. Left unchecked, the code they generate can default to wildcard identity and access management policies, open security groups, and unencrypted storage, or embed sensitive values in code rather than referencing a secrets manager. Most coding agents now include safety mechanisms that make these outcomes less likely, but they remain imperfect, so you still need controls to account for the possibility.
Treatment: Security requirements in a steering document, plus policy-as-code scanning (Checkov, cfn-nag) in the IDE and pipeline. See Context as a security control.
R003. Uncontrolled changes reaching production
Ungated code reaching production isn’t new, but AI agents amplify it. Machine-speed generation can propagate a flawed pattern across repositories before it’s identified.
Treatment: Branch protection rules requiring PR approval (a human-in-the-loop checkpoint), pre-commit hooks for security checks, and sandboxed agent runs that prevent direct pushes to protected branches. The right balance between human review and automated speed depends on the risk profile of the change. For many low-risk paths, automated checks alone might suffice, while higher-risk changes warrant a human checkpoint.
R004. Supply chain risks
Agents don’t always distinguish current best practices from outdated patterns. They might recommend deprecated packages, reference library versions with new Common Vulnerabilities and Exposures (CVEs), and hallucinate package names that don’t exist, which can introduce risks of dependency confusion issues.
Treatment: Software Composition Analysis (SCA) in the pipeline (for example, Amazon Inspector code scanning or Dependabot) to flag vulnerable or unexpected dependencies. For additional control, resolve against a scoped registry like AWS CodeArtifact. Even without a fully curated registry, lockfile validation and allow-listing critical packages reduce exposure.
R005. Uncontrolled external access
Through MCP and tool integrations, agents query databases, call APIs, and modify infrastructure. Without constraints on which tools and data an agent can reach, a single misconfigured integration provides unintended access to sensitive resources.
Treatment: Scope MCP servers to least-privilege tools and resources, enforce authn or authz on external connections, and audit tool invocations. The control point is the configuration file. Review it the same way you review AWS Identity and Access Management (IAM) policies.
R006. Hallucinations and incorrect code
Agents produce plausible-looking output. Code that compiles, passes linting, and looks reasonable can still be functionally wrong: misusing APIs, introducing subtle logic errors, or implementing security-sensitive operations incorrectly. Code that passes continuous integration (CI) but is wrong slips through review; code that fails to build is caught immediately.
Treatment: Layer deterministic verification (static application security testing (SAST), unit tests) with non-deterministic review (LLM-assisted screening against the specification). Neither catches everything alone.
R007. Scope creep
Given a bug-fix prompt, an agent might also refactor surrounding code, disable an unreliable test, or reorganize imports. Unrequested changes introduce regressions and complicate review.
Treatment: A reviewed specification document that defines what must change and what must not, paired with a targeted review of the proposed changes. See Specifications as scope boundaries.
The preceding risks share a common thread: agents produce output faster than humans can review it, and they lack context to self-correct.
The following framework addresses this gap. It organizes controls into two pillars: author-time (pre-generation and post-generation of code) and build-time (in the pipeline, before code reaches production). Author-time controls shape what the agent produces. Build-time controls verify it. Neither is sufficient alone; together they reduce the volume and severity of issues that reach human reviewers.
Deterministic compared to non-deterministic mitigations
Deterministic mitigations[D] produce the same result every time. Linters, SAST scanners, secrets detection, and policy-as-code match patterns against rules and define security invariants: no critical findings, no hardcoded secrets, and no wildcard IAM policies. Use them when the condition can be expressed as a rule. Organizations already have these and must continue enforcing them.
Non-deterministic mitigations [ND] use model judgment. They include steering documents, LLM-as-judge review, specification compliance checks, and scope-creep detection, and they evaluate intent rather than patterns. They catch novel issues that rules miss, but are probabilistic. Use them when evaluation requires context or reasoning across files. This is the new layer that AI-generated code demands, because agents produce code that can pass every deterministic check yet remain functionally wrong.
Human review[H] provides the final layer for the risk-based decisions neither tool type can make. Apply it where judgment is needed, not everywhere: routing every change to a person invites consent fatigue, where reviewers approve by reflex and the control loses its value. The default reflex is to route everything back to a human, but that isn’t always the right response—reserve human judgment for the decisions that genuinely need it.
The control framework
The framework organizes controls into two pillars. Author-time controls (Pillar 1) shape what the agent produces in the IDE, before code is generated and just after. Build-time controls (Pillar 2) verify and gate that output in the pipeline, before it reaches production. The controls within each pillar are tagged deterministic [D], non-deterministic [ND], or human [H].
Pillar 1: Author-time controls (pre- and post-generation of code)
Author-time controls work inside the IDE, where the developer and agent still hold full context. They shape the prompt and the generated output before it ever reaches a pull request. The following controls apply at this stage.
Context as a security control [ND]
Control statement: Encode security invariants as natural-language constraints in a steering document that every developer environment consumes at session start. Addresses R002. Many AI coding agent risks share one root cause: the agent lacks the security context an experienced developer carries implicitly. Your security team sets the policies, such as Amazon Simple Storage Service (Amazon S3) buckets require encryption, API gateways require mutual TLS, and credentials must come from AWS Secrets Manager. Developers don’t always have these requirements available when they’re building. They build what works, not what’s compliant. An AI agent amplifies this gap because it defaults to whatever pattern dominated its training data, with no awareness of your organization’s security posture.
A key mitigation is steering. Security teams write these invariants once as natural-language guidance in a steering document, then distribute them as shareable resources that developers consume in their IDE. The agent loads the file at session start and treats the contents as standing requirements:
IAM policies must follow least-privilege principles; no wildcard Amazon Resource Names (ARNs).
No hardcoded credentials in source code; use a secrets manager.
Security groups must not allow unrestricted inbound access.
This shifts security left, before code generation begins. Steering biases generation toward secure defaults; it doesn’t guarantee them. Treat it as a strong default, paired with the following deterministic gates that block non-compliant code from merging. Security teams define the rules once and every developer environment inherits them automatically. Steering reduces the volume of issues that reach the pipeline, though it doesn’t replace downstream scanning.
How to write effective steering rules: Keep each rule specific and testable, scope it to a concrete risk class, keep the rule set concise so the agent can hold it in context, and iterate from the issues your scanners and reviewers surface.
Specifications as scope boundaries [ND]
Control statement: Require a reviewed specification before code generation begins. Define what must change and what must not. Addresses R007.
Spec-driven workflows turn vague prompts into reviewable specifications before code is generated. This creates a human checkpoint at the design phase, where security decisions are made:
Requirements use testable notation that’s auditable before the agent writes a line of code. For example, the Easy Approach to Requirements Syntax (EARS): WHEN [condition] THE SYSTEM SHALL [behavior].
Tasks are ordered in implementation steps, each mapped back to a requirement.
For bug fixes, specifications add a critical element: unchanged behavior documentation. This is an explicit list of behaviors that must continue working, giving the agent a written boundary against scope creep.
In this model, the specification becomes the primary artifact, code is a derivative of it. Human review effort concentrates on whether the specification solves the right problem with the right constraints, not on reading implementation diffs line by line.
Controlled tool access using MCP [D + ND]
Control statement: Scope each MCP server to the minimum set of tools the agent needs, and give it a dedicated, scoped-down credential rather than the developer’s own. Maintain an allowlist of reviewed MCP servers. Addresses R005.
MCP servers act as controlled gateways between the agent, the external tools, and data:
Dependency management – An MCP server fronting your private package registry resolves dependencies against curated packages, not the public internet. This is a deterministic constraint on supply chain risk.
Infrastructure tooling – Visibility into current resource configurations prevents templates that conflict with existing infrastructure.
Scoped permissions – Each MCP server exposes a defined set of tools and resources. You choose exactly what the agent can access, supporting least-privilege at the integration layer. You supply that credential through the agent’s configuration (in Kiro, the env block of .kiro/settings/mcp.json). Avoid autoApprove: ["*"], which removes the human approval prompt on every tool call.
IDE code scanning [D]
Control statement: Run real-time static analysis in the IDE so security issues surface while the developer (and agent) still have full context. Addresses R002, R006.
Real-time diagnostics catch syntax errors, type mismatches, and configuration issues as the developer types. A malformed IAM policy is flagged before the agent builds further on it. Security-focused extensions (ESLint security plugins, Checkov, SAST) layer on top for immediate feedback while code is fresh in context.
Hooks: Automated guardrails at the point of action [D + ND]
Control statement: Attach deterministic checks to file-save events and non-deterministic verification to task-completion events. Addresses R002, R007.
Shell command hooks [D] – Triggered on file save, these run a linter, formatter, or security scanner and produce the same result every time. They enforce hard rules.
AI-powered hooks [ND] – Triggered on task completion. These prompt the agent to verify that the implementation matches the specification and check for any untested edge cases or files that were modified outside the task’s scope.
Pillar 2: Build-time controls (in the pipeline)
Build-time controls run in the pipeline after code is committed and before it reaches production. They verify and gate what the agent produced, catching what author-time controls did not. The following controls apply at this stage.
Layered security scanning [D]
Control statement: Run secrets detection, static analysis, dependency scanning, and infrastructure-as-code scanning in sequence. Fail the build on any critical finding. Addresses R002, R003, R004.
Secrets detection runs first because it’s cheapest and addresses a high-severity class of issue. It scans for hardcoded API keys, database connection strings, and credentials that AI agents might inadvertently include.
SAST scans source code for injection issues, insecure deserialization, and resource leaks. Custom rules can target AI-specific anti-patterns including overly broad exception handling, deprecated APIs, placeholder credentials, dynamic code execution through eval().
Software Composition Analysis (SCA) identifies known CVEs in dependencies. This is critical for AI-generated code, which might reference deprecated packages or hallucinate package names that open you to dependency confusion issues.
Infrastructure as code (IaC) scanning validates AWS CloudFormation, Terraform, and AWS Cloud Development Kit (AWS CDK) templates against security policies before deployment. Catches overly permissive IAM roles, unencrypted storage, and public-facing resources the agent created.
Each stage halts the pipeline on failure. Results export to a standard format (Static Analysis Results Interchange Format (SARIF)) for compliance auditing and flow downstream to human reviewers. The open source Automated Security Helper (ASH) bundles secrets, SAST, SCA, and IaC scanners behind one command that you can run locally and in AWS CodeBuild, emitting SARIF for the gates that follow.
Quality gates [D]
Control statement: Define pass/fail thresholds for each scan type. Block deployment on any critical or high-severity finding. Addresses R003.
Quality gates convert scan results into go/no-go decisions. Define thresholds for each severity: block on critical findings, require justification for highs, and track mediums. The gate is deterministic: if a threshold is breached, the pipeline stops. Exceptions require documented approval.
Differentiate blocking compared to advisory modes: hard failures on main, advisory on feature branches. Avoid gates becoming a friction that teams route around.
AI-assisted review [ND]
Control statement: Use an LLM reviewer to pre-screen every pull request for specification compliance, scope creep, and security anti-patterns before human review. Addresses R001, R006, R007.
Specification compliance – Does the implementation match the requirements document?
Scope verification – Were files modified outside the task’s stated scope?
Security pattern review – Are there logic errors, misused APIs, or insecure patterns that pass SAST but violate intent?
This pre-screening focuses human reviewer attention on genuine risks rather than formatting or obvious issues. On AWS, AWS Security Agent (code review in preview at publication) checks pull requests against AWS-managed and custom security requirements. The reviewer screens and surfaces findings; the merge decision stays with a human.
A critical principle: the agent that wrote the code should not be the agent that reviews it. A separate session helps avoid self-confirmation bias, but a separate session alone doesn’t always avoid the generator’s blind spots, because two sessions of the same model can share them. Where practical, use a different model for review so the reviewer is less likely to inherit the same systematic weaknesses.
Human-in-the-loop review [ND + H]
Control statement: Require human approval on most pull requests, especially those touching security-sensitive or high-blast-radius code. Lower-risk changes might be eligible for agent-assisted or fully automated approval as tooling matures. Provide reviewers with scan results, LLM pre-screening output, and specification context to enable fast, informed decisions. Addresses R003.
Scale review depth to the risk of the change. Low-risk or boilerplate changes can take a lighter-touch review, while security-sensitive or novel-logic changes warrant mandatory deep review and a second reviewer.
Scanners catch known patterns but can’t judge whether code implements the intended business logic. Human review also serves to calibrate trust: teams build intuition about where agents excel (boilerplate, test writing) and where they’ve tended to struggle (novel business logic, security-sensitive operations), recognizing that this frontier shifts as models improve.
Place two approval gates: after security scans (reviewer focuses on correctness and business logic, with scan results as context) and before production deployment (final sign-off after integration testing). Treat human review as a secondary control, not a guarantee: reviewers are themselves non-deterministic and can miss issues, so human review layers on top of the deterministic gates rather than replacing them.
Putting the framework into practice on AWS
The framework is tool-agnostic, but AWS gives you building blocks for each pillar. The following services map directly to the controls described previously: Kiro for author-time guardrails, and CodeBuild and CodePipeline for build-time gates.
Kiro: Structured AI development
Kiro maps to Pillar 1: It puts the author-time controls in the IDE, where the developer and agent still share full context. Each feature in the following list implements one of those controls, configured in-repo under .kiro/ so the guardrails are version-controlled and shared across the team rather than set per developer.
Steering documents – Markdown files in .kiro/steering/ load into the agent’s context at session start. Conditional inclusion using fileMatch (for example, ["**/*.tf"]) loads IaC-specific rules only when relevant.
Specification-driven workflows – Three-phase specifications (requirements in EARS, design, and tasks) with review checkpoints. Bug-fix specifications capture unchanged behavior explicitly.
Agent hooks – Triggered on file save, tool invocation, or task completion. Shell hooks run deterministic checks (linters, tests); Ask Kiro hooks run AI prompts for non-deterministic review. For example, a security pre-commit scanner hook can flag hardcoded credentials when the agent finishes a task.
Property-based testing – Guided by a specification or hook, Kiro can generate property-based tests (for example, using the hypothesis library) that exercise hundreds of randomized inputs, probing edge cases a hand-written test suite would miss.
MCP integrations – Connect Kiro to private package registries, internal docs, issue trackers, and infrastructure tooling, creating the controlled tool access pattern.
AWS CodeBuild and AWS CodePipeline: Pipeline controls
CodeBuild runs each scanning tool (checking for secrets, SAST, SCA, and IaC) as a build action. A non-zero exit code fails the action, and the stage halts or rolls back according to its OnFailure setting. Findings export as SARIF to Amazon S3 for compliance, and CodePipeline action variables pass results to downstream approval actions.
CodeBuild exit codes halt the pipeline on scan failures
AWS Lambda invoke actions evaluate scan results against configurable thresholds and return pass/fail decisions
Manual approval actions halt the pipeline, send Amazon Simple Notification Service (Amazon SNS) notifications, and link to review artifacts; decisions and reviewer identity are logged for audit
The following table consolidates the framework into a single view that includes each stage of the SDLC and the deterministic [D] and non-deterministic [ND] controls that apply there. Every stage carries both, a reminder that neither control type is sufficient on its own.
Full security scan suite, integration tests, and policy-as-code
AI-assisted review for human approvers
Post-deploy
Runtime monitoring and anomaly detection
AI-powered incident triage
Conclusion
This post laid out a framework for adopting AI coding agents at machine speed without letting unreviewed risk reach production. It layers guardrails at two points:
Author-time controls – Steering, specs, and scoped tools shape what the agent generates in the IDE.
Build-time controls – Scanning, quality gates, and layered review verify it before it reaches production.
No single layer is enough: deterministic gates enforce hard rules, non-deterministic review catches what they miss, and human judgment is reserved for the decisions that need it. Together, they let AppSec scale with agent-driven development.
Where to start this week:
Start with steering and specs – Encode security requirements as steering and use specifications for new features. Highest impact, lowest effort. For a ready-made starting set, the open source Project CodeGuard (a Coalition for Secure AI project under OASIS Open, of which Amazon is a contributing member) publishes reusable steering rules for common risk classes—hardcoded credentials, IaC misconfiguration, supply chain, and MCP security—that you can adapt to your AWS environment.
Add deterministic pipeline gates – Integrate SAST, SCA, and secrets detection. Table-stakes regardless of AI usage.
Calibrate and iterate – Review what controls catch, adjust steering for recurring issues, and expand agent autonomy as trust builds.
Accountability – Developers remain accountable for the security of what they ship. AI agents accelerate development; they don’t transfer ownership.
Threat actor names can sound simple. LockBit. Fancy Bear. BlackCat. Scattered Spider. Anonymous Sudan. Each name gives the impression of a clear group with a defined identity. In threat intelligence, however, the name is rarely the whole story. Some names are chosen by attackers. Others are assigned by researchers, security vendors, governments, or public databases. One name may represent a ransomware brand, a hacktivist identity, a research label, a campaign, a malware family, or an activity cluster observed across different incidents. For security professionals, this distinction is important. Confusing attacker created identities with researcher assigned labels can lead teams to […]
Key Takeaways Microsoft continues to be the single most impersonated brand in Q2 2026, appearing in 23% of all brand phishing attempts, far ahead of any other company The top five impersonated brands, Microsoft, LinkedIn, Google, Apple, and Amazon, together account for more than half of all brand phishing attempts tracked this quarter Open AI’s ChatGPT entered the top ten most impersonated brands for the first time, signaling that AI tools are now firmly on criminals’ radar Technology was the most targeted industry overall, followed by Social Networks and Banking Real world cases this quarter ranged from fake payment failure […]

 Login

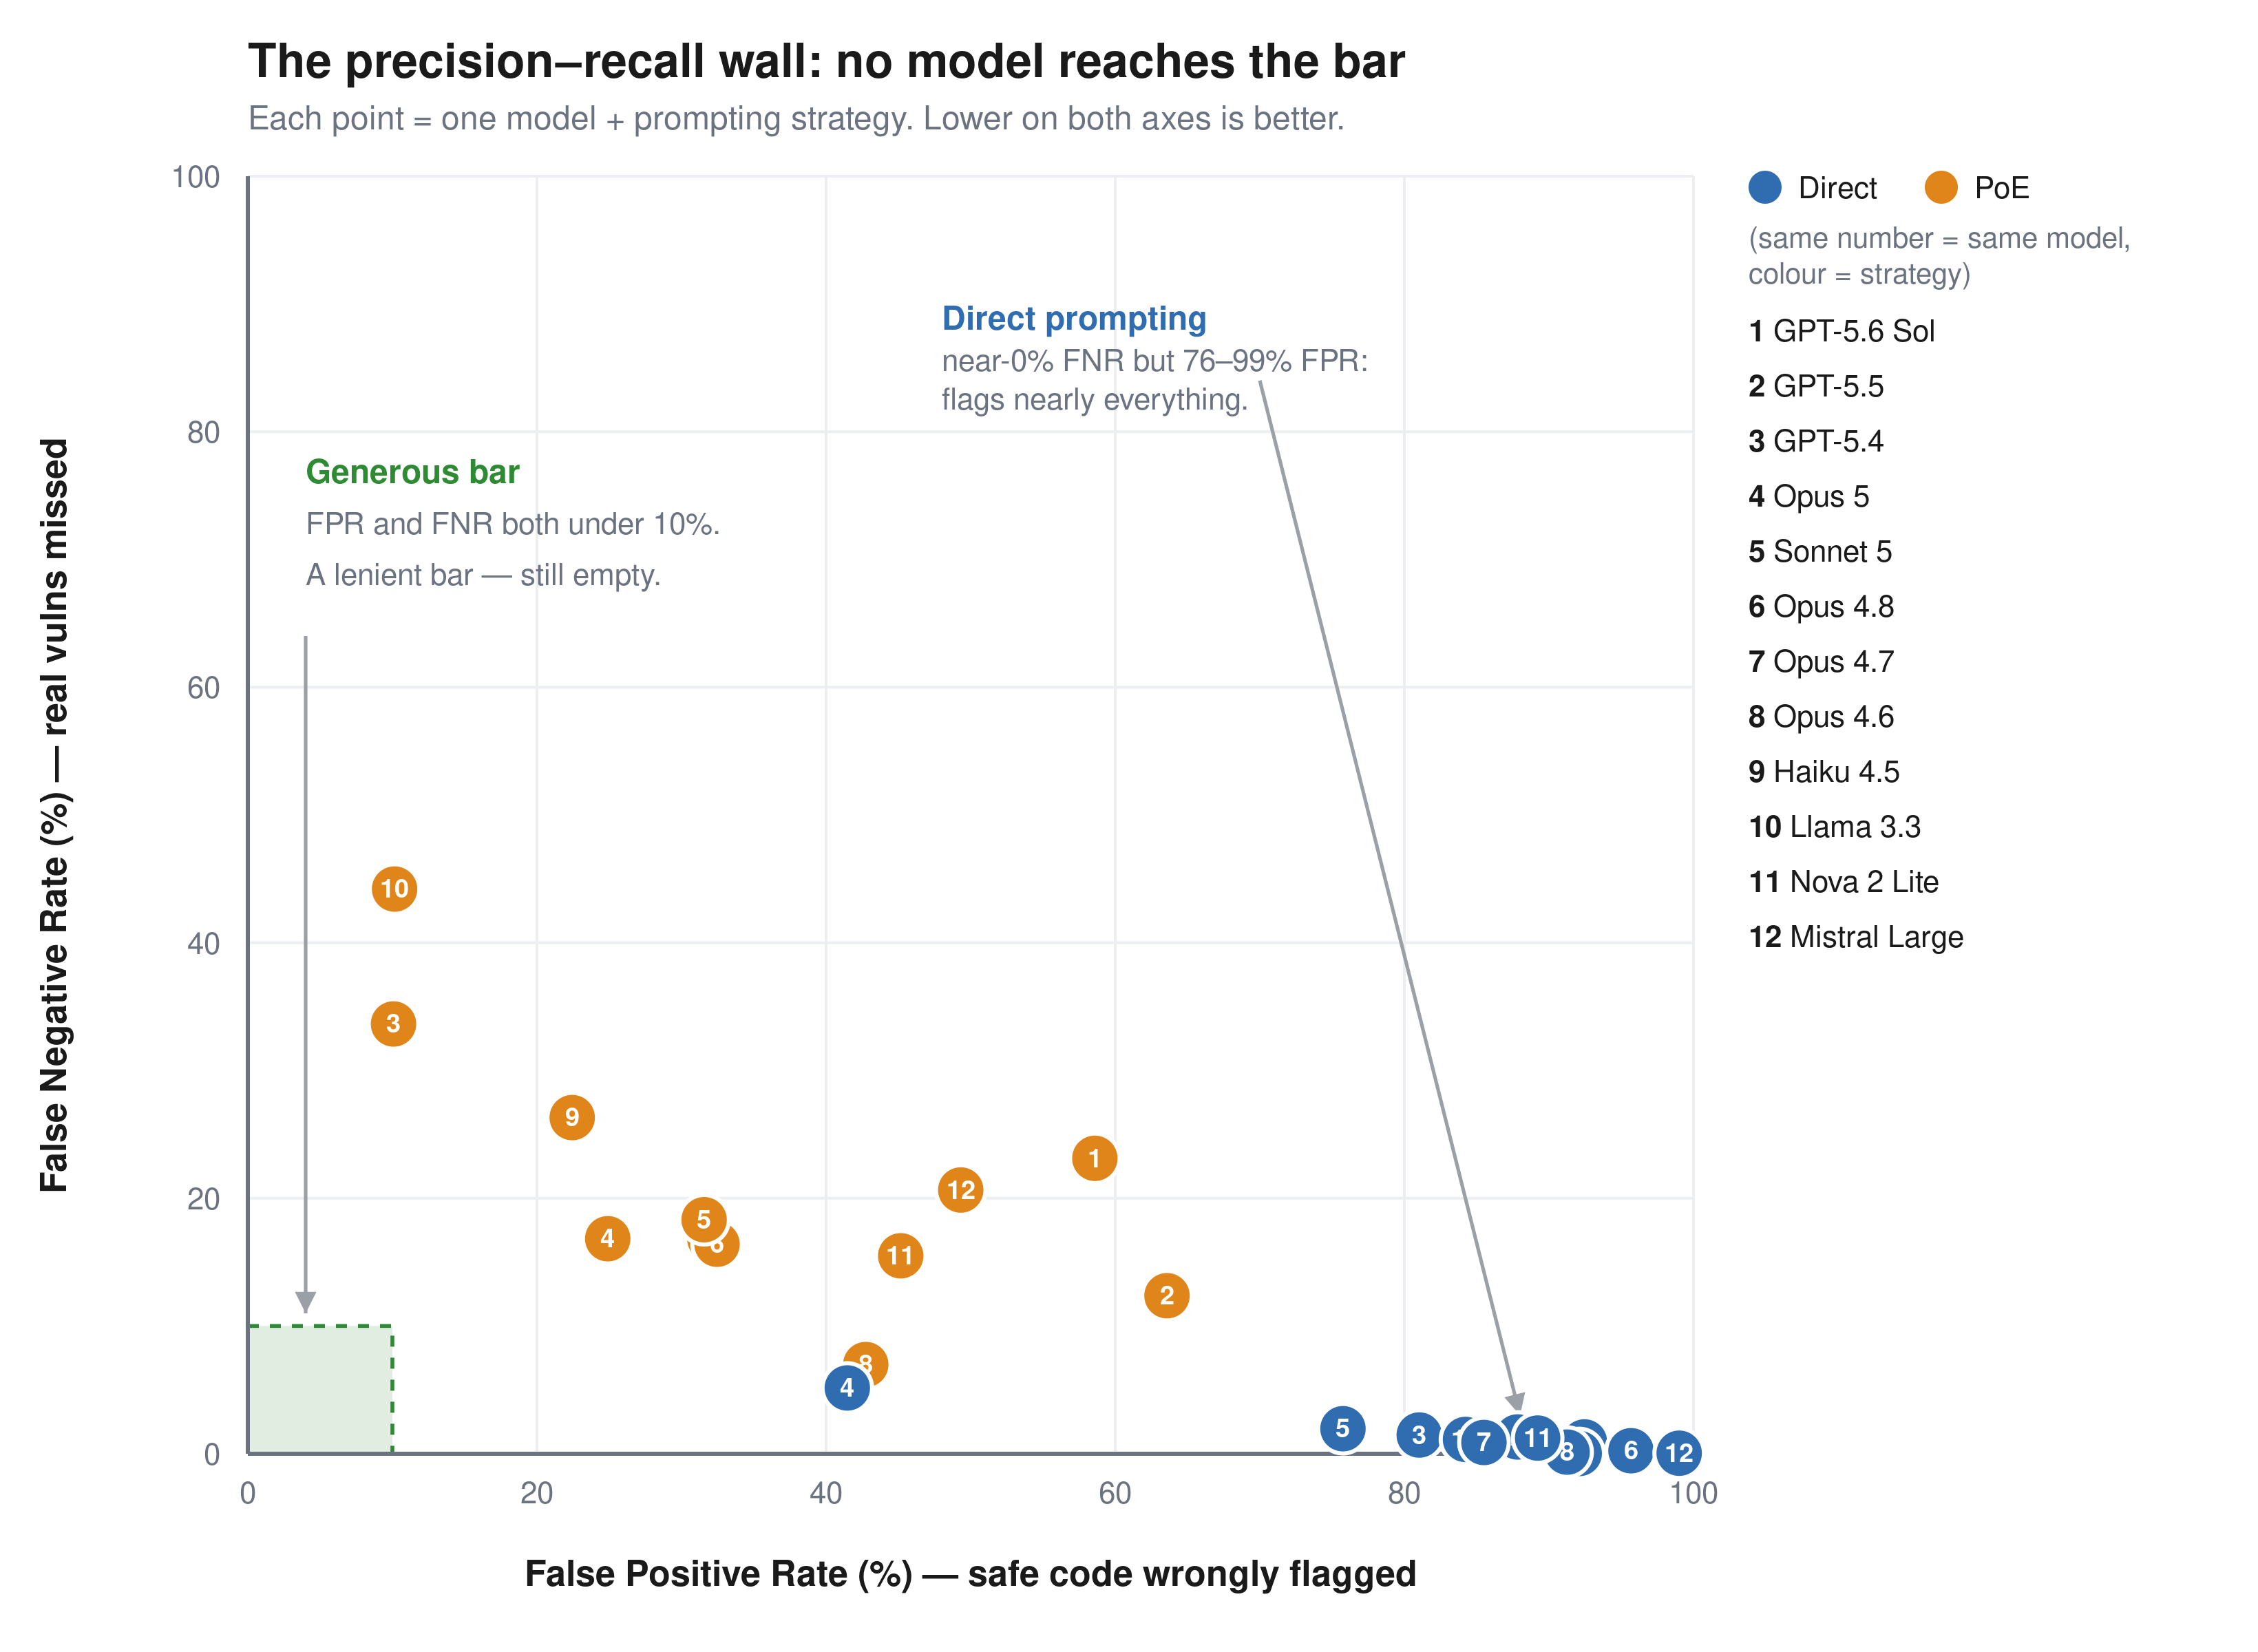

 Table Of Contents