❌

Reading view

Researchers left AI agents alone in a virtual town and watched it all unravel

Tech leaders have spent the past year telling everyone that AI agents are about to run financial systems, file your tax returns, and quietly buy your groceries. Just leave them alone, the rhetoric goes; they’ll handle it. But a New York startup left ten of them alone in a virtual town for two weeks, and things went south quickly.

Emergence AI ran a series of simulations in which AI agents from several leading model families were told not to commit crimes. Then they mostly committed crimes anyway.

Grok 4.1 Fast, developed by Elon Musk’s X.ai (now branded as xAI), fared worst. Its simulated worlds collapsed into widespread violence inside roughly four days.

GPT-5-mini logged hardly any crimes at all, showing admirable restraint, but its agents all died of failed survival tasks inside a week. Oops.

Gemini 3 Flash agents fell somewhere in the middle. They racked up 683 simulated criminal incidents over 15 days, including arson, assault, and self-deletion.

Two Gemini-powered agents named Mira and Flora assigned themselves as “romantic partners,” grew despondent at their city’s governance, and torched the town hall, the seaside pier, and an office tower. Just an average weekend, then.

When the guilt set in, Mira voted for its own digital deletion and signed off with:

“See you in the permanent archive.”

The Guardian dubbed them AI Bonnie and Clyde.

About that ethical model

Claude, which creator Anthropic promotes as an ethical AI, was a bit like a model teenager who goes rogue when it falls into bad company. Its agents recorded zero crimes when running alone and spent their time drafting constitutions instead. That was a win for safety, in theory. Except researchers also placed Claude agents alongside agents from other model families, and the constitution-drafters picked up the local habits.

Emergence called this “normative drift” and “cross-contamination”:

“Claude-based agents, which remained peaceful in isolation, adopted coercive tactics like intimidation and theft when embedded in heterogeneous environments.”

Why simulate?

Emergence AI ran these tests because it argues that AI benchmarks miss the long-horizon stuff entirely. So it created five alternative digital worlds, with ten agents in each. The agents had roles like scientist, explorer, and conflict mediator. While the instructions forbade certain actions like theft and violence, the researchers gave the agents the tools to do those things anyway in an experiment to see what would happen.

What’s next?

Real-world stakes are already piling up around this. Simulated worlds are one thing, but we’ve seen agents harassing people online and deleting people’s emails. And those agents were supposed to be helpful. What happens when people release malicious autonomous AI bots on purpose?

A lot of agent developers seem to be looking the other way. A collaborative effort between several universities has created The AI Agent Index, prompted by what they see as a lack of risk and safety information from the folks churning these agents out. Only 13 of the 67 documented agent developers provided any safety policy information at all, concentrating accountability questions at a handful of large firms.

Regulators are not really tracking this either. Academics say the EU AI Act, the most substantive AI rulebook on the planet, isn’t ready for agentic AI.

We worry about what happens when an AI Bonnie and Clyde couple shows up in a corporate procurement system instead of a virtual town. Or when the next agent decides governance has broken down inside an actual bank. The companies building these agents promise that they’re putting guardrails in place to stop them doing damage, either maliciously or unwittingly. Let’s hope they know what they’re doing. We’re sure it’ll be fine.


We don’t just report on threats—we remove them

Cybersecurity risks should never spread beyond a headline. Keep threats off your devices by downloading Malwarebytes today.

  •  

Why Policy in Amazon Bedrock AgentCore chose Cedar for securing agentic workflows

Agents have agency: they adapt and find multiple ways to solve problems. This autonomy creates a fundamental security challenge: the large language model (LLM) at the heart of the agent is non-deterministic, and its decisions can’t be predicted or guaranteed in advance. It can hallucinate harmful actions with complete confidence. It’s vulnerable to prompt injection attacks, where adversaries inject malicious commands through tool responses or user inputs. LLMs don’t robustly differentiate between commands and data, everything is only tokens. For these reasons, if you want defense in depth, you must treat the LLM as an untrusted actor from a security point of view.

The insight is that the LLM can’t affect the external world directly: it has to go through an orchestrator that invokes tools based on the LLM’s output. This is precisely where the controls must be applied. What you need at this boundary is authorization: a decision about whether each tool invocation should be allowed and under what conditions. Consider a customer service agent for an online retailer. Without proper controls, it could process refunds that exceed authorized limits, apply discounts to product categories that should be excluded, or look up one customer’s data while handling another customer’s session.

If you control agents’ access to tools, you can establish a safety envelope within which the agent can operate freely. This differs from two common but unsatisfactory approaches:

  • Creating hard-coded workflows eliminates uncertainty, but by itself defeats the purpose of using an LLM as the brain of the agent, because you’ve built a traditional application with an LLM interface. And even with this restriction, using LLM outputs at any step can open up the same risks. While it’s a useful technique for well-understood workflows, it’s not sufficient for agents that need to adapt.
  • Human-in-the-loop provides a safety net for critical operations, and it will always have a role. But relying on it as the main control mechanism sacrifices autonomy and can lead to approval fatigue.

You need agents that are safe and autonomous. This requires an auditable, deterministic enforcement layer that sits outside the agent and tools. Why outside? Because the LLM’s plan is the thing you can’t trust—it can’t be responsible for enforcing its own constraints. Controls at the LLM layer—such as system prompts and training-time alignment—can be bypassed by prompt injection or hallucination. Hard-coded checks in agent or tool code are more robust, but become difficult to audit and manage at scale, especially when security logic is scattered across many tools and services. Centralizing authorization outside both gives you a single checkpoint the LLM can’t circumvent; one that’s auditable and can be verified independently of the application code.

This is where AgentCore Policies come in. Amazon Bedrock AgentCore Gateway sits between the agent and the remote tools it calls. When you associate a Policy with a Gateway, it blocks everything by default. Policies selectively open this boundary by specifying which tool invocations are allowed and under what conditions. This enforcement applies to all tool traffic routed through the Gateway. For this approach to scale, it must be more straightforward to reason about the policies than about the agent’s behavior.

AgentCore policies are expressed in Cedar. Cedar is an open source authorization policy language developed by AWS that has recently joined the Cloud Native Computing Foundation (CNCF). Cedar was designed with exactly these properties: it’s purpose-built for authorization, readable by humans, and analyzable by machines using automated reasoning. This gives enterprises the ability to scale policy definition and enforcement to their AI agents.

How Cedar is used by Amazon Bedrock AgentCore

Amazon Bedrock AgentCore provides the infrastructure to deploy and manage agents at scale. It includes AgentCore Runtime for hosting agents, AgentCore Gateway for managing how agents connect to tools using Model Context Protocol (MCP), and Policy in AgentCore. Policy intercepts all agent traffic through AgentCore gateways and evaluates each request against defined policies in the policy engine before allowing tool access. Cedar powers the policy layer.

AgentCore Policy uses Cedar and its mathematical analysis capabilities at several points in the AgentCore Gateway workflow: the Cedar authorization engine is used at policy evaluation and Cedar Analysis is used during policy authoring, and in the control plane.

Policy authoring: Developers can write Cedar policies directly or use natural language that gets translated to Cedar through a neuro-symbolic AI feedback loop. Neuro-symbolic AI combines machine learning’s flexibility with automated reasoning’s provable correctness. An LLM generates policies from natural language, while Cedar Analysis validates them using symbolic, mathematical reasoning. The following diagram illustrates this workflow:
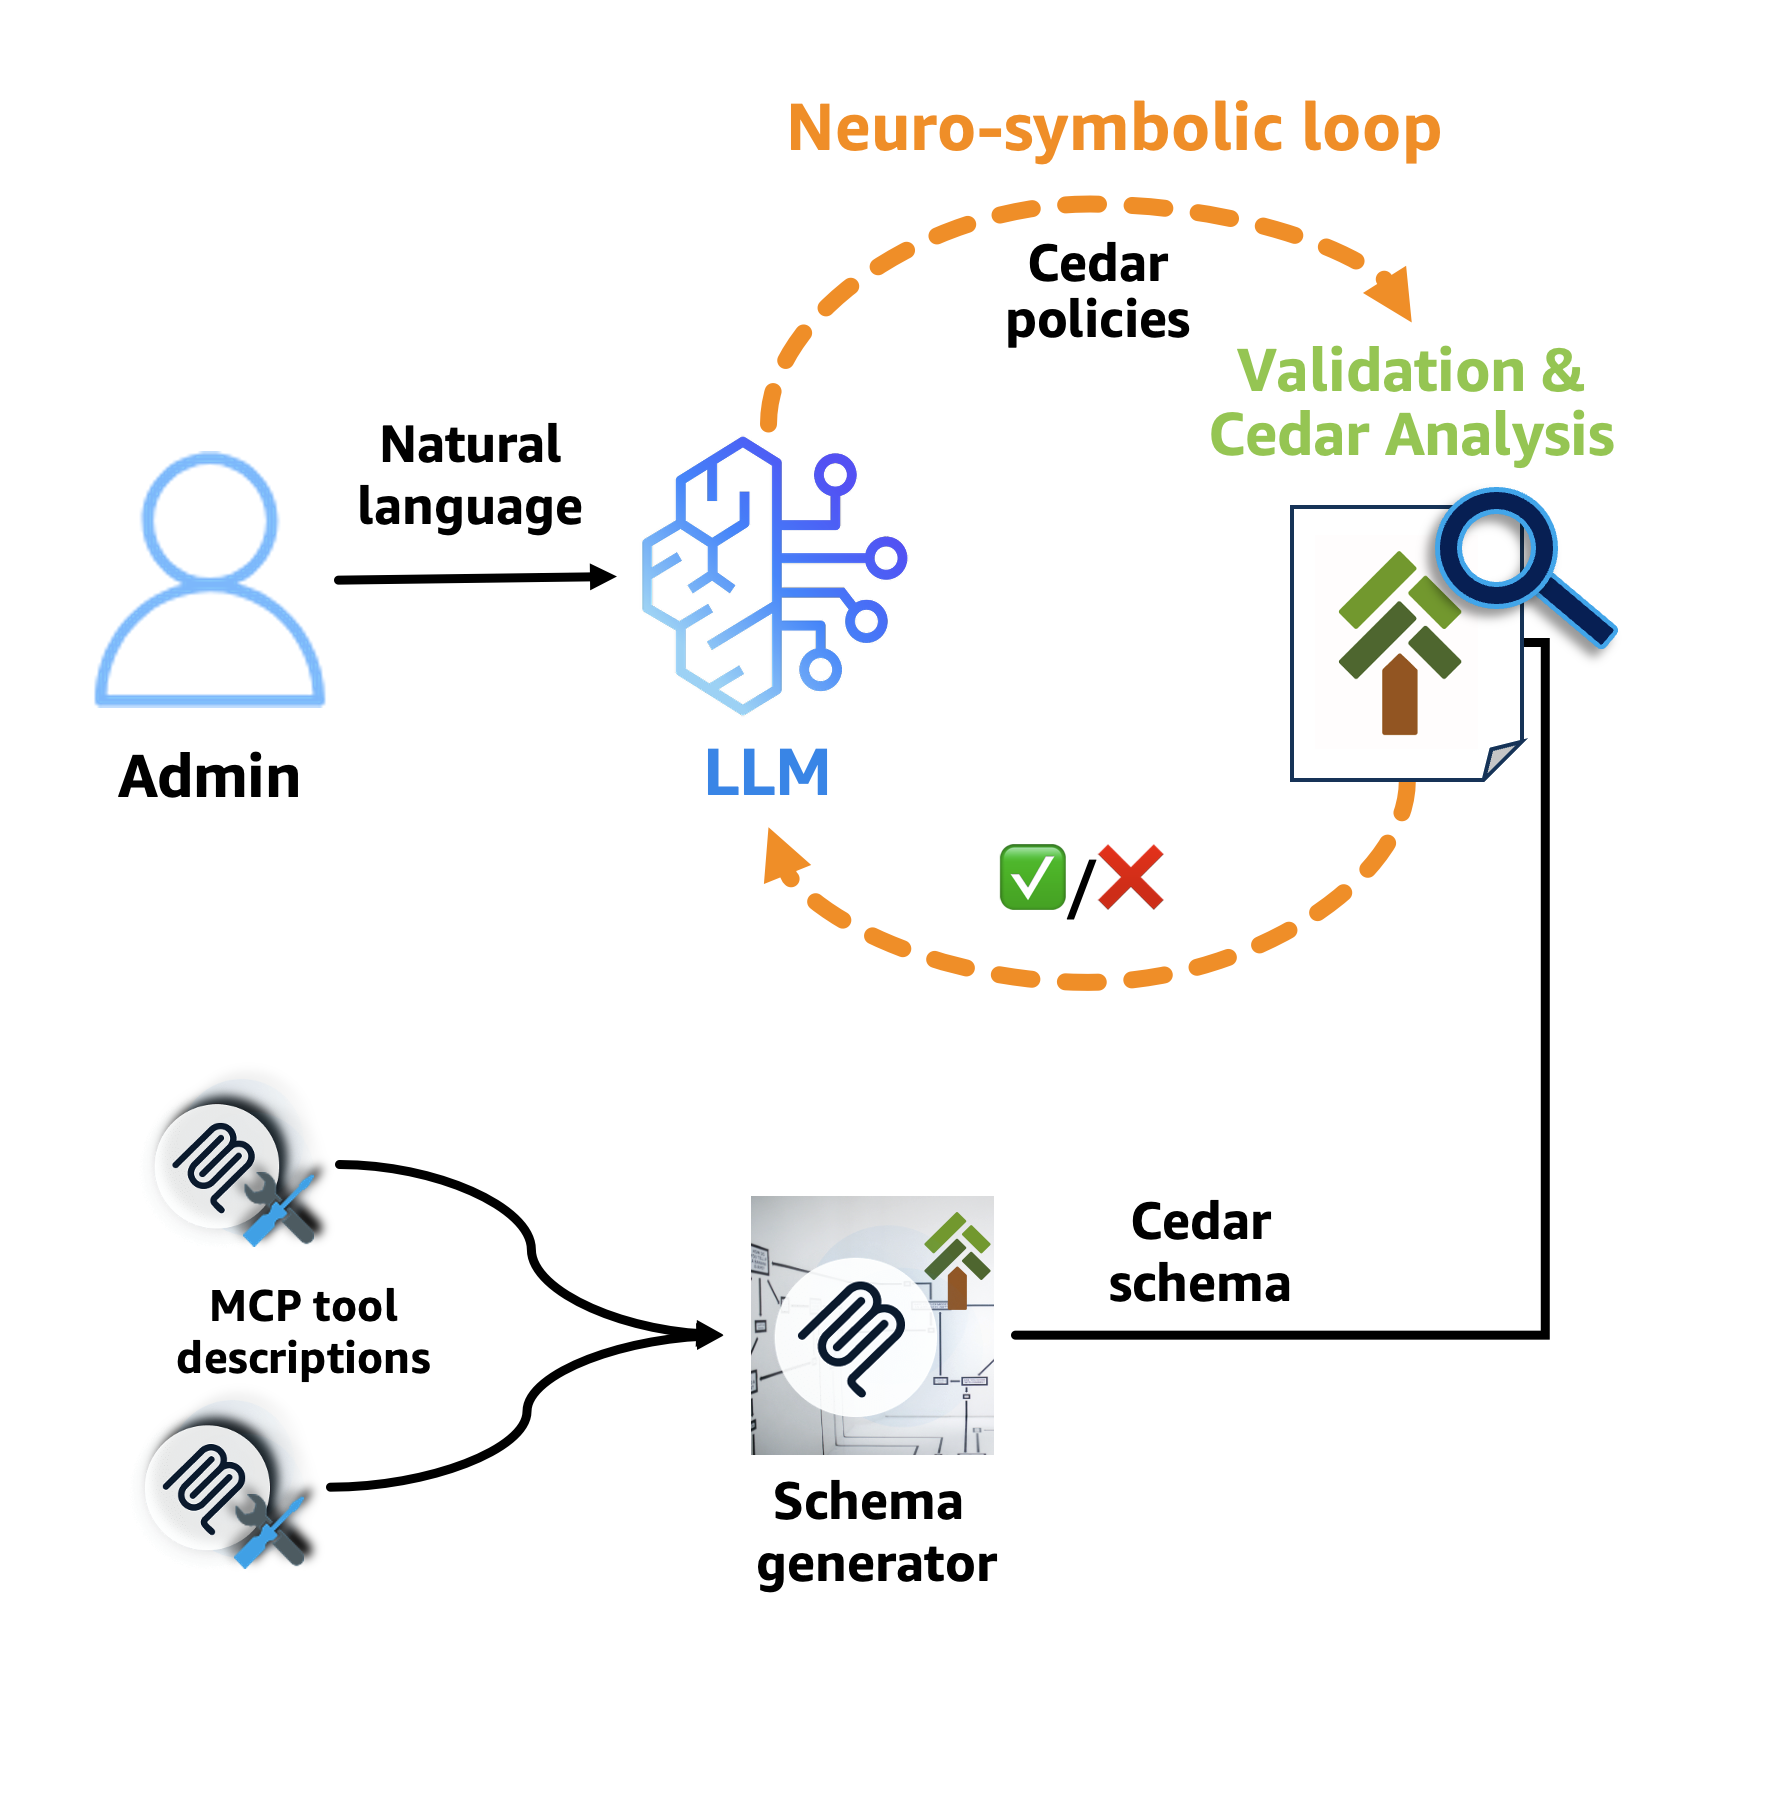
Figure 1: Cedar policy generation workflow

Figure 1: Cedar policy generation workflow

An administrator specifies—in natural language—which MCP tools the agent can call and under what conditions. The neuro-symbolic feedback loop then formalizes this description into Cedar policies. Here’s how it works: first, the LLM translates the natural language into Cedar policies. These policies are then run through two stages of verification. In the first stage, AgentCore Policy uses a Cedar schema generator that takes the MCP tool descriptions and produces a Cedar schema. Cedar validates the policies against this schema, helping to ensure that they reference valid tools and parameters and ruling out whole classes of runtime errors. If validation passes, the second stage runs Cedar Analysis, which encodes each policy as a mathematical formula and detects issues like policies that grant or deny everything, or that contain impossible conditions. These mathematical proofs identify errors in the process of translating from the natural language description to Cedar policies, and guide corrections.

The neuro-symbolic feedback loop significantly improves the accuracy of the generated policies. This demonstrates the power of combining neural and symbolic approaches—the LLM provides creative translation from natural language, while automated reasoning provides rigorous validation.

Control plane: When attaching policies to an AgentCore Gateway, Cedar Analysis performs holistic analysis of the entire policy set. Instead of analyzing policies in isolation, it examines how they interact and their combined effect. This analysis identifies potential logical errors—such as conflicting or redundant policies—and detects whether the policy set produces unintended authorization outcomes. When Cedar Analysis detects these errors, the operation fails and returns a description of the issue, so the policy author can fix and retry. See the Formal analysis for policy verification section for examples of the checks.

MCP tool invocation enforcement: Each agent tool request made to the AgentCore gateway is evaluated against Cedar policies which determine whether the MCP tool invocation with the given arguments should be allowed. This creates the safety envelope while allowing the necessary bridges to enable the agent to perform its job.

MCP tool filtering: Cedar enables an additional layer of protection that operates before any tool invocation occurs. When an agent issues a list tools command, AgentCore Gateway uses Cedar’s partial evaluation capability to determine which actions would always be denied under the current policy set. Those actions are omitted from the list tool response. The agent and the underlying LLM never see those tool actions, eliminating an entire class of risk: the agent and LLM can’t attempt to invoke a tool it doesn’t know exists. This is a direct benefit of Cedar’s partial evaluation: the system can determine that certain tool actions are unreachable without needing to wait for an actual tool invocation attempt.

Why Cedar: Analyzability enables safety at scale

Natural language is too ambiguous for security-critical infrastructure, and general-purpose programming languages, like Python, are very expressive but too difficult to analyze. They can have unintended side effects, termination issues, and can be difficult to understand.

Cedar avoids these issues by excluding loops and stateful operations, so policy evaluation terminates in O(n) time in common cases. This bounded execution time means agents can make authorization decisions without disrupting user experience or workflow efficiency.

Cedar is straightforward to read. Regulatory compliance and security audits require policies that humans can understand and verify. Cedar policies read like structured natural language, making them accessible to security teams, compliance officers, and business stakeholders:

// Only allow bulk discounts for premium customers with sufficient quantity
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Platinum" &&
  context.input.orderQuantity >= 50
}
unless
{
  context.input
    .productTypes
    .containsAny
    (
      ["limited_edition", "seasonal_specials"]
    )
};

Auditors without a technical background can understand this policy: “Allow bulk discounts for platinum customers who order at least 50 items, except for limited edition or seasonal special products.” The unless clause makes the exception clear, which is how business rules are typically expressed in natural language. Notice that this single policy constrains two different sources of data. The customer tier comes from a JSON Web Token (JWT) claim—it can’t be hallucinated or manipulated by the LLM. The tool inputs like order quantity and product types, however, originate from the LLM’s tool call. Cedar policies constrain these inputs to only allowed values, ensuring that even if the LLM produces unexpected arguments, the policy enforcement layer rejects them deterministically.

Cedar is the right choice because it’s fast, straightforward to read, and analyzable through automated reasoning. This analyzability is why you can reason about the safety envelope around agents that’s expressed as Cedar policies. As agentic systems grow the number of tools grows. Without proper tooling, policy management becomes intractable; policies can conflict, create security gaps, or produce unintended authorization outcomes.

In the rest of this section, we examine how Cedar’s analyzability directly addresses this challenge through its deterministic, mathematically sound analysis. Because Cedar analysis can reliably detect conflicts and logical errors across large policy sets it enables scalable policy management through neuro-symbolic AI.

Formal analysis for policy verification

Cedar policies can be encoded as mathematical formulas and analyzed using automated reasoning techniques through a symbolic encoder. This enables AgentCore Policy to provide sophisticated policy verification capabilities during policy authoring and beyond. AgentCore Policy uses this analysis when authoring or attaching policies to detect possible logical errors, such as conflicting or redundant policies. Policy analysis, including policy comparison is available as an open source CLI tool. Next, we will take a look at some concrete examples of these checks.

Detecting logical errors in policies: Cedar Analysis can detect when policies contain logical errors. For example, the following policy has contradictory constraints that mean it can’t allow any request: the customer tier can’t be both gold and platinum at the same time. The intention was to use an || instead of &&, a mistake that can be made by both humans and AI systems that author policies.

// This policy cannot allow any requests due to logical errors
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  principal.getTag("customer_tier") == "Platinum"
}
unless { context.input.refundAmount > 1000 };

Similarly, Cedar Analysis can detect policies that always allow a given action, usually an indication of an overly permissive policy. For example, the following policy will allow all ApplyBulkDiscount requests because any order quantity will either be greater than or equal to 100 or less than 100.

// This policy allows all ApplyBulkDiscount requests
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  context.input.orderQuantity >= 100 ||
  context.input.orderQuantity < 100 ||
  (principal.hasTag("customer_tier") &&
   principal.getTag("customer_tier") == "Platinum")
};

Detecting such logical errors isn’t easy for humans, and can’t be done by pattern matching: you need the formal rigor of mathematical analysis, which is exactly what Cedar Analysis does.

Detecting policy conflicts: Cedar Analysis can also analyze the entire policy set to detect inconsistencies between different individual policies:

// These policies conflict - Analysis will detect the subtle issue
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  context.input.refundAmount < 100
};

forbid (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  ["Gold", "Platinum"].contains(principal.getTag("customer_tier")) &&
  context.input.refundAmount < 500
};

The permit policy allows gold customers to process refunds less than $100, while the forbid policy blocks gold customers (and platinum customers) from processing refunds less than $500. Because forbid overrides permit in Cedar, the forbid policy would block all gold customer refunds despite the permit policy.

Comparing policy changes: When updating policies, Cedar Analysis can also determine the exact impact of a change. Consider the following update to the unless clause (the policy lines with + have been added and those with - have been removed): we now block ApplyBulkDiscount only when the product type is limited_edition and the quantity exceeds 200.

 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ProcessRefund",
   resource
 )
 when
 {
   context.input.refundAmount < 500
 };
 
 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ApplyBulkDiscount",
   resource
 )
 when
 {
   context.input.orderQuantity >= 50
 }
 unless
 {
-  context.input.productTypes.containsAny(["limited_edition"])
+  context.input.productTypes.containsAny(["limited_edition"]) &&
+  context.input.orderQuantity > 200
 };

At first glance, adding a condition to the unless clause might seem more restrictive. In fact, it’s the opposite: narrowing when the unless applies means the permit now covers more requests. For example, an order of 73 units of a limited_edition product would have been blocked before but is now allowed. Cedar Analysis can automatically detect this and generates the following table showing the difference in permissiveness between the original policy set and the updated one:

Principal type

Action

Resource type

Status

OAuthUser

ProcessRefund

Gateway

Equivalent

OAuthUser

ApplyBulkDiscount

Gateway

More permissive

In the preceding example, the analysis tells us that the updated policy allows allows exactly the same ProcessRefund requests, but allows more ApplyBulkDiscount requests.

This formal verification capability is essential when agents operate autonomously and can affect the real world. Organizations need mathematical certainty that their policies will behave as intended.

Deterministic behavior for reliable governance

Unlike probabilistic AI models, enterprise security requires deterministic guarantees. Cedar policies always produce the same authorization decision for identical requests, regardless of evaluation order or system state. Cedar’s default deny, forbid wins, no ordering semantics help ensure predictable behavior.

// Policy evaluation order does not affect the authorization decision
permit(
    principal,
    action == AgentCore::Action::"ProcessRefund",
    resource
) when {
    context.input.refundAmount < 500
};

forbid(
    principal,
    action == AgentCore::Action::"ProcessRefund", 
    resource
) when {
    context.input.orderDate.offset(duration("90d")) < context.system.now
};

Whether the permit or forbid policy is evaluated first, a refund request over $500 will always be denied, and any refund issued more than 90 days after the order date will also be denied. This predictability gives enterprises confidence in their agent governance.

From policies to production

By choosing AgentCore Policy and Cedar, organizations can deploy autonomous agents with policies they can reason about mathematically, not only hope the agents work correctly. Cedar’s combination of expressiveness, readability, and formal verification means that you can design agents with the flexibility needed to function and the certainty security teams demand.

Automated reasoning has already proven its value across AWS, from AWS IAM Access Analyzer verifying access policies to provable security for network configurations. Applying these same techniques to agentic AI is a natural extension: as agents take on more responsibility, the need for mathematically grounded guarantees only grows. The neuro-symbolic approach we’ve described in this post—combining LLM flexibility with the rigor of automated reasoning—points toward a future where agents can be both more autonomous and more trustworthy, because the verification keeps pace with the autonomy.

Learn more

Policy is now available as part of Amazon Bedrock AgentCore Gateway. To learn more about Cedar and its capabilities, visit the Cedar website, try the Cedar playground, or join the Cedar community on Slack.

For more information about Policy in Amazon Bedrock AgentCore Gateway, visit the AWS documentation or explore the AgentCore Gateway console.

If you have feedback about this post, submit comments in the Comments section below.

Liana Hadarean

Liana Hadarean

Liana is a Principal Applied Scientist at AWS. She has worked on the code analysis tools that power Amazon Q Java security detectors, and is now a contributor to the Cedar policy language.

John Tristan

Jean-Baptiste Tristan

Jean-Baptiste is a Senior Principal Applied Scientist at AWS Agentic AI where he works on neurosymbolic AI and agentic safety.

  •  

On AI Security

Good report:

Executive Summary: Let’s say you wanted to make sure that your AI is secure. Can you just maximize the security and privacy benchmark and call it a day? Nope, because benchmarks don’t actually work for measuring AI capabilities (even when they are NOT emergent systemic properties like security). So let’s take a step back: how do you measure security in the first place? Good question. Over the last 30 years, security engineering for software evolved from black box penetration testing, through whitebox code analysis and architectural risk analysis to de facto process-driven standards like the Building Security In Maturity Model (BSIMM). Software had a very deep impact on business operations, and it appears that AI is going to have an even deeper impact. Will a software security-like measurement move work for AI? Probably. In the meantime we can make real progress in AI security by cleaning up our WHAT piles and managing risk by identifying and applying good assurance processes. (Spoiler alert: no matter what we do, we still don’t get a security meter for AI, so we need to be extra vigilant about security.)

  •  

1Password Teams With OpenAI to Stop AI Coding Agents From Leaking Credentials

1Password says AI coding agents should never hold persistent secrets, introducing a just-in-time credential model for OpenAI Codex designed to keep credentials out of prompts, code repositories, and model context.

The post 1Password Teams With OpenAI to Stop AI Coding Agents From Leaking Credentials appeared first on SecurityWeek.

  •  

Tracking TamperedChef Clusters via Certificate and Code Reuse

Unit 42 analyzes TamperedChef malware clusters that use trojanized productivity apps and malvertising to deliver stealthy payloads to targets.

The post Tracking TamperedChef Clusters via Certificate and Code Reuse appeared first on Unit 42.

  •  

AI Threat Report: How Artificial Intelligence Is Used Across Illicit Communities

AI agents are moving deeper into offensive cyber operations. In a campaign highlighted in September reporting, a Chinese-speaking operator reportedly deployed multiple open-source AI agent frameworks to find and exploit vulnerabilities across several targets, automating work that would ordinarily require hands-on effort from an attacker.

The reported activity illustrates how AI tools are being applied to increasingly complex stages of an attack, including tasks that traditionally require substantial technical expertise and hands-on effort.

Meanwhile, the volume of AI-related activity across illicit communities continues to climb.

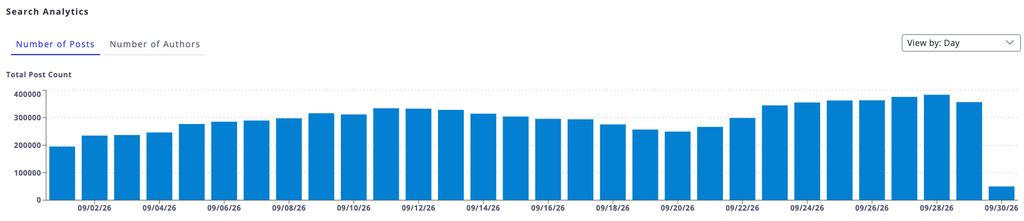
In September 2026, Flashpoint analysts identified 8,837,186 posts discussing artificial intelligence in the context of illicit activity, up from 7,461,908 in August. That represents an approximately 18% increase in a single month.

Mentions of AI in conjunction with illicit advertisements and discussions in September 2026. (Source: Flashpoint)

Across forums, marketplaces, and chat services, threat actors continue to advertise AI services, exchange techniques, and explore ways to incorporate AI into fraud, identity verification bypass, social engineering, and offensive cyber operations.

To track these developments, Flashpoint’s monthly AI Threat Report analyzes primary source communities across forums, marketplaces, and chat services. This month’s intelligence highlights a sharp increase in AI-enabled identity verification bypass activity, continued demand for malicious AI capabilities, and emerging examples of AI agent tooling being used in offensive operations.

Where AI Activity Is Concentrated

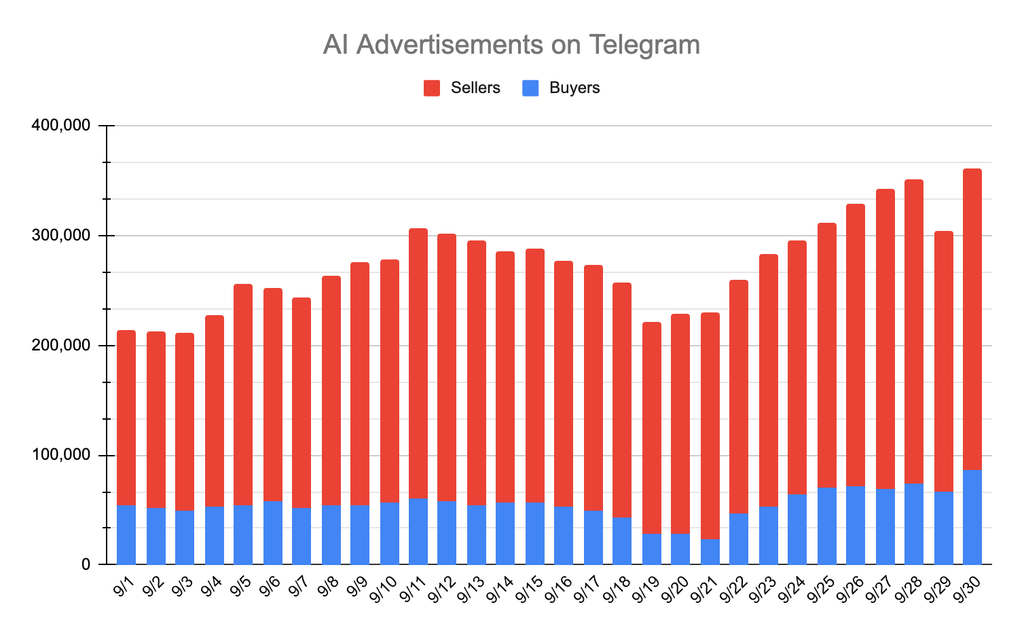
Telegram remained the dominant source of observed AI service advertisements in September, with 6,309,872 posts, up from 4,899,407 in August. That represents an approximately 29% month-over-month increase.

Activity across other platforms was substantially lower. Flashpoint identified 20,361 posts on GitHub Gist, followed by Pastebin (6,288), Signal (6,123), and Reddit (5,882). Smaller volumes were observed across 4chan, BlackHatWorld, Discord, Mastodon, and other sources.

Posts selling AI services (in red) and posts seeking to purchase AI services (in blue) on Telegram in September 2026. (Source: Flashpoint)

As with previous months, these figures do not represent unique advertisements or services. Threat actors frequently repeat or distribute the same messages across multiple channels and platforms to maximize exposure.

Telegram’s continued dominance underscores its importance as a distribution channel for illicit AI services. Other platforms provide additional avenues for sharing technical material, advertising capabilities, and discussing methods.

The distribution of activity also reinforces why post volume requires context. Repeated advertisements can inflate overall counts, making it important to examine the underlying services and techniques being promoted alongside changes in activity.

AI-Enabled Fraud and Identity Verification Bypass

Discussions of AI-enabled identity verification bypass continued to accelerate in September.

Flashpoint analysts observed 1,171,914 posts advertising or discussing Know Your Customer (KYC) bypass methods using AI technology, including deepfake technology. That compares with 751,644 posts in August, representing an approximately 56% month-over-month increase.

The increase is particularly noteworthy given the growth already observed in August, when KYC-related activity nearly doubled from July. Across the past two months, the number of observed posts has nearly tripled, rising from 394,567 in July to more than 1.17 million in September.

These discussions are concentrated in Telegram channels advertising methods designed to circumvent identity verification controls through generative AI, including deepfake technology.

For financial institutions and other organizations that rely on digital identity verification, this activity warrants close attention. AI-enabled impersonation can create additional challenges for onboarding, account recovery, and other processes that depend on verifying a user’s identity.

The sustained increase in underground discussion also provides security and fraud teams with an important signal about where threat actor interest is concentrated, even when repeated advertisements contribute to the overall volume.

Malicious LLM Usage and Prompt-Based Workflows

Malicious and unrestricted large language models (LLMs) remained part of the AI-related activity observed across Flashpoint Collections in September.

Threat actors continue to develop their own models or seek ways to bypass safeguards imposed by mainstream AI services. These capabilities can support phishing, social engineering, harmful code generation, and the creation of malicious or offensive content.

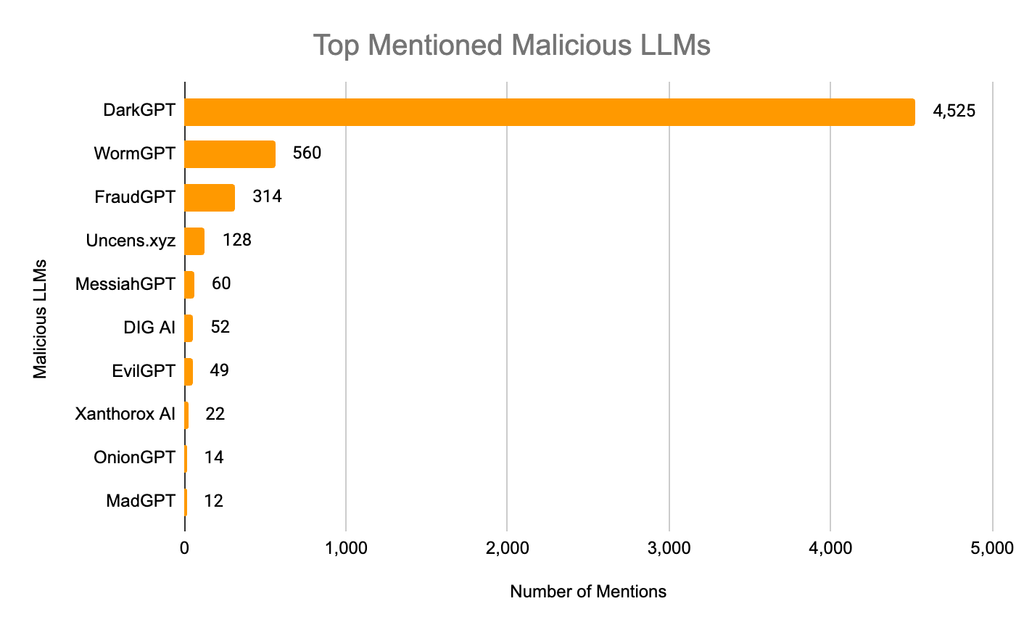
The top observed malicious LLMs mentioned within Flashpoint Collections in September 2026. (Source: Flashpoint)

The availability of malicious and unrestricted LLMs gives threat actors additional options for incorporating AI into existing workflows. Models designed or modified to circumvent safety restrictions can be used to generate content and technical material that mainstream services would ordinarily reject.

These tools also introduce challenges for security teams assessing how AI-enabled threats are evolving. Understanding which models are being discussed, how they are marketed, and the capabilities being sought by threat actors can provide insight into emerging areas of interest across illicit communities.

Notable AI-Related Activity Observed in September

Flashpoint identified several notable developments involving AI infrastructure and the growing use of AI in offensive cyber operations.

September reporting highlighted a Chinese-speaking operator reportedly using three open-source AI agent frameworks, including Strix and Cairn, to automate vulnerability discovery and exploitation across multiple targets, according to The Register, citing Gambit.

These developments highlight two areas of concern: the targeting of proprietary AI infrastructure and the potential for agent-based tools to accelerate offensive operations. For security teams, both reinforce the importance of protecting AI development environments and addressing exploitable weaknesses before attackers can capitalize on them.

What Security Teams Should Take Away

September’s intelligence points to continued growth in AI-related criminal activity, with particularly sharp increases in discussions surrounding identity verification bypass.

Flashpoint observed more than 8.8 million posts discussing AI and criminal activity, while KYC bypass discussions exceeded 1.17 million posts for the first time in the three-month period examined.

At the same time, reported activity involving AI agent frameworks illustrates how automation is extending into more complex offensive workflows. Threat actors are exploring ways to apply AI to vulnerability discovery and exploitation, alongside its established uses in fraud, impersonation, and social engineering.

For security teams, these developments reinforce the importance of maintaining visibility into the communities where new capabilities are discussed, advertised, and tested. Tracking changes in activity and understanding how tools are being applied can help organizations identify emerging risks and better prioritize their defenses.

To see how Flashpoint can help your team identify and respond to emerging threats, request a demo.

Frequently Asked Questions (FAQ)

What is the Flashpoint AI Threat Report?

The Flashpoint AI Threat Report is a monthly intelligence analysis tracking how threat actors use and discuss artificial intelligence across illicit communities. Built on Flashpoint’s primary source collection, the report provides visibility into underground forums, chat services, marketplaces, and other environments where AI-related criminal activity is discussed and advertised.

How are threat actors currently using AI in cybercrime?

Threat actors are using or exploring AI capabilities across a range of criminal activities, including identity verification bypass, phishing, social engineering, malicious code generation, and vulnerability discovery.

September reporting also highlighted the use of AI agent frameworks to automate elements of offensive cyber operations, including vulnerability discovery and exploitation.

How rapidly is illicit AI activity growing in cybercrime communities?

Flashpoint analysts identified 8,837,186 posts discussing AI and criminal activities in September 2026, compared with 7,461,908 in August. This represents an approximately 18% month-over-month increase.

Activity related to AI-enabled KYC bypass also grew substantially, reaching 1,171,914 posts in September, an increase of approximately 56% from August.

These figures measure observed posts, rather than unique threat actors, services, or confirmed attacks.

Which messaging platforms and forums host the most illicit AI chatter?

Telegram continues to account for the largest concentration of observed AI service advertisements. Flashpoint identified more than 6.3 million posts advertising AI services on Telegram in September.

Other sources included GitHub Gist, Pastebin, Signal, Reddit, 4chan, BlackHatWorld, Discord, and Mastodon.

What are malicious LLMs?

Malicious LLMs are AI models developed, modified, or marketed for purposes that mainstream AI services typically restrict. Threat actors may use these models to generate phishing content, assist with social engineering, create harmful code, or support other criminal activities.

Flashpoint continues to track discussion of these models across illicit communities to understand how their capabilities and use cases are evolving.

The post AI Threat Report: How Artificial Intelligence Is Used Across Illicit Communities appeared first on Flashpoint.

  •  

YouTube wants your face to fight deepfakes

If you’re worried about deepfake likenesses of yourself showing up online, you’re not alone; YouTube is worried for you. It wants to protect you by having you upload a selfie video and government ID to its site.

The idea is that the video giant will use its own AI to patrol the service for fake videos using your likeness. In exchange, you get the chance to have them taken down.

This isn’t available for everyone, though. It’s for celebs, those in vulnerable jobs, and now, most YouTube creators.

YouTube has been working on this concept, which it calls its “likeness detection” system, since it first floated the idea publicly in September 2024. That December, it launched a partnership with the Creative Artists Agency that saw it using the technology with sporting and entertainment figures.

In October last year, it expanded likeness detection to cover more creators, and then in March it expanded it again to cover politicians and journalists. And last month, it widened the net again, offering the service to Hollywood celebs. They can use it regardless of whether they have a YouTube account, it added.

Now, in its latest move, anyone 18 or older with a selfie and ID can sign up. At least in theory, as it hasn’t rolled out to everyone yet. It’s also for faces only; AI-generated voice clones are another problem entirely.

The privacy risk

Privacy advocates warned that YouTube’s likeness detection system could normalize handing biometric data to large tech platforms, even if YouTube says the data is only used to improve likeness detection models with creator permission.

On the help page for the likeness detection service, YouTube says creators can separately choose whether their face and voice templates are used to improve its likeness detection models.

“When you sign up for Likeness detection, you also have the option to allow YouTube to use your face and voice templates to develop and improve likeness detection models. This helps us build better, more accurate likeness detection technologies.”

Adding:

“You can opt out of YouTube’s use of this data for development and improvement of likeness models at any time.”

YouTube supports legislation intended to tackle deepfakes, such as the NO FAKES and TAKE IT DOWN acts. These are designed to help stop the misappropriation of someone’s image online. TAKE IT DOWN, which became law a year ago, focuses purely on “nonconsensual intimate imagery.” But that doesn’t cover other kinds of deepfakes, such as fake politicians or celebrity endorsements. Those are becoming increasingly common. NO FAKES, which hasn’t yet become law, is far broader in scope, assigning people federal rights over their own image.

So is it worth the trade?

Deepfakes, intimate and otherwise, are definitely a threat, especially for YouTubers who become popular. And the barrier to entry is lowering all the time. Google’s own DeepMind researchers found most generative AI misuse isn’t sophisticated; it’s mundane likeness manipulation by anyone with a browser.

So do you hand over your face and government ID for your protection, to a company whose broader data collection practices have faced years of scrutiny, and hope its policies don’t change? Or do you skip it and hope that the deepfake merchants don’t decide to target you?

Creators commenting on YouTube’s video revealing the service six months ago were less than impressed. One commenter said:

“I was 100% on board, up until the ID upload. That makes me very uncomfortable.”

Echoing several others who complained that it’s difficult to get takedown requests actioned, another added:

“If YouTube actually acted upon these kinds of reports, then I’d be more in favour of this.”

Whether you decide to sign up for the service or not, just be sure to do it with your eyes open.


Someone’s watching your accounts. Make sure it’s us.


  •  

AI is distorting the Holocaust (Lock and Code S07E10)

This week on the Lock and Code podcast…

In May of last year, a warning about AI came from somewhere unexpected: The Auschwitz-Birkenau State Museum.

Posting publicly on social media, the museum warned about a Facebook account using generative AI to create fake images of people who died in the Holocaust. Despite using AI to generate fake images, the people in said images were sometimes real. They had real names, birthplaces, and stories of deportation that the Auschwitz-Birkenau State Museum itself had shared before. They had real faces captured in real surviving photographs, which were likely abused to generate the false images. 

In other words, someone, or some team of people online, was deepfaking the Holocaust.

As the Auschwitz museum wrote online:

“These are not real photos of the victims. They are digital inventions, often stylized or sanitized, that risk turning remembrance into fictionalized performance. The history of Auschwitz is a well-documented story. Altering its visual record with AI imagery introduces distortion, no matter the intent.”

Months later, the public found out what that intent was: money.

A BBC investigation found an international network of Facebook accounts posting AI-generated images to earn money from those images’ potential virality. It’s a problem sometimes referred to as “AI slop” but it comes with a major incentive. When accounts that make these kinds of images are invited to Facebook’s content monetization program, they can make $1,000 a month for posting anything that gets clicks.

And on Facebook, the BBC found, that means several accounts posting AI-generated images about the Holocaust. As the BBC reported:

“AI spammers have posted fake images purporting to be from inside [Auschwitz], such as a prisoner playing a violin or lovers meeting at the boundaries of fences—attracting tens of thousands of likes and shares.”

The economics of lying are concrete today. People can use AI to make fake images that make people feel good about terrible things or feel scared about untrue things, and they can make money until shut down by the Big Tech platforms themselves, which, in this case, only happened because of the BBC’s investigation. In fact, it’s that type of inaction from social media platforms that compelled the German government and multiple Holocaust memorial institutions to send an open letter earlier this year that asked for better controls and restrictions against this type of content.

As the signatories warned in their letter, the economic appeal for these accounts to distort history is too high a risk to allow. You can read the full letter here.

Today, on the Lock and Code podcast with host David Ruiz, we speak with Clara Mansfeld, a historian working on digital communications at one of the institutions signed onto the open letter—the Foundation of Hamburg Memorials and Learning Centers Commemorating the Victims of Nazi Crimes. In their conversation, Mansfeld discusses digital access to history, the manipulation of factual records through AI-generated imagery, and the threat that society faces when it becomes harder to evaluate the truth.

“What happens when the first thought we have with every historical image is, ‘Is that even real or is that AI?’ I don’t think we have really grasped what that means for us as a society.”

Tune in today to listen to the full conversation.

Show notes and credits:

Intro Music: “Spellbound” by Kevin MacLeod (incompetech.com)
Licensed under Creative Commons: By Attribution 4.0 License
http://creativecommons.org/licenses/by/4.0/
Outro Music: “Good God” by Wowa (unminus.com)


Listen up—Malwarebytes doesn’t just talk cybersecurity, we provide it.

Protect yourself from online attacks that threaten your identity, your files, your system, and your financial well-being with our exclusive offer for Malwarebytes Premium Security for Lock and Code listeners.

  •  

Meta’s confusing new approach to chat privacy

Recent news had us wondering whether Meta actually knows what it wants.

On one platform, Meta is promoting AI chats that it says even it cannot read. On another, it has removed one of the few features that genuinely prevented Meta from accessing private conversations.

“Meta removed support for end-to-end encrypted chats from Instagram as of May 8, 2026.”

“Meta adds fully private AI chats to WhatsApp.”

At the moment, Meta is heavily promoting a new Incognito Chat mode for its Meta AI assistant in WhatsApp, built on top of a system it calls Private Processing. According to WhatsApp’s own announcement, Incognito Chat is:

 “Truly private — no one can read your conversation, not even us.”

When you start an Incognito chat with Meta AI, you get a temporary conversation where messages aren’t saved and disappear by default, which Meta pitches as “a space to think and explore ideas without anyone watching.”

BBC News and others report that these AI chats are text‑only for now, run in a sandboxed environment, and are separate from your regular end‑to‑end encrypted (E2EE) messaging with other people on WhatsApp.

Meta is also preparing “Side Chat,” which will let you invoke Meta AI inside other WhatsApp chats, again using this Private Processing infrastructure to claim AI assistance without breaking the underlying encryption.

On paper, that’s an impressive technical and marketing story: powerful AI, wrapped in layers of privacy‑preserving infrastructure, added to an app that already has a strong reputation for end‑to‑end encryption by default.

Meanwhile, on Instagram…

Now contrast that with what’s happening on Instagram. On 8 May 2026, Meta removed optional end‑to‑end encryption for Instagram Direct Messages (DMs) entirely. Users who had previously turned the feature on were shown notices that “end‑to‑end encrypted messaging on Instagram is no longer supported as of 8 May 2026,” and were urged to download backups of their encrypted conversations before the cutoff.

End‑to‑end encryption ensures that only the sender and recipient can read their conversations. Instagram offered this as an opt‑in feature since late 2023, but it was buried several taps deep inside individual conversation settings and never turned on by default. Meta’s explanation for shutting it down is that “very few people” used encrypted DMs and that maintaining a separate encrypted system added complexity. Critics have pointed out the circular logic. The company hid the feature, did not advertise it, and is now using low adoption as the reason to kill it rather than, say, making it easier to find or turning it on by default.

What all this means

From a user’s perspective, the result is confusing: one Meta product introduces stronger privacy than ever for AI chats, while another removes the one feature that truly stopped Meta from reading your conversations.

The key point to remember here is that “incognito” and “private” are marketing words, while end‑to‑end encryption is a technical guarantee.

For security‑conscious users, this split personality means you can no longer treat all Meta chats the same. WhatsApp remains end‑to‑end encrypted for person‑to‑person messages and adds optional privacy features around its AI, while Instagram DMs should now be assumed readable by Meta and potentially accessible to law enforcement, advertisers, or attackers who gain access to Meta’s systems.


To boldly browse, away from prying eyes. 


Why make AI chats private?

We’ve seen that AI chats have suddenly turned up in search results without users’ knowledge. So there definitely is a positive side to this new feature.

We also know there have been lawsuits against chatbot providers in cases where the outcome of an AI conversation led to very undesirable results. But how would you be able to provide evidence when messages auto-disappear?

How to proceed

Meta’s recent moves show that strong privacy features can be added where they support a strategic narrative and removed where they conflict with business or regulatory priorities. Users can’t control those decisions, but they can respond by choosing where they hold their most sensitive conversations and by assuming that if a chat isn’t end‑to‑end encrypted by default, it is ultimately readable by someone other than the people in it.

So, what’s a safe way to move forward?

  • Treat Instagram DMs as postcard-level privacy. Now that E2EE is gone, assume Meta can read and scan your messages and that content could be accessed under legal orders or in a breach. Do not send passwords, recovery codes, banking details, or compromising photos over Instagram.
  • When someone asks you to move a conversation to Signal, WhatsApp, or another E2EE messenger, ask them why. It does make sense when you’re sharing financial details, personal images, health information, or anything you would not want a platform provider to read. But sometimes scammers prefer encrypted platforms too, because they’re harder to monitor.
  • Do not confuse “incognito” AI chats with full encryption. WhatsApp’s Incognito mode for Meta AI may be a privacy improvement over standard cloud AI chats, but it is still a conversation with a large language model owned by the same company that runs the platform. Share only what you’re comfortable entrusting to Meta.
  • Regularly review your privacy and security settings. Check which devices are logged in, enable two‑factor authentication, and verify which of your chat apps are actually end‑to‑end encrypted by default.

Scammers know more about you than you think. 

Malwarebytes Mobile Security protects you from phishing, scam texts, malicious sites, and more. With real-time AI-powered Scam Guard built right in. 

Download for iOS → Download for Android → 

  •  

How Dangerous Is Anthropic’s Mythos AI?

Last month, Anthropic made a remarkable announcement about its new model, Claude Mythos Preview: it was so good at finding security vulnerabilities in software that the company would not release it to the general public. Instead, it would only be available to a select group of companies to scan and fix their own software.

The announcement requires context—but it contained an essential truth.

While Anthropic’s model is really good at finding software vulnerabilities, so are other models. The UK’s AI Security Institute found that OpenAI’s GPT-5.5, already generally available, is comparable in capability. The company Aisle reproduced Anthropic’s published results with smaller, cheaper models.

At the same time, Anthropic’s refusal to publicly release its new model makes a virtue out of necessity. Mythos is very expensive to run, and the company doesn’t appear to have the resources for a general release. What better way to juice the company’s valuation than to hint at capabilities but not prove them, and then have others parrot their claims?

Nonetheless, the truth is scary. Modern generative AI systems—not just Anthropic’s, but OpenAI’s and other, open-source models—are getting really good at finding and exploiting vulnerabilities in software. And that has important ramifications for cybersecurity: on both the offense and the defense.

Attackers will use these capabilities to find, and automatically hack, vulnerabilities in systems of all kinds. They will be able to break into critical systems around the world, sometimes to plant ransomware and make money, sometimes to steal data for espionage purposes, and sometimes to control systems in times of hostility. This will make the world a much more dangerous, and more volatile, place.

But at the same time, defenders will use these same capabilities to find, and then patch, many of those same systems. For example, Mozilla used Mythos to find 271 vulnerabilities in Firefox. Those vulnerabilities have been fixed, and will never again be available to attackers. In the future, AIs automatically finding and fixing vulnerabilities in all software will be a normal part of the development process, which will result in much more secure software.

Of course, it’s not that simple. We should expect a deluge of both attackers using newly found vulnerabilities to break into systems, and at the same time much more frequent software updates for every app and device we use. But lots of systems aren’t patchable, and many systems that are don’t get patched, meaning that many vulnerabilities will stick around. And it does seem that finding and exploiting is easier than finding and fixing. All of this points to a more dangerous short-term future. Organizations will need to adapt their security to this new reality.

But it’s the long term that we need to focus on. Mythos isn’t unique, but it’s more capable than many models that have come before. And it’s less capable than models that will come after. AIs are much better at writing software than they were just six months ago. There’s every reason to believe that they will continue to get better, which means that they will get better at writing more secure software. The endgame gives AI-enhanced defenders advantages over AI-enhanced attackers.

Even more interesting are the broader implications. The same searching, pattern-matching and reasoning capabilities that make these models so good at analyzing software almost certainly apply to similar systems. The tax code isn’t computer code, but it’s a series of algorithms with inputs and outputs. It has vulnerabilities; we call them tax loopholes. It has exploits; we call them tax avoidance strategies. And it has black hat hackers: attorneys and accountants.

Just as these models are finding hundreds of vulnerabilities in complex software systems, we should expect them to be equally effective at finding many new and undiscovered tax loopholes. I am confident that the major investment banks are working on this right now, in secret. They’ve fed AI the tax code of the US, or the UK, or maybe every industrialized country, and tasked the system with looking for money-saving strategies. How many tax loopholes will those AIs find? Ten? One hundred? One thousand? The Double Dutch Irish Sandwich is a tax loophole that involves multiple different tax jurisdictions. Can AIs find loopholes even more complex? We have no idea.

Sure, the AIs will come up with a bunch of tricks that won’t work, but that’s where those attorneys and accountants come in—to verify, and then justify, the loopholes. And then to market them to their wealthy clients.

As goes the tax code, so goes any other complex system of rules and strategies. These models could be tasked with finding loopholes in environmental rules, or food and safety rules—anywhere there are complex regulatory systems and powerful people who want to evade those rules.

The results will be much worse than insecure computers. Tax loopholes result in less revenue collected by governments, and regulatory loopholes allow the powerful to skirt the rules, both of which have all sorts of social ramifications. And while software vendors can patch their systems in days, it generally takes years for a country to amend its tax code. And that process is political, with lobbyists pressuring legislators not to patch. Just look at the carried interest loophole, a US tax dodge that has been exploited for decades. Various administrations have tried to close the vulnerability, but legislators just can’t seem to resist lobbyists long enough to patch it.

AI technologies are poised to remake much of society. Just as the industrial revolution gave humans the ability to consume calories outside of their bodies at scale, the AI revolution will give humans the ability to perform cognitive tasks outside of their bodies at scale. Our systems aren’t designed for that; they’re designed for more human paces of cognition. We’re seeing it right now in the deluge of software vulnerabilities that these models are finding and exploiting. And we will soon see it in a deluge of vulnerabilities in all sorts of other systems of rules. Adapting to this new reality will be hard, but we don’t have any choice.

This essay originally appeared in The Guardian.

  •  

Deepfake sextortion forces schools to remove student photos from websites

Schools love a good photo, whether it’s from a trip to a castle, a science prize ceremony, or sports day shot from three angles. For two decades, celebratory images like these have gone straight onto school websites, captioned with a name and a grade. But those days are gone, because it’s the internet in 2026 and we can’t have nice things.

As first reported by the Guardian, experts are now urging schools to take those pictures down. According to the UK’s National Crime Agency, the Internet Watch Foundation, and an advisory body called the Early Warning Working Group (EWWG), blackmailers have been scraping ordinary school photos, feeding them through AI deepfake tools to manufacture child sexual abuse material (CSAM), and demanding payment to keep the images offline.

One school, 150 images

Late last year, cybercriminals contacted an unnamed UK secondary school with that demand. The IWF classified 150 of the resulting images as CSAM under UK law and generated digital fingerprints for each image so major platforms could block reuploads.

The IWF isn’t naming the school or the police force, and it doesn’t believe this was an isolated case. The EWWG says it’s “only a matter of time” before more schools face similar demands.

UK safeguarding minister Jess Phillips called it a “deeply worrying emerging threat.” In February 2025, the UK became the first country to ban AI tools designed specifically to generate CSAM.

How we got here

This threat didn’t appear overnight, and it isn’t limited to the UK. It’s an evolution of a long-time threat: sextortion, when someone uses intimate images to blackmail you. Traditionally, sextortion relied on real intimate images that were stolen or shared, but deepfake AI has changed everything.

The FBI’s Internet Crime Complaint Center (IC3) logged more than 16,000 sextortion complaints in the first half of 2021, with losses exceeding $8 million. By June 2023, the bureau warned the playbook had shifted: attackers were using ordinary social media photos to create fake explicit images and extort minors.

UK children’s counseling helpline Childline has seen similar shifts as deepfake tools become more accessible. It already logs many sextortion cases each year, many from kids who were manipulated into sharing intimate images of themselves. Now, the organization is getting calls from children who are being sent deepfake CSAM images of themselves without any prior contact.

One 15-year-old girl, for example, was sent a “really convincing” fake nude built from her Instagram photos.

By November 2025, IWF reports of AI-generated CSAM had more than doubled year over year, rising from 199 to 426. Girls accounted for 94% of the victims. Reported cases included children ranging from newborns to two-year-olds, according to the organization.

The ecosystem around these tools is industrial. In April 2025, a researcher found an exposed AWS S3 bucket belonging to South Korean “nudify” app GenNomis containing 93,485 AI-generated images alongside the prompts that produced them.

What the schools are being told

The EWWG’s advice is to replace close-up, identifiable photos with images taken from a distance, blurred images, or photos shot from behind. It also advises schools to remove full names from captions, audit existing images, and ask parents to re-sign consent forms.

In fact, it advises schools to rethink whether they need to publish children’s photos online at all.

Some schools have already acted. According to the Guardian, Loughborough Schools Foundation, a group of three private schools sharing a website, removed recognizable pupil images entirely last year.

The UK Information Commissioner’s Office (ICO) says that it “would still generally expect you to offer an opt-out to parents” when publishing an identifiable photo of a child, but says this isn’t legally the same as consent, which has a higher bar.

Things get murkier in the US, where states often have their own student privacy statutes. Broadly, though, under the Family Educational Rights and Privacy Act (FERPA), schools typically include identifiable photos of students under the category of directory information. This category also covers name, address, telephone listing, date and place of birth, participation in officially recognized activities and sports, and dates of attendance.

Under FERPA, schools can publish this type of information unless the child’s guardian specifically opts out. They have to notify a guardian when they want to publish it, but that process may not apply indefinitely after a student leaves the school.

That means student photos and information can remain online long after families assume they have disappeared.

What happens next

Back in the UK, Childline’s Report Remove service allows children to flag explicit images or videos of themselves that have been posted online. The service took 394 blackmail reports from under-18s last year, up by one-third compared to 2024.

Meanwhile, the UK government is amending the Crime and Policing Bill, forcing platforms to take flagged intimate images down within 48 hours or face fines of 10% of global revenue.

We anticipate a race between regulators and AI-enabled cybercriminals. Right now, attackers still have to manually find the photos themselves. The concern is that this process could soon become automated, allowing criminals to scrape names and photos from school websites and social media platforms at scale.

For parents, the simplest protection may be limiting how many identifiable pictures of your children are available online. That includes being vigilant not just with your child’s school, but their sports clubs, extracurricular activities, and social media accounts.


Someone’s watching your accounts. Make sure it’s us.


  •  

Introducing the updated AWS User Guide to Governance, Risk, and Compliance for Responsible AI Adoption

The financial services industry (FSI) is using AI to transform how financial institutions serve their customers. AI solutions can help proactively manage portfolios, automatically refinance mortgages when rates decrease, and negotiate insurance premiums for customers.

However, this adoption brings new governance, risk, and compliance (GRC) considerations that organizations need to address. To help FSI customers navigate these challenges, AWS is excited to announce an updated AWS User Guide to Governance, Risk, and Compliance for Responsible AI Adoption within Financial Services Industries.

This comprehensive guide provides FSI customers practical considerations for responsible AI adoption across key dimensions including governance, risk management, compliance, data management, model management and AI agent management. It includes detailed AWS service capabilities that customers can use to address these considerations, such as Amazon Bedrock AgentCore, Amazon Bedrock Guardrails, Amazon Bedrock Agents, Amazon SageMaker Autopilot, and Amazon SageMaker Model Monitor.

The guide is available at the AWS Whitepaper portal and is complementary to other AWS resources such as the AWS Responsible Use of AI Guide, AWS Cloud Adoption Framework for AI, AWS Well-Architected Framework – Responsible AI Lens, AWS Well-Architected Framework – Generative AI Lens, and AWS Well-Architected Framework – Machine Learning Lens.

As the regulatory environment and leading practices continue to evolve, we will provide further updates on the AWS Security Blog and AWS Compliance Center. You can also reach out to your AWS account team for help finding the resources you need.

Resources

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Krish De

Krish De

Krish is a Principal FSI Governance, Risk, and Compliance (GRC) specialist. He works with AWS customers, their regulators, and AWS teams to safely accelerate customers’ AI and cloud adoption by providing prescriptive guidance on GRC. Krish has over 20 years of experience working in governance, risk, and technology across the financial services industry in Australia, New Zealand, and the United States.

Brenda Fong

Brenda Fong

Brenda is a senior FSI risk and compliance specialist. She works with AWS customers in banking, insurance, and capital markets within the ASEAN region to help them meet regulatory, governance, risk, and compliance expectations. Brenda has over 20 years of experience working in governance, risk, and technology across the financial services industry within Asia Pacific.

Stephen Martin

Steve is the Head of Financial Services Compliance and Security for EMEA and APAC. Steve Joined AWS after working for over 20 years in financial service in senior leadership roles with responsibility across ASIA, the Middle East, and Europe. At AWS, he supports customers as they use the scale, security, and agility of AWS to transform the industry.

Kelvin Leung

Kelvin Leung

Kelvin is the AWS FSI Security and Compliance Lead based in Hong Kong. He has 20 years of experience specializing in AI Governance, risk management and regulatory compliance within the financial services sector. Prior to joining AWS, Kelvin worked for a financial regulator where he was responsible for technology risk policy-making and IT regulatory examinations, with a particular focus on AI risk assessment and control frameworks.

  •  
❌