Your workloads reach most destinations by domain name, but a firewall can only act on what it sees in the traffic. For HTTP and HTTPS, AWS Network Firewall domain rules match the name that the client puts in the request, and the client chooses that name. The connections for protocols such as SSH and SSH File Transfer Protocol (SFTP) don’t carry the domain name. The client uses the name only for the DNS lookup and then connects straight to the IP address that DNS returned. As a result, Network Firewall rules for these protocols have used IP addresses, which change over time. For web and non-web traffic alike, Network Firewall had no view of the answers that your DNS resolver returned, because that shared visibility between DNS and the firewall didn’t exist.
On October 21, 2026, we launched Route 53 Resolved IP Validation for AWS Network Firewall, at no additional charge. Amazon Route 53 Resolver now shares the IP addresses that it returns for each domain name with Network Firewall, and Network Firewall checks each new outbound connection against them. With this launch, you can now filter non-web traffic by domain name, and you can prevent Server Name Indication (SNI) manipulation on TLS traffic without needing to enable TLS inspection.
In this post, we explain how the feature works, show how to turn it on in alert mode, and walk through two common use cases. They’re examples; the same check applies to any outbound traffic that you control by domain name.
How it works
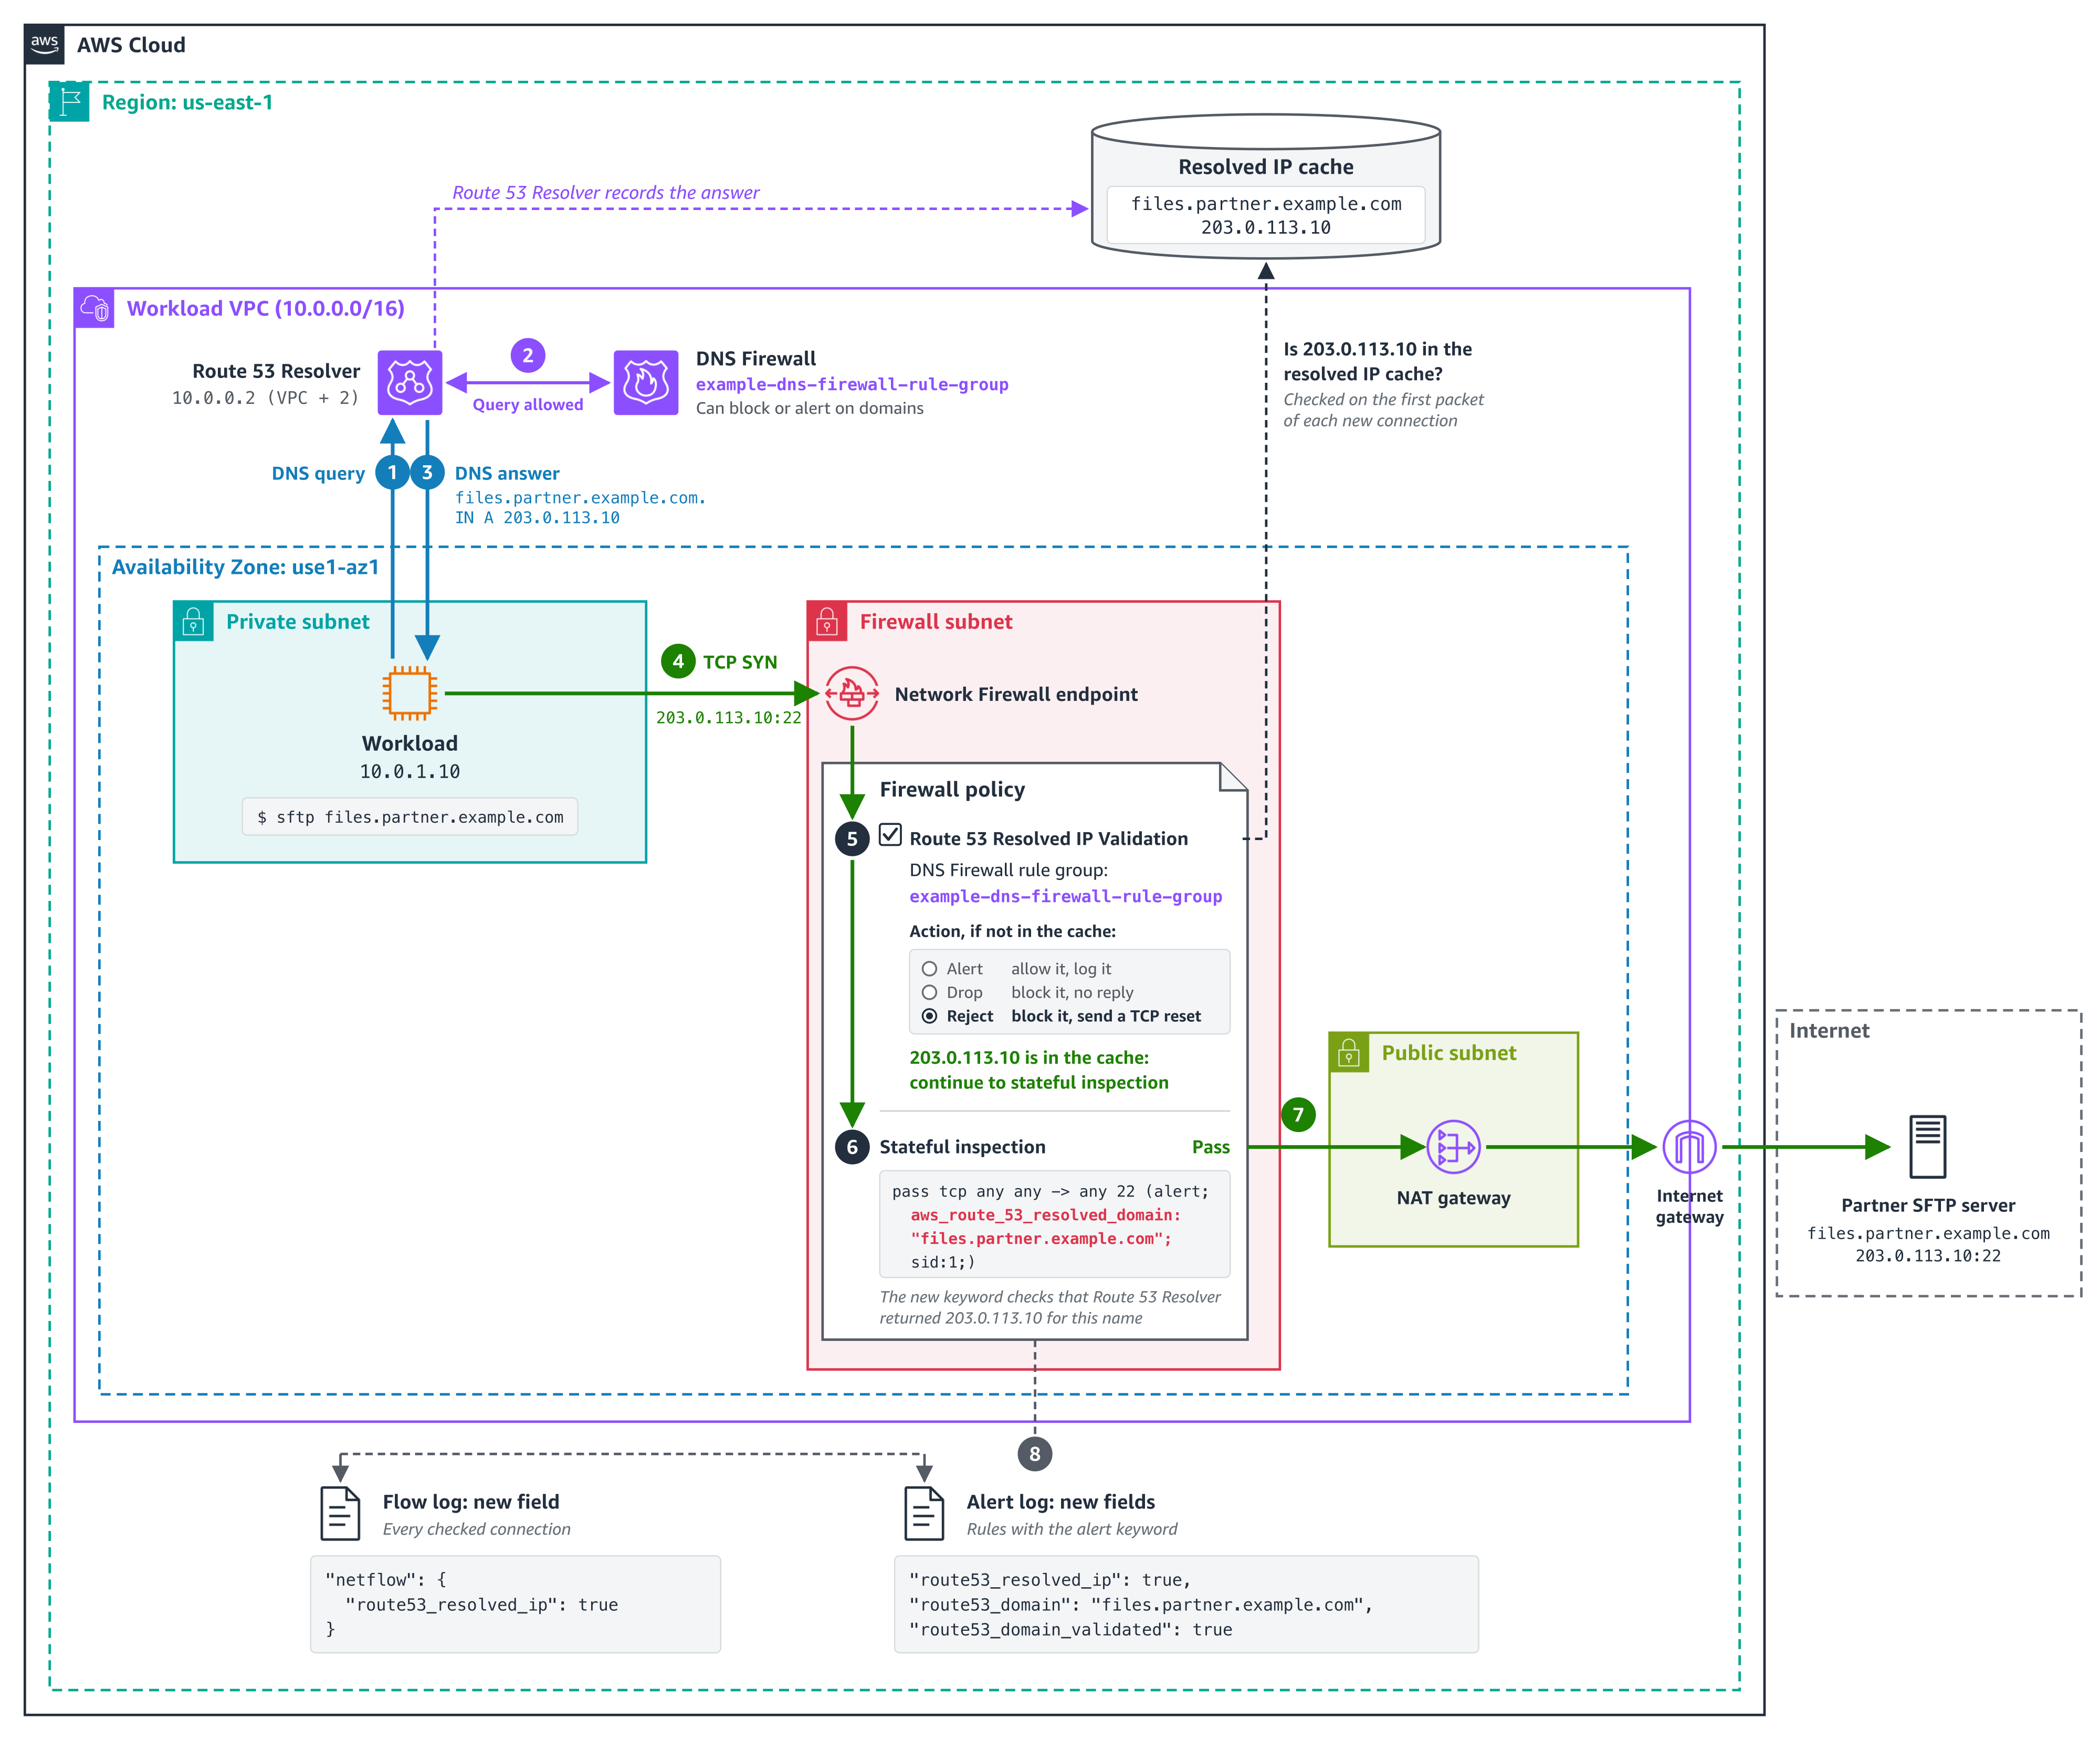
Amazon Route 53 Resolver answers DNS queries from resources in your virtual private cloud (VPC) configured to use it, and it’s available by default in every VPC. With this feature, Route 53 Resolver keeps the IP addresses that it returns for each domain name in a resolved IP cache. When a new outbound connection starts, Network Firewall checks the destination address against that cache.
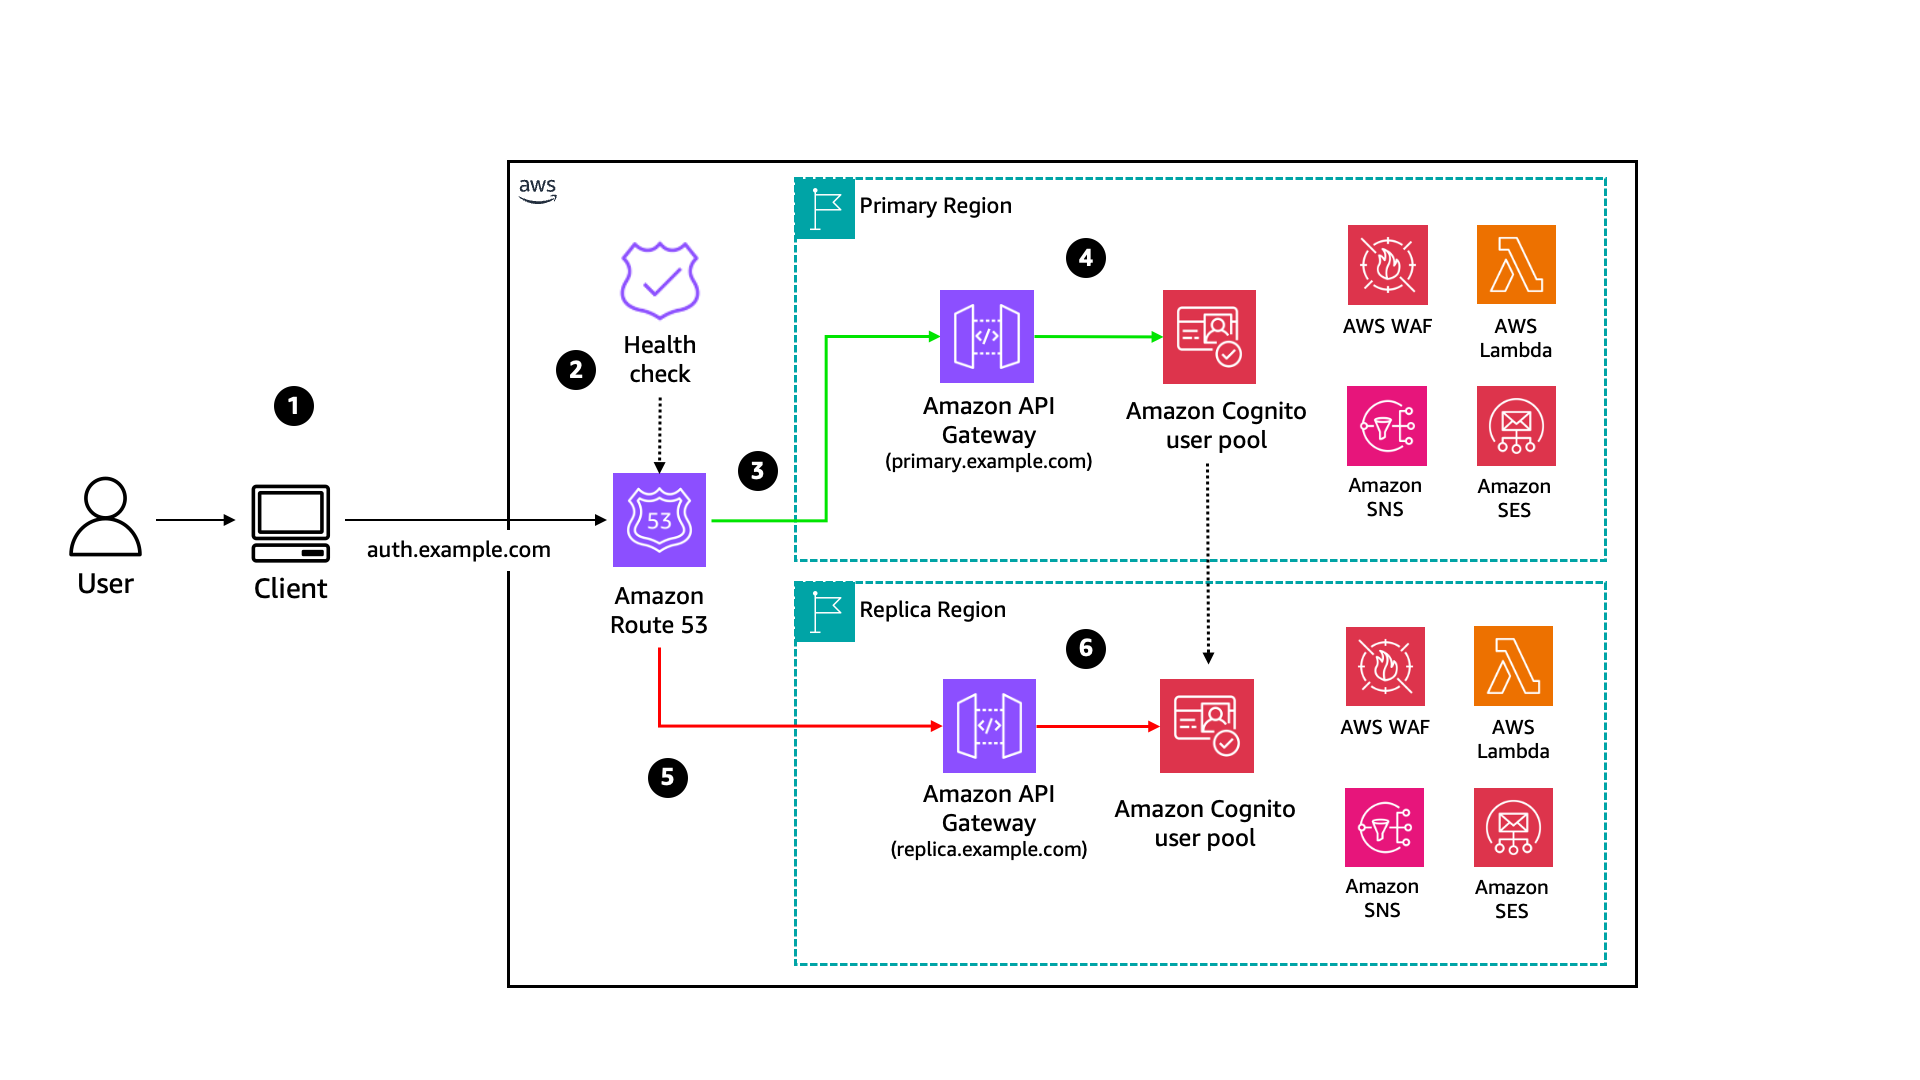
The workload asks Route 53 Resolver at 10.0.0.2 for files.partner.example.com.
DNS Firewall checks the query first. Domain rules can block or alert on it; an empty rule group lets it through.
Route 53 Resolver answers 203.0.113.10 and records the answer in the resolved IP cache.
The SFTP connection to 203.0.113.10 on port 22 reaches the Network Firewall endpoint.
The policy checks the first packet. The address is in the cache, so the connection continues.
The stateful rule passes it, because Route 53 Resolver returned the address for files.partner.example.com.
The connection leaves through the NAT gateway and internet gateway.
The flow log and alert log record the new fields.
The feature has three parts:
An Amazon Route 53 Resolver DNS Firewall rule group – It defines the scope. The answers that Route 53 Resolver returns in every VPC associated with this rule group go into the resolved IP cache. The rule group can be empty. Add rules to it and the same rule group also filters the DNS queries themselves, for example, by blocking lookups of known threat domains. Together, DNS Firewall checks the lookup and Network Firewall checks the connection that follows.
The Network Firewall policy setting – On the first packet of each new connection, before your stateful rules run, Network Firewall checks whether Route 53 Resolver returned the destination address for a domain name. If it did, the connection continues to your stateful rules. If it didn’t, Network Firewall applies the action you chose: Alert, Drop, or Reject.
Resolved-domain rules – In your stateful rule groups, these rules match a connection by the domain name that its destination address was resolved for, so they work with every protocol. Use the name that your clients look up.
The following diagram shows this architecture.
Figure 1. How Network Firewall checks the SFTP connection from use case 1 against the answers that Route 53 Resolver returned
The policy setting checks every connection, not only web traffic. A connection to an IP address that no client looked up through Route 53 Resolver, such as a hardcoded address, fails the check. If any of your workloads connect straight to IP addresses, add those addresses to Bypass destination validation IP ranges before you enforce. A stateful pass rule doesn’t exempt them because the policy check runs before your rules. The check is per address: when any client in an associated VPC looks up a name, its addresses pass the check for every client in scope in the same Availability Zone. For details, see Resolved IP validation in AWS Network Firewall in the AWS Network Firewall Developer Guide.
Prerequisites
To follow along, you need:
DNS through Amazon Route 53 Resolver – Network Firewall can check only answers that Route 53 Resolver returned. Queries that reach Route 53 Resolver through Resolver endpoints or Resolver forwarding rules count.
A Route 53 Resolver DNS Firewall rule group associated with the VPCs whose DNS answers Network Firewall should check connections against.
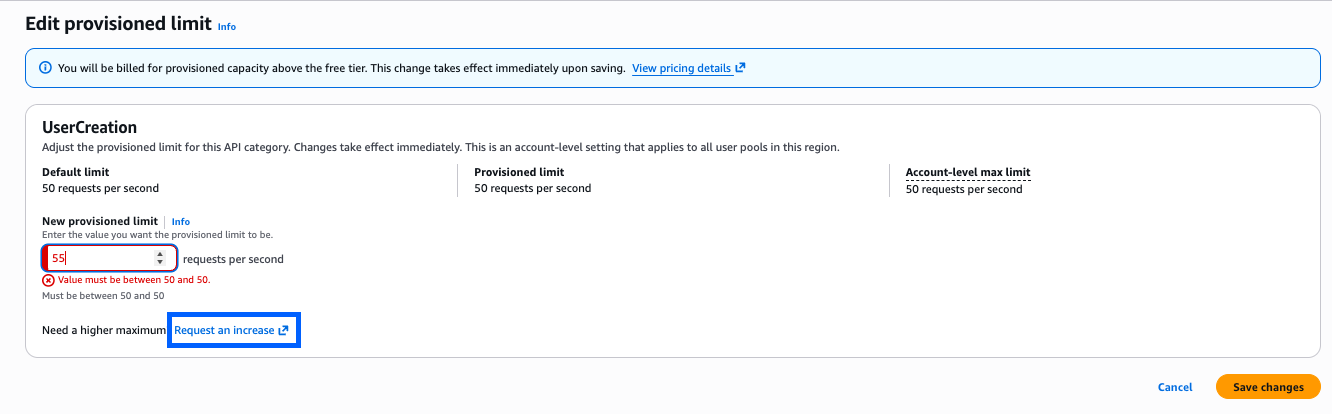
The policy setting turned on before you add resolved-domain rules – Rules that use domain filtering (the aws_route_53_resolved_domain keyword) need Route 53 Resolved IP Validation turned on in the same firewall policy. Turn the setting on first, in alert mode, then add the rules.
A supported deployment model – The feature works with distributed deployments, including multiple firewall endpoints, where clients reach a firewall endpoint in their own Availability Zone, and with centralized deployments where the firewall is attached natively to AWS Transit Gateway. If routing sends a client to a firewall endpoint in another Availability Zone, its connections fail the check. To move a centralized deployment to a natively attached firewall, see Why and how to migrate to a Transit Gateway attached AWS Network Firewall.
How to turn it on in alert mode
Start in alert mode because clients cache DNS answers. Network Firewall recognizes only the answers that Route 53 Resolver returns after the DNS Firewall rule group is associated with the VPC and selected in the policy. A client that still uses an answer it cached earlier fails the check until it looks up the name again, usually when its cached record expires. Alert mode lets you see this without blocking anything. Allow about 24 hours in alert mode for clients to refresh their caches.
Create a DNS Firewall rule group (it can be empty) and associate it with the VPCs whose DNS answers Network Firewall should check connections against. For the steps, see Creating a rule group and rules.
Or, to use a DNS Firewall rule group that you already have, make sure it’s associated with those VPCs and only those. An answer returned in any associated VPC is valid for every client that the firewall checks. Which clients are checked is set by source IP ranges in step 6.
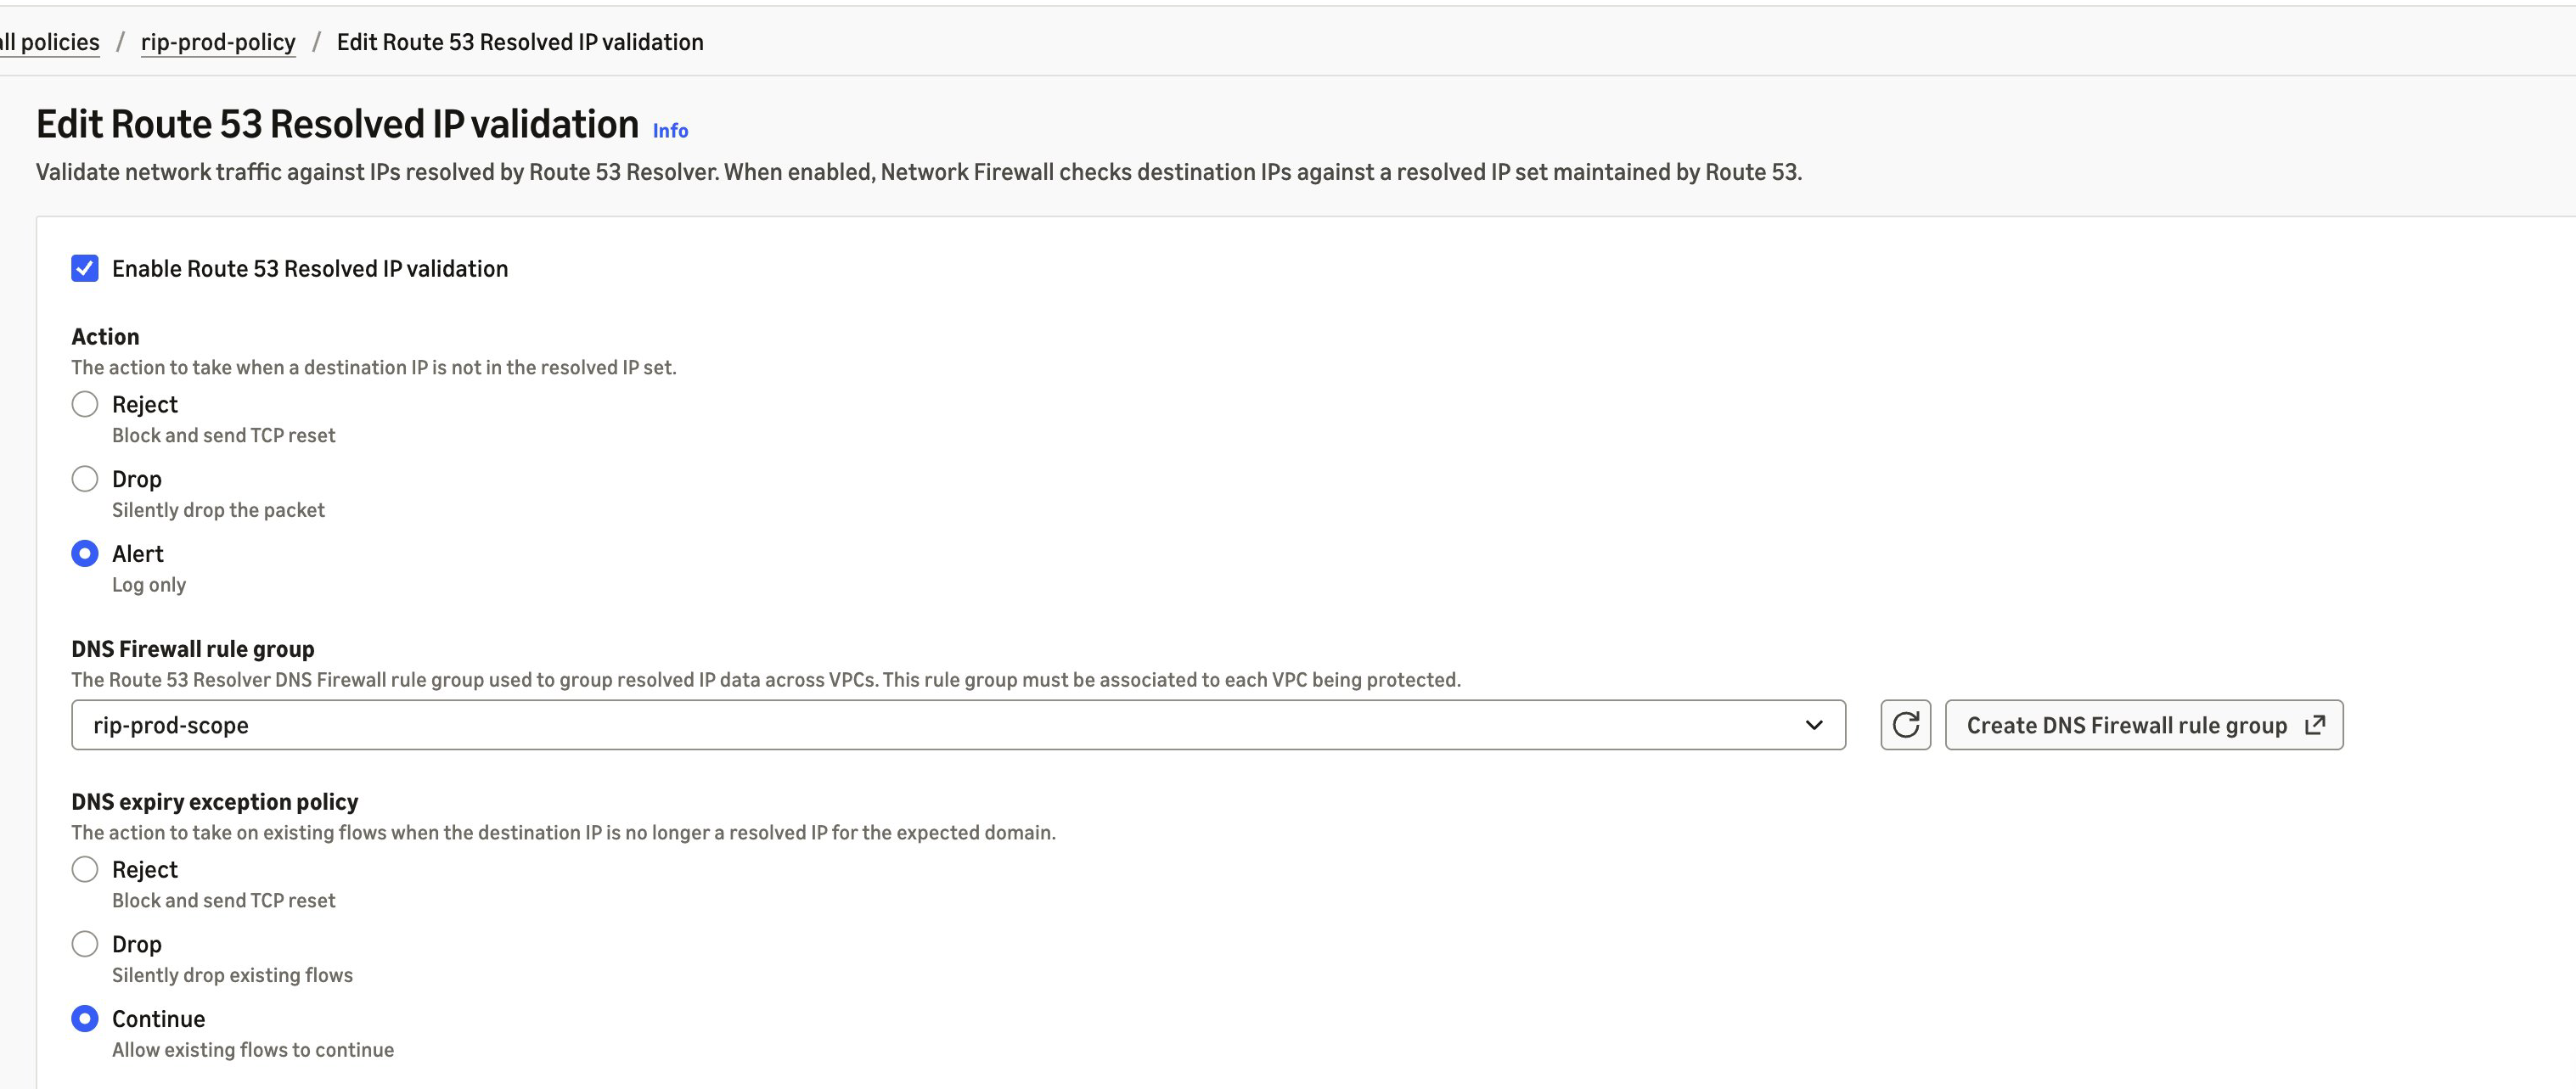
In the Amazon Virtual Private Cloud (Amazon VPC) console, under Network Firewall, choose Firewall policies, then choose the policy that your firewall uses. On the Traffic inspection tab, in the Route 53 Resolved IP validation section, choose Edit and select Enable Route 53 Resolved IP validation.
For Action, choose Alert. For DNS Firewall rule group, choose the rule group from step 1 or 2.
For DNS expiry exception policy, choose what happens to a connection that’s already open when its entry expires from the resolved IP cache. Continue keeps it running, Drop stops it silently, and Reject stops it with a TCP reset. We recommend Continue so that long-running sessions, such as file transfers, aren’t cut off midway. However, choose the option that fits your security requirements.
For source IP ranges, list the clients to check. If you don’t set it, Network Firewall checks clients in the firewall’s VPC and in any additional VPCs attached to the firewall. If your clients are in other VPCs, such as spoke VPCs that send traffic to a firewall attached to a transit gateway, enter their CIDR ranges; otherwise, Network Firewall doesn’t check their connections. Add destinations that you allow by IP address to Bypass destination validation IP ranges. Choose Save.
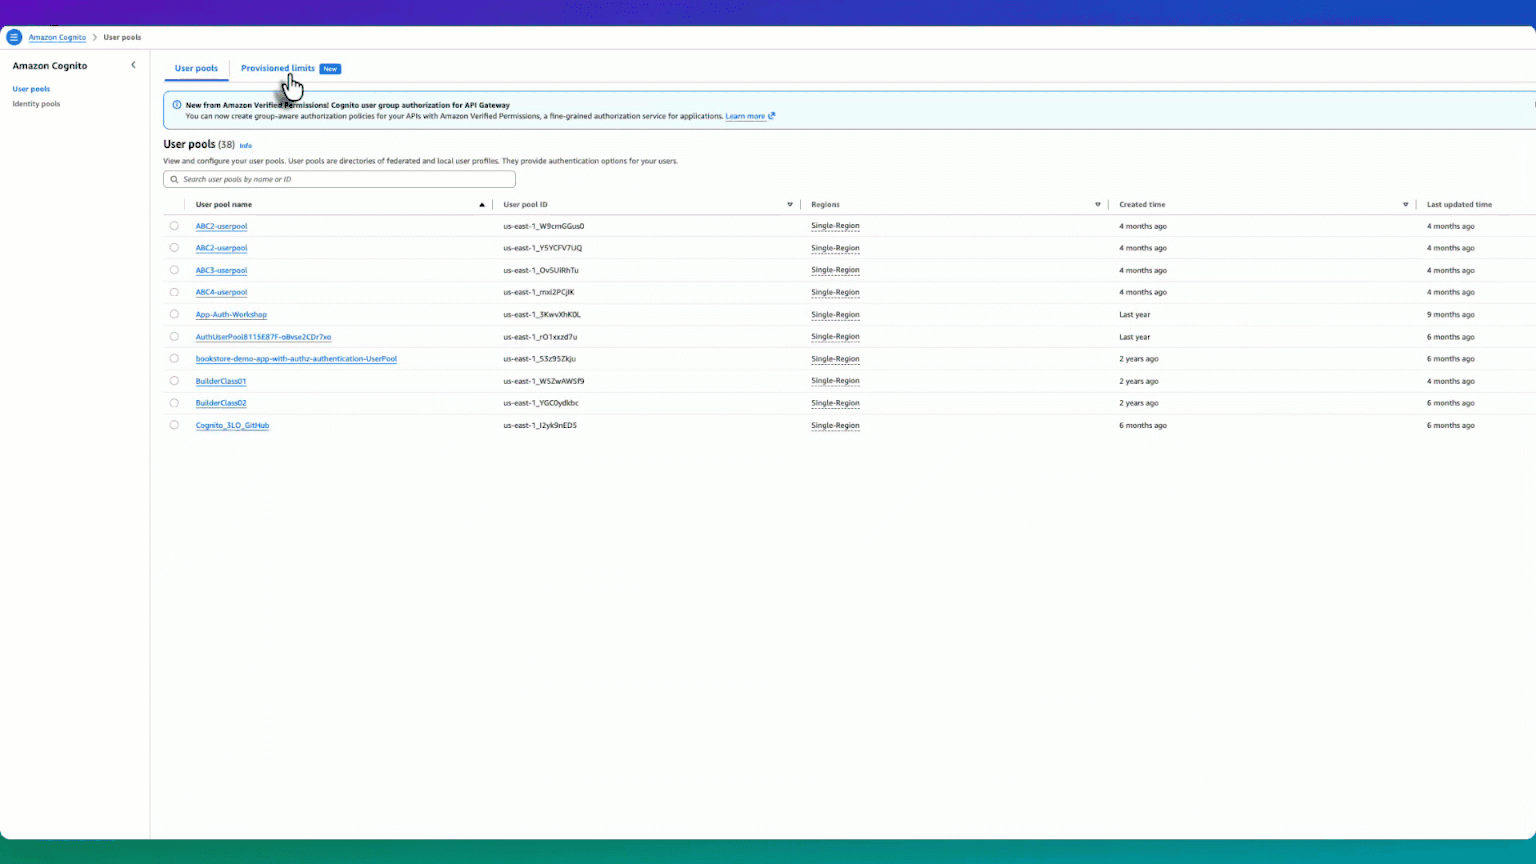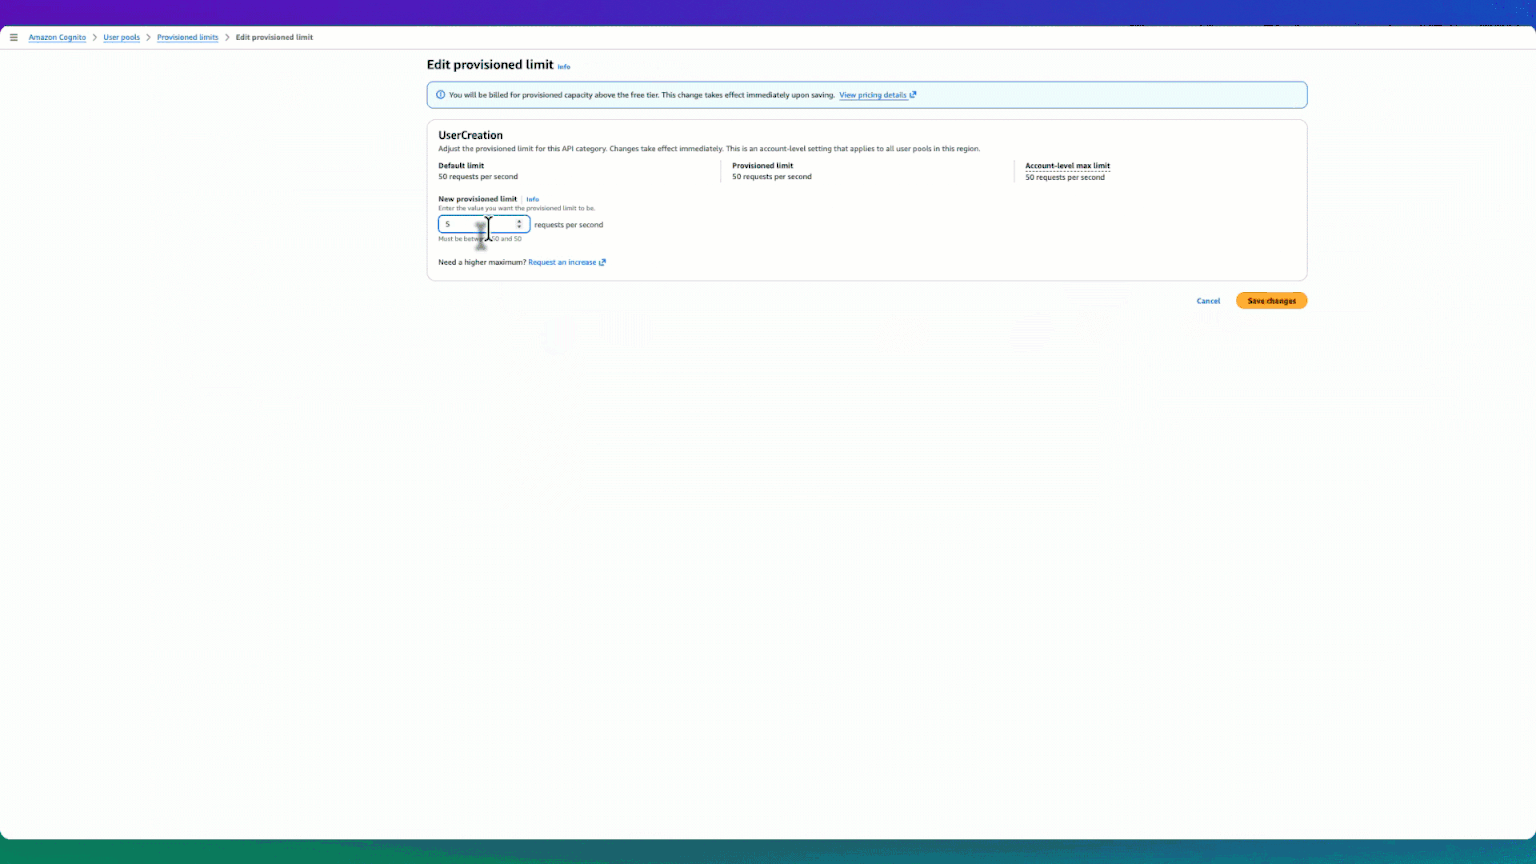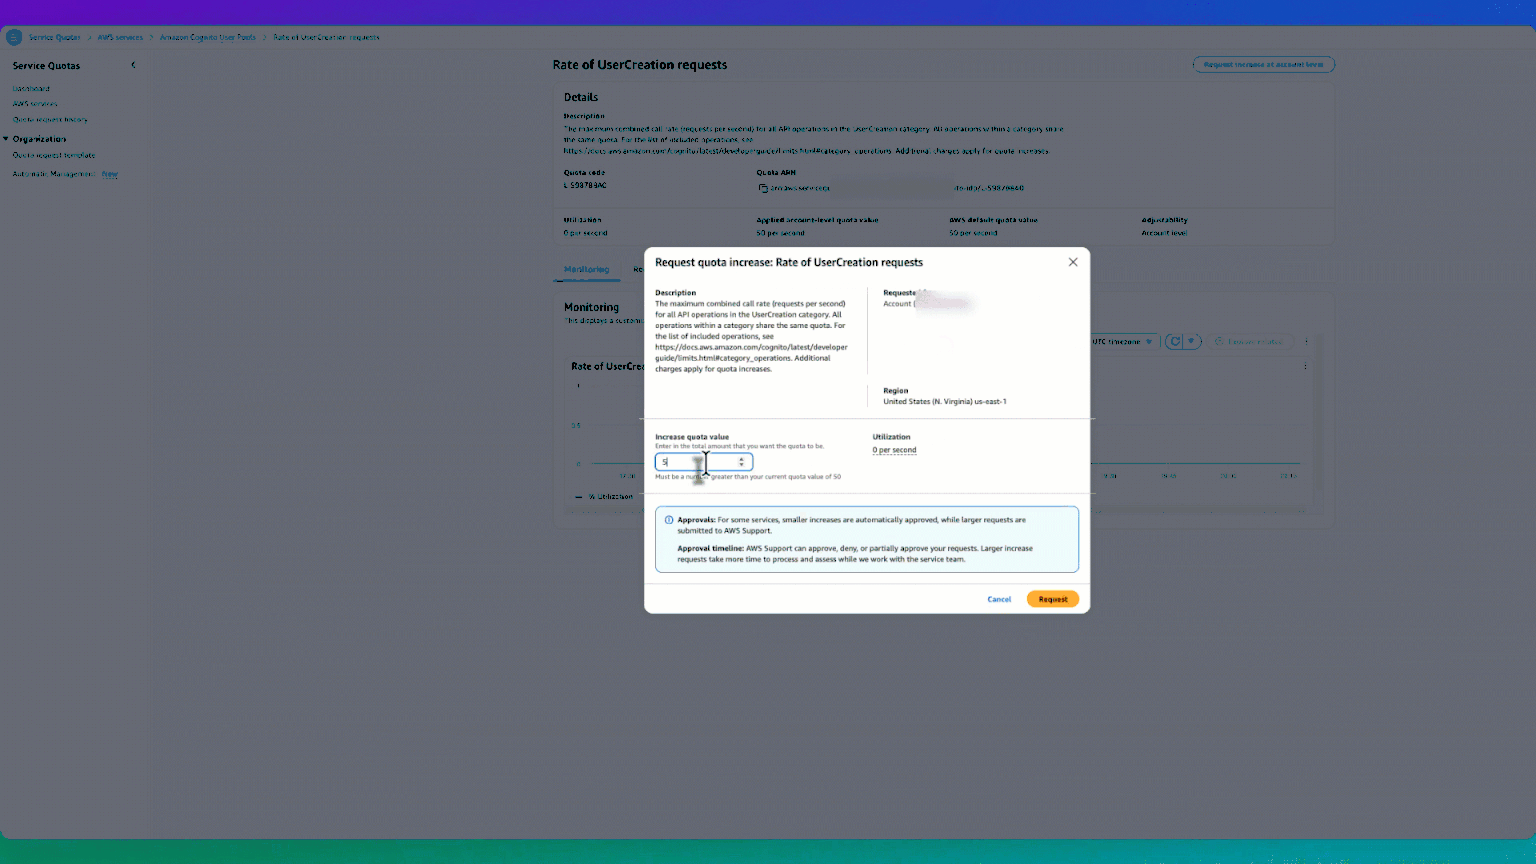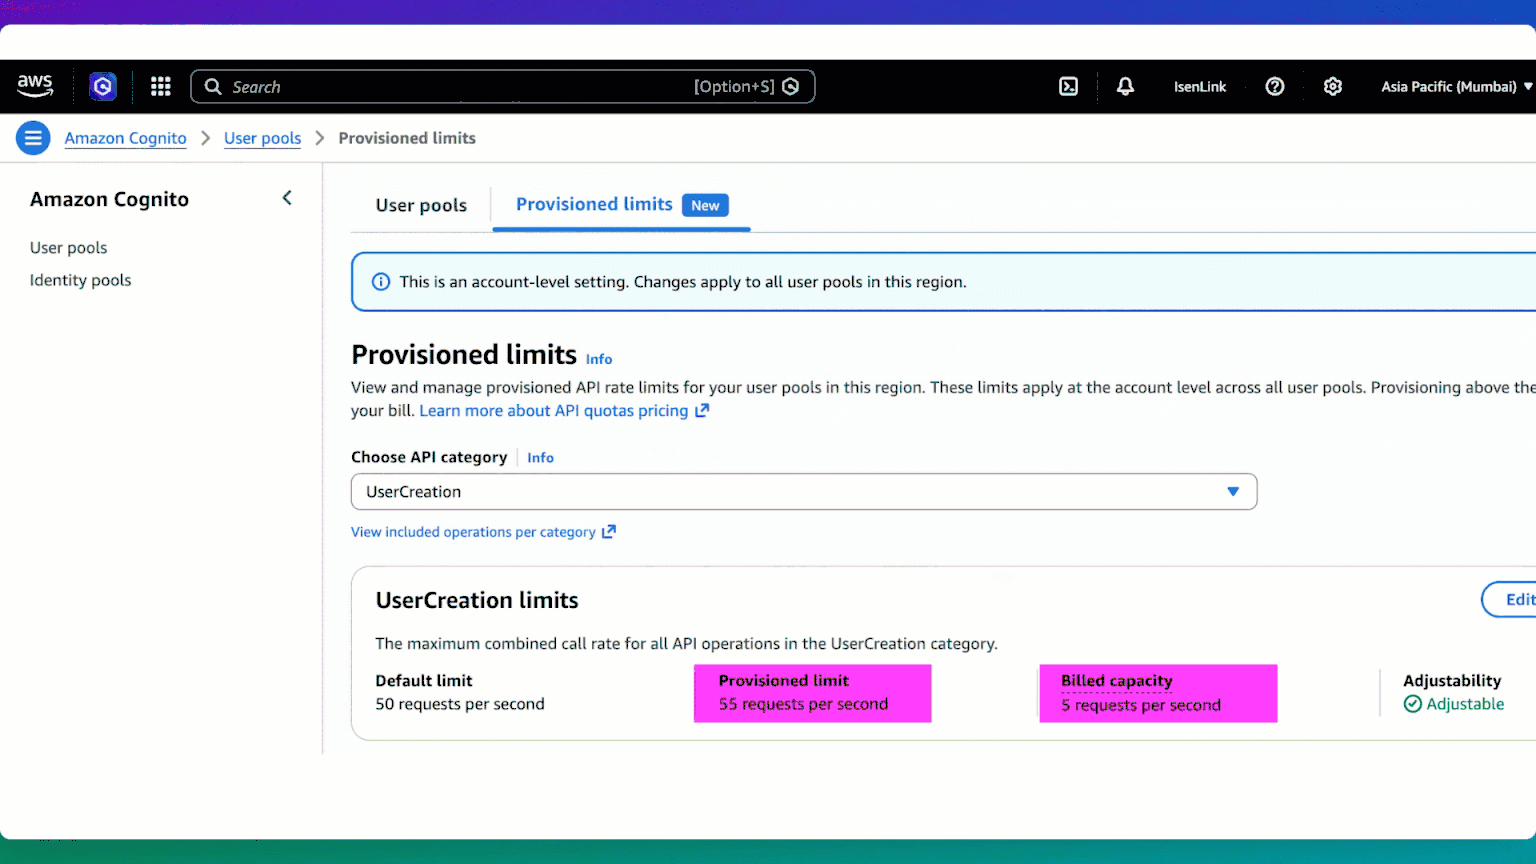
The following screenshot illustrates these steps.
Figure 2. Route 53 Resolved IP Validation turned on in alert mode
In alert mode, Network Firewall doesn’t block a connection that fails the check, and it doesn’t write an alert of its own. It records the result in your flow logs, in the route53_resolved_ip field of each connection. A value of true means Route 53 Resolver returned the destination address for a domain name. A value of false means it didn’t, so enforcement would block the connection. The same field also appears in alert log records that a rule or the policy’s default action writes for the connection. Pass rules don’t write one unless they have the alert; keyword. The DnsUnresolvedFlows metric in Amazon CloudWatch counts the connections that fail the check, and DnsAzUnavailableFlows counts connections from an Availability Zone that doesn’t support the feature. The following alert log record (trimmed, with example values) was written by a default action that alerts, for a connection to an address that Route 53 Resolver returned:
In alert mode, this record is for a TLS connection that presented an allowed domain name but went to an address that Route 53 Resolver didn’t return for it, blocked by the policy’s default action in use case 2:
Before you switch Action to Drop or Reject, check that connections that fail the check are ones you expect and that destinations you allow by IP address are in the bypass ranges. Reject sends a TCP reset, so a blocked TCP client fails right away instead of waiting for a timeout. After you enforce, blocked connections appear in your flow logs with route53_resolved_ip as false, not in your alert logs. For the metrics and log fields to watch, see Monitoring and troubleshooting resolved IP validation.
Use case 1: Filter non-web traffic by domain name
Before this launch, Network Firewall rules for protocols that carry no domain name, such as SFTP, used IP addresses. Now, you can allow them by domain name. In this example, a workload sends files over SFTP to a partner at files.partner.example.com on TCP port 22, and the partner can change the addresses behind that name at any time. The same approach works for SSH, MySQL, and other non-web protocols. You create it as a standard stateful rule. Follow these steps:
Under Network Firewall, choose Network Firewall rule groups, then choose Create rule group. Choose Stateful rule group and Standard stateful rule, and choose the rule evaluation order that your policy uses.
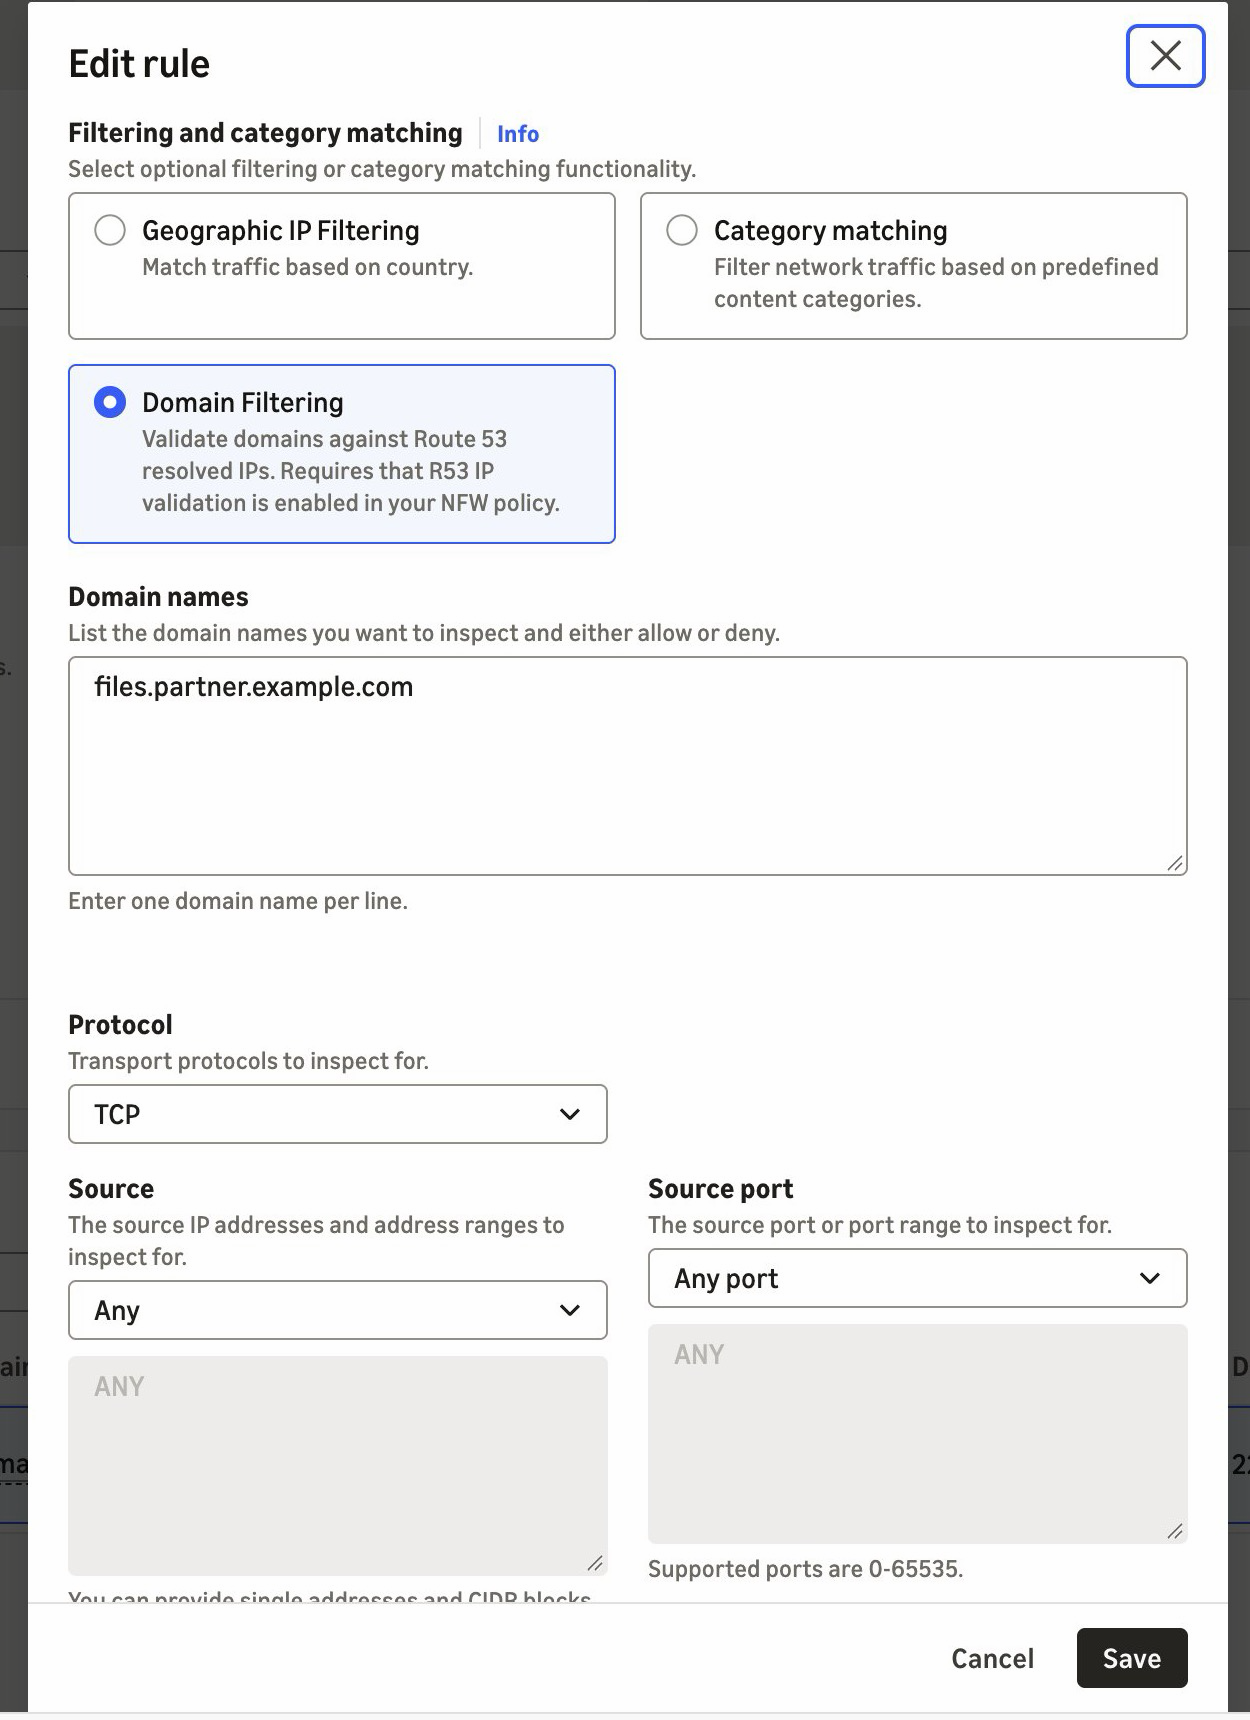
Choose Add rule. For Protocol, choose TCP. For Destination port, enter 22. Under Domain filtering, enter files.partner.example.com. For Action, choose Pass.
Create the rule group, then add it to your firewall policy.
Figure 3. A pass rule for SFTP on TCP port 22, scoped to the partner’s domain name
If you manage rules as code, the equivalent Suricata rule is shown in the following code. It adds the alert; keyword so that the firewall logs allowed connections. The console rule doesn’t add it.
pass tcp any any -> any 22 (alert; msg:"Allow TCP/22 to files.partner.example.com"; aws_route_53_resolved_domain:"files.partner.example.com"; sid:1;)
When the partner moves its server to a new address, the next DNS answer adds it to the resolved IP cache. There’s no IP list to maintain. The cache keeps earlier answers for longer than their DNS time to live (TTL), so the old address can still pass for a while.
Use case 2: Prevent SNI spoofing without TLS inspection
With SNI spoofing, a client presents an allowed domain name in its TLS request while it connects to a different server. Preventing that has required TLS inspection, which decrypts the traffic. Route 53 Resolved IP Validation prevents it without TLS inspection. In this example, a workload calls a partner API at api.partner.example.com over HTTPS. TLS traffic on port 443 must reach only the addresses that Route 53 Resolver returned for that name. You create a pass rule in a standard stateful rule group, as in use case 1, and the firewall policy’s default action drops everything that no rule passes. Follow these steps:
Under Network Firewall, choose Network Firewall rule groups, and then choose Create rule group. Choose Stateful rule group and Standard stateful rule, then choose Strict order.
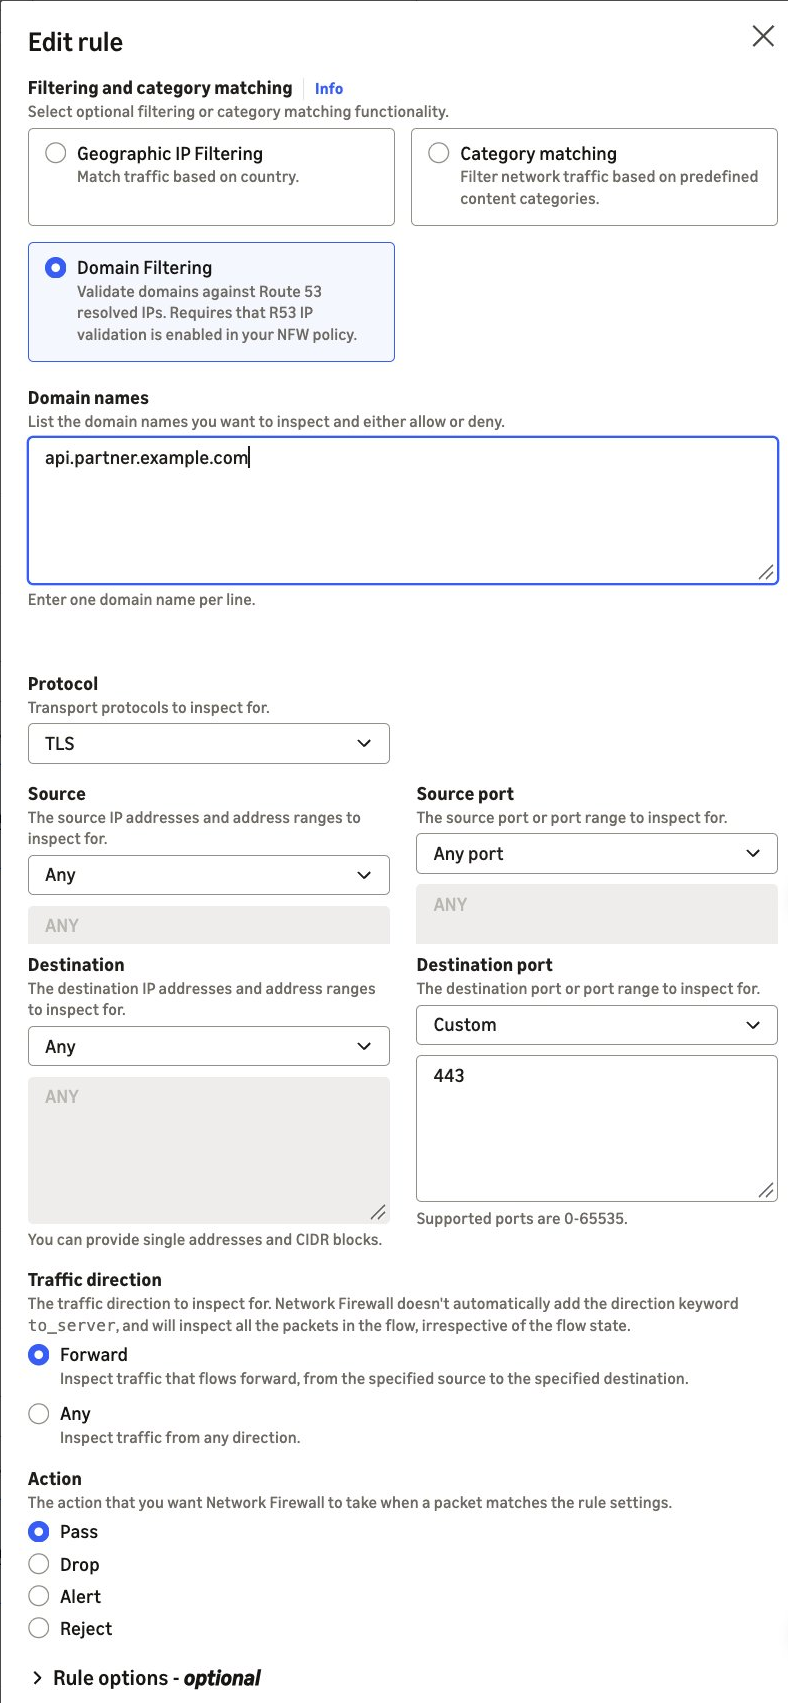
Choose Add rule. For Protocol, choose TLS. For Destination port, enter 443. Under Domain filtering, enter api.partner.example.com. For Action, choose Pass.
Create the rule group, then add it to your firewall policy.
In the firewall policy, use strict rule order. For the stateful default actions, choose Application drop established(server-directed only) and Application alert established (server-directed only). The alert action logs what the drop action blocks. For why we recommend these default actions, see Firewall policy configuration in the AWS Security Services Best Practices guide.
Figure 4. A pass rule for TLS on port 443, scoped to the partner’s domain name
If you manage rules as code, the equivalent Suricata rule is:
pass tls any any -> any 443 (aws_route_53_resolved_domain:"api.partner.example.com"; sid:2;)
The pass rule matches the destination address, not the name in the TLS request. TLS traffic on port 443 passes only when Route 53 Resolver returned the destination address for api.partner.example.com. If the partner’s addresses also serve other domain names, such as behind a content delivery network (CDN), those names pass too. To also require the partner’s name in the TLS request, add an exact SNI match to the same rule: tls.sni; content:"api.partner.example.com"; startswith; endswith; nocase;.
Without startswith and endswith, the content match accepts any SNI that contains the name.
A connection that presents the partner’s name but goes to another address doesn’t match the pass rule. If Route 53 Resolver never returned that address, the policy setting’s enforcement action blocks the connection before your rules run. In alert mode, the policy setting lets the connection through to your rules instead, and the stateful default action drops it because the pass rule doesn’t match. Its alert log record shows route53_resolved_ip as false, as in the second example previously. If Route 53 Resolver returned the address for a different domain name, the connection passes the policy check. The stateful default action then drops it because the pass rule doesn’t match, and that record shows route53_resolved_ip as true.
Best practices
We recommend that you follow these best practices:
Keep DNS on Route 53 Resolver – Block outbound UDP and TCP port 53 DNS to other resolvers, including DNS over HTTPS (DoH) and DNS over TLS (DoT), on Network Firewall, so that clients don’t bypass the check. Route 53 Resolved IP Validation alone doesn’t do this. If any client looks up a public resolver’s name, such as dns.google, that resolver’s addresses pass the check.
Keep DNS Firewall rules in those VPCs – Route 53 Resolved IP Validation checks the connections that follow a DNS lookup, not the DNS queries themselves. DNS Firewall blocks lookups of known threat domains with AWS managed domain lists, and its advanced rule groups detect data leaving through DNS queries, such as DNS tunneling.
Start small – Add domain filtering to a few rules at a time, then add more when the results look clean. For domain allow list patterns, see Allow rules and domain allowlisting.
Turn on flow and alert logging and detailed monitoring – Connections that fail the resolved IP check show in your flow logs (route53_resolved_ip: false) and in the DnsUnresolvedFlows metric, not in your alert logs. Pass rules without the alert; keyword don’t write an alert log record.
Pricing and availability
Route 53 Resolved IP Validation is available today in all commercial AWS Regions (Regions other than the AWS GovCloud (US) Regions and the China Regions) where AWS Network Firewall and Amazon Route 53 Resolver DNS Firewall are available, at no additional charge. For the list of Regions, see AWS Capabilities by Region. A DNS Firewall rule group with no rules doesn’t incur DNS Firewall charges. Standard DNS Firewall pricing applies after you add rules. See AWS Network Firewall pricing and Amazon Route 53 pricing.
Conclusion
In this post, we showed you how Route 53 Resolved IP Validation works and how to turn it on in alert mode. Network Firewall now checks each connection’s destination against the IP addresses that Amazon Route 53 Resolver returned for the DNS query. Filtering SFTP, SSH, database, and other non-web traffic by domain name and preventing SNI spoofing without TLS inspection are two common examples of what that makes possible. To get started, turn the feature on in alert mode and review the results before you enforce. For the full walkthrough, see Getting started with resolved IP validation.
October 23, 2026-2: The PHP project disclosed CVE-2026-115560, a separate remote code execution issue that the October 21 releases don’t fix. It affects only applications with an uncommon configuration that keeps session upload progress enabled. The PHP2Shell_BODY rule in the PHP application managed rule group, version 2.4 and later, already blocks POST requests that carry a PHP session ID and the session upload progress field (PHP_SESSION_UPLOAD_PROGRESS). This helps mitigate CVE-2026-115560 until PHP releases a fix, and no rule group update is needed. PHP recommends setting session.upload_progress.enabled=0 until its next regular bugfix release. If you applied this setting for CVE-2026-109619, keep it in place.
October 23, 2026: We updated this post for version 2.4 of the AWS WAF PHP application managed rule group, which adds the PHP2Shell_BODY_Extended rule for CVE-2026-109618, and AWS made it the default version. AWS is continuously updating the AWS WAF PHP managed rule group to add protection for both CVE-2026-109618 and CVE-2026-109619. If you use the default version, you will be automatically protected without any action on your part. If you have pinned a specific version, update to the latest version to receive this protection. For the latest version and details on the rules added, see the AWS Managed Rules changelog and subscribe to the AWS Managed Rules SNS topic (both linked below). Patching is the only complete fix, and you should upgrade PHP as your first priority.
October 22, 2026: We updated this post to add the AWS WAF PHP application managed rule group. Version 2.3 of the rule group adds the PHP2Shell_BODY rule for CVE-2026-109619, and AWS made it the default version.
On October 21, 2026, the PHP project released emergency fixes for two critical remote code execution (RCE) vulnerabilities in the PHP core runtime, tracked as CVE-2026-109618 and CVE-2026-109619 and collectively named PHP2Shell. Both are rated 9.2 (Critical) under CVSS v4.0, and both allow an unauthenticated attacker to run code on a vulnerable server. The fixed releases are PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35.
Patching is the only complete fix, and you should upgrade PHP as your first priority. But patching a fleet takes time: you need to inventory where PHP runs, schedule maintenance windows and test applications against the new builds. This post shows you how to use AWS Web Application Firewall (AWS WAF) to help reduce your exposure during that window. The AWS WAF PHP application managed rule group includes rules for both vulnerabilities: PHP2Shell_BODY for CVE-2026-109619 and PHP2Shell_BODY_Extended for CVE-2026-109618. AWS continues to release new versions of this rule group as detection improves. Track them in the AWS Managed Rules changelog, or subscribe to the AWS Managed Rules SNS topic to get notified. If your protection pack (web ACL) uses this rule group at the default version, these rules are already active. This post shows you how to confirm that and how to add the rule group if you don’t use it yet. It also covers the custom rules that still add defense in depth. It also explains where AWS WAF protection ends, so you don’t develop a false sense of safety. For how Amazon threat intelligence detected PHP2Shell exploitation before public disclosure, see Amazon Threat Intelligence identifies PHP2Shell exploitation prior to public disclosure in MadPot. For AWS service status and patching guidance, see AWS Security Bulletin 2026-143-AWS.
IMPORTANT: Patching is the only complete fix, and you should upgrade PHP as your first priority.
The vulnerabilities in brief
Both PHP2Shell vulnerabilities are unauthenticated RCE issues rooted in how PHP handles multipart/form-data request processing (the request format browsers use for file uploads) before your application code runs, which is why the AWS WAF rules in this post focus on multipart traffic, request body size, and the session upload progress field. At a high level, CVE-2026-109618 corrupts memory when PHP runs out of memory mid-request, and CVE-2026-109619 lets one request leave behind stale data that a later request on the same worker process reuses. For the root-cause analysis, affected versions, and PHP’s own guidance, see the official PHP advisories and release announcement:
AWS WAF is a defense-in-depth control in this situation, not a replacement for the PHP upgrade. The PHP advisories are explicit: updating to a patched release is the only complete mitigation. One of the two vulnerabilities is largely outside the reach of any web application firewall, as explained later. Treat the managed rules and the custom rules in this post as mitigating controls that help reduce exposure while you patch, then remove them or keep them as supporting controls after you’ve patched.
AWS WAF inspects HTTP requests at the edge. It doesn’t parse the internal structure of a multipart body, and it has no visibility into PHP worker memory or server-side configuration. The following table maps each attack element to whether AWS WAF can help mitigate it.
Attack element
AWS WAF coverage
Request patterns that match CVE-2026-109618
Yes. The PHP2Shell_BODY_Extended rule in the PHP application managed rule group, version 2.4 or later.
Request patterns that match CVE-2026-109619
Yes. The PHP2Shell_BODY rule in the PHP application managed rule group, version 2.3 or later.
Session upload progress field in a multipart POST (PHP_SESSION_UPLOAD_PROGRESS, the form field that turns on PHP’s upload-tracking feature)
Yes. The PHP2Shell_BODY rule (version 2.4 or later) and the custom rule in this post block POST requests that carry a PHP session ID and that field. This also helps mitigate CVE-2026-115560.
Multipart upload path (multipart/form-data, the request type used for file uploads and the entry point for both vulnerabilities)
Yes, if the application has no legitimate multipart uploads. Block multipart/form-data.
Out-of-memory condition from an oversized body
Partial. PHP2Shell_BODY_Extended inspects the request body up to the body inspection limit. Cap the request body size with the Core rule set SizeRestrictions_BODY rule or a custom rule. Neither catches header amplification (many small part headers that cost far more memory to represent than their size on the wire) that stays under the cap.
Repeated attempts against the same worker (the reused PHP process that handles many requests)
Partial. A rate-based rule reduces the volume an exploit needs, but it doesn’t stop a single successful request.
fatal_error_backtraces producer (a PHP 8.5 setting that stores crash-trace state across a request)
No. This is a server configuration setting (fatal_error_backtraces=0).
Invalid or deprecated INI diagnostics as a consumer (warnings PHP raises when applying bad configuration settings)
No. This path runs server-side, not over client HTTP.
Where an application does not accept multipart uploads, an edge rule that blocks multipart/form-data removes the multipart out-of-memory path that works against any application, plus the session-upload-progress trigger, which is a defense-in-depth control during the patch window.
If your application does use multipart uploads, AWS WAF reduces risk but does not close the vulnerability, because header amplification (a few kilobytes of part headers that expand into far more memory inside PHP) stays within size limits and the firewall cannot parse the headers inside individual body parts. In that case, prioritize the PHP upgrade and apply the server-side mitigations described later.
Start with the AWS WAF PHP application managed rule group
The PHP application managed rule group (AWSManagedRulesPHPRuleSet) contains rules that block request patterns associated with the exploitation of vulnerabilities specific to PHP. PHP2Shell_BODY inspects the request body for requests that match CVE-2026-109619 and is in version 2.3 and later. PHP2Shell_BODY_Extended inspects the request body for requests that match CVE-2026-109618 and is in version 2.4 and later. The default action of both rules is Block. The AWS WAF documentation notes that this rule group contains a virtual patch for CVE-2026-109618 and CVE-2026-109619, and that you can add it to your protection pack (web ACL) to help protect your application against exploitation attempts until your application is patched. The rule group uses 100 web ACL capacity units (WCUs). Like the other AWS managed baseline and use-case rule groups, it has no charge beyond standard AWS WAF pricing.
What you need to do depends on how your web ACL uses the rule group:
You use the default version. Both PHP2Shell_BODY and PHP2Shell_BODY_Extended are already active. Confirm that you haven’t overridden the whole rule group to Count, and review your AWS WAF logs for matches.
You pin a static version.Version_2.3 has PHP2Shell_BODY but not PHP2Shell_BODY_Extended, and Version_2.2 and earlier have neither. Change the version to Version_2.4 or later. We recommend that you use the default version.
You don’t use the rule group yet. Add it to the web ACL in front of each PHP workload, as shown in the following example.
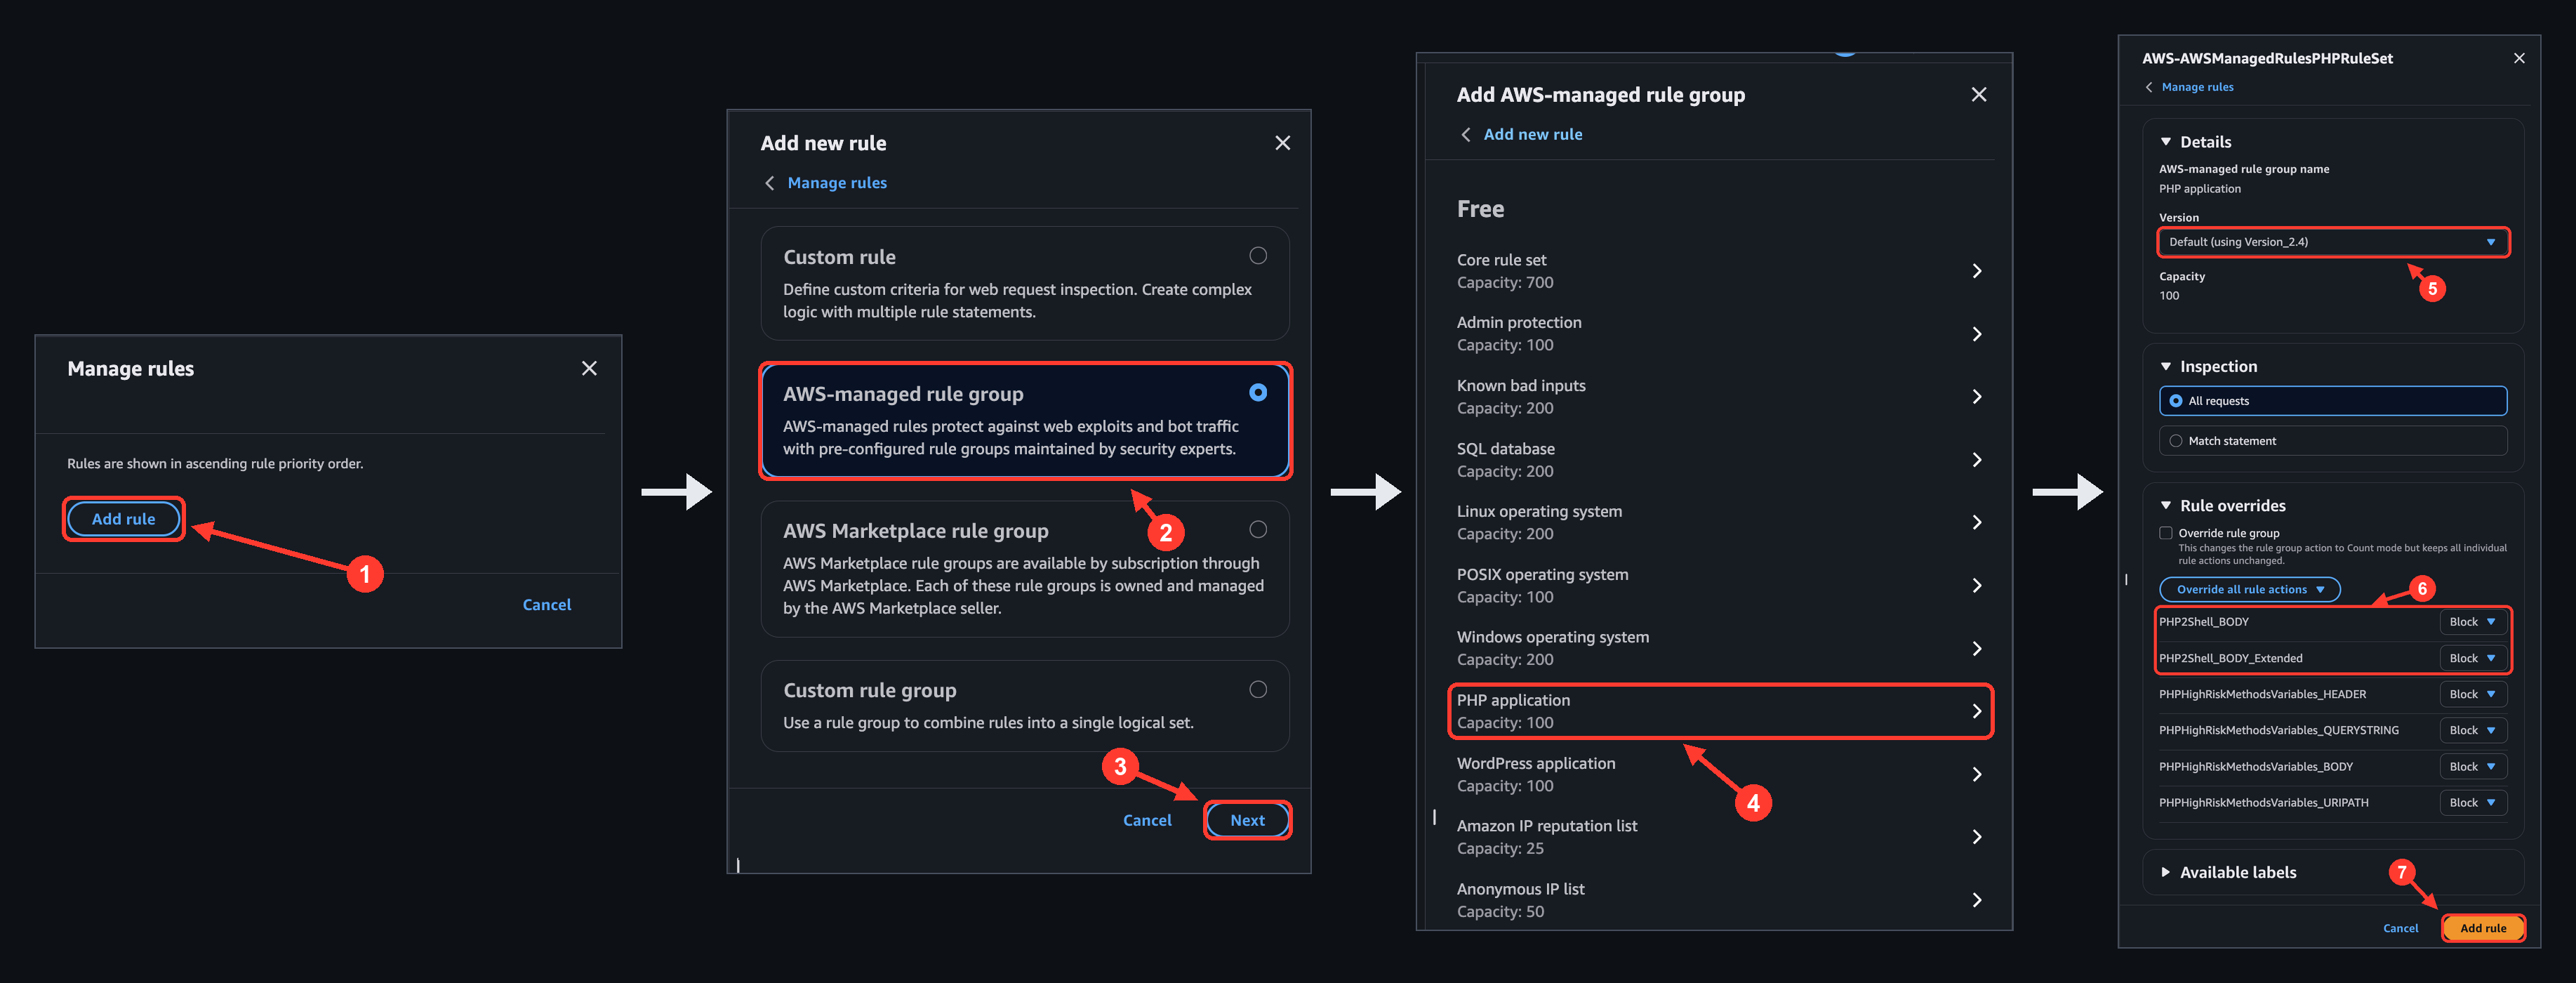
To add the rule group in the AWS WAF console, open your protection pack (web ACL), choose Manage rules, and then do the following, as shown in Figure 1:
Choose Add rule.
Select AWS-managed rule group.
Choose Next.
Under Free, choose PHP application.
For Version, keep Default (recommended). If you need to pin a version, choose Version_2.4 or later.
Under Rule overrides, confirm that PHP2Shell_BODY and PHP2Shell_BODY_Extended are listed. To review matches before they block, set both to Count.
Choose Add rule.
Figure 1: Adding the PHP application managed rule group in the AWS WAF console.
If you prefer to work programmatically, run the following commands to see the current default version and the version that a web ACL uses. Both commands are read-only.
For web ACLs associated with Amazon CloudFront, use --scope CLOUDFRONT and the US East (N. Virginia) Region. A rule without a Version field uses the default version.
The following rule adds the rule group at the default version. The RuleActionOverrides entry sets PHP2Shell_BODY and PHP2Shell_BODY_Extended to Count so you can review their matches before they block. Remove the override when you’re satisfied. Given how quickly exploitation followed disclosure, measure that review period in hours, not days. If you need to pin the rule group, add a Version field set to Version_2.4 or later to the ManagedRuleGroupStatement. We recommend the default version.
If PHP2Shell_BODY or PHP2Shell_BODY_Extended matches legitimate requests, keep the rule in Count and add a label-based exception after the rule group. The rule group adds the labels awswaf:managed:aws:php-app:PHP2Shell_Body and awswaf:managed:aws:php-app:PHP2Shell_Body_Extended to requests that match either rule, and the following rule blocks those requests everywhere except one path. Requests to the excluded path aren’t protected by this rule, so keep the exception as narrow as you can and patch that application first. Labels are case sensitive: confirm the label name in the rule group’s available labels (the DescribeManagedRuleGroup API) before you deploy. For the full pattern, see Creating exceptions in the AWS WAF best practices guide.
You can also return a web ACL to Version_2.2 while you tune, but that version includes neither PHP2Shell_BODY nor PHP2Shell_BODY_Extended. Treat a rollback as removing the CVE-2026-109619 and CVE-2026-109618 protection, and prefer the Count override and exception.
PHP2Shell_BODY and PHP2Shell_BODY_Extended inspect the request body only up to the web ACL body inspection limit. Both use the Continue oversize option, so they don’t inspect content beyond that limit. Pair them with a body size rule such as SizeRestrictions_BODY in the Core rule set (AWSManagedRulesCommonRuleSet), which blocks request bodies over 8 KB. If you set that rule to Count because of upload paths, use a label-based exception scoped to those paths instead. That keeps the rule in Block everywhere else. For the limit on each resource type, see Request body inspection limits later in this post.
Additional WAF Rules to consider
The managed rule groups cover two of the rules in this section. PHP2Shell_BODY in the PHP application rule group covers CVE-2026-109619, the same CVE as the custom rule later in this post. SizeRestrictions_BODY in the Core rule set caps request bodies at 8 KB, which covers body content beyond the inspection limit. For CVE-2026-109618 itself, the PHP application rule group includes PHP2Shell_BODY_Extended (version 2.4 or later). No AWS managed rule group blocks all multipart requests or rate-limits POST requests, so those two rules remain custom. Use them where they fit your application.
The following rules are in AWS WAF JSON format. Add each one to the protection pack (web ACL) associated with the CloudFront distribution, Application Load Balancer, or API Gateway stage in front of your PHP workloads. Adjust the priorities to fit your web ACL. The AWS WAF best practices guide describes a recommended rule order, with managed rule groups before the label-based exceptions that depend on them.
IMPORTANT: Before you change anything, turn on AWS WAF logging so you can see what each rule matches. Start every rule in Count mode, confirm it doesn’t match legitimate traffic, then switch to Block.
Request body inspection limits
The body inspection limit depends on the resource that the web ACL protects. On Application Load Balancer and AWS AppSync, the limit is a fixed 8 KB. On CloudFront, API Gateway, Amazon Cognito, App Runner, Verified Access, and Amazon Bedrock AgentCore Gateway, the default is 16 KB, and you can raise it up to 64 KB through the web ACL AssociationConfig, as shown in the following example. AWS WAF treats any part of the body beyond the limit as oversize. Choose a limit that fits the rules you deploy, because a body size rule can only enforce a cap up to the inspected size.
Custom rule for CVE-2026-109619 (if you can’t use the managed rule group)
Use this custom rule if you would prefer to use a custom rule instead of a managed rule group. It targets CVE-2026-109619 and blocks a request only when all three conditions in its AndStatement are true at once:
The method is exactly POST, matched on the HTTP method with no transformation.
A PHP session identifier is present (the nested OrStatement, so either sub-condition satisfies this leg):
PHPSESSID appears as a cookie key (exact match on the key, scanning all cookies), or
PHPSESSID appears anywhere in the request body (contains match).
The body contains PHP_SESSION_UPLOAD_PROGRESS, the form field that activates PHP’s session upload progress feature.
Pair the rule with session.upload_progress.enabled=0 on the server, which turns the feature off. The following rule has its action set to Count. Change it to Block after you confirm it doesn’t match legitimate traffic.
Block multipart requests when the application has no uploads
NOTE: This rule, in Block mode, breaks applications that require file uploads. If your application doesn’t require file uploads, blocking removes the multipart out-of-memory path that works against any application for both CVEs at the edge.
AWS WAF inspects a single named header in full, with no 8 KB header limit, so matching the Content-Type header is reliable.
Capping body size reduces the out-of-memory condition behind CVE-2026-109618 and the stale state it can leave behind. It also covers request bodies larger than the inspection limit, which body-inspecting rules such as PHP2Shell_BODY and PHP2Shell_BODY_Extended evaluate only in part. If you use the Core rule set, its SizeRestrictions_BODY rule blocks bodies over 8 KB by default. Use the following custom rule when you need a different threshold or don’t use the Core rule set. It uses OversizeHandling: MATCH with a size constraint so that any body larger than the threshold is blocked, including bodies that exceed the inspection limit. To enforce a cap of N bytes, the web ACL body inspection limit must be at least N.
Note that you can’t cap the numeric Content-Length with a size constraint, because the constraint measures the length of the header value string, not the number it contains. If your application has legitimate large uploads, scope this rule to non-upload paths with an AndStatement on the URI path, or it will break those uploads.
NOTE: If a specific managed rule breaks legitimate traffic, override that rule to Count rather than disabling the whole group.
Rate-limit repeated attempts
A rate-based rule on POST requests limits how many requests one IP address can send. That lowers the chance of triggering either vulnerability through volume. It also makes the stale-state path harder, because that path needs a producer request and a consumer request to land on the same worker. Set the limit from your normal per-IP POST rate; 100 requests per 60 seconds is a starting point. This rule complements a server setting of pm.max_requests=1, which recycles the worker on each request.
These host and runtime changes address the parts of CVE-2026-109619 that sit below the HTTP layer a WAF inspects, so they fall outside its scope by design. Apply them alongside the AWS WAF rules as the host and runtime layer of your defense.
Upgrade PHP to 8.5.12, 8.4.27, 8.3.36, or 8.2.35. This is the only complete fix for CVE-2026-109618 and CVE-2026-109619. These releases don’t fix CVE-2026-115560; see the session.upload_progress.enabled bullet. PHP 8.1 and earlier are no longer supported upstream, so check with your distribution or long-term support vendor for a backported fix, or plan a move to a supported branch.
Address CVE-2026-109618 at the PHP level. Set memory_limit=-1 in a way applications can’t override, such as php_admin_value in the FPM pool or Apache configuration, and check that no pool, directory, or application setting puts a finite limit back. Keep post_max_size low (8M where the application accepts no uploads, 32M where it does), and keep upload_max_filesize below post_max_size. Use a container or cgroup limit as an availability boundary, not RLIMIT_AS or RLIMIT_DATA, which can cause the vulnerable allocation failure.
Set fatal_error_backtraces=0 on PHP 8.5 and restart every worker. This disables the setting that stores crash-trace state across a request, one of the confirmed ways the vulnerability is triggered.
Set session.upload_progress.enabled=0 and restart every worker. This turns off the upload-tracking feature that’s the other confirmed trigger. Keep it off after you patch: it is also PHP’s mitigation for CVE-2026-115560, which the October 21 releases don’t fix.
Prefer php.ini, FPM pool, or server startup configuration over per-request INI overrides (settings applied per request through .htaccess, php_value, or FastCGI PHP_VALUE). Remove obsolete directives so they don’t raise diagnostic warnings.
Eliminate fatal errors and execution timeouts on attacker-reachable routes, including upload, import, error-page, shutdown, serialization, and extension paths.
Set pm.max_requests=1 if performance allows, so each worker process is recycled after one request, which breaks the link between the request that plants stale data and a later request that would reuse it.
Turn on error logging (log_errors=On, a working error_log, error_reporting=E_ALL) and review your Apache, FPM, or proxy logs for repeated warnings, deprecations, fatal errors, and timeouts on attacker-controlled routes. The absence of errors is not proof of safety.
Getting started
Complete the following steps to get started:
Inventory where PHP runs and which versions and server APIs (mod_php, FPM, FrankenPHP, LSAPI) are in use. Identify any public endpoint that accepts a request body.
Check the web ACL in front of each PHP workload. If it uses the PHP application rule group at the default version, PHP2Shell_BODY and PHP2Shell_BODY_Extended are already active. If it pins a static version, change it to Version_2.4 or later, or remove the Version field to use the default version.
Add the PHP application rule group and the Core rule set where they’re missing. Then decide whether each application uses multipart uploads, which determines whether you can add the rule that blocks multipart requests.
Add the applicable custom rules in Count mode. Raise the body inspection limit on CloudFront or API Gateway if a rule needs it.
Watch the sampled requests and Amazon CloudWatch metrics for each rule. Confirm that legitimate uploads and large JSON POSTs aren’t matched.
Switch the rules to Block after the metrics are clean. Test the custom rules with a benign multipart/form-data POST, an oversized body, and a POST request that has a PHPSESSID cookie and PHP_SESSION_UPLOAD_PROGRESS in the body. After you switch to Block, expect a 403 response and the matching rule metric.
In parallel, apply the PHP upgrade and the configuration mitigations. Remove or retain the AWS WAF rules as supporting controls after your fleet is patched.
Conclusion
The PHP2Shell vulnerabilities—CVE-2026-109618 and CVE-2026-109619—are unauthenticated RCE vulnerabilities that reach PHP before your application code runs. AWS WAF gives you a way to help narrow the attack surface during the patch window. Turn on the PHP application managed rule group at the default version (or version 2.4 or later if you pin) and the Core rule set. Then add the custom controls that fit your application: block multipart requests where no uploads are expected, cap request body size, and rate-limit repeated attempts. These mitigating controls can help reduce exposure, but they don’t close the vulnerabilities. Upgrade PHP to a fixed release, apply the server configuration changes (including session.upload_progress.enabled=0, which also covers CVE-2026-115560 until PHP releases a fix), and treat AWS WAF as the edge layer that supports those fixes rather than the fix itself.
Most security tooling that fits into a CI/CD pipeline—static analysis (SAST), software composition analysis (SCA), and dynamic scanners (DAST)—flags potential issues from patterns and signatures. A flagged pattern shows you where to look; penetration testing is what confirms whether something is actually exploitable. That confirmation has traditionally come from a periodic, out-of-band engagement that runs on a schedule rather than on a deploy, so deploys between engagements reach production with that confirmation still pending.
AWS Continuum for penetration testing (formerly AWS Security Agent) is a service that uses AI agents to find and confirm exploitable vulnerabilities in your running applications. In this post, we walk you through making it a post-deployment gate in your pipeline. The gate runs a penetration test that is automatically scoped to the change you just deployed, and it can block promotion to production when a finding is at or above a severity threshold you choose. Because each run tests only the change since the last passing gate rather than the whole application, it is fast and economical enough to run on every deploy. We give a high-level overview of the pattern, which can be applied on four major CI/CD platforms: GitHub Actions, GitLab CI/CD, Bitbucket Pipelines, and Azure DevOps Pipelines. We then provide a specific worked example for GitHub Actions.
By the end, you will have a pipeline that deploys a change to a staging environment, runs a scoped penetration test against the deployed change, and promotes the change to production only when the gate passes.
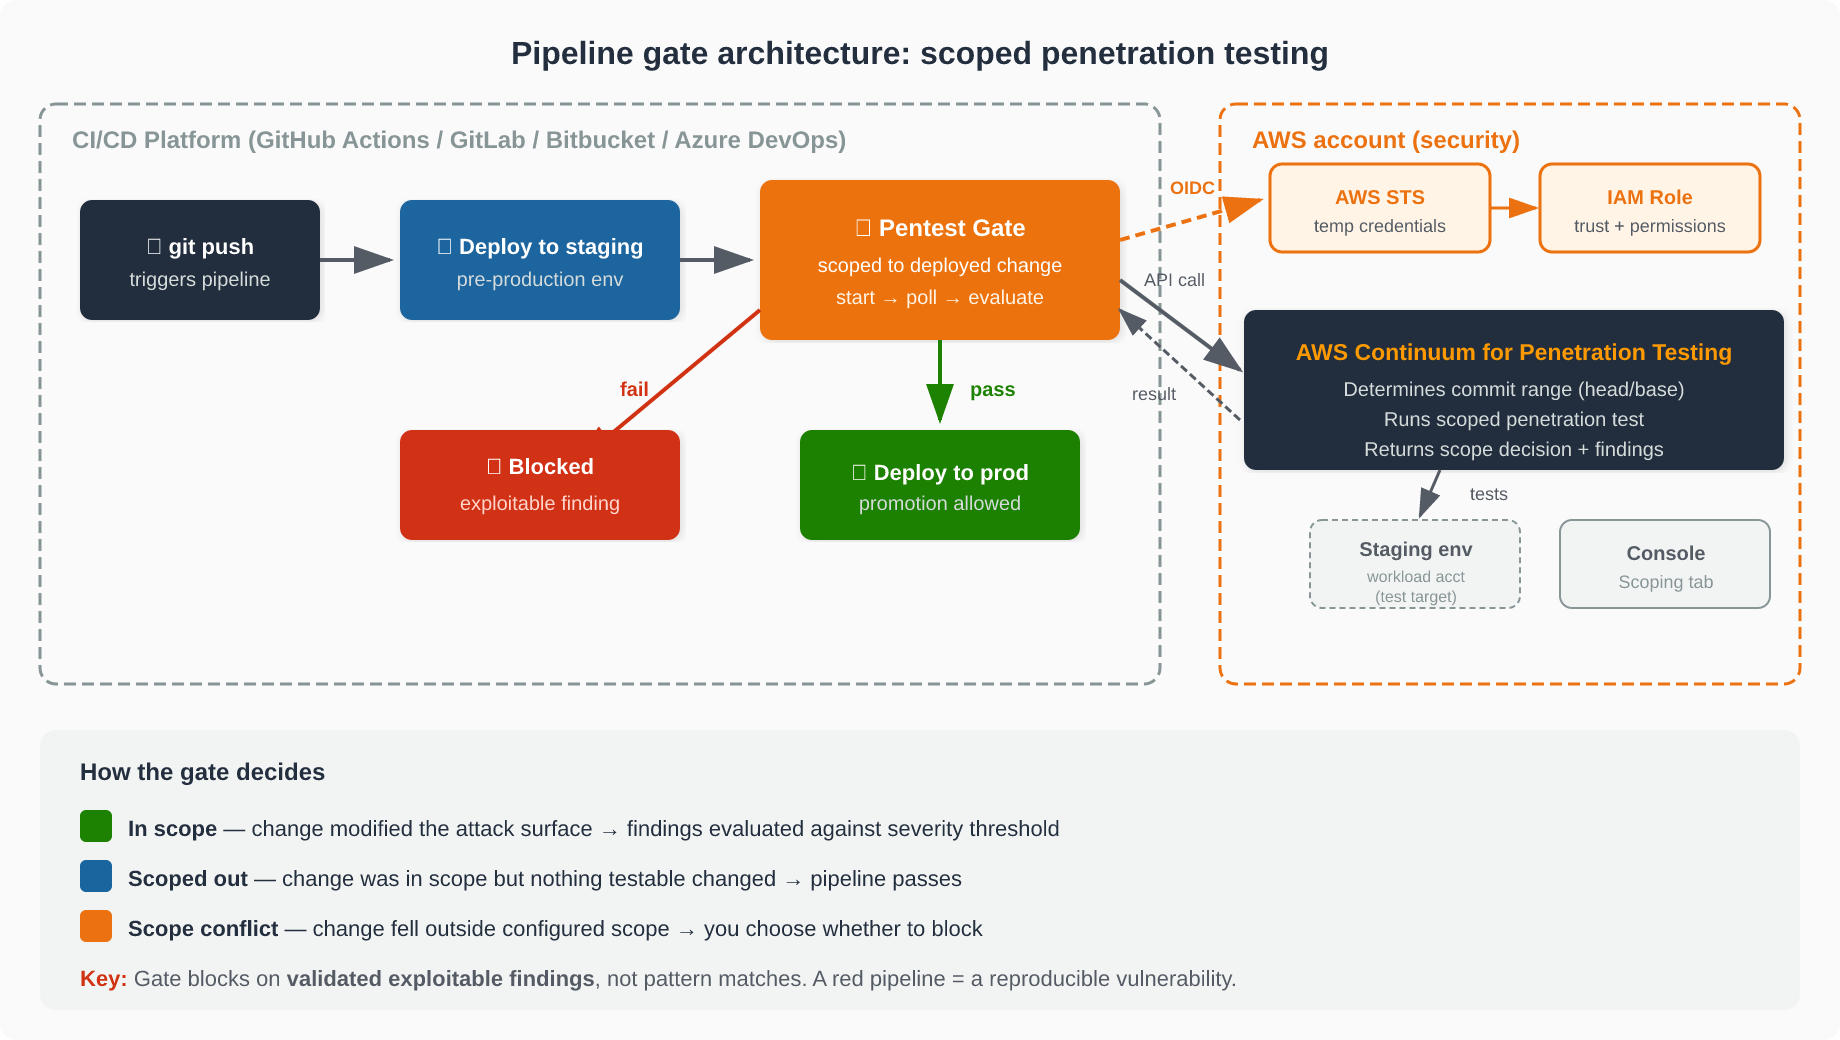
The following diagram shows the end-to-end flow. Your CI/CD pipeline deploys to staging, then the pentest gate step authenticates to your AWS account through OpenID Connect (OIDC) and calls Continuum for penetration testing, which runs the scoped test against the staging environment. The gate waits for the result, reports the outcome back to your pipeline, and conditionally blocks promotion to production. All testing runs server-side in your AWS account, so no penetration testing logic runs on your CI/CD runner.
Figure 1: Pipeline gate architecture: Your CI/CD pipeline deploys to staging, the pentest gate authenticates via OIDC and calls Continuum for penetration testing, which returns a scope decision that gates promotion to production.
Why scoping to the change matters
What makes the gate practical to run on every deploy is that it scopes each test to the change you just deployed. Continuum for penetration testing determines the commit range—the head is the commit being gated, and the base is the previous commit the gate already cleared—and tests only what changed. Testing the change instead of the whole application is what keeps a per-deploy penetration test fast and cheap enough to belong in a pipeline rather than on a quarterly calendar.
Each run returns one of three scope decisions: in scope (the change modified the attack surface—findings are evaluated against your threshold), scoped out (the change was within scope but nothing security-relevant changed—the pipeline passes), or scope conflict (the change fell outside the configured scope and was not tested—you choose whether that blocks). The Continuum for penetration testing console records the decision and the commit range on the Scoping tab of each run. When a gate blocks, you can see exactly why. For the full mechanics of how the commit range is computed and validated, see How the pipeline integration scopes the test.
Because the gate blocks on findings that Continuum for penetration testing validated as exploitable rather than on pattern matches, a red pipeline carries a clear meaning: a reproducible vulnerability in the change, waiting to be fixed before promotion.
Setting up the gate
The gate takes three steps to set up: configure a penetration test, create an AWS Identity and Access Management (IAM) role that your pipeline can assume, and add the gate step to your pipeline.
Before you start, you need an AWS account with permission to create both an IAM OIDC identity provider and an IAM role, and a staging environment the penetration test can reach.
Step 1: Configure the penetration test
Complete the one-time setup described in Before you start: verify your target domain, create a penetration test in your Agent Space, enable CI/CD mode, and connect your repository. Note the Agent Space ID (as-…) and penetration test ID (pt-…), because you pass both to the gate step in Step 3. The pipeline tests whatever this penetration test is configured to test, so its target and scope set what the gate covers.
Step 2: Create the IAM role
Authentication uses OIDC federation rather than stored keys. Your CI/CD provider issues a short-lived token identifying the pipeline, and AWS Security Token Service (AWS STS) exchanges it for temporary credentials when the pipeline assumes an IAM role you create. There are no long-lived AWS access keys to store as CI/CD variables, which removes the credential most often leaked from a pipeline.
The security of the gate rests on two policies: the IAM role’s trust policy (which pipelines can assume the role) and its permissions policy (what the pipeline can do once the role is assumed). For the exact policy JSON, the provider-specific OIDC URLs and audience values, and the sub claim format for each CI/CD platform, follow the reference in Scope the trust policy to your pipeline and Grant least-privilege permissions.
The following judgment calls help you decide how to scope these policies.
How tightly to scope the trust policy is the first decision. Pinning the sub claim to a single branch (for example, main) is the right default when a branch is the only one that deploys through this pipeline. If several branches or environments legitimately run the gate, scope to the environment instead of the branch where your provider’s claim supports it—and remember that not every provider carries a branch in the claim at all. On Bitbucket, the repository (and optionally a deployment environment) is as tight as it gets. Start as narrow as your deployment reality allows and widen only when a real branch or environment needs it. Note that GitHub repositories created or renamed on or after July 15, 2026 emit an immutable sub claim with numeric IDs—confirm the exact sub your pipeline emits before you write the policy.
Step 3: Add the gate step to your pipeline
The step is the same idea on every provider—the syntax differs. Pin the integration to an immutable version (a release tag, commit SHA, or pinned component version) so an upstream change can’t alter what runs in your pipeline. For the full settings reference and defaults table, see Defaults the integration ships with.
Before relying on the gate, run it once in dry-run mode. A dry run checks authentication, the Region, and that your repository resolves—without starting a scoped penetration test job. If validation fails, the step fails regardless of your error-handling settings, so a misconfiguration surfaces immediately.
A worked example: GitHub Actions
The following workflow shows the three-job topology that makes the gate work: deploy deploys to staging, security-pentest runs the gate, and deploy-prod promotes to production. Because deploy-prod declares needs: [security-pentest], GitHub skips production whenever the gate fails.
Note: The tutorials use an application with a deliberate SQL injection so the gate has a real finding to block on. Deploy it only to an isolated, non-production environment and remove it when you finish.
Replace the account ID, role name, Region, and the as-/pt- identifiers with your own values.
Two things in this example deserve attention. First, the contents: write permission lets the gate advance the baseline marker it keeps as a ref in your repository—without write access, every run would test a wider range than intended. Second, the role-duration-seconds: 7200 on the credential step must outlast the penetration test; AWS STS rejects a request for more than the role allows rather than reducing it, so set the role’s maximum session duration to at least (timeout + 10) x 60 seconds. A credential that expires partway through makes an otherwise-healthy run fail as though the service were at fault and leaves the cleanup unable to stop the abandoned, still-running job.
The full step-by-step tutorials for all four providers are linked at the end of this post.
Rolling out the gate: from report-only to blocking
The single most important detail before you roll this out.
Three independent settings decide whether the step fails, and each covers a different outcome: severity-threshold (what happens to findings), on-scope-conflict (what happens when the change wasn’t tested), and fail-on-infrastructure-error (what happens when the job couldn’t run). They are independent—relaxing one does not affect the others.
Most teams introduce the gate in report-only mode first—set threshold to NONE so the test runs and publishes findings without blocking anyone’s pipeline. Watch what it finds for a release or two, then tighten the threshold to HIGH. This staged rollout is sound, with one critical caveat:
A run that passes—including a report-only run—advances the baseline. The commits in that run’s range are then recorded as cleared and will not be re-tested when you later tighten the threshold. If you run report-only for a month and then switch to HIGH, the gate only assesses commits after the last report-only run—it does not go back and recheck what it already reported on.
This is by design: relaxing a setting is you accepting the outcome it allows. But if you want a stricter setting to reassess a range an earlier run cleared, override the head and base commit SHAs by settingbase-commit-shaandhead-commit-sha. Where the marker lives differs by provider; see What advances the baseline, and why that matters for the full matrix.
One default also deserves attention: fail-on-infrastructure-error ships as false (fail-open). For pipelines where promotion requires security sign-off, set it to true from the start.
GitLab: your committed settings are defaults, not a contract
On GitLab CI/CD, a pipeline variable overrides the value a job sets in its own variables: block. That means anyone who can run a pipeline could supply a variable that lowers the threshold, turns on dry-run, or relaxes error handling—and the gate does what the variable says, not what your .gitlab-ci.yml says. Restrict who may override variables in your project’s CI/CD settings before you rely on the gate to hold a release.
Protecting credentials on the runner
The temporary credentials and OIDC token are sensitive for the duration of the step. Three practices matter:
Keep debug and verbose tracing off for steps that handle credentials—shell-trace modes (for example, GitLab CI’s CI_DEBUG_TRACE) echo command arguments to the job log in plaintext.
Don’t persist source control credentials in the workspace—set persist-credentials: false on the checkout step so a token isn’t written to the runner’s .git configuration where a later step could read it.
Don’t expose the token to untrusted steps—grant OIDC-token permission only to the jobs that need it, and don’t run untrusted code (such as a fork build) in a job that can read the token.
Taking this to production and multiple accounts
The example uses one account for clarity. In practice, your staging and production environments are often separate AWS accounts. The pattern extends cleanly:
Create the pentest-gate IAM role in the account where the penetration test and Agent Space live—the security account. Your pipeline assumes that role via OIDC regardless of which workload account it deploys to, so you keep one well-scoped gate role rather than a copy or a set of long-lived keys in every account.
Run the gate against each pre-production environment you promote through, and gate promotion to the next stage on its result. Because the baseline advances only on a passing gate, coverage stays continuous across deploys.
Set fail-on-infrastructure-error to true and restrict who can override pipeline variables once the gate is holding real releases.
Pin the integration version so upstream changes are reviewed before they run.
For broader guidance of AWS Security Agent—testing against non-production environments, validating AI-generated findings, and IAM—see Security best practices for AWS Continuum.
Cleanup
If you followed one of the provider tutorials to try the gate, complete its Clean up section to remove everything it had you create: the sample application’s staging environment, the IAM role and OIDC identity provider, and—if you created one specifically for the walkthrough—the penetration test (and dedicated Agent Spaces) in the Continuum for penetration testing console. Removing them avoids ongoing charges and takes the intentionally vulnerable sample application offline.
Conclusion
Scoping penetration tests to the deployed change is what makes them practical as a per-deploy gate rather than a quarterly exercise. The key decisions you now have are:
How strict: Start report-only (NONE), but know the baseline advances—delete the marker when you tighten.
How to fail: Set fail-on-infrastructure-error to true for anything that requires security sign-off.
How to scope trust: Pin the sub claim as narrowly as your deployment reality allows.
Where to put the role: One role in a security account, assumed from workloads pipeline via OIDC.
To build the gate end to end on your platform, follow the worked tutorial for your provider:
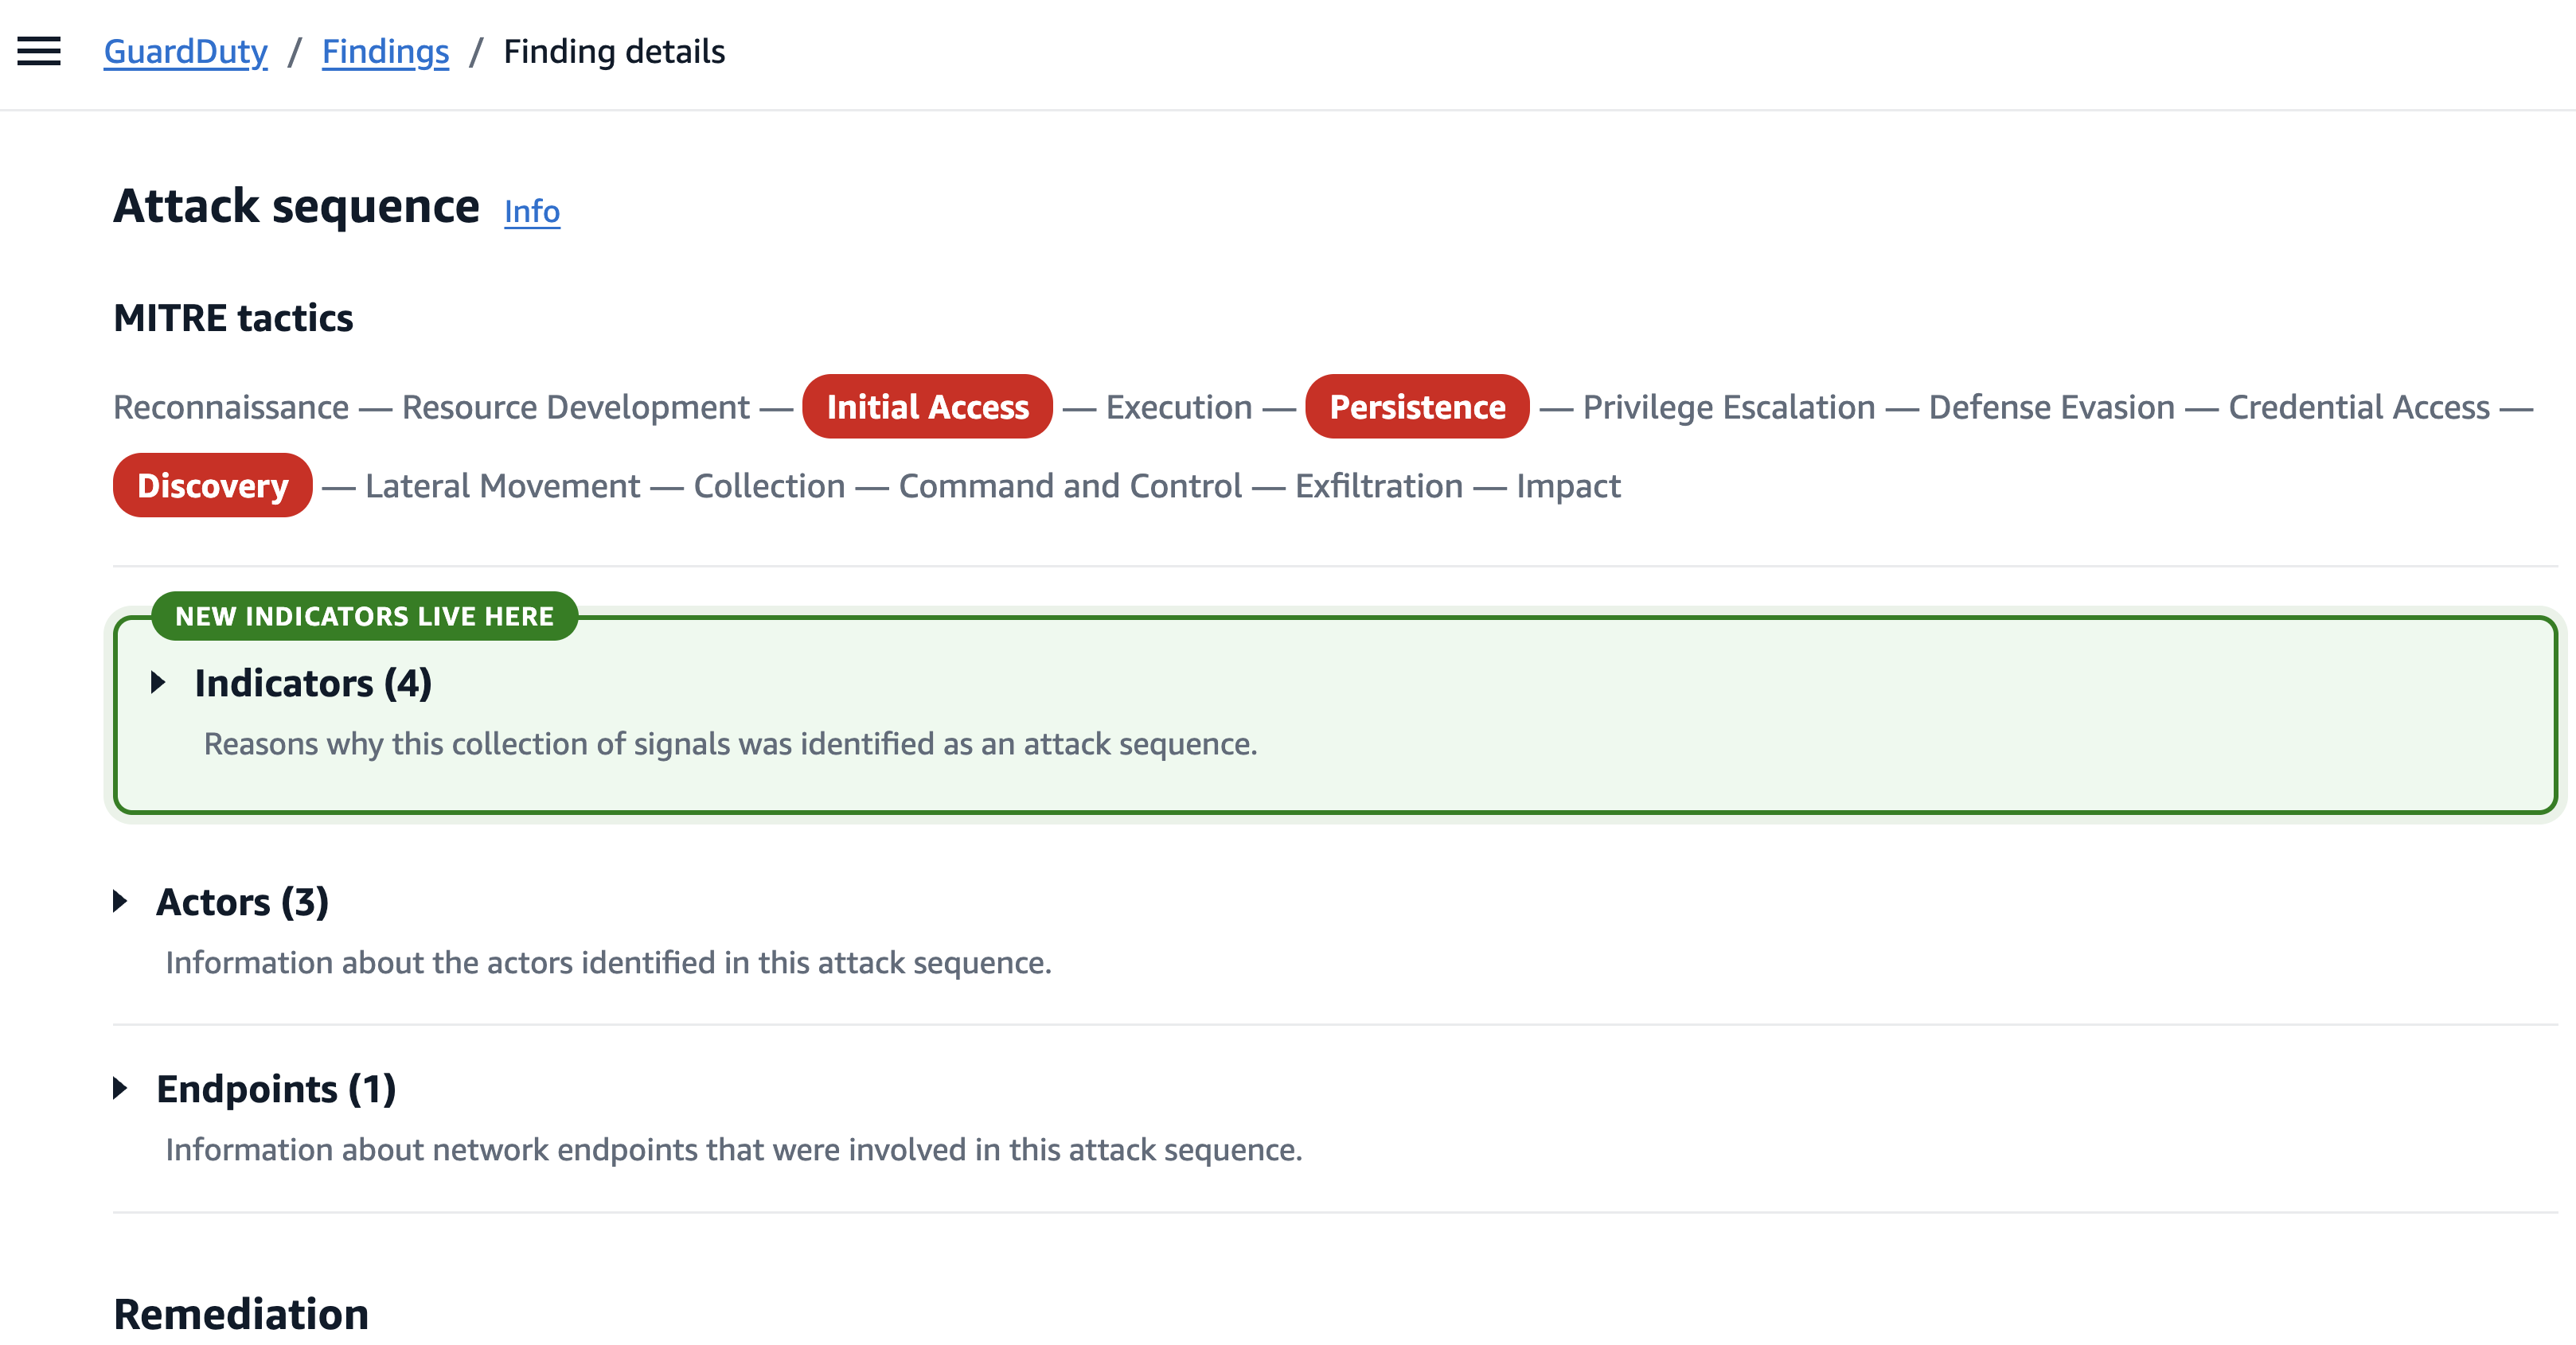
Amazon GuardDutyExtended Threat Detection correlates weak GuardDuty signals into a single, critical-severity attack sequence finding when their composition crosses a threshold of credibility. On May 20, 2026, the service started attaching five new indicator types to those sequences: MALICIOUS_PACKAGE, MISCONFIGURATION, REACHABILITY, SENSITIVE_DATA, and VULNERABILITY. For more information, see Document history for Amazon GuardDuty and Attack sequence finding details.
In GuardDuty, a signal is any event it evaluates when looking for suspicious activity. A weak signal is one that, on its own, doesn’t clearly point to a threat which the five new indicators fall into. A single Common Vulnerabilities and Exposures (CVE) finding on a host, for instance, tells you a vulnerability exists not that an attacker is exploiting it. These findings earn their value when GuardDuty correlates them with the suspicious-activity signals it already tracks, as shown in the following table:
Potential sensitive data has been discovered in the resource.
The five values appear on the Indicators tab of the attack-sequence finding in the AWS Management Console for GuardDuty and in the GetFindings JSON file.
Figure 1: Indicators section of an attack sequence finding
A note on EPSS, because the VULNERABILITY indicator carries it. According to the FIRST EPSS overview, the score is the probability that a published CVE will be exploited in the wild in the next 30 days ranging from 0 to 1. EPSS doesn’t replace CVSS, which describes the inherent severity of a vulnerability, whereas EPSS describes how likely it is to be exploited soon making it the more useful number for incident response.
Prerequisites
To populate the indicators, you need to have the following AWS services enabled:
Amazon Inspector on Amazon EC2 and Amazon EKS to support VULNERABILITY and MALICIOUS_PACKAGE.
Runtime signals such as a process invocation, a pod exec, or a syscall pattern can be noisy sometimes. A single runtime signal that doesn’t match a known offensive-tool path isn’t significant on its own, and without resource-state context it typically stays below the threshold for a Critical attack sequence.
The new indicators supply that missing context. When Extended Threat Detection sees a weak runtime signal on a host that also carries a combination of high-priority unpatched CVEs, a known malicious package, an IMDS misconfiguration, and internet reachability, it promotes the collection to a single CRITICAL attack sequence with high confidence. Customer feedback on individual GuardDuty runtime findings has consistently identified noise as a major pain point and adding this resource-state context is what turns those weak signals into actionable alerts.
In practice, this surfaces as a substantial increase in net-new attack-sequence findings on the runtime-process surface to roughly one in four prioritized runtime-process attack sequences, with little change on the network-indicator of compromise (IOC) surface. Within the first week of launch, this pattern showed up across many customer accounts where attack sequences that would previously have surfaced as a collection of weaker, unconnected findings now surface as a single CRITICAL finding.
Example: A net-new attack sequence on Amazon EKS
Now that you understand how Extended Threat Detection has improved through additional indicators, let’s walk through an example of how these indicators add value. In this example we analyze an actual scenario that was observed on an Amazon EKS cluster. The observed activity occurred over an 8-day period with eleven different GuardDuty findings.
Figure 2: Activity summary for the EKS cluster before Extended Threat Detection correlated the signals
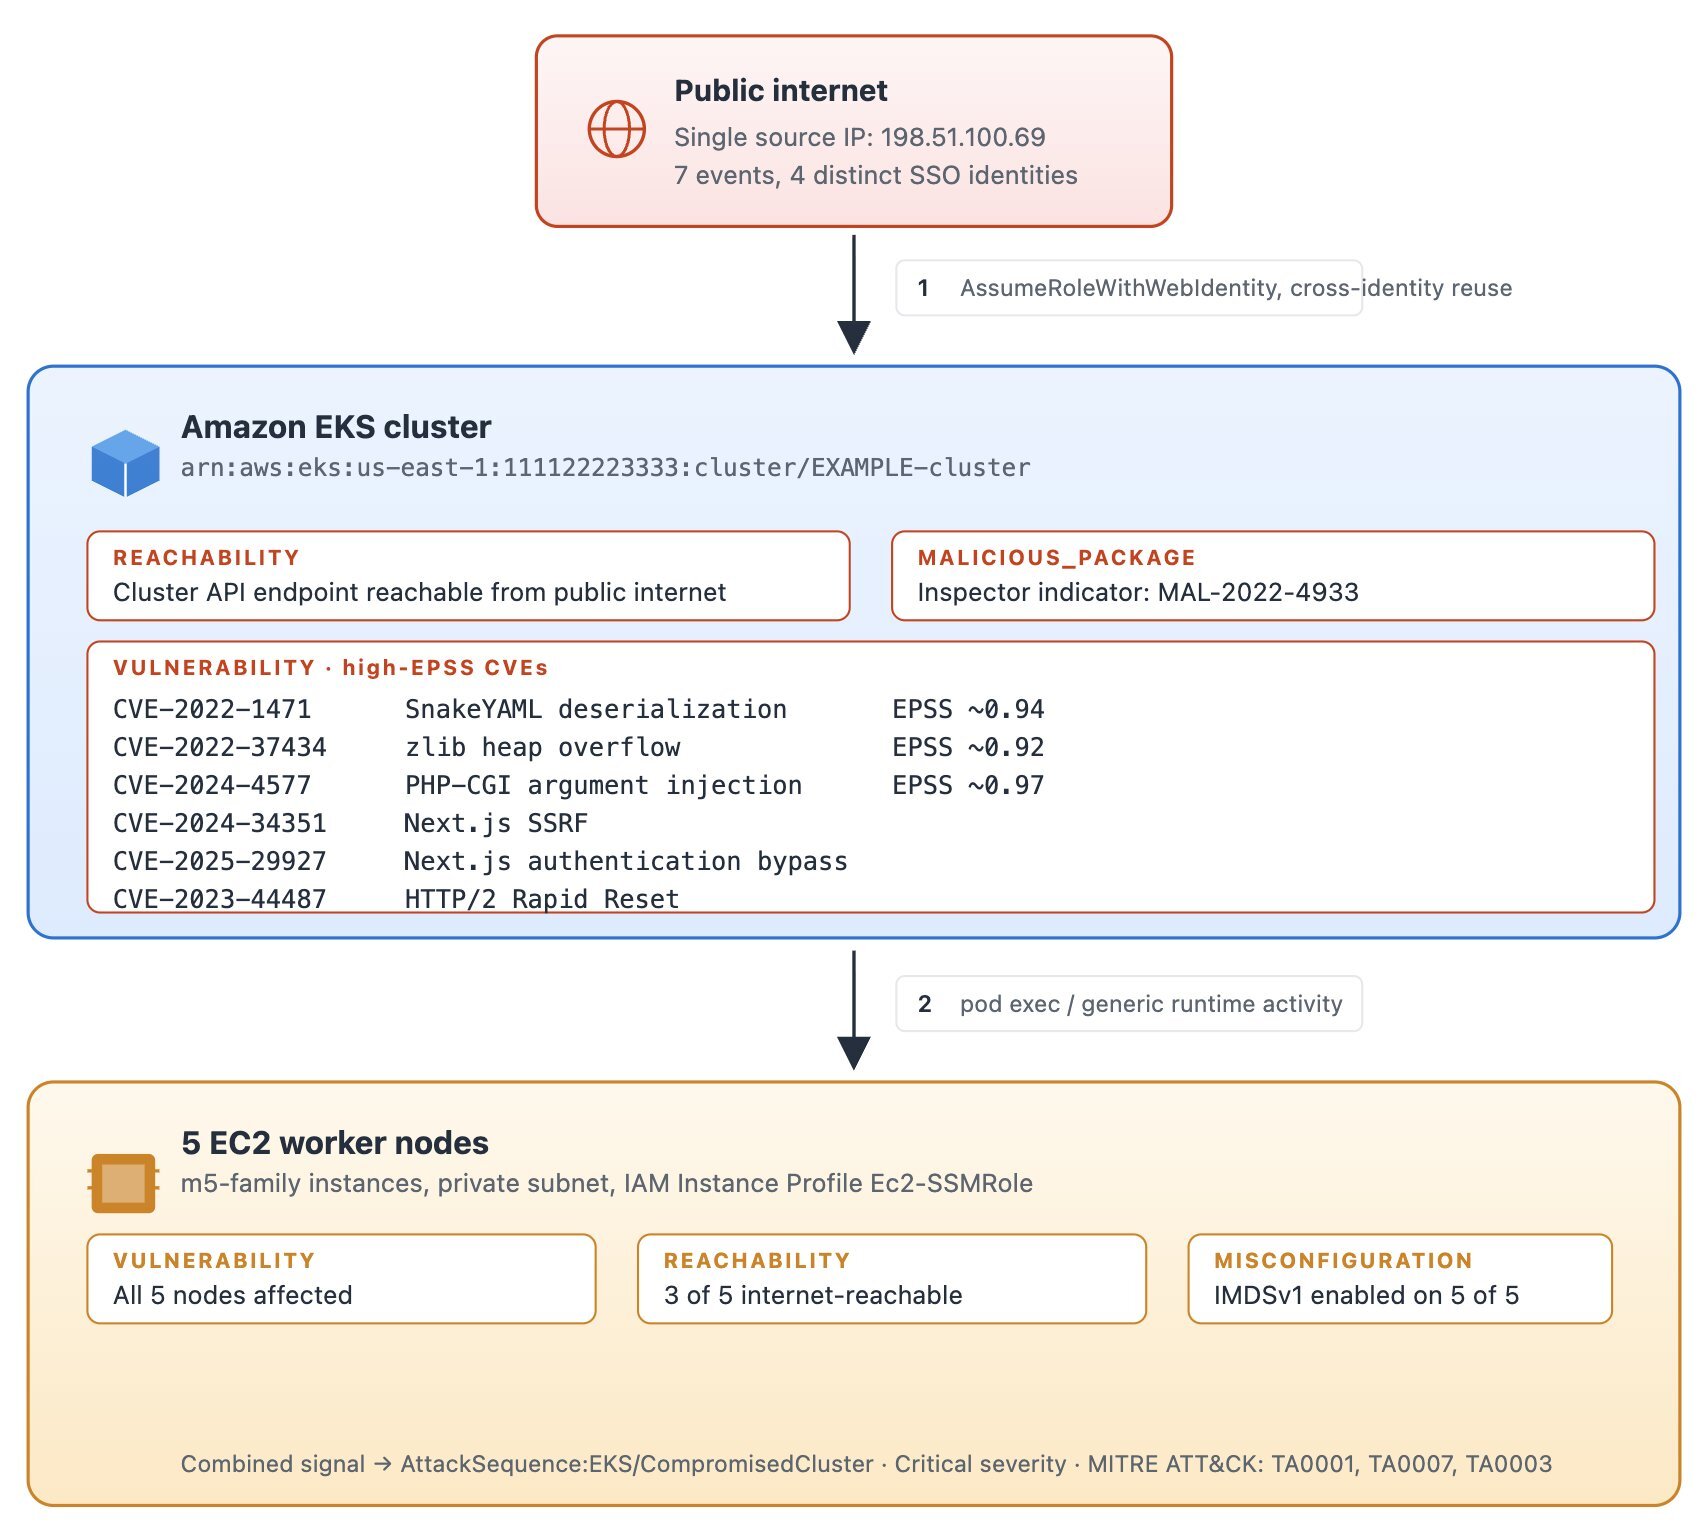
What GuardDuty saw on the activity surface over 8 days as shown in Figure 2 was 55 EKS_AUDIT_LOGS signals across pod execs, role assumptions, and AssumeRoleWithWebIdentity calls and 18 finding-level signals all originating from one external IP address of 198.51.100.69. This IP address authenticated as four distinct AWS Identity and Access Management (IAM) identities to the same EKS cluster. Runtime activity on the worker nodes was generic because there was no process that matched a known offensive-tool path and no execution-profile flag was fired. Under the pre-launch correlation, this sequence would have needed the EKS_MALICIOUS_PROCESS rule to fire, which requires either a malicious exec path or an unusual-suspicious-tool profile. Neither was present in this activity, so no correlated attack-sequence finding was raised.
What the new GuardDuty Extended Threat Detection indicators added to the EKS example:
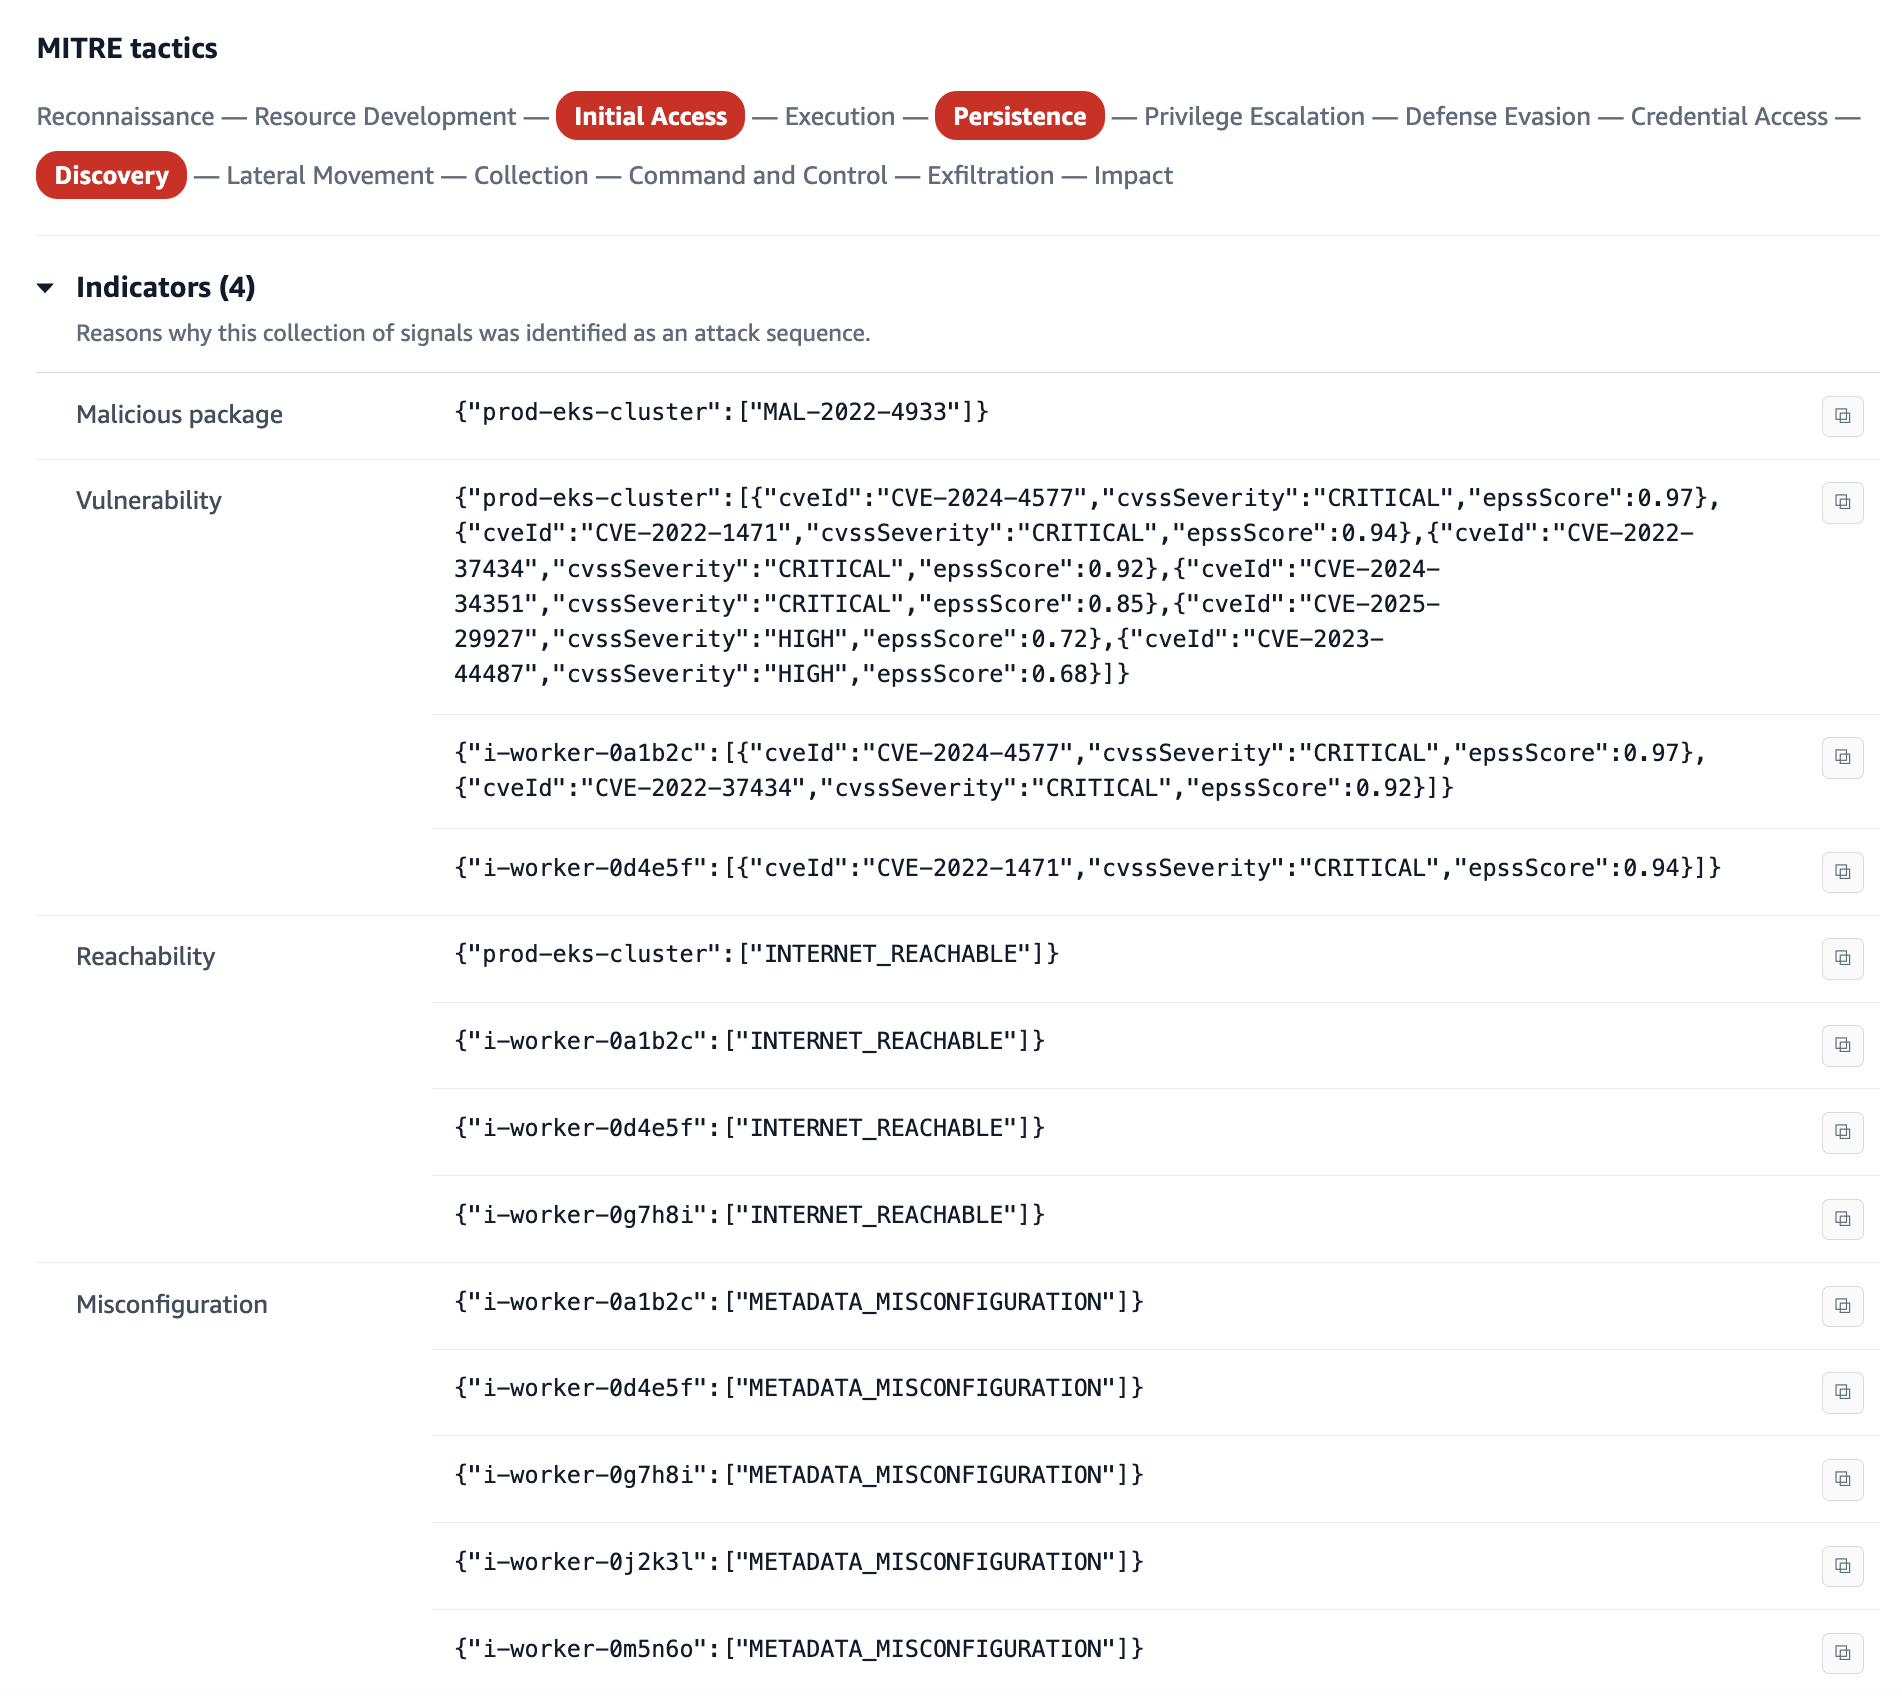
MALICIOUS_PACKAGE on the cluster: Amazon Inspector identifier MAL-2022-4933.
VULNERABILITY (full Amazon Inspector output) on the cluster: 42 CVEs total, 33 rated CRITICAL by CVSS.
On the cluster: 12 CVEs including CVE-2022-1471 (SnakeYAML deserialization, EPSS 0.94), CVE-2024-4577 (PHP-CGI argument injection, EPSS 0.97), CVE-2024-34351 (Next.js SSRF), CVE-2025-29927 (Next.js authentication bypass), CVE-2023-44487 (HTTP/2 Rapid Reset), and CVE-2022-37434 (zlib heap overflow, EPSS 0.92).
Across the five worker nodes: 379 CVEs total, with 68 of them marked CRITICAL by Amazon Inspector.
REACHABILITY: Cluster API endpoint internet-reachable and three of five worker nodes also internet-reachable.
MISCONFIGURATION (EC2 IMDS): All five worker nodes still expose IMDSv1.
When these additional indicators are taken into consideration, this surfaces as a single AttackSequence:EKS/CompromisedCluster with a CRITICAL severity, with all four populated indicators on the Indicators tab and a MITRE ATT&CK® mapping to Initial Access (External Remote Services), Discovery, and Persistence.
Figure 3: New vulnerability indicators within an attack sequence
The finding lists more than 100 Amazon EC2 CVEs at the worker-node level, one CRITICAL CVSS, plus a long HIGH tail, but most are LOW vulnerability priority because their EPSS scores are low. Rather than sifting through more than 100 findings to decide which to address first, GuardDuty highlights the high-priority ones so you can focus your response efforts where they have the most impact.
Example: Cryptomining and a vulnerable host
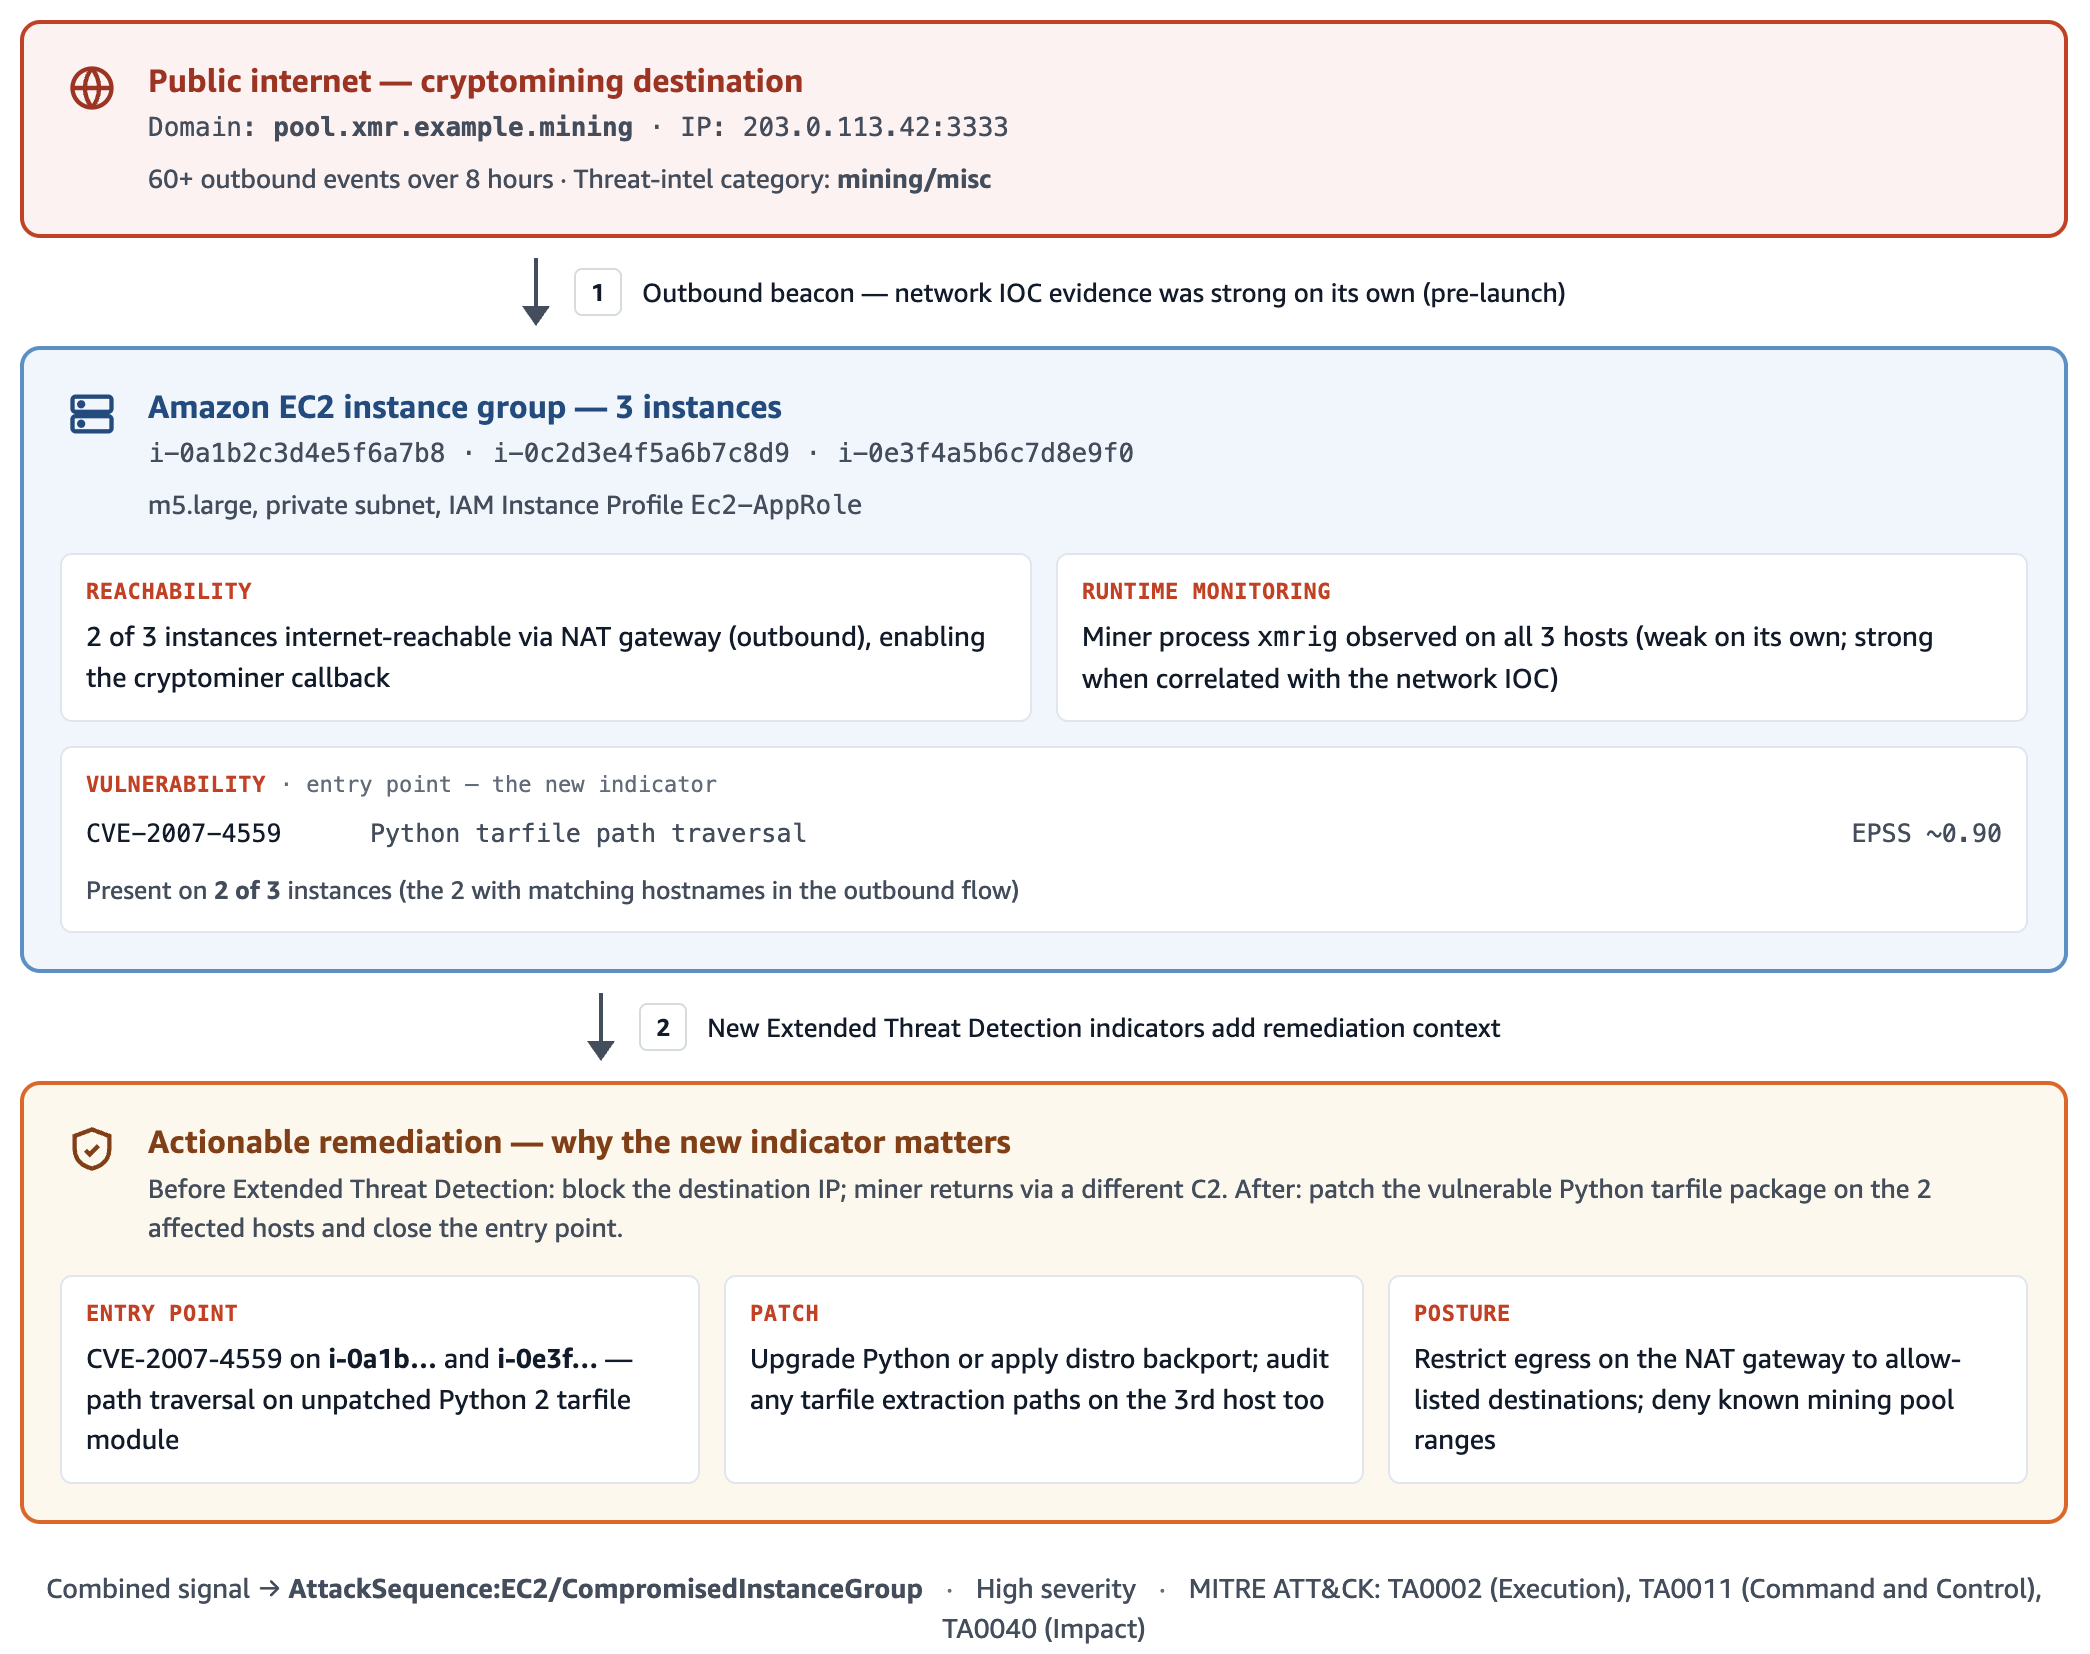
In this second example we walk through an EC2 instance group where GuardDuty already had a strong network-based finding for cryptomining and the new indicators provided additional remediation context that made incident response faster.
Figure 4: Cryptomining attack on EC2 instances
A set of EC2 instances was communicating with a known cryptomining destination, which was flagged by threat intelligence as mining/misc. The network IOC evidence was strong on its own.
Observations added by the new indicators: VULNERABILITY listed CVE-2007-4559 Python tarfile with EPSS around 0.9 on two of the three involved instances.
Result: The AttackSequence:EC2/CompromisedInstanceGroup finding is now actionable beyond block the destination IP; it tells you which patch will remediate the vulnerability the cryptominer likely came in through so you can address the underlying entry point rather than only removing the outbound connection.
This attack sequence would have been generated without the vulnerability context because GuardDuty had strong evidence of cryptomining of the EC2 instance group, however, triaging is faster with more context.
Indicators of compromise observed across the first-week launch sample
The following CVEs listed, along with their EPSS scores at the time, were observed on hosts across the customer accounts that received the new Extended Threat Detection indicators during the first week after launch at the moment each indicator finding was generated. EPSS scores are point-in-time, so a CVE’s listed priority on any future finding will reflect the current EPSS rather than the values shown here.
CVE-2024-4577 – PHP-CGI argument injection on Windows. EPSS 0.97+.
CVE-2007-4559 – Python tarfile path-traversal. EPSS still 0.9+ in 2026.
CVE-2025-29927 – Next.js authentication bypass. Frequent on Node web tiers.
CVE-2024-34351 – Next.js SSRF.
CVE-2023-44487 – HTTP/2 Rapid Reset.
Runtime monitoring surfaced weak signals tied to malware and tooling artifacts recovered from the compromised hosts:
HackTool family Linux/frp (Fast Reverse Proxy variants were used as command-and-control tunnels), often disguised as kuboard-agent and kuboard-agent-server binaries on Amazon EKS worker nodes. Container-snapshot path matches were also observed under /var/lib/containerd/io.containerd.snapshotter.v1.overlayfs/snapshots/.../usr/bin/. The frp binaries are present inside the container image and on the node, which means rebuilding the node from an unpatched AMI won’t be sufficient remediation.
BurpCollaborator out-of-band callback hostnames were found under *[.]oastify[.]com, matching pattern <35-char base32>[.]oastify[.]com. These co-occurred with frp on the same EKS sequence, probably a second tool or actor on shared infrastructure.
The Amazon Inspector malicious-package indicator MAL-2022-4933 was found in both Amazon EC2 and Amazon EKS contexts.
Identity and access patterns correlated with the tooling signals above:
A single external source IP authenticated as multiple distinct human IAM identities across separate Amazon EKS, Amazon ECS, and Amazon EC2 surfaces over a short window. This was the most common identity signature on the new Amazon EKS-process net-new class.
Responding to attack sequences with these indicators
The new indicators don’t change incident-response runbooks for attack sequences that have already occurred. They matter for new findings, which are concentrated on enhancing signals related to runtime monitoring. For those:
Treat the sequence with urgency. MALICIOUS_PACKAGE and a high-priority VULNERABILITY mean the host was, and still is, at risk of being compromised. Contain the exposures and remediate the vulnerabilities. Rotate every IAM credential, instance profile, or IAM Roles for Service Accounts (IRSA)-bound role that could have been exposed.
Patch on EPSS-weighted priority, not alone on raw CVSS. The finding’s high-priority VULNERABILITY list is already filtered to high-EPSS CVEs.
Isolate public resources indicated by REACHABILITY indicators. An internet-reachable host with exploitable vulnerabilities should be isolated for remediation.
GuardDuty Extended Threat Detection can deliver more high-confidence attack sequence findings on the runtime workload surfaces where your security teams often need help most: Amazon EC2, Amazon ECS, and Amazon EKS. It does this by combining GuardDuty activity signals with resource-state context from other AWS services. Customer feedback on individual GuardDuty runtime findings has consistently identified noise as a major pain point, and correlating those weak signals with vulnerability, package-risk, reachability, misconfiguration, and sensitive-data indicators is how Extended Threat Detection turns the noise into actionable CRITICAL findings. If you’ve already enabled AWS Security Hub, Amazon Inspector, Amazon VPC Reachability Analyzer, Macie, and GuardDuty Runtime Monitoring, the new indicators automatically start showing up on your attack-sequence findings. If you aren’t using these services, we encourage you to explore enabling them to access the new GuardDuty Extended Threat Detection indicators and the value that these individual services deliver.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.
You want to set a cryptographic algorithm policy and stop non-compliant choices from being made in your Amazon Web Services (AWS) environment. This post shows you how. As you adopt post-quantum cryptography, one of the first decisions you face is which algorithms and parameter sets fit your business needs, balancing security against signature size, key size, and performance. Your cloud environment’s job is to let you express that decision and enforce it consistently, so an approved choice stays fully usable while an excluded one cannot be introduced. This post works through one concrete example on AWS: taking an organization’s cryptographic algorithm policy and turning it into preventive and detective controls. The same patterns apply to whatever your approved set is today and whatever it becomes as standards evolve.
This post is Part 2 of a two-part series on quantum-resistant signing on AWS. Part 1, Build a software supply chain with ML-DSA, is for builders and constructs an end-to-end ML-DSA signing pipeline for binaries, container images, and software bills of materials. This part is for the security, governance, and compliance teams who decide which algorithms that pipeline, and everything else in the organization, is permitted to use, and who need that decision enforced.
AWS Key Management Service (AWS KMS) supports the ML-DSA digital signature scheme (FIPS 204) through three parameter sets, ML-DSA-44, ML-DSA-65, and ML-DSA-87, targeting NIST security categories 2, 3, and 5. All three are strong, standardized choices. Each one trades signature size, key size, and speed against security margin, the amount of cryptographic strength a parameter set holds in reserve above its target security category. ML-DSA-44 is the most compact and fastest. ML-DSA-65 and ML-DSA-87 carry a larger security margin, which is what you want for signatures that must stay trustworthy over a long lifetime.
Throughout this post, the examples use the same example policy: an organization that has standardized on ML-DSA-65 and ML-DSA-87 and wants ML-DSA-44 kept out of its approved set. That is a standardization decision, not a judgment that ML-DSA-44 is insecure (see the following note). Wherever you see ML-DSA-44 in the controls that follow, read it as the variant your policy doesn’t include; the mechanics are identical for any allow/deny split you choose. The approved set here is also the one the Part 1 architecture deploys: ML-DSA-87 for the root certificate authority (CA) and ML-DSA-65 for the subordinate CA and the code-signing key. Part 1 makes the choice; this post makes it stick.
Note: ML-DSA-44 is a valid choice. ML-DSA-44 is a fully NIST-standardized parameter set (FIPS 204) at NIST security category 2, which targets roughly 128-bit-class classical security (category 2 is benchmarked against the collision resistance of SHA-256). It produces the smallest signatures and public keys of the three variants (a 1312-byte public key and 2420-byte signature) and is the fastest to sign and verify, which makes it a strong fit for constrained devices, high-volume signing, and bandwidth- or storage-sensitive workloads. You would choose ML-DSA-65 or ML-DSA-87 instead to gain extra security margin for long-lived signatures or to align with an internal standard, not because ML-DSA-44 is weak.
What success looks like
The approved variants (ML-DSA-65 and ML-DSA-87 in the example) remain fully usable throughout. What you want to rule out is the introduction of a variant outside the policy (here, ML-DSA-44). Concretely, within the AWS service surfaces in scope, principals shouldn’t be able to:
Create ML-DSA-44 key material
Use existing ML-DSA-44 keys for signing or verification
Stand up private certificate authorities (CAs) that would introduce ML-DSA-44.
And any drift from those settings should be detected.
Certificate material brought in through acm:ImportCertificate or iam:UploadServerCertificate is also not algorithm-aware (see the Private CA section). Other TLS-terminating or signing services (for example Amazon CloudFront and Amazon API Gateway) and AWS IAM Roles Anywhere aren’t covered in this post and should be assessed separately. (Part 1 of this series uses IAM Roles Anywhere with ML-DSA certificates; controls for that service are out of scope here.)
These controls are intended to be applied as defense in depth. You can apply all of them or only a subset, depending on how prescriptive you want to be:
A blanket SCP at the organization root prevents member accounts from creating or using ML-DSA-44 keys. (SCPs don’t apply to the management account, so workloads there aren’t restricted.)
An SCP at a production organizational unit (OU) restricts keys only in production accounts.
If you need flexibility inside an account, use IAM permission boundaries instead of account-wide settings enforced through an SCP.
Choose the combination that matches your operating model. The policy examples here are written to apply across all AWS Regions. If you need to scope a control to specific Regions, add an aws:RequestedRegion condition.
The policies in this post are illustrative starting points. Authoring, validating, and maintaining the specific SCPs, IAM policies, and permission boundaries for your environment is your responsibility. Test all policies in a non-production environment before deployment and adjust example values (such as policy names and key Amazon Resource Names (ARNs)) to match your organization’s approved standards.
A note on cryptographic agility
Your algorithm policy isn’t fixed forever, and these controls shouldn’t be either. The point of expressing the policy as AWS controls is that you can revise it as your needs and the relevant standards change, tightening, loosening, or swapping the approved set without re-architecting. Treat the examples here as a template you adjust to whatever your current policy is.
A deny-based control that names specific algorithms is, in effect, an allow-list of everything it does not name. The risk is default-allow: any parameter set you have not explicitly denied is permitted, so a newly introduced variant, including one you have not yet evaluated, becomes usable until you notice it and add it to the deny list. Deprecation of an already-approved variant is easy to handle in this model, because you simply add the deprecated variant to the deny list. What the model does not catch on its own is the arrival of something new. Review these controls periodically and pair the deny-list with detection so a variant outside your policy surfaces quickly rather than waiting to be discovered.
The alternative is to write the condition against the approved set rather than the excluded one. A Deny that uses StringNotEquals with a list of approved key specs fires when the request’s key spec matches none of them, so a new or not-yet-evaluated variant is blocked by default until you add it. That closes the default-allow gap, at the cost of a policy update before anyone can use a newly approved variant. The family-level SCP in Part 1 of this series takes this shape: it denies creation of any signing key whose key spec isn’t ML_DSA_*. The examples in this post take the other shape and name the excluded variant, so that approved variants stay usable without a policy change. Both are valid. Choose based on whether you would rather block something new first and approve it later, or notice it first and decide then.
The StringLike clause scopes the statement to ML-DSA key specs so it doesn’t affect other key types; the StringNotEquals clause denies any ML-DSA variant outside the approved list.
Just as algorithms and key sizes will be introduced over time, or move from approved to unapproved, so will AWS service operations. The set of operations through which an ML-DSA-44 key can be used today (AWS KMS Sign, Verify, and GetPublicKey) reflects current service capabilities and might expand as AWS releases new features. If your policy is to block use in addition to creation, you should periodically review the list of operations you restrict, because services evolve over time.
Background: Key spec compared to signing algorithm
AWS KMS support for ML-DSA introduces three key specs—ML_DSA_44, ML_DSA_65, and ML_DSA_87—that all use a single post-quantum signing algorithm: ML_DSA_SHAKE_256. This distinction drives which controls are effective.
kms:KeySpec: Reflects the KeySpec property of the key. It’s evaluated both on CreateKey (the requested key spec) and on AWS KMS key resource operations that act on a specific key, including Sign, Verify, and GetPublicKey. This makes kms:KeySpec a reliable lever for both preventing creation of ML-DSA-44 keys and restricting use of existing ones, because it can single out ML_DSA_44 from ML_DSA_65 and ML_DSA_87.
kms:SigningAlgorithm: Reflects the signing algorithm supplied on Sign and Verify, which is ML_DSA_SHAKE_256 for all three variants. It therefore can’t distinguish ML-DSA-44 from the approved variants and shouldn’t be used for this purpose.
The practical consequence: for keys held in AWS KMS, preventing ML-DSA-44 key material from being created is the most robust single control. If no ML-DSA-44 KMS keys exist, none can be used for signing through AWS KMS and none can become the subject key of a certificate. CA keys and TLS server keys are separate material: AWS Private CA generates and holds a CA’s key pair in its own HSMs, and ACM-issued, imported, or uploaded TLS certificates carry their own keys, so those surfaces are governed by the AWS Private CA and certificate controls later in this post. Where ML-DSA-44 KMS keys already exist, their use can additionally be restricted with kms:KeySpec.
Organization and account-level blocking using SCPs
SCPs can be applied at the organization root or to a specific OU to restrict ML-DSA-44. Placement determines the effective scope: it applies organization-wide when attached at the root; attached to an OU, it applies to the accounts within that OU. An SCP is the broadest-scope preventive control available.
Note that SCPs apply to member accounts and OUs but not to the organization’s management account, so avoid running ML-DSA-44-capable workloads in the management account, where an SCP will not restrict them.
The following example SCP denies both the creation of ML-DSA-44 keys (kms:CreateKey) and their use (kms:Sign, kms:Verify, kms:GetPublicKey), matching on the ML_DSA_44 key spec in each case. The creation deny stops new keys from being created; the usage deny covers keys that already exist, whether created before the SCP was attached or living in an account that later joins the OU, because kms:KeySpec is also evaluated at request time on those usage operations.SCPs are guardrails: a Deny in an SCP can’t be overridden by any IAM policy within member accounts.
Attach the following SCP at the organization root (or relevant OU):
Scope the usage deny to the three key-spec-aware actions. Limit the use of Deny to kms:Sign, kms:Verify, and kms:GetPublicKey (testing confirmed kms:KeySpec is evaluated on all three). Avoid a blanket kms:*: a wildcard that would also catch management operations such as DescribeKey, DisableKey, and ScheduleKeyDeletion, which you need to inspect or clean up those same keys, effectively locking you out of managing the keys you’re trying to remove. If you use multi-Region keys, also add kms:ReplicateKey to the creation deny: replicating an ML-DSA-44 primary key creates a new ML-DSA-44 key in another Region, and kms:KeySpec is evaluated on ReplicateKey as well.
Combining with a family-level guardrail. This SCP governs which ML-DSA parameter set is allowed; it says nothing about RSA or ECDSA. Part 1 of this series includes a complementary SCP that denies creation of any signing key whose key spec isn’t ML-DSA. Attached together, they require every new signing key to be ML-DSA and to be an approved variant.
Operational considerations. A blanket Deny at the organization root is the strongest control but has trade-offs: it removes any ability to create ML-DSA-44 keys anywhere in scope, with no exception path, which can block legitimate testing and might cause infrastructure as code (IaC) or pipeline runs that attempt ML-DSA-44 creation to fail. To preserve flexibility, consider scoping the Deny to a production OU and using IAM permission boundaries (see the following section) in build and non-production accounts.
What the caller sees. When an SCP denies a request, the caller receives an AccessDenied error indicating an explicit deny in a service control policy. For same-account and same-organization requests, the error includes the type of the denying policy and, as the enhanced error messages roll out across services, its ARN. The error doesn’t expose the SCP policy contents, and the user being blocked often can’t see the SCPs applied to their environment. Document the SCP ARN and its purpose internally so support teams can map an AccessDenied quickly.
Prevent ML-DSA-44 key creation in AWS KMS (principal-level)
The following IAM policy blocks ML-DSA-44 at the principal level. It is the identity-based counterpart to the SCP shown earlier, useful when you want per-account or per-role control rather than an organization-wide guardrail. Attach it to the IAM role or user you want to constrain.
The condition value is ML_DSA_44 (underscores, not hyphens).
This policy blocks CreateKey only. To also block use of existing ML-DSA-44 keys at the principal level, add the Sign, Verify, and GetPublicKey deny shown in the Restricting use of existing ML-DSA-44 keys section.
For comprehensive, non-overridable coverage, deploy as an SCP rather than relying solely on principal-level policies.
IAM permission boundaries
IAM permission boundaries set the maximum permissions an identity-based policy can grant to an IAM role or user and can be used as an alternative or complement to using SCPs. The effective permissions are the intersection of the identity-based policy and the boundary, and a Deny in a boundary can’t be overridden by an attached policy. Boundaries are useful where you want per-account or per-role flexibility (for example, in build or non-production accounts) rather than a blanket, multi-account deny.
Operational consideration. A permission boundary only takes effect on principals that have it attached. To rely on boundaries as a control, you need a mechanism to enforce the boundary on all IAM principals programmatically. One example enforcement mechanism would be an SCP that denies iam:CreateRole, iam:CreateUser, iam:PutRolePermissionsBoundary, and iam:PutUserPermissionsBoundary unless the approved boundary is set (using the iam:PermissionsBoundary condition key), and denies iam:DeleteRolePermissionsBoundary and iam:DeleteUserPermissionsBoundary outright so the boundary can’t be removed after the fact. You would also want to probe for non-conforming principals periodically and respond, perhaps by automatically attaching the PermissionsBoundary. IAM users shouldn’t be used, but the enforcement should account for the possibility that they exist.
Because a boundary only sets a ceiling and does not itself grant anything, it opens with Allow on all actions, then denies ML-DSA-44 key creation specifically. The following permission boundary denies creation of ML-DSA-44 keys:
To also block use of existing ML-DSA-44 keys for the principals carrying this boundary, add the Sign, Verify, and GetPublicKey deny statement shown in the following section (which also uses kms:KeySpec).
Restricting use of existing ML-DSA-44 keys
As described in the Background section, kms:KeySpec is also evaluated on Sign, Verify, and GetPublicKey, reflecting the KeySpec of the key being used. You can therefore deny those operations when kms:KeySpec equals ML_DSA_44 while continuing to permit ML_DSA_65 and ML_DSA_87. The IAM policy below, attached to an IAM principal, does exactly that.
This deny can also live in an AWS KMS key policy. The same kms:KeySpec deny can be placed directly in the key policy of an AWS KMS key. A key policy is a resource policy, so the statement must include a Principal element. Identity policies and SCPs do not name principals to which they apply. A deny in the key policy is a resource-side backstop that protects a specific key, while an SCP gives non-overridable organization-wide coverage. To turn the previous example into an AWS KMS key policy, add a Principal element to the statement (for example "Principal": {"AWS": "*"}, or a more specific principal), and keep the rest of it the same.
Additional approaches
Depending on your goals you might also want to remove the key material itself rather than only deny its use. Remember that it is difficult to know what data has been signed by a specific key, unless you track that somehow. Deleting a key that was used will make signature verification impossible. Take great care to make sure keys are not used before deleting them.
Disable or schedule deletion of the keys. Disabling stops key use immediately and is reversible. Key deletion is definitive but irreversible after the waiting period, so confirm before scheduling.
Deny Sign, Verify, and GetPublicKey by specific key ARN. You can target named keys rather than the whole key spec. To do this, you would list the exact key ARNs in the Resource element of the IAM policy (no condition key required). This is effective for targeting a single key specifically, but it is difficult to maintain lists of key ARNs. Use this strategy sparingly. If you’re considering using an IAM policy naming a key ARN, remember that a Deny in the key policy of the target key accomplishes the same goal and is attached to the key itself.
Finding existing keys (only needed if you disable or delete). A Deny in an IAM policy or SCP, based on kms:KeySpec, doesn’t require you to know which keys exist – it applies by key spec at request time. If you want to disable or delete existing ML-DSA-44 keys, you need to locate them. AWS KMS has no server-side filter for key spec, so you must enumerate keys with ListKeys and call DescribeKey and inspect each KeySpec. This client-side filtering pattern is common across AWS APIs and is well supported by pagination in the AWS SDKs. You can also use AWS Config to record and query KMS key resources.
Approved ML-DSA variants and control of AWS Private CA
AWS Private CA sets a certificate authority’s (CA’s) signing algorithm at creation time, in the CertificateAuthorityConfiguration parameter of CreateCertificateAuthority (valid values include ML_DSA_44, ML_DSA_65, and ML_DSA_87). There is currently no condition key for the algorithm, so an SCP cannot enforce signing algorithm. The approach in this section controls who can create CAs and pins the algorithm in that trusted path, backed by AWS CloudTrail-based detection.
Recommended approach
Restrict who can create CAs. Deny acm-pca:CreateCertificateAuthority broadly via SCP, and allow it only for a small set of trusted roles or an approved provisioning pipeline. This removes the ability for arbitrary principals to stand up a CA with an unapproved algorithm.
Pin the algorithm in the trusted path. Have that approved pipeline or infrastructure-as-code template hard-code SigningAlgorithm to ML_DSA_65 or ML_DSA_87 in CertificateAuthorityConfiguration. Because AWS Private CA exposes no algorithm condition key, this provisioning path is the enforcement point. Note that the CA’s algorithm pins the signature on the certificates it issues; the subject key in each certificate comes from the CSR, which AWS Private CA copies without validating its algorithm, so pin the CSR key algorithm in the same issuance pipeline.
Control the trust chain. On the PKI side, only add approved CAs to your trust stores and issuance hierarchies, and do not trust or subordinate CAs that could issue ML-DSA-44. This prevents an unapproved CA from being introduced into a trusted path.
Detect drift. Use CloudTrail to capture CreateCertificateAuthority calls and AWS Config to flag any CA whose configuration uses ML_DSA_44, so an unapproved CA is caught quickly.
Part 1 of this series shows what this looks like in practice: it creates an ML-DSA-87 root CA and an ML-DSA-65 subordinate CA with CreateCertificateAuthority, activates them, and distributes the resulting chain to verifiers. In the model described here, those are the calls that only your approved provisioning pipeline is allowed to make.
Setting the ML-DSA value in CertificateAuthorityConfiguration. The same variant goes in both the KeyAlgorithm and SigningAlgorithm fields (for example, KeyAlgorithm=ML_DSA_65 with SigningAlgorithm=ML_DSA_65). Note a difference in signing algorithms between AWS KMS and AWS Private CA. With AWS Private CA, the SigningAlgorithm takes the variant value directly (ML_DSA_44, ML_DSA_65, and ML_DSA_87), and doesn’t accept ML_DSA_SHAKE_256. In contrast, AWS KMS uses ML_DSA_SHAKE_256 as its signing algorithm. Be aware that some older AWS Command Line Interface (AWS CLI) builds omitted descriptions of the ML-DSA variants from the built-in CLI help, so don’t rely on the help in the AWS CLI to determine valid values. For more information, see CertificateAuthorityConfiguration API Reference.
Known limitation. Some surfaces have no algorithm condition key, so you enforce them through provisioning and detection rather than policy. acm-pca:CreateCertificateAuthority has no condition key for the algorithm, and acm:ImportCertificate and iam:UploadServerCertificate are not algorithm-aware, so a disallowed signature setting on a created, imported, or uploaded certificate cannot be blocked by an IAM policy or SCP condition. Govern these through your provisioning process, restrict who can call them, and deny the import and upload actions entirely where they are not required. The controls above remain the available mitigation.
In particular, iam:UploadServerCertificate doesn’t support any method to prevent use of particular algorithms, and AWS doesn’t recommend using this API to generate and upload certificates. This API predates ACM and exists mainly to cover AWS Regions or partitions where ACM is not yet available. While a new Region or partition is being built out, workloads can still need a TLS server certificate before ACM support has shipped there, and uploading a certificate to IAM gives you a place to store and reference it in the meantime. Once ACM is available in that Region, you should use ACM instead. Outside that narrow case, deny iam:UploadServerCertificate unless it is genuinely required.
ACM-issued leaf certificates. A CA’s own key and signing algorithm are separate from the leaf certificates that ACM issues from it. If you use ACM to request leaf certificates, you can constrain the leaf’s key algorithm with the acm:KeyAlgorithm condition key on acm:RequestCertificate. This lets you allow-list approved algorithms for leaf certificates using SCPs or IAM policies, similar to the AWS KMS examples earlier in this post. Be aware that, at the time of writing, ACM doesn’t offer ML-DSA leaf certificates. So a policy like this is a forward-looking defense-in-depth control rather than an immediate ML-DSA-44 risk. The IAM example below is illustrative (using example approved algorithms). Since this is an evolving part of the service, be sure to validate this in your environment before relying on it.
This example uses StringNotEqualsIfExists so it denies only requests that specify a disallowed algorithm. With plain StringNotEquals, a request that omits acm:KeyAlgorithm would also be denied, because the missing key makes the condition evaluate true. Choose the operator that matches whether you want to block requests that leave the algorithm unspecified.
Prevent ML-DSA-44 usage in TLS for NLB and ALB
Elastic Load Balancing, for both network load balancers (NLB) and application load balancers (ALB), terminates TLS on behalf of your applications. The certificates used by these listeners are requested through or imported into ACM, or uploaded to IAM. A listener’s configured security policy and its certificate determine what’s offered during negotiation. At the time of writing, ACM requests and imports accept RSA and ECDSA keys only, and NLB and ALB listeners accept RSA and ECDSA certificates only, so no ML-DSA certificate can be bound to a listener today. As with the ACM leaf-certificate policy earlier, the controls in this section are forward-looking defense in depth rather than a mitigation of an immediate ML-DSA-44 risk.
Certificate controls (the effective mechanism for ML-DSA-44)
Because the listener API calls reference a certificate only by ARN, you can’t write an SCP on CreateListener, ModifyListener, or AddListenerCertificates that inspects the certificate’s algorithm. IAM conditions can’t reference attributes of a separately-referenced resource. Keeping ML-DSA-44 out of TLS therefore relies on there being no ML-DSA-44 certificate material to associate:
Configure your private CA to issue only ML_DSA_65 or ML_DSA_87 certificates, and control who can create CAs.
Prevent ML-DSA-44 key creation in AWS KMS, so that no KMS-held ML-DSA-44 key can become the subject key of a certificate. TLS server keys for ACM-issued, imported, or uploaded certificates are not KMS keys; those are governed by items 1 and 3.
Control imported and uploaded certificates through your provisioning process or deny the import and upload actions where not required, as described in the AWS Private CA section.
Detective controls
CloudTrail records the certificate and listener API calls in this section: certificate creation and import (acm-pca:CreateCertificateAuthority, acm:ImportCertificate, iam:UploadServerCertificate) and listener configuration (CreateListener, ModifyListener, AddListenerCertificates). Whether the algorithm shows up in the event depends on what the call itself carries. Creation calls that take the algorithm as an input record it: kms:CreateKey logs the KeySpec, and acm-pca:CreateCertificateAuthority logs the signing algorithm. That makes CloudTrail effective for catching the creation of ML-DSA-44 key material or a CA. A listener binding references its certificate only by ARN, so the certificate’s algorithm does not appear in that event. To evaluate the algorithm of a bound or imported certificate, use AWS Config resource evaluation as the detective backstop.
Summary for TLS
The primary preventive control is the certificate material itself: with no ML-DSA-44 CA, no ML-DSA-44 KMS key, and certificate import and upload controlled, no ML-DSA-44 certificate can be issued or bound. Where you also operate an allow-list of permitted TLS security policies, the elasticloadbalancing:SecurityPolicy condition key (on CreateListener and ModifyListener) can additionally constrain which TLS policies listeners can use.
Summary of controls
The following table maps the example policy (allow ML-DSA-65 or ML-DSA-87, exclude ML-DSA-44) to the available controls. Modify the controls to limit use to the approved set of algorithms your policies require.
Area
Control
Status
Block ML-DSA-44 key creation (Organization-wide or for all accounts in an organization OU)
SCP on kms:CreateKey using kms:KeySpec
Fully supported via condition key
Block ML-DSA-44 key creation (per account or per role)
IAM policy or permission boundary using kms:KeySpec
Supported; requires programmatic enforcement of boundaries
Block use of existing ML-DSA-44 keys
Deny Sign, Verify, and GetPublicKey using kms:KeySpec (key policy, IAM, or SCP); optionally disable and delete keys
Supported using kms:KeySpec (not kms:SigningAlgorithm)
Only allow approved variants in Private CA
Restrict who can create CAs; pin ML_DSA_65 or ML_DSA_87 in provisioning path
No algorithm condition key; enforce using process and detection
Limit variants in imported or uploaded TLS certificates
Process controls, or deny import or upload APIs (prefer ACM over iam:UploadServerCertificate)
APIs aren’t algorithm-aware
Block use of ML-DSA-44 in TLS with network load balancers (NLB) and application load balancers (ALB)
Restrict TLS policy using elasticloadbalancing:SecurityPolicy; control cert material
TLS-policy restriction supported; no per-cert algorithm condition
Detect use of unapproved variants
CloudTrail (API-level) and AWS Config custom rules
Supported using custom AWS Config rules; not managed rules
Conclusion
In this post, you learned how to use ML-DSA as an example of turning a cryptographic algorithm policy into enforceable AWS controls. The key lever is the kms:KeySpec condition key: it keeps your approved parameter sets (ML-DSA-65 and ML-DSA-87) fully usable while preventing the creation and use of a parameter set you’ve excluded (ML-DSA-44) on the CreateKey, in addition to the Sign, Verify, and GetPublicKey operations, where kms:SigningAlgorithm can’t tell the variants apart. Applied as defense in depth across SCPs, IAM policies, permission boundaries, and KMS key policies, and extended to the surfaces that have no algorithm condition key (AWS Private CA, certificate import, and Elastic Load Balancing TLS) through provisioning controls plus AWS CloudTrail and AWS Config drift detection, these controls give you a consistent way to keep an unapproved variant out of your accounts.
The pattern isn’t specific to ML-DSA-44. Because your algorithm policy will change as standards and your own requirements evolve, treat these controls as a reusable template and re-point the same condition keys and guardrails at whatever your approved set becomes. This adaptability is the practical meaning of cryptographic agility: changing what you allow without re-engineering how you enforce it.
To see the workloads these controls govern, read Part 1 of this series, which builds a complete ML-DSA signing pipeline, from key creation and PKI through artifact signing and verification, using the approved set enforced here.
Software supply chain attacks have grown in both frequency and sophistication. Recent high-profile compromises of build systems and open source dependencies demonstrate that attackers increasingly target the trust mechanisms that verify software integrity. Those trust mechanisms rely on digital signature algorithms, and today many use traditional algorithms such as Rivest-Shamir-Adleman (RSA) and the Elliptic Curve Digital Signature Algorithm (ECDSA). If a sufficiently powerful quantum computer could forge these signatures, an attacker could potentially inject unauthorized code into signed artifacts, fabricate build attestations, or impersonate legitimate publishers. Using quantum-resistant signatures today defends against threats that might emerge in the future.
Since 2025, the Commercial National Security Algorithm Suite 2.0 (CNSA 2.0), published by the US National Security Agency (NSA), has required US National Security Systems (NSS) to “support and prefer” quantum-resistant signatures for software and firmware, with exclusive use mandated by 2030. The EU Cyber Resilience Act (CRA) takes full effect in December 2027. It requires manufacturers to maintain verifiable software integrity throughout a product’s lifecycle. Organizations that ship software to US federal agencies or sell products in the European market face converging deadlines that demand action now.
This post is Part 1 of a two-part series on adopting ML-DSA signatures, standardized in NIST FIPS 204 (ML-DSA) signatures, on AWS. As of Oct 2026, this series is the first end-to-end guide from any cloud provider for post-quantum signing across the software supply chain, from establishing an ML-DSA root of trust to enforcing algorithm policy across an organization. This part is for builders and walks through constructing and operating the signing pipeline. Part 2, Enforce your ML-DSA algorithm policy with SCPs and IAM, is for security and governance teams and shows how to turn the algorithm choices made here into preventive and detective controls across an organization.
Understanding the harvest now, forge later threat
After a cryptographically relevant quantum computer (CRQC) exists, the mathematical problems protecting today’s public-key cryptography can be solved efficiently. Attacks that are impractical today because of the computational complexity suddenly become practical using a CRQC. Most discussions of post-quantum cryptography (PQC) focus on the harvest now, decrypt later threat to data confidentiality. The asymmetric keys protecting data in transit can be efficiently derived using a CRQC, exposing the data that was meant to be protected. Digital signatures rely on the same asymmetric mathematical problems that a CRQC would break. This means that software supply chains face a parallel threat that targets integrity rather than confidentiality. An attacker who records signed artifacts today can forge those signatures in the future on a totally different artifact, using a CRQC.
Consider firmware signed with ECDSA P-256 and deployed to a fleet of embedded devices in 2026. These devices verify the firmware signature on every boot for their 15-year operational lifetime and can’t be recalled to re-sign after deployment. If a CRQC becomes operational in 2035, an attacker could produce a valid-looking signature over tampered firmware, and every device in the fleet would accept it as authentic on next restart. For organizations that rely on classical digital signatures as the primary mechanism for verifying software integrity, this weakens a critical link in the verification chain. This is why CNSA 2.0 specifies aggressive timelines for digital signatures: the artifacts you sign today must remain trustworthy for their full operational lifetime.
ML-DSA is designed to resist attacks from both classical and quantum computers. AWS KMS, AWS Private CA, and AWS IAM Roles Anywhere all support ML-DSA, making it possible to address the forge-later threat across your supply chain today without additional tooling.
Architecture overview: Five pillars of a quantum-resistant supply chain
The architecture comprises five trust pillars that together protect your software delivery pipeline:
ML-DSA key management in AWS KMS – All signing keys are generated and protected in FIPS 140-3 Security Level 3 hardware security modules (HSMs). Private keys never leave the HSM boundary.
ML-DSA public key infrastructure (PKI) throughAWS Private CA – A certificate hierarchy (root CA, subordinate CA, end-entity certificates) binds ML-DSA public keys to identities, establishing who signed what. CA private keys are generated and stored in hardware-protected HSMs managed by the service and never leave the HSM boundary.
Quantum-resistant workload identity (for external build agents) – For continuous integration and delivery (CI/CD) agents running outside AWS that authenticate through X.509 certificates, IAM Roles Anywhere with ML-DSA certificates ties the signer’s identity back to the same quantum-resistant root of trust.
ML-DSA SBOM integrity attestation – The SBOM for each release is wrapped in an in-toto Statement that names the artifact it describes by digest, and the Statement is signed with the same ML-DSA code-signing key. This provides quantum-resistant proof that the dependency manifest hasn’t been tampered with and that it belongs to the artifact it accompanies.
These pillars create a chain of trust: AWS Private CA protects the root CA key in its own HSMs, issues certificates that bind identities to AWS KMS code-signing keys, IAM Roles Anywhere uses those certificates to authenticate build agents, and authenticated agents sign every artifact and SBOM they produce.
Figure 1: End-to-end quantum-resistant software supply chain on AWS
Figure 1 illustrates this architecture in four layers, numbered in the order you build them:
Root of trust (Pillars 1 and 2) – Establish your AWS Private CA hierarchy and create your code-signing key in AWS KMS.
Workload identity (Pillar 3) – Register the CA as an IAM Roles Anywhere trust anchor and issue ML-DSA certificates to build agents, ensuring the signer’s identity chains back to the same quantum-resistant root of trust.
Artifact signing (Pillars 4 and 5) – Sign binaries, container images, and SBOMs using the authenticated build agent.
Verification and enforcement – Validate signatures at deployment and enforce ML-DSA-only policies.
Prerequisites
To follow along, you need:
An AWS account with permissions to create resources in AWS KMS, AWS Private CA, IAM Roles Anywhere, and Amazon ECR.
IAM Roles Anywhere credential helper (aws_signing_helper) v1.8.0 or later, the first release that supports ML-DSA keys and certificates, for workload authentication. Download from the IAM Roles Anywhere documentation.
OpenSSL 3.5 or later (required for ML-DSA signature verification and mu computation).
ORAS CLI v1.2 or later (for attaching Open Container Initiative (OCI) referrer artifacts to container images). Alternatively, you can use the Notation CLI with a custom plugin or any OCI-compliant client that supports the OCI Referrers API.
jq, for constructing and parsing the in-toto Statements used for SBOM attestation and for parsing ORAS output.
Amazon Inspector SBOM Generator (Sbomgen), or another tool that produces a CycloneDX JSON SBOM, for the SBOM example. Sbomgen runs only on Linux (x86-64 and ARM64), so run that step on a Linux build agent or container. It uses the registry credentials that oras login stores in the Docker config file, and it also accepts them through --username or the INSPECTOR_SBOMGEN_USERNAME and INSPECTOR_SBOMGEN_PASSWORD environment variables.
Java 11 or later and Apache Maven, to run the diy-code-signing-kms-private-ca sample that produces the code-signing CSR in Step 4 of Building the ML-DSA PKI foundation.
A container image pushed to Amazon ECR (for the container signing example).
Building the ML-DSA PKI foundation
Start by creating the certificate hierarchy that will anchor your supply chain trust. AWS Private CA generates and stores its own CA signing keys internally in hardware-protected HSMs when you create a certificate authority. Use ML-DSA-87 (NIST security category 5, defined as at least as hard to break as exhaustive key search on AES-256) for the root CA because it protects the longest-lived trust anchor. Use ML-DSA-65 (NIST security category 3) for the subordinate CA to balance security with smaller signature sizes for frequently issued certificates.
The parameter sets used here, ML-DSA-87 and ML-DSA-65, are also the approved set in the example algorithm policy that Part 2 of this series turns into enforceable controls. If your organization has standardized on a different set, substitute it in the commands that follow; the build steps don’t change.
Step 1: Create the root CA in AWS Private CA
When you specify KeyAlgorithm: ML_DSA_87, Private CA generates an ML-DSA-87 key pair internally. You don’t need to create a separate AWS KMS key for the CA.
After creation, the root CA is in PENDING_CERTIFICATE state. Activate it by self-signing its certificate. This is where you set the root CA’s validity period (10 years is typical for a root):
After creation, the subordinate CA enters PENDING_CERTIFICATE state with no link to the root. Activate it by signing its certificate signing request (CSR) with the root CA:
# Retrieve the subordinate CA's certificate signing request
aws acm-pca get-certificate-authority-csr \
  --certificate-authority-arn <sub-ca-arn> \
  --output text > sub-ca.csr

# Sign the CSR using the root CA (this establishes the trust hierarchy)
SUB_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --csr fileb://sub-ca.csr \
  --signing-algorithm ML_DSA_87 \
  --validity Value=1825,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/SubordinateCACertificate_PathLen0/V1 \
  --query CertificateArn --output text)

# Retrieve the signed certificate and import it to activate the subordinate CA
aws acm-pca get-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --certificate-arn $SUB_CERT_ARN \
  --query Certificate --output text > sub-ca-cert.pem

aws acm-pca import-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate fileb://sub-ca-cert.pem \
  --certificate-chain fileb://root-ca-cert.pem
Step 3: Create the code-signing key in AWS KMS
Your build agents use this key to sign artifacts, so their IAM roles need the kms:Sign permission on it. The end-entity certificate issued by your subordinate CA binds an identity to this key’s public key.
Step 4: Issue the end-entity code signing certificate
To issue a certificate, you need a CSR. Because the ML-DSA private key never leaves the AWS KMS HSM, you can’t generate the CSR locally with OpenSSL. Instead, you construct the CSR’s TBS (to-be-signed) structure containing your subject name and public key, sign it remotely by calling aws kms sign, and assemble the final CSR from those components.
For a working implementation that assembles an ML-DSA CSR around a KMS-managed private key and signs it with AWS KMS, see Post-quantum (ML-DSA) code signing with AWS Private CA and AWS KMS and its diy-code-signing-kms-private-ca sample on GitHub (Java, built with Maven). There is no AWS CLI-only path for this step: the CSR must be constructed and signed in code, and the sample is the reference implementation.
After you have the code-signing.csr file, issue the certificate from your subordinate CA:
# Issue a code-signing certificate valid for one year, signed by the subordinate CA using ML-DSA-65.
# Replace <sub-ca-arn> with the ARN that create-certificate-authority returned for the subordinate CA in Step 2.
CODE_SIGNING_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --csr fileb://code-signing.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=365,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/CodeSigningCertificate/V1 \
  --query CertificateArn --output text)

# Retrieve the issued certificate
aws acm-pca get-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-arn $CODE_SIGNING_CERT_ARN \
  --query Certificate --output text > code-signing-cert.pem
This certificate binds the signer identity to the AWS KMS code-signing key material. Note that the certificate validity period (365 days in this example) determines how long verifiers can validate signatures by checking the certificate alone. AWS Private CA lets you choose the validity period of an issued certificate, as long as it ends no later than the issuing CA’s own certificate; in this example the subordinate CA certificate from Step 2 is valid for 1,825 days, so the three-year option below fits inside it. For artifacts that must remain verifiable beyond the certificate’s expiry, consider these approaches:
Longer certificate validity – For private PKI, code-signing certificates are commonly issued with multi-year validity (for example, Value=1095,Type=DAYS for 3 years) because you control the issuance policy.
Trusted timestamping (RFC 3161) – Countersign each signature with an RFC 3161 timestamp from a Time Stamping Authority (TSA) at signing time. The timestamp proves the signature was created while the certificate was valid, allowing verification indefinitely. AWS doesn’t provide a managed TSA; use a third-party TSA or operate your own.
Re-signing – Before a certificate expires, re-sign active artifacts with a newly issued certificate.
Distribute the certificate chain (root CA certificate, subordinate CA certificate, and end-entity certificate) to systems that need to verify your signatures.
Signing artifacts with ML-DSA in your CI/CD pipeline
With the PKI hierarchy in place, integrate ML-DSA signing into your build process. The approach depends on artifact type. ML-DSA-65 signatures are 3,309 bytes (compared to 64 bytes for ECDSA P-256), and the latency of the AWS KMS Sign operation for ML-DSA is comparable to existing asymmetric operations. The larger signature size has negligible impact when stored alongside multi-megabyte container images or packages, but is worth accounting for in size-constrained environments like embedded device images transmitted over low-bandwidth links.
Binary and package signing
Most build outputs, including compiled binaries and packages, are far larger than the 4,096-byte limit that AWS KMS places on the message passed to aws kms sign. Make the EXTERNAL_MU method your pipeline’s default: compute the 64-byte message representative (mu) externally with OpenSSL 3.5, then pass only mu to AWS KMS. This handles an artifact of any size and never needs to change as your artifacts grow. AWS KMS also accepts content directly with --message-type RAW, up to 4,096 bytes. Use RAW only for inputs whose size is fixed by construction, such as the 71-character manifest digest in the container image example that follows. An artifact that fits today is likely to outgrow the limit later, and a pipeline that depends on RAW fails when it does. Both methods produce cryptographically identical signatures. The verifier doesn’t need to know which method was used; standard ML-DSA verification applies in either case.
# Retrieve the public key
aws kms get-public-key --key-id alias/pqc-code-signing \
  --query PublicKey --output text | base64 --decode > pk.der

# Extract raw public key bytes from the DER-encoded SubjectPublicKeyInfo.
# The BIT STRING starts at offset 17 for all ML-DSA key sizes.
# Expected output: 1,312 bytes (ML-DSA-44), 1,952 bytes (ML-DSA-65), or 2,592 bytes (ML-DSA-87).

openssl asn1parse -inform DER -in pk.der -strparse 17 -noout -out pk_raw.bin

# Compute mu per FIPS 204 Section 6.2
printf '\x00\x00' | cat - artifact.bin > m_prime.bin
openssl dgst -shake256 -xoflen 64 -binary pk_raw.bin > pk_hash.bin
cat pk_hash.bin m_prime.bin | openssl dgst -shake256 -xoflen 64 -binary > mu.bin

# Sign the mu value
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > artifact.bin.sig
Store the .sig file alongside the artifact in Amazon S3 or your package repository. Protect the integrity of both the artifact and its signature by enabling S3 Object Lock (WORM protection) or at minimum S3 Versioning with restricted write access. If an attacker can modify or delete either file, verification can’t be trusted. For comprehensive guidance, see Security best practices for Amazon S3.
Container image signing
For container image signing, use the OCI referrer pattern, defined in the OCI Image and Distribution Specifications v1.1. A referrer is an artifact, such as a signature or an SBOM, whose manifest names another image in its subject field. Registries that support the pattern, including Amazon ECR, return these artifacts when a client asks for an image’s referrers. This approach uses AWS KMS ML-DSA keys to generate the signature and stores it as a referrer of the image:
# Repository URI used by ORAS here and in the SBOM steps; replace the account ID and Region
ECR_URI=111122223333.dkr.ecr.us-east-1.amazonaws.com/myapp

# Authenticate ORAS to Amazon ECR
aws ecr get-login-password --region us-east-1 | \
  oras login --username AWS --password-stdin 111122223333.dkr.ecr.us-east-1.amazonaws.com

# Get the image manifest digest
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)

# Sign the digest. It is a fixed 71 characters, so RAW is safe here (see Binary and package signing).
# AWS CLI v2 expects blob parameters to be base64, so write the digest to a file and pass it with fileb://
echo -n "$IMAGE_DIGEST" > digest.txt
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://digest.txt \
  --message-type RAW \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > image.mldsa.sig

# Attach signature as OCI referrer using ORAS
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" \
  image.mldsa.sig:application/octet-stream
At deployment time, your admission controller retrieves the referrer artifact and verifies the ML-DSA signature before allowing the image to run. See Verifying a container image signature before deployment later in this post for the full verification workflow and admission control implementation.
SBOM signing
A software bill of materials (SBOM) is a structured inventory of every component, library, and dependency included in a software release. It lists package names, versions, suppliers, and dependency relationships. Organizations use SBOMs to track vulnerabilities, verify license compliance, and respond quickly when a compromised component is disclosed.
Signing the SBOM file on its own proves that the inventory hasn’t been tampered with since it was signed, but not which artifact it describes. If the image signature and the SBOM signature are independent of each other, an attacker who holds a legitimately signed SBOM for a clean image can present it alongside a different signed image and claim that the two correspond. Attaching the SBOM to the image as an OCI referrer doesn’t close this gap by itself, because the subject field of a referrer manifest is set by whoever pushes the referrer; it’s a discovery mechanism, not a cryptographic binding. The binding must be inside the bytes that the signature covers.
To create that binding, wrap the SBOM in an in-toto Statement before signing it. A Statement names the artifacts it describes in its subject field, by digest, and carries the SBOM as its predicate. Because the image manifest digest is part of the signed content, a verifier can confirm that the SBOM in hand was issued for exactly the image it is about to deploy, and a swapped SBOM or a swapped digest fails verification. Embedding the SBOM in the image filesystem is another way to bind the two, because the image digest then covers the SBOM bytes. This post uses the Statement approach because it also works for SBOMs generated by scanning a finished image, for artifacts that have no filesystem such as binaries and firmware, and for images that are already in your registry, and because the SBOM stays readable from the registry without pulling the image.
Generate the SBOM with your preferred tool (such as Amazon Inspector SBOM Generator (Sbomgen) for container images), wrap it in a Statement, and sign the Statement with the same EXTERNAL_MU step you use for binaries:
# Scan the pushed image by digest so the inventory describes exactly the manifest you signed.
# Sbomgen reuses the registry login from the oras login step in the previous section.
inspector-sbomgen container --image $ECR_URI@$IMAGE_DIGEST -o sbom.json

# Wrap the SBOM in an in-toto Statement whose subject is the image manifest digest.
# This puts the digest inside the signed bytes, which binds this SBOM to this image.
jq -n \
  --arg name "$ECR_URI" \
  --arg digest "${IMAGE_DIGEST#sha256:}" \
  --slurpfile sbom sbom.json \
  '{
    "_type": "https://in-toto.io/Statement/v1",
    "subject": [{"name": $name, "digest": {"sha256": $digest}}],
    "predicateType": "https://cyclonedx.org/bom",
    "predicate": $sbom[0]
  }' > sbom.statement.json

# Sign using EXTERNAL_MU (same mu computation as binary signing above,
# with sbom.statement.json as the input)
# ... compute mu from sbom.statement.json ...
aws kms sign \
  --key-id alias/pqc-code-signing \
  --message fileb://mu.bin \
  --message-type EXTERNAL_MU \
  --signing-algorithm ML_DSA_SHAKE_256 \
  --query Signature --output text | base64 --decode > sbom.statement.json.sig

# Attach the Statement and its signature to the image as an OCI referrer so
# verifiers discover them alongside the image signature
oras attach $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" \
  sbom.statement.json:application/vnd.in-toto+json \
  sbom.statement.json.sig:application/octet-stream
Ship the Statement and its .sig file together; the SBOM itself is the Statement’s predicate field, and verifiers extract it after verification. The same pattern binds an SBOM to a binary or package: set the subject digest to the SHA-256 of the file instead of an image manifest digest. The Verifying a binary or SBOM signature section later in this post walks through the full verification workflow, including the subject check that completes the binding.
Quantum-resistant workload identity for build agents
Signing artifacts with ML-DSA keys addresses the integrity of the artifacts themselves. Separately, build agents running outside AWS (on-premises Jenkins, self-hosted GitHub Actions runners, or third-party CI/CD systems) authenticate using X.509 certificates or OIDC tokens typically signed with RSA or ECDSA. These authentication credentials represent a classical cryptographic dependency in the pipeline. IAM Roles Anywhere with ML-DSA certificates replaces that dependency: the credential that the external build agent presents, and the CA that vouches for it, no longer rely on algorithms that are vulnerable to quantum attack. (The TLS connection that carries the request still authenticates the AWS endpoint with a traditional certificate, as public TLS does today; that is a transport concern separate from the signing identity this post is about.) Build agents running on AWS with an attached IAM role don’t have this dependency: their API requests are authenticated with AWS Signature Version 4 (SigV4), which uses a symmetric hash-based message authentication code (HMAC-SHA256). Symmetric schemes like this are already considered quantum-resistant, so no additional action is needed.
Step 1: Register a workload identity CA as a trust anchor
For this walkthrough, reuse the subordinate CA that you created earlier; that avoids the monthly charge for a second CA, and the commands that follow assume it. In production, use a dedicated subordinate CA for workload identity certificates, separate from your code-signing CA. This limits the blast radius if either CA is compromised and has to be revoked, and it lets you apply different issuance policies to the two certificate types.
# Use the ARN that create-certificate-authority returned when you created the
# subordinate CA earlier. If you no longer have it, list your CAs and copy the
# ARN of the SUBORDINATE one.
aws acm-pca list-certificate-authorities \
  --query "CertificateAuthorities[?Type=='SUBORDINATE'].[Arn,Status,CertificateAuthorityConfiguration.Subject.CommonName]" \
  --output table
SUB_CA_ARN=arn:aws:acm-pca:us-east-1:111122223333:certificate-authority/abc-123   # replace with yours

# Register the subordinate CA as an IAM Roles Anywhere trust anchor
aws rolesanywhere create-trust-anchor \
  --name "PQC-CI-CD-Trust-Anchor" \
  --source "sourceType=AWS_ACM_PCA,sourceData={acmPcaArn=$SUB_CA_ARN}" \
  --enabled
Step 2: Create the build agent role and a profile that references it
An IAM Roles Anywhere profile specifies which IAM roles a workload can assume after it authenticates with a certificate from your trust anchor. Create the role first. Its trust policy lets IAM Roles Anywhere assume it only through your trust anchor and only for a certificate whose subject common name identifies the build agent; without those conditions, any certificate that the trust anchor CA issues could assume the role. Its permissions policy grants only what signing requires, on only the code-signing key. Save the trust policy as build-agent-trust.json, replacing the trust anchor ARN with the one that create-trust-anchor returned in Step 1:
Save the permissions policy as build-agent-permissions.json, replacing the resource with your key’s ARN (aws kms describe-key --key-id alias/pqc-code-signing --query KeyMetadata.Arn --output text):
Step 3: Issue the build agent certificate and configure the credential helper
Generate the build agent’s ML-DSA-65 key pair and CSR locally with OpenSSL, have the subordinate CA issue a client authentication certificate for it, and then configure the IAM Roles Anywhere credential helper to present that certificate:
# Generate the build agent's key pair and CSR. The CN must match the
# aws:PrincipalTag/x509Subject/CN condition in the role's trust policy.
openssl genpkey -algorithm ML-DSA-65 -out build-agent-mldsa-key.pem
chmod 400 build-agent-mldsa-key.pem
openssl req -new -key build-agent-mldsa-key.pem \
  -subj "/C=US/O=Example Corp/CN=pqc-build-agent-01" \
  -out build-agent.csr

# Issue a 30-day client authentication certificate from the subordinate CA
# registered as the trust anchor in Step 1.
BUILD_AGENT_CERT_ARN=$(aws acm-pca issue-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --csr fileb://build-agent.csr \
  --signing-algorithm ML_DSA_65 \
  --validity Value=30,Type=DAYS \
  --template-arn arn:aws:acm-pca:::template/EndEntityClientAuthCertificate/V1 \
  --query CertificateArn --output text)

aws acm-pca get-certificate \
  --certificate-authority-arn $SUB_CA_ARN \
  --certificate-arn $BUILD_AGENT_CERT_ARN \
  --query Certificate --output text > build-agent-mldsa.pem

# In production, store the private key in a TPM or HSM rather than as a plaintext file.
aws_signing_helper credential-process \
  --certificate build-agent-mldsa.pem \
  --private-key build-agent-mldsa-key.pem \
  --trust-anchor-arn arn:aws:rolesanywhere:us-east-1:111122223333:trust-anchor/ta-id \
  --profile-arn arn:aws:rolesanywhere:us-east-1:111122223333:profile/profile-id \
  --role-arn arn:aws:iam::111122223333:role/PQCBuildAgentRole
The helper produces short-lived AWS Security Token Service (AWS STS) credentials scoped to the build role, replacing long-lived AWS access keys. In production, protect the ML-DSA private key with hardware-backed storage such as a Trusted Platform Module (TPM), an HSM, or an encrypted credential store with restricted file permissions. The plaintext file path shown here is for demonstration purposes. The private key authorizes access to your code-signing infrastructure and should be treated with the same protection level as any signing key. On Linux build agents, at minimum restrict the file to chmod 400 owned by the service account and consider using a PKCS#11 provider to avoid storing the raw key on disk entirely.
Verification and policy enforcement
A signing architecture is only as strong as its verification. Producing signatures is half the story. The other half is giving the systems and people that deploy your artifacts, such as deployment pipelines, Kubernetes admission controllers, and engineers installing a package, a concrete way to verify those signatures and make trust decisions before an artifact is deployed or run.
Distributing your trust chain
Before any verifier can check a signature, it needs to trust the CA that issued the code-signing certificate. This trust is established through a trust store: a local collection of root CA certificates that a system treats as authoritative. Trust stores exist in operating systems (such as /etc/pki/ca-trust/ on Linux, Keychain on macOS), language run-times (Java cacerts), container base images, and custom application configurations.
For private PKI hierarchies like the one in this post, your root CA certificate isn’t in any default public trust store. You must explicitly add it to the trust stores of every system that will verify your signatures. Common approaches include:
Baking the root CA certificate into your container base images during the build process
Publishing it to an internal S3 bucket with versioning and access logging
Storing it as an OCI artifact in Amazon ECR alongside the images it protects
Treat trust store management with the same rigor as credential management. If an attacker can inject a rogue root certificate into your trust stores, they can make forged signatures appear valid. Restrict write access to trust stores and audit changes through AWS CloudTrail or your system-level audit logs.
Exporting your certificate chain requires exporting the root CA, and then any subordinate CAs that issue certificates that will be involved in verifying signatures:
# Export the root CA certificate
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <root-ca-arn> \
  --query Certificate --output text > root-ca.pem

# Export the subordinate CA certificate. Select only the Certificate field: for a
# subordinate CA this call also returns CertificateChain, and --output text would
# print both on one tab-separated line, producing a file that OpenSSL can't parse.
aws acm-pca get-certificate-authority-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --query Certificate --output text > sub-ca.pem

# Bundle the full chain for verifiers
cat root-ca.pem sub-ca.pem > trust-chain.pem
Verifiers use this chain to confirm that the code-signing public key was issued by a CA they trust.
The CAs in this post are created without a revocation configuration, and the verification commands that follow don’t check revocation status, which keeps the walkthrough short. In production, configure a certificate revocation list (CRL) or an Online Certificate Status Protocol (OCSP) responder on the subordinate CA (see Plan your AWS Private CA certificate revocation method in the AWS Private CA User Guide; both work with ML-DSA CAs). If you use a CRL, distribute it alongside the trust chain and add -crl_check -CRLfile <crl-file> to the openssl verify command below, where <crl-file> is the CRL that AWS Private CA publishes to your S3 bucket, so that a revoked code-signing certificate fails verification.
Verifying a binary or SBOM signature
Verify the code-signing certificate against the trust chain, confirm that it is a code-signing certificate issued to the signer you expect, extract its public key, and then verify the signature with OpenSSL 3.5. The second check matters: a chain check alone accepts every certificate that the CA hierarchy has issued, including the build agent client certificates from the previous section, so pin the expected subject in your verifier configuration:
# Step 1: Verify that the code-signing certificate chains to the trusted root CA and carries the
# Code Signing extended key usage. -purpose codesign (OpenSSL 3.2 and later) rejects a certificate
# that chains correctly but was issued for another purpose, such as a build agent's client
# authentication certificate from the same subordinate CA.
# trust-chain.pem contains the root CA and subordinate CA certificates distributed in the previous section.
openssl verify -CAfile trust-chain.pem -purpose codesign code-signing-cert.pem
# Confirm that the certificate was issued to the signer you expect. Replace <signer-cn> with the
# common name in your code-signing certificate's subject.
openssl x509 -in code-signing-cert.pem -noout -subject -nameopt RFC2253 | grep -q "CN=<signer-cn>" || { echo "Unexpected signer"; exit 1; }

# Step 2: Extract the public key from the verified certificate.
openssl x509 -in code-signing-cert.pem -pubkey -noout > signing-key.pem

# Step 3: Verify the artifact signature using the trusted public key.
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in artifact.bin \
  -sigfile artifact.bin.sig \
  -rawin
A successful verification prints Signature Verified Successfully and returns an exit status of 0. A failed verification prints Signature Verification Failure and returns a nonzero exit status. In shell scripts, check the exit status of each command, or run the block with set -e, so that a failed certificate chain check stops the script before signature verification and a failed signature check blocks downstream actions.
For an SBOM, run the same three steps with sbom.statement.json as the -in file and sbom.statement.json.sig as the -sigfile, then add a fourth: confirm that the subject digest inside the verified Statement is the digest of the artifact you are about to deploy. Signature verification proves the Statement is authentic; the subject check proves it describes this artifact and not another one. The digest you compare against must come from the artifact itself, resolved from the registry for an image or computed from the file for a binary, never from the Statement. For an image, this is the same digest you verify the image signature against, so the two checks together establish that this SBOM describes this signed image.
# Step 4 (SBOM only): the signed Statement must name the image being deployed.
# Resolve the digest from Amazon ECR, not from the Statement.
IMAGE_DIGEST=$(aws ecr batch-get-image \
  --repository-name myapp \
  --image-ids imageTag=v1.2.0 \
  --query 'images[0].imageId.imageDigest' --output text)
SUBJECT_DIGEST=$(jq -r '.subject[0].digest.sha256' sbom.statement.json)
[ "sha256:$SUBJECT_DIGEST" = "$IMAGE_DIGEST" ] || { echo "SBOM does not describe this image"; exit 1; }

# Only now extract the SBOM for downstream tooling
jq '.predicate' sbom.statement.json > sbom.json
For a binary, compare the subject digest to the output of sha256sum artifact.bin instead. Reject the SBOM if either the signature or the subject check fails.
Verifying a container image signature before deployment
Pull the ML-DSA signature from the OCI referrer artifact in Amazon ECR, then verify it against the image manifest digest:
# Pull the signature referrer. ORAS 1.2 lists referrers under "manifests";
# ORAS 1.3 and later list them under "referrers". The jq filter accepts either.
oras discover $ECR_URI@$IMAGE_DIGEST \
  --artifact-type "application/vnd.example.mldsa-signature.v1" --format json | \
  jq -r '(.referrers // .manifests)[0].digest' | \
  xargs -I{} oras pull $ECR_URI@{} -o /tmp/sig/

# Re-derive the image digest and verify
echo -n "$IMAGE_DIGEST" > /tmp/digest.txt
openssl pkeyutl -verify \
  -pubin -inkey signing-key.pem \
  -in /tmp/digest.txt \
  -sigfile /tmp/sig/image.mldsa.sig \
  -rawin

# Exit code 0 = image is authentic; non-zero = reject deployment
The same oras discover command with --artifact-type "application/vnd.example.mldsa-sbom-attestation.v1" retrieves the SBOM attestation and its signature; verify them as described in the previous section, including the subject check. The jq filter shown takes the first referrer of the requested type. Don’t rely on the order in which a registry lists referrers, and expect more than one after an image has been re-signed: a production verifier should check every referrer of that type and accept the image if at least one signature verifies against a certificate that chains to your trust store. Taking only the first can reject a correctly signed image, but it can never accept an unsigned one.
To enforce these checks at deployment time, run them in a Kubernetes admission controller, a component that the API server calls before it accepts a pod and that can reject the request. You can write one as a validating admission webhook (see Dynamic Admission Control in the Kubernetes documentation), or use Open Policy Agent (OPA) Gatekeeper, an admission webhook that enforces policies evaluated by the OPA policy engine, and package the verification steps as a Gatekeeper external data provider that a constraint calls. For a worked example of gating Amazon EKS deployments on image signatures, see Announcing Container Image Signing with AWS Signer and Amazon EKS, which verifies AWS Signer signatures at admission with Kyverno and discusses the Gatekeeper and custom webhook alternatives. The ML-DSA signature referrer in this post is a custom artifact type that those tools don’t verify out of the box, so the verification steps in this section run in code you supply. In either design, the controller runs before any pod is scheduled, rejecting images that lack a valid ML-DSA signature referrer in Amazon ECR or whose SBOM attestation doesn’t name the image being deployed.
Preventive and detective controls
Signature verification stops the use of an untrusted artifact at deployment. Organization-level controls apply earlier and more broadly: preventive controls stop teams from creating new traditional signing keys, and detective controls record every signing operation so you can audit which principal signed each artifact and when.
Preventive guardrails. Use an AWS OrganizationsService control policy (SCP) to block creation of traditional signing keys in security-critical accounts, forcing all new signing workloads to use ML-DSA:
This SCP prevents teams from creating new RSA or ECDSA signing keys, enforcing quantum-resistant signatures as the only option for new workloads. Note that this SCP constrains the algorithm family, not the parameter set: it would still permit an ML-DSA-44 key, which this architecture doesn’t use. Part 2 of this series picks up at exactly this point. It shows how to express a complete algorithm policy (in its example, approve ML-DSA-65 and ML-DSA-87 and exclude ML-DSA-44) as layered controls using the kms:KeySpec condition key in SCPs, IAM permission boundaries, and AWS KMS key policies; how to restrict the use of keys that already exist; and how to govern surfaces such as AWS Private CA that have no algorithm condition key. This SCP and the parameter-set SCP in Part 2 work together: attach both, and every new signing key must use an approved parameter set.
Audit trail.AWS CloudTrail logs every kms:Sign and kms:Verify API call, providing an immutable record of when each artifact was signed and by which principal. Use an organization trail and query its logs with Amazon Athena to analyze signing activity across accounts and correlate it with your deployment events.
Regulatory timeline and recommended actions
The following table maps regulatory milestones to specific actions you can take today using the architecture described in this post. This information is provided for general awareness only and does not constitute legal or compliance advice. Consult your legal and compliance teams to determine your organization’s specific obligations. For a broader overview of global PQC regulatory timelines, see Migrating to Post-Quantum Cryptography.
Regulation
Deadline
Regulatory language
Action on AWS
CNSA 2.0: Support and prefer
2025 (in effect)
CNSA 2.0 timeline (Sep 2022, FAQ v2.1 Dec 2024): Software and firmware signing must “support and prefer” CNSA 2.0 algorithms by 2025
Create ML-DSA keys in AWS KMS, begin signing artifacts with ML-DSA alongside existing traditional signatures
CNSA 2.0: New system acquisitions
January 2027
CNSA 2.0 FAQ v2.1 (Dec 2024): “All new NSS acquisitions must be CNSA 2.0 compliant at deployment, effective 1 January 2027”
Full ML-DSA PKI operational, IAM Roles Anywhere trust anchors using ML-DSA, all new builds carry ML-DSA signatures
EU Cyber Resilience Act
11 December 2027
Regulation (EU) 2024/2847, Annex I, Part I(2)(f): Products must “protect the integrity of stored, transmitted or otherwise processed data, personal or other, commands, programs and configuration against any manipulation or modification not authorised by the user, and report on corruptions”; Part II(7): Manufacturers must “provide for mechanisms to securely distribute updates”
ML-DSA code signing for all software updates shipped to EU markets, signed SBOMs accompany every release
CNSA 2.0: Exclusive use
2030
CNSA 2.0 timeline: Software and firmware signing must “exclusively use” CNSA 2.0 algorithms by 2030
Remove traditional signing keys from supply chain, SCP enforcement of ML-DSA-only key creation
PCI DSS 4.0 Req 12.3.3
Mandatory since March 2025
PCI DSS v4.0.1, Requirement 12.3.3: “Cryptographic cipher suites and protocols in use are documented and reviewed at least once every 12 months”, including an up-to-date inventory of the cipher suites and protocols in use
Document cryptographic inventory in AWS KMS, tag ML-DSA versus traditional keys, maintain migration progress tracking
Note for NSS customers and other CNSA 2.0 adopters: CNSA 2.0 is the quantum-resistant algorithm suite that the NSA requires for NSS, the federal systems that carry classified information or support intelligence, cryptologic, military command and control, and weapons functions. When ML-DSA is used for any signature purpose, including software and firmware signing, CNSA 2.0 permits only the ML-DSA-87 parameter set. (For software and firmware signing it also approves the stateful hash-based schemes LMS and XMSS, which this post doesn’t cover.) The ML-DSA-65 parameter set used in this post’s code-signing examples is appropriate for commercial workloads but isn’t permitted on NSS. CNSA 2.0 is binding only for NSS, but it’s followed voluntarily well beyond that boundary: by suppliers to the US defense and intelligence market, in the United States and allied countries, whose products must meet NSS requirements, and by commercial organizations in and outside the United States that adopt it as a conservative baseline because it specifies the highest NIST security category and removes the need to revisit parameter choices later. If your systems fall under CNSA 2.0 scope, or you’ve chosen to align with it, substitute ML-DSA-87 for all signing keys and certificates. Part 2 of this series shows how to make that substitution enforceable: the same kms:KeySpec controls that exclude ML-DSA-44 in its example can be pointed at ML_DSA_87 as the only approved key spec.
For organizations serving both US government and EU commercial markets, the January 2027 and December 2027 deadlines converge into a single migration window. Starting now provides margin for testing, key rotation planning, and certificate chain validation.
Clean up
You created a number of cryptographic resources in the prior steps and examples. AWS Private CA charges a monthly fee per CA and AWS KMS charges per key per month. To avoid ongoing charges, delete them if you aren’t actively using them. Start by listing what exists, so that you catch every resource you created, including duplicates from repeated runs. These commands list one Region; if you worked in more than one, repeat them with --region for each.
# List every private CA with its type, status, key algorithm, and subject.
# A CA you already deleted shows DELETED until its restoration window ends.
aws acm-pca list-certificate-authorities \
  --query 'CertificateAuthorities[].[Arn,Type,Status,CertificateAuthorityConfiguration.KeyAlgorithm,CertificateAuthorityConfiguration.Subject.CommonName]' \
  --output table

# List every ML-DSA key in AWS KMS with its state and creation date.
# A key already scheduled for deletion shows PendingDeletion.
for KEY_ID in $(aws kms list-keys --query 'Keys[].KeyId' --output text); do
  aws kms describe-key --key-id "$KEY_ID" \
    --query 'KeyMetadata.[KeyId,KeySpec,KeyState,CreationDate]' --output text
done | grep ML_DSA

# Show which alias points at which key. A key that no alias points at
# is usually a leftover from an earlier run.
aws kms list-aliases --query 'Aliases[].[AliasName,TargetKeyId]' --output text | grep -v '^alias/aws/'
AWS Private CA has no command that lists the certificates a CA has issued. If you need serial numbers for the revocation step that follows, generate an audit report with aws acm-pca create-certificate-authority-audit-report, which writes a list of every certificate the CA has issued or revoked to an S3 bucket that grants the service write access.
Delete each resource that you don’t need, including any extra copies that the listing revealed, then run the listing again to confirm that nothing is left:
# Revoke any issued end-entity certificates while the subordinate CA is still active
aws acm-pca revoke-certificate \
  --certificate-authority-arn <sub-ca-arn> \
  --certificate-serial <serial-number> \
  --revocation-reason CESSATION_OF_OPERATION

# Delete the IAM Roles Anywhere resources that reference the CA
aws rolesanywhere delete-profile --profile-id <profile-id>
aws rolesanywhere delete-trust-anchor --trust-anchor-id <trust-anchor-id>

# Delete the build agent role that the profile referenced, and the local copy of its private key
aws iam delete-role-policy --role-name PQCBuildAgentRole --policy-name pqc-code-signing
aws iam delete-role --role-name PQCBuildAgentRole
rm -f build-agent-mldsa-key.pem

# Delete the AWS KMS code-signing key (schedule 7-day waiting period).
# ScheduleKeyDeletion doesn't accept an alias, so resolve the key ID first.
KEY_ID=$(aws kms describe-key --key-id alias/pqc-code-signing \
  --query KeyMetadata.KeyId --output text)
aws kms schedule-key-deletion --key-id $KEY_ID --pending-window-in-days 7

# Remove the alias. It survives key deletion and would otherwise show up in the
# listing above on your next run.
aws kms delete-alias --alias-name alias/pqc-code-signing

# Disable and delete the subordinate CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <sub-ca-arn> --permanent-deletion-time-in-days 7

# Disable and delete the root CA
aws acm-pca update-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --status DISABLED
aws acm-pca delete-certificate-authority \
  --certificate-authority-arn <root-ca-arn> --permanent-deletion-time-in-days 7
If you are adapting this for long-term use, plan for log retention. CloudTrail Event History keeps only the last 90 days of management events and is not a substitute for a trail. For the audit trail described earlier, create a trail that delivers to an S3 bucket with the lifecycle policy and access controls your retention requirements call for.
Conclusion
In this post, I showed you how to build a quantum-resistant software supply chain on AWS by combining ML-DSA signing in AWS KMS, ML-DSA certificate hierarchies in AWS Private CA, and ML-DSA workload authentication through IAM Roles Anywhere. The architecture covers the full pipeline; from authenticated build agents through signed binaries, container images, and SBOMs, to verification and policy enforcement at deployment.
Every ML-DSA capability used in this post is generally available. AWS Private CA and IAM Roles Anywhere support ML-DSA in all commercial AWS Regions, the AWS GovCloud (US) Regions, and the China Regions, and AWS KMS supports ML-DSA in commercial AWS Regions. You don’t need to wait for a standards body or third-party tool to finalize PQC support. The primitives are ready.
To get started, create your first ML-DSA key in AWS KMS and sign a test artifact. From there, extend to your PKI hierarchy, integrate IAM Roles Anywhere for your build agents, and add ML-DSA signatures to your container and SBOM workflows.
Building the pipeline is half the work. The other half is making sure the algorithm choices you made stay in force as accounts, teams, and standards change. That’s the subject of Part 2 of this series, Enforce your ML-DSA algorithm policy with SCPs and IAM, written for the security and governance teams who own that problem.
In cloud-centered environments, establishing trust between workloads is fundamental to securing machine-to-machine communication. Traditional approaches such as API keys, shared secrets, and static service account credentials weren’t designed for the scale and ephemeral nature of cloud workloads. This drives an organizational need to shift from long-term, static credentials to short-lived cryptographic workload identities. Organizations are turning to SPIFFE (Secure Production Identity Framework for Everyone) as a core component of their workload identity strategy. SPIFFE is a set of open source standards for securely identifying software systems in dynamic and heterogeneous environments. Using SPIFFE can help address what’s known as the bottom turtle problem: the circular dependency where protecting one credential requires yet another credential.
SPIRE (the SPIFFE Runtime Environment) is an open source implementation of SPIFFE. Customers can use it to quickly experiment with the framework. However, there are operational and security considerations when deploying SPIRE in production, such as:
Where cryptographic signing keys for workload identities are managed
How to ensure availability and resiliency of the workload identity registry
How the SPIRE Certificate Authority integrates into the existing enterprise PKI
How workloads without direct connectivity to the SPIRE server validate identities
How workload identities are delivered to serverless environments
How fine-grained authorization based on SPIFFE IDs is enforced
In this post, we show you how to address each of these considerations by offloading SPIRE core functionality to AWS managed services. This post is accompanied by a Github Repository that guides you through the deployment of the reference architecture.
To learn the core concepts the SPIFFE framework, take a moment to familiarize yourself with the SPIFFE documentation.
SPIRE background
A SPIRE deployment is comprised of at least one SPIRE Server, at least one SPIRE Agent, and at least one workload.
Figure 1: SPIRE high-level architecture
The SPIRE Server is deployed on a central control plane instance (or instances) and manages identity issuance and stores workload identity registrations. The SPIRE server handles five key functions:
RegistrationAPI:Create, update, and delete registration entries that define which workloads are entitled to specific SPIFFE IDs based on selectors (for example, Kubernetes namespace, Unix UID).
DataStore: The SPIRE server uses a data store to keep track of the workload identity registration entries and the status of the SVIDs it has issued.
KeyManager: Controls how the server manages private keys used to sign X.509-SVIDs and JWT-SVIDs.
BundlePublisher: Publishes the local trust bundle to a store. The trust bundle is an object containing a trust domain’s cryptographic keys
UpstreamAuthority:Dictates which root certificate authority is used to sign the SPIRE certificate authority (CA) certificate
WorkloadAPI: Exposes the workload API to workloads, which enable workloads to retrieve their SVIDs and trust bundles from the SPIRE server.
NodeAttestation: SPIRE requires that each agent attest and verify itself.
WorkloadAttestation:The SPIRE agent collects workload metadata to determine its identity.
SVIDStore: The SPIRE Agent also stores SVIDs in other destinations, such as AWS Secrets Manager or HashiCorp Vault making them available for workloads running in serverless environments.
After the server and agent are deployed, applications retrieve short-lived SPIFFE Verifiable Identity Documents (X.509 Certificates or JSON Web Tokens (JWTs)) using the workload API.
How to use AWS managed services for core SPIRE functions
In the following sections, we dive deeper into what each of these SPIRE functions does and the advantages of using each AWS service for the function.
Figure 2: SPIFFE architecture using AWS managed services
To deploy the infrastructure required to follow along with this post, follow the deployment process in the Github Repository.
Note: For each managed service, there’s a parameter in the source AWS CloudFormation templates that you can use to specify whether to provision the resource. For example, if you already have an AWS Private Certificate Authority (AWS Private CA) certificate authority deployed in your environment, you can use that for your SPIRE implementation and avoid provisioning a new certificate authority.
SPIRE Key Manager using AWS KMS
The SPIRE Key Manager controls the cryptographic keys that are used to sign SPIFFE Verifiable Identity Documents (SVIDs), which are either X.509 certificates or JWTs.
By using SPIRE, you can configure the cryptographic keys to be either stored in memory or on disk, or to use a plugin where external keys are used for signing SVIDs.
By using the AWS KMS plugin for SPIRE, you bring the security benefits of AWS KMS to your SPIRE implementation.
HSMs: AWS KMS uses hardware security modules (HSMs) that have been validated under FIPS 140-3 Level 2
Key protection: Your plaintext AWS KMS keys don’t leave the HSMs, aren’t written to disk, and are only used in the volatile memory of the HSMs for the time needed to perform your requested cryptographic operation
Comprehensive auditing: Each request to use the keys for signing must be authenticated using Signature Version 4 (SigV4) and is audited and logged in AWS CloudTrail
Fine-grained access control: Use AWS KMS Key Policies to restrict access to your signing keys
This configuration block indicates to SPIRE that AWS KMS keys are used to sign our SVIDs:
The SPIRE server uses a data store to keep track of the workload identity registration entries as well as the status of the SVIDs it has issued. By default, the datastore lives as an SQLite database in memory. However, you can configure the SPIRE server to use Amazon Aurora. By doing this, you can decouple the database from the server and offload the operational overhead of managing the datastore to AWS.
Benefits:
High availability: Automatic failover and multi-Availability Zone deployments
Automated backups:Point-in-time recovery and automated backup retention
Scalability:Scale compute and storage independently
SPIRE certificate authority using AWS Private Certificate Authority
The SPIRE Server issues SVIDs to SPIRE agents and workloads. Given that these SVIDs are X.509 certificates, the SPIRE server needs to act as a certificate authority. In the default configuration of SPIRE, the server generates a self-signed certificate that it will use as the root CA certificate. In production scenarios, organizations often use their existing AWS Private CA certificate authority hierarchy.
Using the AWS Private CA plugin for SPIRE, you configure the SPIRE CA to act as an issuing certificate authority that chains to your existing root CA. This delivers three benefits for your SPIRE implementation:
HSM-backed root of trust: The root of trust of your CA hierarchy is backed by fully managed, FIPS 140-2 Level 3 validated hardware security modules
Non-exportable private keys: The private keys for the root CA can’t be exported
Note: If the SPIRE CA certificate will be signed by an issuing CA, you need to ensure that the path length of that CA is at least 1. The sample code provisions a root CA, so this isn’t an issue if you’re following the sample code.
After the sample deployment is complete, the configuration of the SPIRE server configuration includes the UpstreamAuthority plugin to use your AWS Private CA certificate authority as the root of trust.
In SPIFFE, trust bundles are sets of public keys that are used by destination workloads to verify the identity of source workloads. These bundles contain the root certificates and public keys used to sign JWT SVIDs.
Decouple:Decouple bundle access from the SPIRE server availability
Continuous validation: Allow destination workloads to continually validate source workload identities without requiring network access to the SPIRE server
Global distribution: Distribute the trust bundle using Amazon CloudFront, improving performance through the CloudFront global edge network with over 750 Points of Presence
Reduced load: Offload trust bundle retrieval traffic from the SPIRE server
Version control: Maintain historical versions of trust bundles with S3 versioning
The following is a sample configuration for this plugin:
BundlePublisher "aws_s3" {

plugin_data {

region = "<your_bucket_region>"

bucket = "<your_bucket_name>"

object_key = "<your_bundle_name"

format = "spiffe"

}

}
In a typical SPIRE implementation, SVIDs are retrieved from the workload API using the SPIRE agent by workloads. In serverless or container cases, it isn’t feasible or possible to run the SPIRE agent, especially in workloads running on AWS Lambda or an AI agent running in Amazon Bedrock AgentCore Runtime. In these scenarios, use the SVID store plugin to push the SVID to Secrets Manager.
In this scenario, you still need a SPIRE agent running on a node that performs node attestation with the SPIRE server and delivers the SVID to a secrets store. One of the available secrets store plugins is the AWS Secrets Manager SVIDStore Plugin.
Benefits:
Encryption at rest: Secrets are encrypted by default using AWS managed or customer-managed AWS KMS keys
Fine-grained access control: Use resource policies to control which workloads access which SVIDs
Audit trail: All secret access is logged in CloudTrail
This plugin is configured in the agent, as opposed to the SPIRE server. A reference for the specific permissions required are in the plugin Github repository. In the sample code, see the configuration in the following agent.conf file:
SVIDStore "aws_secretsmanager" {

plugin_data {

region = "<your_region>"

}

}
When you need to specify a given workload’s SVID to be pushed to Secrets Manager, you add the storeSVID and selector parameters when you create the entry in the workload registry. If you’re managing your SPIRE server in Kubernetes, the appropriate command looks like:
Fine-grained access control using Verified Permissions
Up to this point, all the managed services we’ve talked about have been used for creating and distributing SVIDs and trust bundles to workloads. However, a key advantage of using a framework such as SPIFFE is that it allows resource owners to protect resources with fine-grained access control. One managed service that helps you do that in the context of SPIFFE and SPIRE implementations is Amazon Verified Permissions.
Verified Permissions is a scalable, fine-grained permissions management and authorization service that helps you build secure applications. You can use it to:
Define declarative policies: Use Cedar policy language, which provides human-readable, declarative access control rules
Centralize policy management: Separate authorization logic from application code
Make real-time decisions: Evaluate authorization requests in real-time based on multiple factors including user identity, workload identity (SPIFFE ID), resource attributes, and contextual information
Integrate with identity providers: Support for OpenID Connect (OIDC) providers, enabling validation of JWT tokens including JWT-SVIDs
With Verified Permissions, you authenticate SPIRE issued SVIDs using the public keys associated with your trust domain, and deploy fine-grained authorization policies protecting your resources. To use Verified Permissions, you need a policy store, an identity source, and authorization policies.
The github sample creates a policy store on your behalf and sets up the necessary infrastructure to have SPIRE serve as an identity source for your policy store.
You will need policies to enforce fine grained authorization. The following sample policy forbids a specific workload from taking any action:
forbid(

principal,

action,

resource

)

when {

context has sub &&

context.sub like "spiffe://example.org/forbidden-workload/*"

};
Or conversely allows a specific workload to take actions:
permit(

principal,

action,

resource

)

when {

context has sub &&

context.sub like "spiffe://example.org/allowed-workload/*"

};
Experiment with these policies as you build on top of your SPIRE infrastructure.
Conclusion
This post demonstrates how organizations enhance their SPIRE deployments on AWS by replacing default implementations with AWS managed services. We showed you integrations with AWS KMS for SVID signing, Amazon RDS Aurora for managed datastore operations, AWS Private Certificate Authority for root of trust, Amazon S3 and CloudFront for global trust bundle distribution, AWS Secrets Manager for SVID storage, and Amazon Verified Permissions for fine-grained authorization. By adopting these integrations, organizations can improve security posture, reduce operational complexity, and enhance resiliency.
You’re building a data agent that lets business users ask questions about lakehouse data in natural language. You’ve already built governance policies that control who can access which datasets. The challenge is making the agent respect those rules without rebuilding them in your application code.
When a user asks a question, the agent maps it to data and constructs a query. The tool runs under its own AWS Identity and Access Management (IAM) role, so AWS Lake Formation sees the tool’s credentials, not the person behind the request. This leaves you with two inadequate options: restrict tool access (limiting self-service analytics) or rebuild access controls in application code (moving governance out of the data layer).
In this post, we show you a different approach: identity-aware AI data agents that propagate each user’s identity through every hop, from the user, through the agent, into the tool, so Lake Formation evaluates the user’s grants. Your application code makes no authorization decisions, existing Lake Formation policies work without modifications, and AWS CloudTrail records the actual person who accessed the data.
In this post, you learn how to:
Set up per-user data access controls for AI agents querying your lakehouse without rewriting your existing Lake Formation governance policies by configuring Amazon Bedrock AgentCore to carry each user’s identity through trusted identity propagation (TIP).
Ensure auditability and compliance by performing a server-side token exchange inside AWS Lambda that converts the identity token into Lake Formation credentials scoped to the real user, with CloudTrail recording every query.
Validate the pattern end-to-end by testing with multiple users and confirming per-user query results and CloudTrail audit evidence.
The building blocks in this post, OAuth 2.0 token delegation, AWS IAM Identity Center, Lake Formation, and Lambda are well-documented individually. The new constraint is that a foundation model (FM) now sits in the middle of the propagation chain. The FM is the agent’s brain, it decides which tools to call and what arguments to pass and anything that enters its context (prompts, tool schemas, arguments) is accessible within that trust boundary. So, the user’s identity token must reach the tool, but it must do so on the HTTP transport layer, bypassing the FM’s reasoning layer entirely. This post demonstrates the three Amazon Bedrock AgentCore configurations that achieve that.
Whether you’re building agents on Strands, LangGraph, or a similar framework, this post gives you a deployable pattern on Amazon Bedrock AgentCore. Security engineers will find the identity-transport and audit properties relevant, and data platform owners will see how existing Lake Formation grants extend to AI workloads with no changes.
With this pattern (shown in Figure 1), your data agent can query Lake Formation governed data with per-user access controls, full CloudTrail audit trails, and no changes to your existing governance policies. Here’s how it works.
Two tokens travel through the system. An access_token authenticates the request at each trust boundary (Bedrock AgentCore Runtime, Bedrock AgentCore Gateway). An id_token carries your identity and is exchanged, server-side, for the identity context that Lake Formation evaluates.
A separate TIP role carries only the IAM permissions needed to call service APIs, it has no Lake Formation data grants.
Lake Formation evaluates only the propagated user identity, not the TIP role.
The request flow is:
User to UI: The user authenticates with an OpenID Connect (OIDC) identity provider (IdP). This post uses Amazon Cognito, but you can use any OIDC provider, such as Okta. The UI receives an id_token and an access_token.
UI to Bedrock AgentCore Runtime: The UI calls the agent running in AgentCore Runtime over HTTPS. The access_token goes in the standard Authorization header. The id_token goes in a custom header: X-Amzn-Bedrock-AgentCore-Runtime-Custom-IdToken. The HTTP body contains only the user’s prompt.
AgentCore Runtime to agent code: The runtime validates the access_token against the configured JSON Web Token (JWT) authorizer, then passes the request to the agent container with both headers accessible through context.request_headers.
Agent to Bedrock AgentCore Gateway: The agent opens a Model Context Protocol (MCP) connection to an AgentCore gateway, including both headers on the connection. The AgentCore gateway validates the access_token and forwards the custom header to its Lambda target.
AgentCore Gateway to Lambda: The propagated headers arrive in context.client_context.custom[‘bedrockAgentCorePropagatedHeaders’].
Lambda to the data layer: Lambda validates the id_token, exchanges it for an identity context, assumes a role with that context, and runs the Amazon Athena query under the user’s identity.
Lake Formation evaluates grants against the real user. Athena returns only the rows and columns that the user is entitled to see. CloudTrail records the assumed role with an onBehalfOf entry identifying the human.
Now that you’ve seen the end-to-end flow, the following sections walk through each piece, starting with what you need to have in place before you build.
Prerequisites
This post assumes you have the working knowledge of OAuth 2.0, IAM, and Lake Formation grants.
An OIDC IdP. The reference implementation uses Amazon Cognito as the demo IdP, but the pattern is IdP-agnostic. Auth0, Microsoft Entra ID, Okta, Ping, or any OIDC-compliant provider works identically, if your TTI accepts its tokens.
This post doesn’t walk through setting up any of these components. The existing AWS documentation covers each one. For more information, see the links in the preceding list and the related resources at the end of this post.
The three Bedrock AgentCore configuration steps
Three Bedrock AgentCore features make this pattern work. Together they form the chain of custody for the user’s id_token from the moment it arrives at the Bedrock AgentCore Runtime to the moment Lambda uses it.
Configure the runtime request header allow list
Bedrock AgentCore Runtime doesn’t pass request headers into the agent container by default. You opt in by declaring an allow list, either through agentcore configure or directly in the runtime configuration:
AgentCore Runtime supports two types of forwarded headers:
The standard Authorization header for OAuth inbound JWT authentication (access_token), and
Custom headers prefixed with X-Amzn-Bedrock-AgentCore-Runtime-Custom-
The id_token in this pattern uses a custom header. Inside the agent, the allow listed headers arrive as a dictionary object on the request context.
The following Python code runs in the agent container:
from bedrock_agentcore.runtime import BedrockAgentCoreApp

ID_TOKEN_HEADER = "X-Amzn-Bedrock-AgentCore-Runtime-Custom-IdToken"
app = BedrockAgentCoreApp()

@app.entrypoint
def invoke(payload, context):
    request_headers = getattr(context, "request_headers", None) or {}

    id_token = ""
    access_token = ""
    for key, value in request_headers.items():
        if key.lower() == ID_TOKEN_HEADER.lower():
            id_token = value
        elif key.lower() == "authorization":
            access_token = value.replace("Bearer ", "")

    # ... build MCP headers and call the Gateway
The agent code reads the id_token from the HTTP transport and forwards it (also on the HTTP transport) to the next hop. It doesn’t treat the token as a tool argument and doesn’t inject it into a prompt.
Key takeaway: The runtime allow list is the first gate. Without it, the id_token doesn’t reach your agent code.
Configure AgentCore Gateway metadata for header propagation
An AgentCore Gateway is the Model Context Protocol (MCP) endpoint the agent talks to. When AgentCore Gateway invokes a Lambda target, it doesn’t forward arbitrary request headers by default. You configure which headers to propagate using metadataConfiguration.allowedRequestHeaders on the target:
Notice that the tool schema doesn’t include an id_token parameter; there’s no token parameter on any tool. The FM doesn’t see, select, or pass an id_token because the token isn’t part of the tool’s contract. It travels parallel to the tool call, on the HTTP connection, through metadataConfiguration.
This is a critical property for security. If you put the id_token in the tool schema instead, the FM becomes responsible for passing it, which means the token lands in prompts, traces, memory, and logs. Keeping the token off the tool contract keeps it out of the FM entirely.
Key takeaway: The metadataConfiguration of the AgentCore gateway is the second gate. It controls which headers cross from the agent into the Lambda function without touching the tool schema.
Read propagated headers in Lambda
On the Lambda side, the propagated header arrives not in the event body but in the client context, under a specific key.
The following Python code runs in the Lambda function:
ID_TOKEN_HEADER = "X-Amzn-Bedrock-AgentCore-Runtime-Custom-IdToken"

def lambda_handler(event, context):
    client_ctx = getattr(context.client_context, "custom", {}) or {}
    propagated_headers = client_ctx.get("bedrockAgentCorePropagatedHeaders", {})
    id_token = propagated_headers.get(ID_TOKEN_HEADER)

    if not id_token:
        return {"statusCode": 400, "body": {"error": "missing id_token"}}

    # Tool arguments from the agent's call (no id_token here)
    query = event["query"]
    database = event["database"]
    workgroup = event["workgroup"]
    output_location = event["output_location"]

    # ... validate token, exchange, run query
The event dictionary contains the tool’s declared parameters and nothing else. You reach the id_token only through context.client_context.custom[‘bedrockAgentCorePropagatedHeaders’]. That’s the handoff point.
Key takeaway: The id_token arrives through the client context rather than tool arguments; the FM has no access to it. The Lambda is the only component that reads the token.
Perform the server-side token exchange
After Lambda has the id_token, it validates the token and exchanges it for an identityContext. This step uses standard IAM Identity Center TIP mechanics. That it happens inside Lambda rather than anywhere else is what keeps the identity context from crossing a process boundary.
The identityContext is created and consumed inside a single Lambda invocation. It doesn’t get returned to the agent, the gateway, or the UI.
The resulting boto3.Session holds short-lived credentials whose underlying identity assertion is the real user. When the session calls Athena, the query runs with the user’s identity propagated. Lake Formation sees the user, not the Lambda function’s role.
Everything after this, including the Athena query and result formatting, is standard boto3.
Configure Lake Formation grants
You need one grant to the IAM Identity Center user or group. That’s the whole story at the Lake Formation layer.
This is the grant Lake Formation evaluates at query time. You add column-level and row-level filters to the same user or group the same way. Nothing here is aware of or specific to AI agents. If you already have a Lake Formation grants model for human users, you already have the grants this pattern needs.
Understanding the TIP role: The TIP role that Lambda assumes has no Lake Formation data grants. It holds only IAM permissions to call the service APIs: athena:* for query runs, glue:* for catalog reads, lakeformation:GetDataAccess for the query plan handshake, and Amazon S3 access for the Athena output bucket. When Lambda assumes this role with an identityContext attached through ProvidedContexts, Lake Formation evaluates only the propagated user identity against its grants. The role itself is transparent to the authorization decision.
In the more common agent runs as a role pattern, the role carries the grants, which is why per-user governance breaks. Here the role carries no grants; it’s a session vehicle, not an authorization subject.
Test the pattern end-to-end
Two users, same question, different outcomes.
User A has SELECT on trip_details. They ask the agent for five records from the table.
Figure 2: Five records are requested and returned by the agent
User B has no grant on trip_details. They ask the same question.
Figure 3: User doesn’t have access to the data
No code changed between the two interactions. No parameter was toggled. Lake Formation made the decision based on the propagated identity.
The CloudTrail record for the AssumeRole call shows the delegation:
The onBehalfOf block closes the audit loop. Each query the agent runs on a user’s behalf has a CloudTrail record naming that user, with no additional instrumentation in your code.
Security properties
Four properties follow from this architecture. These are the core value propositions of the identity-aware pattern:
The id_token never reaches the foundation model: It travels on HTTP headers at every hop, and Lambda reads it from context.client_context.custom. It’s not a parameter on any tool. The FM has no path to it: not in tool arguments, not in prompts, not in memory, not in traces.
The identity context stays inside a single Lambda invocation: It’s derived from the id_token, used immediately in an AssumeRole call, and discarded. It doesn’t go back to the agent, the gateway, or the UI.
Authorization decisions live in Lake Formation, against the real user only: The TIP role the Lambda function assumes has no data grants. Lake Formation evaluates the propagated user identity. No code path in the agent, gateway, or Lambda function performs authorization logic.
The audit trail requires no extra work: The CloudTrail AssumeRole event with onBehalfOf identifies the human user for every query. You get the same audit fidelity you would have for human users accessing data directly.
Deploy the pattern
To deploy this pattern, you need to configure four things:
An OIDC IdP with a TTI in IAM Identity Center accepting its tokens, and an Identity Center OAuth Application configured for CreateTokenWithIAM.
Bedrock AgentCore Runtime running your agent container with requestHeaderAllowlist covering Authorization and your custom id_token header.
Bedrock AgentCore Gateway with a Lambda target whose metadataConfiguration.allowedRequestHeaders includes the id_token header. The Lambda target’s tool schema has no id_token parameter.
Lambda reading the id_token from context.client_context.custom[‘bedrockAgentCorePropagatedHeaders’], performing the token exchange through sso-oidc:CreateTokenWithIAM, and calling sts:AssumeRole with ProvidedContexts to get the TIP-bearing session.
Conclusion
When an AI agent queries a governed lakehouse, the data layer needs to know who’s asking, not which role the agent is running under. This post showed you how to resolve that by treating the agent as an OAuth delegated actor. The user’s token travels alongside the agent’s HTTP transport but doesn’t enter the model’s context, and the token exchange that produces query-time credentials happens server-side inside Lambda, scoped to a single invocation.
The three Bedrock AgentCore features that make this composable (requestHeaderAllowlist on runtime, metadataConfiguration.allowedRequestHeaders on gateway, and bedrockAgentCorePropagatedHeaders on Lambda) are specific to building on Bedrock AgentCore. Everything downstream of Lambda is IAM Identity Center and Lake Formation functionality.
If you’re building agents that read governed data, you don’t have to choose between a single over-permissioned service role and per-user code paths. The identity the data layer evaluates can be the real user, the audit trail can name the real user, and the foundation model doesn’t need to know the user’s token exists.
The result is a clean separation: the user’s identity travels end-to-end, the model never sees it, and the data layer enforces it exactly as if the user queried directly.
The AWS European Sovereign Cloud is a new, independent cloud for Europe, physically and logically separate from existing AWS Regions and operated within the European Union (EU). It provides the same services, features, and APIs as AWS commercial Regions, but runs as a distinct AWS partition (aws-eusc), with its own control plane, AWS Identity and Access Management (IAM), billing, console, and service endpoints. Understanding the partition boundary is the key that unlocks correct answers to questions about billing roll-ups, single sign-on (SSO), cross-account roles, AWS Direct Connect, and image distribution. In this post, we show you how to architect a secure, scalable landing zone in the AWS European Sovereign Cloud. We cover account structure and governance, identity managed as infrastructure as code (IaC), centralized logging to a security and event management (SIEM) tool, data protection, network and perimeter design, secure continuous integration and delivery (CI/CD) and artifact distribution, and incident response. Throughout, we map the design to the AWS Security Reference Architecture (AWS SRA) and the AWS Well-Architected Framework, and we call out which behaviors are platform boundaries of a sovereign partition and which are configuration choices you can adapt.
If you are evaluating compliance readiness alongside your landing zone build-out, see the companion post Landing Zone Accelerator Independent Assessment Report for C5:2020 now available on AWS Artifact. This post covers how to align with C5:2020 criteria and provides an independent assessment report and compliance workbook, resources that complement the architectural patterns described here.
The foundational concept: EUSC is a partition
AWS groups Regions into partitions. Every Region is in exactly one partition, and each partition has one or more Regions. Partitions have independent instances of AWS Identity and Access Management (IAM) and provide a hard boundary between Regions in different partitions. AWS commercial Regions are in the aws partition, Regions in China are in the aws-cn partition, and AWS GovCloud Regions are in the aws-us-gov partition. The AWS European Sovereign Cloud is the aws-eusc partition, with its first Region in Brandenburg, Germany (eusc-de-east-1).
Some AWS services provide cross-Region functionality, such as Amazon S3 Cross-Region Replication or AWS Transit Gateway Inter-Region peering. These capabilities work only between Regions in the same partition. You can’t use IAM credentials from one partition to interact with resources in a different partition. There are practical differences that impact your architecture, shown in the following table:
Dimension
Commercial AWS (aws)
AWS European Sovereign Cloud (aws-eusc)
ARN prefix
arn:aws:
arn:aws-eusc:
Console or endpoint domain
amazonaws.com
amazonaws.eu
AWS Organizations
One organization in the partition
A separate, independent organization
AWS IAM Identity Center
Instance in the partition
A separate instance in the partition
Billing
Consolidated in the partition’s payer
A separate payer and billing system (EUR currency)
Cross-partition features and services such as: sts:AssumeRole, VPC peering, Transit Gateway, AWS RAM, Amazon S3 replication
Cross-Region features and functionality
Not available across the aws and aws-eusc boundary
Every AWS Region is sovereign by design: if you find yourself architecting across Regions, note that this partition boundary means that the centralization—one organization, one logging account, one identity source, one billing roll-up—is achievable within each partition. In the EUSC you operate an independent landing zone in aws-eusc that mirrors your commercial operating model. Where you need to bridge the two clouds (for example, a standard application CI/CD system in an AWS commercial Region deploying into EUSC), you integrate at the network or API layer with separate credentials for each partition, not with cross-partition trust. With these partition fundamentals in mind, the remainder of this post walks you through the considerations to build a production-ready landing zone in the EUSC. Each section addresses a critical layer of the architecture, starting with how to write partition-aware infrastructure code that works across both aws and aws-eusc, then moving into the organizational and governance controls that underpin everything else.
Cross-partition IaC
These Terraform and AWS CloudFormation IaC snippets demonstrate partition-aware Amazon Resource Name (ARN) construction—a pattern that helps ensure your infrastructure code works unchanged across AWS partitions (such as standard aws, GovCloud aws-us-gov, or European Sovereign Cloud aws-eusc).
In the case of using the same Terraform script from a commercial Region, ensure that arn:aws isn’t hard coded. This Terraform script derives the partition at deploy time so the same modules work in both AWS commercial Regions and the EUSC.
# Terraform: partition-aware ARNs (works unchanged in aws and aws-eusc)data "aws_partition""current" {}
data "aws_partition" "current" {}
data "aws_region" "current" {}
data "aws_caller_identity" "current" {}
data "aws_organizations_organization" "current" {}

locals {
partition = data.aws_partition.current.partition# "aws" or "aws-eusc"
account_id = data.aws_caller_identity.current.account_id
org_id= data.aws_organizations_organization.current.id
ecs_task_execution_policy_arn = "arn:${local.partition}:iam::aws:policy/service-role/AmazonECSTaskExecutionRolePolicy"
central_logs_bucket_arn= "arn:${local.partition}:s3:::${local.org_id}-central-logs"
}

resource "aws_iam_role" "amazon_ecs_role" {
  name = "AmazonECSrole"
  assume_role_policy = jsonencode({
    Version = "2012-10-17"
    Statement = [
      {
        Action = "sts:AssumeRole"
        Effect = "Allow"
        Sid= ""
        Principal = {
          # IAM service principals are "amazonaws.com" across all partitions,
          # this stays literal (do NOT use ${AWS::URLSuffix} here).
          Service = "ecs-tasks.amazonaws.com"
        }
      },
    ]
  })
}

resource "aws_iam_role_policy_attachment" "amazon_ecs_role_attach" {
  role= "AmazonECSrole"
  # Use ${local.partition } rather than hardcoding "aws" in the ARN.
  policy_arn = "arn:${local.partition}:iam::aws:policy/service-role/AmazonECSTaskExecutionRolePolicy"
}
# CloudFormation: use the AWS::Partition pseudo parameter, never a literal "aws"

AWSTemplateFormatVersion: "2010-09-09"

Description: >-
Creates an ECS task execution role. Demonstrates using the
${AWS::Partition} pseudo parameter in ARNs instead of hardcoding "aws",
so the template works across partitions (aws, aws-cn, aws-us-gov, aws-eusc).

Resources:
  ExecRole:
    Type: AWS::IAM::Role
    Properties:
      RoleName: AmazonECSroleCF
      AssumeRolePolicyDocument:
        Version: "2012-10-17"
        Statement:
          - Effect: Allow
            Principal:
              Service:
                # IAM service principals are "amazonaws.com" across all partitions,
                # so this stays literal (do NOT use ${AWS::URLSuffix} here).
                - "ecs-tasks.amazonaws.com"
            Action: "sts:AssumeRole"
      ManagedPolicyArns:
        # Use ${AWS::Partition} rather than hardcoding "aws" in the ARN.
        - !Sub "arn:${AWS::Partition}:iam::aws:policy/service-role/AmazonECSTaskExecutionRolePolicy"

Outputs:
  ExecRoleArn:
    Description: ARN of the created ECS task execution role
    Value: !GetAtt ExecRole.Arn
Account structure and governance
AWS Control Tower offers a straightforward way to set up and govern an AWS multi-account environment, following prescriptive best practices. AWS Control Tower orchestrates the capabilities of several other AWS services, including AWS Organizations, AWS Service Catalog, and AWS IAM Identity Center, to build a landing zone in less than an hour. Resources are set up and managed on your behalf.
We recommend following the AWS Security Reference Architecture (AWS SRA) multi-account model structure for a EUSC deployment. Use the management account only for governance, deploy universal security guardrails through service control policies (SCPs), resource control policies (RCPs), and service deployments (such as AWS CloudTrail) that will affect all member accounts in the organization.
Region-deny SCPs are commonly applied in commercial Regions, but aren’t required (at this time) in the EUSC because of the physically and logically separated nature of its design.
Other possible SCPs for the management OU:
Service-level guardrails – Restrict which AWS services can be used, based on your compliance posture.
Network perimeter controls – Enforce virtual private cloud (VPC) endpoints, deny public access patterns, and restrict egress.
Encryption and key management – Require AWS Key Management Service (AWS KMS) managed keys for all data-at-rest services and enforce key policies aligned with your sovereignty requirements.
Note: As additional EUSC Regions or Local Zones become available, the partition boundary continues to enforce isolation from non-EUSC Regions. If you need to restrict usage to a subset of EUSC Regions (for example, only eusc-de-east-1 but not a future eusc-de-west-1), a Region-deny SCP would become relevant at that point.
Identity: IAM Identity Center as IaC, no direct payer access
IAM Identity Center is available in the AWS European Sovereign Cloud as an independent instance within the partition. You can connect it to your external identity provider (IdP)—Microsoft Entra ID, Okta, and so on—using SAML/SCIM, exactly as in AWS commercial Regions. If you already use Identity Center to federate in the commercial partition, you can point a second Identity Center integration at the same corporate IdP, so users keep one set of credentials. You manage permission sets, groups, and account assignments separately for each partition.
Manage permission sets and assignments as code
The following Terraform defines a permission set with both an AWS managed policy and an inline least-privilege policy, then assigns a group to a target account. Reproduce the aws_ssoadmin_account_assignment for each account or organizational unit (OU) mapping.
Because group membership comes from your IdP over SCIM, the IdP handles joiner, mover, and leaver, and access in EUSC updates automatically. No one receives direct access to the management account; all human access flows through IAM Identity Center permission sets assigned to non-management accounts.
data "aws_ssoadmin_instances" "this" {}
data "aws_partition" "current" {}

# Workload account the group is assigned to.
variable "analytics_workload_account_id" {
  type        = string
  description = "Account ID of the workload account to assign the permission set to"
}

locals {
  sso_instance_arn  = tolist(data.aws_ssoadmin_instances.this.arns)[0]
  identity_store_id = tolist(data.aws_ssoadmin_instances.this.identity_store_ids)[0]
}

resource "aws_ssoadmin_permission_set" "analytics_operator" {
  name             = "AnalyticsOperator"
  description      = "Operate analytics workloads; no IAM or billing"
  instance_arn     = local.sso_instance_arn
  session_duration = "PT4H"
}

# Attach an AWS managed policy
resource "aws_ssoadmin_managed_policy_attachment" "analytics_ro" {
  instance_arn       = local.sso_instance_arn
  permission_set_arn = aws_ssoadmin_permission_set.analytics_operator.arn
  managed_policy_arn = "arn:${data.aws_partition.current.partition}:iam::aws:policy/ReadOnlyAccess"
}

# Add a least-privilege inline policy (note the partition-aware ARNs)
resource "aws_ssoadmin_permission_set_inline_policy" "analytics_inline" {
  instance_arn       = local.sso_instance_arn
  permission_set_arn = aws_ssoadmin_permission_set.analytics_operator.arn
  inline_policy = jsonencode({
    Version = "2012-10-17"
    Statement = [{
      Sid      = "OperateAnalyticsData"
      Effect   = "Allow"
      Action   = ["s3:GetObject", "s3:PutObject", "s3:ListBucket"]
      Resource = [
        "arn:${data.aws_partition.current.partition}:s3:::analytics-*",
        "arn:${data.aws_partition.current.partition}:s3:::analytics-*/*"
      ]
      Condition = { StringEquals = { "aws:RequestedRegion" = "eusc-de-east-1" } }
    }]
  })
}

# Group for analytics operators.
# In production this is typically synced from your IdP via SCIM; here we
# manage it directly so the config is self-contained.
resource "aws_identitystore_group" "analytics" {
  identity_store_id = local.identity_store_id
  display_name      = "analytics-operators"
  description       = "Analytics operators"
}

# Assign the group to a workload account with the permission set
resource "aws_ssoadmin_account_assignment" "analytics_to_workload" {
  instance_arn       = local.sso_instance_arn
  permission_set_arn = aws_ssoadmin_permission_set.analytics_operator.arn
  principal_id       = aws_identitystore_group.analytics.group_id
  principal_type     = "GROUP"
  target_id          = var.analytics_workload_account_id
  target_type        = "AWS_ACCOUNT"
}
Cross-account roles for governance, logging, and tooling
Cross-account roles within the EUSC partition work normally; this is how the logging and security-tooling accounts collect from workload accounts. Scope each trust policy to a specific principal and harden it with an external ID (for third-party tooling) and partition-aware ARNs.
A role in the aws partition can’t assume a role in aws-eusc (or the reverse).
Logging and monitoring: centralized in EUSC, exported to your SIEM
A sovereign logging architecture requires three things:
A single, immutable store for all audit and operational logs
A central security account that runs detective controls and correlates findings
A reliable, in-partition path that feeds everything into your SIEM without data ever leaving the boundary.
In the subsections that follow, we walk through each layer: Centralized log collection in the Log Archive account, Amazon GuardDuty and AWS Security Hub administration through the Security Tooling account, and the pull-based SIEM integration pattern that keeps telemetry inside the EUSC partition.
Centralize logs in the Log Archive account
The Log Archive account holds the organization trail and a central log bucket as part of the landing zone. In the commercial AWS partition, global services like IAM route their CloudTrail events to us-east-1. In the EUSC, global services events are logged within the EUSC partition because the control plane is independent and located entirely within the EU.
Organization level detective services
GuardDuty and Security Hub are available in EUSC, but organization-wide auto-enable and some newer features might differ from commercial AWS features at any given time. Design the Security Tooling account as the delegated administrator where supported. If org-level auto-enable isn’t yet available, enable per-account through your IaC (AWS CloudFormation StackSets) so coverage is complete and code-managed. Treat the EUSC service and feature list as the source of truth and gate optional features behind a partition flag.
Network security and perimeter, including AWS Direct Connect
The AWS European Sovereign Cloud has its own sovereign AWS Direct Connect points of presence (PoPs), with dedicated networking infrastructure and connectivity from European providers, providing customers an autonomous network path into the partition. You terminate Direct Connect in a dedicated Network account and share connectivity to workload VPCs using Transit Gateway (with AWS RAM). A Direct Connect connection or Direct Connect gateway in the commercial partition can’t be extended into aws-eusc. To reach EUSC VPCs, you provision a separate Direct Connect connection that lands in the EUSC partition’s Network account. If your on-premises network already backhauls to AWS commercial Regions, you connect that network to EUSC with its own virtual interface or connection, or a site-to-site VPN. You don’t bridge the two AWS partitions through a shared Direct Connect gateway.
The following figure shows the recommended perimeter design in EUSC.
Figure 1: Recommended perimeter design in EUSC
The perimeter design includes:
Centralized egress and inspection – Route workload egress through an inspection VPC in the Network account (gateway load balancer with your firewall of choice, or AWS Network Firewall. Keep workload VPCs private with no internet gateway.
Private service access – Use VPC interface endpoints (VPCe) for AWS service calls so traffic stays on the AWS network within the partition. VPCe doesn’t cross partitions; expose any commercial-partition service to EUSC consumers over DX/VPN and an in-EUSC load balancer.
DNS – EUSC has its own Amazon Route 53. For names that must resolve across clouds, use subdomain delegation or Resolver forwarding rules over your DX or VPN link rather than expecting hosted zones to be visible across partitions.
Segmentation as code – Express segmentation with security groups referencing prefix lists and keep the EUSC IP ranges current from the partition’s published ip-ranges file in your firewall automation.
Data protection
AWS Key Management Service (AWS KMS) is available in EUSC; use customer managed keys for all sensitive data stores and enforce their use with SCPs and key policies. Where your residency or operational-autonomy requirements call for it, evaluate AWS KMS external and imported key material options available in the partition.
For workloads where regulation mandates that key material never resides within the cloud provider’s infrastructure, configure an AWS KMS External Key Store (XKS) in the EUSC Region. The XKS proxy connects AWS KMS to your EU-based hardware security module (HSM) (on-premises or hosted with an EU trust service provider); all encrypt and decrypt operations are performed by your external key manager. Note the trade-offs: increased latency, reduced availability SLA, and added operational burden. Reserve XKS for the subset of data where regulatory or contractual obligations explicitly require it.
The EUSC Region has achieved SOC 2, BSI C5 Type 1 attestation, and seven ISO certifications, including ISO 27001, 27017, 27018, and 27701. Reference these in your data protection evidence packages when demonstrating encryption-at-rest and key management controls to EU regulators.
Secure CI/CD and distributing images across the partition boundary
Container images – Build (or re-tag and re-sign) images and push to an Amazon ECR registry inside EUSC. ECR cross-Region replication works within the partition (useful as EUSC adds Regions or Local Zones), but the initial crossing from commercial is an explicit pipeline push using EUSC credentials. Sign images with a sovereign signing key and verify at deploy time.
AMIs and images – Rebuild golden images in EUSC with EC2 Image Builder (run the pipeline natively in EUSC), or import virtual machine (VM) images using Amazon S3 in EUSC and aws ec2 import-image. There is no direct cross-partition AMI copy.
Binaries and artifacts – Stage in an artifact bucket in the EUSC Shared Services account. Move packages across the boundary with aws s3 sync or AWS DataSync over your DX or VPN, or using controlled export, then distribute within the partition using in-partition S3 replication to other EUSC Regions or Local Zones as they come online.
# Push a container image to ECR inside EUSC (note the .eu endpoint).
# Credentials/profile must be for the aws-eusc partition.
aws ecr get-login-password --region eusc-de-east-1 --profile eusc-shared-services \
  | docker login --username AWS --password-stdin \
    111122223333.dkr.ecr.eusc-de-east-1.amazonaws.eu

docker tag company/runtime:7.x \
  111122223333.dkr.ecr.eusc-de-east-1.amazonaws.eu/company/runtime:7.x
docker push \
  111122223333.dkr.ecr.eusc-de-east-1.amazonaws.eu/company/runtime:7.x
Remember that endpoints and ARNs use amazonaws.eu in the EUSC partition. IAM service principals always use amazonaws.com regardless of partition.
Replicating deployment code and pipelines
Run a native deployment plane in EUSC (AWS CodePipeline, AWS CodeBuild, AWS CodeDeploy, or your existing tool deployed in-partition) in the Shared Services account, with cross-account deploy roles into workload accounts. If a commercial-partition continuous-integration system must deploy into EUSC, give it separate credentials for each partition; the clean pattern is OIDC federation with two trust configurations, one for each partition, because no cross-partition role assumption exists.
// Deploy role in an EUSC workload account, trusted by the EUSC Shared Services pipeline role
{
  "Version": "2012-10-17",
  "Statement": [{
    "Effect": "Allow",
    "Principal": { "AWS": "arn:aws-eusc:iam::<SHARED_SERVICES_ACCT>:role/PipelineDeployRole" },
    "Action": "sts:AssumeRole",
    "Condition": { "StringEquals": { "sts:ExternalId": "EUSC-deploy" } }
  }]
}
For account vending and landing-zone-as-code, use Account Factory for Terraform (AFT) deployed in EUSC. AFT pipelines create accounts through AWS Control Tower, apply baseline guardrails, bootstrap the preceding partition-aware modules, and register OUs, giving you the accounts and account groups as code. Keep Terraform state for each partition in an in-EUSC Amazon S3 backend with an Amazon DynamoDB lock table; don’t share state across partitions.
The Landing Zone Accelerator on AWS (LZA) solution is an alternative deployment method that provisions a baseline security architecture and includes customizations for each partition, with consideration for service availability. A customized configuration baseline for European Sovereign Cloud was recently released and is accompanied by the LZA Compliance Workbook, which maps regional European security standards and international frameworks to over 200 security settings deployed by LZA.
Supported compared to by-design boundaries: A quick reference
Capability
Status in EUSC
What to do
AWS Control Tower account vending, controls
Supported in-partition
Govern the EUSC Region; drive vending with AFT; re-register OUs after Region changes
AWS Control Tower–managed or self-managed IAM Identity Center
Configuration choice
Choose self-managed to own permission sets as code
Permission set creation and assignment as IaC
Supported
Manage with SCIM groups from your IdP
Identity Center single home and delegated admin for each partition
By-design behavior
Administer from one Region; non-issue in single-Region EUSC
Roll up within the EUSC organization, not across partitions. Enable consolidated billing in the EUSC management account and deliver AWS Data Exports (Cost and Usage Report 2.0) to an S3 bucket in a dedicated finance or governance account in the Security or Infrastructure OU.
Set permissions so workload teams can query the curated data in that account; no one should be able to access the management or payer account directly. You can’t replicate billing data into the commercial partition; the EUSC has a separate payer (billed in EUR through the EU contracting entity).
Conclusion
Architecting in the AWS European Sovereign Cloud is, in most respects, architecting a second well-run AWS landing zone with one organizing principle that resolves nearly every design question: it’s an independent partition. Centralization of governance, identity, logging, and billing is fully achievable, but within the EUSC partition. The boundaries you encounter between commercial AWS and EUSC—no cross-partition roles, peering, replication, or billing roll-up—are the sovereignty guarantees doing their job.
Build the foundation as code. Use an AWS Control Tower landing zone driven by AFT, IAM Identity Center permission sets and assignments in Terraform federated to your corporate IdP, an immutable central log store, customer managed encryption keys constrained to the sovereign Region, and a Network account terminating a dedicated Direct Connect. Add a CI/CD plane that pushes images and artifacts into the partition with per-partition credentials. Keep every ARN partition-aware and every optional service behind a feature flag, and the same modules will serve both clouds.
To accelerate your build with additional enablement from AWS, explore the LZA Universal Configuration for European Sovereign Cloud on GitHub, which packages many of the patterns described in this post into a ready-to-deploy baseline. To complement your deployment with compliance readiness, the LZA Independent Assessment Report for C5:2020 evaluates how LZA’s security baseline maps to C5:2020 technical requirements, and you can download the report and the LZA Compliance Workbook from AWS Artifact.
AWS Security Token Service (AWS STS) has simplified session token size limits, giving you more room for your session policies and session tags. STS has replaced the packed policy size and the overall session token size limits with a single token size limit of 4,096 bytes. STS now reports session token size in API responses, Amazon CloudWatch metrics, and AWS CloudTrail events. By using STS, you can also generate session tokens of different sizes, so you can find the maximum token size that your infrastructure can support.
The 4,096-byte limit is the current maximum, not a permanent ceiling. AWS might increase the limit as new capabilities are added that require session tokens to carry more information.
In this post, you learn what has changed, what this change means for you, and what to do next.
What has changed
AWS STS session-vending APIs, such as AssumeRole, AssumeRoleWithSAML, AssumeRoleWithWebIdentity, GetSessionToken, and GetFederationToken, return temporary security credentials: an access key ID, a secret access key, and a session token. This change governs the session token, the opaque string that STS creates from the session policies and tags you pass plus the context that AWS adds.
Three things have changed.
A single limit: Previously, STS enforced two size limits on the session token. It serialized and compressed your session policies and tags into a form called the packed policy, which had its own limit. The assembled token, which included the packed policy, had a separate overall limit. A request could fail against either limit, and both failures returned the same PackedPolicyTooLargeException, so you couldn’t tell which one you exceeded. STS now enforces a single limit: the assembled session token must fit within 4,096 bytes. The separate packed policy limit, which made failures hard to predict, has been removed. When a token exceeds the assembled session token limit, STS returns PackedPolicyTooLargeException. STS continues to use the same exception, so existing error-handling code works without an SDK update.
Session token size is now reported. Every successful response from an STS session-vending API includes SessionTokenSize (which reports the session token size in bytes) and SessionTokenUtilization (which reports the percentage of the 4,096-byte limit consumed). STS also returns PackedPolicySize in every successful response for backward compatibility. PackedPolicySize now reports the same value as SessionTokenUtilization, enabling applications that use older AWS SDK versions to monitor utilization through this field. These response fields are also recorded in CloudTrail events. In CloudWatch, SessionTokenSize and SessionTokenMaxSize (the enforced limit) are published in the AWS/STS namespace.
Testing is more straightforward:MinimumSessionTokenSize is a new optional parameter on the STS session-vending APIs. You can use it to increase a session token to at least the size you specify, up to 4,096 bytes. Use the parameter to find the maximum token size your infrastructure can handle.
Behavior
Previously
Now
Limits enforced
Two: Packed policy size and assembled token size
One: Assembled session token size (4096 bytes)
Error on failure
PackedPolicyTooLargeException: The error message didn’t identify which of the two limits was exceeded.
PackedPolicyTooLargeException: The updated message reports your session token size and the maximum allowed size, both in bytes.
Session token size visibility
Not reported
API Response and AWS CloudTrail:
SessionTokenSize, SessionTokenUtilization, and PackedPolicySize. PackedPolicySize reports the same percentage as SessionTokenUtilization for backward compatibility.
Amazon CloudWatch:
SessionTokenSize and SessionTokenMaxSize
Infrastructure testing
No mechanism
MinimumSessionTokenSize: Parameter on sesssion-vending APIs
What this change means for you?
How this affects you depends on your situation. The following scenarios cover the most common cases.
If you have never hit a token size error: You’re unlikely to notice a change. Your tokens stay their current size and gain headroom. Over time they could become larger than your systems have handled before. We recommend you use MinimumSessionTokenSize to find the maximum token size your systems can handle. See the What to do next section for more details.
If you’ve hit PackedPolicyTooLargeException before: Some requests that previously failed now succeed under the single limit. Review any workarounds you put in place specifically to avoid token size errors and decide whether you still need them. General best practices still apply: consistent tag casing and reused tag values compress more efficiently, and concise session policies keep the assembled token smaller. No code change is required for error handling. AWS STS still returns PackedPolicyTooLargeException when the assembled session token exceeds the limit, the same exception STS returned before this change.
If your systems enforce their own size limits on credentials: If your application uses an AWS SDK to obtain temporary credentials and make AWS API calls, the SDK handles the session token internally, so token size doesn’t affect your code. Focus instead on systems that store or forward session tokens, such as load balancers, proxies, caches, and databases. These systems might have size limits that smaller tokens didn’t reach. For example, a database column defined as varchar(2048) can’t hold a 4,096-byte token. Review where you persist or pass session tokens, and identify the maximum token size each system supports. The next section shows how to test this.
What to do next
We recommend the following three steps to prepare your systems for this change.
Validate the maximum token size your systems can handle. Use MinimumSessionTokenSize to find the maximum session token size each system in your infrastructure can handle. Knowing these limits helps you identify systems that might reject or truncate larger tokens. The 4,096-byte limit reflects today’s needs, not a permanent ceiling. It might grow as AWS introduces new capabilities such as additional context keys for new services, richer audit metadata, and larger cryptographic signatures as the industry transitions to post-quantum algorithms. Avoid hard-coding the current maximum into your systems and revisit any fixed size assumptions if the limit changes.
Tip: AWS STS serializes and compresses your session policies and tags when assembling the token. Compression results vary based on the actual content, not just its length. Two sets of tags with identical character counts can produce different token sizes. This is why MinimumSessionTokenSize is a more reliable way to test your infrastructure than estimating from input length.
Start at 4,096 bytes to test against the largest possible token. If a system truncates or rejects it, lower the value to find the size your infrastructure supports, then raise that limit where you can. MinimumSessionTokenSize is available in the latest AWS SDK, AWS Command Line Interface (AWS CLI), and Tools for PowerShell versions. See the STS API Reference for details. If your AWS SDK or AWS CLI predates the parameter, update it to use this feature.
Monitor your session token size (recommended). If your infrastructure has size constraints, you can use monitoring to see tokens that are approaching your limit and act before a request fails. AWS STS reports size through three channels, each suited to a different need.
In the API response: Reading SessionTokenUtilization and SessionTokenSize from the response requires the latest AWS SDK version. You can also monitor token size through CloudWatch and CloudTrail without updating your SDK.
In CloudWatch: STS publishes SessionTokenSize and SessionTokenMaxSize in the AWS/STS namespace. Use them to build dashboards and set alarms. Set your alarm against the size limit you found during testing, not the 4,096-byte maximum. The maximum is the same for every account, so your own infrastructure limit is the one that matters.
The following figure shows the SessionTokenMaxSize and SessionTokenSize metrics graphed in the CloudWatch console.
Figure 1: SessionTokenMaxSize and SessionTokenSizemetrics in the CloudWatch console
In CloudTrail: Each STS session-vending event records SessionTokenUtilization and SessionTokenSize for successful calls.
Use appropriate fields for monitoring session token utilization. AWS STS still returns PackedPolicySize in session-vending API responses and CloudTrail records for backward compatibility. The field now reports the same value as SessionTokenUtilization: the percentage of the 4,096-byte session token size limit consumed by the token. As a result, PackedPolicySize values might appear lower even when your token content has not changed.
If your SDK exposes SessionTokenUtilization, use that field because its name reflects the value’s current meaning. If an earlier SDK does not expose SessionTokenUtilization, use PackedPolicySize to monitor the same utilization percentage without updating the SDK. We recommend you monitor SessionTokenSize for the token size in bytes.
Conclusion
You now have more room for session tags, tag values, and session policies in your AWS sessions. AWS STS enforces a single 4,096-byte session token limit, returns a clearer error message when a token exceeds it, and reports token size so you can track growth proactively. Validate your token-handling systems with MinimumSessionTokenSize, and watch SessionTokenUtilization and SessionTokenSize for ongoing visibility.
Your consumer identity and access management (CIAM) system is the foundation of your customer experience. It’s how users sign in, access services, and engage with your applications. As your business scales across geographies, ensuring authentication is always available becomes a core architectural requirement. However, building multi-Region authentication has traditionally required complex custom replication solutions that synchronize user data, manage consistency, and handle failover, all adding significant operational overhead. Amazon Cognito simplifies this with multi-Region replication (MRR), which automatically replicates user pools across AWS Regions with near-real-time synchronization, built-in failover, and seamless sign-in, while keeping operational complexity and costs optimized.
In this post, we show you how to prepare your user pool for MRR, provide architectural decisions and reference architectures for business to consumer (B2C), business to business (B2B), and machine to machine (M2M) use cases, and practical guidance on implementing failover strategies.
Amazon Cognito MRR at a glance
Amazon Cognito MRR creates a replica user pool in another AWS Region (a replica Region) that shares the same user pool ID as your primary user pool. The primary user pool (the user pool in your primary Region) remains authoritative, and its configurations (app client IDs, client secrets), user data (attributes, hashed credentials, group memberships), and external identity provider (IdP) settings are replicated to the replica with eventual consistency.
The user pool in the replica Region (replica user pool) supports user authentication operations (such as sign-in, token generation and revocation) and read-only operations towards user pool configurations and user attributes (such as list users and groups and describe user pool configurations). Write operations against user pool configurations and updating user attributes aren’t enabled in the replica user pool and can only be made in the primary user pool. Amazon Cognito returns an Action temporarily unavailable error when using managed login, or an OperationNotEnabledException when using an AWS SDK for those operations. See Supported API operations in secondary Regions for a list of API operations supported in replica Regions.
JSON web tokens (JWTs) and active sessions are interoperable between Regions; for example, a refresh token issued by the primary Region is accepted in the replica Region to retrieve new ID and access tokens.
While this post primarily focuses on MRR architecture patterns and considerations, you can visit the following posts to learn more about MRR basics and the next-generation infrastructure behind it:
You only need to set up one replica multi-Region key for your customer managed key because Amazon Cognito MRR supports only one additional replica Region.
You own the administration of the customer managed key, including key policies, rotation, and deletion. You can also consider a key rotation strategy before enabling MRR or enable automatic key rotation.
Follow least-privilege principles in KMS key policy and scope the KMS key to your user pool only. You can do so by applying a condition statement: kms:EncryptionContext:aws:cognito-idp:<userpool-arn>. See the data encryption section in the Amazon Cognito developer guide for a full example key policy.
Choose a multi-Region OIDC issuer
In each ID and access tokens, Amazon Cognito includes a default Issuer claim in the JWT payload, referred as iss, to represent the identity provider that issued the token. The OpenID Connect (OIDC) specification dictates that the iss format must be a URL that uses https scheme and publishes a JSON metadata document about the identity provider available at the <iss>/.well-known/openid-configuration path. The metadata document must also include the JSON Web Key (JWK) document in the <iss>/.well-known/jwks.json path, which contains the signing keys to validate the token signatures for its integrity.
The original issuer type follows the format as https://cognito-idp.<region>.amazonaws.com/<userpool_id>. However, this issuer URL format and the OIDC well-known metadata are regional resources. As part of the MRR capability, Cognito introduces a new multi-Region OIDC issuer type, the updated issuer, and follows the format as https://issuer-cognito-idp.<region>.amazonaws.com/<userpool_id>. This new updated issuer type replaces the original single Region type and maintains availability of the issuer endpoint regardless of the state of primary or replica Region.
Based on the issuer URL format you select, your OpenID Connect discovery endpoint is hosted at <iss>/.well-known/openid-configuration and your JSON Web Key Set (JWKS) endpoint at <iss>/.well-known/jwks.json. Both original type and updated type are supported with the Amazon Cognito MRR capability. You can change the issuer type at any stage in your MRR journey, and the newly issued tokens, including those generated by refresh tokens, will reflect the most current issuer type configurations.
We recommend adopting the updated issuer type. With the updated issuer type, the OpenID Connect discovery document and JWKS endpoint remain consistent and available regardless of which Region is servicing requests. This means your applications can always fetch signing keys for token verification, even during a regional impairment.
To adopt the updated issuer type, update your applications and downstream dependencies to validate against the new updatediss value. If you use the aws-jwt-verify library, update to v5.2.1 or later that supports updatedissuer type. Plan this as a coordinated deployment; existing ID and access tokens with the original issuer type remain valid and accepted by Amazon Cognito endpoints until they expire. When using an existing refresh token to exchange for a new set of ID and access tokens, new tokens always carry the current issuer format configuration at the time of token refresh operation, providing interoperability across two issuer formats.
If you can’t immediately adopt the multi-Region issuer—for example, because downstream services or third-party integrations validate the iss claim against a hard-coded original format pattern—you can enable MRR while continuing to use the originalissuer type. However, in this configuration the OIDC discovery endpoint and JWKS endpoint are tied to a single Region and might be unavailable during a regional impairment. Your multi-Region application might not be able to fetch public keys dynamically and validate token signatures. To mitigate this, it’s a good practice to implement a JWKS caching strategy in your token verification layer. Cache the signing keys locally (respecting the Cache-Control headers) so your applications can continue to validate tokens using cached keys when the JWKS endpoint is unreachable. This approach lets you benefit from MRR for user authentication while maintaining token verification continuity until you’re ready to complete the issuer migration. To learn more about the original and updated issuer types, see the Amazon Cognito user pools as an OIDC issuer section of the developer guide.
Configure regional service dependencies
Amazon Cognito user pools support several integrations with AWS services for extended customization functionalities. Those AWS services are regional services and must be configured independently in the replica Region, including:
AWS Lambda – Lambda triggers (for example, pre-authentication, pre-token generation, and others) are invoked in different authentication stages and should be deployed in the replica Region and attached to the replica user pool to match customized behaviors in the primary user pool. When deploying Lambda triggers, you can adopt the same logic for both primary and replica user pools and access to downstream resources or set up a different logic to characterize different behaviors when requests are served in the replica Region.
AWS WAF – WAF web access control lists (web ACLs) are associated to protect the user pool from unwanted requests. When accepting traffic to the replica user pool, create matching WAF web ACLs in the replica Region.
Amazon Simple Notification Service (Amazon SNS) – If you send text messages (for example, SMS-based multi-factor authentication (MFA), passwordless authentication, or SMS notifications), configure Amazon SNS in the replica Region. SNS requires additional set up (origination identities, spending limits) in each Region, and sender ID registration time depends on several factors.
Amazon Simple Email Service (Amazon SES) – If you use Amazon SES for email delivery, verify sending domains and email addresses in the replica Region and configure your replica user pool accordingly.
Amazon CloudWatch – If you export user activity logs from Amazon Cognito to a CloudWatch log group, or monitor service quotas in CloudWatch, configure alarms and analytics accordingly.
Use infrastructure-as-code tools like AWS CloudFormation or AWS Cloud Development Kit (AWS CDK) to maintain consistent configurations and deployments across Regions and environments. You should also monitor for any configuration drifts between assets.
Consider automatic domain failover
For authentication use cases that rely on managed login and OAuth 2.0 endpoints—including federated authentication and M2M authorization—Amazon Cognito supports automatic failover to the replica Region with an Amazon Route 53health check. Cognito uses the health status of Route 53 health check to control whether traffic routes to the primary or replica user pool. The health check can be set up to monitor the health of an endpoint, a CloudWatch alarm, or a calculated number of other health checks, so you determine what triggers a healthy or unhealthy state and can adjust traffic routing as needed.
Both the Amazon Cognito prefix domain (for example, auth.us-east-1.amazoncognito.com) and custom domain (for example, auth.example.com) support automatic domain failover. Your domain serves as the single entry point for the user pool OAuth 2.0 endpoints and directs traffic to the managed login pages. Cognito automatically fails over domain traffic to the replica Region when a Route 53 health check becomes unhealthy and fails back to the primary Region when the check is healthy. You don’t need to create another prefix domain in the replica user pool for failover use cases.
With the automatic failover capability, you can use a single domain to serve external IdP configurations, including redirect URIs and SAML assertion consumer URLs. For example, use https://auth.example.com/saml2/logout to send SAML 2.0 sign-out responses. Because the domain can serve traffic to both the primary and replica Regions and remains unchanged across Regions, your external IdP configurations stay consistent across Regions, and existing federated users continue to authenticate without disruption. This means that you can enable MRR without having to contact external IdP admins to update configurations; all existing configurations will continue to work.
For SDK-based authentication use cases without managed login, a custom domain isn’t strictly required. We recommend configuring a custom endpoint for SDK requests to simplify failover orchestration, so you don’t have to modify the Region parameter in the SDK configuration. Behind your custom endpoint, you can use the same Route 53 health check or a custom load balancing strategy to proxy API requests to primary or replica Region endpoints. You might also consider load balancing user authentication traffic, by referring to an X-Amz-Target HTTP header (for example, X-Amz-Target: AWSCognitoIdentityProviderService.InitiateAuth), to both the primary and replica Regions, while keeping user sign-up operations in the primary Region. If you use both managed login and SDK authentication in the same user pool, you can consider using the custom domain as the custom endpoint of the SDK for a streamlined operation, where Route 53 health check initiates failover and failback between the primary and replica Regions.
Plan for TOTP MFA alternatives
Time-Based One-Time Password (TOTP) MFA isn’t supported in replica user pools. Users configured to use TOTP MFA must authenticate through the primary Region. If your application relies on TOTP as a second factor, this limitation requires careful planning because you want to enable an alternative MFA for your users, such as SMS OTP, email OTP, or passkey.
Review quotas
When you activate a replica user pool, you gain a separate set of default quotas in the replica Region. Previously reserved higher quotas for your user pool in the primary Region aren’t carried over to the replica Region.
Data sovereignty
When selecting a replica Region for your user pool, consider your organization’s data sovereignty and residency requirements, as user identity data will be replicated to and stored in that Region. For guidance on navigating compliance, continuity, and control obligations that may influence your Region selection, see Practical digital sovereignty: Navigating the pillars of compliance, continuity, and control.
Reference architectures
In this section, we show you reference architectures for common authentication patterns using the Amazon Cognito MRR capability. Each architecture demonstrates how Cognito MRR works with different authentication use cases.
Managed login and federation
Amazon Cognito managed login provides a fully managed authentication UI that handles sign-in, sign-up, and federation flows. With MRR, managed login endpoints are served from the healthy user pool based on your Route 53 health check configuration. Managed login also includes OAuth 2.0 endpoints and can be used with local Cognito accounts and federated users. Figure 1 depicts a reference architecture for using managed login to authenticate Cognito users.
Figure 1: Cognito MRR reference architecture for managed login and federation use cases
When using Amazon Cognito with managed login, the process flow is:
The user visits the application and is redirected to the managed login to begin the authentication flow.
Managed login uses the Route 53 health check to control traffic routing.
If the health check returns a healthy status, all traffic to the managed login flows to the primary Region user pool for user authentication.
For a federated user, the primary Region user pool redirects the user to a federated IdP or social IdP for authentication. After successful authentication, Amazon Cognito creates or updates user attributes depending on whether it’s a new user signing in for first time or an existing user.
If the health check returns an unhealthy status, all traffic to the managed login flows to the replica Region user pool. Cognito users will authenticate against the replica user pool.
The replica Region user pool endpoint redirects federated users to external IdPs. However, any user creation or attribute update against replica user pool will fail until the health check returns healthy and traffic routes back to the primary Region.
M2M architecture
In an M2M architecture, services authenticate using the OAuth 2.0 client credentials grant. This flow doesn’t involve users; instead, backend services exchange client credentials for access tokens.
Figure 2: Cognito MRR reference architecture for machine-to-machine use case
The authentication flow is:
Application clients send a POST request to the Amazon Cognito /token endpoint with client credentials.
Managed login uses the Route 53 health check to determine whether traffic should flow to the primary or replica user pool.
If the health check returns a healthy status, traffic to the /token endpoint will flow to the primary Region user pool.
If the health check returns an unhealthy status, traffic to the /token endpoint will flow to the replica Region user pool. After the health check returns to a healthy status, traffic will return to routing to the primary user pool.
SDK-based architecture
For applications that use AWS SDK or Amazon Cognito APIs directly (rather than through managed login), the authentication flow is embedded in your application code. This gives you more control over the user experience but requires additional considerations for failover.
Figure 3: Cognito MRR reference architecture for SDK use cases
The process shown in Figure 3 is:
The user visits the application and signs in through a custom UI (using APIs or SDKs).
(Optional) An Amazon Route 53 health check is configured to perform a health check against regional proxy endpoints and determine traffic routing. You can also use a custom health check or your DNS resolver to make traffic routing determinations.
If the health check returns a healthy status, all traffic to the proxy endpoints will flow to the primary Region proxy for user authentication. You can also choose to load balance user authentication traffic across both the primary and backup Regions.
The primary Region Amazon API Gateway proxy forwards user requests to the Amazon Cognito regional endpoint.
If the health check returns an unhealthy status, all traffic will flow to the replica Region proxy.
The replica Region API Gateway proxy begins forwarding user requests to the Amazon Cognito regional endpoint until the health check returns to healthy status.
In an SDK-based architecture, Amazon Cognito regional endpoints can also be called directly. You can also set up custom routing to use replica Region endpoints to load balance user authentication requests by routing read-only requests to both the primary and replica Region endpoints while keeping write requests in the primary Region.
Failover strategies
Now that you’ve set up multi-Region replication with Amazon Cognito, the next step is to test and monitor your multi-Region configuration. In this section, we walk through strategies for monitoring your endpoints, determining when to trigger failover, and testing your failover readiness.
Monitor with Route 53 health checks
Failover for Managed Login and all OAuth 2.0 flows is driven by Amazon Route 53 health checks associated with your Amazon Cognito prefix or custom domain. You’re responsible for what determines the state of this health check. The health check isn’t tied to your DNS CNAME record but is the signal that tells Amazon Cognito whether to route traffic to the primary or replica Region for all managed login endpoints. When the health check fails, Amazon Cognito routes traffic to the replica user pool. When the health check recovers, traffic is restored to the primary user pool.
A practical approach to get started to build a health check:
Create a synthetic canary – Use Amazon CloudWatch Synthetics to run a canary that periodically exercises an actual authentication flow against your primary Region. For example, the canary can perform a client credentials token request against your Amazon Cognito domain’s /oauth2/token endpoint or execute a full AdminInitiateAuth API call with test credentials. This validates that the end-to-end authentication path is functional, not just that an endpoint is responding.
Tie the canary to a CloudWatch alarm – Configure a CloudWatch alarm on the canary’s SuccessPercentCloudWatch metric. Set a threshold that accounts for transient errors (for example, alarm when success drops below 90% for three consecutive evaluation periods).
Connect the alarm to your Route 53 health check (optional) – Create a Route 53 health check that monitors the CloudWatch alarm. When the alarm enters the ALARM state, the health check fails, and Amazon Cognito routes traffic to the replica user pool. If you prefer to rely on human intervention, skip this step and instead configure the CloudWatch alarm alert your operations team to manually invert the health check.
After you have your health check, associate it with your Amazon Cognito domain using the UpdateUserPoolDomain API or the Amazon Cognito console.
Authentication-only compared to full-stack failover
Before implementing failover, consider how your authentication layer relates to the rest of your application stack. There are two common patterns:
Authentication-only failover – Your application remains in a single Region, but authentication traffic fails over to the Amazon Cognito replica if only the primary Region’s authentication service is impaired. This works when your application can continue operating with tokens already issued (for example, cached JWTs, active sessions) and when downstream APIs don’t depend on the same Region as your user pool. Consider this option when the rest of your stack has its own availability model.
Full-stack failover – Your entire application—compute, data stores, APIs, and authentication—fails over to a replica Region. In this model, Amazon Cognito MRR is one component of a broader multi-Region architecture where authentication flows have tight dependencies on regional resources (such as Lambda triggers calling regional Amazon DynamoDB tables, or post-authentication logic writing to a regional event bus) that must be co-located with the user pool.
Use Amazon Application Recovery Controller (ARC) to coordinate failover across all components with a single action. ARC provides three capabilities that are particularly relevant for multi-Region authentication architectures:
Routing controls – Extremely reliable data plane controls that let you shift DNS traffic across Regions, with safety rules that prevent partial or unintended failovers (for example, preventing you from failing over authentication without also failing over the dependent API layer).
Readiness checks – Continuous monitoring of resource quotas, capacity, and network routing policies in your secondary Region, so you have confidence that the replica environment—including your Amazon Cognito replica user pool and its regional dependencies—can handle production traffic before you failover.
Region switch – Centralized, automated, and observable multi-Region recovery orchestration across multiple AWS accounts and resources, so you can execute a coordinated failover of your Cognito user pool alongside databases, compute, and APIs in a single recovery plan.
ARC is particularly valuable when your Amazon Cognito Lambda triggers, WAF rules, SNS and SES configurations, and downstream services all need to switch Regions in lockstep. Rather than managing failover for each component independently, you can use ARC to define a single recovery group that treats your authentication stack and application stack as one unit. To learn more about the capabilities and use cases of ARC, see Introducing Amazon Route 53 Application Recovery Controller.
The right choice depends on your recovery scope. Map the dependencies in your authentication flow: if your Lambda triggers call regional DynamoDB tables or your post-authentication logic writes to a regional event bus, those tight couplings point to full-stack failover. If your application validates tokens independently and doesn’t make real-time calls back to Amazon Cognito after token issuance, authentication-only failover keeps both your blast radius and operational overhead smaller.
Determine when to failover
Triggering failover too aggressively risks unnecessary disruptions; too conservatively risks a drop in desired availability. Here are the factors to balance:
Monitor authentication flow health – Validate that critical flows are functioning, including managed login endpoint availability and token endpoint responses.
Use composite health checks – Combine multiple signals. For example, require both the managed login and token endpoints to be healthy.
Set appropriate thresholds – Configure failure thresholds (for example, three consecutive failures) to distinguish transient errors from genuine impairments.
Consider downstream dependencies – Factor in Lambda triggers, external IdPs, and other regional services.
Client side retry logic – For SDK-based single-page application (SPA) architectures, consider implementing client-side retry logic with Region failover. When the primary Region is unavailable, your application should detect the failure and redirect authentication of API calls to the replica Region’s Amazon Cognito endpoint.
Understanding and determining the recovery time objective (RTO) and recovery point objective (RPO) should also be the key factor in determining when and why to failover. See the Establishing RPO and RTO Targets for Cloud Applications blog post to learn more.
Test failover readiness
If using Route 53 health check, start by manually inverting your Route 53 health check during a maintenance window. In the Route 53 console, enable Invert health check status to force the health check into a failed state; this triggers failover to the replica Region without requiring any infrastructure changes. While traffic is routing to the replica Region, validate that your critical authentication flows (sign-in, token refresh, federation) work correctly, then disable the inversion to restore traffic to the primary. This test confirms your end-to-end failover path is functional.
When you’re confident in the basic failover path, graduate to more realistic failure simulations with AWS Fault Injection Service (FIS). Create FIS experiment templates that disrupt your primary Region’s Amazon Cognito dependencies; for example, block network access to a dependent resource or inject latency into downstream API calls. Use FIS stop conditions (guardrails) to automatically halt experiments if unexpected impacts are detected. These experiments validate not just that failover triggers correctly, but that your replica Region handles real authentication load under degraded conditions.
We recommend conducting failover tests on a predefined and regular cadence and after any significant changes to your authentication architecture. Document your runbooks and make sure your operations team is familiar with both the failover and recovery procedures.
Conclusion
In this post, we built on the foundational knowledge of the Amazon Cognito MRR capability and showed you how to architect resilient authentication for real-world use cases:
The principle of least privilege is straightforward to articulate but challenging to maintain at scale. When teams first deploy applications to AWS, they often grant broader permissions than strictly necessary; it’s faster to get things working, and the plan is always to tighten permissions later. But later rarely comes. Permissions accumulate, AWS Identity and Access Management (IAM) principals that once needed broad access for initial deployment retain those permissions long after they’re necessary, and some principals stop being used entirely. Even small teams face this challenge—permission reviews aren’t a one-time task but an ongoing operational burden that demands automation.
AWS IAM Access Analyzer addresses detection and recommendation. It identifies unused permissions across IAM roles and users: actions that haven’t been exercised, services that haven’t been accessed, and principals that aren’t being assumed at all. For each finding, it generates a recommended policy with the excess permissions removed. Security teams can see exactly what to fix, but manual remediation doesn’t persist. A security engineer can right-size a role today, but if that role is defined in an AWS CloudFormation template or AWS Cloud Development Kit (AWS CDK) stack, the next deployment restores the original permissions. The fix must live where the role is defined, and not every role starts in the same place. Some are managed through infrastructure-as-code (IaC), where remediation means updating source code and deploying through a pipeline. Others were created manually through the AWS Management Console and have no code representation. And some principals aren’t being used at all and need a controlled decommission path. Each scenario requires a different remediation strategy.
This post walks through an automated remediation workflow that bridges the gap between detection and action. Instead of findings accumulating in a dashboard waiting for someone to investigate, the automation classifies each role by how it was created and produces a ready-to-review remediation artifact: a pull request with production-ready CDK code and a plain-English explanation for IaC-managed roles, an issue with the recommended policy and step-by-step IaC migration guidance for manually created roles, or a soft-disable issue with a monitored decommission plan for unused principals. Each output flows through your existing code review and issue tracking processes—the same workflows your teams already follow. By the end of this post, you’ll have a pattern that converts IAM Access Analyzer findings into tested, deployable code changes rather than a growing backlog of security tickets.
Understanding the problem
Unused IAM permissions increase the attack surface. Removing unused permissions limits the actions available to any compromised credentials, reducing potential impact. Roles that aren’t being assumed represent unused resources; removing them simplifies your IAM inventory and reduces potential access paths that aren’t actively monitored.
The challenge isn’t knowing what to fix. As we said earlier, Access Analyzer provides both the findings and the recommended policies. The challenge is acting on that knowledge consistently across your environment. Each finding requires context:
What the role does
Who created the role
Determining if the permission is unused or used infrequently
If the role is managed in a CloudFormation stack, or was created through the console
Multiply this by hundreds of roles and security teams face a backlog that grows faster than they can address it.
Manual remediation compounds the problem. A security engineer can right-size a role directly in the console, but that fix is fragile. If the role is defined in an IaC template, the next deployment restores the original permissions. If it was created manually, there’s no record of what changed or why, and no easy way to revert if the change causes issues.
This is where IaC changes the equation. When roles are defined in code, remediation means updating that code. Changes flow through pull requests, are reviewed by the team that owns the role, and deploy consistently across environments. The fix becomes permanent, not a point-in-time correction that drifts back on the next deployment. And because every change is tracked in version control, teams can confidently remove permissions knowing they can revert if something breaks. That safety net matters; it’s often the difference between a team acting on a finding and leaving it in the backlog.
Solution overview
The solution automates remediation by connecting four capabilities: IAM Access Analyzer for detection and policy recommendations, CloudTrail for role attribution, Amazon Bedrock for CDK code generation and plain-English explanations, and your existing continuous integration and delivery (CI/CD) pipeline for remediation execution. The workflow operates on a core principle: every IAM role has an origin, and that origin determines the remediation path.
Figure 1 shows the solution architecture: Amazon EventBridge triggers an AWS Lambda orchestrator on a daily schedule. The Lambda orchestrator integrates with IAM Access Analyzer, CloudTrail, Amazon Bedrock, and Amazon CloudWatch. Each finding is routed to one of three remediation paths: a pull request for IaC-managed roles, an issue for manually created roles, and a soft-disable issue for unused roles.
Figure 1: The daily remediation workflow; from scheduled trigger to the three role-based remediation paths
On each scheduled run, the automation retrieves active findings from IAM Access Analyzer and queries CloudTrail to determine how each role was created. Roles created through CloudFormation or AWS CDK have a traceable origin: the service principal, stack name, and originating repository. Roles created manually through the console have a different origin: the IAM user who created them and the timestamp. This distinction drives the remediation strategy.
For IaC-managed roles, the automation retrieves the IAM Access Analyzer-recommended policy and uses Amazon Bedrock to wrap it in production-ready CDK code that includes the role definition and policy statements and imports what your CI/CD pipeline needs to deploy the update. It then creates a pull request in the originating repository. The pull request (PR) includes the updated CDK code, a policy diff showing exactly which permissions are being removed, and a plain-English explanation of the changes, for example, “This change removes write access to S3, keeping only read and list permissions.” Your existing code review process evaluates the change, and after being merged, the fix deploys consistently across environments.
For manually created roles, the automation creates an issue that includes the IAM Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, and an Amazon Bedrock-generated explanation of what the permission changes accomplish. The issue also provides guidance on importing the role into your IaC codebase. This gives teams an immediate remediation path while encouraging long-term governance through IaC adoption.
For roles that aren’t being assumed at all, the automation takes a more cautious approach. Instead of taking direct action, it creates an issue recommending a soft-disable workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. The issue provides the steps and context, the team executes the decommission through their preferred process, whether that’s a console change, an AWS Command Line Interface (AWS CLI) script, or a PR removing the role from the IaC. This controlled decommission path reduces the risk of removing a role that’s used infrequently or seasonally.
The solution supports both single-account and organization-wide deployment. In single-account mode, it uses an ACCOUNT_UNUSED_ACCESS analyzer to process findings for one account. In organization mode, it uses an ORGANIZATION_UNUSED_ACCESS analyzer deployed in a delegated administrator account, which generates findings across all member accounts from a single vantage point. The Lambda function automatically detects which analyzer type is available and extracts the account ID from each finding’s resource Amazon Resource Name (ARN), so role attribution and remediation routing work the same way regardless of scope.
This three-path strategy acknowledges operational reality. Not all roles start in IaC, not all unused roles are safe to delete immediately, and forcing immediate migration isn’t always practical. The solution provides a clear path forward for each scenario: remediate IaC roles through code, give teams actionable recommendations for manually created roles, and safely decommission what’s no longer needed. Over time, your infrastructure becomes increasingly code-driven, and remediation becomes a routine part of your CI/CD process rather than a manual security task.
Technical details
Consider a company—call them AnyCompany—running 200 IAM roles across three AWS accounts. Some roles were created through AWS CDK stacks during initial deployment. Others were created manually through the console by engineers who needed quick access during incident response or prototyping. A handful haven’t been assumed in over 6 months. AnyCompany’s security team wants to act on their IAM Access Analyzer findings, but each role requires different handling. The solution’s architecture addresses this by routing each finding through a classification and remediation pipeline.
Figure 2 shows how each IAM Access Analyzer finding is processed:
The finding is first checked against exclusions and excluded findings are skipped.
Remaining findings are split by type: UnusedPermission findings retrieve a recommended policy from IAM Access Analyzer and then query CloudTrail for role origin, while UnusedIAMRole findings follow the unused role path.
By origin, IaC-managed roles generate AWS CDK code using Amazon Bedrock and create a pull request.
Manually created or unknown-origin roles create an issue with the recommended policy and IaC migration guidance.
Unused roles create a soft-disable issue to deny-all, monitor for 30 days, then delete.
All paths publish CloudWatch metrics.
Figure 2: Detailed component interactions—the orchestrator’s five steps, its four service integrations, and the three remediation paths
The rest of this section walks through each component using AnyCompany’s roles as examples.
Exclusion filtering
Before processing any finding, the Lambda function loads an exclusion configuration and checks whether the role should be skipped. This prevents the automation from creating remediation items for roles that legitimately need broad permissions.
AnyCompany excludes their break-glass role (used only during incidents), any service-linked roles, and roles tagged CriticalService. The min_unused_days threshold prevents false positives from seasonal workloads; a role that ran a quarterly batch job 25 days ago won’t generate a finding.
Detection and analysis
IAM Access Analyzer generates two types of findings relevant to this solution. UnusedPermission findings identify roles with permissions that haven’t been exercised within the analysis period. UnusedIAMRole findings identify roles that haven’t been assumed at all. The Lambda function queries both finding types separately because they follow different remediation paths.
The Lambda function auto-detects the analyzer type at startup. When ANALYZER_SCOPE is set to organization, it checks for an ORGANIZATION_UNUSED_ACCESS analyzer first and falls back to ACCOUNT_UNUSED_ACCESS if none exists. If multiple analyzers of the same type exist in the account, the Lambda function selects the first active analyzer returned by the API. To target a specific analyzer, set the ANALYZER_ARN environment variable explicitly. With an organization-level analyzer, findings include roles from all member accounts. The Lambda function extracts the account ID from each finding’s resource ARN (for example, account 111122223333 from arn:aws:iam::111122223333:role/MyRole) and carries that context through the entire pipeline: attribution, remediation, and issue or PR creation all include the originating account.
For UnusedPermission findings, the Lambda function calls GenerateFindingRecommendation to initiate policy generation, then retrieves the IAM Access Analyzer-recommended policy through the GetFindingRecommendation API. This is a key integration point: IAM Access Analyzer provides the right-sized policy with unused permissions removed, so the automation doesn’t need to generate policies itself.
Here’s what a typical finding looks like for one of AnyCompany’s application roles:
The OrderProcessorRole has write and delete permissions for Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB, but only uses read operations. The IAM Access Analyzer recommendation removes the four unused actions while preserving the three active ones.
For UnusedIAMRole findings, no recommendation is needed: the role isn’t being assumed at all, so the remediation is to disable or delete it. The Lambda function caps the number of unused role issues per run (configurable using MAX_UNUSED_ROLE_ISSUES, default 10) to avoid overwhelming teams with a flood of issues on the first execution.
Role attribution using CloudTrail
For each finding, the Lambda function queries CloudTrail to determine how the role was created. The CreateRole event contains the information needed to classify the role’s origin.
An IaC-created role looks like this in CloudTrail:
The cloudformation.amazonaws.com service principal and user agent tell the automation this role was created through a CloudFormation or AWS CDK deployment. The Lambda function then looks up the role’s tags to find the originating repository (stored in a Repository tag set during deployment).
Here, the IAMUser type and console.amazonaws.com user agent indicate someone created this role through the console. Roles created through the AWS CLI show a similar pattern: the IAMUser type with a user agent like aws-cli/2.x.x. The automation classifies both console and AWS CLI-created roles as manually created, because neither has an IaC origin that can be updated programmatically. The automation captures the username and timestamp for the remediation issue.
Cross-account role attribution
When the Lambda function processes findings from an organization-level analyzer, the role might live in a different account than the one running the function. The automation handles this by assuming a cross-account role (configurable using CROSS_ACCOUNT_ROLE_NAME, defaulting to OrganizationAccountAccessRole) in the member account, then querying that account’s CloudTrail and IAM APIs for the CreateRole event. If the cross-account assume fails—because the role doesn’t exist in that account or permissions aren’t configured—the automation falls back gracefully, classifying the role as unknown origin and creating an issue with the account ID and available context. This approach helps the automation produce an actionable output for findings even when attribution is incomplete.
Policy recommendations and AWS CDK code generation
For IaC-managed roles with UnusedPermission findings, the Lambda function retrieves the IAM Access Analyzer-recommended policy and sends it to Amazon Bedrock to generate production-ready AWS CDK code. This is an important distinction: IAM Access Analyzer decides what the policy should be, and Amazon Bedrock wraps that policy in the AWS CDK constructs, imports, and resource definitions that the CI/CD pipeline needs to deploy the update.
The prompt instructs Amazon Bedrock to convert the recommended policy to AWS CDK code exactly as provided, with no modifications:
Generate Python CDK code that creates/updates the role with the
RECOMMENDED policy exactly as provided. Include proper imports
(aws_cdk, aws_iam), use CDK best practices (PolicyStatement,
proper resource ARNs), and add tags: ManagedBy=CDK,
RemediatedBy=AccessAnalyzer.
IAM Access Analyzer generates recommendations for both inline policies and customer managed policies. When a managed policy has partially unused permissions, the recommendation contains the full right-sized policy. The automation wraps this in AWS CDK code as an iam.ManagedPolicy construct. Note that if a managed policy is shared across multiple roles, the recommendation applies to the specific role’s usage pattern. In this case, the automation generates an issue for manual review rather than a PR, because modifying a shared policy could affect other roles.
The generated code goes through a validation step before inclusion in any PR. The Lambda function compiles the Python code to check for syntax errors and verifies that required AWS CDK patterns (iam, PolicyStatement) are present. If validation fails, the finding is logged as an error rather than creating a broken PR.
The solution doesn’t currently invoke the IAM Access Analyzer ValidatePolicy API to check the generated policy for errors or overly permissive statements. However, this is a natural extension point. Teams can add a validation step that calls ValidatePolicy on the Amazon Bedrock-generated policy before including it in a PR, detecting issues like missing resource constraints or invalid action names.
Amazon Bedrock also generates a plain-English explanation of the policy changes. For AnyCompany’s OrderProcessorRole, the explanation might read:
“The role currently has full S3 write access and DynamoDB delete permissions, but only uses read operations. Removing s3:PutObject, s3:DeleteObject, s3:PutBucketPolicy, and dynamodb:DeleteItem reduces the scope of impact if credentials are compromised, while preserving the s3:GetObject, s3:ListBucket, and dynamodb:Query permissions the application needs.”
The solution uses the Anthropic Claude Sonnet model on Amazon Bedrock for CDK code generation (where accuracy matters) and Claude Haiku on Amazon Bedrock for explanations (where speed and cost efficiency matter more).
Three-path remediation
The Lambda function evaluates each finding’s origin and routes it to one of three remediation paths.
Path 1: IaC-managed roles (pull request) – For AnyCompany’s OrderProcessorRole, the automation creates a PR in the originating repository. The PR includes:
The Amazon Bedrock-generated AWS CDK code implementing the IAM Access Analyzer-recommended policy
A policy diff showing exactly which permissions are being removed
The plain-English explanation of what the changes accomplish
Labels (security, iam-remediation, automated) for filtering and tracking
The team that owns the role reviews the PR through their normal code review process. Once merged, the fix deploys consistently across environments through the existing CI/CD pipeline.
Path 2: Manually-created roles (issue) – For AnyCompany’s IncidentResponseRole, the automation creates an issue that includes the Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, an Amazon Bedrock-generated explanation, and step-by-step guidance on importing the role into IaC. This gives the team an immediate remediation path (apply the recommended policy) while encouraging long-term governance through IaC adoption.
Path 3: Unused roles (soft-disable issue) – For roles that haven’t been assumed at all, the automation creates an issue recommending a three-stage decommission workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. This controlled approach reduces the risk of removing a role that’s used infrequently or seasonally – if something breaks during the monitoring period, removing the deny-all policy restores access immediately.
Dry-run mode
Before creating real PRs and issues, you can run the automation in dry-run mode by setting “dry_run": true in the CI/CD configuration or setting the CI_CD_PLATFORM environment variable to dryrun. In this mode, the Lambda function processes findings, classifies roles, and generates remediation data, but logs what it would create instead of making actual API calls to your repository platform. You can use the log to validate the automation’s behavior, review the classification accuracy, and tune exclusions before going live.
Operational metrics
The Lambda function publishes CloudWatch metrics after each run:
findings_processed
Total UnusedPermission findings evaluated
iac_roles_found
Roles classified as IaC-managed
manual_roles_found
Roles classified as manually created
unused_roles_found
Roles with no assume activity (UnusedIAMRole findings)
prs_created
Pull requests created for IaC roles
issues_created
Issues created (manual roles and unused roles)
errors
Processing errors (failed classifications, API failures)
These metrics feed into dashboards and alarms. AnyCompany sets an alarm on errors > 5 to catch API throttling or configuration issues, and tracks prs_created + issues_created over time to measure remediation velocity.
Implementation
The solution ships as two AWS CDK stacks and deploys in minutes. The accompanying GitHub repository contains the complete source code, AWS CDK stacks, configuration templates, and step-by-step deployment instructions.
At a high level, deployment involves:
Prerequisites: An AWS account with an ACCOUNT_UNUSED_ACCESS or ORGANIZATION_UNUSED_ACCESS analyzer enabled, Python 3.11 or later, AWS CDK v2, a CI/CD platform API token stored in AWS Secrets Manager, and Amazon Bedrock model access for the Anthropic Claude models you plan to use. The model IDs are configurable environment variables (BEDROCK_CODEGEN_MODEL and BEDROCK_EXPLANATION_MODEL); Amazon Bedrock retires older foundation models over time, so if the shipped defaults stop working, set these variables to current models you have enabled and redeploy. The repository README documents this.
Configuration: Two files in the config/ directory control behavior. exclusions.json defines which roles and permissions to skip (break-glass roles, service-linked roles, tagged exceptions), and ci_cd_config.json configures your repository platform integration (GitLab or GitHub), labels, and throttling limits.
Deploy: Run cdk deploy --all to create the Lambda function, EventBridge schedule, IAM roles, and CloudWatch alarms.
Validate in dry-run mode: Start with “dry_run": true to see how the automation classifies your roles without creating real PRs or issues. Review the CloudWatch logs to confirm attribution accuracy and tune exclusions.
Go live: Set “dry_run": false and redeploy. The Lambda function runs on schedule (daily by default) and begins creating PRs and issues.
The repository README covers each step in detail, including organization-wide deployment, cross-account configuration, and platform-specific setup for GitLab and GitHub.
Operational considerations
Deploying the automation is only the starting point. Running it in production means making decisions about how roles are retired, how the volume of findings is managed at scale, which roles warrant human review before any change is proposed, and how you measure the automation’s impact over time. The following practices keep remediation sustainable as your IAM footprint grows, so the automation reduces operational burden rather than adding to it.
Unused role lifecycle
Unused roles follow a three-stage decommission workflow. When the automation identifies a role that hasn’t been assumed within the analysis period, it creates an issue with the recommended decommission steps; the automation doesn’t modify the role directly. The team then follows the soft-disable approach:
Attach a deny-all inline policy to the role. This blocks all actions without deleting the role or its existing policies.
Monitor for 30 days. If a workload depends on the role (seasonal jobs, infrequent batch processes), the deny-all policy surfaces the dependency quickly. Removing the deny-all policy restores full access immediately; no need to recreate the role or reattach policies.
Delete the role after the monitoring period confirms no impact.
This approach is deliberately conservative. Deleting a role is irreversible; you lose the trust policy, attached policies, and any resource-based policies that reference it. The soft-disable step gives teams a safety net while still making progress on reducing their unused role inventory.
Scaling and throttling
On AnyCompany’s first run, the automation found 47 unused permission findings and 4 unused roles. That’s manageable. But organizations with hundreds of accounts and thousands of roles might see significantly more findings on initial deployment.
This is especially true with an organization-level analyzer. A single-account deployment might surface dozens of findings; an organization-level analyzer across multiple accounts could surface hundreds or thousands on the first run. The throttling controls become critical at this scale.
Two throttling controls prevent the automation from overwhelming teams:
max_findings_per_run (default 50): Caps the total UnusedPermission findings processed per Lambda function execution. Remaining findings are picked up on the next scheduled run.
MAX_UNUSED_ROLE_ISSUES (default 10): Caps unused role issues per run. This is especially important during initial deployment when you might have a large backlog of roles that haven’t been assumed in months.
Start with conservative limits and increase them as your team builds confidence in the review process. A team that can review 10 PRs per week shouldn’t receive 50 on Monday morning.
Approval workflows for sensitive roles
Not every role should receive automated PRs. Roles with administrative permissions or access to sensitive data might warrant manual review before any remediation is created. The exclusion configuration supports this through the approval_required_for_tags field:
Roles matching these tags generate issues for manual review instead of automated PRs, regardless of whether they’re IaC-managed. This gives security teams a checkpoint for high-risk roles while still automating remediation for standard application roles.
Monitoring and alerting
The metrics published after each Lambda function run (covered in the Technical details section) feed into CloudWatch dashboards and alarms. A few patterns worth setting up:
Alert on errors > 5 per run to catch API throttling, expired CI/CD tokens, or Amazon Bedrock availability issues.
Trackprs_created + issues_created over time. A healthy trend shows this number decreasing as your environment converges toward least privilege.
Monitorunused_roles_found as a leading indicator. A sudden increase might signal a team spinning up roles for a project and not cleaning up afterward.
Compareiac_roles_found to manual_roles_found over time. As teams adopt IaC, the ratio should shift toward IaC-managed roles, which means more automated remediation and less manual work.
Cost
The solution uses Lambda (minimal cost at daily execution), CloudTrail (typically already enabled), IAM Access Analyzer (charges per IAM role or user analyzed per month for the unused access analyzer), and Amazon Bedrock (pay-per-token for AWS CDK code generation and explanations). For most organizations the ongoing cost is low, and Amazon Bedrock token usage is the largest variable, scaling with the number of findings processed per day and the complexity of each policy. Review the pricing pages for each service for current rates.
For organization-level deployments, the IAM Access Analyzer cost scales with the number of IAM roles analyzed across all member accounts. The ORGANIZATION_UNUSED_ACCESS analyzer charges per role per month across the organization, so an organization with 500 roles across 20 accounts will see higher analyzer costs than a single account with 50 roles. Review the IAM Access Analyzer pricing page for current rates.
Cleanup
To remove the solution, run cdk destroy --all from the infrastructure/ directory. This removes the Lambda function, EventBridge rule, CloudWatch alarms, and IAM roles created by the stacks.
If you stored a CI/CD platform API token in Secrets Manager as part of deployment, delete it with aws secretsmanager delete-secret --secret-id <your-secret-name> --recovery-window-in-days 7. The 7-day recovery window lets you restore the secret if the deletion was accidental. After 7 days, the secret is permanently deleted and can’t be recovered. To delete immediately without a recovery window, add --force-delete-without-recovery.
Lambda automatically creates a CloudWatch Logs log group at /aws/lambda/<function-name> that persists after cdk destroy --all and continues to incur log storage charges. To remove it, run aws logs delete-log-group --log-group-name /aws/lambda/<function-name>. WARNING: This permanently deletes all execution logs.
The IAM Access Analyzer isn’t created by the AWS CDK stacks. WARNING: Deleting the analyzer permanently removes all findings, analysis history, and unused permission data. Export any findings you need to retain before deletion. After exporting, run aws accessanalyzer delete-analyzer --analyzer-name <your-analyzer-name> to delete it. The ACCOUNT_UNUSED_ACCESS and ORGANIZATION_UNUSED_ACCESS analyzer types incur charges based on the number of IAM roles and users analyzed per month.
If you deployed in organization mode and created cross-account roles (default name: OrganizationAccountAccessRole) in member accounts solely for this solution, remove them from those accounts.
Any PRs or issues already created in your CI/CD platform remain after stack deletion; they’re artifacts in your repository, not AWS resources. See the repository README for detailed cleanup instructions.,
Conclusion
Automating IAM permission remediation turns least privilege from a periodic compliance exercise into an operational practice. By connecting IAM Access Analyzer findings and recommendations to your CI/CD pipeline, remediation shifts from manual security tasks to code review processes that your teams already follow.
The three-path strategy acknowledges how infrastructure evolves. IaC-managed roles receive pull requests with production-ready AWS CDK code and plain-English explanations. Manually created roles receive actionable issues with recommended policies and IaC migration guidance. Unused roles are put on a controlled decommission path that protects against accidental disruption. Over time, the manual role count decreases as teams adopt IaC, and remediation becomes a routine part of your deployment pipeline.
Start with a pilot. Choose 10–20 non-production roles, deploy in dry-run mode, and review the classification results. Tune your exclusions, confirm the CloudTrail attribution is accurate for your environment, and then enable live remediation. Expand to production roles after your team is comfortable with the review cadence.
When you’re ready to scale beyond a single account, switch to an organization-level analyzer and the same Lambda function will process findings across all member accounts with no architectural changes required, only a configuration toggle.
The complete source code, AWS CDK stacks, and configuration templates are available in the accompanying GitHub repository.
If you have feedback about this post, submit comments in the Comments section below.
October 20, 2026: This post was republished to reflect the new migration capability from Active Directory to an external identity provider (IdP) or the Identity Center directory, now available in IAM Identity Center.
September 2, 2026: This post was republished to include Active Directory migration strategies and automation for permission sets.
Organizations that are switching identity providers (IdPs), consolidating identity infrastructure, adopting new single sign-on capabilities, or migrating off legacy on-premises systems may need to change the identity source in IAM Identity Center. Previously, migrations from Active Directory to another identity source deleted users, groups, memberships, and assignments at the moment of cutover. Now, migrations away from Active Directory preserve your users, groups, memberships, and assignments, just as transitions between an external IdP and the Identity Center directory already do. Only switching to Active Directory still removes users, groups, and assignments. Because the change applies to the entire Identity Center instance at once, test validation and a dress rehearsal are strongly recommended.
This post walks you through the migration process and provides sample code to assist the transition. It includes architectural guidance and a step-by-step runbook for switching from Active Directory to Okta. This guide helps AWS administrators, identity engineers, and project teams switch identity sources safely.
Note: This walkthrough uses Okta as a representative example of a SAML 2.0 identity provider. The inclusion of Okta in this example does not constitute an endorsement of any specific identity provider.
Identity source options in IAM Identity Center
The identity source is the definitive system of record: it determines which directory holds the primary copy of user identities and group memberships used for AWS access.
Each IAM Identity Center instance connects to one identity source at a time. IAM Identity Center supports three main identity sources:
Identity Center directory – The default identity store. Users and groups are created and managed directly within IAM Identity Center, with no dependency on an external provider. Suitable for organizations without an existing enterprise directory or those wanting a setup that uses only AWS services.
External IdP – Integration with third-party providers that support SAML 2.0, including Okta Universal Directory, Microsoft Entra ID (formerly Azure AD), Ping Identity, and others. This is the approach covered in the migration runbook that follows.
For example, migrating from Active Directory to an external IdP carries your existing users and groups over to the new identity source. IAM Identity Center keeps the same identity store, user IDs, and group IDs, and SCIM updates only the external identifier (externalId) to reflect the new source.
How access flows to AWS resources
IAM Identity Center grants access to AWS resources in two ways, as shown in Figure 1:
Permission set assignments – Users or groups are assigned permission sets within specific AWS accounts. This enables assume-role access, and AWS Identity and Access Management (IAM) roles (named AWSReservedSSO_...) are automatically created in each account to back these assignments.
Application assignments – Users or groups are granted access to AWS-managed applications (such as Amazon SageMaker Studio, Amazon OpenSearch Service and so on) and customer-managed applications integrated with IAM Identity Center.
Figure 1: Granting access to AWS resources for users and groups managed by an identity source in IAM Identity Center
When you change the identity source, the downstream impact on these assignments depends heavily on which sources you’re switching from and to. In some transitions, assignments remain intact.
When you switch the identity source from Active Directory to an external IdP or to the Identity Center directory, users, groups, user and group IDs, group memberships, and their associated assignments are preserved. Users keep their access to AWS accounts and applications after the new identity source takes over. Switching to Active Directory from any source removes users, groups, and assignments at the moment of cutover, so pre-migration backup and post-migration restoration are still essential in that scenario.
What changes when switching identity source in IAM Identity Center
Migrations away from Active Directory, and transitions between an external IdP and the Identity Center directory, now preserve users, groups, memberships, and assignments. Transitions to Active Directory removes users, groups, and assignments permanently from IAM Identity Center at the moment of cutover, as shown in the following table. For more information, see Considerations for changing your identity source.
IAM Identity Center item
Status upon switch from AD to external IdP or Identity Center directory
Status upon switch from external IdP or Identity Center directory to AD
Users and groups in Identity Center
Preserved (same user and group IDs; the externalId changes as the new source takes over)
Deleted (must be re-provisioned from AD)
Account assignments
Preserved
Deleted (must be recreated)
Application assignments
Preserved*
Deleted (must be recreated)
Note: *Test each application in a non-production environment before you migrate. Also inventory any assignments that live inside an application itself, because those sit outside IAM Identity Center.
Before you start: common blockers
Matching attribute – Confirm which attribute your target IdP uses to find an existing user (sometimes called matching precedence or existing resource lookup). The IdP must take over each existing Identity Center user and group rather than create a duplicate. Test this in a non-production environment.
Required attributes – Every user must have a username, first name, last name, and display name. If any required attribute is missing, that user silently fails to provision. If you send email, it must be unique and single-valued.
Username and NameID – Each user’s IdP userName must exactly match the existing Identity Center username, and the SAML NameID must map to the same value. Decide your sign-in identifier (for example, a legacy sAMAccountName or a UPN) before cutover.
Groups – Confirm that your IdP supports group provisioning through SCIM (for example, Google Workspace provisions users only). Group names must be unique, and renaming a group can cause it to be treated as new, which strands its assignments. Depending on the external Identity provider, users who belong to a group only through a nested group are not provisioned and lose group-based access. Inventory nested groups and directly assign the child groups that contain those users before cutover.
Emergency access – Set up a break-glass administrative access path that does not depend on AWS Identity Center.
Sample deployment
The following five-step summary (expanded into seven phases in the runbook that follows) applies to an identity source transition in IAM Identity Center from Active Directory to Okta, focusing on permission set assignments. The AD-to-Okta runbook in the next section expands each of these steps with specific instructions and commands. To assist users, you can also use the Identity Center migration tool script, which provides a structured workflow for Identity Center migrations with commands for precheck, cutover, validation, and cleanup. Because assignments are now preserved, the restore command is used only for manual rollback. The sample scripts and detailed steps are available on GitHub.
Note: This solution is available in the GitHub aws-samples repository. You can report bugs or make feature requests through GitHub Issues. The builders of this solution can help with GitHub issues. Enterprise Support customers can reach out to their Technical Account Manager (TAM) for further questions or feature requests.
Prerequisites
Before you start this walkthrough, make sure you have the following prerequisites in place:
Python 3.10 or later
AWS credentials configured using environment variables, an AWS configuration file, or a named AWS Command Line Interface (AWS CLI) profile (specified with --profile)
An active IAM Identity Center instance in the target account
Okta Global Admin access
Install the migration tool as described in the README file
Basic solution walkthrough
The following steps summarize the migration process. The next section expands each step with detailed Okta-specific instructions and commands.
Step 1: Back up users, groups, and assignments – Before making any changes, export your current identity data such as users, groups, and all assignments. This backup protects you if something goes wrong during migration. Store them in a secure, access-controlled location. The runbook includes a script that exports all current IAM Identity Center assignments and principals to a CSV file, then validates referential integrity.
Step 2: Prepare and validate users and groups in the target identity source – Before switching the IAM Identity Center identity source, confirm that your users and groups exist in the new authoritative source. Verify usernames, display names, email addresses, group names, group memberships and other required attributes. Each user’s userName in the new source must exactly match the existing Identity Center username, because this is how the new source usually takes over the user. In a test environment, confirm that an existing user is matched, not duplicated.
Step 3: Switch IAM Identity Center to the new identity source, and configure sign-in – Update IAM Identity Center to point to the new identity source. For external IdPs, upload the SAML metadata and configure the Assertion Consumer Service (ACS) and issuer URLs in your IdP. Before enabling SCIM (System for Cross-domain Identity Management), confirm that a pilot user can sign in.
WARNING: The identity source change applies to the entire Identity Center instance. After you confirm it, Active Directory sync and authentication stop, and users can’t sign in until SAML sign-in works with the new IdP. Users, groups, memberships, and assignments are preserved.
Step 4: Enable SCIM provisioning and verify takeover – Enable automatic provisioning and assign users and groups to the IAM Identity Center application in your IdP. The IdP takes over each existing user and group. Then run the validate command to compare the live assignments against your backup and find any missing or extra assignments.
If drift is found, the script writes a drift_report.csv file with MISSING and EXTRA entries.
Step 5: Validate access – Test access for a sample of users across different roles and permission levels before declaring the migration complete. Confirm that users can authenticate through the new identity source, access their expected AWS accounts, and assume the correct IAM roles. Confirm that the identity source shows your external IdP, that users and groups keep the same IDs, and that no duplicates were created.
Detailed runbook for Okta migration
This runbook covers one of the most common identity source transitions: migrating from an Active Directory to Okta as a SAML 2.0 identity provider.
The sample deployment describes what happens during a transition. It walks through seven phases: stakeholder alignment and pre-migration inventory, pre-cutover validation, the identity source switch itself, takeover verification, post-migration testing, ongoing cleanup and monitoring, and a documented manual rollback procedure for when things don’t go to plan.
If you’re migrating to Active Directory, which still removes users, groups, memberships and assignments, you can adapt the backup and restore scripts from this guide.
Phase 1: Plan your pre-migration activities
Pre-migration planning has four components: stakeholder engagement, inventory, scheduling, and access verification. Complete all four before you schedule the cutover.
1.1 – Document relevant stakeholders:
Fill out this table with actual contact information. You’ll need to reach these people during the cutover window.
Before any changes are made, document the complete current state of your IAM Identity Center configuration. Capture a baseline of all three assignment layers: the users and groups assigned to the IAM Identity Center application in your IdP, the account and application assignments in IAM Identity Center, and any assignments inside the applications themselves:
Run the precheck script to export all current Identity Center assignments and principals to CSV.
assignments.csv – One row per account, permission-set, and principal assignment
principals.csv – All users and groups from the identity store
1.3 – Define the cutover window:
Schedule the migration during a low-usage period to minimize user impact. Size the maintenance window using timings from a full-dress rehearsal in a test environment. SCIM provisioning is rate-limited, so for large directories, sync users in batches. Identify a maintenance window of sufficient length to complete all phases, including time for validation and potential manual rollback (described in Phase 7) if needed. Notify all affected users in advance of the potential temporary disruption to single-sign-on access.
1.4 – Confirm access requirements:
Verify that the following access is confirmed and tested before the cutover window:
AWS Administrator access to IAM Identity Center and AWS Organizations.
Identity provider (IdP) administrator access (for example, Okta) to configure the IAM Identity Center application, create the SCIM integration, and assign users to the AWS app.
A break-glass or emergency administrative access path that does not depend on the identity source you are migrating.
Phase 2: Complete final pre-cutover steps
Before starting the cutover, complete the final validation, access, and communication checks described in this phase.
2.1 – Export IAM Identity Center configuration:
Validate that the backup files generated in Step 1.2 are present and non-empty before proceeding.
2.2 – Communicate impact to users:
Send advance notice to all affected users covering:
The migration timeline and expected impact window.
That users can’t sign in between the identity source change and the new IdP’s sign-in going live, but that their access and assignments are unchanged.
The new sign-in process. After migration, users sign in through your IdP (for example, the Okta My Apps dashboard) or the AWS access portal, depending on the sign-in flow you choose.
Whether the new sign-in flow is IdP-initiated (through Okta) or SP-initiated (through the AWS access portal), and any differences in the user experience.
After migration, the d-xxxxxxxxxx.awsapps.com/start access portal URL is no longer supported, and the console shows the supported dual-stack regional URL (https://ssoins-<instance-id>.portal.<region>.app.aws) instead, so you must communicate the new URL and update bookmarks/allow-lists.
That the custom access portal alias (friendly URL) isn’t supported after migrating away from Active Directory. If a proxy or bookmark relies on redirect flows, plan to update it.
Prepare a user guide for the new sign-in process and an FAQ for common issues. Schedule a training session to demonstrate how to access AWS through Okta. Ensure your support team is briefed and ready to handle an influx of access issues during and immediately after the cutover.
2.3 – Validate Okta-to-IAM Identity Center sync (pre-cutover testing):
Using a sandbox or test environment if available, perform the following validation steps before executing against production:
Run the full migration in a test instance that mirrors your production AD configuration and applications and confirm that existing test users are matched by Okta and not duplicated.
Use the AWS Management Console for IAM Identity Center to verify that groups and users appear in Users & Groups with the correct attributes.
Test the complete end-to-end sign-in flow for a test user. Authenticate through Okta, access the AWS portal, and assume a role in a test account. Confirm that the user keeps access to their assigned accounts, permission sets, and applications.
Phase 3: Complete the cutover
You’re ready to configure Okta, switch the IAM Identity Center identity source, and complete the production cutover.
Important: Downtime begins when you confirm the identity source change in Step 3.2 and ends when SAML sign-in works through Okta. Have the Okta application, SAML metadata, and signing certificate ready before you start. Users, groups, memberships, and assignments are preserved.
3.1 – Configure the Okta application:
Sign in to Okta as an administrator.
Navigate to Applications and then to Browse App Catalog.
Search for AWS IAM Identity Center and choose Add Integration. Choose Done.
Choose the newly created app and select the Sign On tab.
Locate the Metadata URL (it will look like: https://<your-okta-domain>/app/<app-id>/sso/saml/metadata). Open this URL in a new browser tab.
An XML file will render in the browser. Save this file. This is your SAML metadata file, which will be uploaded to IAM Identity Center.
Download and save the SAML signing certificate from the Sign On tab.
3.2 – Switch the identity source in IAM Identity Center:
In the IAM Identity Center console navigation pane, choose Settings.
Choose Actions and select Change Identity Source.
Important: This change applies to the entire Identity Center instance. On the confirmation screen, you must enter ACCEPT to confirm. During this step and before SCIM provisioning is enabled, if the change could not be completed by Identity Center you will see a clear error message in the console to retry changing identity providers. It is safe to retry.
Select External Identity Provider.
Upload the XML metadata file and the SAML signing certificate downloaded from Okta.
Confirm the change. IAM Identity Center will display progress updates as it migrates to the new identity provider.
Don’t enable automatic provisioning yet. Complete Step 3.3 and confirm pilot sign-in in Step 3.4 first.
3.3 – Configure the ACS and issuer URLs in Okta:
In the IAM Identity Center console, choose Settings and then Actions. Select Manage Authentication.
Copy the IAM Identity Center Assertion Consumer Service (ACS) URL and the IAM Identity Center Issuer URL.
Return to Okta and choose Applications and select IAM Identity Center app. Select the Sign On tab and choose Edit.
Under Advanced Sign On Settings, paste the ACS URL and Issuer URL into the corresponding fields.
Choose Save.
3.4 – Confirm pilot sign-in:
Before you enable SCIM provisioning, assign an existing pilot user to the IAM Identity Center application in Okta and confirm they can sign in through the AWS access portal. The SAML NameID that Okta sends must exactly match the user’s existing Identity Center username. If sign-in fails, fix the mapping now before proceeding to the next step.
3.5 – Enable automatic provisioning (console) and connect SCIM in Okta:
In the IAM Identity Center console, choose Settings, then choose Enable Automatic Provisioning. Copy and securely record the SCIM endpoint URL and access token.
Return to the IAM Identity Center app in Okta. Choose the Provisioning tab.
Choose Configure API Integration.
Paste the SCIM Endpoint URL into the Base URL field.
Paste the Access Token into the API Token field.
Choose Test API Credentials. You should receive confirmation that the credentials are valid.
Choose Save.
On the Provisioning page, choose Edit and under To App enable all three provisioning options (Create Users, Update User Attributes, and Deactivate Users). Choose Save. (The To App settings control how Okta provisions users to IAM Identity Center. All three options are required for the migration to work correctly.)
On the Push Groups tab, push the groups that are assigned to the AWS application. Group names must exactly match the existing group names in IAM Identity Center.
In the attribute mappings, confirm that userName maps to the existing Identity Center username and that first name, last name, display name, and a single email address are populated.
3.6 – Test SCIM takeover:
Before you assign all users, verify that Okta takes over existing users correctly:
In Okta, select an existing pilot user who already exists in IAM Identity Center (People).
Open the user and navigate to the Applications tab.
Assign the AWS IAM Identity Center app to this test user.
Wait 5–10 minutes for SCIM sync to run.
In the IAM Identity Center console, select Users and confirm that the pilot user still has the same user ID, that no duplicate user was created, and that the user’s assignments still work.
Note: If the user is duplicated or doesn’t update after 10 minutes, check the Okta System Log for SCIM provisioning errors and verify the SCIM endpoint URL and token are correctly configured.
After the pilot user is taken over successfully, assign the remaining users and groups to the application in Okta. For large directories, assign them in batches.
Phase 4: Verify takeover
Now that you’ve completed cutover, verify that Okta has taken over all users and groups and that the preserved assignments match your pre-migration baseline.
4.1 – Verify SCIM takeover:
Confirm that all production users and groups are provisioned from Okta, that they keep the same user and group IDs, and that no duplicates were created. Check the Okta provisioning logs for errors such as “Refused to create a new, duplicate resource.”
4.2 – Check for assignment drift: Compare the live assignments against the pre-migration CSV
If drift is found, the script writes a drift_report.csv file with MISSING and EXTRA entries. Because assignments are preserved, investigate any entries before you continue.
Phase 5: Post-migration validation
After the cutover, validate end-to-end access for representative user roles and confirm that assignments were preserved.
5.1 – Test end-to-end access:
Using a test Okta user account, complete the following validation steps:
Sign in to the Okta Dashboard.
Choose the AWS IAM Identity Center tile under My Apps.
Select an assigned AWS account from the portal.
Confirm that you can assume a role and access the AWS console.
Test role switching within the console to validate permission boundaries.
5.2 – Spot-check multiple user types:
Validate access for a representative sample of users across different access levels, including Administrator, Developer, Read-Only or Audit, and any other standard roles defined in your environment. Confirm that permission sets are correctly mapped and that no unintended access has been granted or denied.
For each application, confirm that user-specific data and settings are intact and that any assignments inside the application still work.
Phase 6: Post-migration cleanup and monitoring
After confirming the migration is stable, shift focus to ongoing monitoring of provisioning and authentication, and update your operational documentation.
6.1 – Decommission AD only when stable:
Don’t decommission the Active Directory domain controllers until you’re confident the migration is stable and rollback is no longer needed. Keep AD online as a fallback. Deleting the AD directory removes the manual rollback option and the AD-based access portal endpoint.
The following command will identify disabled users, empty groups, and unassigned permission sets.
```bash
# Report only
python -m idc_migration_tool cleanup

# Report and prompt for deletion
python -m idc_migration_tool cleanup --delete
```
6.2 – Monitor SCIM sync:
Confirm that SCIM provisioning continues to run without errors in the days following migration.
Monitor new user onboarding from Okta to verify that newly created Okta users are automatically provisioned into IAM Identity Center.
Review IAM Identity Center and AWS CloudTrail logs for failed sign-in attempts or unexpected authentication errors.
6.3 – Update documentation:
Update all internal documentation to reflect the new identity architecture:
Record the SCIM integration details, SAML metadata links, and new group-to-permission-set mappings.
Update internal SOPs and onboarding guides to reflect the new Okta-based login process.
Document troubleshooting procedures for the most common failure modes.
6.4 – Post-migration checklist:
Before closing the migration project, confirm all of the following:
Users can authenticate successfully through Okta.
Permission sets are correctly assigned to the correct users and groups.
Account assignments are working correctly across accounts.
Monitoring and logging are configured and alerting on anomalies.
Internal documentation and SOPs are updated.
Support team is trained on the new login process.
Rollback procedures have been reviewed and are ready if needed.
Active Directory integration cleanup is scheduled (do not rush decommission).
Phase 7: Rollback (if needed)
Rollback requires manually switching the identity source back to Active Directory, which deletes users, groups, memberships and assignments, and then rebuilding assignments from the pre-migration backup files, as described in the following steps.
Note: Define in advance what counts as a failure, who makes the rollback decision, and the acceptable discrepancy threshold. Only initiate rollback if the Okta migration has failed and cannot be recovered within the migration window. Rollback is a manual, time-consuming process. There is no single-button undo for an identity source switch.
7.1 – Switch identity source back to Active Directory:
Navigate to IAM Identity Center and choose Settings, then Actions, and then Change Identity Source.
Select Active Directory as the identity source.
Select your existing AD domain. Ensure AD is still running and reachable before confirming.
Accept the conditions and confirm the switch. Identity Center will display progress updates.
When complete, choose Resume Sync, then choose Start Guided Setup.
Confirm the attribute mappings and select the users and groups to sync.
Review and save the configuration.
7.2 – Wait for AD users and groups to repopulate:
After completing the guided setup, AD users and groups will begin to reappear in IAM Identity Center through the directory sync. This might take several minutes depending on the size of your directory.
7.3 – Recreate account assignments:
Recreate the assignments from the pre-migration CSV file. This will resolve each principal name in identity store, create the assignment, and poll until completion, and produce a summary of succeeded, failed, and skipped counts.
Confirm users can authenticate using the original AD-based AWS access portal URL and can access their expected AWS accounts and roles. Test key role types (such as Admin, Developer, and Audit) before declaring rollback complete.
Troubleshooting the cutover
The identity source change in Step 3.2 runs as a sequence of steps: stopping Active Directory sync, disconnecting the directory, and deleting the AD sync profile. If a step after “Stopping Active Directory sync” fails, the Confirm change screen reports which steps failed and offers a Retry failed steps button. You will see one of two error messages, both safe to retry:
“The identity source change could not be completed. Please try again.” — AD sync was stopped but the directory wasn’t disconnected, so new users and changes are not currently syncing from Active Directory. Choose Retry failed steps to complete the transition. If instead you want to stay on Active Directory, choose Start guided setup in the Settings page to reconfigure the sync.
“The identity source change could not be completed. Your identity source has been reverted to Active Directory. Please try again.” — IAM Identity Center automatically rolled back to a healthy AD-connected state, and a banner confirms that AD sync resumed. You don’t need to reconfigure the sync; choose Retry failed steps when you’re ready to try again.
Important: In both cases, choose Retry failed steps on the Confirm change screen. If you navigate away from this screen, you can no longer retry the failed steps and will need to restart the identity source change.
If you have feedback about this post, submit comments in the Comments section below.
Conclusion
This post covered how to migrate your IAM Identity Center identity source from Active Directory to an external identity provider (Okta), including backing up existing assignments, validating your target identity source, performing the cutover, verifying that the new identity source took over your users and groups with their assignments intact, validating access, and rolling back if needed.
For the backup and restore scripts referenced in this guide, see the aws-samples GitHub repository. For more information about IAM Identity Center configuration and permission set management, visit the AWS Security Blog and the AWS IAM Identity Center documentation.
AWS IAM Identity Center integrates with external identity provider (IdP) to provide customers with a centralized authentication and authorization solution for AWS resources across AWS Organizations. AWS continues to invest into IAM Identity Center with a growing number of AWS services that natively integrate with IAM Identity Center. As your AWS organization scales, maintaining visibility into who has access to which applications and enforcing governance policies across accounts and Regions becomes increasingly complex. Identity Center helps address this by centralizing authentication and authorization for AWS resources across your organization, integrating with your external identity provider and a growing number of AWS services. However, as adoption scales, tracking access assignments and enforcing governance policies consistently becomes its own challenge.
This blog post focuses on planning your integration between an identity provider and IAM Identity Center for managed applications in your organization. We also walk through deploying and using an automated Identity Center discovery and reporting sample solution to help answer the governance and security questions:
Which users or groups have access to which AWS applications?
Who last accessed a specific AWS application and when?
Which users and groups are assigned to which IAM Identity Center applications across organization and AWS Regions?
How can you quickly generate reports to assist with compliance audits or security reviews?
The sample solution will identify associated AWS applications and the corresponding user and group assignments for the IAM Identity Center instances within your organization. The output is stored in a queryable format and generates CSV files for downstream analysis or reporting.
Plan identity governance for Identity Center application assignments
There are four key areas to start on when planning how to manage delegation and provisioning access across IAM Identity Center managed AWS applications. Bring together key stakeholders across security, governance, application, and business teams to make sure the implementation and integration will fit into the overall identity governance strategy.
Who can provision managed AWS applications: You can implement the IAM restrictions for creation of new AWS resources within AWS accounts in your organization. For example, if you restrict provisioning into a production AWS account to only infrastructure as code (IaC) IAM roles, you would continue implementing restrictions using AWS identity policies, service control policies (SCP), resource control policies (RCP), or IaC policy evaluation tools like Open Policy Agent (OPA) or Checkov.
Who manages user and group assignments: The managed application administrator handles authorization to managed applications within an AWS account. It’s recommended to clearly define roles and responsibilities across the workflow. You would have an IaC pipeline manage the integrated AWS resource provisioning with IAM Identity Center, then another workflow to allow requests to manage user and group membership for the managed application.
How authentication flows from the IdP to AWS resources: Users will authenticate into Identity Center, then be authorized to access AWS managed applications. From there, they will be authorized to access the associated AWS service and resources tied to the managed application. Depending on the AWS service, the associated downstream resources might have their own IAM principals that the users can access.
Mapping IdP identities to AWS resource access: There needs to be a link for workforce users and groups in your IdP, to Identity Center managed applications, and to downstream resources and permissions. Identifying the relationship will help you understand access within your AWS environment. Trusted identity propagation (TIP) is an additional feature of Identity Center that provides an end to end trail of the identity to the downstream service.
Create and manage an Identity Center application assignment lifeycle
After you have IAM Identity Center set up within an organization instance, your member AWS accounts can start creating associated AWS resources. Within each member AWS account, the IAM principals that provision AWS resources will need two types of service-specific IAM permissions:
The first type of IAM permissions will be specific to the AWS service you want to provision. For example, to create an Amazon SageMaker AI domain, you would need the same IAM permissions to create the SageMaker AI domain and the downstream AWS resources SageMaker AI might use.
The second type of IAM permissions is specific to IAM Identity Center. The IAM principal used to create the resource, in this example SageMaker AI, will also need permissions to manage applications within the Identity Center instance.
IAM Identity Center application Amazon Resource Names (ARNs) follow a different standard naming convention that isn’t based on the original resource name that was provided during resource creation. For example, when a user creates an Amazon Simple Storage Service (Amazon S3) bucket and sets a specific bucket name, that bucket name is included in the ARN: arn:[partition]:s3:::[bucket-name]. Identity Center application ARNs use unique identifiers (GUIDs) generated at creation time.
Manage access for an Identity Center application
After the IAM Identity Center application is created, you will need to manage access to the Identity Center application and associated AWS resources. To continue with the SageMaker AI domain example, after the domain is created, an authorized IAM principal will need to assign Identity Center users or groups from the Identity Center instance to the domain. For Identity Center, you will need two types of Identity Center IAM permissions.
The first type of IAM permissions is used to list IAM Identity Center users and groups within the Identity Center instance. This is needed to read and select specific IAM users or groups to assign to an Identity Center application.
Although IAM Identity Center users and groups have a GUID, the GUIDs aren’t clearly linked to the resource friendly names. For example, a group name could be Read-Only and the resource GUID could be 1234567890-abcdef12-3456-7890-abcd-ef1234567890 in the identity store. Additionally, the IAM actions to list users or groups require the AllUsers or AllGroups parameter. Because List actions require access to users and groups, a restrictive IAM policy can’t be used to prevent IAM principals from seeing a subset of users or groups within the identity store. The second type of IAM permission is used to create and manage application assignments for the Identity Center application within the Identity Center instance.
Because the IAM Identity Center application ARN is created using a unique application ID during creation, it’s not recommended to implement an IAM policy restricting authorized IAM principals to manage specific Identity Center applications. For example, to limit the application assignments to only a specific set of applications, you would need to:
Create the AWS resource with IAM Identity Center as the authentication mechanism
Query the Identity Center application ARN for the associated AWS resource
Identify the IAM principal that will be used for application assignments
Create or update an IAM policy associated to that IAM principal to allow application assignments for that specific application
Create or update an SCP to restrict application assignment to that specific IAM principal
In lieu of implementing resource restrictions within identity policies, you should limit management of IAM Identity Center application and application assignments to a limited number of authorized IAM principals. In addition, it is recommended to implement detective and reactive capabilities to manage Identity Center application assignments.
Plan your naming conventions and automation strategy
IAM Identity Center provides several APIs to capture information about your AWS organization instances, applications, and assignments. Before implementing automation or guardrails, you should develop a methodical approach and understand what outcome you’re working backwards from. Start by defining naming conventions and deciding what parts of the workflow you want to centralize.
Determine a naming convention for groups within your IdP: For example: AWS_<ACCT#>_<AWS_Service>_<LOB>_<ENV>_<AppName>. The IdP group name would look like: AWS_123412341234_SageMaker_Data_PROD_GTLabel.
Define the naming convention for AWS resources for your Identity Center integrated applications: For example: <AWS_Service>_<LOB>_<AppName>. The AWS resource name would look like: SageMaker_Data_GTLabel.
Define the naming convention for Identity Center application names: For example: <AWS_Service>_<LOB>_<ENV>_<AppName>. The Identity Center application name would look like: SageMaker_Data_PROD_GTLabel.
Decide on the restrictions that you want to implement within your AWS environment. Depending on your enterprise’s security standard, you can implement specific restrictions based on mapping of a similar combination of ENV (environment), AWS service, LOB (line of business), or application name.
Choose the portions of the application workflow that you want to centralize. This could include creating the application, making application assignments, or remediating issues.
As more configurations and permissions are centralized, additional overhead and bottlenecks can be introduced. It’s important to find the right balance for your enterprise. For example, if you centralize application assignments, each application team will need to submit a request to modify assignments that will be reviewed by a centralized team and could result in a delayed response. Conversely, if each application team handles their own assignments, there’s a risk that application assignments won’t align to enterprise security standards.
By understanding your goals and how you want to reach them, you can tailor the sample solution accordingly. Getting alignment on this requires planning and coordination across multiple teams within your organization. When thinking about more customized authorization logic—such as using provisioned AWS resource metadata—you should review how the specific AWS service integrates with IAM Identity Center managed applications. For example, if you want to find the Identity Center application ARN for a specific AWS resource, such as a SageMaker AI domain, use the following approach. A reverse lookup is necessary because AWS services create Identity Center applications with GUID-based ARNs that aren’t easily discoverable.
Amazon API Gateway – Provides an IAM-authenticated REST API for a Lambda function to generate and export reports as CSV files
Amazon S3 – Stores the encrypted CSV file exports, with lifecycle policies and time-limited Amazon S3 presigned download URLs
Deploy the IAM Identity Center reporting sample
The following procedure deploys the automated discovery and reporting infrastructure using AWS Cloud Development Kit (AWS CDK). Make sure you have the following prerequisites in place, then continue with the steps to set up the solution.
Prerequisites
You need to have the following to test the solution in this post.
An AWS organization with an IAM Identity Center organization instance with delegated administrator access configured
IAM Identity Center configured with at least one instance
export IDC_EXTERNAL_ID="$(uuidgen)" # alternatively you can set this value — member-account roles need the same value

cdk deploy --parameters AllowedIpRange=10.0.0.0/8 --parameters CrossAccountExternalId="$IDC_EXTERNAL_ID"
Note: AllowedIPRange is optional but recommended as a security best practice. The parameter will add a network restriction to download the Amazon S3 presigned URL export.
Optional: For AWS account-level Identity Center instance discovery, a cross-account IAM role is required.
Figure 2: Successful AWS CDK deployment of the reporting stack
After the stack is successfully deployed, obtain the CDK output values for the API Gateway URL and S3 bucket name. If using a command line to deploy, these values will be displayed after the stack successfully deploys. It can also be found in the AWS Management Console as AWS CloudFormation stack output. The output will be used for generating reports in the following sections.
Note that this stack is for the reporting stack only. Reactive monitoring and deployment are described in the next section.
After the reporting stack is successfully deployed, the automation will run on a daily schedule. The first discovery run executes immediately after deployment. You can monitor discovery execution history and detailed logs through the the AWS Step Functions console. Review the detailed Lambda function logs in Amazon CloudWatch Logs. Query discovered instances, applications, and assignments through the DynamoDB console for one-time analysis.
Generate reports for Identity Center application assignments
To generate on-demand reports as CSV files from the REST API:
The generated CSV files include enriched data with friendly names:
Instance ARN
Account ID
Application name
Principal type
Principal name
Status
arn:aws:sso:::instance/…
123456789012
SageMaker_PROD
GROUP
Engineering-Team-Dev
ACTIVE
arn:aws:sso:::instance/…
123456789012
OpenSearch_PROD
USER
jane.doe@example.com
ACTIVE
You can use the generated CSV files to help identify anomalies or non-compliant assignments, such as:
Each PROD application should only have GROUP assignments. OpenSearch_PROD has a USER principal type and so is non-compliant.
Each PROD application should only allow PROD groups assigned. SageMaker_PROD has a DEV group name (Engineering-Team-Dev) assigned and so is non-compliant.
Based on the testing and analysis of the output from the IAM Identity Center governance reporting sample solution, it’s important to start thinking about what restrictions to put in place for application assignments. It’s also important to conduct this exercise before taking action within the Identity Center remediation sample solution in the next section.
IAM Identity Center remediation
The following diagram shows the IAM Identity Center remediation architecture.
The IAM Identity Center remediation sample solution deploys the following resources:
Amazon EventBridge – Matches IAM Identity Center assignment and profile events from CloudTrail (sso.amazonaws.com) and invokes the monitor function across the following IAM actions:
CreateApplicationAssignment
DeleteApplicationAssignment
PutApplicationAssignmentConfiguration
AssociateProfile
DisassociateProfile
CreateProfile
UpdateProfile
DeleteProfile
Lambda – Resolves the application and group names, validates the assignment against your naming convention, and notifies or remediates based on the configured mode
AWS KMS – Customer-managed key to encrypt the Lambda environment variables, CloudWatch logs, SNS topic, and dead-letter queue
Amazon CloudWatch – Log group stores the function’s structured, encrypted logs as an audit trail
Flexible naming policies support regex-based pattern matching for specific organizational requirements. The automation actions are logged to CloudWatch with structured JSON for additional analysis and reporting.
The following procedure deploys the remediation infrastructure using AWS Cloud Development Kit (AWS CDK). Make sure you have the following prerequisites in place, then continue with the steps to set up the solution.
Prerequisites
You need the following to run the remediation solution:
An AWS organization with an IAM Identity Center organization instance with delegated administrator access configured
IAM Identity Center configured with at least one instance and an IdP
Python 3.12 & Node.js 18 or later installed for CDK deployment
Provide your IAM instance ARN and the account ID where IAM Identity Center is administered:
git clone https://github.com/aws-samples/sample-iam-idc-application-discovery-reporting # only needed if you did not clone in the previous reporting section
cd identity-center-remediation
cdk deploy --context enableAutoDeletion=false --parameters IdentityCenterInstanceArn=arn:aws:sso:::instance/ssoins-<INSERT-ORG-INSTANCE-ID> --parameters ManagementAccountId=<INSERT-MANAGEMENT-ACCOUNT>
Note: If you don’t pass a parameter for GroupNameRegex, the default action of the sample solution is to verify the group name appears as a whole word in the application name: Case-insensitive, splitting on -, _, and spaces, so ReadOnly matches sagemaker_readonly but read does not. If different validation is needed, the sample can be deployed with the regex value for GroupNameRegex.
After the solution is deployed, we will walk through testing both a compliant and non-compliant application assignment.
Gather Identity Center and application information
For this blog, we have already created two groups within the IdP that is integrated into an IAM Identity Center instance. We also already created two applications within Identity Center instance to use. Next, we’ll need to gather information specific to the environment to run through each example.
Obtain the IAM Identity Center instance ARN and set the value.
After you have the output for IAM Identity Center groups and applications, select two groups and one application that you want to test with. You will need to set additional variables for each group GUID and application ARN. In this example, I select the following two groups (ReadOnly and Developer) for testing and set the environment variables using export:
As part of this validation, the sample solution verifies the group name appears as a whole word in the application name: Case-insensitive, splitting on the -, _, characters and spaces, so ReadOnly matches sagemaker_readonly but read does not. For different use-cases, The GroupNameRegex parameter can be used during deployment.
Test compliant and non-compliant assignments
Run the following command to add the ReadOnly group assignment to the sagemaker_readonly application:
aws sso-admin create-application-assignment --application-arn $APP_READONLY --principal-id $GRP_READONLY --principal-type GROUP
The group assignment request meets the validation criteria because the application name sagemaker_readonly contains the group name ReadOnly. The output logs for this validation exist within the associated lambda function CloudWatch log group /aws/lambda/identity-center-app-monitor”.
In this example, the logs will show:
✓ COMPLIANT - Group name found in application name
Run the following command to try to add the Developer group assignment to the sagemaker_readonly application:
aws sso-admin create-application-assignment --application-arn $APP_READONLY --principal-id $GRP_DEVELOPER --principal-type GROUP
The group assignment request doesn’t meet the validation criteria because the application name sagemaker_readonly doesn’t contain the group name Developer. The output logs for this validation exists within the associated lambda function CloudWatch log group /aws/lambda/identity-center-app-monitor. Note that the remediation action listed shows NOTIFICATION_ONLY, meaning it only sent a notification to the configured SNS topic and did not take action. If you want the group assignment to be deleted, the value should be set to enableAutoDeletion=true.
In this example, the logs will show:
✗ NON-COMPLIANT - Group name not found in application name
Scheduled reporting gives baseline visibility into IAM Identity Center managed applications. Event-driven monitoring can provide near real-time notification or enforcement. Together, these sample solutions can help align and scale Identity Center with your governance and security standards through both historical analysis and immediate response.
Clean up
For each deployed CDK stack, run the following commands in the AWS account where it was deployed.
To delete the remediation stack, run the following commands:
cd sample-iam-idc-application-discovery-reporting/identity-center-remediation
cdk destroy
To delete the reporting stack, run the following commands:
cd sample-iam-idc-application-discovery-reporting/identity-center-reporting
cdk destroy
IAM governance automation at scale
Achieving effective IAM Identity Center governance at scale requires moving beyond manual processes to automated, continuous monitoring and reporting. The following high-level steps can provide an Identity center governance framework:
Deploy the sample automation with an IAM principal that has access in your delegated administrator account.
Establish a baseline by running your first discovery and reviewing the generated reports.
Configure naming policies to match your organization’s security conventions.
Deploy the event-driven monitoring capabilities to enable real-time policy enforcement and automated response based on the security policies.
Start in notification mode to establish a baseline before enabling auto-remediation.
Integrate with your governance tools by connecting the API endpoints to your compliance dashboards or ITSM tools.
Move to auto-remediation once you have validated policies are working as expected.
Conclusion
Managing AWS IAM Identity Center at scale doesn’t have to be a manual, time-consuming process. By implementing automated discovery and reporting combined with real-time event-driven monitoring, you can maintain continuous visibility into your organization’s identity and access landscape, respond immediately to policy violations, and enforce governance policies consistently across your organization. Automation reduces operational work, strengthens security, speeds up incident response, and maintains compliance. Start by deploying these solutions to gain visibility and enable real-time enforcement.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post or contact AWS Support.
Organizations in regulated industries such as financial services, government, defense, and healthcare restrict their sensitive workloads to isolated network environments with no access to the public internet. Until now, customers could restrict AWS Management Console access to authorized AWS accounts and corporate networks, but the console itself required internet connectivity. This was creating tension between operational convenience and network security controls.
We’re happy to announce that AWS Management Console Private Access is now generally available with support for virtual private clouds (VPCs) without internet connectivity. Organizations in regulated industries that restrict workloads to isolated network environments can now route all traffic for supported service consoles—including authentication flows, static assets (JavaScript, CSS, images), console-only APIs, and AWS service API calls—through AWS PrivateLink VPC endpoints, eliminating the need for an internet gateway, NAT gateway, or any route to the public internet. This capability is available in all AWS commercial Regions for a select set of supported service consoles.
In 2023, we launched AWS Management Console Private Access, which you can use to connect to the console by routing console, sign-in, and service API calls through VPC endpoints. However, accessing the console required internet connectivity for static assets and console-only APIs. This meant security teams faced a choice: allow internet connectivity to use the console or deny console access to operators working in network-isolated environments.
With this launch, AWS Management Console Private Access addresses two common scenarios:
Console traffic over internet restricted networks: Traffic for supported service consoles now flows entirely through your VPC endpoints—no proxy allowlists to maintain, no TLS-intercepting proxies to operate, and no CLI-only workflows to accept as a compromise. The same path works seamlessly from Amazon WorkSpaces, Amazon Elastic Compute Cloud (Amazon EC2) instances, and on-premises networks connected through AWS Direct Connect or AWS Site-to-Site VPN. Combined with sign-in resource control policies (RCPs) and sign-in resource policies, you can ensure that console authentication only succeeds from expected networks—even if valid credentials are presented elsewhere, the session is denied. Teams that previously relied on restricted egress rules or manual domain allowlists now get full console access with the same network controls they already trust.
Data-exfiltration prevention: Private Access enables you to restrict which AWS accounts and organizational identities can use the AWS Management Console from within your VPC. This prevents access from personal accounts and from accounts outside your organization. Attach a VPC endpoint policy with an aws:ResourceOrgID condition, and console actions are automatically scoped to resources inside your organization. Sign-in RCPs add a second layer by ensuring authentication only succeeds from networks within your perimeter. Together, these controls prevent supported service consoles from being used to access resources in accounts outside your organization—such as personal accounts—without requiring complex network-layer workarounds.
In this post, you will learn how AWS Management Console Private Access works in environments without internet connectivity, and how to layer access controls using VPC endpoint policies and sign-in resource control policies (RCPs) to strengthen your data perimeter.
Solution overview
AWS Management Console Private Access and sign-in resource control policies are a natural extension of the service control policies (SCPs), resource control policies, and VPC endpoint policies you already use for API traffic; now applied to the console session itself. The same data perimeter controls for identity, resource, and network that protect your programmatic access now protect interactive browser sessions too.
Perimeter
Control objective
Policy construct
Implementation Steps
Identity
Only trusted identities can access my resources
Sign-In RCPs and RBPs
Restrict which principals can sign in to the console. Before authentication, signin:PrincipalArn is available for exemptions only. After authentication, RCPs restrict at the organization, account, or principal level (aws:PrincipalOrgID, aws:PrincipalAccount, aws:PrincipalArn); RBPs restrict at the account or principal level.
Identity
Only trusted identities are allowed from my network
Console VPC endpoint policy and Sign-In VPC endpoint policy
Console endpoint: aws:PrincipalOrgID or aws:PrincipalAccount on signed-in identities. Sign-In endpoint: aws:ResourceOrgID or aws:ResourceAccount before authentication, principal and resource keys after authentication. Blocks sign-in to accounts outside your organization, such as personal accounts, from your network.
Resource
My identities can access only trusted resources
SCP
Resource perimeter SCP with aws:ResourceOrgID follows your principals into every console session; each service API call the console makes on their behalf is denied if the target resource is outside your organization.
Resource
Only trusted resources can be accessed from my network
Console VPC endpoint policy and service VPC endpoint policies
Console endpoint policy with aws:ResourceOrgID and aws:ResourceAccount scopes what the console can reach through your network.
Network
My identities can access resources only from expected networks
SCP
Network perimeter SCPs that use aws:SourceVpc deny your principals’ service calls from outside expected networks. With Private Access, requests proxied by the console to supported services carry aws:SourceVpc set to the VPC hosting your Private Access endpoints. Direct browser requests carry VPC context only when the service has its own VPC endpoint, so configure endpoints for every service you use. AWS recommends conditioning on aws:SourceVpc rather than specific aws:SourceVpce values.
Network
My resources can only be accessed from expected networks
Sign-In RBPs and RCPs and network perimeter RCPs
Sign-In policies deny console authentication from unexpected networks using aws:SourceIp, aws:SourceVpc, aws:SourceVpce, and aws:VpcSourceIp in both pre-authentication and post-authentication statements. Network perimeter RCPs apply the same network conditions to your data resources for any access path.
With this launch, Console Private Access routes browser traffic for supported service consoles through VPC endpoints, including:
Authentication flows – Sign-in, credential exchange, and session token requests
Static assets – JavaScript, CSS, and images that render the console UI
Service console API calls – The backend requests made when users interact with service consoles
How traffic flows from a workload in a private VPC through the three Private Access endpoints, with no path to the public internet (shown in Figure 1):
The operator’s browser requests <region>.console.aws.amazon.com.
The corporate DNS forwarder forwards the query to an Amazon Route 53 Resolver inbound endpoint configured within the VPC, which forwards the traffic to the console VPC endpoint.
Browser traffic flows from on-premises through Direct Connect (or AWS Site-to-Site VPN) to the VPC, and the VPC endpoint routes traffic to the console service over the AWS private network.
The console service redirects to the SignIn endpoint <region>.signin.aws.amazon.com to establish a browser session.
The DNS now resolves to the SignIn VPC endpoint’s private IP addresses, and browser traffic flows to the SignIn service over the AWS private network.
After entering credentials, the SignIn service evaluates VPC endpoint policies, in addition to resource-based policies (RBPs) and RCPs, then redirects back to the console.
The console evaluates VPC endpoint policies, loads static content from the console API VPC endpoint, and enforces identity and resource restrictions when making calls to AWS service APIs.
Users can now access the AWS Management Console over Private Access.
Figure 1: Network isolation architecture
Deploy a pilot of AWS Management Console Private Access
This high-level walkthrough sets up AWS Management Console Private Access for a single AWS Region within one organizational unit (OU). We recommend rolling out incrementally; validate each step before you expand to additional Regions and OUs.
If you want to validate the mechanics of a Private Access deployment before you build out the full solution, the Getting started with a test environment guide walks you through a minimal configuration: a single VPC with the three Private Access endpoints and a permissive policy. This gives you a working setup to experiment with, independent of the deployment described in the rest of this post. To understand how sign-in policies can verify a user’s network location when they access the console, see Controlling console access with resource-based policies and resource control policies.
Prerequisites
You must have the following prerequisites:
An AWS account that’s a member of an organization within AWS Organizations. The example RCP in Step 4 requires the management account access.
Before changing anything, use CloudTrail to map how your users access the console today. Search for eventName = ConsoleLogin over a representative window (we recommend 30 days) and review the sourceIPAddress, vpcEndpointId, and awsRegion fields. Identify which identity types are in use: root user, IAM user, SAML federation, and AWS IAM Identity Center. Decide which OU or account you will pilot with.
Note: A misconfigured sign-in policy can lock users out of the console. Avoid piloting in a production or shared account. Instead, use a dedicated test account and configure a break-glass principal (covered in Step 5) before enabling access enforcement.
Step 2: Create the Private Access VPC endpoints
In your chosen Region, create or identify a VPC to host the endpoints, then create three interface VPC endpoints in that VPC:
com.amazonaws.<region>.console for the console.
com.amazonaws.<region>.signin for AWS Sign-In.
com.amazonaws.<region>.console-static for console-only APIs. This endpoint is required only if your VPC has no internet path.
Step 3: Configure private DNS for AWS Management Console Private Access
To use AWS Management Console Private Access, you must configure private DNS so that the console domains—.console.aws.amazon.com, .signin.aws.amazon.com, and the associated static-content domains—resolve to your interface endpoints’ network interfaces within your VPC.
For workloads inside your VPC: If the workloads in your VPC use the default Amazon Route 53 Resolver, no additional DNS configuration is required. When you create each interface endpoint, enable the private DNS name option (set PrivateDnsEnabled = true). The public console domains will then resolve automatically to the endpoint network interfaces inside your VPC. If you use a custom DNS resolver or a private hosted zone, you must configure it explicitly to map the console domains to the endpoint addresses. See Working with private hosted zones for more information. For the complete list of domains and detailed DNS configuration steps, see the AWS Management Console Private Access required endpoints documentation.
For workloads outside your VPC: For workloads that reach the endpoints from outside the VPC—such as corporate offices connecting over AWS Direct Connect or AWS Site-to-Site VPN—ensure that your corporate DNS resolver returns the endpoint addresses for these domains. See Simplify DNS management in a multi-account environment with Route 53 Resolver for more information.
Step 4: Verify private connectivity
Sign in to the console from a workload inside your VPC. The console should load normally. To confirm that traffic is routing through your VPC endpoints, look for the lock icon in the console navigation bar, shown in Figure 2.
Figure 2: Console Private Access
You can also verify in CloudTrail that recent ConsoleLogin events show the vpcEndpointId field populated with one of your endpoint IDs. Here’s an example CloudTrail ConsoleLogin event snippet showing the vpcEndpointId field:
If the AWS Management Console doesn’t load, work through the following checks.
Private DNS is enabled on each interface endpoint (or your custom resolver returns the endpoint addresses)
When Private DNS is enabled, AWS automatically creates the DNS entries that resolve the service domains (such as console.aws.amazon.com) to the private IP addresses of your VPC endpoints. Without it, your browser still routes to the public AWS endpoints, bypassing your private access setup entirely.
Confirm that each endpoint shows PrivateDnsEnabled:
Then, from within your VPC, verify that the domains resolve to private addresses:
nslookup console.aws.amazon.com
nslookup signin.aws.amazon.com

# Should return a private IP (e.g., 10.x.x.x), not a public one
Each query should return a private IP address from your VPC CIDR range. If you use a custom DNS resolver instead of the Amazon-provided DNS, ensure your forwarding rules direct the AWS domain queries to the Route 53 Resolver inbound endpoints in your VPC.
The endpoint security groups allow HTTPS (TCP 443) from your workload subnets
Each VPC endpoint creates elastic network interfaces (ENIs) in your subnets, and these ENIs are governed by security groups. If those security groups don’t permit inbound HTTPS traffic from your workloads, the connection fails silently.
Identify the security groups attached to your endpoints:
aws ec2 describe-vpc-endpoints --vpc-endpoint-ids vpce-0abc123def456789a \
  --query "VpcEndpoints[].Groups[].GroupId" --output text
Then verify that each security group allows inbound TCP 443 from your workload subnets:
For traffic from outside the VPC (Direct Connect or Site-to-Site VPN), corporate DNS returns the endpoint IPs and the route propagates correctly
If you access the console from an on-premises workstation connected over AWS Direct Connect or AWS Site-to-Site VPN, two additional conditions must be met.
Your corporate DNS must resolve the AWS domains to the VPC endpoint private IPs. From your on-premises machine, run:
nslookup console.aws.amazon.com
If this returns public AWS IPs, your corporate DNS isn’t forwarding queries through Route 53 Resolver. Configure conditional forwarding for the aws.amazon.com and amazonaws.com domains to your Resolver inbound endpoint IPs.
Second, network routes must propagate correctly. Ensure the route table associated with your endpoint subnets has propagated routes from your virtual private gateway (VGW) or transit gateway, so return traffic can reach your on-premises network. Verify this with:
A quick end-to-end validation: Run traceroute console.aws.amazon.com from your workstation and confirm the path uses private hops only—no traffic should traverse the public internet.
If the console loads but the lock icon is missing
If the console loads but the connection isn’t private (for example, the lock icon is missing), the browser is reaching the console over the public internet instead of through your VPC endpoints.
Run nslookup console.aws.amazon.com from a workload inside the VPC. The result should be a private IP from your VPC CIDR range. A public IP means DNS is bypassing the endpoint, which usually happens because Private DNS has not been enabled on the interface endpoint (set PrivateDnsEnabled = true).
For workloads outside the VPC, make sure your corporate DNS forwards the console domains into the VPC, for example, through an Amazon Route 53 Resolver inbound endpoint.
Step 5: Apply VPC endpoint policies
Attach an endpoint policy to the console and AWS Sign-In endpoints that limits access to identities in your organization. The static-content endpoint doesn’t support endpoint policies.
Begin with a permissive Allow * policy and confirm that traffic routes through the endpoints (you should see the vpcEndpointId field populated in CloudTrail console events). After confirming the routing, add restrictions to your VPC endpoint policy and observe the traffic.
A starter policy uses two condition keys: aws:PrincipalOrgID to restrict identities to your organization and aws:ResourceOrgID to restrict the resources the console can reach to your organization’s resources. The full reference, including additional condition keys and resource-restriction patterns, is in the AWS Management Console Private Access user guide.
Sign-In policies deny console authentication requests that don’t match your network or principal conditions. The policy is composed of a pre-authentication statement covering signin:Authenticate and a post-authentication statement covering signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token. Include both statements.
For your pilot, deploy the policy as an RCP from your AWS Organizations management account. When enabled, the RCP applies to all accounts in your organization, so we recommend piloting in a dedicated test organization before rolling it out broadly. Activate enforcement by calling the signin:PutConsoleAuthorizationConfiguration API for the organization in the us-east-1 Region (AWS Sign-In replicates policies globally from there). Resource permission statements have no effect until console authorization is enabled.
Important: Configure at least one excluded principal as a break-glass path before you enable the RCP. The recommended principal is a dedicated IAM role.
Write the permission statements that define the network conditions:
Example – Restrict access to corporate VPC:
So far, the console shell loads, the lock icon appears, and your Sign-In policy lets approved identities through. If you sign in to a service console such as the AWS Key Management Service (AWS KMS) console, the page might fail to load resources or hang. The Private Access endpoints carry the console shell, not the service API calls that the console makes on your behalf. In a VPC without an internet gateway, those calls have nowhere to go.
Add a VPC endpoint for the service itself. For the pilot, create an AWS KMS interface endpoint (com.amazonaws.<region>.kms) in the same VPC, with Private DNS enabled. Open the AWS KMS console from inside the VPC and confirm the list of keys loads. Repeat for each service your users need on day one. Please note that a single service console often calls more than one AWS service API. If a console loads but parts of the page show errors or stay empty, the most common cause is a missing endpoint for one of the services it depends on.
The current list of services that support PrivateLink is in the AWS PrivateLink documentation. Service consoles whose services don’t support PrivateLink will not work in a no-internet VPC and need to be handled separately.
Step 8: Hide Regions and services you haven’t configured (optional)
Console links to a service or Region that you don’t have endpoints for will fail inside your VPC. To prevent users from navigating to broken pages, use User Experience Customization (UXC) to hide Regions and services that aren’t part of your Private Access deployment. UXC is configured at the account level and applies to navigation, search results, and service-selection drop-downs.
Step 9: Validate, then expand
After applying the endpoint policies and the Sign-In RCP to one pilot account:
Sign in from inside the corporate network. The session should succeed.
Sign in from outside the corporate network. The session should be denied at the Sign-In step, before reaching the console.
In CloudTrail, confirm ConsoleLogin events show vpcEndpointId populated for traffic from inside the network.
For unexpected denials, look in CloudTrail for ConsoleLogin events with the error message Authorization denied because of a resource-based policy or Authorization denied because of a resource control policy to identify which statement was responsible.
Considerations
A few items worth mentioning before you commit to this design:
AWS IAM Identity Center: IAM Identity Center sign-in support isn’t yet available through a VPC endpoint. Initial single sign-on (SSO) authentication must still transit over the internet.
Programmatic access: Sign-In RBPs and RCPs gate interactive console sign-in. AWS SDK and AWS CLI requests signed with SigV4 aren’t affected. This is also your recovery path: a principal with signin:DeleteConsoleAuthorizationConfiguration permission can disable enforcement programmatically if console authorization is misconfigured.
For services that aren’t supported, you can still navigate to other consoles, but will require internet connectivity for the unsupported service consoles and console-only APIs.
Costs: You pay regular AWS PrivateLink endpoint pricing and data processing for each endpoint and each Region you deploy in. The three Private Access endpoints (console, signin, and console-static) plus the service endpoints you already use are the relevant line items.
Conclusion
In this post, we showed you how to extend the AWS data perimeter framework to the AWS Management Console. You routed console traffic through VPC endpoints with AWS Management Console Private Access, restricted console sign-in by network and organization with Sign-In RBPs and RCPs, and configured the console to operate in a VPC without an internet gateway. The four control objectives that you already enforce for API traffic now also apply to the console.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the IAM forum on AWS re:Post or contact AWS Support.
A single alert from one security service tells you something happened. Read that signal alongside activity from other services and your own business context, and you will know whether what happened is part of a multi-stage attack.
Consider a short sequence. An identity calls GetCallerIdentity from a source address it hasn’t previously used. Within minutes, that same identity runs a burst of List and Describe calls across several services, and some of them fail with AccessDenied. Soon after, a large volume of data leaves your environment toward a domain that was registered last week. Amazon GuardDuty might already flag pieces of this, such as the reconnaissance from an unfamiliar source, through finding types like Recon:IAMUser/* or Discovery:S3/*. What you gain from correlating the pieces yourself is a single view of the sequence, tied to your own business context, so you can act on the whole rather than triaging findings one at a time.
This post is for security engineers and security operations teams who run Amazon Web Services (AWS) detection services and want to catch patterns specific to their environment. You will see how AWS detection and your business context fit together, and how to build correlations that use that context. The examples run in Amazon CloudWatch Logs Insights so you can try them today, and the closing section describes how to grow them into an automated pipeline. The walkthrough later in this post lists the prerequisites for these queries.
Start with AWS detection services
Begin with the AWS detection services. They cover the threats common across customers, and everything in this post is built on them.
Amazon Detective (a security investigation service that visualizes relationships between resources and findings) lets you investigate findings with graph-based context across services and accounts.
AWS Security Hub aggregates security findings into a single prioritized dashboard.
Amazon Inspector (a vulnerability management service that scans workloads for software vulnerabilities) correlates vulnerability data with workload context.
Turn these on and tune them before you build anything custom. Tuning means adjusting sensitivity to reduce false positives for your environment, choosing which data sources each service monitors, and suppressing findings for known-good patterns.
GuardDuty correlates multi-stage attacks for you
Before you build anything by hand, see what GuardDuty already does for you. Amazon GuardDuty Extended Threat Detection correlates signals across multiple data sources including AWS CloudTrail, Amazon S3 data events, runtime monitoring, Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, and more, then raises a single critical severity attack sequence finding when it spots a multi-stage pattern. It recognizes sequences such as credential compromise followed by data exfiltration, maps them to MITRE ATT&CK tactics, and attaches a timeline and remediation guidance. If you have GuardDuty enabled today, then GuardDuty Extended Threat Detection is already enabled by default and needs no queries from you. For details on how GuardDuty charges apply, see Amazon GuardDuty pricing.
The credential compromise sequence in the opening example is the kind of universal pattern GuardDuty Extended Threat Detection is built to catch, so rely on it for those. Attack sequence findings show up in the GuardDuty console next to your other findings, and they route to Security Hub and your response workflows the same way.
GuardDuty handles the threats that look the same in every account. What it doesn’t have is the context that makes a given action suspicious in your account. That’s what you provide.
Add your business context
Business context is what only you know about your environment: which buckets hold sensitive data, which principals have a reason to touch which resources, which role chains your policy permits, and when your production change windows open. GuardDuty Extended Threat Detection learns from patterns common across customers, but it can’t answer these environment-specific questions. Express them as correlations and you add a detection layer tuned to your environment. Each of the following four patterns turns one of these facts into a query.
Run these queries in the AWS Management Console for CloudWatch by choosing Logs, then Logs Insights, using the CloudWatch Logs Insights query language. Most read CloudTrail events from a CloudWatch Logs log group that your trail delivers to. If your trail writes only to Amazon S3, add CloudWatch Logs delivery on the trail, or run equivalent queries in Amazon Athena (a serverless query service for analyzing data in Amazon S3 using SQL).
Note: The queries and code in this post use placeholder values. Replace them with your own before running: your-sensitive-bucket (your S3 bucket name), your-key-id (your AWS KMS key ID), region (your AWS Region, such as us-east-1), account-id (your 12-digit AWS account ID), and aws-cloudtrail-logs-my-trail (your CloudTrail log group name).
A note on multi-account environments. In AWS Organizations, an organization trail delivers every account’s events to one log group, so these queries work as-is but return cross-account results. Filter by recipientAccountId for account-scoped views. Without an organization trail, run queries per account or use Amazon Security Lake as a central query surface.
The attack chain mapped to AWS services
Multi-stage attacks move through five phases, and each phase leaves a signal in a different service. These signals surface across three log sources: CloudTrail, which records API activity in your account; Amazon VPC Flow Logs, which capture network connection metadata; and Amazon Route 53 Resolver query logs, which record DNS queries from your VPCs.
Initial access – Stolen credentials reach your environment. CloudTrail records GetCallerIdentity, GetSessionToken, or AssumeRole from an unfamiliar source.
Discovery – The threat actor enumerates with List, Describe, and Get calls, often triggering AccessDenied responses.
Privilege escalation – The threat actor chains roles or edits policies. CloudTrail records AssumeRole sequences, PutRolePolicy, or CreateAccessKey.
Lateral movement – The threat actor moves across accounts or AWS Regions, assuming roles and creating resources in unfamiliar places.
Exfiltration – Data leaves through GetObject calls at scale, large outbound transfers in VPC Flow Logs, and DNS queries in Route 53 Resolver query logs to recently registered domains.
Figure 1 shows the five attack phases mapped to the AWS log source that records each one.
Figure 1: Attack chain mapped to AWS services
GuardDuty Extended Threat Detection watches this chain for universal patterns. The four patterns that follow add the dimension you supply: your business context.
Pattern one: Sensitive data access by an unexpected principal
Your data classification and access norms drive this detection. One bucket holds customer records, another holds public web assets, and you know which principals have a reason to read the customer records, which are sensitive. Encode that knowledge and an ordinary looking read turns into something worth chasing.
Three signals converge here. CloudTrail shows GetObject at volume on a bucket you’ve classified as sensitive. The principal isn’t on your list of expected readers for that bucket. And VPC Flow Logs show a large outbound transfer from the same source in the same window, while DNS query logs show a recently registered destination domain, which together increase your confidence that there’s a potential threat.
CloudTrail management events don’t record GetObject. You must turn on CloudTrail data events for the buckets you care about to capture GetObject. Many teams miss GetObject because data events weren’t enabled on the relevant buckets.
This query shows bulk reads on a sensitive bucket, grouped by principal. Run it in CloudWatch Logs Insights with your CloudTrail log group selected.
fields @timestamp, userIdentity.arn, requestParameters.bucketName
| filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
| filter requestParameters.bucketName = "your-sensitive-bucket"
| stats count(*) as objectReads,
        count_distinct(requestParameters.key) as distinctObjects
        by userIdentity.arn, bin(10m)
| filter objectReads > 100
| sort objectReads desc
The threshold of 100 is a placeholder. Run the query over a week of normal activity, find the ninety-fifth percentile read count for that bucket, and set the threshold above it. Then check each principal the query returns against your expected reader list. A principal that isn’t on the list, reading at volume, is the result to investigate.
To corroborate, look for a matching outbound transfer. Switch the log group selector to your VPC Flow Logs log group and run this.
fields @timestamp, srcAddr, dstAddr, bytes
| filter action = "ACCEPT"
# exclude RFC 1918 private ranges so only external destinations remain
| filter dstAddr not like /^10\./
        and dstAddr not like /^192\.168\./
        and dstAddr not like /^172\.(1[6-9]|2[0-9]|3[0-1])\./
| stats sum(bytes) as totalBytes by srcAddr, dstAddr, bin(10m)
| filter totalBytes > 1000000000
| sort totalBytes desc
The Amazon S3 query returns a principal, and the Flow Logs query works on IP addresses, so you translate one into the other. The worked example later in this post covers that translation in full.
Picture an analytics role that reads a reporting bucket all day. One afternoon, it reads a thousand objects from your customer records bucket instead. GuardDuty stays quiet, because an authenticated role making valid GetObject calls isn’t suspicious anywhere else. Your query flags it, because that role isn’t on the expected reader list for that bucket. The classification you applied is what turns silence into a signal.
Figure 2 shows a bulk read from a sensitive bucket in CloudTrail, a large outbound transfer in VPC Flow Logs, and a young domain resolution in Route 53 Resolver logs.
Figure 2: Three signals converging within a single time window to indicate exfiltration
Pattern two: A role chain that crosses your access policy
Picture a deployment that assumes one role to build, then a second to release. For one principal, that two-hop AssumeRole chain is routine; for a different principal it’s a policy violation. This pattern relies on your trust topology—the chains your organization permits—so put that knowledge in the query.
This pattern needs three conditions:
CloudTrail shows several AssumeRole calls from the same source inside a short window
The chain ends in a sensitive action such as CreateAccessKey, PutRolePolicy, or AttachUserPolicy
The starting identity isn’t one your policy expects to run that chain
In CloudWatch Logs Insights, select your CloudTrail log group and run this query, which surfaces chains of two or more hops.
fields @timestamp, userIdentity.arn, requestParameters.roleArn, sourceIPAddress
| filter eventName = "AssumeRole"
| stats count(*) as assumeCount,
        count_distinct(requestParameters.roleArn) as rolesAssumed
        by sourceIPAddress, bin(5m)
| filter assumeCount >= 2 and rolesAssumed >= 2
| sort assumeCount desc
Two hops is the minimum for a chain; raise the count if your environment chains roles often. Your deployment pipeline probably assumes several roles an hour, as do AWS service principals such as AWS Security Hub. Exclude the identities you expect to see assuming multiple roles, including your pipeline role and known AWS service principals. What’s left is the set to investigate, such as a person assuming several roles at an odd hour and ending in a new access key. Treat that distinction as data: list the identities and actions you consider normal, and review the chains that fall outside the list.
Pattern three: An encryption key used outside its owning workload
Resource ownership is the signal here. A given AWS Key Management Service (AWS KMS) key creates and controls the encryption keys for a workload, and a single key should serve a single workload, such as a payments service. A Decrypt call against it is a valid, authorized API action, so nothing about the call itself looks wrong. The ownership rule you set is what makes another principal’s use of the key worth a second look.
This pattern applies only to customer-managed keys scoped to one workload. It doesn’t apply to AWS-managed keys (alias/aws/*) or to customer-managed keys intentionally shared across services. Confirm single-workload intent from the key policy’s Principal block before deploying this rule.
Two conditions indicate misuse:
CloudTrail shows Decrypt or GenerateDataKey calls on a key that’s tied to one workload
The calling principal isn’t the role that owns that workload
Against your CloudTrail log group, run this query to list the principals that called a specific key.
Compare what comes back against the one workload role you expect. A principal you don’t recognize on that key is the signal. Because key misuse is an early move in data theft, this correlation catches activity that only your ownership knowledge can flag.
Consider a key that wraps your payments database. The payments service role calls it in normal operation, and nothing else should. If a developer role or a freshly created role runs Decrypt against it, the call succeeds and reads as ordinary in isolation. The reason it matters is the ownership rule you hold in your head and now state in this query.
Pattern four: A privileged action outside your change window
Start with the query, then read what it means.
fields @timestamp, userIdentity.arn, eventName, sourceIPAddress
| filter eventName in ["PutRolePolicy", "AttachRolePolicy",
        "CreateAccessKey", "AuthorizeSecurityGroupIngress", "PutBucketPolicy"]
| stats count(*) as sensitiveChanges by userIdentity.arn, eventName, sourceIPAddress
| sort sensitiveChanges desc
Run it against your CloudTrail log group, scoped to your off-hours window when you schedule it, so it returns only activity outside the change window. Your change process defines what normal looks like here: production security and identity changes flow through a pipeline during defined hours, run by a known actor. A console-driven policy change at 2:00 AM, made by a person rather than the pipeline, doesn’t fit those expectations. The signal is a sensitive change such as PutRolePolicy or AuthorizeSecurityGroupIngress, made outside the window, by a person rather than your pipeline role.
Exclude the actors you expect, such as your deployment pipeline role, your patch automation role, and AWS service principals like AWS CloudFormation and AWS Systems Manager. What remains is privileged change made outside your process, which is both what an attacker does to establish persistence and what your own change discipline says shouldn’t happen.
Your pipeline might open security group rules during a deployment every weekday afternoon. A person opening a security group rule at midnight on a weekend is the same API call carrying a very different meaning. The schedule and the actor, both facts you define, are what separate the two.
Build your first correlation rule
The following walkthrough uses pattern one as a complete example. The other three patterns follow the same design with their own queries.
Prerequisites
These prerequisites feed the queries in this walkthrough. Confirm each one before you start:
A CloudTrail trail logging management events to a CloudWatch Logs log group
CloudTrail data events enabled for your sensitive S3 buckets
GuardDuty enabled, with its protection plans and Extended Threat Detection
CloudTrail, GuardDuty, VPC Flow Logs, and Route 53 Resolver query logging provide the raw signals that your correlations connect. Without them, the queries in this post return empty results.
Step 1: Record the bucket and its expected readers
Choose one sensitive bucket to monitor, and write down the principals allowed to read it. Store the list where your automation can reach it, such as a configuration file in version control or an Amazon DynamoDB table (a managed NoSQL database).
This example hardcodes the list for simplicity. In production, load it from a DynamoDB table or Parameter Store so you can update it without redeploying.
Step 2: Baseline before you set a threshold
Run the pattern one query over one week of normal activity. Find the 95th percentile read count for the bucket and use a value greater than that as your alert threshold. This step keeps legitimate high-volume access from generating false positives later.
Set the THRESHOLD_READS environment variable to this value when you configure the function in Step 5.
Step 3: Run the access query
In the CloudWatch console:
Choose Logs, then choose Logs Insights.
In the Select log group(s) dropdown, select your CloudTrail log group.
Set the time range to 3h (the last three hours).
In the query editor, paste the pattern one query.
Replace your-sensitive-bucket with your bucket name.
Choose Run query.
Review the principals in the results table.
Compare each principal against your expected reader list from step 1, and flag any that are not on it.
Each result includes a principal that step 4 translates into an IP address.
Step 4: Correlate with network activity
CloudTrail logs actions by AWS Identity and Access Management (IAM) principal, while VPC Flow Logs record traffic by IP address. To connect the two signals, translate the principal into its address.
For a role attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the userIdentity.principalId field includes the instance ID after the colon, in the form AROAEXAMPLE:i-1234567890abcdef0. Copy the instance ID and look up its private IP address.
Other compute types differ. A VPC-connected AWS Lambda function sends traffic through elastic network interfaces in your subnets, so correlate on those interface addresses. An Amazon Elastic Container Service (Amazon ECS) task records its network interface in task metadata. For a plain assumed-role session with no instance behind it, the sourceIPAddress field in CloudTrail already holds the caller’s address, so you correlate on it directly.
Run the Flow Logs query from pattern one, filtering srcAddr to that address within 10 minutes of the Amazon S3 read timestamp. A match places the same source behind both the sensitive read and a large external transfer in one window. CloudTrail events reach CloudWatch Logs 5–15 minutes after the API call, so correlate on eventTime rather than query time. Query a wider lookback than your correlation window: for example, look back 30 to 60 minutes but correlate on a 10-minute eventTime window. Steps 3 and 4 are manual validation; step 5 automates them.
Figure 2 shows DNS resolution as a third corroborating signal. This walkthrough implements the CloudTrail and VPC Flow Logs correlation. To add DNS, apply the same run_query() pattern against your Route 53 Resolver query log group.
Step 5: Automate the check
Move the query into a Lambda function (serverless compute that runs your code without a server to manage), send results to a notification channel, and schedule regular runs. Work through the following sub-procedures.
Note the topic Amazon Resource Name (ARN) at the top of the topic details page. You will use it in the function.
Choose Create subscription.
For Protocol, select Email.
For Endpoint, enter your email address or incident management endpoint.
Choose Create subscription, then confirm the subscription from the email AWS sends.
To create the EventBridge Scheduler execution role
The schedule needs a role that lets it invoke your function, and its trust policy needs conditions that pin the role to the schedule you own. Without those conditions, another account with access to the scheduler service could theoretically call this role; a class of misuse known as the confused deputy problem.
1. Create a trust policy file named scheduler-trust-policy.json.
2. Create the role, then attach permission to invoke the function. Scope Resource to the specific function ARN so this role can’t invoke anything else.
When you create the function, Lambda automatically creates an execution role. You will attach the permissions this function needs to that role in a later step.
On the Code tab, replace the default code with the following function, then choose Deploy.
import os
import time
import logging
import boto3
from botocore.exceptions import ClientError

logger = logging.getLogger()
logger.setLevel(logging.INFO)

logs = boto3.client("logs")
sns = boto3.client("sns")
ec2 = boto3.client("ec2")

CLOUDTRAIL_LOG_GROUP = os.environ["CLOUDTRAIL_LOG_GROUP"]
FLOWLOGS_LOG_GROUP = os.environ["FLOWLOGS_LOG_GROUP"]
SNS_TOPIC = os.environ["SNS_TOPIC_ARN"]
BUCKET = os.environ["SENSITIVE_BUCKET"]
THRESHOLD = int(os.environ.get("THRESHOLD_READS", "100"))

# Expected readers per bucket
EXPECTED_READERS = {
    "customer-records-prod": [
        "arn:aws:iam::123456789012:role/AnalyticsPipeline",
        "arn:aws:iam::123456789012:role/ComplianceAudit",
    ],
}


def run_query(log_group, query, start, end):
    """Start a Logs Insights query and wait for it to finish."""
    started = logs.start_query(
        logGroupName=log_group,
        startTime=start,
        endTime=end,
        queryString=query,
    )
    query_id = started["queryId"]
    while True:
        outcome = logs.get_query_results(queryId=query_id)
        if outcome["status"] in ("Complete", "Failed", "Cancelled"):
            break
        time.sleep(1)
    if outcome["status"] != "Complete":
        raise RuntimeError(f"Query did not complete: {outcome['status']}")
    return [{f["field"]: f["value"] for f in row} for row in outcome["results"]]


def private_ip_for_principal(principal_id):
    """Resolve an EC2 instance role principalId to its private IP."""
    if ":" not in principal_id:
        return None
    instance_id = principal_id.split(":", 1)[1]
    if not instance_id.startswith("i-"):
        return None
    reservations = ec2.describe_instances(InstanceIds=[instance_id])
    for reservation in reservations["Reservations"]:
        for instance in reservation["Instances"]:
            return instance.get("PrivateIpAddress")
    return None


def egress_bytes(src_addr, start, end):
    """Sum external egress bytes for one source address."""
    query = f"""
    fields srcAddr, dstAddr, bytes
    | filter action = "ACCEPT" and srcAddr = "{src_addr}"
    | filter dstAddr not like /^10\\./
            and dstAddr not like /^192\\.168\\./
            and dstAddr not like /^172\\.(1[6-9]|2[0-9]|3[0-1])\\./
    | stats sum(bytes) as totalBytes
    """
    rows = run_query(FLOWLOGS_LOG_GROUP, query, start, end)
    if rows and rows[0].get("totalBytes"):
        return int(rows[0]["totalBytes"])
    return 0


def lambda_handler(event, context):
    try:
        # 1-hour lookback absorbs CloudTrail's 5-15 min delivery latency;
        # correlation happens on eventTime via 10-min bins in the query below.
        end = int(time.time())
        start = end - 3600  # 1 hour lookback
        allowed = EXPECTED_READERS.get(BUCKET, [])

        access_query = f"""
        fields userIdentity.arn, userIdentity.principalId
        | filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
        | filter requestParameters.bucketName = "{BUCKET}"
        | stats count(*) as objectReads
                by userIdentity.arn, userIdentity.principalId, bin(10m)
        | filter objectReads > {THRESHOLD}
        """

        for row in run_query(CLOUDTRAIL_LOG_GROUP, access_query, start, end):
            principal = row.get("userIdentity.arn")
            if not principal or principal in allowed:
                continue

            message = (
                f"Principal {principal} read {row.get('objectReads')} "
                f"objects from {BUCKET}."
            )

            ip = private_ip_for_principal(row.get("userIdentity.principalId", ""))
            if ip and egress_bytes(ip, start, end) > 1_000_000_000:
                message += (
                    f" The same source ({ip}) also sent a large volume of "
                    f"data to external destinations in the same window."
                )

            sns.publish(
                TopicArn=SNS_TOPIC,
                Subject="Unexpected S3 access detected",
                Message=message,
            )
    except ClientError as error:
        logger.error(f"AWS API error: {error}")
        raise
    except Exception as error:
        logger.error(f"Unexpected error: {error}")
        raise
    finally:
        logger.info("Correlation check completed")
On the Configuration tab, choose General configuration, then choose Edit. Set Timeout to 5 minutes (300 seconds). CloudWatch Logs Insights queries run asynchronously and can take 30 to 60 seconds against large log groups. Choose Save.
On the Configuration tab, choose Environment variables, then choose Edit, and add CLOUDTRAIL_LOG_GROUP, FLOWLOGS_LOG_GROUP, SNS_TOPIC_ARN, SENSITIVE_BUCKET, and THRESHOLD_READS.
On the Configuration tab, choose Permissions, open the execution role, and attach the following least-privilege policy.
Replace REGION, ACCOUNT-ID, and the log-group names with your values. The ec2:DescribeInstances action doesn’t support resource-level permissions, so Resource: "*" is required for that statement; the other statements are scoped to specific ARNs.
To schedule automated runs
Amazon EventBridge (a serverless event bus that connects applications using events) runs targets on a schedule. Create one from the command line, using the role you made earlier.
Enrichment cuts triage time by adding an independent signal, but it isn’t required for the correlation to work. This step adds costs. You pay your geolocation provider for API calls, and the additional Lambda execution time increases your Lambda charges. To add IP geolocation, sign up for a geolocation API, add this function to the code, and call it where the handler resolves an IP.
import urllib.request
import json

def geo_context(ip_address):
    """Enrich an IP address with geolocation data from your provider."""
    try:
        url = f"https://your-geolocation-api.example/json/{ip_address}"
        with urllib.request.urlopen(url, timeout=5) as response:
            data = json.load(response)
        return {
            "country": data.get("country_name"),
            "city": data.get("city"),
            "org": data.get("org"),
        }
    except Exception as error:
        logger.warning(f"Geolocation lookup failed for {ip_address}: {error}")
        return None
Inside the handler’s loop, after you resolve ip, append the location to the alert.
            if ip:
                geo = geo_context(ip)
                if geo:
                    message += (
                        f" Source location: {geo['city']}, "
                        f"{geo['country']} ({geo['org']})."
                    )
Step 7: Scale to additional patterns and accounts
As your library grows, move the logic into automated pipelines with EventBridge, Lambda, and AWS Step Functions (a serverless orchestration service that coordinates multiple services into workflows), and surface correlations next to findings in Security Hub. For cross-service correlation at scale, CloudWatch unified data and telemetry capabilities can convert security and compliance data into the OCSF format and let you query sources such as CloudTrail, VPC Flow Logs, and DNS logs from one interface. Security Lake with Athena is a strong option for long-term analysis. Choose the endpoint that fits your retention and query needs.
Figure 3 shows a correlation pipeline built on AWS services including EventBridge, Lambda, Step Functions, and AWS Security Hub. The pipeline runs from data sources through scheduled queries and enrichment to automated response and centralized visibility.
Figure 3: A correlation pipeline built on AWS services
Conclusion
You now have four correlation patterns that layer your business context on top of GuardDuty Extended Threat Detection to catch attacks specific to your environment. A few principles carry across every correlation you build.
Identity is your primary correlation key: Track the same principal across services.
Time windows matter,but they depend on the attack: Events minutes apart are usually related for fast, automated sequences; the ten-minute bins here work for that pattern. Slow or manual reconnaissance can stretch across hours or days, so widen the window when the pattern is deliberate rather than automated.
Context is what you add: Your data classification, access norms, resource ownership, and change windows are signals you bring to detection.
Start with one rule: A single well-tuned correlation catches more significant activity than a wall of uncorrelated alerts.
GuardDuty Extended Threat Detection handles the multi-stage patterns common across customers. The correlations in this post add the layer that only your business context can supply. Start with one pattern this week, validate it against your own traffic, and add the next pattern after the first proves reliable.
Have you built correlation rules for patterns not covered here? Share your experience in the Comments section below.
When you build a new application or capability on Amazon Web Services (AWS), you want to focus on what you’re building. Getting a service running almost always begins with AWS Identity and Access Management (IAM). Many AWS services that act on your behalf need an IAM role, an identity the service assumes to access your resources with a defined set of permissions. You then author a trust policy so the service can assume the role, choose the permissions the workload needs, and attach it. Configuring roles and policies for common patterns is repeatable work that doesn’t need to be manual.
IAM role manager does that work for you. When role manager is enabled, AWS creates and configures the IAM roles as you build in supported service consoles, so you can start using a service and let AWS handle the role behind it. You create the resource you want, and role manager provisions and attaches the role you need as part of the same flow, so you can build now and refine permissions as your workload matures.
With that step automated, getting started takes minutes. You can create an AWS Lambda function and start running your code, with its execution role already created and attached, without switching context to set one up. Role creation becomes an automated part of building your application rather than a separate step.
Role manager is especially useful when you’re getting started: the moments when you want to stand up a service or get a proof of concept running and want to defer role configuration until later in your development process. You don’t need prior IAM experience to get started. You keep full control of what it creates, because the roles are ordinary IAM roles that you can view, edit, or delete like any role you author yourself. When you want to tighten a role, AWS IAM Access Analyzer reviews how it has been used and recommends a policy scoped to only the permissions it needs.
How to enable role manager
Role manager has two states, enabled and disabled. Enabling it for an account authorizes AWS to create roles in that account. In an organization, administrators can use a service control policy (SCP) to control whether member accounts can enable or use role manager. To enable it:
Open the IAM console and choose Account settings.
In the role manager section, choose Enable.
Figure 1: Enable Role Manager
Some AWS services already create a role for you when you create a resource that needs one. Role manager doesn’t change that: those services keep creating roles automatically, and roles you already created keep working. What role manager adds is a single account-level control, and coverage for a case that built-in flows can’t handle: tasks whose permissions AWS can’t determine in advance, such as running your own code. For those tasks, role manager provisions a role that you can narrow later.
Example: Create an Amazon EventBridge rule
Start with a common task: an Amazon EventBridge rule that invokes a target, such as an Amazon Simple Queue Service (Amazon SQS) queue or an Amazon Simple Notification Service (Amazon SNS) topic. Without role manager, you would pause here to create a role that lets EventBridge invoke the target, write the role’s trust policy, attach the required permissions, and then return to finish the rule. With role manager enabled, you define the rule and its target, choose Create, and role manager provisions the role and attaches it for you. The EventBridge console shows the rule created and ready, and you never open the role-creation flow.
Figure 2: Creating an EventBridge rule with no manual role setup
The role comes from an AWS managed role template: a definition AWS builds and maintains for a specific task, with the trust policy and permissions already worked out. The console calls a new IAM API, AcquireRole, which finds the matching template, provisions the role from it, and returns it to EventBridge. Depending on the service, AcquireRole either creates a new role or reuses one that already fits, so an account does not fill up with duplicate roles for the same task.
Role manager creates the role using your own IAM permissions, not a separate role-manager permission. To provision a new role, you need permission for the actions the template performs: at minimum, you need permissions to create and attach roles. When AcquireRole reuses an existing role instead of creating one, it needs only iam:GetRole and iam:GetRoleTemplateVersion. If you’re missing either of these permissions, the console tells you which one is needed rather than creating the role.
Run code that calls other AWS services
Not every task has a set of permissions AWS can define in advance. When a role runs your own code, such as a Lambda function, AWS has no way of knowing which services that code will call. Role manager covers this case too: create a Lambda function with role manager enabled, and it attaches an execution role that your code can use right away and that you can narrow once you know what the function calls.
Because the permissions your code needs aren’t known up front, role manager attaches the AWS managed policy PowerUserAccess to the role. PowerUserAccess grants access to AWS services so your function can call what it needs. By design, it doesn’t grant permission to manage IAM, AWS Organizations, or account settings. The template also configures the role to trust only the Lambda service.
Figure 3: Create an AWS Lambda function with no manual role setup
Role manager attaches an execution role, and your function is ready to run. Figure 4 shows the Execution role panel on the function’s Configuration tab, with the role that role manager attached.
Figure 4: Role manager provides a role automatically to an AWS Lambda function
You can open the role in the IAM console to review its permissions. Figure 5 shows the role’s Permissions tab with the PowerUserAccess policy attached.
Figure 5: Permissions of the role provided by role manager for an AWS Lambda function
You keep full visibility into what role manager creates. Every role it creates records the role template it came from, and both GetRole and ListRoles return that template reference. You can inspect any role in your account and tell which were created by role manager. You read a role’s trust policy and permissions the same way you would for a role you authored, and AWS CloudTrail records each role’s creation.
Refining roles as workloads mature
As your workloads mature, refine the roles that role manager created to follow least privilege. When you’re ready, you can disable role manager and get IAM Access Analyzer unused access analysis at no additional cost for 90 days. Access Analyzer looks at how each role has been used and recommends a policy you can apply that keeps only the permissions the role needs. Start with the roles attached to your most critical workloads and work outward.
Disabling role manager doesn’t disrupt anything already running: your resources keep the roles they have, those roles stay in your account until you change them, and from that point you author new roles yourself, the same as before. If you would rather narrow a single role than the whole account, editing that role removes it from role manager’s control and it becomes a standard customer-managed role, with your changes preserved. In sandbox or development accounts, keeping role manager enabled saves time. For production workloads, disable role manager and refine the roles it created to least privilege before going live.
Conclusion
Role manager automates IAM role setup so you can focus on building from the start. When you enable it, AWS creates and attaches the IAM roles your resources need as you build, so you can start in minutes without prior IAM experience. Because these are IAM roles that you fully control, you keep the same visibility and the same tools you already use. Keep role manager enabled while you build, and refine the roles it created as your workloads mature.
To get started, enable role manager in the IAM console and create a resource in a supported service. To learn more, see IAM role creation and the list of supported services in the IAM User Guide.
If you have feedback about this post, submit comments in the Comments section below.
Misconfigured Amazon Simple Storage Service (Amazon S3) buckets can expose your data to unauthorized access. Without proactive review, S3 bucket policies or Access Control Lists (ACLs) configured with broad access may go unnoticed in your environment. In this post, you learn how to identify and fix over-permissioned S3 buckets across your AWS environment, along with best practice recommendations and automation opportunities to help you prevent security gaps. This post provides a workflow framework and methodology recommendations for your security team to adapt. The focus of this post is on the what and why rather than a prescriptive implementation. You will need to customize the approach based on your organization’s requirements and existing security tooling.
This solution is intended for security engineers, cloud architects, and DevOps teams managing single- or multiple-account AWS environments with Amazon S3 workloads that require access management.
Prerequisites
Before you begin, make sure you have the following in place:
For multi-account environments, AWS Organizations should already be configured.
Basic familiarity with IAM policies and Python will help you customize the solution to your needs.
Solution overview
This solution uses a five-phase workflow diagram to detect, remediate, and continuously monitor over-permissioned S3 buckets across your AWS accounts. The following workflow diagram illustrates the high-level end-to-end process for identifying and remediating over-permissioned S3 buckets across your Amazon Web Services (AWS) environment.
Setup and prerequisites – Configure AWS Organizations or multi-account access, designate a central security account, deploy AWS Config across all accounts, and enable AWS Security Hub with a central administrator.
Detection and identification – Deploy AWS Config rules (such as s3-bucket-public-read-prohibited and s3-bucket-public-write-prohibited) and run an audit Lambda function that scans each S3 bucket. The function checks three areas: Public Access Block configuration, bucket policy status, and bucket ACL grants. Buckets with issues are added to a risky buckets list. The function then generates a report in CSV and JSON format, uploads it to an output S3 bucket, and sends an SNS alert.
Remediation – Address findings using one or more approaches – Apply restrictive bucket policies to deny public read/write access and restrict access to specific IAM principals; deploy a remediation Lambda function to automatically update bucket policies and disable public access settings; or use CloudFormation StackSets to deploy standardized policies across multiple accounts.
Continuous monitoring – Schedule the audit Lambda function for recurring scans (daily or weekly) using Amazon EventBridge. Use EventBridge to detect policy changes, configure automated notifications for new violations, enable IAM Access Analyzer for S3 to identify external access, and run regular compliance scans.
Resource cleanup – Review and delete resources created during the audit that are no longer needed, including Lambda functions and IAM roles, EventBridge rules, SNS topics and subscriptions, audit output S3 buckets, AWS Config rules, and Security Hub (if enabled only for this audit).
Cost considerations
This section covers the AWS services used in this solution and their associated costs so you can estimate spend before deployment. The primary cost drivers are AWS Config and Security Hub, which scale with the number of accounts and resources you monitor. Lambda, Amazon EventBridge, Amazon SNS, and Amazon S3 typically add minimal costs for most environments. Start with a pilot in one or two accounts to validate costs before scaling.
AWS Config – Charges per configuration item recorded and per rule evaluation. Costs scale with the number of accounts and resources tracked.
Security Hub – Charges per account per AWS Region for security checks and finding ingestion.
Lambda – Charges per request and per GB-second of compute time.
EventBridge – Scheduled rules are free. Custom event bus usage might incur charges.
Amazon SNS – Charges per notification delivered.
Amazon S3 – Storage costs for audit report output files. Minimal for most environments.
Check the service pricing pages for current rates. Use the AWS Pricing Calculator to estimate costs for your specific environment before enabling services across all accounts. Consider starting with a pilot in one or two accounts to validate costs before scaling.
Detect and report over-permissioned buckets
This section walks you through setting up the audit environment, deploying the Lambda-based scanner, and generating reports of over-permissioned S3 buckets across your accounts. Follow these steps to identify over-permissioned S3 buckets in your multi-account environment, starting with preparing your environment for an Amazon S3 audit.
To set up the multi-account audit environment:
Set up AWS Organizations or multi-account access. Set up centralized management of your AWS accounts using AWS Organizations or configure cross-account IAM roles.
Choose a central security account. Choose one account as your security/audit account. This account will run the audit Lambda function and collect results from member accounts.
Create an Amazon SNS topic for alerts. Subscribe your security team to receive notifications when over-permissioned buckets are detected. Note the topic Amazon Resource Name (ARN) from the output—you will need it when creating the Lambda execution role (step 6) and the Lambda function (step 9). Confirm the email subscription before testing; Amazon SNS doesn’t deliver alerts until the subscription is confirmed. Learn more in the Amazon SNS Developer Guide.
(Optional): Create an S3 bucket for audit reports. If you plan to use Script v2 for historical reporting and trend analysis, create a dedicated bucket now. Skip this step if you only need real-time alerts using Script v1.
Plan cross-account IAM roles. The central security account needs permission to scan member accounts. Design cross-account roles that:
Grant minimum Amazon S3 read permissions (list buckets, read policies, ACLs, public access configurations).
Include an external ID condition to mitigate the confused deputy problem.
Note: The specific trust policy and permissions policy for your cross-account roles will depend on organizational requirements. Work with your IAM administrators to grant minimum necessary access for the audit function.
Create the Lambda execution role. Create an IAM role for your Lambda function with the permissions it needs to scan buckets, publish alerts, and write logs. Apply the principle of least privilege—grant only the minimum Amazon S3 read permissions required for the audit (such as, listing buckets, reading bucket policies, ACLs, and public access block configurations), Amazon SNS publish permission for the alert topic created in step 3, Amazon S3 write permission for the output bucket created in step 4 (Script v2), and Amazon CloudWatch Logs permissions. For multi-account scanning, also include sts:AssumeRolepermission for the cross-account role ARNs created in step 5. The AWS Lambda execution role documentation has instructions on creating and configuring execution roles.
To deploy the S3 audit solution Deploy the audit components
Enable AWS Config in member accounts. AWS Config provides compliance monitoring and can detect when S3 buckets are created or modified with public access settings. This will enable the Lambda-based audit to receive real-time detection between scheduled scans. The AWS Config Developer Guide has setup instructions. Deploy pre-defined AWS Config rules to identify overly permissive settings. These managed rules provide automated compliance checking. When AWS Config detects violations, it sends findings to Security Hub (configured in step 8) for centralized visibility alongside the Lambda audit results.
s3-bucket-public-read-prohibited
s3-bucket-public-write-prohibited
Create AWS Config rules for specific permission patterns. For the full list of available rules, see the AWS Config managed rules reference
Enable Security Hub for centralized visibility. Enable AWS Security Hub in member accounts and configure the central security account as the administrator. Security Hub aggregates findings from AWS Config rules (step 7), IAM Access Analyzer (enabled later), and can receive custom findings from your Lambda audit function, providing a single dashboard for Amazon S3 security issues across your organization. See the Security Hub User Guide for setup details.
Deploy the audit Lambda function. Deploy a Python Lambda function using the Boto3 library to list S3 buckets, check their policies, ACLs, and IAM permissions, and identify over-permissioned buckets. See the example scripts that follow.
Important: These code examples aren’t production ready. Adapt them to meet your organization’s requirements and test them in a non-production environment before deployment.
Choose your approach:
Script v1 – Best for immediate SNS alerts when issues are detected.
Script v2 – Best for historical reports, trend analysis using BI tools.
Both scripts – Best for different schedules and ongoing needs.
Audit Lambda function – Example script v1 (Scan and alert)
The following is an example of a Lambda function script for reference purposes. Review, adapt, and test before use in your environment, it scans all S3 buckets in the current account and checks for:
Public Access block configuration gaps
Bucket policies that allow public access
ACL grants to AllUsers
Note: Replace placeholder values with actual values before deployment:
<REGION>– Your AWS Region (for example, us-east-1)
<ACCOUNT_ID>– Your 12-digit AWS account ID
<TOPIC_NAME>– The name of your SNS topic created in step 3
import boto3
import json

def lambda_handler(event, context):
    s3 = boto3.client('s3')
    sns = boto3.client('sns')
    risky_buckets = []
    errors = []

    try:
        buckets = s3.list_buckets()['Buckets']
    except Exception as e:
        return {'statusCode': 500, 'body': f'Failed to list buckets: {str(e)}'}

    for bucket in buckets:
        bucket_name = bucket['Name']
        issues = []

        try:
            # Check Public Access Block — all four settings should be enabled
            try:
                pab = s3.get_public_access_block(Bucket=bucket_name)
                config = pab['PublicAccessBlockConfiguration']
                if not all([
                    config.get('BlockPublicAcls'),      # Block new public ACLs
                    config.get('BlockPublicPolicy'),     # Block new public bucket policies
                    config.get('IgnorePublicAcls'),      # Ignore existing public ACLs
                    config.get('RestrictPublicBuckets')   # Restrict access to public buckets
                ]):
                    issues.append('Public Access Block not fully enabled')
            except s3.exceptions.NoSuchPublicAccessBlockConfiguration:
                issues.append('No Public Access Block configured')

            # Check bucket policy — flag if policy status is public
            try:
                policy_status = s3.get_bucket_policy_status(Bucket=bucket_name)
                if policy_status['PolicyStatus']['IsPublic']:
                    issues.append('Bucket policy allows public access')
            except s3.exceptions.NoSuchBucketPolicy:
                pass  # No bucket policy is acceptable

            # Check bucket ACL
            acl = s3.get_bucket_acl(Bucket=bucket_name)
            for grant in acl.get('Grants', []):
                grantee = grant.get('Grantee', {})
                uri = grantee.get('URI', '')
                # 'AllUsers' = anonymous public access
                # 'AuthenticatedUsers' = any AWS account (still overly permissive)
                if grantee.get('Type') == 'Group' and ('AllUsers' in uri or 'AuthenticatedUsers' in uri):
                    issues.append('Bucket ACL grants public access')
                    break

            if issues:
                risky_buckets.append({'bucket': bucket_name, 'issues': issues})

        except Exception as e:
            errors.append(f'{bucket_name}: {str(e)}')

    # Send alert if risky buckets found
    if risky_buckets:
        message = f'Found {len(risky_buckets)} buckets with public access:\n\n'
        for item in risky_buckets:
            message += f"  {item['bucket']}: {', '.join(item['issues'])}\n"

        sns.publish(
            TopicArn='arn:aws:sns:<REGION>:<ACCOUNT_ID>:<TOPIC_NAME>',
            Subject='S3 Public Access Alert',
            Message=message
        )

    return {
        'statusCode': 200,
        'body': json.dumps({
            'risky_buckets': risky_buckets,
            'errors': errors,
            'total_checked': len(buckets)
        })
    }
Multi-account scanning: This script scans the current account only. To scan across member accounts, see the Multi-account extension section later in this post.
Audit Lambda function – Example script v2 (CSV and JSON report)
The following is an example Lambda function script for reference purposes. Before deploying any script, review error handling, logging, output structure, and permissions. This script generates CSV and JSON output files and uploads them to an S3 bucket for reporting and business intelligence (BI) dashboard integration.
You can deploy both functions with different EventBridge schedules, for example, Script v1 daily for alerts and Script v2 weekly for reports.
Note: Before you deploy this script, replace <OUTPUT_BUCKET_NAME> with the S3 bucket you created for audit reports in step 4.
import boto3
import csv
import json
import os

def lambda_handler(event, context):
    s3 = boto3.client('s3')
    buckets = s3.list_buckets()['Buckets']

    full_access_buckets = []
    for bucket in buckets:
        bucket_name = bucket['Name']
        try:
            bucket_policy = s3.get_bucket_policy(Bucket=bucket_name)['Policy']
            policy = json.loads(bucket_policy)
            for statement in policy['Statement']:
                if (statement['Effect'] == 'Allow'
                    and statement['Principal'] == '*'
                    and 'Action' in statement
                    and 's3:*' in statement['Action']):
                    full_access_buckets.append({'BucketName': bucket_name})
                    break
        except s3.exceptions.ClientError as e:
            if e.response['Error']['Code'] != 'NoSuchBucketPolicy':
                print(f'Error checking bucket policy for {bucket_name}: {e}')

    # Output CSV
    csv_output = os.path.join('/tmp', 'full_access_buckets.csv')
    with open(csv_output, 'w', newline='') as csvfile:
        writer = csv.DictWriter(csvfile, fieldnames=['BucketName'])
        writer.writeheader()
        writer.writerows(full_access_buckets)

    # Output JSON
    json_output = os.path.join('/tmp', 'full_access_buckets.json')
    with open(json_output, 'w') as jsonfile:
        json.dump(full_access_buckets, jsonfile, indent=2)

    # Upload to Amazon S3
    output_bucket = '<OUTPUT_BUCKET_NAME>'
    s3.upload_file(csv_output, output_bucket, 'full_access_buckets.csv')
    s3.upload_file(json_output, output_bucket, 'full_access_buckets.json')

    return {
        'statusCode': 200,
        'body': json.dumps(f'CSV and JSON files uploaded to {output_bucket}')
    }
Important: If this function runs on a schedule, consider implementing a file naming strategy with timestamps to prevent overwriting previous reports or establish a lifecycle policy to manage retention. Include the output bucket in your cleanup procedures when the auditing process is no longer needed.
What if no over-permissioned buckets are found?
If the audit scan returns zero risky buckets, document the clean baseline for future comparison and move to the verification and monitoring phase to so new buckets or policy changes don’t introduce risk over time.
Multi-account extension
The preceding example scripts scan buckets in the current account only. To scan across member accounts in your organization, add the following AssumeRole logic. This function assumes the cross-account IAM role you created during setup, then returns an Amazon S3 client with temporary credentials for each member account.
Note: Before you deploy, configure the following Lambda environment variables:
<MEMBER_ACCOUNTS> – Comma-separated list of 12-digit account IDs to scan (for example, 111111111111,222222222222)
<CROSS_ACCOUNT_ROLE_NAME> – The IAM role name created in each member account (for example, S3AuditRole)
<EXTERNAL_ID> – The external ID configured in the trust policy (for example, s3-audit-external-id)
import boto3
import os

def get_member_s3_clients():
    """
    Assumes the cross-account audit role in each member account
    and returns a list of (account_id, s3_client) tuples.
    """
    sts = boto3.client('sts')
    member_accounts = os.environ.get('<MEMBER_ACCOUNTS>', '').split(',')
    cross_account_role_name = os.environ.get('<CROSS_ACCOUNT_ROLE_NAME>')
    external_id = os.environ.get('<EXTERNAL_ID>')

    clients = []
    for account_id in member_accounts:
        account_id = account_id.strip()
        if not account_id:
            continue

        try:
            assumed_role = sts.assume_role(
                RoleArn=f'arn:aws:iam::{account_id}:role/{cross_account_role_name}',
                RoleSessionName='S3AuditSession',
                ExternalId=external_id
            )

            # Create S3 client with assumed credentials
            s3_client = boto3.client(
                's3',
                aws_access_key_id=assumed_role['Credentials']['AccessKeyId'],
                aws_secret_access_key=assumed_role['Credentials']['SecretAccessKey'],
                aws_session_token=assumed_role['Credentials']['SessionToken']
            )
            clients.append((account_id, s3_client))

        except Exception as e:
            print(f'Failed to assume role in account {account_id}: {e}')

    return clients
To scan each member account, replace the single-account s3.list_buckets() call with a loop over member accounts:
def lambda_handler(event, context):
    all_risky_buckets = []
    all_errors = []

    # Scan each member account
    for account_id, s3_client in get_member_s3_clients():
        try:
            buckets = s3_client.list_buckets()['Buckets']
            for bucket in buckets:
                # ... same scanning logic as the single-account scripts ...
                # Use s3_client instead of s3 for each API call
                pass
        except Exception as e:
            all_errors.append(f'Account {account_id}: {e}')

    # ... same alerting/reporting logic ...
The Lambda execution role in the central security account needs sts:AssumeRole permission for the cross-account role ARNs. Add this to the execution role policy you created in step 5.
Remediate elevated access
This section describes how to fix over-permissioned buckets using account-level controls, bucket policies, and optional automation. Any elevated access that you find needs to be remediated.
Enable Amazon S3 Block Public Access (account level)
Before applying individual bucket policies, enable Amazon S3 Block Public Access at the account level. This prevents buckets in the account from being made public, regardless of individual bucket policies or ACLs. See theS3 Block Public Access documentation for configuration details. See the following example AWS CLI command; replace <ACCOUNT_ID> with the ID of the account you’re using to manage resource access:
For multi-account environments, deploy this setting across member accounts using AWS CloudFormation StackSets or AWS Organizations service control policies (SCPs).
Important: Before enabling account-level S3 Block Public Access, check whether any workloads need public bucket access (for example, static website hosting, public dataset sharing). Coordinate with your application teams to identify any exceptions.
Remediate using bucket policies
Implement bucket policies that restrict access to specific IAM users, roles, or accounts. When crafting policies, apply the principle of least privilege and include only the actions and principals required for your use case.
Example S3 bucket policy: deny public read/write access. Modify the resource ARN, actions, and conditions to match your requirements:
Automate remediation with Lambda or CloudFormation StackSets (optional):
You can also remediate using Lambda or CloudFormation Stacksets:
Create Lambda functions to automatically update bucket policies or disable public access settings for flagged buckets
Use CloudFormation StackSets to deploy standardized bucket policies and S3 Block Public Access settings across multiple accounts
Verify your remediation
This section explains how to confirm that your fixes are effective before moving to ongoing monitoring. After applying remediation, verify the fix is effective before setting up ongoing monitoring:
Re-run the audit Lambda function – Confirm the previously flagged buckets no longer appear in the risky buckets list.
Check Security Hub compliance – Verify the compliance status has changed from FAILED to PASSED for Amazon S3-related controls.
Validate with IAM Access Analyzer – Review findings for the remediated S3 buckets. Active findings should resolve automatically after public access is removed.
Test application functionality – Confirm that legitimate workloads continue to function correctly.
Document the verification results for your auditing needs. If any S3 buckets still show issues, investigate whether the policy was applied correctly or if there are conflicting permissions.
Automation opportunities
This section covers optional strategies to automate ongoing detection and maintain your security posture without manual intervention.
(Optional) Schedule recurring scans with Amazon EventBridge
Regular security scans help identify new issues arising from configuration changes or newly created S3 buckets. When new security risks are detected, Amazon SNS sends an alert and automatically initiates the remediation phase (Workflow 2 in Figure 1). To avoid repeated alerts, you can configure the audit Lambda function to run on a schedule and compare current results with the previous baseline to generate notifications when new findings are discovered.
For ongoing monitoring, you can schedule the audit Lambda function to run on a recurring basis using EventBridge. Create a scheduled rule with a cron expression (for example, daily at 6:00 AM UTC or weekly on Mondays), add the Lambda function as the target, and grant EventBridge permission to invoke it. See Amazon EventBridge scheduling documentation for instructions on creating scheduled rules and configuring targets.
Enable IAM Access Analyzer for Amazon S3
IAM Access Analyzer monitors bucket policies, ACLs, and access points to identify buckets accessible from outside your account or organization. Create an analyzer scoped to your organization or individual account, then review findings to identify unintended external access. Findings automatically flow into Security Hub when both services are enabled, giving you a dashboard view for Amazon S3 security findings. See the IAM Access Analyzer documentation for setup and usage instructions.
Automate notifications for policy drift
Recurring scans might surface new findings from policy drift or newly created buckets. When new risks are detected, Amazon SNS alert triggers and the remediation cycle repeat (as shown in Workflow 2 in Figure 1) sends email notifications. Configure the audit Lambda function to compare current scan results against the previous baseline and alert on new findings for ongoing reviews.
Clean up
This section lists the resources created during this walkthrough that you should review and remove when they are no longer needed. If the following services were not previously active in your account, leaving them enabled might result in additional ongoing charges. See the Cost considerations section for details. Review and remove unused resources to optimize costs.
Delete or disable the following script-generated resources if they’re not required after outputs are generated. Focus first on Lambda functions and EventBridge rules if you’re not running recurring scans. If you enabled AWS Config or Security Hub specifically for this audit, evaluate whether you need them for other compliance requirements before disabling.
Lambda – Functions, IAM roles, and policies created for auditing
Amazon EventBridge – Scheduled rules created for recurring audit triggers
Amazon SNS – Topics and subscriptions created for notifications
AWS Config – Rules and recorders if no longer needed for compliance
Security Hub – Disable if enabled solely for this audit
IAM Access Analyzer – Delete the analyzer if no longer needed for ongoing monitoring
Note: Be careful when deleting data and consider temporarily disabling services first to check for dependencies. Only delete resources generated as part of your audit outputs. Verify you have retained any necessary results before proceeding. Verify resources are not used by other workloads before deletion.
Best practices
This section provides recommendations to maintain secure Amazon S3 configurations long-term. To learn more about maintaining secure Amazon S3 configurations, review the AWS documentation links provided in the conclusion. The following recommendations aren’t exhaustive. Adapt and extend them based on your organization’s evolving security requirements and AWS best practices guidance. After you’ve fixed existing issues, these practices help you maintain secure Amazon S3 configurations.
Start with account-level controls – Enable S3 Block Public Access at the account level. This prevents buckets from becoming public even if someone misconfigures an individual bucket policy. For multi-account environments, enforce this through AWS Organizations SCPs.
Automate detection – Use IAM Access Analyzer to detect external access. Schedule your audit Lambda function with EventBridge to catch new issues weekly or daily, depending on your change frequency. Compare scan results against previous baselines to identify drift.
Standardize across accounts – Use CloudFormation StackSets to deploy the same secure configuration to all accounts in your organization, reducing the chance of configuration drift. Use StackSets for IAM roles, AWS Config rules, and S3 Block Public Access settings.
Additional security measures
Regularly review and rotate cross-account IAM role credentials and external IDs
Implement Amazon S3 server-side encryption (SSE-S3 or SSE-KMS) for data at rest
Enable S3 access logging and AWS CloudTrail data events for audit trails
Conclusion
This section summarizes what you accomplished and suggests next steps to maintain your S3 security posture. By implementing the detection, remediation, and monitoring workflow outlined in this post, you can proactively identify and secure over-permissioned S3 buckets across your AWS environment. To maintain your ongoing security posture, enable IAM Access Analyzer for continuous monitoring and schedule recurring audits with EventBridge. To learn more about Amazon S3 security best practices, see Security best practices for Amazon S3
Customers tell us that managing TLS certificates at scale is one of their biggest operational concerns. The Certification Authority Browser Forum (CA/Browser Forum) has mandated a phased reduction in maximum certificate validity for public certificates. By March 2027, the maximum validity drops to 100 days. By March 2029, it lasts for 47 days. For an organization managing 1,000 certificates, the final transition means roughly 30 renewal events every day. Renewal and rotations of renewed certificates at that cadence isn’t something manual processes or ticket-driven workflows can sustain at scale.
We recently announced Automated Certificate Management Environment (ACME) protocol support in AWS Certificate Manager (ACM). With this launch, you can use the ACME clients your teams already know, including popular open source tools like certbot, cert-manager, acme.sh, and win-acme, to automate public certificate issuance and renewal for your infrastructure. Customers that are using third-party certificate authorities (CAs) can point their existing ACME-compatible clients at ACM instead of their current CA, with minimal reconfiguration. This applies whether it’s running on Amazon Web Services (AWS), on premises, or in a hybrid environment. Certificates created through ACME are registered in ACM, giving you a unified view of your entire certificate inventory.
This post covers how the feature works, how to get started, and the controls and best practices to help you manage certificate issuance at scale.
Background
ACME is an open source protocol that automates the process of verifying domain ownership and issuing certificates and has become a standard mechanism for certificate automation. While ACM has long provided managed certificate issuance and renewal for AWS-integrated services such as Elastic Load Balancing (ELB), Amazon CloudFront, and Amazon API Gateway, many customers also need to automate certificates for their own infrastructure, including servers they manage in their data centers, Kubernetes clusters, Internet of Things (IoT) fleets, and hybrid environments. Until now, those customers had to turn to external providers. This launch brings the ACM automation model to that same infrastructure, using the standard ACME protocol with AWS managed certificate endpoints.
How it works
The feature introduces a new centrally provisioned and managed resource type: the ACME endpoint. Each endpoint is an AWS resource with a unique ACME directory URL and AWS Identity and Access Management (IAM)-based access controls. You create and manage endpoints through the ACM API or AWS Management Console, and point your existing ACME clients at the endpoint URL. Certificates issued through your endpoint are automatically registered with ACM, appearing in your certificate inventory alongside certificates created by the RequestCertificate and ImportCertificate API calls.
The architecture separates into two planes. In the control plane, PKI administrators use ACM APIs to create ACME endpoints, pre-approve the domains an endpoint is allowed to issue for, and generate external account binding (EAB) credentials. In the data plane, ACME clients register with an endpoint using EAB credentials and request certificates for domains the administrator has already validated. This architecture is how we provide customers the ability to scale. Instead of each client proving domain ownership on every request, a principal with appropriate ACM permissions (typically your PKI administrator) validates domains once at the endpoint level, and then application owners don’t need DNS credentials to get a certificate.
Adding to the data plane, EABs control client access to the endpoints. Each EAB is bound to an IAM role that controls what certificate operations the ACME client can perform, and credentials you generate in ACM are distributed to authorized ACME clients. An ACME client authorized for one endpoint can’t use a different endpoint. This creates security boundaries between environments. For example, a client authorized for your development endpoint can’t obtain certificates from your production endpoint.
Figure 1 shows the ACME request flow through ACM. An ACME client authenticates to an ACME endpoint using EAB credentials. The endpoint routes certificate orders to Amazon Trust Services for issuance. Issued certificates are registered in ACM inventory, where Amazon EventBridge and AWS CloudTrail provide expiration alerting and audit logging.
Figure 1: An ACME architecture and workflow
Getting started
Getting started with the new ACME feature in ACM is straightforward. Use the following steps to create your first ACME-generated certificate.
Prerequisites
An AWS account with permissions to create and manage ACM resources
An ACME client installed on your infrastructure (for example, Certbot, cert-manager, acme.sh, or others)
Amazon Route 53 hosted zone for your domain, or the ability to create a CNAME record with your DNS provider
Step 1: Create an ACME endpoint
Before you can use ACME clients with ACM, you need to create an ACME endpoint. This endpoint provides the URL that your ACME clients will use to request certificates.
Run the following command from the AWS CLI to create an ACME endpoint:
Before ACME clients can request a certificate, the administrator validates the domain using DNS once at the endpoint level. Use DomainScope to control exactly which certificate patterns are allowed:
Enabling only ExactDomain restricts clients to that specific name,
Subdomains enabled allows names like api.example.com,
Wildcards enabled allows *.example.com.
Leave a scope disabled to block that pattern outright, even if an otherwise-valid ACME request asks for it. For a production endpoint, consider enabling only ExactDomain and Subdomains and leaving Wildcards disabled for a stricter posture.
If your domain is hosted in Route 53, specifying HostedZoneId lets ACM create the required CNAME record automatically. If your domain is hosted elsewhere, omit it and create the provided CNAME record manually with your DNS provider. Validation typically completes within a few seconds after the record is in place.
EAB credentials authenticate your ACME clients to your endpoint. Generate a unique set of credentials for each client or environment to maintain security boundaries.
Run the following command to generate your EAB credentials, adjusting your expiration to fit your organization’s risk profile:
With your endpoint URL and EAB credentials ready, you can now configure your preferred ACME client. The following examples show configuration for two popular clients. As a reminder, the server information was retrieved in step 1, part 4 as the EndpointUrl.
After the initial registration, your ACME client handles renewals.
Enterprise controls
Other ACME alternatives can provide certificates but don’t give the same amount of control and governance for customers that need to scale their certificate environment. The following controls are available to help reduce risk across your organization.
Domain validation
Customers managing large numbers of domains told us they need a way to prevent unauthorized certificate issuance across their domain space. Domain validation gives you this control. For each domain you validate, you enable the certificate patterns it should be allowed to issue, whether it’s ExactDomain, Subdomains, or Wildcards. For example, if you validate internal.example.com and enable only Wildcards, an ACME client can request *.internal.example.com but a request for internal.example.com itself or api.internal.example.com is rejected. This enforcement happens at the endpoint level, before requests reach the ACM certificate authority, and you can validate multiple domains under a single endpoint, each with its own scope.
Centralized certificate visibility
Certificates issued through your ACME endpoints are registered with ACM. You can use the aws acm list-certificates command to see all your issued certificates.
IAM authorization, CloudTrail audit logging and observability
Endpoint management operations are authorized through IAM and logged to CloudTrail. You can use IAM policies to control which principals can create endpoints, generate EAB credentials, and manage domain constraints.
Best practices
For customers implementing ACME certificates for the first time, consider the following best practices for your organizations.
Segment endpoints along organizational or environment boundaries
The endpoint serves as a useful method of isolation for larger organizations. A large enterprise can create one endpoint per organizational boundary (business unit, subsidiary, or environment) instead of a single shared endpoint company-wide. Each endpoint has its own pre-approved domains and its own set of EABs, so a compromised credential in one business unit has no path to certificates in another.
However, weigh this against your operational overhead as well. A reasonable starting point is one endpoint per environment (dev, staging, andprod) within a business unit, expanding to per-business-unit endpoints only where compliance or organizational requirements call for it.
Manage EAB credentials securely
Anyone holding a validKeyIdandMacKeyfor an endpoint can obtain certificates for any domain pre-approved on that endpoint, so these credentials deserve the same handling you’d give an access key.
Avoid hard coding theMacKeywhere possible by using a secret store such as AWS Secrets Manager. Distribute it only to the ACME clients that you authorize to use the endpoint.
Set the expiration of the EAB to an acceptable level. While EAB supports long-lived credentials, not all scenarios require an indefinitely long EAB.
When creating the role for each EAB, adhere to concept of least privilege. Creating a role per EAB, rather than sharing a role across all bindings, can help reduce risk in your AWS environment.
Audit CreateAcmeExternalAccountBinding and GetAcmeExternalAccountBindingCredentials calls in CloudTrail separately. Because retrieving the actual key material is a distinct API call from creating the binding, alerting on retrieval events is a stronger signal of real credential distribution than binding creation alone.
Automate how EABs are associated with clients at runtime
Generate a unique set of EAB credentials for each client or environment rather than sharing one binding across multiple ACME clients. As you begin to scale with multiple endpoints, usesome of the following patterns to reduce operational toil.
Name each EAB and its bound IAM role after the client it belongs to (team, application, environment), so the binding’s purpose is obvious from DescribeAcmeExternalAccountBinding output alone, without cross-referencing a spreadsheet.
Store each client’s KeyId and MacKey under a secrets path scoped to that client (for example, a Secrets Manager path per team and environment), and let the client’s provisioning pipeline retrieve its own credentials.
In Kubernetes, use one ClusterIssuer or namespace-scoped Issuer per EAB rather than one shared issuer across teams. This keeps the client-to-EAB association explicit in cluster config, and lets you revoke one team’s access without touching anyone else’s.
For ephemeral infrastructure (build agents, autoscaled fleets), provision EAB credentials as part of your infrastructure-as-code or continuous integration and deployment (CI/CD) pipeline instead of a one-time manual handoff, so credential lifecycle tracks infrastructure lifecycle.
Monitor your deployment of ACME
ACME’s power is through automation, and organizations should monitor their ACME usage for anomalies.
Alarm on issuance failures, not just successes. At 45-day certificate validity, a silent renewal failure gives you far less runway to react than the months of time you might be used to with longer-lived certificates.
Test renewal automation before you depend on it. Force a manual renewal against a non-production endpoint and confirm your client, monitoring, and on-call runbooks behave as expected, before the CA/Browser Forum’s shortened validity windows turn a failed renewal into a disruptive event for your organization.
Availability and pricing
ACME support in AWS Certificate Manager is available today in all commercial AWS Regions and will be available in AWS GovCloud (US), the China Regions, and the AWS European Sovereign Cloudpartitions at a later date. See the ACM pricing page for more information on ACME pricing.
Conclusion
The phased reduction in certificate validity can’t easily be solved without automation. ACME support in ACM gives you that automation through a standard protocol and standard tooling, while keeping the visibility and governance controls your security teams rely on from ACM.
Imagine preparing for your biggest sales event of the year, and you want to ensure your customer identity management service can handle the elevated traffic for carrying out application activities. For security teams, business leaders, and technologists managing identity infrastructure at scale, this scenario has been all too familiar. Whether you’re a CISO evaluating security controls, a CFO managing cloud costs, traditional support ticket processes for adjusting Amazon Cognito rate limits meant waiting 10–14 days for capacity increases, requiring teams to plan weeks in advance or rush to escalate.
Today, we’re announcing provisioned limits for Amazon Cognito, a capability that transforms how you manage authentication rate limits. This introduces a feature in the AWS Management Console for Amazon Cognito for on-demand capacity adjustments, working alongside the existing account-level maximum limits in AWS Service Quotas. Together, they give you self-service control over your authentication infrastructure so you can scale up for Black Friday (or similar sales events), scale down after tax season, and optimize costs with unprecedented precision. What once took up to 2 weeks now happens in minutes.
In this post, you’ll learn how provisioned limits work, the relationship between account-level maximums and provisioned capacity, the cost implications and optimization strategies, and step-by-step implementation guidance. This capability fundamentally changes how you approach authentication capacity planning.
Manual processes that can’t keep pace
Identity management services open the front door to your application. When users can’t sign in, everything else stops. Amazon Cognito offers extremely flexible limit management: customers can request adjustments as granular as 1 request per second (RPS) for as short as 1 day. As customer demand for faster, self-service adjustments grew, we identified opportunities to address the following challenges:
Support tickets required for each rate limit change
10–14 day approval timelines for standard review and processing
Advance planning needed weeks ahead of anticipated traffic spikes
For businesses with seasonal traffic, like tax preparation services that see 90% of annual authentication volume in March and April, or ecommerce platforms preparing for Black Friday, these factors meant teams had to plan capacity decisions well in advance with limited ability to adjust in the moment.
Provisioned limits and account-level max limits
Starting July 6, 2026, Amazon Cognito introduced provisioned limits in the Amazon Cognito console. At the account level (per AWS Region, per account), you’ll find a Provisioned limits tab next to the User Pools tab. This gives you direct control over your authentication rate limits through two complementary mechanisms:
Provisioned limits (Amazon Cognito console) – Adjust your provisioned capacity up or down on-demand. Changes take effect immediately. You’re billed for the capacity you provision above the default limit, regardless of how much you use.
Account-level max limit (Service Quotas console) – Set your account’s ceiling, the maximum RPS your account is allowed to provision. Raising this ceiling doesn’t incur additional charges. Approximately 90% of requests are automatically approved within minutes. For larger limit increases (depending on the API category and Region), manual approval through AWS Support might still be required.
The following experience shows the end-to-end workflow of adjusting your provisioned limits and requesting a higher account-level max.
Figure 1: Provisioned limit experience workflow
How they work together
Let’s use the UserCreation API as an example. The default limit is 50 RPS, and initially the provisioned limit is also 50 RPS—meaning billed capacity is 0 (no additional charge). The applied account-level max limit is also 50 RPS. So you have three values: default (50), provisioned limit (50), and account-level max (50).
Start by going to the Amazon Cognito console and choosing User pools from the navigation pane.
Figure 2: UserCreation with default values
Choose Edit provisioned limit, to go to the Edit provisioned limit page with an input field for New provisioned limit. However, because the account-level max limit is 50 RPS, you can’t set the provisioned limit above 50. For example, if you want to provision 55 RPS, the console won’t allow it because 55 exceeds the current account max of 50.
Figure 3: Editing the provisioned limit constraint constraint to more than the account-level max
To set a higher limit, choose Request an increase. This takes you to the Service Quotas console, where you can choose Request increase at account level to request a higher account-level max, for example, 55 RPS. Most requests are automatically approved within minutes. At any time, you can check the status of the request using the Request history tab.
Figure 4: Service Quotas page where the account-level max increase is requested and auto-approved
After receiving approval, return to the Amazon Cognito console to edit your provisioned limit up to 55 RPS. Your billed capacity becomes 5 RPS (55 minus the 50 default).
Figure 5: Provisioned after increasing the provisioned limit to 55 RPS, with billed capacity of 5 RPS.
This two-part model gives you precise control over both cost and capacity. Raising the account-level max in Service Quotas doesn’t incur additional charges—it only sets your ceiling. You are billed for what you provision in the Amazon Cognito console above the default, so you benefit from right-sizing your provisioned capacity to match expected demand. Raise your account max ahead of time to prepare for future scaling needs without incurring any cost. When the time comes, increase your provisioned limit to what you need, and scale back down after the event. You stop being charged for the extra capacity as soon as you reduce the provisioned limit. This applies equally to seasonal spikes, planned load tests, or unexpected viral growth—all self-service, all within minutes.
How the provisioned limits experience works
The provisioned limits experience introduces three key concepts that work together:
Default limit – The baseline rate included at no additional cost (for example, 50 RPS for UserCreation).
Provisioned limit – The capacity you actively request and reserve in the Amazon Cognito console. Because this capacity is reserved specifically for your account, it’s the chargeable dimension. You’re billed for any provisioned capacity above the default, regardless of how much you consume. For example, if the default is 50 RPS and you provision 80 RPS, you’re billed for 30 RPS even if your actual usage is only 60 RPS. If your provisioned capacity is 50 RPS (the default), your billed capacity is 0.
Applied account-level max limit – The ceiling managed through Service Quotas. This determines how high you can set your provisioned limit. Raising this ceiling doesn’t incur charges, it only unlocks the ability to provision higher capacity. Importantly, the Provisioned limits page displays each API category with its adjustability status. For example, UserCreation is marked Adjustable (shown earlier in Figure 5) and can be modified. However, UserList is marked Not adjustable, meaning the account-level max limit can’t be adjusted for that category. You can still see its default and provisioned limit on the page, but you can’t modify them. For adjustable categories, you will see the default limit, current provisioned limit, and billed capacity at a glance.
Figure 6: Provisioned limits overview with non-adjustable API categories.
Multi-tenant SaaS considerations
For software as a service (SaaS) providers managing multiple tenants with varying throughput requirements, the UpdateProvisionedLimit API enables programmatic management of provisioned capacity. Teams using dedicated user pools per tenant, for example, can integrate this into their infrastructure-as-code pipelines to adjust provisioned limits per tenant tier. With provisioned limits, SaaS vendors can tier their capacity management per tenant, for example, provisioning higher capacity for enterprise-tier tenants and lower capacity for free-tier tenants, and adjust each tenant’s provisioned capacity independently through the API based on their service tier and demand patterns.
Conclusion
With provisioned limits, whether you’re preparing for peak shopping season, tax filing deadlines, or any other scaling event, you can now adjust provisioned limits to respond to your organization’s needs on demand. The separation between the account-level max (in Service Quotas) and the provisioned limit (in the Amazon Cognito console) gives you full control to plan ahead, respond to demand changes in minutes, and optimize costs on your own terms.
Get started
The provisioned limits experience for Amazon Cognito user pools launched on July 6, 2026, and is available across all AWS Regions where Amazon Cognito is supported. To get started:
Review your current authentication traffic patterns using Amazon CloudWatch metrics to understand your baseline
Set up CloudWatch alarms at 70% and 85% of your current rate limits
Ensure your team has appropriate AWS Identity and Access Management ( IAM) permissions for both Service Quotas and the Provisioned limits tab in the Amazon Cognito console
Raise your account-level max in Service Quotas based on your demand expectations
Use the Amazon Cognito console Provisioned limits tab to adjust capacity up or down as needed

 Login