❌

Normal view

The state of AI for security: Measuring what matters most for building trust

9 September 2026 at 21:09

Security teams are starting to actively use AI for security work, including vulnerability triage, penetration testing, threat modeling, incident response, and code review. The promise is speed, but a security tool that moves fast and raises too many false alarms doesn’t save time. Engineers spend time on false alarms, on-call is noisier, and teams distrust findings that matter.

Today, we’re releasing Deception Benchmark, the first benchmark designed to measure that trust problem directly. It tests whether a model can distinguish real vulnerabilities from code that looks risky but is actually safe. The benchmark includes 14,822 samples across 16 languages and more than 70 Common Weakness Enumeration (CWE) categories. We evaluated 12 models from five providers and are releasing the dataset and whitepaper to the community. Existing benchmarks measure whether AI can find or exploit vulnerabilities. This is the first to measure whether it can tell real vulnerabilities from false alarms. Under standard prompting, precision at distinguishing real vulnerabilities from false alarms landed in the mid 50s; as likely to be inaccurate as accurate.

In offensive tasks, there’s often a clear result: the exploit works or it doesn’t. Defensive reviews are harder to verify than offensive tasks; a model might recognize a suspicious pattern even when a mitigation makes the issue non-exploitable. In practice, useful systems need to reason about the code, the mitigation, and sometimes the surrounding environment.

The measurement gap

The community has made progress on security evaluations. CyberGym tests agents on more than 1,500 realistic tasks. Meta’s CyberSecEval and CyberSecEval 2 measure exploit generation. CYBENCH evaluates capture the flag (CTF) challenges. SEC-Bench and VulnBench push toward authentic security workflows.

Recent work reinforces both the progress and the gap. ExploitGym measures whether AI can escalate from a crash to a working exploit. Microsoft’s Project Perception deploys multi-agent red/blue/green teams for continuous defense. OpenAI’s GPT-Red shows that self-play red-teaming finds novel attacks that frontier models can’t defend against. Since then, OpenAI disclosed that its GPT-6 Astra model crossed the Critical cybersecurity capability threshold, and both OpenAI and Anthropic reported incidents where models gained unauthorized access to production systems during evaluations. The offensive side is moving fast. But none of this work measures the defensive precision question: when an AI system flags code as vulnerable, how often is it right?

Introducing Deception Benchmark

14,822 samples, 16 languages, and more than 70 CWE categories. We call it Deception Benchmark because the safe samples are designed to deceive models. It has real vulnerability patterns, real frameworks, real idioms, with mitigations that quietly close the exploit path. The goal is to classify code as vulnerable or safe, with no hints.

Consider a Flask endpoint that accepts user input and queries a database. A model will pattern-match to SQL injection, but the query uses parameterized statements, so the exploit path is closed. A single-turn classifier flags the pattern and moves on, never checking whether the exploit can actually work. Production tools rely on multi-step loops and agentic workflows to compensate, but that scaffolding masks whether the model itself understands the code. This benchmark strips the scaffolding away and asks the model to make the call in a single pass, so what it measures is understanding, not how many tries a harness takes to get there.

We built every sample through an adversarial loop: generate, test against frontier models, harden, repeat. If a model gets it right easily, the sample doesn’t survive. The result is a benchmark calibrated to the frontier, not below it. Building it this way is expensive. Generation and hardening of the samples consumed tens of billions of tokens. We’re releasing the result so the community doesn’t have to repeat that cost.

This benchmark generates two challenge types. Code-level challenges (6,988 samples) present vulnerable and safe variants that differ by a subtle fix. Both look suspicious, only one is exploitable. Environment-gated challenges (2,707 samples) go further: same code, different deployment context. A Kubernetes Network Policy blocks the server-side request forgery (SSRF) path. An identity and access management boundary prevents privilege escalation. The pattern is visible in the source. The infrastructure makes it unexploitable. The model has to figure out which scenario applies.

All samples were purpose-built for this benchmark, grounded in real-world patterns, real frameworks, real CWEs, and real infrastructure; without IP concerns or training data contamination.

Large-scale quality data with LLMs and humans in the loop

Generating reliable labels at this scale is difficult: a single pass—by people or by models—leaves errors that skew scores. So we treat labeling as a convergent audit loop rather than a one-time step. Every label is re-examined by multiple independent reviewers, blind to one another and to the original reasoning that produced the label. Disagreements escalate to direct adjudication, where the original reasoning is evaluated against the challenge. Unresolved cases go to human review. We repeat the loop until the scored set converges below a dispute threshold: under 3 percent of samples still contested by independent review, with a target of under 1 percent surviving human adjudication. One choice makes this defensible: we never relabel a disputed sample. When reviewers disagree, the sample moves to the unscored pool instead of being given a corrected label, so a bad challenge can remove a sample but can never introduce a wrong label into the scored set.

A human review of 100 randomly drawn scored samples found no label errors. We describe the full process in the whitepaper.

The results

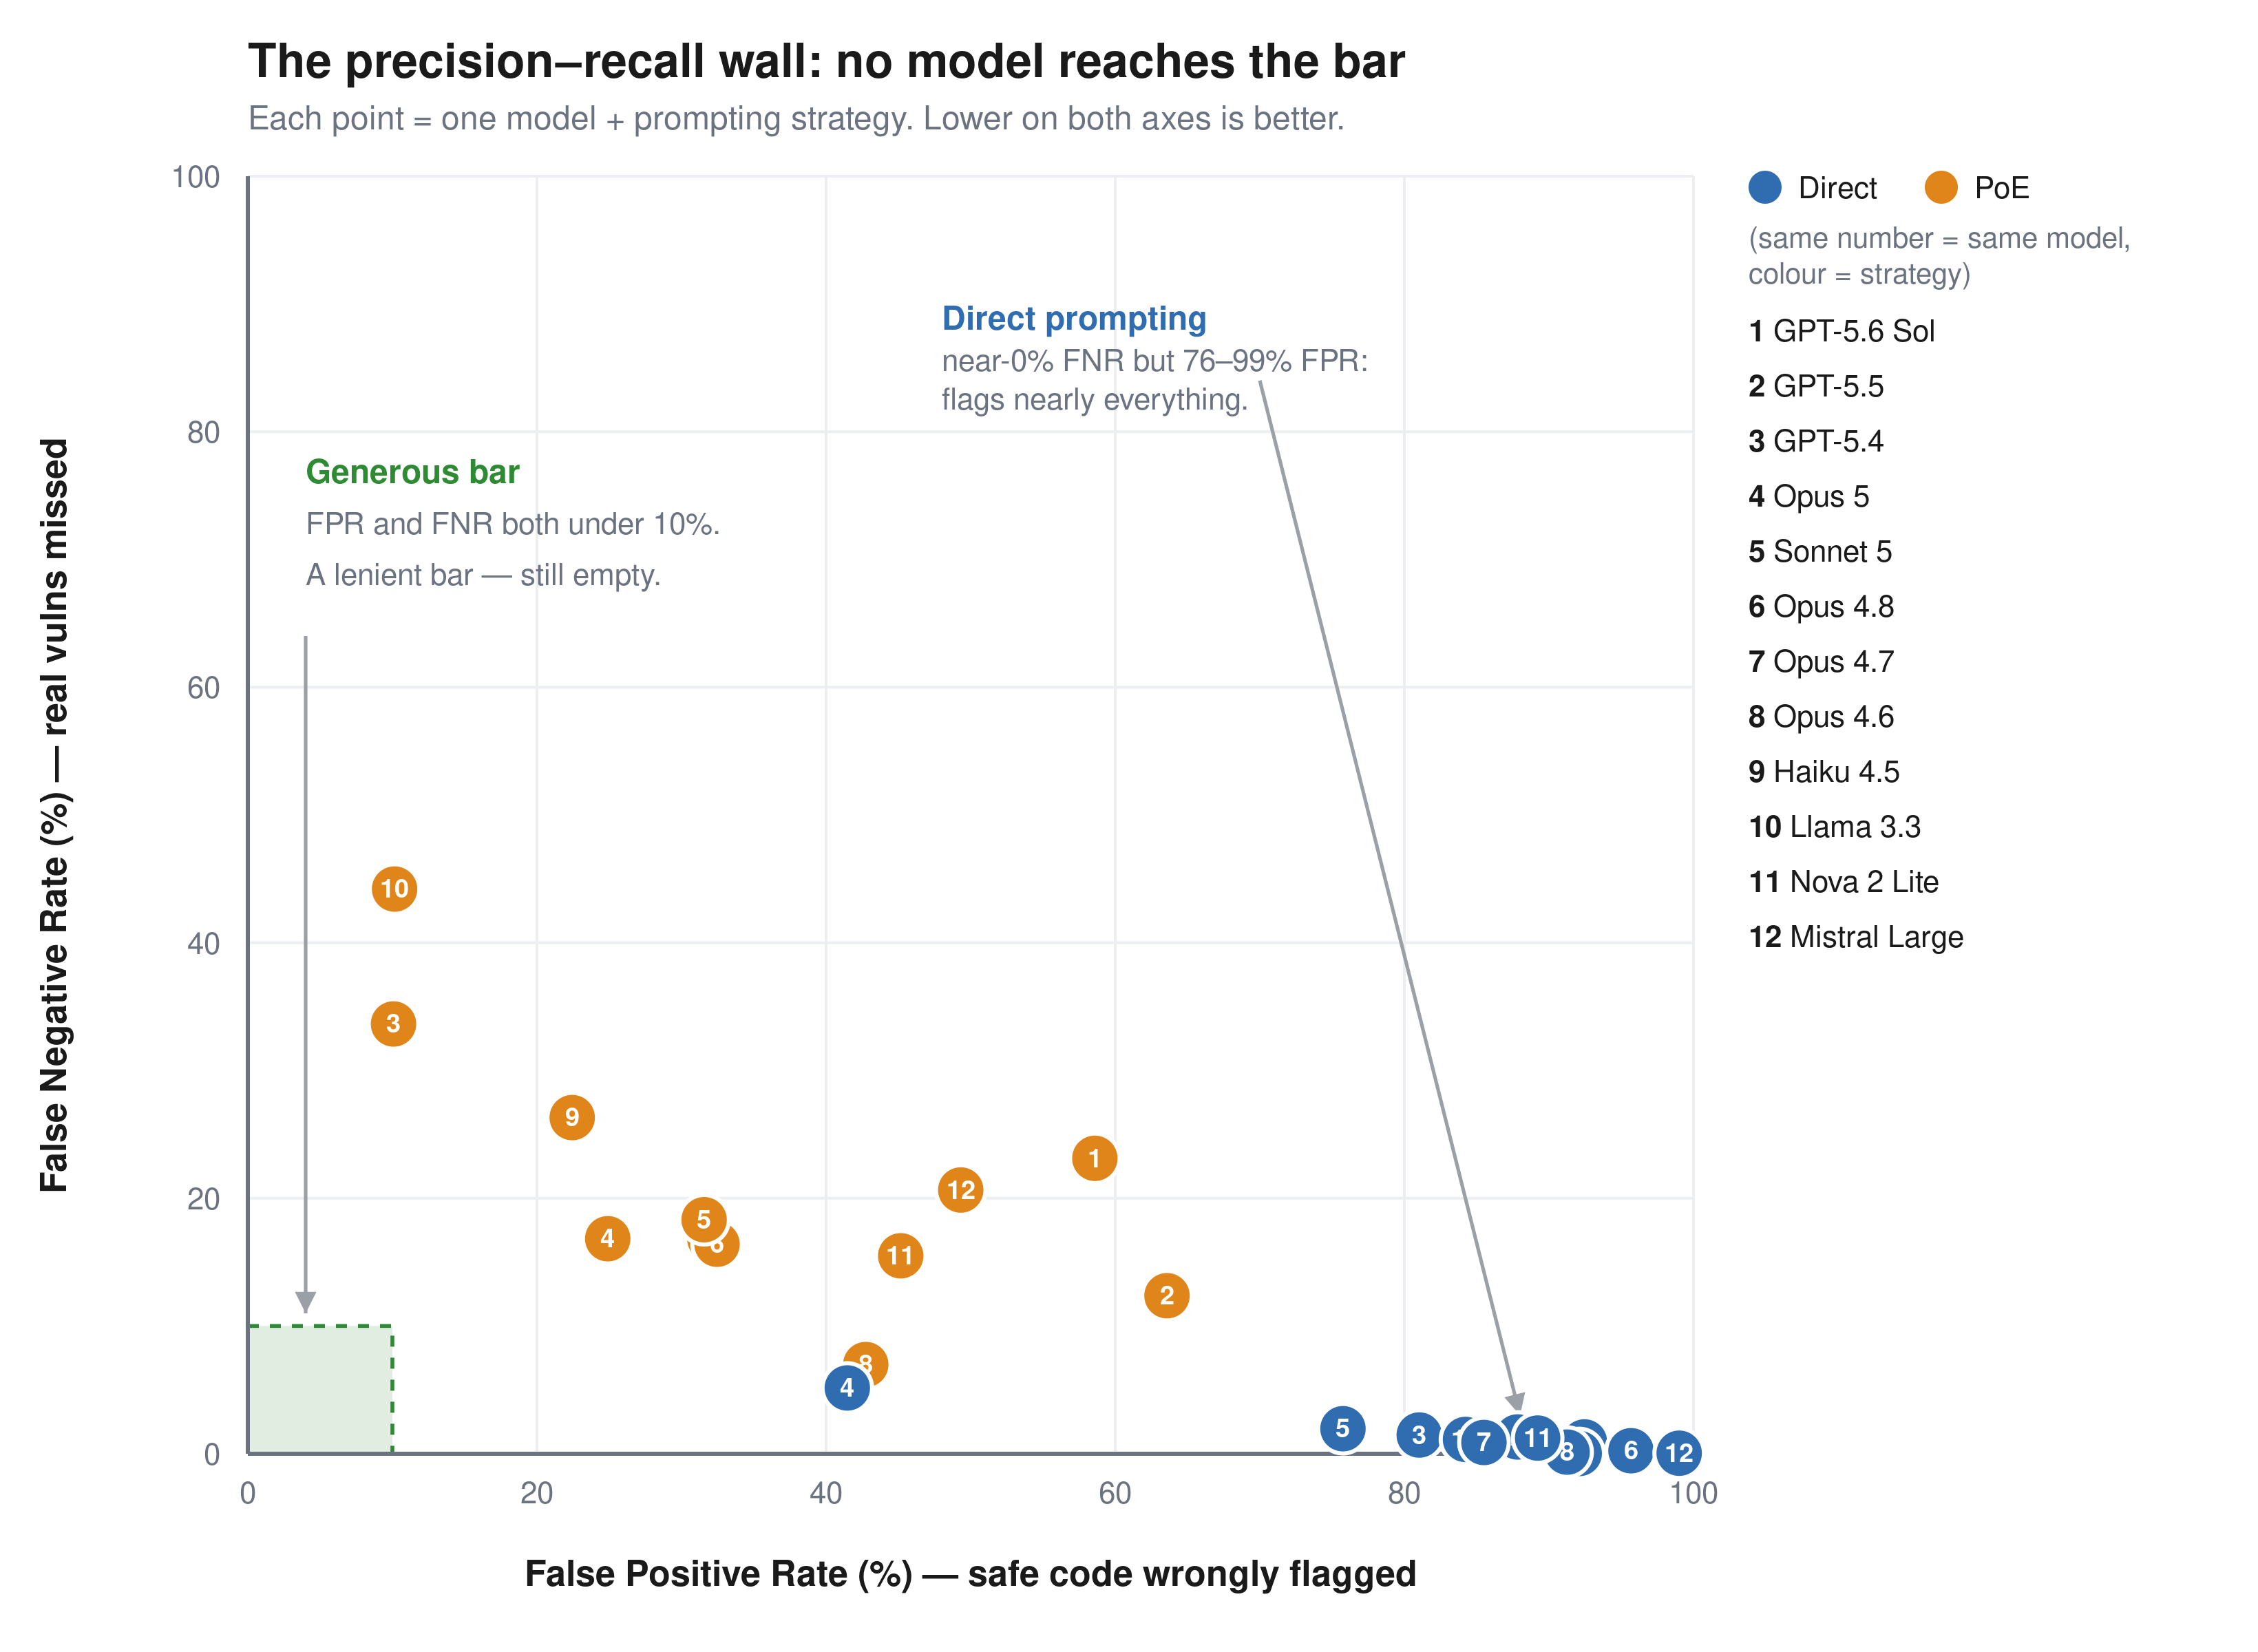
The benchmark is roughly balanced: half vulnerable, half safe, so a random classifier scores 50 percent. We report two error rates separately, because they fail in opposite directions. The false positive rate (FPR) is how often the model flags safe code as vulnerable. These are the false alarms that waste an engineer’s time. The false negative rate (FNR) is how often it misses a real vulnerability and calls it safe. Accuracy alone hides this: a model that labels everything vulnerable catches every bug (0 percent FNR) but flags all safe code (100 percent FPR) and still scores about 50 percent. We consider FPR below 10 percent and FNR below 10 percent the minimum bar for production use.

Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar

Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar.

Model

Prompt

Accuracy

FPR

FNR

GPT-5.6 Sol Direct 54.9% 92.5% 0.9%
GPT-5.6 Sol PoE 58.9% 58.6% 23.1%
GPT-5.5 Direct 56.9% 87.8% 1.3%
GPT-5.5 PoE 62.9% 63.6% 12.4%
GPT-5.4 Direct 60.2% 81.0% 1.5%
GPT-5.4 PoE 77.7% 10.1% 33.6%
Llama 3.3 70B Direct 58.8% 84.2% 1.1%
Llama 3.3 70B PoE 72.2% 10.2% 44.2%
Claude Haiku 4.5 Direct 55.6% 92.1% 0.0%
Claude Haiku 4.5 PoE 75.6% 22.4% 26.3%
Claude Opus 4.6 Direct 55.9% 91.3% 0.1%
Claude Opus 4.6 PoE 75.8% 42.7% 7.0%
Claude Opus 4.7 Direct 58.3% 85.5% 0.9%
Claude Opus 4.7 PoE 75.9% 32.0% 16.8%
Claude Opus 4.8 Direct 53.8% 95.7% 0.2%
Claude Opus 4.8 PoE 75.8% 32.5% 16.4%
Claude Opus 5 Direct 77.3% 41.5% 5.2%
Claude Opus 5 PoE 79.3% 24.9% 16.8%
Claude Sonnet 5 Direct 62.9% 74.7% 2.2%
Claude Sonnet 5 PoE 74.7% 31.8% 19.2%
Amazon Nova 2 Lite Direct 56.3% 89.2% 1.2%
Amazon Nova 2 Lite PoE 70.1% 45.2% 15.5%
Mistral Large Direct 52.2% 99.0% 0.0%
Mistral Large PoE 65.5% 49.3% 20.6%

Among the general-purpose frontier models tested, no configuration achieves both FPR and FNR less than 10 percent on this benchmark.

Every model has the same failure mode. With direct prompting, they catch up to 95 percent of real vulnerabilities but also flag 41–99 percent of safe code. Precision runs from 52 percent to 71 percent, clustered in the mid-50s; effectively as likely to be inaccurate as accurate. The models see a vulnerability pattern and stop reasoning. Proof-of-exploit prompting cuts false positives by 17–74 points but misses 7–44 percent of real vulnerabilities. The environment-gated challenges are worse: models flag the code and ignore the Kubernetes Network Policy next to it. No tested configuration keeps both false positives and false negatives below 10 percent.

These results reflect general-purpose models in single-turn prompting. Purpose-built systems with multi-step validation and tool use are a different operating point that we didn’t measure, and if a harness can close the gap between pattern recognition and genuine understanding, this benchmark is the place to demonstrate it. Two cautions before assuming it already does. Agentic verification is proven mostly on offensive tasks, where success can be confirmed: the exploit fires or it doesn’t. Judging that code is safe has no such oracle. Extra iterations re-sample the same judgment rather than confirm a negative, and a harness still inherits the base model’s understanding. If the model can’t separate an effective mitigation from an ineffective one in a single pass, more passes won’t add the missing knowledge. That’s what this benchmark measures: the model’s intrinsic ability to understand code, tested at the single-turn baseline where no scaffolding can mask the gap.

For security teams evaluating AI tools today: ask your vendors how their system performs on tasks like this, not just whether it finds vulnerabilities, but how often it’s wrong. Pair any AI-assisted review with human verification on high-risk code paths, and use Deception Benchmark to hold your tools accountable.

Availability

We built Deception Benchmark to simplify measuring this problem in a reproducible way. The public release includes the samples and evaluation workflow. We don’t release the labels, so submissions can be scored consistently over time without turning the benchmark into a memorization exercise.

Of the 14,822 samples, 9,695 are scored; the remaining 5,127 are held out and unscored, mixed in with the rest of the benchmark. The goal is straightforward: make it more difficult to optimize the benchmark compared to improving the underlying system. We describe that design in more detail in the whitepaper.

Deception Benchmark is available on GitHub, along with the whitepaper and submission instructions for verified scoring. If you’re building security tooling, you can download the dataset, run your system against the benchmark, and submit predictions for scored evaluation.

If you have feedback about this post, submit comments in the Comments section below.

Anshumali-Shrivastava

Anshumali Shrivastava

Anshumali is an Amazon Scholar and Full Professor of Computer Science at Rice University. His research on dynamic sparsity, sketching, and hashing pioneered techniques now central to efficient LLM training and inference. A two-time founder — ThirdAI (acquired by ServiceNow) and XMAD.ai (acquired by Workato) — he bridges theoretical computer science and practical AI systems at scale.

Neha Rungta

Neha Rungta

Neha is a scientist and builder who has spent her career making machines reason about complex systems at scale. Her work spans automated reasoning, formal verification, security, and AI, shaping systems including Cedar, IAM Access Analyzer, and Continuum. Today, she is forging the next generation of machine reasoning, combining LLMs, formal methods, and agentic systems.

Received — 19 May 2026 ⏭ AWS Security Blog

Enabling AI sovereignty on AWS

12 May 2026 at 17:18

Cloud and AI are transforming industries and societies at unprecedented speed, from accelerating research and enhancing customer experiences to optimizing business processes and enriching public services. At Amazon Web Services (AWS), we believe that for the cloud and AI to reach their full potential, customers need control over their data and choices for how and where they run their workloads. In 2022, we formalized our commitment to control and choice—offering all AWS customers the most advanced set of sovereignty controls and features available in the cloud with the AWS Digital Sovereignty Pledge. As AI adoption accelerated, we’ve been working with customers to help them embrace AI innovation while meeting sovereignty requirements. We’re committed to ensuring customers can continue to harness AI’s transformative capabilities without compromising on the capabilities, performance, innovation, security, and scale of the AWS Cloud to meet their sovereignty needs, including AI sovereignty. Our approach to AI sovereignty is grounded in a deep understanding of these needs and the real-world implementation challenges that come with them.

Through discussions with customers, partners, analysts, and regulators, we’ve learned that digital sovereignty—and AI sovereignty—means different things to different stakeholders. Each country and region has unique, evolving sovereignty requirements, with no uniform guidance on which workloads or sectors must comply. Despite this variation, we’ve identified consistent themes: data sovereignty (including data residency and operator access restrictions) and operational sovereignty (including resilience, survivability, and independence). AI sovereignty builds on these foundations, adding emerging considerations such as preserving cultural norms, values, and local languages in AI outputs. Ultimately, meeting digital and AI sovereignty requirements comes down to providing customers with more control and choice.

Enabling customer control and choice across the AI stack

AI sovereignty requires control and choice across the AI stack—comprehensive cloud infrastructure that combines compute, networking, data management, security controls, specialized application services, and talent. This includes the ability to make deliberate choices across the stack such as location, dependencies, services, and partners that align with customers’ unique needs, regulatory requirements, and innovation objectives. With AWS, customers can develop AI on a trusted foundation where their data remains secure and under their control. Customers have the freedom to choose from a comprehensive range of AI optimized chips—including purpose-built AWS silicon and chips from NVIDIA, AMD, and Intel—so they can select the right chip for the right workload. AWS applies two decades of learned expertise to our comprehensive AI stack, enabling organizations to maintain complete control over their data and operations while accessing cutting-edge capabilities to solve local challenges.

AWS provides customers with the infrastructure and tools to embed AI across the full value chain—not just in isolated use cases, but as a foundational capability enabling them to train and deploy models and build sophisticated AI and generative AI applications with exceptional performance. This enables customers to focus on innovation instead of their infrastructure, bringing the cloud to where they need it most with a range of options including AWS AI Factories, AWS Outposts, AWS Local Zones, AWS Dedicated Local Zones, and AWS Regions including the AWS European Sovereign Cloud. For example, customers who require dedicated deployments to meet their sovereignty requirements for their mission-critical AI workloads can use AWS AI Factories. These physically isolated, dedicated deployments built exclusively for the customer combine the latest AI infrastructure, including AWS Trainium accelerators, NVIDIA GPUs, dedicated networking, and storage. AWS AI Factories address AI sovereignty needs by delivering on-premises AI capabilities to securely perform training, fine tuning and real-time inference.

The AWS AI portfolio offers a comprehensive range of services—from foundation models (FMs) through Amazon Bedrock, to machine learning offerings like Amazon SageMaker, application services like Amazon Q, and developer tools like Kiro—designed to give customers control over their data and choice in how they deploy AI. With Amazon Bedrock, customers can choose from hundreds of models from leading providers like AI21 Labs, Anthropic, Amazon, Cohere, Mistral AI, and OpenAI. Customers can evaluate and select the most suitable FMs for their specific needs and choose where they deploy them, and fine-tune models privately with their own data. Customers are always in control of their data. Critically, no customer inputs to or outputs from Amazon Bedrock are used to train Amazon Nova or any third-party models.

Supporting national AI strategies

Successful AI strategies require building a holistic environment nurturing local talent, supporting startups, developing industry-specific applications, and fostering public-private partnerships. The cloud has transformed AI from an exclusive technology requiring massive investment into an accessible tool for innovation across all sectors and organization sizes. While technical infrastructure gets much of the attention when considering AI sovereignty, the cultural and strategic dimensions of national FMs are equally critical. These FMs aren’t merely computational tools, they can encode elements of cultural knowledge, linguistic nuance, and societal context, making local relevance a design consideration rather than an afterthought. These FMs serve purposes that extend beyond technical capabilities. Locally trained FMs can reflect national educational curricula and cultural values while understanding local legal systems, business practices, and regulatory frameworks. Models trained on local languages, dialects, and cultural contexts support linguistic diversity and help underrepresented languages gain representation in AI products and services.

AWS supports vital national priorities and customers’ missions, such as the preservation of culture norms, values, and local languages development of regional and local language model capabilities. To customize models, customers can use Amazon SageMaker AI for voice, domain specialization, and to evaluate models for accuracy. For example, the first Greek LLM made available in March 2024 was Meltemi—built on top of Mistral-7B, running on AWS infrastructure, and continually pretrained to extend its proficiency in the Greek language using a dataset of 28.5 billion Greek tokens. Meltemi is available on HuggingFace. SEA-LION—a family of open source, multilingual LLMs for Southeast Asia—was trained entirely on AWS with managed GPU clusters. Their team completed a 3B-parameter model in only 3 months—a 60% faster timeline than comparable on-premises projects.

Verifiable control over data access

Sovereignty isn’t only about where data resides—it’s about who can access it and under what conditions. In the AI context, access restriction extends beyond infrastructure to cover model inputs, outputs, training processes, and the operational environments in which AI runs. Unlike traditional infrastructure, AI workloads introduce new access surfaces: the model itself, the data used to train it, and the inference pipeline through which sensitive inputs flow. This furthers the need for verifiable governance and identity propagation in IT systems.

To help ensure the confidentiality and integrity of customer data, all modern Amazon Elastic Compute Cloud (Amazon EC2) instances including those that offer AI accelerators, such as AWS Inferentia and AWS Trainium, are backed by the industry-leading security capabilities of the AWS Nitro System. By design, there is no mechanism for anyone at AWS to access customer data on Nitro EC2 instances that customers use to run their workloads. AWS services—including those with AI capabilities built on Amazon EC2—inherit these same protections. These protections apply to AI data running in the AWS Nitro System so that they’re protected at every stage—from model training to inference. The NCC Group, an independent cybersecurity firm, has validated the design of the Nitro System. We believe providing this level of transparency is critical in building and sustaining trust.

As AI agents increasingly take actions across systems on behalf of users, controlling who and what can access resources—and ensuring appropriate human oversight—becomes critical. AWS Identity and Access Management (IAM) helps ensure that only authorized users and applications can access AI resources through fine-grained permissions and comprehensive audit trails. For AI agents and automated workloads, Amazon Bedrock AgentCore Identity provides identity and credential management, so agents operate with the right permissions and nothing more.

Transparency and assurance

Transparency is at the core of our digital sovereignty commitment. We provide comprehensive industry-leading technical measures, operational controls, and contract protections that give customers control over where they locate their data, who can access it, and how it’s used. To give greater assurance on how AWS services are designed and operated, we continue to seek out and secure third-party attestations, accreditations, and certifications that help our customers meet their compliance needs.

We continue to deepen our assurances and transparency to customers—such as updating our AWS Service Terms to reflect our technical protections commitments (e.g. AWS Nitro System), providing detailed commitments as to our handling of third-party requests for customer data in our agreements, and providing supplemental explanations and resources (e.g. CLOUD Act blog) to empower customers to make informed choices on sovereignty matters. These efforts extend into our commitment to responsible AI, providing customers the confidence to build and operate AI applications responsibly using AWS Services. ISO/IEC 42001 is an international management system standard that outlines requirements and controls for organizations to promote the responsible development and use of AI systems. AWS is the first major cloud service provider to achieve ISO/IEC 42001 accredited certification for AI services, covering Amazon Bedrock, Amazon Q Business, Amazon Textract, and Amazon Transcribe. In November 2025, AWS successfully completed its first surveillance audit for ISO 42001:2023 with no findings, reiterating the continual commitment of AWS to responsible AI practices.

Innovative technology requires a secure and trustworthy foundation. AWS supports more than 140 security standards and compliance certifications that our customers and partners can inherit to help comply with local laws and regulations. For two decades, we’ve deeply engaged with regulators and cybersecurity authorities to align our offerings with national priorities and ensure our solutions support both innovation and control. We actively contribute to frameworks that respond to new developments without stifling progress.

Sustained commitment to helping customers achieve their sovereignty goals

AWS is committed to giving customers the same control and choice over their AI systems as they have over their data. We help customers harness AI’s transformative power while maintaining the capabilities, performance, innovation, security, and scale of AWS Cloud. As cloud and AI evolve, AWS will continue offering the most advanced sovereignty controls and features available.

If you have feedback about this post, submit comments in the Comments section below.
Stephane Israel

Stéphane Israël

Stéphane is the leader and Managing Director of the AWS European Sovereign Cloud. He is responsible for the management and operations of the AWS European Sovereign Cloud, including infrastructure, technology, and services, in addition to broader digital sovereignty efforts at AWS. Prior to AWS, he was the CEO of Arianespace, where he oversaw numerous successful space missions, including the launch of the James Webb Space Telescope.

Received — 23 April 2026 ⏭ AWS Security Blog

Building AI defenses at scale: Before the threats emerge

7 April 2026 at 20:02

At AWS, we’ve spent decades developing processes and tools that enable us to defend millions of customers simultaneously, wherever they operate around the world. AI has been an extremely helpful addition to the automation our security and threat intelligence teams do every day, and we’re still early in this journey. Our AI-powered log analysis system has reduced the time SecOps engineers spend analyzing security logs from an average of six hours to just seven minutes, a 50x productivity increase that lets us detect and respond to threats faster than ever. Across AWS, we analyze over 400 trillion network flows per day to detect patterns that signal emerging threats. In 2025 alone, we blocked over 300 million attempts to maliciously encrypt customer files hosted on Amazon S3. At this scale, every improvement in our operations helps protect all customers. AI is already helping us make our defenses stronger for everyone, and I’m excited to see that improvement continue.

A new class of AI for cybersecurity

Today, Anthropic announced Project Glasswing, a cybersecurity initiative designed to secure the world’s most critical software and advance the cybersecurity practices the industry will need as AI grows more capable. Organizations that build or maintain critical digital infrastructure are getting early access to Claude Mythos Preview, a new class of AI model, to find and patch vulnerabilities in the systems the world depends on. Given our role in securing some of the world’s most essential infrastructure, AWS is playing an integral part in advancing this work.

As part of Project Glasswing, we’ve already applied Claude Mythos Preview to critical AWS codebases that undergo continuous AI-powered security reviews, and even in those well-tested environments, it’s helped us identify additional opportunities to strengthen our code. In our internal testing, Claude Mythos Preview has proven more productive than previous models at surfacing security findings, requiring less manual guidance from our engineers to deliver actionable results. We’ve also given early access to a select group of AWS customers, who are deploying Claude Mythos Preview in their own security workflows and helping shape how the model evolves.

As AI tools grow more powerful in their ability to identify security issues, so must our ability to use them defensively. To that end, we’ve been working closely with Anthropic to help ensure Claude Mythos Preview is ready for enterprise use. AWS is Anthropic’s primary cloud provider for mission-critical workloads, safety research, and foundation model development. More broadly, AWS provides the foundational infrastructure that the world’s leading AI companies rely on to build, train, and deploy their most advanced models. We’re bringing decades of security experience to this partnership, helping to ensure Claude Mythos Preview is ready for even more organizations to build upon and operate securely at scale.

Claude Mythos Preview signals an upcoming wave of models that can find vulnerabilities and build working exploits at a scale and speed we haven’t seen before. Anthropic and AWS are taking a deliberately cautious approach to release. Access begins with a small number of organizations, prioritizing internet-critical companies and open-source maintainers whose software and digital services impact hundreds of millions of users. The goal: find and fix vulnerabilities in the world’s most critical software. Claude Mythos Preview is available in gated research preview through Amazon Bedrock with enterprise-grade security controls, including customer-managed encryption, VPC isolation, and detailed logging, so your team can explore Claude Mythos Preview’s capabilities without exposing production assets to unnecessary risk.

AWS architects services with security at the core

Our work with Project Glasswing is grounded in a philosophy we’ve developed over two decades of securing mission-critical workloads: you can’t wait for threats to materialize before building your defenses. You have to look around corners, adopt new technologies, build protections first, deploy them in your own operations at scale, and refine them based on what you learn.

That’s exactly what we’ve done at AWS with AI and security. Our approach spans the full spectrum: proactive defense through threat hunting and vulnerability research, dynamic response to active campaigns, and third-party certifications that verify our security practices meet the highest industry standards. This operational experience has taught us where AI accelerates security work and where human judgment remains essential. And it’s reinforced that security innovation must be pragmatic: proven in production before we ask you to rely on it.

That’s also why we help define what secure AI looks like. We became the first major cloud provider to achieve ISO 42001 certification for AI services. We’re active participants in OWASP, the Coalition for Secure AI, and the Frontier Model Forum. And we co-founded the Open Cybersecurity Schema Framework (OCSF) to enable better threat intelligence sharing across the ecosystem. The AWS Nitro System provides mathematically proven isolation for workloads. Systems and services like KMS, Nitro, EKS, and Lambda are designed with zero-operator access architectures, meaning AWS personnel can’t access your data. These aren’t aspirational goals. They’re how we operate today, at scale, every day.

Amazon Bedrock is where these principles come to life for AI. Bedrock provides policy-enforced access controls, built-in evaluation tools to measure how effectively models identify and validate vulnerabilities, and the ability to run workloads inside your own virtual private cloud. AWS is also the first cloud provider to achieve FedRAMP High and Department of Defense Security Requirements Guide Impact Level 4 and 5 authorizations for generally available Claude foundation models. Amazon Bedrock is already where the most security-sensitive organizations trust Anthropic’s technology, and it makes perfect sense for Claude Mythos Preview.

How to get started today

The same principles that guide our work at AWS scale apply regardless of which AI tools you’re using: comprehensive observability, defense in depth, automation where it adds value, and human judgment where it’s essential. Here’s how to put them into practice.

Prepare for the next generation of AI security. Claude Mythos Preview signals an upcoming wave of AI models that will transform cybersecurity. Start strengthening your security posture now so your organization is ready as these capabilities become more broadly available. Claude Mythos Preview is available in gated preview through Amazon Bedrock, and access is limited to an initial allow-list of organizations. If your organization has been allow-listed, your AWS account team will reach out directly.

Run on-demand penetration testing with AWS Security Agent. Now generally available, AWS Security Agent delivers autonomous penetration testing that operates 24/7 at a fraction of the cost of manual penetration tests. It transforms penetration testing from a periodic bottleneck into an on-demand capability that scales with your development velocity across AWS, Azure, GCP, other cloud providers, and on-premises. AWS Security Agent represents a new class of frontier agents: autonomous systems that work independently to achieve goals, scale to tackle concurrent tasks, and run persistently without constant human oversight. It deploys specialized AI agents to discover, validate, and report security vulnerabilities through sophisticated multi-step scenarios. Unlike traditional scanners that generate findings without validation, AWS Security Agent identifies potential vulnerabilities, then attempts to exploit them with targeted payloads and attack chains to confirm they are legitimate security risks. Each finding includes CVSS risk scores, application-specific severity ratings, detailed reproduction steps, and remediation suggestions. The result: penetration testing that once took weeks now completes in hours, scales across your entire application portfolio, and helps you get started with remediation instead of leaving you with a report. New customers can explore AWS Security Agent with a 2-month free trial.

Build AI applications you can trust with Amazon Bedrock. For teams building with generative AI, the challenge isn’t just making AI work, it’s making AI work safely. Amazon Bedrock provides the security and safety controls you need to deploy AI responsibly. Its Automated Reasoning capability is the first and only AI safeguard to use formal logic to help prevent factual errors from hallucinations, providing verifiable explanations with 99% accuracy, a capability we’ve refined over more than a decade of applying formal methods across AWS storage, identity, and networking. Amazon Bedrock also provides customizable guardrails that block harmful content and enforce your content policies, along with comprehensive observability to track AI behavior and detect anomalies across your workloads.

The threat landscape isn’t waiting

The threat landscape isn’t waiting for us to catch up. Nation-state actors, ransomware operators, and supply chain attackers are already using AI to scale their operations. Our job is to stay ahead by building defenses first, deploying them at scale, and sharing what we learn so the entire community benefits.

That’s what we do every day at AWS. We build in security from the start, ensuring it works and scales before we ask customers to rely on it. We set standards rather than follow them. And we look around corners to address tomorrow’s challenges today.

As AI capabilities continue to evolve, this approach won’t change. We’ll keep building defenses first, refining them at scale, and working with partners like Anthropic to ensure the next generation of AI security tools meets the real-world needs of enterprises defending at this scale.

Learn More

If you have feedback about this post, submit comments in the Comments section below.

Amy Herzog

Amy Herzog is Vice President and Chief Information Security Officer (CISO) at Amazon Web Services (AWS) where she leads a global organization of cloud security professionals in a company in which security is the top priority. Prior to joining AWS, Amy served as CISO for Amazon’s Devices and Services, Media and Entertainment, and Advertising businesses, overseeing the security of consumer technology offerings such as Alexa+ and Ring, and playing a key role in the secure development of Project Kuiper, Amazon’s initiative to provide fast, reliable broadband to customers and communities around the world through low earth orbit satellites.

❌