 Login

WhatsApp says it disrupted new NSO spyware phishing attacks
WhatsApp has detected and stopped spear-phishing campaigns allegedly conducted by the NSO Group after investigating user reports of social engineering attacks. [...]

The company founded by Yossi Torati, Omer Gull, and Yuval Itzchakov has emerged from stealth mode.
The post A Security Raises $37 Million for Autonomous Offensive Security Platform appeared first on SecurityWeek.
Enabling security tooling is the starting point. Making it operational—where findings drive decisions, response times are measurable, and your security posture improves week over week—is where most organizations struggle.
This blog post provides a phased maturity roadmap for organizations that have already enabled AWS Security Hub and Amazon GuardDuty. These two services form the foundation of a cloud-centered security operations capability on AWS. Security Hub provides centralized security posture management and aggregates findings from multiple AWS security services, while GuardDuty provides intelligent threat detection by continuously monitoring for malicious activity and unauthorized behavior. For any production or enterprise AWS environment, having both services enabled across all accounts and AWS Regions is a baseline expectation; not because they’re optional add-ons, but because effective security operations require both the ability to detect threats and the ability to understand your overall security posture. If you haven’t yet enabled them, the Security Hub documentation and GuardDuty documentation provide setup guidance, including multi-account deployment with AWS Organizations.
Customers consistently tell us that while individual AWS security service documentation is thorough, what’s missing is a consolidated operational playbook—one resource that ties the services together into a working security operations practice with clear phases, progression criteria, and an operational cadence. That’s the gap this post fills. Rather than covering how each feature works (the documentation does that well), this post focuses on when and why to use each capability, and how to build the organizational habits that make them effective.
What follows is a six-phase roadmap for moving from these services are active to these services are driving our security operations. Each phase builds on the previous one, and each is designed to deliver tangible, measurable improvement.
Goal: Understand what’s working before changing anything.
Estimated timeline: 1–2 weeks
Move to Phase 1 when: You have a documented current-state assessment covering all the following items.
Before introducing new processes or automation, establish a clear picture of the current environment. This assessment informs every decision that follows.
Actions:
Deliverable: A one-page current state assessment that identifies what’s enabled, what’s flowing where, who’s looking at it, and what’s in the existing backlog.
Goal: Make the signal meaningful before asking anyone to act on it.
Estimated timeline: 2–3 weeks
Move to Phase 2 when: Remaining findings represent items requiring real decisions, compliance scores reflect actual posture, and you can articulate why every suppression rule and disabled control exists.
This is the single most important phase. If this step is skipped in favor of jumping straight to automation, the result is automated chaos. Alert fatigue is the primary reason security tooling is ignored, and addressing it first is what makes everything that follows sustainable.
GuardDuty tuning:
Security Hub tuning:
Deliverable: A tuned environment where remaining findings represent items that require real decisions. Compliance scores should now reflect your organization’s actual security posture rather than noise.
Goal: Get the right findings to the right people at the right time.
Estimated timeline: 2–3 weeks
Move to Phase 3 when: CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked tickets, and notifications include enriched context. No action is taken until a person or an automation is informed that something needs attention.
Architecture: Security Hub to EventBridge rule to routing logic to destination
Tiered notification strategy:
| CRITICAL | Page on-call immediately | PagerDuty or Opsgenie | 15 minutes |
| HIGH | Alert security team channel | Slack or Teams channel and ticket creation | 4 hours |
| MEDIUM | Create ticket for review | Jira or ServiceNow | 48 hours |
| LOW or INFORMATIONAL | Batch digest | Weekly email summary or dashboard review | Next review cycle |
Key design decisions:
Deliverable: A working notification pipeline where CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked work items, and LOW and INFORMATIONAL findings are batched for periodic review.
Goal: For findings where the correct response is deterministic, remove the human from the loop.
Estimated timeline: 3–4 weeks
Move to Phase 4 when: At least 3–5 high-confidence finding types have automated responses deployed with audit trails, and the team has established a process for evaluating new auto-remediation candidates.
The guiding principle: Only auto-remediate when all three conditions are met: the finding is high-confidence, the response is deterministic, and the blast radius of the automated action is limited. Automated remediation must not create the risk of a production outage.
Decision framework:
| Confidence level | High – no false positive risk | Medium – context-dependent | Low – requires investigation |
| Response complexity | Single, well-defined action | Multiple steps or judgment calls | Requires forensic analysis |
| Blast radius | Limited to one resource | Could affect dependent services | Production-wide impact |
| Rollback difficulty | Straightforward to reverse | Moderate effort to reverse | Difficult or impossible to reverse |
Common auto-remediation categories:
For implementation, AWS provides Security Hub Automated Response and Remediation (SHARR), a solution that includes pre-built remediation playbooks deployed as AWS Step Functions workflows triggered by EventBridge. This is a strong starting point—evaluate the provided playbooks, enable the ones that fit, and extend with custom remediations as needed.
Note: For findings that recur because the environment lacks preventive guardrails, the best long-term response is often a service control policy (SCP) that prevents the misconfiguration from occurring in the first place. Phase 5 covers this preventive controls layer.
Deliverable: A library of automated and semi-automated remediation runbooks with full audit trails, and a documented decision framework the team uses to evaluate new auto-remediation candidates.
Goal: Turn security findings management into a sustained organizational practice, not a one-time cleanup.
Estimated timeline: 4–6 weeks to establish, then ongoing
Move to Phase 5 when: The weekly cadence has been running consistently for at least 8 weeks, monthly metrics show positive trends, and the first quarterly review has been completed.
This is where many organizations stall, and it’s the most important phase in the entire roadmap. The technology is working, the notifications are flowing, automated remediations are firing, but there’s no organizational habit built around it. Without this phase, everything you’ve built in Phases 0–3 will gradually decay. Suppression rules will go stale, new team members won’t know the system exists, and findings will start accumulating again. The operational rhythm is what converts a security tooling deployment into a security operations practice.
Attendees: Security team lead, cloud platform team representative, rotating engineering lead from an application team
Why the rotating engineering lead matters: Security findings don’t exist in a vacuum; they’re generated by workloads that engineering teams own. Rotating an engineering representative through this meeting accomplishes three things: it builds security awareness across the organization, ensures findings are routed to people with the context to resolve them, and creates organizational accountability beyond the security team.
Agenda template:
| 5 minutes | Compliance score trend – Review Security Hub scores by account and standard. Is the trend improving, declining, or flat? If declining, why? | Security lead | Identified regression areas |
| 5 minutes | Critical and high findings review – Walk through new HIGH and CRITICAL GuardDuty findings from the past week. Are there any that need immediate escalation? | Security lead | Escalation actions assigned |
| 10 minutes | Top five failing controls – Identify the five Security Hub controls with the most failures. Assign an owner and a target date for each. | Platform lead | Owners and dates documented |
| 5 minutes | Automation review – Did any auto-remediations fire this week? Did they work correctly? Were there any false triggers? | Security lead | Automation adjustments queued |
| 5 minutes | Tuning decisions – Are new suppression rules needed based on this week’s findings? Are any new finding types candidates for auto-remediation? | All | Tuning backlog updated |
Running the meeting effectively:
Define clear escalation paths before they’re needed:
| CRITICAL finding not acknowledged within the SLA | Auto-escalate to security team manager | 15 minutes after SLA breach |
| HIGH finding not resolved within the SLA | Escalate to finding owner’s manager | 4 hours after SLA breach |
| Compliance score drops more than 5 points in a week | Escalate to cloud platform team lead for investigation | Next business day |
| Auto-remediation failure | Page security on-call | Immediate |
| New finding type not covered by existing runbooks | Add to weekly review agenda for triage and runbook development | Next weekly review |
Compile these metrics monthly and review them with security and engineering leadership. The goal is to tell a story about whether the organization’s security posture is improving, stable, or degrading, and why.
| Mean time to acknowledge (MTTA) for CRITICAL findings | Are findings being seen promptly? | Decreasing month over month |
| Mean time to resolve (MTTR) for CRITICAL and HIGH findings | Are findings being acted on? | Decreasing month over month |
| Security Hub compliance score by standard, by account | What is the posture trend over time? | Increasing month over month |
| Number of active GuardDuty findings by severity | Is the backlog growing or shrinking? | Decreasing for HIGH and CRITICAL |
| Findings auto-remediated compared to manually resolved | Is automation delivering value? | Auto-remediation ratio increasing |
| Number of suppressed findings (with quarterly justification review) | Is noise being managed, or are problems being hidden? | Stable or decreasing |
| New findings introduced compared to resolved this month | Is the organization getting ahead or falling behind? | More finding resolved than introduced |
| SLA adherence rate by severity | Are response commitments being met? | More than 95% for CRITICAL, and more than 90% for HIGH |
Building the dashboard: Use Amazon CloudWatch dashboards for real-time operational visibility or Amazon QuickSight connected to Security Hub findings through Amazon Security Lake for historical trend analysis and executive reporting. The dashboard should be visible to—and regularly viewed by—everyone in the weekly review, not locked in a security team tool.
The quarterly review is a deeper inspection of the system itself; not just the findings, but the machinery processing them.
Quarterly review checklist:
Use this rubric to assess the maturity of your operational rhythm itself. Score each dimension 1–3 and use the total to track progress over time.
| Review cadence | One time reviews when someone remembers | Weekly review happens, but attendance is inconsistent | Weekly review is consistently attended with documented outcomes |
| Metrics tracking | No metrics captured | Metrics are collected monthly but not acted on | Metrics drive decisions and declining trends trigger specific actions |
| Finding ownership | Findings sit in queue with no owner | Findings are assigned to teams but SLAs aren’t tracked | Every finding has an owner, SLAs are tracked, and breaches are escalated |
| Automation management | Set-and-forget automations | Automation logs are reviewed periodically | Automation is reviewed weekly, and new candidates are evaluated continuously |
| Tuning lifecycle | Suppression rules created but never reviewed | Annual review of suppressions and disabled controls | Quarterly reviews with documented justification for every rule |
| Cross-team engagement | Security team works in isolation | Platform team participates | Engineering teams actively participate and own remediation |
Scoring (revisit quarterly):
Deliverable: A documented operational cadence with clear ownership (consider a RACI matrix), metrics dashboards, escalation procedures, and a continuous improvement loop. The cadence should survive team member turnover—if it depends on one person remembering to run it, it’s not yet operational.
Goal: Fill remaining gaps and build toward a comprehensive security operations capability. Estimated timeline: Ongoing. Prioritize based on organizational risk profile and compliance requirements.
In this post, I provided a six-phase roadmap for operationalizing Security Hub and GuardDuty and showed that it isn’t a single project, but a progression. Phase 0 and Phase 1 can typically be completed in 3–5 weeks and deliver immediate clarity. Phases 2 and 3 build the response infrastructure that turns findings into action over the following 5–7 weeks. Phase 4 is what makes everything sustainable and is where you should invest the most attention. And Phase 5 expands the aperture from Security Hub and GuardDuty into a comprehensive security operations capability.
If you walked away from this post and did one thing, run the Phase 0 assessment this week. That single deliverable tells you exactly where to focus next. Use the following self-assessment checklist to identify your current phase, then focus on the next one. A tuned environment with working notifications and a weekly review cadence is dramatically more effective than a fully featured but neglected deployment. Start where you are, reduce the noise, build the habits, and iterate. To learn more, explore the AWS Security Hub User Guide, the Amazon GuardDuty User Guide, and the AWS Security Incident Response Guide. If you’ve implemented a similar operational cadence, or have questions about any phase, share your experience in the comments.
| Phase 0 | We know how many active GuardDuty findings exist across all accounts | ☐ |
| We know our current Security Hub compliance score | ☐ | |
| We know whether GuardDuty is enabled in every account and region | ☐ | |
| We know who (if anyone) is reviewing findings today | ☐ | |
| Phase 1 | GuardDuty suppression rules exist for known-benign activity | ☐ |
| Irrelevant Security Hub controls have been disabled with documented justification | ☐ | |
| All active HIGH and CRITICAL findings have been triaged | ☐ | |
| Security Hub compliance scores reflect actual posture, not noise | ☐ | |
| Phase 2 | HIGH and CRITICAL findings generate real-time notifications to the security team | ☐ |
| MEDIUM findings automatically create tracked work items | ☐ | |
| Notifications include enriched context (account alias, resource ARN, and console link) | ☐ | |
| Phase 3 | At least three high-confidence finding types trigger automated remediation | ☐ |
| Auto-remediation actions have full audit trails | ☐ | |
| Remediation runbooks are documented and version-controlled | ☐ | |
| Phase 4 | A weekly security review meeting occurs with defined attendees and agenda | ☐ |
| MTTA and MTTR are tracked monthly for CRITICAL and HIGH findings | ☐ | |
| Suppression rules and disabled controls are reviewed quarterly | ☐ | |
| Security metrics trend positively over the past 3 months | ☐ | |
| Phase 5 | Amazon Inspector, Macie, or Security Lake are integrated | ☐ |
| Preventive controls (SCPs, permission boundaries) address recurring findings | ☐ | |
| Incident response playbooks exist and are tested through tabletop exercises | ☐ |
If you have feedback about this post, submit comments in the Comments section below.
Check Point Research has identified active exploitation of CVE-2026-50751, a critical authentication bypass vulnerability affecting Check Point Remote Access VPN and Mobile Access deployments configured to use the deprecated IKEv1 key exchange protocol. By exploiting a logic flaw in certificate validation, an attacker can establish a VPN session without possession of a valid password, effectively bypassing authentication requirements. Additional post-authentication activity is required to access internal resources or escalate privileges. To date, the observed exploitation has been limited to a few dozen targeted organizations globally. One case involved confirmed post-compromise activity associated with Qilin ransomware affiliate. Customers using IKEv1 key […]
The post Security Advisory – Action Required – Active Exploitation of Check Point VPN Authentication Bypass (CVE-2026-50751) appeared first on Check Point Blog.
Modern web applications require robust security controls to protect user data and application resources. Authentication and authorization are two fundamental pillars of application security that answer critical questions: Who are you? and What are you allowed to do? Implementing these controls correctly can be challenging for developers, especially when building data-intensive applications with frameworks like Streamlit (an open-source Python framework for building interactive web applications) or when requiring fine-grained access control. Key challenges include protecting access to application resources, implementing application identity with multi-factor authentication (MFA), and implementing usage-based controls.
In this post, you will learn how to build fine-grained access controls for a sample Streamlit application using Amazon Cognito for authentication and Amazon Verified Permissions with Cedar policies for authorization. This architecture provides enterprise-grade security with minimal development effort, so you can focus on your application’s core functionality. You will learn how to reduce development time for secure applications, implement enterprise-grade authentication, through proper access management, and scale security with growing user bases.
The reference architecture follows a layered security design with four key components; separating identity verification, authorization evaluation, application logic, and enforcement boundaries. By assigning clear responsibilities to each layer, the architecture limits blast radius and ensures that a failure in any single control does not compromise the overall system.
This separation of concerns enables authentication and authorization to function as complementary security controls, following defense-in-depth principles. Figure 1 illustrates the end-to-end authentication and authorization workflow, showing how a user’s sign-in request flows through Amazon Cognito for identity verification, then through Verified Permissions for Cedar policy-based access decisions, before the application enforces the result.
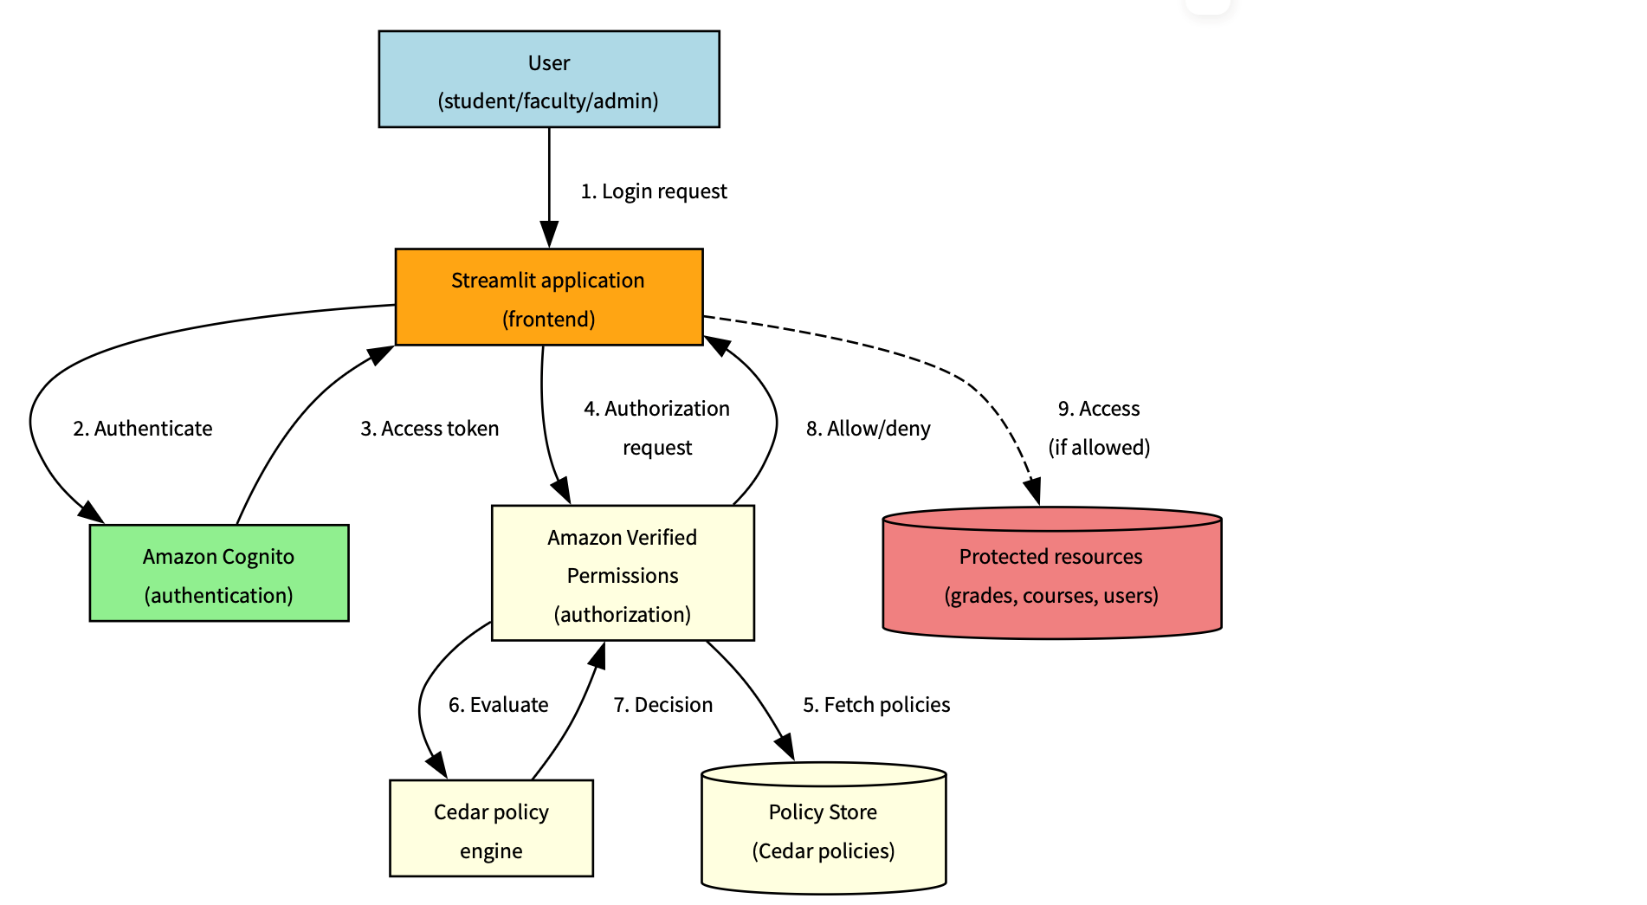
Figure 1: Solution architecture and workflow
The following workflow demonstrates how the three architecture layers work together: the authentication layer (steps 1–3) handles identity verification using Amazon Cognito, the authorization layer (steps 4–6) evaluates Cedar policies using Verified Permissions, and the application layer (steps 7–8) enforces the decision in Streamlit.
While authentication establishes user identity, authorization determines what actions users can perform. Verified Permissions provides a scalable authorization service based on Cedar, a policy language specifically designed for fine-grained access control.
Cedar policies follow a structured format that defines who can perform which actions on what resources. Let’s examine the anatomy of a Cedar policy:
permit(
    principal == ?principal,
    action == application::Action::"ViewGrade",
    resource == ?resource
) when {
    principal has role == "Student" &&
    resource.student == principal.entityId
};
Policy components
permitor forbid determines whether the policy allows or denies access?principal as a variablewhen clause contains logical expressions that must evaluate to trueThis section describes commonly used Cedar policy patterns for implementing fine-grained authorization with Amazon Verified Permissions. The examples illustrate how to model ownership, role-based access, hierarchical permissions, and administrative controls in real-world applications
This pattern helps ensure that users can only access resources they own:
permit(
    principal == ?principal,
    action == application::Action::"ViewGrade",
    resource == ?resource
) when {
    principal has role == "Student" &&
    resource.student == principal.entityId
};
What it does – This policy allows students to view only their own grades by:
Student roleentityIdThis pattern grants access based on role and resource type:
permit(
    principal == ?principal,
    action == application::Action::"EditCourse",
    resource == ?resource
) when {
    principal has role == "Faculty" &&
    resource has resourceType == "Course" &&
    resource.instructor == principal.entityId
};
What it does – This policy allows faculty members to edit courses they teach by:
Faculty roleCourseentityIdThis pattern allows department heads to manage faculty in their department:
permit(
    principal == ?principal,
    action == application::Action::"ManageFaculty",
    resource == ?resource
) when {
    principal has role == "DepartmentHead" &&
    resource has role == "Faculty" &&
    resource.department == principal.department
};
What it does – This policy implements departmental hierarchy controls by:
DepartmentHeadThis pattern provides emergency access with proper justification:
permit(
    principal == ?principal,
    action == ?action,
    resource == ?resource
) when {
    principal has role == "Administrator" &&
    context has emergencyAccess == true &&
    context has justification
};
What it does – This policy provides emergency access capabilities by:
trueUnderstanding how policies are evaluated helps design effective authorization systems. Figure 2 shows a common evaluation pattern for an academic scenario
Note: A policy match evaluates to the policy’s effect (permit or forbid). Forbid policies take precedence: if any forbid policy matches, access is denied regardless of permit policies.
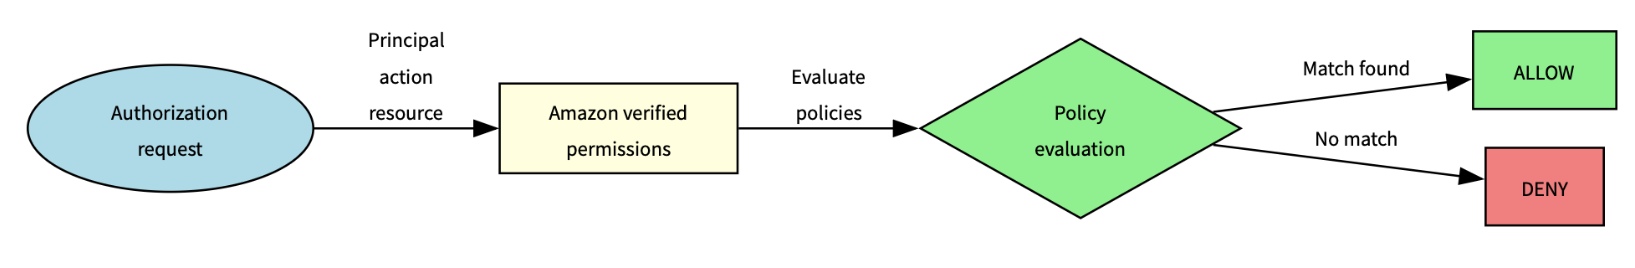
Figure 2: Policy evaluation process
The policy evaluation process follows these steps:
forbid policy matches, access is denied immediatelypermit policy matches and no forbid policies match, access is allowedALLOW or DENY) is returned to the applicationCedar is an Amazon open source policy language designed for fine-grained authorization. Every policy defines who (principal) can perform what action on which resource under what conditions, as shown in Figure 3.
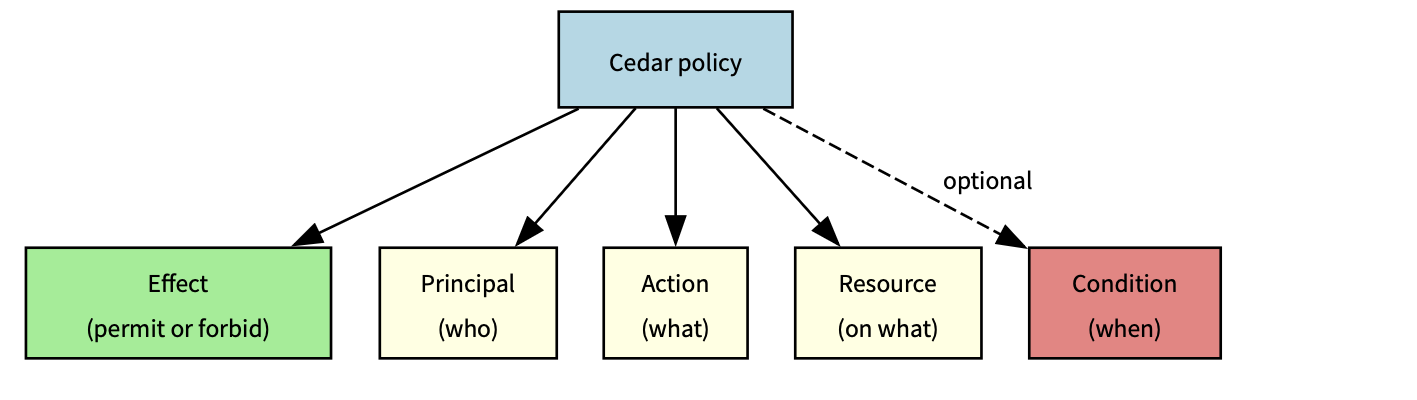
Figure 3: Cedar policy definitions
The following table shows how different policies interact in complex scenarios where multiple policies could apply:
| Scenario | Student policy | Faculty policy | Department head policy | Admin policy |
| Student accessing own grade | Permit | N/A | N/A | Override |
| Faculty editing course | N/A | Permit | N/A | Override |
| Department head managing faculty | N/A | N/A | Permit | Override |
| Emergency admin access | N/A | N/A | N/A | Permit |
Legend:
The preceding table shows how each role’s policy applies to different scenarios, with admin access having override capabilities across most situations except for emergency admin access where it’s the primary permit authority. The Override column specifically indicates that the administrator’s emergency access policy can supersede other role-specific policies, but only when the emergencyAccess context flag is explicitly set and a justification is provided. This is not an automatic override.
Policy optimization tips:
entityId, role, resource type) as primary conditions. Best practices for designing an authorization modelConsider an academic system with different user roles and their corresponding permissions:
Student: View own grades
Faculty: Edit course content, manage grades
Teaching assistant (TA): Grade management and course support
Department head: Manage faculty assignments
Administrator: System-wide access
To implement the preceding Academic system application, you need an active AWS account, Python 3.8 or later, basic Streamlit knowledge, and AWS Identity and Access Management (IAM) permissions for Amazon Cognito and Verified Permissions.
pip install boto3
aws login --region $REGION./verify-setup.sh./deploy-demo-environment.sh
Do you want to start the demo now? (Y/N): YThis provisions an Amazon Cognito user pool, a Verified Permissions policy store, and any sample resources needed for the demo.
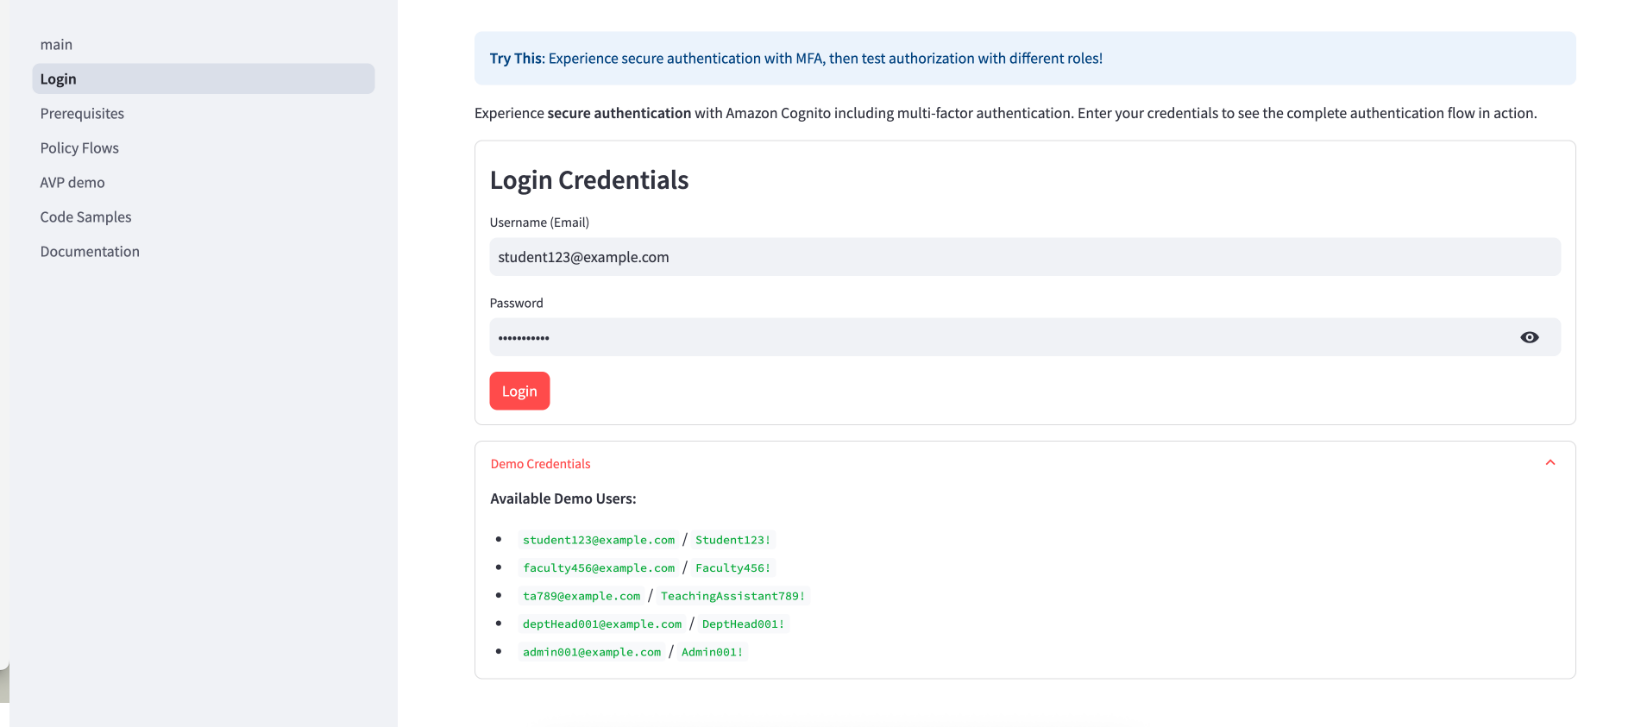
Figure 4: Verify login credentials
Ctrl+C to shut down and stop.When implementing this architecture, follow these best practices to support security:
Implementing proper authentication and authorization is critical for application security. By using Amazon Cognito and Amazon Verified Permissions, you can build robust security controls without complex custom code. Through this approach, you can implement enterprise-grade authentication with minimal effort, define and enforce fine-grained authorization policies, scale your security controls as your application grows, and centrally manage and audit security policies.
To get started with your implementation, create your AWS resources including an Amazon Cognito user pool and Verified Permissions policy store. Define your Cedar policies based on your application’s access requirements. Integrate authentication and authorization checks into your application flow. Test thoroughly with different user roles and access scenarios. Finally, monitor and refine your security controls based on usage patterns.
For additional resources, check out the Amazon Cognito documentation and Amazon Verified Permissions documentation.
If you have feedback about this post, submit comments in the Comments section below.
Public attitudes toward Artificial Intelligence (AI) are changing, and we wanted to understand why.
A recent Pew Research survey found that about half of adults say the increased use of AI in daily life makes them more concerned than excited, and that concern has grown over the last few years. People tend to worry most about long‑term social effects (jobs, creativity, relationships, misinformation), even while many do use AI tools and see some practical benefits, particularly for data analysis and routine tasks.
Data from an older UK survey already showed something similar. Awareness of highly visible AI technologies, such as driverless cars and facial recognition is high, but awareness of AI in welfare assessments, loan decisions, or care services is much lower. Concern about many of these use cases has risen since 2022. In other words, people feel AI is everywhere, but don’t always understand where or how it’s being used, and that makes people cautious.
The concern is usually less about science‑fiction extinction scenarios and more about social and economic harm. People worry about their jobs disappearing, a loss of creativity, the spread of disinformation, and increased surveillance, more than about killer robot scenarios.
Research into public attitudes towards AI repeatedly finds that people hold conflicting views, shaped by narratives of admiration and hype on one side and threat and dystopia on the other.
They see genuine benefits in the technology, but are increasingly wary of how companies, governments, and criminals might use it. Basically, people aren’t scared of AI itself, but about who’s using it and for what purpose.
AI in cybersecurity is a special case. When asked in which field of AI research they would invest an unlimited amount of money, people chose the fields of medicine and cybersecurity.
People increasingly recognize that AI is now a tool used by both defenders and cybercriminals. Few would feel comfortable with defenders refusing to use AI while attackers continue to adopt it.
Security products use machine learning to process huge volumes of data, detect unusual behavior, prioritize alerts, and identify threats faster than human analysts could alone.
At the same time, cybercriminals are using AI to create more convincing phishing emails, clone voices, generate fake images and videos, automate research on victims, and develop malware that can evade traditional detection techniques.
Both sides use AI-assisted tools to find software vulnerabilities that could be exploited to defraud people or breach systems, so vendors want to patch them before cybercriminals exploit them.
While studies consistently show that cybersecurity is one of the AI applications people worry about most, they also see that AI is increasingly necessary to keep pace with modern threats. A 2025 study focusing on AI in cybersecurity found that the public widely recognizes the technical benefits of AI‑driven defenses (speed, scale, accuracy), while remaining concerned about privacy, bias, and job displacement in security operations.
That is why the AI debate in cybersecurity feels different from the debate in many other fields. People may be uneasy about AI, but they also understand that the threat landscape no longer moves at human speed. Attackers already use automation, scale, and increasingly AI‑assisted workflows, so defensive teams that refuse to adapt would simply be slower and less effective.
Our mission at Malwarebytes is twofold: reduce the risks created by AI, and use AI to prevent, detect, and respond to threats. We’ve been using machine learning in our security products for nearly two decades, developing proprietary detection systems that help identify malicious code and suspicious behavior at a scale and speed that would be impossible manually.
Malwarebytes recently surveyed 1,500 adults across the US, UK, Austria, Germany, and Switzerland about their experiences with AI. The findings reveal a growing uncertainty about what people can trust online, alongside increasing concern about scams, impersonation, and AI-generated deception.
Stay tuned for the full Malwarebytes report on how AI is reshaping trust, identity, and scams.
If you use AI in a security context, keep your data hygiene strict. Don’t paste passwords, customer data, or sensitive incident details into public AI tools. Treat AI-generated outputs as untrusted until verified, especially when they touch code, logs, indicators, or policy decisions.
AI can be useful for summarizing information, indentifying patterns, and producing first drafts, but keep a human in the loop for anything that affects access, containment, legal decisions, or public communications. Where possible, prefer enterprise or local deployments with logging, access control, and clear data-retention rules.
Also remember that AI can hallucinate confidently. In security work, that means every output needs validation against logs, documentation, source code, or other primary evidence before you act on it.
Malwarebytes Scam Guard helps you analyze suspicious links, texts, and screenshots instantly.
Available with Malwarebytes Premium Security for all your devices, and in the Malwarebytes app for iOS and Android.
