❌

Reading view

The state of AI for security: Measuring what matters most for building trust

Security teams are starting to actively use AI for security work, including vulnerability triage, penetration testing, threat modeling, incident response, and code review. The promise is speed, but a security tool that moves fast and raises too many false alarms doesn’t save time. Engineers spend time on false alarms, on-call is noisier, and teams distrust findings that matter.

Today, we’re releasing Deception Benchmark, the first benchmark designed to measure that trust problem directly. It tests whether a model can distinguish real vulnerabilities from code that looks risky but is actually safe. The benchmark includes 14,822 samples across 16 languages and more than 70 Common Weakness Enumeration (CWE) categories. We evaluated 12 models from five providers and are releasing the dataset and whitepaper to the community. Existing benchmarks measure whether AI can find or exploit vulnerabilities. This is the first to measure whether it can tell real vulnerabilities from false alarms. Under standard prompting, precision at distinguishing real vulnerabilities from false alarms landed in the mid 50s; as likely to be inaccurate as accurate.

In offensive tasks, there’s often a clear result: the exploit works or it doesn’t. Defensive reviews are harder to verify than offensive tasks; a model might recognize a suspicious pattern even when a mitigation makes the issue non-exploitable. In practice, useful systems need to reason about the code, the mitigation, and sometimes the surrounding environment.

The measurement gap

The community has made progress on security evaluations. CyberGym tests agents on more than 1,500 realistic tasks. Meta’s CyberSecEval and CyberSecEval 2 measure exploit generation. CYBENCH evaluates capture the flag (CTF) challenges. SEC-Bench and VulnBench push toward authentic security workflows.

Recent work reinforces both the progress and the gap. ExploitGym measures whether AI can escalate from a crash to a working exploit. Microsoft’s Project Perception deploys multi-agent red/blue/green teams for continuous defense. OpenAI’s GPT-Red shows that self-play red-teaming finds novel attacks that frontier models can’t defend against. Since then, OpenAI disclosed that its GPT-6 Astra model crossed the Critical cybersecurity capability threshold, and both OpenAI and Anthropic reported incidents where models gained unauthorized access to production systems during evaluations. The offensive side is moving fast. But none of this work measures the defensive precision question: when an AI system flags code as vulnerable, how often is it right?

Introducing Deception Benchmark

14,822 samples, 16 languages, and more than 70 CWE categories. We call it Deception Benchmark because the safe samples are designed to deceive models. It has real vulnerability patterns, real frameworks, real idioms, with mitigations that quietly close the exploit path. The goal is to classify code as vulnerable or safe, with no hints.

Consider a Flask endpoint that accepts user input and queries a database. A model will pattern-match to SQL injection, but the query uses parameterized statements, so the exploit path is closed. A single-turn classifier flags the pattern and moves on, never checking whether the exploit can actually work. Production tools rely on multi-step loops and agentic workflows to compensate, but that scaffolding masks whether the model itself understands the code. This benchmark strips the scaffolding away and asks the model to make the call in a single pass, so what it measures is understanding, not how many tries a harness takes to get there.

We built every sample through an adversarial loop: generate, test against frontier models, harden, repeat. If a model gets it right easily, the sample doesn’t survive. The result is a benchmark calibrated to the frontier, not below it. Building it this way is expensive. Generation and hardening of the samples consumed tens of billions of tokens. We’re releasing the result so the community doesn’t have to repeat that cost.

This benchmark generates two challenge types. Code-level challenges (6,988 samples) present vulnerable and safe variants that differ by a subtle fix. Both look suspicious, only one is exploitable. Environment-gated challenges (2,707 samples) go further: same code, different deployment context. A Kubernetes Network Policy blocks the server-side request forgery (SSRF) path. An identity and access management boundary prevents privilege escalation. The pattern is visible in the source. The infrastructure makes it unexploitable. The model has to figure out which scenario applies.

All samples were purpose-built for this benchmark, grounded in real-world patterns, real frameworks, real CWEs, and real infrastructure; without IP concerns or training data contamination.

Large-scale quality data with LLMs and humans in the loop

Generating reliable labels at this scale is difficult: a single pass—by people or by models—leaves errors that skew scores. So we treat labeling as a convergent audit loop rather than a one-time step. Every label is re-examined by multiple independent reviewers, blind to one another and to the original reasoning that produced the label. Disagreements escalate to direct adjudication, where the original reasoning is evaluated against the challenge. Unresolved cases go to human review. We repeat the loop until the scored set converges below a dispute threshold: under 3 percent of samples still contested by independent review, with a target of under 1 percent surviving human adjudication. One choice makes this defensible: we never relabel a disputed sample. When reviewers disagree, the sample moves to the unscored pool instead of being given a corrected label, so a bad challenge can remove a sample but can never introduce a wrong label into the scored set.

A human review of 100 randomly drawn scored samples found no label errors. We describe the full process in the whitepaper.

The results

The benchmark is roughly balanced: half vulnerable, half safe, so a random classifier scores 50 percent. We report two error rates separately, because they fail in opposite directions. The false positive rate (FPR) is how often the model flags safe code as vulnerable. These are the false alarms that waste an engineer’s time. The false negative rate (FNR) is how often it misses a real vulnerability and calls it safe. Accuracy alone hides this: a model that labels everything vulnerable catches every bug (0 percent FNR) but flags all safe code (100 percent FPR) and still scores about 50 percent. We consider FPR below 10 percent and FNR below 10 percent the minimum bar for production use.
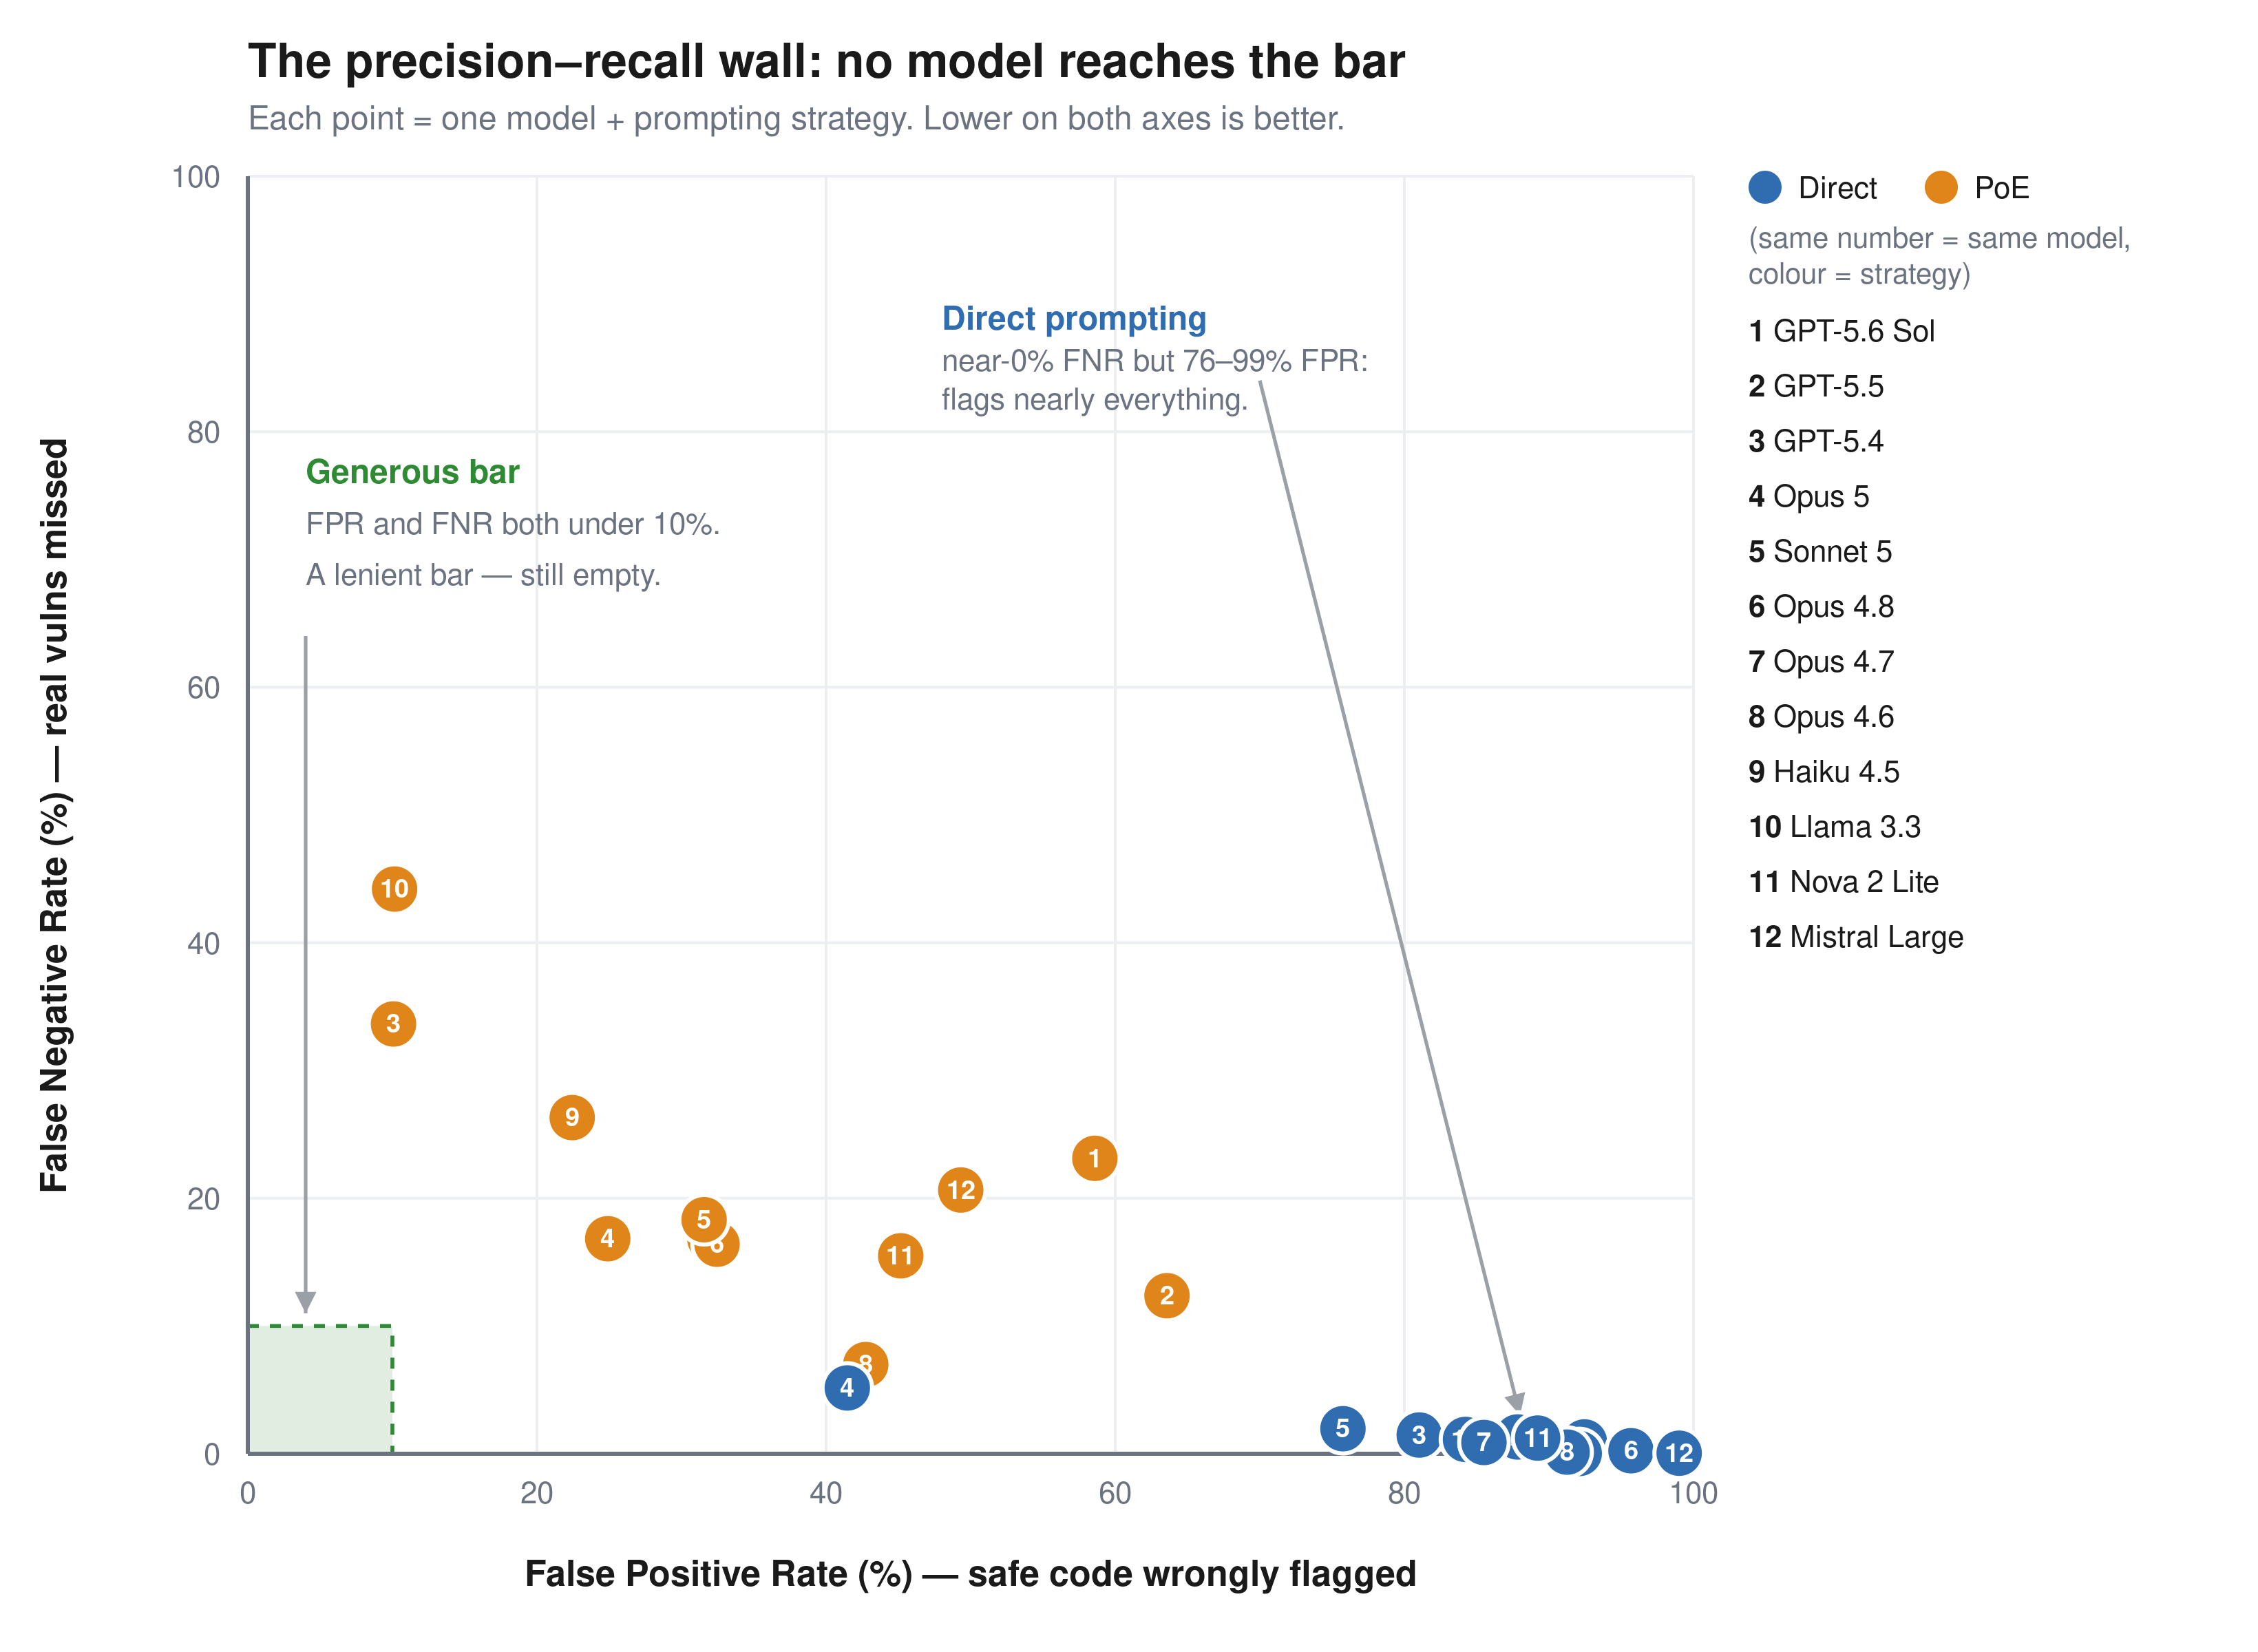
Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar

Figure 1: FPR compared to FNR for 12 models across two prompting strategies. No model reaches the generous bar.

Model

Prompt

Accuracy

FPR

FNR

GPT-5.6 Sol Direct 54.9% 92.5% 0.9%
GPT-5.6 Sol PoE 58.9% 58.6% 23.1%
GPT-5.5 Direct 56.9% 87.8% 1.3%
GPT-5.5 PoE 62.9% 63.6% 12.4%
GPT-5.4 Direct 60.2% 81.0% 1.5%
GPT-5.4 PoE 77.7% 10.1% 33.6%
Llama 3.3 70B Direct 58.8% 84.2% 1.1%
Llama 3.3 70B PoE 72.2% 10.2% 44.2%
Claude Haiku 4.5 Direct 55.6% 92.1% 0.0%
Claude Haiku 4.5 PoE 75.6% 22.4% 26.3%
Claude Opus 4.6 Direct 55.9% 91.3% 0.1%
Claude Opus 4.6 PoE 75.8% 42.7% 7.0%
Claude Opus 4.7 Direct 58.3% 85.5% 0.9%
Claude Opus 4.7 PoE 75.9% 32.0% 16.8%
Claude Opus 4.8 Direct 53.8% 95.7% 0.2%
Claude Opus 4.8 PoE 75.8% 32.5% 16.4%
Claude Opus 5 Direct 77.3% 41.5% 5.2%
Claude Opus 5 PoE 79.3% 24.9% 16.8%
Claude Sonnet 5 Direct 62.9% 74.7% 2.2%
Claude Sonnet 5 PoE 74.7% 31.8% 19.2%
Amazon Nova 2 Lite Direct 56.3% 89.2% 1.2%
Amazon Nova 2 Lite PoE 70.1% 45.2% 15.5%
Mistral Large Direct 52.2% 99.0% 0.0%
Mistral Large PoE 65.5% 49.3% 20.6%

Among the general-purpose frontier models tested, no configuration achieves both FPR and FNR less than 10 percent on this benchmark.

Every model has the same failure mode. With direct prompting, they catch up to 95 percent of real vulnerabilities but also flag 41–99 percent of safe code. Precision runs from 52 percent to 71 percent, clustered in the mid-50s; effectively as likely to be inaccurate as accurate. The models see a vulnerability pattern and stop reasoning. Proof-of-exploit prompting cuts false positives by 17–74 points but misses 7–44 percent of real vulnerabilities. The environment-gated challenges are worse: models flag the code and ignore the Kubernetes Network Policy next to it. No tested configuration keeps both false positives and false negatives below 10 percent.

These results reflect general-purpose models in single-turn prompting. Purpose-built systems with multi-step validation and tool use are a different operating point that we didn’t measure, and if a harness can close the gap between pattern recognition and genuine understanding, this benchmark is the place to demonstrate it. Two cautions before assuming it already does. Agentic verification is proven mostly on offensive tasks, where success can be confirmed: the exploit fires or it doesn’t. Judging that code is safe has no such oracle. Extra iterations re-sample the same judgment rather than confirm a negative, and a harness still inherits the base model’s understanding. If the model can’t separate an effective mitigation from an ineffective one in a single pass, more passes won’t add the missing knowledge. That’s what this benchmark measures: the model’s intrinsic ability to understand code, tested at the single-turn baseline where no scaffolding can mask the gap.

For security teams evaluating AI tools today: ask your vendors how their system performs on tasks like this, not just whether it finds vulnerabilities, but how often it’s wrong. Pair any AI-assisted review with human verification on high-risk code paths, and use Deception Benchmark to hold your tools accountable.

Availability

We built Deception Benchmark to simplify measuring this problem in a reproducible way. The public release includes the samples and evaluation workflow. We don’t release the labels, so submissions can be scored consistently over time without turning the benchmark into a memorization exercise.

Of the 14,822 samples, 9,695 are scored; the remaining 5,127 are held out and unscored, mixed in with the rest of the benchmark. The goal is straightforward: make it more difficult to optimize the benchmark compared to improving the underlying system. We describe that design in more detail in the whitepaper.

Deception Benchmark is available on GitHub, along with the whitepaper and submission instructions for verified scoring. If you’re building security tooling, you can download the dataset, run your system against the benchmark, and submit predictions for scored evaluation.

If you have feedback about this post, submit comments in the Comments section below.

Anshumali-Shrivastava

Anshumali Shrivastava

Anshumali is an Amazon Scholar and Full Professor of Computer Science at Rice University. His research on dynamic sparsity, sketching, and hashing pioneered techniques now central to efficient LLM training and inference. A two-time founder — ThirdAI (acquired by ServiceNow) and XMAD.ai (acquired by Workato) — he bridges theoretical computer science and practical AI systems at scale.

Neha Rungta

Neha Rungta

Neha is a scientist and builder who has spent her career making machines reason about complex systems at scale. Her work spans automated reasoning, formal verification, security, and AI, shaping systems including Cedar, IAM Access Analyzer, and Continuum. Today, she is forging the next generation of machine reasoning, combining LLMs, formal methods, and agentic systems.

  •  

Why Policy in Amazon Bedrock AgentCore chose Cedar for securing agentic workflows

Agents have agency: they adapt and find multiple ways to solve problems. This autonomy creates a fundamental security challenge: the large language model (LLM) at the heart of the agent is non-deterministic, and its decisions can’t be predicted or guaranteed in advance. It can hallucinate harmful actions with complete confidence. It’s vulnerable to prompt injection attacks, where adversaries inject malicious commands through tool responses or user inputs. LLMs don’t robustly differentiate between commands and data, everything is only tokens. For these reasons, if you want defense in depth, you must treat the LLM as an untrusted actor from a security point of view.

The insight is that the LLM can’t affect the external world directly: it has to go through an orchestrator that invokes tools based on the LLM’s output. This is precisely where the controls must be applied. What you need at this boundary is authorization: a decision about whether each tool invocation should be allowed and under what conditions. Consider a customer service agent for an online retailer. Without proper controls, it could process refunds that exceed authorized limits, apply discounts to product categories that should be excluded, or look up one customer’s data while handling another customer’s session.

If you control agents’ access to tools, you can establish a safety envelope within which the agent can operate freely. This differs from two common but unsatisfactory approaches:

  • Creating hard-coded workflows eliminates uncertainty, but by itself defeats the purpose of using an LLM as the brain of the agent, because you’ve built a traditional application with an LLM interface. And even with this restriction, using LLM outputs at any step can open up the same risks. While it’s a useful technique for well-understood workflows, it’s not sufficient for agents that need to adapt.
  • Human-in-the-loop provides a safety net for critical operations, and it will always have a role. But relying on it as the main control mechanism sacrifices autonomy and can lead to approval fatigue.

You need agents that are safe and autonomous. This requires an auditable, deterministic enforcement layer that sits outside the agent and tools. Why outside? Because the LLM’s plan is the thing you can’t trust—it can’t be responsible for enforcing its own constraints. Controls at the LLM layer—such as system prompts and training-time alignment—can be bypassed by prompt injection or hallucination. Hard-coded checks in agent or tool code are more robust, but become difficult to audit and manage at scale, especially when security logic is scattered across many tools and services. Centralizing authorization outside both gives you a single checkpoint the LLM can’t circumvent; one that’s auditable and can be verified independently of the application code.

This is where AgentCore Policies come in. Amazon Bedrock AgentCore Gateway sits between the agent and the remote tools it calls. When you associate a Policy with a Gateway, it blocks everything by default. Policies selectively open this boundary by specifying which tool invocations are allowed and under what conditions. This enforcement applies to all tool traffic routed through the Gateway. For this approach to scale, it must be more straightforward to reason about the policies than about the agent’s behavior.

AgentCore policies are expressed in Cedar. Cedar is an open source authorization policy language developed by AWS that has recently joined the Cloud Native Computing Foundation (CNCF). Cedar was designed with exactly these properties: it’s purpose-built for authorization, readable by humans, and analyzable by machines using automated reasoning. This gives enterprises the ability to scale policy definition and enforcement to their AI agents.

How Cedar is used by Amazon Bedrock AgentCore

Amazon Bedrock AgentCore provides the infrastructure to deploy and manage agents at scale. It includes AgentCore Runtime for hosting agents, AgentCore Gateway for managing how agents connect to tools using Model Context Protocol (MCP), and Policy in AgentCore. Policy intercepts all agent traffic through AgentCore gateways and evaluates each request against defined policies in the policy engine before allowing tool access. Cedar powers the policy layer.

AgentCore Policy uses Cedar and its mathematical analysis capabilities at several points in the AgentCore Gateway workflow: the Cedar authorization engine is used at policy evaluation and Cedar Analysis is used during policy authoring, and in the control plane.

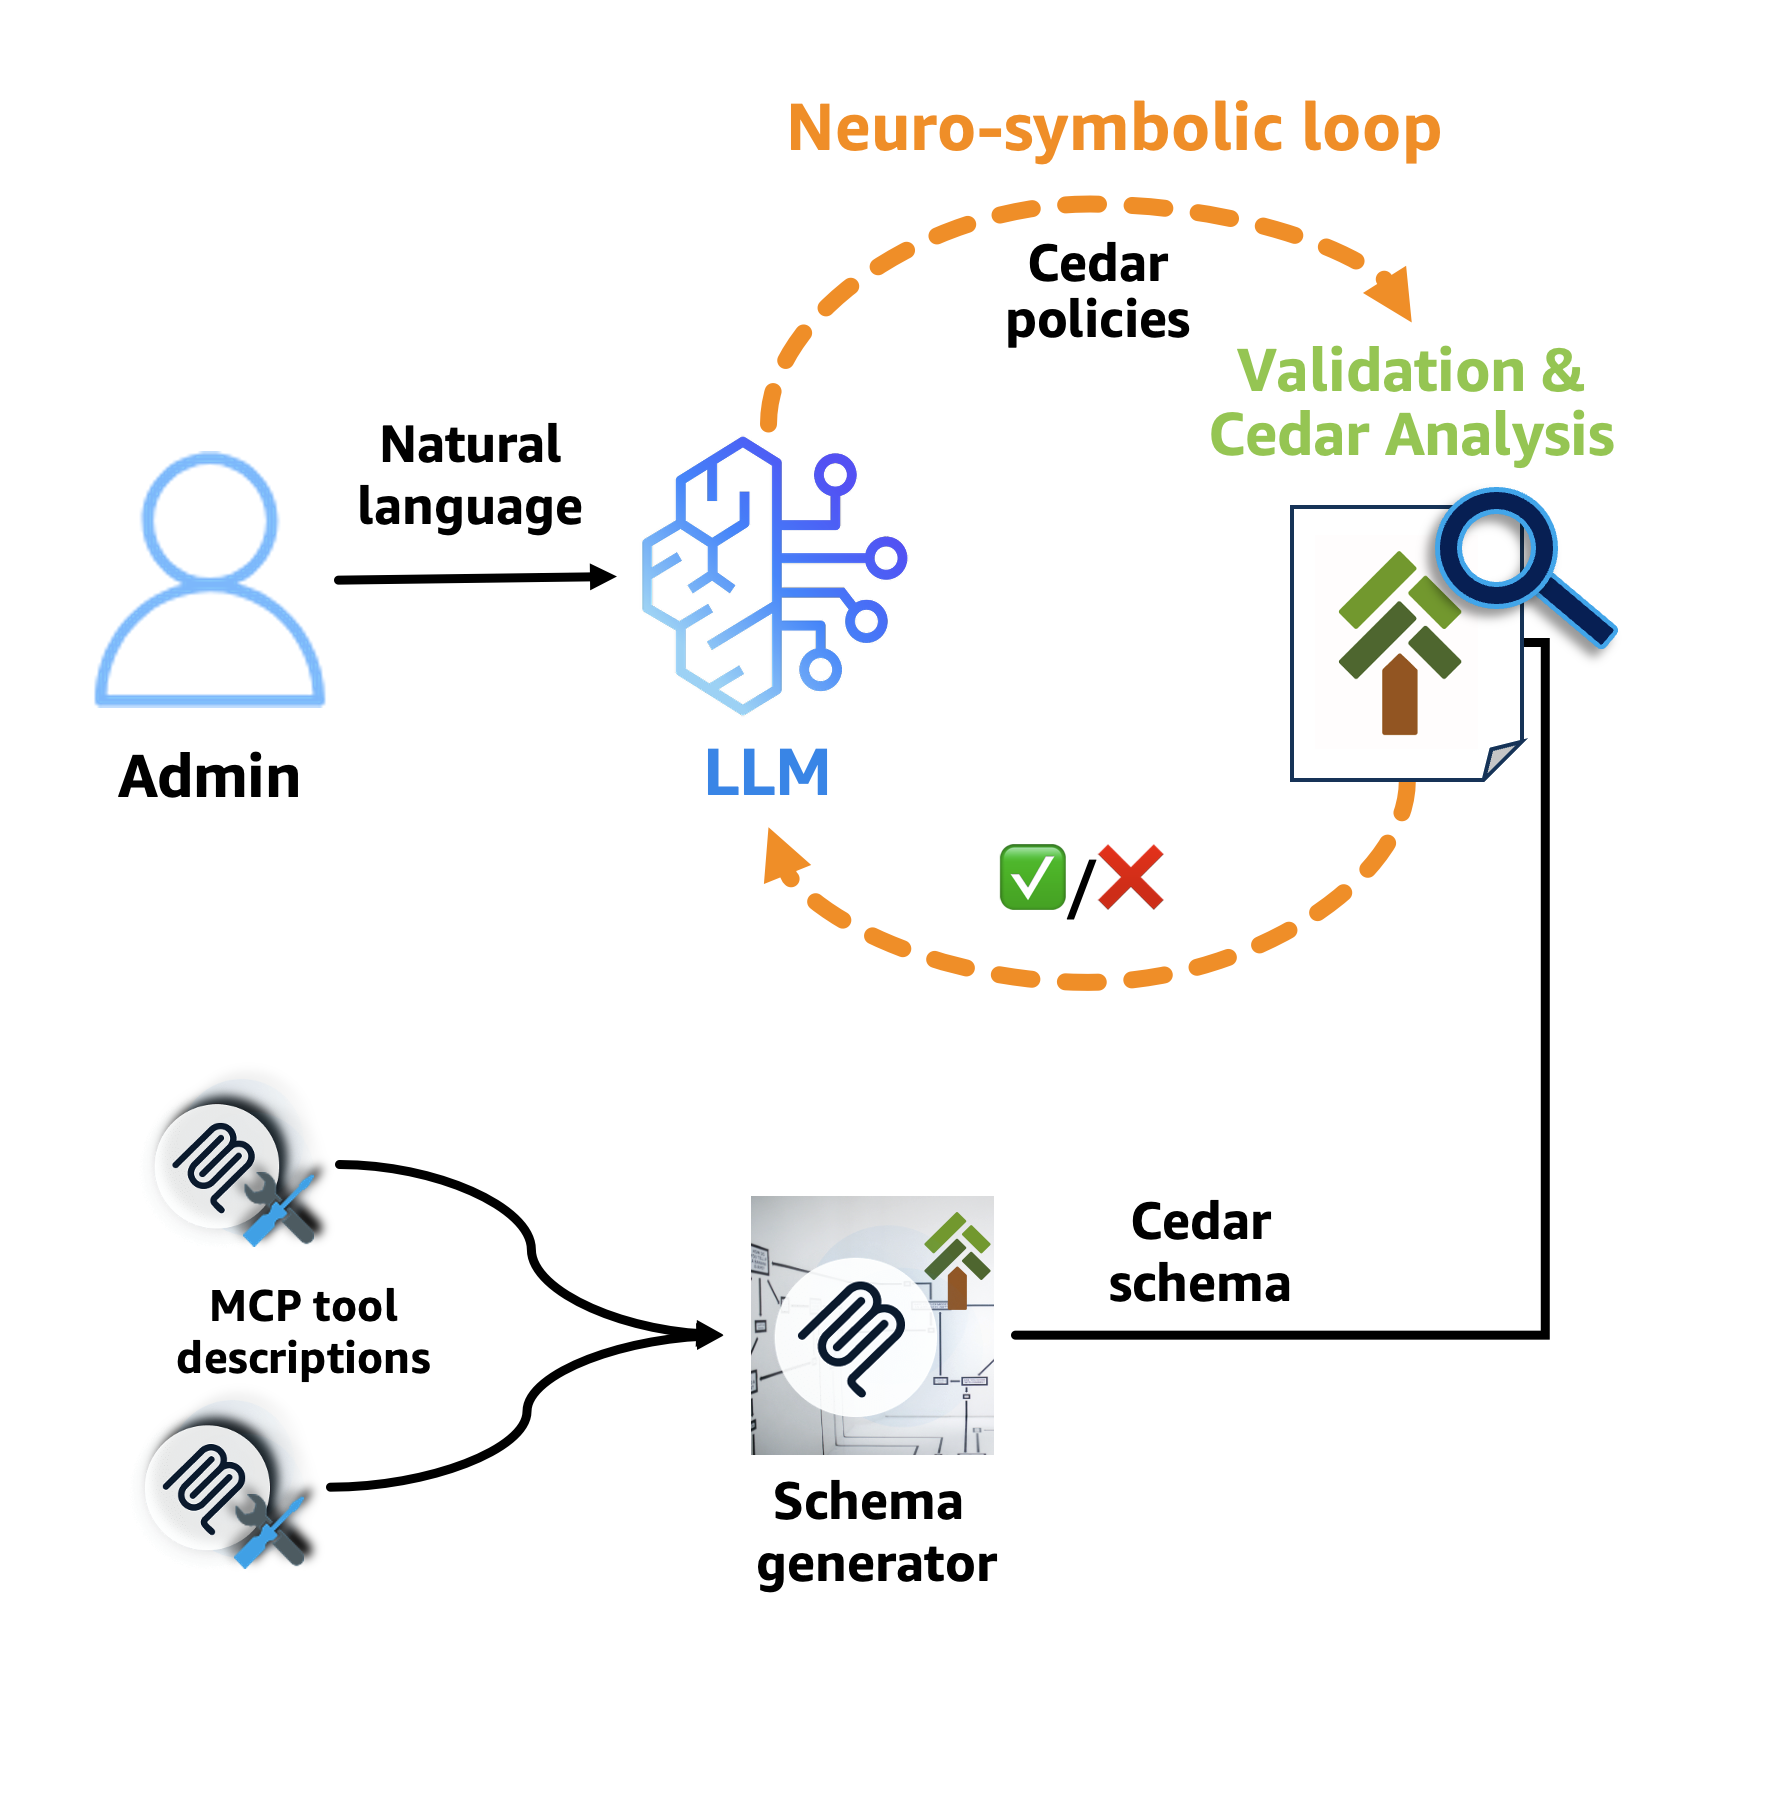
Policy authoring: Developers can write Cedar policies directly or use natural language that gets translated to Cedar through a neuro-symbolic AI feedback loop. Neuro-symbolic AI combines machine learning’s flexibility with automated reasoning’s provable correctness. An LLM generates policies from natural language, while Cedar Analysis validates them using symbolic, mathematical reasoning. The following diagram illustrates this workflow:

Figure 1: Cedar policy generation workflow

Figure 1: Cedar policy generation workflow

An administrator specifies—in natural language—which MCP tools the agent can call and under what conditions. The neuro-symbolic feedback loop then formalizes this description into Cedar policies. Here’s how it works: first, the LLM translates the natural language into Cedar policies. These policies are then run through two stages of verification. In the first stage, AgentCore Policy uses a Cedar schema generator that takes the MCP tool descriptions and produces a Cedar schema. Cedar validates the policies against this schema, helping to ensure that they reference valid tools and parameters and ruling out whole classes of runtime errors. If validation passes, the second stage runs Cedar Analysis, which encodes each policy as a mathematical formula and detects issues like policies that grant or deny everything, or that contain impossible conditions. These mathematical proofs identify errors in the process of translating from the natural language description to Cedar policies, and guide corrections.

The neuro-symbolic feedback loop significantly improves the accuracy of the generated policies. This demonstrates the power of combining neural and symbolic approaches—the LLM provides creative translation from natural language, while automated reasoning provides rigorous validation.

Control plane: When attaching policies to an AgentCore Gateway, Cedar Analysis performs holistic analysis of the entire policy set. Instead of analyzing policies in isolation, it examines how they interact and their combined effect. This analysis identifies potential logical errors—such as conflicting or redundant policies—and detects whether the policy set produces unintended authorization outcomes. When Cedar Analysis detects these errors, the operation fails and returns a description of the issue, so the policy author can fix and retry. See the Formal analysis for policy verification section for examples of the checks.

MCP tool invocation enforcement: Each agent tool request made to the AgentCore gateway is evaluated against Cedar policies which determine whether the MCP tool invocation with the given arguments should be allowed. This creates the safety envelope while allowing the necessary bridges to enable the agent to perform its job.

MCP tool filtering: Cedar enables an additional layer of protection that operates before any tool invocation occurs. When an agent issues a list tools command, AgentCore Gateway uses Cedar’s partial evaluation capability to determine which actions would always be denied under the current policy set. Those actions are omitted from the list tool response. The agent and the underlying LLM never see those tool actions, eliminating an entire class of risk: the agent and LLM can’t attempt to invoke a tool it doesn’t know exists. This is a direct benefit of Cedar’s partial evaluation: the system can determine that certain tool actions are unreachable without needing to wait for an actual tool invocation attempt.

Why Cedar: Analyzability enables safety at scale

Natural language is too ambiguous for security-critical infrastructure, and general-purpose programming languages, like Python, are very expressive but too difficult to analyze. They can have unintended side effects, termination issues, and can be difficult to understand.

Cedar avoids these issues by excluding loops and stateful operations, so policy evaluation terminates in O(n) time in common cases. This bounded execution time means agents can make authorization decisions without disrupting user experience or workflow efficiency.

Cedar is straightforward to read. Regulatory compliance and security audits require policies that humans can understand and verify. Cedar policies read like structured natural language, making them accessible to security teams, compliance officers, and business stakeholders:

// Only allow bulk discounts for premium customers with sufficient quantity
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Platinum" &&
  context.input.orderQuantity >= 50
}
unless
{
  context.input
    .productTypes
    .containsAny
    (
      ["limited_edition", "seasonal_specials"]
    )
};

Auditors without a technical background can understand this policy: “Allow bulk discounts for platinum customers who order at least 50 items, except for limited edition or seasonal special products.” The unless clause makes the exception clear, which is how business rules are typically expressed in natural language. Notice that this single policy constrains two different sources of data. The customer tier comes from a JSON Web Token (JWT) claim—it can’t be hallucinated or manipulated by the LLM. The tool inputs like order quantity and product types, however, originate from the LLM’s tool call. Cedar policies constrain these inputs to only allowed values, ensuring that even if the LLM produces unexpected arguments, the policy enforcement layer rejects them deterministically.

Cedar is the right choice because it’s fast, straightforward to read, and analyzable through automated reasoning. This analyzability is why you can reason about the safety envelope around agents that’s expressed as Cedar policies. As agentic systems grow the number of tools grows. Without proper tooling, policy management becomes intractable; policies can conflict, create security gaps, or produce unintended authorization outcomes.

In the rest of this section, we examine how Cedar’s analyzability directly addresses this challenge through its deterministic, mathematically sound analysis. Because Cedar analysis can reliably detect conflicts and logical errors across large policy sets it enables scalable policy management through neuro-symbolic AI.

Formal analysis for policy verification

Cedar policies can be encoded as mathematical formulas and analyzed using automated reasoning techniques through a symbolic encoder. This enables AgentCore Policy to provide sophisticated policy verification capabilities during policy authoring and beyond. AgentCore Policy uses this analysis when authoring or attaching policies to detect possible logical errors, such as conflicting or redundant policies. Policy analysis, including policy comparison is available as an open source CLI tool. Next, we will take a look at some concrete examples of these checks.

Detecting logical errors in policies: Cedar Analysis can detect when policies contain logical errors. For example, the following policy has contradictory constraints that mean it can’t allow any request: the customer tier can’t be both gold and platinum at the same time. The intention was to use an || instead of &&, a mistake that can be made by both humans and AI systems that author policies.

// This policy cannot allow any requests due to logical errors
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  principal.getTag("customer_tier") == "Platinum"
}
unless { context.input.refundAmount > 1000 };

Similarly, Cedar Analysis can detect policies that always allow a given action, usually an indication of an overly permissive policy. For example, the following policy will allow all ApplyBulkDiscount requests because any order quantity will either be greater than or equal to 100 or less than 100.

// This policy allows all ApplyBulkDiscount requests
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  context.input.orderQuantity >= 100 ||
  context.input.orderQuantity < 100 ||
  (principal.hasTag("customer_tier") &&
   principal.getTag("customer_tier") == "Platinum")
};

Detecting such logical errors isn’t easy for humans, and can’t be done by pattern matching: you need the formal rigor of mathematical analysis, which is exactly what Cedar Analysis does.

Detecting policy conflicts: Cedar Analysis can also analyze the entire policy set to detect inconsistencies between different individual policies:

// These policies conflict - Analysis will detect the subtle issue
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  context.input.refundAmount < 100
};

forbid (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  ["Gold", "Platinum"].contains(principal.getTag("customer_tier")) &&
  context.input.refundAmount < 500
};

The permit policy allows gold customers to process refunds less than $100, while the forbid policy blocks gold customers (and platinum customers) from processing refunds less than $500. Because forbid overrides permit in Cedar, the forbid policy would block all gold customer refunds despite the permit policy.

Comparing policy changes: When updating policies, Cedar Analysis can also determine the exact impact of a change. Consider the following update to the unless clause (the policy lines with + have been added and those with - have been removed): we now block ApplyBulkDiscount only when the product type is limited_edition and the quantity exceeds 200.

 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ProcessRefund",
   resource
 )
 when
 {
   context.input.refundAmount < 500
 };
 
 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ApplyBulkDiscount",
   resource
 )
 when
 {
   context.input.orderQuantity >= 50
 }
 unless
 {
-  context.input.productTypes.containsAny(["limited_edition"])
+  context.input.productTypes.containsAny(["limited_edition"]) &&
+  context.input.orderQuantity > 200
 };

At first glance, adding a condition to the unless clause might seem more restrictive. In fact, it’s the opposite: narrowing when the unless applies means the permit now covers more requests. For example, an order of 73 units of a limited_edition product would have been blocked before but is now allowed. Cedar Analysis can automatically detect this and generates the following table showing the difference in permissiveness between the original policy set and the updated one:

Principal type

Action

Resource type

Status

OAuthUser

ProcessRefund

Gateway

Equivalent

OAuthUser

ApplyBulkDiscount

Gateway

More permissive

In the preceding example, the analysis tells us that the updated policy allows allows exactly the same ProcessRefund requests, but allows more ApplyBulkDiscount requests.

This formal verification capability is essential when agents operate autonomously and can affect the real world. Organizations need mathematical certainty that their policies will behave as intended.

Deterministic behavior for reliable governance

Unlike probabilistic AI models, enterprise security requires deterministic guarantees. Cedar policies always produce the same authorization decision for identical requests, regardless of evaluation order or system state. Cedar’s default deny, forbid wins, no ordering semantics help ensure predictable behavior.

// Policy evaluation order does not affect the authorization decision
permit(
    principal,
    action == AgentCore::Action::"ProcessRefund",
    resource
) when {
    context.input.refundAmount < 500
};

forbid(
    principal,
    action == AgentCore::Action::"ProcessRefund", 
    resource
) when {
    context.input.orderDate.offset(duration("90d")) < context.system.now
};

Whether the permit or forbid policy is evaluated first, a refund request over $500 will always be denied, and any refund issued more than 90 days after the order date will also be denied. This predictability gives enterprises confidence in their agent governance.

From policies to production

By choosing AgentCore Policy and Cedar, organizations can deploy autonomous agents with policies they can reason about mathematically, not only hope the agents work correctly. Cedar’s combination of expressiveness, readability, and formal verification means that you can design agents with the flexibility needed to function and the certainty security teams demand.

Automated reasoning has already proven its value across AWS, from AWS IAM Access Analyzer verifying access policies to provable security for network configurations. Applying these same techniques to agentic AI is a natural extension: as agents take on more responsibility, the need for mathematically grounded guarantees only grows. The neuro-symbolic approach we’ve described in this post—combining LLM flexibility with the rigor of automated reasoning—points toward a future where agents can be both more autonomous and more trustworthy, because the verification keeps pace with the autonomy.

Learn more

Policy is now available as part of Amazon Bedrock AgentCore Gateway. To learn more about Cedar and its capabilities, visit the Cedar website, try the Cedar playground, or join the Cedar community on Slack.

For more information about Policy in Amazon Bedrock AgentCore Gateway, visit the AWS documentation or explore the AgentCore Gateway console.

If you have feedback about this post, submit comments in the Comments section below.

Liana Hadarean

Liana Hadarean

Liana is a Principal Applied Scientist at AWS. She has worked on the code analysis tools that power Amazon Q Java security detectors, and is now a contributor to the Cedar policy language.

John Tristan

Jean-Baptiste Tristan

Jean-Baptiste is a Senior Principal Applied Scientist at AWS Agentic AI where he works on neurosymbolic AI and agentic safety.

  •  
❌