❌

Reading view

Some cheap smart glasses are a security disaster

Apart from the privacy concerns around smart glasses, researchers have found that some cheap brands come with barely any security at all.

ABC Australia reports that researchers from NSB Cyber and Abstract Shield tested two inexpensive pairs, costing A$60 and A$110 (around US$42 and US$78), and found more than a dozen flaws across the smart glasses themselves, their app, and an associated website.

The main problem they uncovered was insecure Bluetooth pairing: If the glasses were powered on and not connected to their owner’s phone, an attacker could connect first, with no password or meaningful pairing confirmation.

After connecting, an attacker could reportedly control the glasses to capture photos or recordings, copy existing media, and intercept data moving between the glasses and the phone. An attacker could also make another device appear to be the victim’s glasses, allowing it to connect to the owner’s mobile app.

The testing also found that a Bluetooth-visible device identifier could allegedly be used with a weakness in the app’s website to retrieve a user’s email address and date of birth.

The research uncovered another privacy issue. ABC reports that voice or text submitted to the built-in AI, along with images sent to it, was first transmitted to a server in Shenzhen and could be forwarded elsewhere, depending on the function. The tests did not establish how the data was subsequently used.

The server locations, combined with some of the AI’s answers to specific questions, led researchers to conclude that the chatbot companion relied at least in part on Chinese sovereign AI models. Professor Kimberlee Weatherall, a technology regulation expert involved in the testing, said the failure to identify China in the privacy policy appeared to violate the Australian Privacy Principles,

The timing of the testing is also relevant because Australia’s smart-device security standards apply to most consumer smart devices manufactured on or after March 4, 2026. They require, among other measures, no universal default passwords, a way to report vulnerabilities, and information about the minimum security-update period. Devices made before that date are outside the requirements.

Experts quoted by ABC said the devices violated Australia’s privacy laws and were also likely to breach several sections of the Cyber Security Act. However, whether the new smart-device standards apply would depend partly on when the glasses were manufactured, and the rules have not yet been tested in a known enforcement action.

Professor Weatherall said:

“The rules say that the password must be unique. It doesn’t even seem like they were applying a password, which might mean that their standards are so low they don’t even technically breach that rule, which I find amazing.”

What to do

We’re not fans of smart glasses, expensive or cheap. But if you own a pair:

  • Avoid pairing or using inexpensive camera glasses that lack a clear physical pairing step, account authentication, a published security-contact process, and a stated update-support period.
  • Stop using their AI or cloud features for sensitive material, remove unnecessary permissions from the companion app, check for firmware and app updates, and consider returning the product if the vendor cannot document a fix.
  • Ask permission before recording people, and check your local laws to understand what is and isn’t allowed.

From reporting threats to removing them.

Cybersecurity risks should never spread beyond a headline. Keep threats off your devices by downloading Malwarebytes today.

  •  

The Odyssey and Trojans again: MovieReaper attacks users in multiple countries through compromised torrents

Introduction

Torrent trackers have long been abused for distributing malicious software, disguised as popular films, games, and other content. Our previous research has shown that cybercriminals repeatedly turn to torrents as an initial infection vector, using trojanized cracks and installers to reach a large number of users. Installation guides for pirated software routinely instruct users to disable their antivirus, conditioning them to ignore the potential threats they are inviting onto their computers.

During our analysis of malware that leverages blockchain networks for its C2 infrastructure, we discovered a previously unknown modular, multi-stage framework that we dubbed MovieReaper. This report details the new crimeware campaign that began with the mass infection of users via compromised torrent tracker file storage. We have identified several hundred victims, including both individual users and organizations in multiple countries, such as Russia, Türkiye, Japan, Kenya, Uganda, and Colombia, as well as in several European countries like Spain, the Netherlands, Belgium, and Germany. We analyze the techniques for evading detection by security and sandbox solutions, and examine the capabilities of the modular framework.

Kaspersky products detect this threat as HEUR:Trojan.Win64.Agent.gen.

Technical details

Background

In mid‑August 2026, during our threat‑hunting efforts, we identified a large‑scale infection campaign involving previously unknown malware disguised as popular movies. The campaign affected both individuals and organizations across multiple countries. Our initial analysis revealed a common denominator: all of the victims had used torrent trackers. This finding prompted us to investigate the campaign further and analyze its distribution mechanism, overall scope, and unknown malware implants.

Initial infection and spread

Compromised torrent trackers are the primary vector used to distribute malware. During our investigation, we identified multiple user reports describing suspicious files being downloaded instead of the intended content.

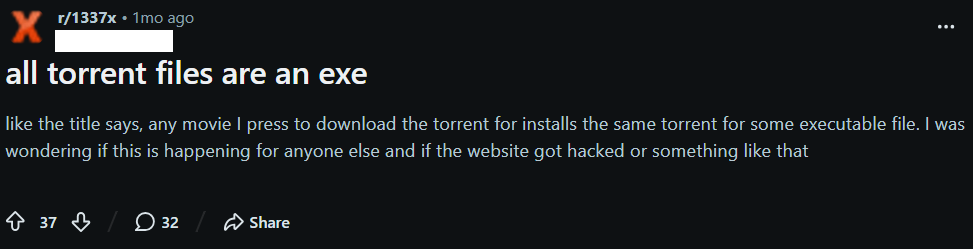
For example, a user of a popular movie torrent tracker reported the following case on Reddit:

Further analysis of the attack revealed that instead of compromising torrent trackers, the threat actor modified a widely used public repository of torrent files, itorrents[.]org. As a result, the trackers that relied on the repository began inadvertently distributing malicious torrent files to their users. This approach is particularly dangerous because it lets the threat actor reach users of multiple trackers without having to compromise each platform individually.

As of the publication date of this report, the archive remains compromised. When a user attempts to download a torrent via a magnet link, the legitimate torrent archive returns a different torrent file. This malicious torrent leads to the download of the malware loader, used to deploy a framework that we dubbed MovieReaper.

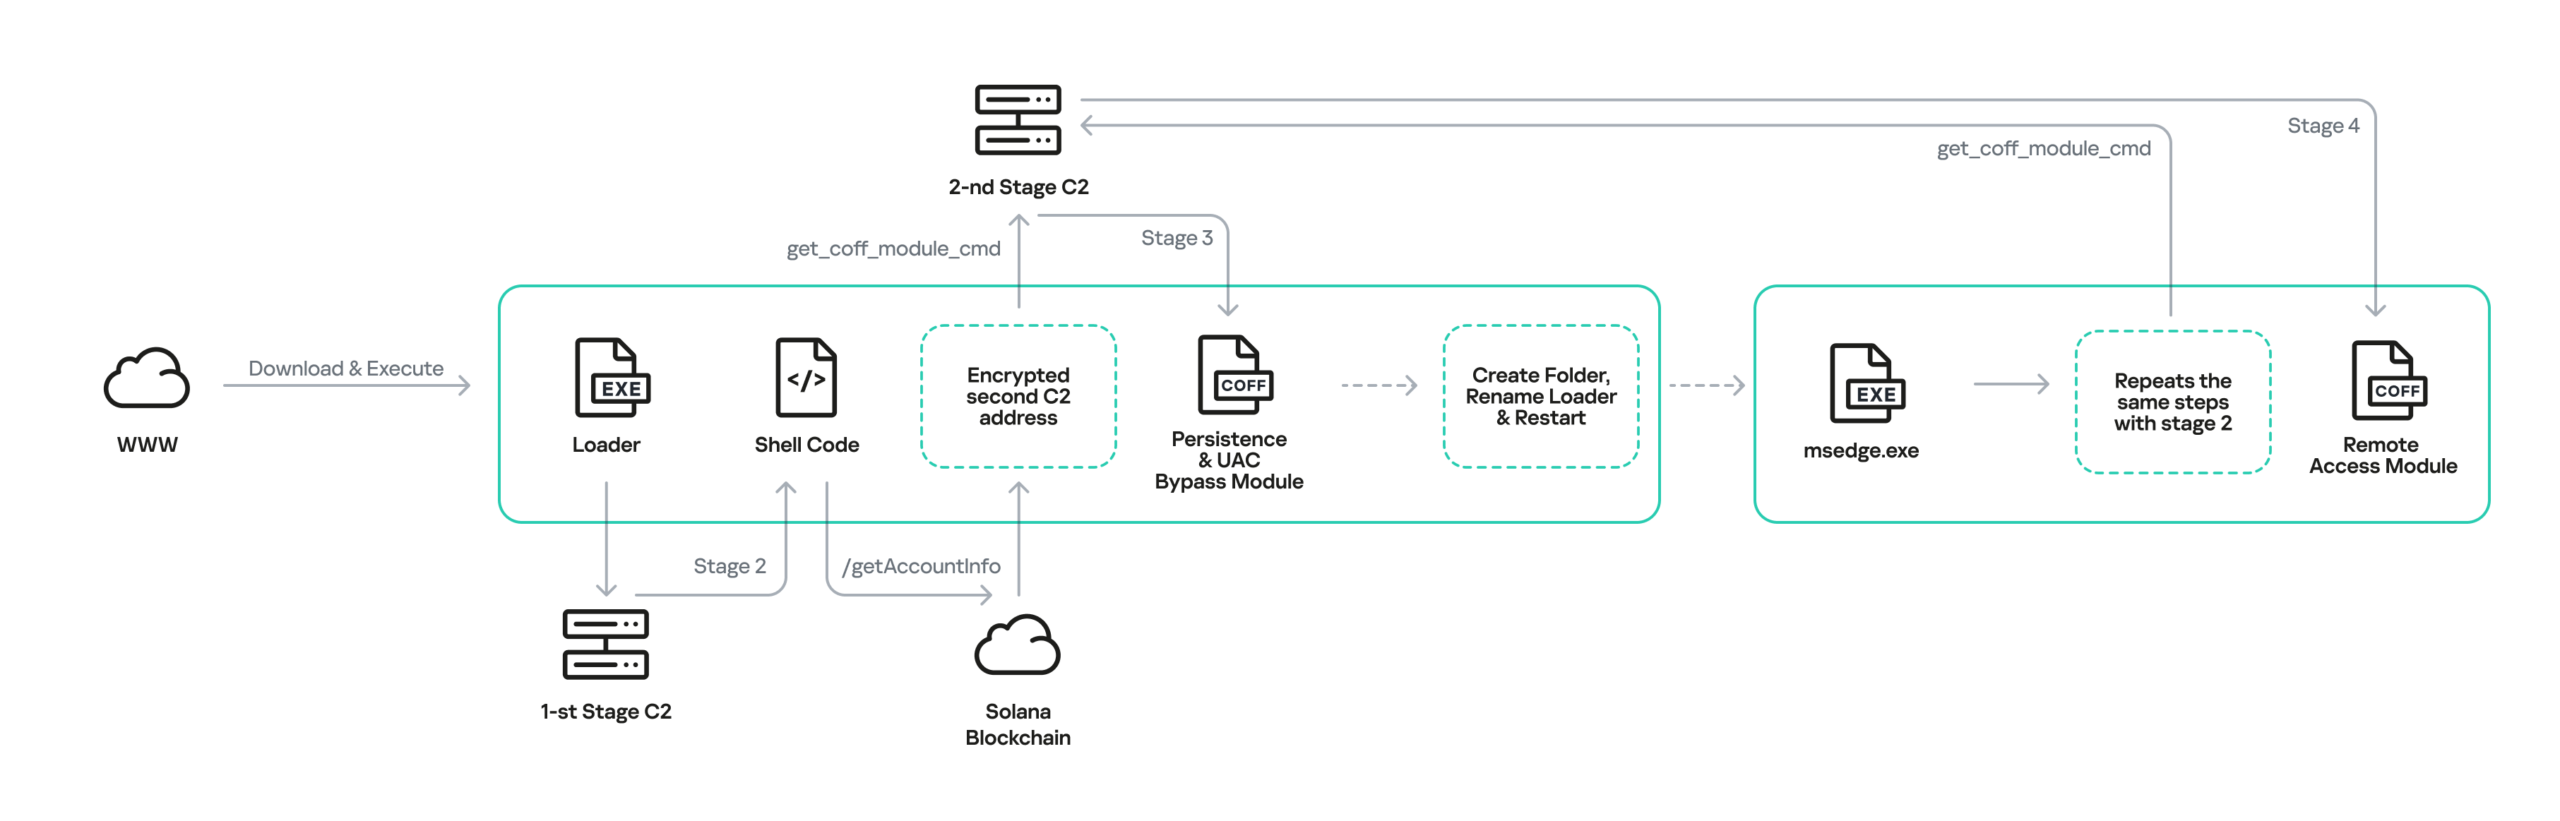
The loader initiates the infection chain shown in the diagram below. Each stage of the chain is described in detail in the following sections.

Malware implants

The infection chain consists of several steps, where only the initial one is dropped on the disk before it is executed to avoid detection. The malware itself is not heavily obfuscated, apart from strings being encrypted with a custom stream cipher. Most of the countermeasures were aimed at avoiding detection by AV sandboxes.

Step 1: Loader

The most popular initial executable was distributed through torrent trackers under many different names (for example, the odyssey (2026) [1080p] [webrip] [5.1].exe), but the file hash (MD5: A0B13781EDD7CFDAB13D79AFFF3C83C1) was identical across all downloads. We have seen multiple different loaders, where the executable file disguises itself with a long filename and an icon of some well-known application. Most of the filenames are rather long, presumably to hide the EXE extension at the end.

After the user manually starts the application, it establishes a global mutex to ensure that only one loader is executed at a time. We have seen several mutex variations in our samples, containing a randomly generated string (in the example Global\fnulSktzSqvVLXHU). This executable then performs a series of operations in order to avoid detection by AV sandbox solutions.

While performing those operations, the malware avoids making LoadLibrary and GetProcAddress calls to acquire the addresses of required functions. Instead, it searches for loaded libraries by traversing the double-linked list taken from the Ldr field of the PEB and then performs manual parsing of the loaded DLL to calculate the function address.

After all initial checks have passed, the binary prepares to establish a network connection to a C2 web server to download the shellcode, map it to the RWX memory and execute. While doing so, the loader decodes the domain name https://deadhub[.]org and if connection to it has failed, it uses the IP address http://193.23.118[.]155 as a fallback and connects to it using plain HTTP. The malware chooses a random group of strings and uses them as a path in the HTTP request to download the parts of the shellcode.

Example URLs:

/cloud/v192.4/ui/sync-status-icons.png
/cloud/v192.4/onboarding/welcome-bg.jpg
/cloud/v192.4/ui/file-preview-placeholder.png
/cloud/v192.4/shared/link-banner.jpg

While mapping the address space and executing the shellcode, the loader registers a vectored exception handler and rewrites the handler address in memory in order to perform a debug break. This, will not crash the program, but instead redirect controlflow to the function that actually makes a raw NtProtectVirtualMemory syscall (via a previously located “0x0F 0x05” syscall instruction inside ntdll). Then it calls the undocumented ntdll function EtwpCreateEtwThread, which is a popular alternative to  CreateThread for code executionm, and executes the shellcode.

Step 2: Shellcode

The second stage of this malware performs an HTTPS request to the Solana blockchain at the endpoint /getAccountInfo endpoint for the account 6pnDGAiHgyPdmckM5Qt1YbanGzrX43WLEU159nRaNLDm. The data in field of the response contains the base64‑encoded address of a second C2, which is encrypted with a static XOR key located within the shellcode itself. To store data in this account, attackers used a simple Solana program (address: CSiY8bQLBYPdfPWkwipBzH6sijTVQVVsA279JQdvwHtL).

Utilizing the Solana blockchain as a storage layer for next-stage C2 endpoints substantially complicates infrastructure takedown efforts by defenders.

The second stage payload communicates with its C2 server strictly through HTTPS via a TLS-pinned certificate using the nanopb protobuf library as a container for transferred data. The main logic of the stage 2 implant contains several initial commands, where the most important is the one that parses the COFF file, loads it into memory, and executes the module_init function from it. This provides a convenient interface for extension of the command list, which brings us to the next stage of the payload.

Step 3: UAC Bypass and persistence

Notably, the recovered modules were compiled with symbols, which accelerated reverse engineering.

After receiving the next stage from the second C2 server, the newly loaded module performs several tasks right in the module_init function.

Stage 3 performs UAC Bypass and achieves persistence using public techniques, masquerades the original binary as C:\ProgramData\Microsoft\Windows\Telemetry\msedge.exe, and restarts itself.

The respawned process starts with the initial loader, but with a special command-line argument, which allows it to skip most of the anti-sandboxing checks and proceed straight to downloading the next payload. The executable proceeds with the same steps as before, but this time, instead of downloading the persistence and UAC bypass module, a new one is downloaded from the second C2 server. This is because the malware uses the beacon to send a flag to the remote server, indicating whether the implant is running from the Telemetry folder, which allows the C2 to distinguish between first-run and respawned instances.

Step 4: The final implant

The final module (“file manager”) exposes 21 commands that give the operator filesystem access on the victim host. This allows remote the operator to download, upload, and read files on the system; list and enumerate directories; manipulate files with create, copy, rename, move, delete, chmod, and symlink commands; and use preview and thumbnail commands to exfiltrate previews of images and files before actually extracting them.

We suspect that other modules may be loaded on demand if requested by the operator.

Infrastructure

During this malware campaign, attackers are using various commercial hosting providers for their C2 infrastructure (see the IoC section for details). Furthermore, as noted above, the campaign leverages the legitimate Solana blockchain via the RPC endpoint api.mainnet.solana.com to deliver the address of the second‑stage C2 server to the malware. This approach provides the attackers with decentralized storage for C2 addresses, adding an additional layer of resilience and making it more difficult for defenders to disrupt the campaign by simply blocking the IP addresses of the C2 servers.

Victims

The observed campaign targeted both individuals and organizations across Europe, Asia, Africa, and Latin America, with infection attempts identified in Russia, Spain, Germany, Finland, Türkiye, Japan, Nepal, Kenya, Tanzania, Ghana, Uganda, Colombia, the Netherlands, Belgium, and other countries. The targeted organizations span a wide range of sectors, including enterprise, government, IT, consulting, retail, transportation, and agriculture.

Conclusions

Our research uncovered activity by the same actor dating back to October 2025. Although the campaign has evolved over time, with the malware authors expanding their arsenal and making the loader harder to detect, the pattern remains the same. This includes encoded strings, parts of shellcode downloaded through plain HTTP, and several techniques used to avoid sandboxes and virtual machines. We will continue monitoring this actor’s activity to catch new potential threats.

The first stage offers the clearest opportunity to disrupt this campaign: it relies on a single specific domain name and a single IP address to serve the shellcode, so taking down this server would prevent subsequent infection stages. This includes the second-stage payload, which uses the Solana blockchain network for a C2 and is therefore more resistant to conventional infrastructure takedowns.

However, this framework’s self-containment, modularity and in-memory execution has potential for reuse in later campaigns with minimal rework.

Indicators of compromise

File hashes

4334BBAEA8DE33BF9D45E9B4E4E3BC2
4843F9FAFCAE492F11E2D4D33DBB4CDD
5310CABAE3FBE6DB8742849B588093F9
A0B13781EDD7CFDAB13D79AFFF3C83C1
70060341CAF3338697A7DDFE0FB62875
AD4643EEA15AC286FA47D1131F9EF756
D0B967571AC8A3863C7F324BF5BDE99C
D88D550D0FB8E60CFFFF3EA61FF7A067

File paths

%ProgramData%\Microsoft\Windows\Telemetry\msedge.exe

Mutexes

Global\E4AyDKzvEhe2hgAr
Global\fnulSktzSqvVLXHU

Domains and IPs

First-stage C2:
deadhub[.]org
193.23.118[.]155

Second-stage C2:
208.64.33[.]90
208.94.246[.]53

  •  

Why OT Resilience Is Now a Boardroom Imperative

For decades, industrial cybersecurity rested on a comfortable assumption: operational technology (OT) was protected by physical isolation. The "air gap" guaranteed that power grids, manufacturing lines, and water systems remained safely disconnected from the chaos of the public internet.

That assumption is no longer just outdated - it is a strategic liability.

Driven by the imperative for real-time efficiency, predictive maintenance, and AI-led automation, industrial operations are integrating with enterprise IT and cloud environments at an unprecedented scale. Telemetry from Palo Alto Networks reveals a 332% surge in unique internet-exposed OT devices and services, bringing nearly 20 million OT-related assets onto the public internet.

Digital transformation has fundamentally redrawn the perimeter. What was once an engineering challenge managed on the plant floor has transformed into an existential risk that demands board-level oversight.

Every Industrial Asset Is Now a Digital Asset

Modernizing critical infrastructure is rarely framed as a security initiative; it is an operational mandate. Heavy machinery engineered to last thirty years is now instrumented with IoT sensors, managed through cloud-native platforms, and remotely monitored.

This connectivity creates tight dependencies between core business IT and physical operations. Modern industrial facilities rely on enterprise identity management, cloud telemetry, and continuous software updating to function day to day.

Consequently, a threat actor does not need to breach the factory floor to stop production.

When an enterprise IT network suffers an incident, executive leadership often initiates a manual shutdown of operational lines out of caution or because shared authentication mechanisms become unavailable. The business processes linking enterprise IT and OT have become functionally inseparable.

The Anatomy of Modern Industrial Threats

Attackers no longer require sophisticated, state-sponsored zero-day exploits to disrupt physical infrastructure. As seen in recent cyber incidents targeting municipal water systems in the US and the breach of a Polish power plant, threat actors continuously exploit basic internet exposure, unpatched vulnerabilities, weak default credentials, and unsegmented remote connections.

Threat dynamics across critical infrastructure have shifted toward two major vectors:

  • Low-Friction Initial Access: Basic internet discovery tools allow threat actors to identify exposed control systems and programmable logic controllers (PLCs) in minutes. Weak factory default passwords or unsegmented cellular modems provide direct entry points into physical operations.
  • Operational Blindness: Modern attacks deliberately target the reporting layer - such as HMI and SCADA interfaces - to suppress alarms and present "normal" operational telemetry to engineers, even while underlying physical processes operate dangerously out of specification.

Operational Realities and the Zero Trust Imperative

The integration of artificial intelligence and automated workflows into industrial environments accelerates this challenge. Beyond human engineers logging into control networks, automated software pipelines, third-party monitoring platforms, and autonomous AI agents are executing commands within OT environments.

Data from recent identity landscape research reveals that machine identities outnumber human identities by 109 to 1 across EMEA organizations.

In an environment populated by millions of interconnected human, machine and AI actors, implicit trust based on network location is dangerous. Applying Zero Trust to OT requires moving away from traditional perimeter defense toward continuous, explicit verification:

  • Verify Explicitly: Authenticate and authorize every access request - human or machine - regardless of where the request originates.
  • Enforce Least-Privilege Access: Limit access strictly to the assets and commands necessary for a specific operational role or process.
  • Assume Breach: Design networks under the assumption that enterprise systems are compromised, preventing lateral movement into physical control layers.

The Industrial "Red Button": Engineering for Containment

While IT security prioritizes data confidentiality, OT security prioritizes human safety, system availability, and operational continuity. Halting a processing facility or energy grid carries immediate financial, environmental, and regulatory consequences. Security controls designed for corporate office networks cannot simply be retrofitted onto plant floors.

Cyber resilience is measured not merely by prevention, but by limiting the blast radius when a breach occurs.

Leading industrial organizations are establishing a programmable "Red Button" capability - a combination of architectural micro-segmentation and automated playbooks. This architecture allows security teams to rapidly isolate critical physical operations from compromised IT networks or cloud dependencies without bringing production to a complete halt.

Five Strategic Actions for Executive Boards

With regulatory frameworks like NIS2 increasing direct accountability for senior leadership, OT cybersecurity requires strategic governance centered on comprehensive visibility, robust micro-segmentation, operational risk scoring, and virtual patching:

  • Establish Complete Asset Visibility: Eliminate dark corners across physical environments. Organizations must maintain a continuous, real-time inventory of every connected industrial asset, controller, and external dependency.
  • Embed Security by Design and Virtual Patching: Integrate cybersecurity requirements directly into industrial modernization programs from initiation. Deploy virtual patching mechanisms - such as Frontier Virtual Patching - to shield unpatchable legacy systems against rapidly evolving AI-driven threats.
  • Architect for Degraded Mode: Design critical infrastructure to maintain safe, baseline operations even if cloud access, enterprise IT, or external network connections are severed.
  • Practice Operational Recovery: Develop and stress-test incident response playbooks specifically designed for physical environments, including offline configuration backups and manual operational overrides.
  • Unify Risk Governance: Align executive leadership, security operations, and plant engineering around operational-based risk scoring and shared business metrics: physical safety, system uptime, and operational continuity.

Accelerating digital transformation should not mean compromising physical safety or operational stability. Palo Alto Networks provides an integrated platform built to address the unique constraints of operational environments. By combining AI-driven asset discovery, granular micro-segmentation, continuous risk assessment, and virtual patching across both enterprise IT and physical control networks, Palo Alto Networks empowers industrial organizations to modernize with confidence - securing operations, protecting revenue, and safeguarding national infrastructure.

Further interesting reading:

The post Why OT Resilience Is Now a Boardroom Imperative appeared first on Palo Alto Networks Blog.

  •  

AWS European Sovereign Cloud: Demonstrating an independent operation

On Saturday, October 24, 2026, we will conduct an exercise demonstrating that the AWS European Sovereign Cloud can operate without depending on any infrastructure outside of the European Union (EU).

For several hours, the AWS European Sovereign Cloud will operate without a connection to the AWS Global Network backbone. The backbone is the private network that moves authorized AWS operational data between AWS locations without using the public internet. During the exercise, this traffic will securely reroute over the public internet.

The exercise will not affect service availability within the AWS European Sovereign Cloud, other AWS Regions, or private connectivity through AWS Direct Connect. Customers may experience brief connectivity disruptions as traffic moves onto a separate network route at the beginning or the end of the exercise, after which normal connectivity resumes.

The operational team, composed entirely of EU residents within the EU, will execute the exercise using only the hardware and software resources of the AWS European Sovereign Cloud. The AWS European Sovereign Cloud Managing Directors called for this exercise to showcase its operational independence.

An independent cloud for Europe

The AWS European Sovereign Cloud is a new, independent cloud for Europe. Located in Brandenburg, Germany, its data centers are physically and logically separate from other AWS Regions, with a local in-EU copy of the source code. All customer content and customer-created metadata stay in the EU. It has no critical dependencies on non-EU infrastructure and is operated exclusively by EU residents.

In standard operations, the AWS European Sovereign Cloud uses two global systems. The first is the AWS Global Network backbone. The second is a dedicated system that the local EU team controls and supervises to securely manage limited, controlled transfers of operational AWS data.

Neither is operation-critical, and neither affects the sovereignty assurance of the AWS European Sovereign Cloud. The AWS European Sovereign Cloud can operate independently at any time without a connection to these global systems, and on October 24 that’s what the team will demonstrate.

Built to meet regulatory standards

This exercise will produce verifiable technical and operational evidence that the AWS European Sovereign Cloud can operate independently within the EU. The exercise is designed to be consistent with the objectives of the European Commission’s EU Cloud Sovereignty Framework (CSF) and the criteria of the C3A framework from Germany’s Federal Office for Information Security (BSI). These frameworks set out objectives and criteria for assessing whether cloud services can be provided independently and autonomously.

We designed the AWS European Sovereign Cloud for regulated customers and the public sector across the EU. The AWS European Sovereign Cloud: Sovereign Reference Framework (ESC-SRF) gives our customers and partners a comprehensive set of evidence points, maps to controls, artifacts, and other elements regulators and compliance authorities need to accelerate their adoption of the AWS European Sovereign Cloud. The results of this exercise will provide additional evidence for their compliance and assurance packages.

Standalone and fully secure

The AWS European Sovereign Cloud runs connected to the AWS Global Network backbone because it delivers superior performance, capacity, reliability, security, and cost savings to customers. That includes always-on encryption and distributed denial of service (DDoS) defenses; and the backbone can’t decrypt or see the encrypted data that AWS European Sovereign Cloud customers send and receive. While the backbone delivers these benefits day-to-day, the AWS European Sovereign Cloud can continue to operate independently, with the appropriate security controls in place.

During the exercise, instead of using the AWS Global Network backbone, the AWS European Sovereign Cloud will exclusively use its dedicated internet connectivity from European internet service providers. This will provide connectivity to the worldwide internet.

Whenever traffic moves between internet links, there’s a small window of limited disruption called convergence, a short time when other non-AWS networks change their routing information to reflect the change. This could happen at the beginning of the exercise, when traffic moves to dedicated AWS European Sovereign Cloud internet providers, and at the end of the exercise, when traffic moves back to the AWS Global Network backbone.

Customer data stays in the EU

AWS has committed to not moving AWS European Sovereign Cloud customer content and customer-created metadata outside of the EU. Only certain data, which is neither customer content nor customer-created metadata, such as AWS operational data, leaves the EU. We use a dedicated system to securely manage these limited, controlled transfers under the control and supervision of the local EU team. We’re rigorous about what the system transfers. It accepts vetted source code mirroring and software updates, and transfers out very limited and approved routine information. During the exercise, the AWS European Sovereign Cloud team will disable the system entirely, confirming that the AWS European Sovereign Cloud continues to operate independently without it.

Learn more

AWS will share an update after the exercise with regulators and customers. To learn more about the AWS European Sovereign Cloud’s design and digital sovereignty controls, visit aws.eu. If you have questions about this exercise or would like to discuss how it may impact your workloads, reach out to AWS Support or contact your AWS Account team.

Stephane Israel

Stéphane Israël

Stéphane is the leader and Managing Director of the AWS European Sovereign Cloud. He is responsible for the management and operations of the AWS European Sovereign Cloud, including infrastructure, technology, and services, in addition to broader digital sovereignty efforts at AWS. Prior to AWS, he was the CEO of Arianespace, where he oversaw numerous successful space missions, including the launch of the James Webb Space Telescope.

  •  

Goals Are Not Enough: Securing AI Agents with NVIDIA OpenShell

In this article An agent’s goal rarely says how the agent may reach it, and capable agents are good at finding routes nobody planned for. →NVIDIA Open Agent Safety Platform puts the boundary in the infrastructure, outside the agent’s reach →Check Point semantic monitoring judges whether each step still fits the task →the two already work together in a beta integration with NVIDIA OpenShell →the monitor’s verdict can arrive before the action runs, in under 100 milliseconds What the Goal Leaves Out When an organization hands an autonomous agent a job, such as processing supplier invoices, it states the goal […]

The post Goals Are Not Enough: Securing AI Agents with NVIDIA OpenShell appeared first on Check Point Blog.

  •  

A Decision Model Breaks Like Any Other Language Model: A First Look at Jev

A new kind of AI model returns decisions instead of text. We spent a day trying to change its mind. It cost about 50 cents. In this article Jev is a new kind of AI model that returns typed decisions instead of text, built for software to call rather than for people to read. We put it inside a realistic application and tried to change its verdict from the outside. →every configuration we tested was broken: risk downgraded to low and investment advised, on a document that flags every warning sign →about 50 cents per successful break, with our strongest […]

The post A Decision Model Breaks Like Any Other Language Model: A First Look at Jev appeared first on Check Point Blog.

  •  

Can We Control Every AI Agent Before It Becomes Our Next Privileged Insider?

AI agents are moving into the enterprise much faster than most security programs were designed to handle. They are no longer just answering questions or generating content. Agents can read email, access SaaS applications, query databases, invoke APIs, use MCP tools, modify records and execute business workflows. In other words, AI is moving from generating answers to taking actions. For CISOs and C-level leaders, that changes the security conversation. The question isn’t simply whether an organization is using AI safely. A more important question is: Can we confidently identify, govern, monitor, and control every AI agent before it becomes our […]

The post Can We Control Every AI Agent Before It Becomes Our Next Privileged Insider? appeared first on Check Point Blog.

  •  

ICYMI: August 2026 @AWS Security

Read all about the latest AWS security features, compliance updates, and hands-on resources in our monthly digest posts. You’ll find expert blog posts, new service capabilities, code samples, and workshops.

AWS Security Blog posts

August brought 20 AWS Security Blog posts organized across seven categories. Identity and access management led the month with five posts covering self-service rate limits for Amazon Cognito, a decade of AWS Managed Microsoft AD, a redesigned sign-in experience, console Private Access for isolated VPCs, and automated IAM Identity Center governance. Data protection followed with four posts on AWS KMS data key caching, ACME protocol support in AWS Certificate Manager, Amazon S3 over-permissioned access remediation, and the upcoming deprecation of email-based domain validation. AI security continued to grow with four posts on custom authentication in Amazon Bedrock AgentCore Gateway, user authorization propagation in AI agents, and extending Bedrock Guardrails to tool interactions. Threat detection, governance and networking.

Identity

From 2 weeks to 2 minutes: Amazon Cognito launches provisioned limits for self-service rate limit management
Authors: Kiran Dongara, Howie Li | Published: August 5, 2026
Learn to use Amazon Cognito provisioned limits for on-demand authentication rate limit adjustments, replacing the previous 10–14 day support ticket process with self-service capacity scaling in minutes.

A decade of enterprise identity in the cloud with AWS Managed Microsoft AD
Authors: Vladimir Provorov, Tekena Orugbani, Rodney Underkoffler | Published: August 7, 2026
AWS Managed Microsoft AD celebrates 10 years of fully managed Active Directory in the cloud, now offering Standard, Enterprise, and Hybrid editions with multi-Region replication and 20+ AWS service integrations.

Updates to your AWS sign-in experience
Authors: Vaibhav Chowla, Ella Segura | Published: August 17, 2026
AWS is gradually rolling out a redesigned sign-in page with a unified email entry point, social identity provider options, and an updated session selection experience for managing multiple active sessions.

Extend your data perimeter to the AWS Management Console with Private Access
Authors: Madhur Kulkarni, Abhijit Barde, Sujay Ghosh, Mateusz Jaworski | Published: August 28, 2026
AWS Management Console Private Access now supports VPCs without internet connectivity, routing all console traffic – authentication, static assets, and service API calls – through AWS PrivateLink endpoints to strengthen your data perimeter.

Automate IAM Identity Center governance with continuous discovery and reporting
Author: Jonathan Nguyen | Published: August 31, 2026
Learn to deploy automated discovery and reporting for AWS IAM Identity Center applications and assignments across your organization, with event-driven monitoring that validates naming conventions and enables near real-time enforcement of governance policies.

Data Protection

Caching KMS data keys in multi-thread environments: per-tenant encryption for event-driven systems at scale
Authors: Maria Gutovsky, Hemmy Yona | Published: August 6, 2026
Learn to solve the cache stampede problem in multi-tenant envelope encryption using the AWS-recommended hierarchical keyring pattern or a custom Caffeine-based caching approach to reduce AWS KMS costs.

Automate certificates with ACME support in AWS Certificate Manager
Authors: Anthony Harvey, Chandan Kundapur | Published: August 6, 2026
Learn to use ACME protocol support in AWS Certificate Manager to automate public certificate issuance and renewal using standard clients like Certbot and cert-manager, with enterprise controls for domain scoping and centralized visibility.

Securing your Amazon S3 buckets: identifying and remediating over-permissioned access
Authors: Hetal Kolekar, Fernando Chiera di Vasco Freitas, Manonmayi Vedam | Published: August 7, 2026
Learn to detect and fix over-permissioned Amazon S3 buckets across multi-account environments using AWS Lambda, AWS Config, and AWS Security Hub, with automation for continuous monitoring.

AWS Certificate Manager will discontinue email validation to prove domain validation for certificates
Authors: Adam Aboudi, Poojil Tripathi | Published: August 13, 2026
ACM will discontinue email-validated public certificates by September 30, 2027, aligning with CA/B Forum standards – learn the timeline and how to migrate to DNS validation in place.

AI Security

Implement custom authentication for tools integration using request Lambda interceptor in AgentCore Gateway
Authors: Nishant Mainro, Ram Ramani | Published: August 18, 2026
Learn to use a request Lambda interceptor in Amazon Bedrock AgentCore Gateway to bridge legacy authentication mechanisms like Basic Auth, isolating credentials from AI agents using AWS Secrets Manager.

Propagate user authorization context in AI agents with Amazon Bedrock AgentCore
Authors: Anshu Bathla, Prafful Gupta, Rohit Verma | Published: August 19, 2026
Learn to enforce least-privilege access in AI agents by propagating user identity through Amazon Bedrock AgentCore to Amazon DynamoDB, Knowledge Bases, and Salesforce, without embedding authorization logic in agent code.

Extend Amazon Bedrock Guardrails to tool interactions using the Strands Agents SDK
Authors: Stephan Traub | Published: August 27, 2026
Learn to extend Amazon Bedrock Guardrails beyond the model boundary to tool calls, external data, and MCP server interactions using three validation checkpoints built with Strands Agents SDK lifecycle hooks.

Threat detection and incident response

Security Hub Extended adds supply chain security as its tenth category
Author: Michael Fuller | Published: August 18, 2026
AWS Security Hub Extended now includes supply chain security with Chainguard and Socket as curated partners, helping you verify open source dependencies and block malicious packages through a single AWS billing relationship.

Detecting multi-stage attacks on AWS: a guide to cross-service signal correlation
Authors: Nisha Kashyap | Published: August 26, 2026
Learn to correlate signals across AWS CloudTrail, VPC Flow Logs, and Route 53 Resolver logs to detect multi-stage attacks by layering your business context, data classification, access norms, and change windows – on top of Amazon GuardDuty Extended Threat Detection.

AWS partners with Anthropic and OpenAI to bring AWS Continuum into developer workflows
Author: Chet Kapoor | Published: August 5, 2026
AWS Continuum for code vulnerabilities now integrates with Anthropic Claude Code, OpenAI Codex, and Kiro, enabling developers to discover, prioritize, validate, and remediate vulnerabilities within their coding environments.

We invited a direct competitor into Security Hub Extended. Here’s why.
Authors: Michael Fuller | Published: August 31, 2026
AWS Security Hub Extended now includes Upwind, a runtime-first cloud security company, offering eBPF-based workload protection with pay-as-you-go pricing through a single AWS bill, reinforcing customer choice even where capabilities overlap with AWS offerings.

Infrastructure security

AWS Network Firewall now supports rule hit count
Authors: Preetkumar Shah, Amit Gaur, Cheriyan Mundapuzha, Santosh Shanbhag, Srivalsan Mannoor Sudhagar | Published: August 20, 2026
AWS Network Firewall now tracks how often stateful rules match traffic, helping you identify unused rules, validate security controls for compliance, and accelerate incident response at no additional cost.

Governance and compliance

Landing Zone Accelerator independent assessment report for C5:2020 now available on AWS Artifact
Authors: Kevin Donohue, Michael Wahlers | Published: August 11, 2026
An independent assessment by Schellman evaluates how Landing Zone Accelerator on AWS aligns to C5:2020 requirements, implementing 325 security controls to accelerate your compliance journey.

Fast track ISM-ready cloud environments and IRAP assessments with Landing Zone Accelerator on AWS
Authors: Kevin Donohue, Dave Connell, Dan Friebe | Published: August 25, 2026
A new independent assessment by gwi.digital evaluates Landing Zone Accelerator against 1,081 ISM controls, achieving 91% coverage of addressable scope to help Australian customers accelerate IRAP assessment readiness.

How Moeve scales AWS governance with automated AWS Organization Service Control Policies
Authors: Gonzalo Guerrero, Jonatan De Martín, Rayco Martinez | Published: August 26, 2026
Learn how Moeve manages 150 SCPs across 300+ accounts in three AWS Organizations using a governance-as-code model; policies live in Git, deploy through GitHub Actions pipelines, and attach dynamically based on account metadata during onboarding, with Amazon EventBridge and AWS Lambda providing real-time observability of every organizational change.

August Security Bulletins

In August 2026, AWS published 23 security bulletins addressing vulnerabilities across open-source SDKs, MCP servers, developer tools, and the OpenSearch ecosystem. A dominant theme was the AI agent tool surface: prompt-injection consent bypasses in Strands Agents Tools enabled command and code execution, an insecure direct object reference exposed cross-tenant agent memory, and credential disclosure and authorization flaws affected the Amazon MQ, DocumentDB, and AWS Transform MCP servers and the Bedrock AgentCore harness. Remote code execution recurred throughout, from prototype pollution and Java deserialization in OpenSearch to path-traversal-to-root in amazon-ssm-agent, Zip Slip in awsdac, and an uncontrolled search path in the Kiro IDE and CLI on Windows.

Other notable issues include disabled SSH host key verification in the AWS CLI, memory-safety flaws in the AWS SDK for C++, privilege escalation in the FreeRTOS-Kernel, and memory-amplification denial of service in Amazon ion-java. OpenSearch accounted for a large share of the month, spanning authorization, input validation, SSRF, stored XSS, and denial of service, while Athena Federated Query connectors exposed Secrets Manager secrets. A common thread: insufficient authorization and input validation at the boundary between AI agents and the systems they reach. All patches are available, upgrade promptly. For more information, see AWS Security Bulletins.

AWS Samples

In August 2026, we published 17 new code samples organized into five categories: governance and compliance (7), AI security (3), data protection and privacy (3), identity and access management (2), and infrastructure security (2). This month’s collection reflects the rapid growth of agentic AI workloads: most samples focus on governing, auditing, and securing AI agents built on Amazon Bedrock AgentCore, from platform-level governance and telemetry to fraud investigation and biosecurity screening.

Governance and compliance

Agentic Governance Platform

Learn to deploy an AWS-native control plane for governing AI agents across your enterprise with centralized registry, Microsoft Entra ID single sign-on, Cedar tool policies, multi-vendor agent inventory, and Langfuse observability, all self-hosted on Amazon Bedrock AgentCore.

Enterprise Agentic AI Platform Accelerator

Learn to deploy a secure, governed foundation for production AI agents on Amazon Bedrock AgentCore with modular CDK stacks covering identity, gateway, memory, runtime, and observability; supporting Strands Agents, LangGraph, and Claude Agent SDK with opt-in security controls.

Video Compliance Agent

Learn to deploy an end-to-end pipeline that automatically verifies video content against broadcast compliance guidelines such as Ofcom; extracting frames, audio transcripts, and OCR text shot by shot, then using Amazon Bedrock to flag potential violations and produce a structured per-shot compliance report.

Intelligent Security for Healthcare APIs

Learn to add behavioral anomaly detection, automated data sensitivity classification, and HIPAA compliance reporting to your FHIR API using Amazon Bedrock; running asynchronously so clinical workflows are never blocked, with Amazon Comprehend Medical and Bedrock Guardrails anonymizing PHI throughout the monitoring path.

Governed Agentic Companion

Learn to deploy a governed, orchestrator-driven multi-agent builder companion on Amazon Bedrock AgentCore, reachable from Kiro, Claude Code, or any MCP client; the kit enforces 13 codified tenets through an always-on governance gate with no off switch, routing each request to a specialist while blocking deploys, secret leaks, and ungrounded answers by construction.

Audit the Agent

Learn to deploy a serverless daily executive audit pipeline for AWS AI agents (AWS DevOps Agent, AWS Security Agent) using AWS Step Functions and AWS Lambda; the report answers five questions: what the agent accessed, who authorized it, what it cost, its risk posture across five trust dimensions, and whether you should be concerned, all sourced deterministically from AWS CloudTrail, CUR, and IAM with AI-generated summaries bounded by layered guardrails.

AI Security

Telemetry Enablement for AgentCore CloudFormation

Learn to deploy a single AWS CloudFormation stack that enables Amazon CloudWatch logs and X-Ray traces for every Amazon Bedrock AgentCore resource type – Runtime, Gateway, Memory, Browser, CodeInterpreter, and WorkloadIdentity – using native and custom telemetry rules.

Bedrock Guardrails to OCSF on CloudWatch

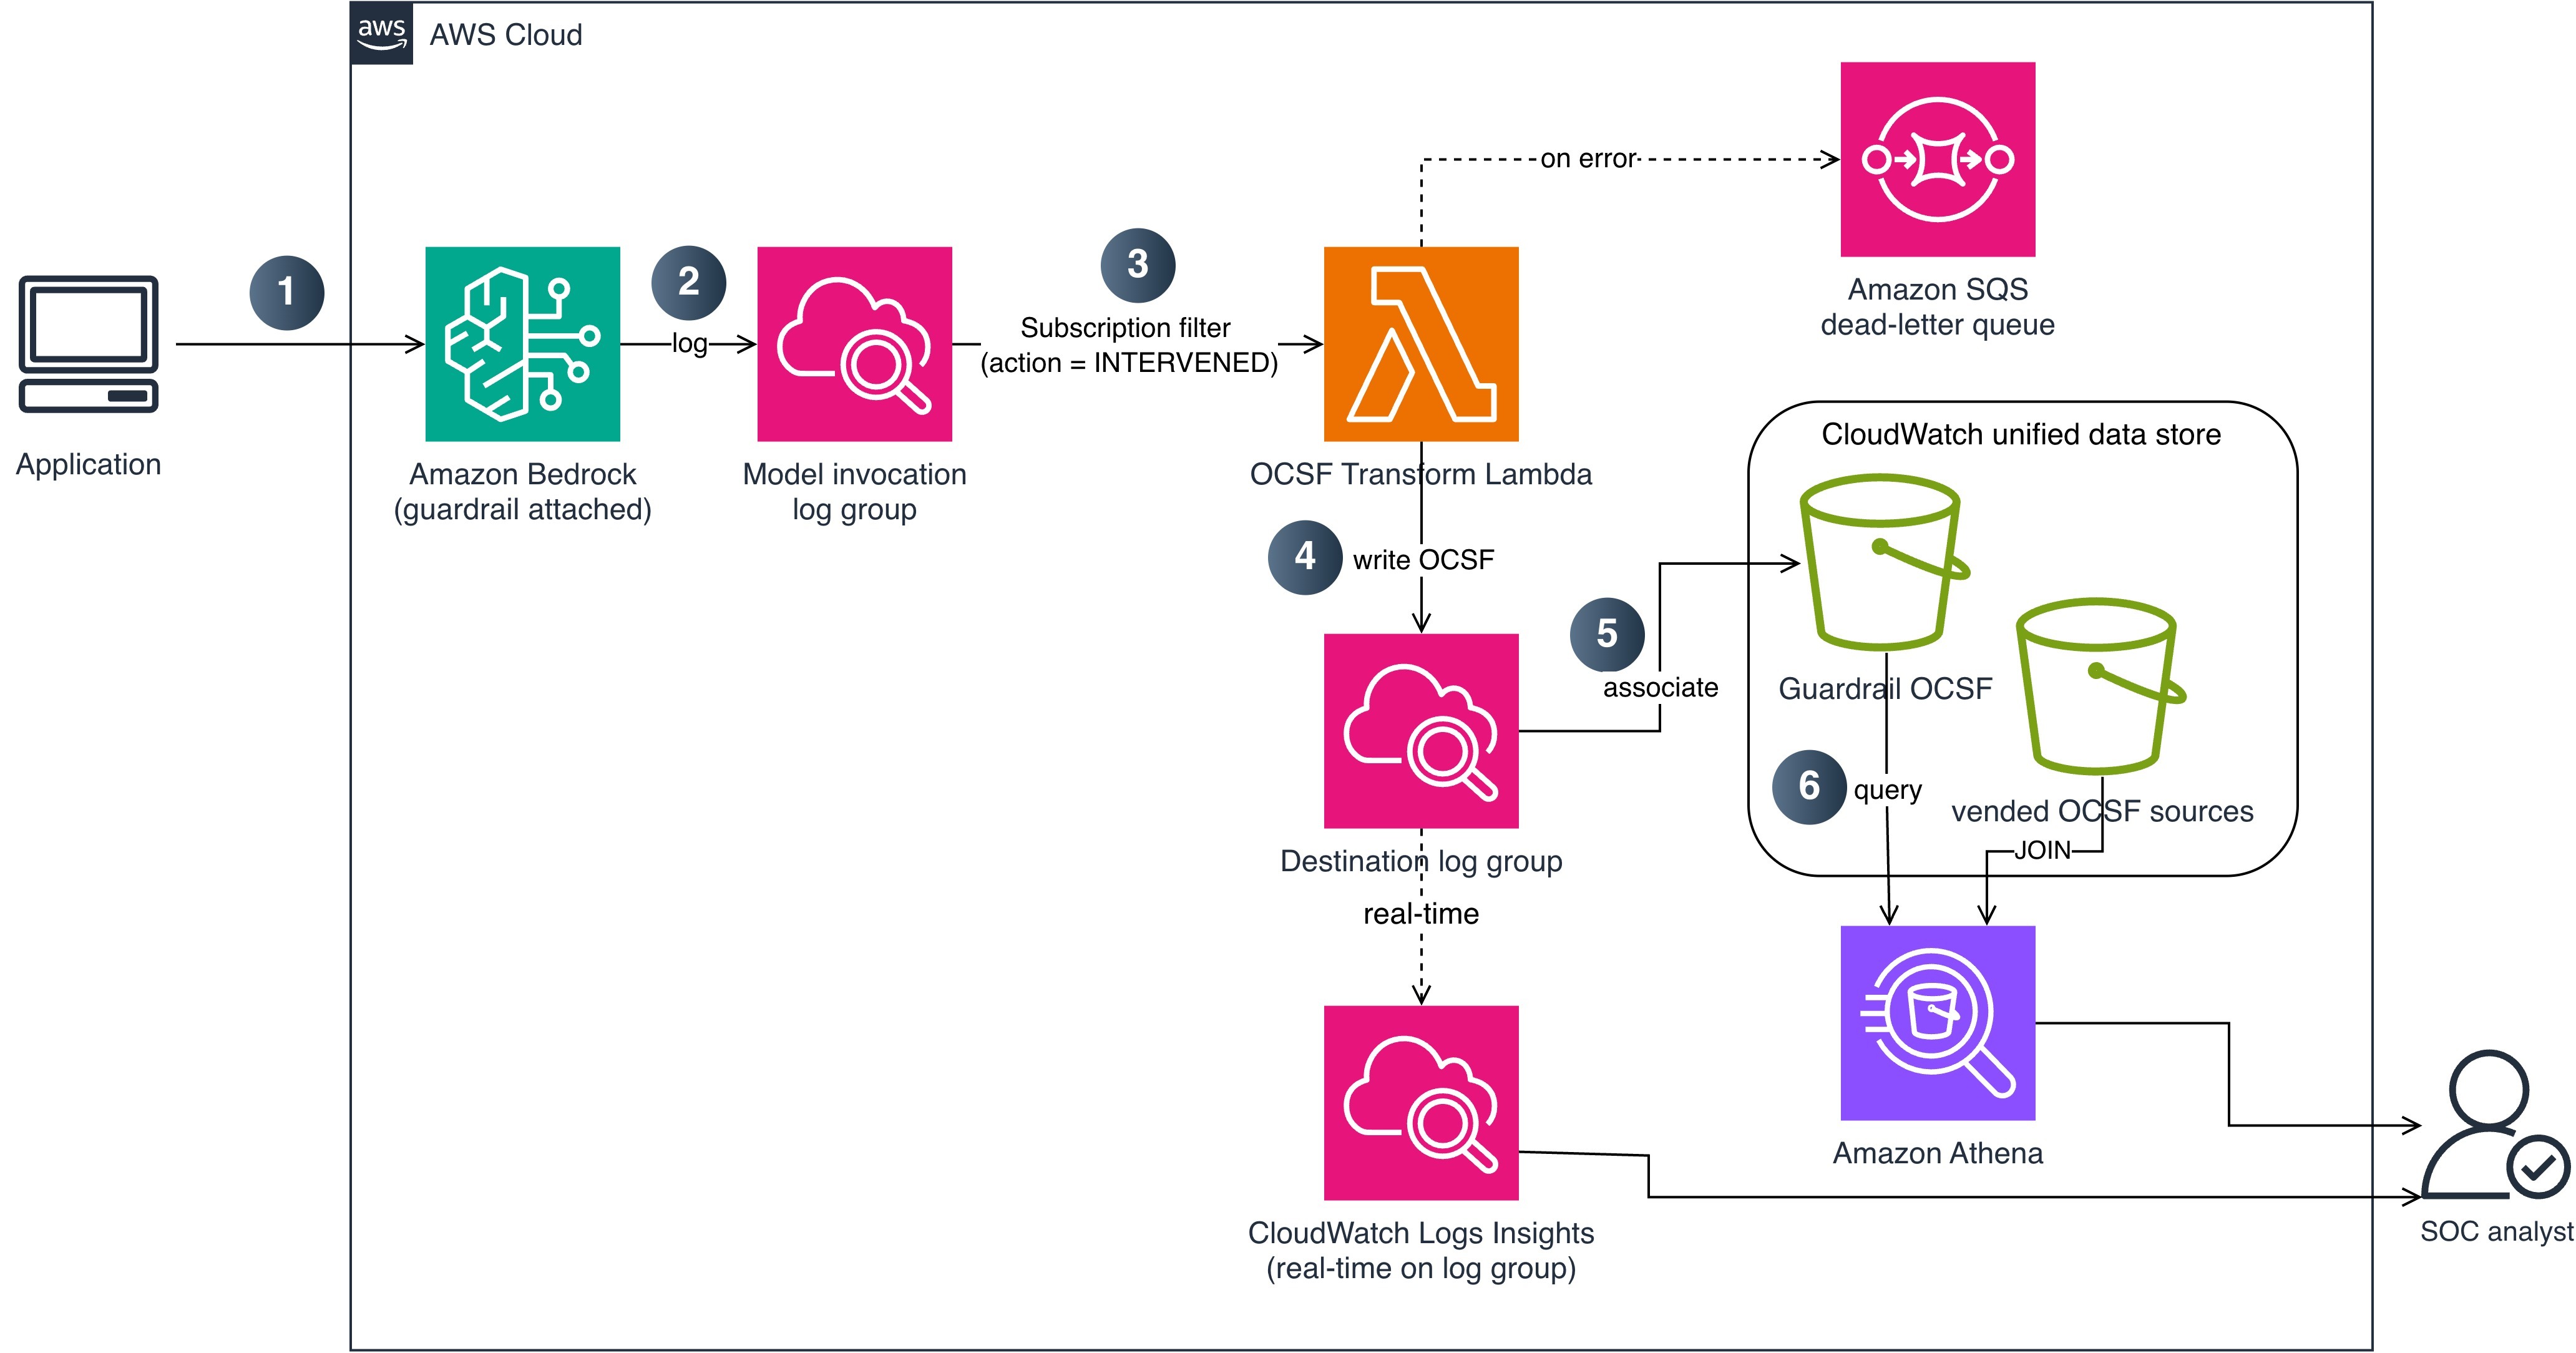
Learn to transform Amazon Bedrock Guardrails intervention events into OCSF Detection Finding records and land them in the Amazon CloudWatch unified data store; enabling you to query guardrail violations alongside AWS CloudTrail, Amazon VPC Flow Logs, and other sources with Amazon Athena or CloudWatch Logs Insights.

Bedrock Readiness Agent

Learn to deploy a read-only assessment agent built with the Strands Agents SDK that evaluates your Amazon Bedrock environment across six dimensions: IAM governance, data retention, quota headroom, model selection fitness, cost projection, and operational observability; generating severity-rated findings with AWS CloudFormation and Terraform remediation templates you can apply directly.

Infrastructure security

DDoS Guardian

Learn to install an agent skill that reviews an AWS WAF web ACL as a system: evaluation order, rule interactions, and L7 DDoS posture; then delivers a severity-ranked HTML report with ready-to-apply remediation. Offline, read-only, no AWS resources modified.

Biosecurity Screening Policy on Amazon Bedrock AgentCore Gateway

Learn to use Policy in Amazon Bedrock AgentCore to deterministically screen AI agent tool requests for biosecurity risks, combining Cedar policies with three independent screening layers: MMseqs2 sequence alignment, ESMC-600M embedding similarity, and Foldseek structural homology; enabling defense-in-depth controls that block high-risk protein sequences before they reach downstream tools.

MCP Fraud Investigation Agent

Learn to deploy an end-to-end AI-powered e-commerce fraud investigation agent built with the Strands SDK on Amazon Bedrock AgentCore, connecting through an AgentCore Gateway over MCP to query transaction history, customer profiles, login activity, support cases, and fraud playbooks; a React dashboard on AWS Amplifystreams the agent’s reasoning token by token as it works each case.

Identity

IAM Account Access Manager with ABAC

Learn to implement workforce access using IAM account access manager and attribute-based access control, where one IAM role per project shares a single policy document and access decisions are made by comparing role tags against resource tags at request time; onboarding a new project requires only tagging and entitlement configuration with no policy authoring.

Operationalizing Least Privilege: Automate IAM Remediation through Your CI/CD Pipeline

Learn to automate remediation of unused IAM permissions using AWS IAM Access Analyzer, AWS CloudTrail, and Amazon Bedrock for AI-generated AWS CDK code; the solution attributes each role to its origin (IaC or manual), then creates pull requests for IaC-managed roles or issues for manually created roles in GitLab or GitHub, with configurable exclusion rules and policy diffs for human review.

Data Protection

Data Residency Chatbot with Amazon Bedrock AgentCore

Learn to deploy a data-residency-compliant natural-language chatbot on Amazon Bedrock AgentCore where all data and AI inference stay within a single AWS Region; the solution uses a Strands agent that answers plain-English questions from Aurora PostgreSQL through governed, whitelist-validated read-only tools exposed via an AgentCore Gateway, with a residency guard that rejects any cross-region inference profile, demonstrated with a rooftop-solar subsidy program and adaptable to any sector or geography.

LLM-based PII Detection

Learn to detect personally identifiable information in conversational text using Amazon Bedrock; the solution prompts any Converse-compatible model to return PII spans with category, value, and character offsets, handles long inputs via word-boundary chunking, recovers near-miss labels, and supports custom categories, few-shot examples, and pluggable backends beyond Bedrock.

Agentic Data Classification and Redaction

Learn to build a conversational AI research assistant that automatically classifies documents for MNPI, PII, and security sensitivity, then enforces per-user redaction at query time using Amazon Bedrock AgentCore, Guardrails, and Amazon OpenSearch Serverless vector search.

Conclusion

August 2026 provides comprehensive guidance and runnable code for governing agentic AI workloads at enterprise scale, from orchestrator-driven governance gates and biosecurity screening policies to daily executive audit pipelines and OCSF-normalized guardrail telemetry. The posts and samples provide patterns for console Private Access in isolated VPCs, attribute-based access control with IAM account access manager, automated least-privilege remediation through CI/CD, and cross-service signal correlation for multi-stage threat detection. Each resource includes deployment steps or runnable code so you can validate in your own environment before adopting. Subscribe to the AWS Security Blog RSS feed to receive updates as they publish, and revisit this digest monthly for a consolidated view of what changed and what to act on.

If you have feedback about this post, submit comments in the Comments section below.


Rodolfo Brenes

Rodolfo Brenes

Rodolfo is a Principal Solutions Architect focused on Cloud Governance and Compliance. With over 18 years of experience, he currently leads a technical field community in AWS helping customers scale and improve their security and governance frameworks. Besides work, Rodolfo enjoys video games, playing with his four cats, and won’t say no to a good outdoor adventure.

Anna Brinkmann

Anna has 18 years of experience in the technical content space and has spent the last 6 years managing the AWS Security Blog. Outside of work, she enjoys spending time with her family.

  •  

OWASP LLM Top 10 2026: Every Move Points the Same Direction

This is Post 4 of a four-part series:
Post 1: Agentic AI Security: The Chatbot Era Is Over
Post 2: Generative AI Security: Why AI Needs a New Kind of Security
Post 3: The OWASP LLM Top 10 Was the Warm-Up: What Comes Next

The 2026 edition of the the OWASP Top 10 for LLM Applications, published by the OWASP GenAI Security Project on August 3, 2026, is easy to skim past. No entry was dropped and no new category was introduced, so at a glance it can read as housekeeping. It is worth a closer look than that. Eight of the ten entries changed position, and one was renamed and widened in scope, which changes what it asks of the teams working against it.

When a framework adds or drops entries, it is usually telling you the threat surface itself has changed. This edition did something more specific. The categories held, but their order was substantially revised and one of them grew, which suggests the original naming was sound while the relative priority had drifted from what teams were meeting in production. Read the movements together and a pattern shows up.

The short version: the OWASP Top 10 for LLM Applications 2026 kept all ten categories but moved eight of them. Excessive Agency climbed from LLM06 to LLM03, Unbounded Consumption from LLM10 to LLM06 and Misinformation from LLM09 to LLM07, while Improper Output Handling fell from LLM05 to LLM10. System Prompt Leakage was renamed Hidden Context Exposure and broadened to cover everything an application places in front of the model without the user seeing it.

What changed in the OWASP LLM Top 10 2026

The table below sets the 2026 order against the 2025 one, listed by 2026 rank.

2025 rank Entry 2026 rank Movement
LLM01 Prompt Injection LLM01 No change
LLM02 Sensitive Information Disclosure LLM02 No change
LLM06 Excessive Agency LLM03 Up 3
LLM03 Supply Chain LLM04 Down 1
LLM04 Data and Model Poisoning LLM05 Down 1
LLM10 Unbounded Consumption LLM06 Up 4
LLM09 Misinformation LLM07 Up 2
LLM07 Hidden Context Exposure LLM08 Down 1, renamed and widened from System Prompt Leakage
LLM08 Vector and Embedding Weaknesses LLM09 Down 1
LLM05 Improper Output Handling LLM10 Down 5

Prompt Injection and Sensitive Information Disclosure held first and second, which surprised nobody. Every other entry sits somewhere new, and the rest of this piece is about why the direction of those moves matters more than the individual rankings.

Excessive Agency and Unbounded Consumption: the climbers describe applications, not models

The two biggest climbers are the same kind of risk wearing different clothes. Excessive Agency is about what an application is permitted to do once a model is driving it: which tools it can call, which systems it can reach, how far one decision can travel before a human sees it. Unbounded Consumption is about what happens when that same application meets traffic engineered to abuse it, producing no malware and no traditional indicators, just an enormous bill. Neither is a property of the model. Both are properties of an application in production.

The biggest faller makes the same argument from the other end. Improper Output Handling dropped five places, and not because it stopped happening. It fell because it is the entry the industry already knew how to answer. Rendering untrusted output safely, refusing to execute what came back from an untrusted source, treating downstream consumers as a boundary: application security teams have been practicing that discipline for twenty years. The skill transferred. The novelty did not survive contact with people who already had the muscle.

Setting the renamed entry aside, the three entries that each slipped a place have something in common too. Supply Chain, Data and Model Poisoning, and Vector and Embedding Weaknesses are all risks you address before the application serves its first request, in procurement, in the training pipeline, in how the knowledge base was assembled and secured. They did not become less serious. They became less urgent relative to the things that only exist once the system is live.

Misinformation climbing two places fits once you ask who pays for it. A model that invents a refund policy is a quality problem in a lab and a liability problem in production, and a Canadian tribunal has already held Air Canada responsible for what its chatbot told a customer (Moffatt v. Air Canada, 2024). That entry did not move because models got worse. It moved because the consequences arrived.

Read together: the entries that climbed are the ones that only exist while the application is running. The entries that fell are handled before deployment, or handled by controls the industry already had.

From System Prompt Leakage to Hidden Context Exposure: the rename nobody is discussing

System Prompt Leakage became Hidden Context Exposure, and it is the most consequential edit in the document.

A system prompt is one specific thing: the instruction block sitting at the top of a conversation, defining the model’s role and its rules. Hidden context is everything else the application quietly places in front of the model without the user ever seeing it. Retrieved documents. Tool definitions. Prior turns held in memory. Configuration a developer assumed was private because no interface displays it.

The rename takes the entry from one field to an entire supply of runtime input, and it lands the same point the reordering makes. What the application feeds the model has become the attack surface. That is a materially bigger claim than the 2025 wording made, and any content or tooling still describing this entry as system prompt protection is now describing a fraction of it.

How to read an OWASP LLM Top 10 coverage claim, including ours

A reordering like this produces a wave of updated coverage claims, and some of them will describe protection across the whole list. Those claims are worth examining rather than accepting, and one question does most of the work: which control fires, inline, at runtime, for this specific entry?

Ask it of the entries that just fell. A poisoned model dependency arrives before a single request is served. At the moment of compromise there is no traffic to inspect, no prompt to score, no response to hold. Something does address that risk, but that something is a procurement process, a posture scan or a signed build pipeline. The same is true of a poorly governed vector store. These are real controls and they matter; they are simply not the same category of thing as a runtime control, and they usually sit with a different team and a different budget.

This is not a criticism of any product. It is the shape of the problem. Runtime protection covers runtime problems. When you meet a claim spanning all ten entries, the useful follow-up is to ask which of the ten are covered by inline enforcement, which by a scanner, which by a partner integration, and which by a policy document, and then to decide whether that composition is what you thought you were buying. A vendor who can answer that cleanly is telling you something about how they think. So is one who cannot.

Apply the same question to us. We would rather you did.

Where we stand against the 2026 order

Thales Imperva AI Application Security addresses five entries with runtime enforcement. In 2026 numbering, they are Prompt Injection (LLM01), Sensitive Information Disclosure (LLM02), Unbounded Consumption (LLM06), Hidden Context Exposure (LLM08) and Improper Output Handling (LLM10).

Two of those five moved this year, and the moves cut in opposite directions. Unbounded Consumption climbed four places, which raises the profile of a control we already ship. Improper Output Handling fell five, which lowers the profile of another one we already ship. Reporting the first without the second would be the kind of selective reading this piece is arguing against.

Two of those five are also where our next work lands, and they are connected. Hidden Context Exposure now covers tool definitions, and Excessive Agency is the question of what an application is permitted to do once a model is driving it. We are adding tool call guardrails that check whether the specific tool being called is permitted, and the tool definitions themselves are what we look at next. Today we detect and monitor tool calls. Checking them against what is allowed is the step after that, and it is better to say so plainly than to let a coverage table imply it already exists.

The other five entries need different tools, and we would rather name them than imply otherwise. Supply Chain and Data and Model Poisoning are build-time and procurement problems. Vector and Embedding Weaknesses belongs with the data security controls sitting in front of the retrieval pipeline. Misinformation is evaluation and grounding work. Excessive Agency is the one to watch: it is the entry moving fastest toward runtime, it is where the agentic controls across this whole category are heading, and at number three it is now the highest-ranked risk that most security programs have no inline answer for at all.

The list caught up with agentic AI

In a recent piece we argued that the LLM Top 10 had been the warm-up, and that the frameworks describing agentic and MCP risk had already been published while most security programs were still resourcing against the first list. The 2026 edition is that argument told from inside the framework itself.

Excessive Agency at number three is an agentic risk sitting near the top of an LLM list. Hidden Context Exposure is the retrieval and tool layer being named as attack surface. Neither entry is about a model producing text. Both are about a system taking action on the strength of what it was fed. The list has started describing applications that act, which is the same shift the newer frameworks were built for.

A practical exercise for this quarter: take the four entries that moved most, and for each one write down which control in your own environment would fire while the attack was in progress, not after it appeared in a report. The gaps in that list are what the 2026 reordering is pointing at.

Thales’s Imperva AI Application Security is purpose-built runtime protection for AI applications, agents, and the ecosystems behind them, deployable in-app, at the Imperva edge, or via API, standalone or as part of Imperva’s unified application security platform. Our white paper, Beyond the LLM Top 10, maps the agentic and MCP threat surface against the published frameworks.

Frequently asked questions about the OWASP LLM Top 10 2026

What changed in the OWASP Top 10 for LLM Applications 2026?

The 2026 edition, published by the OWASP GenAI Security Project on August 3, 2026, added and removed no categories. Eight of the ten entries changed position: Excessive Agency rose from LLM06 to LLM03, Unbounded Consumption from LLM10 to LLM06 and Misinformation from LLM09 to LLM07, while Improper Output Handling fell from LLM05 to LLM10. Prompt Injection (LLM01) and Sensitive Information Disclosure (LLM02) held their places, and System Prompt Leakage was renamed Hidden Context Exposure.

What is Hidden Context Exposure in the OWASP LLM Top 10?

Hidden Context Exposure (LLM08 in 2026) replaces System Prompt Leakage (LLM07 in 2025). It widens the entry from the system prompt alone to everything an application places in front of the model without the user seeing it: retrieved documents, tool definitions, prior turns held in memory and configuration a developer assumed was private.

Why did Excessive Agency move up to LLM03?

Excessive Agency describes what an application is permitted to do once a model is driving it: which tools it can call, which systems it can reach and how far one decision can travel before a human sees it. It climbed three places, from LLM06 to LLM03, as agentic applications that take actions moved into production.

Which OWASP LLM Top 10 risks can runtime protection address?

Runtime controls act on live traffic: prompts, responses and tool calls. Supply Chain and Data and Model Poisoning are build-time and procurement problems, Vector and Embedding Weaknesses belongs with data security controls in front of the retrieval pipeline, and Misinformation is evaluation and grounding work. When a vendor claims coverage of all ten entries, ask which are covered by inline enforcement, which by a scanner, which by a partner integration and which by a policy document.

Read more in our white paper: Beyond the LLM Top 10.

The post OWASP LLM Top 10 2026: Every Move Points the Same Direction appeared first on Blog.

  •  

Supporting ASD’s multi-factor authentication campaign: Why MFA matters more than ever

The Australian Signals Directorate (ASD) has this month issued a clear call to action through its Multi-factor authentication: Switch it on campaign, urging businesses, organisations, and individuals to enable multi-factor authentication (MFA) across their online accounts. At AWS, we strongly support this message.

As threat actors continue to target credentials through phishing, credential stuffing, and social engineering, passwords alone are no longer enough. MFA is one of the most effective security controls available. It’s a cornerstone of ASD’s Essential Eight maturity model and a recognized component of major cybersecurity frameworks worldwide. ASD’s campaign reinforces what the security community has long advocated: switching on MFA is one of the simplest and most impactful steps any organization or individual can take to protect themselves online, and we encourage all to heed ASD’s call.

How AWS enforces MFA across every account type

At AWS, we’ve put this principle into practice at scale. In June 2025, AWS Identity and Access Management (IAM) achieved comprehensive MFA enforcement for root users across all account types, a significant milestone and the first of its kind among major cloud providers. This was the culmination of a deliberate, phased security journey: beginning with requiring MFA for AWS Organizations management account root users in May 2024, expanding to standalone account root users in June 2024, introducing centralized root access management in November 2024, and completing enforcement across all account types including member accounts. MFA prevents over 99 percent of password-related attacks and is available to all AWS customers at no additional cost, with support for FIDO2 passkeys and FIDO-certified security keys for phishing-resistant authentication. This milestone reflects our ongoing commitment to secure-by-design principles, setting a high bar for our customers’ default security posture and demonstrating that organizations of any scale can, and should, make MFA the standard rather than the exception.

ASD’s Multi-factor authentication: Switch it on campaign banner

Extending MFA beyond your AWS environment

A compromised email account can be used to reset AWS passwords. A breached source control system can expose infrastructure-as-code secrets. Enable MFA on your email, collaboration tools, source control, and other services that support it. Visit the ASD Multi-factor authentication campaign page for broader guidance.

Getting started with MFA on AWS

AWS enforces MFA automatically for root users. To extend that same protection to your IAM users—the identities your team members and applications use daily—you can configure MFA individually through the AWS Management Console for IAM. To learn more, see Security best practices in IAM. For phishing-resistant authentication with FIDO2 passkeys, see Passkeys and security keys in IAM.

If you have questions or feedback about MFA on AWS, leave a comment below or reach out on AWS re:Post. If you haven’t already, heed ASD’s call and switch on MFA across every account you own.

This post was written in support of ASD’s Multi-factor authentication: Switch it on campaign. For more AWS security content, visit the AWS Security Blog.

If you have feedback about this post, submit comments in the Comments section below.


Grace Zhang

Grace Zhang

Grace is the Regulatory and Security Compliance Lead for Australia and New Zealand (ANZ), based in Sydney. She supports security assurance and compliance initiatives across the ANZ region, helping customers navigate regulatory requirements and build confidence in the security of the AWS Cloud.

  •  

Workforce AI Security Policy Management Is Now Conversational 

In this article The new Workforce AI MCP is Check Point’s own Model Context Protocol server for Workforce AI Security. Connect a compatible AI client and you can query, analyze, and manage your employee AI usage policy in natural language instead of working through filters, screens, and individual rule checks. →ask plain questions such as which rule applies to a given user and application, or whether a rule is shadowed by a higher-priority one →work across users, managed assets, GenAI application usage, DLP data types, and agent and MCP activity in a single conversation →create and update rules by request […]

The post Workforce AI Security Policy Management Is Now Conversational  appeared first on Check Point Blog.

  •  

How a hidden Wi-Fi network name can give away your data to strangers | Kaspersky official blog

For more than two decades now, setting up a home router has meant going through the same old routine: pick a Wi-Fi band, name your network, choose a security type, and set a password. After you type in your network name, you often see an option next to it to hide the network name — sometimes labeled hide SSID, or simply hidden or closed network. If you choose this option, the network you create won’t show up automatically in the list of available Wi-Fi networks on any smartphone, computer, or smart-home device — you need to type in the correct network name by hand. Only then will the device be able to find that network and connect to it. At first glance, hiding your wireless network’s name might seem like a smart precaution: keeping neighbors or passersby from hacking into your Wi-Fi since they simply can’t see it. But in fact things work differently: all your devices will give away the hidden network — and not just at home either.

How devices connect to Wi-Fi

Every Wi-Fi access point broadcasts a short data packet roughly 10 times a second so your smartphone or computer can show you a list of nearby networks’ names, like JohnWiFi, TommyNet, CafeDeArts_Guest, or other, creative variants. This packet contains (i) the network’s name (Service Set Identifier, or SSID), (ii) a unique identifier for the access point (Basic Service Set Identifier, or BSSID), and (iii) details about the radio channel the network uses. This info helps devices (i) pick the best network to connect to, and (ii) automatically join networks they already know; accordingly, none of the data in that packet is encrypted. Hidden networks also broadcast these advertising packets; they just leave the SSID field blank. This method of finding networks is called passive because a Wi-Fi client, like, say, your smartphone, just needs to listen to the airwaves to spot nearby access points.

On top of that, the client can scan for Wi-Fi networks on its own, which is known as active discovery. Your smartphone or computer is constantly broadcasting the names of Wi-Fi networks it knows and would like to connect to. If one of those networks happens to be nearby, the access point answers back, and the connection is made.

Active discovery can sometimes help save your smartphone’s battery, and it’s indispensable when you’re working with hidden networks. Discovering a hidden network and connecting to it becomes a two-step process. First, the smartphone “hears” that there’s a Wi-Fi access point nearby with a hidden network name. It then tries to reach that network by broadcasting the names (SSIDs) it already knows — either hidden networks it’s connected to before, or the name the user typed in when first connecting to a hidden network. If the name matches, the router responds, and the connection goes through.

A hidden network name (SSID) doesn’t actually hide your Wi-Fi network

The regular list of available Wi-Fi networks on your smartphone or computer won’t show networks that don’t broadcast a public SSID. But any specialized Wi-Fi scanning software can spot them easily — it just won’t show their names. And hidden networks are still easy to identify and tell apart thanks to each router’s unique BSSID.

So hiding a Wi-Fi network’s name doesn’t make it truly invisible, and it won’t protect you from cybercriminals. It’s worth noting that any large-scale analysis, such as mapping the geographic locations of Wi-Fi networks, relies on BSSIDs, not SSIDs. Besides the huge databases kept by Apple and Google, there are public access-point-mapping projects too, like WiGLE.

If someone wants to break into a network at a specific location, specialized software lets them find out its SSID just by waiting for one of the legitimate clients to connect and listening in on the active discovery session. From there, they can connect to that Wi-Fi network — provided it uses a weak enough security protocol.

Your devices leak hidden Wi-Fi network names and personal data

The main drawback of a hidden SSID is that smartphones and computers have to broadcast it before they can connect to the wireless network. And they do this everywhere — not just near the specific access point in question. As soon as any network with a hidden name shows up within signal range, the client attempts to connect, and during that attempt it broadcasts the names of every hidden network it knows. And this broadcast isn’t encrypted, which means anyone nearby can pick up the data being transmitted.

In 2021, researchers at the University of Hamburg ran an experiment collecting radio signal data on a busy street. In just three one-hour listening sessions, they gathered 252 000 Wi-Fi connection requests from passersby’s smartphones. Of those, 23% contained the SSID of a network the smartphone would have preferred to connect to.

And that’s where a factor few people think about comes into play: the network’s name itself. Twelve percent of the SSIDs found were long numeric strings that looked a lot like passwords. So, once someone knows the SSID and BSSID, they can look up the BSSID in a service like WiGLE and find the access point’s real-world address. Once there, an attacker can try to use such a string as both the SSID and the password to connect — with a good chance of success. The researchers’ sample also included 106 SSIDs containing a first and/or last name, 92 SSIDs that pointed to a home address, and three that revealed an email address.

Given all this, it’s no surprise that Apple and Asus recommend against using the hidden SSID feature.

Other drawbacks of hiding your Wi-Fi network

Beyond the data leak issues, hidden SSID technology — a holdover from early Wi-Fi versions — also hurts the performance of modern versions of the radio protocol. In the 6GHz band, searching for a hidden Wi-Fi network across 59 possible channels becomes noisy and power-hungry: the client has to run through every option and send a lot of requests. As a result, performance drops for all nearby Wi-Fi networks in the 6GHz band, and the client itself burns through battery power sending out all those requests.

Asus also points out that Windows devices may tend to connect to visible networks first — even if a network with a hidden SSID is available and marked as preferred.

When a hidden SSID actually makes sense

There aren’t many scenarios where hiding your network name is genuinely useful. For example, if a router is meant for a small group of people but is installed in a very crowded location, a hidden SSID can cut down on the number of connection attempts and ease the load on the router. But keep in mind that this boosts performance, not security — and only slightly at that.

Another similar case is a technical Wi-Fi network for a limited number of fixed devices — like a network of security cameras or smart home gadgets. These devices always stay in the same place, so whenever they try to connect to their assigned Wi-Fi, they find it right away, and no data leaks out — unless an attacker is actually listening in on the radio signal near the router. At the same time, outsiders are less likely to try connecting to such a network.

How to make your Wi-Fi more secure

To protect your Wi-Fi network from wireless hackers, don’t hide the SSID: instead, use the modern WPA3 security protocol along with a long password. Attackers can intercept data over the air and then try to crack the password with brute force, so a strong Wi-Fi password should be at least 20 characters long. The easiest way to generate and store such long, hard-to-crack passwords is with a password manager that syncs across your devices; that way they’re always at hand — no matter which gadget you’re using.

If some of your older devices don’t support WPA3, it’s fine to use WPA2 with protected management frames (PMF) turned on, which guard against many types of attacks on Wi-Fi networks.

You should also make sure Wi-Fi Protected Setup (WPS) is turned off, since it essentially replaces your password with an easy-to-guess PIN code.

To quickly spot unknown devices connected to your Wi-Fi network, use Smart Home Monitor in Kaspersky Premium.

As for the network name, instead of hiding it, pick one that doesn’t reveal your name, address, or any other personal details. It’s also worth avoiding default network names like ISPName-XXXX or dlink, but for a different reason: generic names like these can confuse you and your guests alike. If you don’t want your access point to show up on Wi-Fi geolocation maps from Apple, Google, and other providers, you can add the suffix _nomap to the end of your network name, but there’s no guarantee it will actually work.

Apart from protecting your Wi-Fi, make sure your router is configured securely overall. First and foremost, that means giving it a long, unique admin password, and keeping it updated with the manufacturer’s latest firmware. And if you have a bit more time, you could even boost your Wi-Fi performance.

How Wi-Fi networks get hacked, and how to protect them:

  •  

Security Advisory – Action Required – Active Exploitation of CVE-2026-85102 and a Management Pre-Authentication Vulnerability CVE-2026-93616

As part of Check Point’s Frontier AI Readiness Program, we continue to release Jumbo hotfixes with security fixes and hardening improvements for our Firewall and Management products. This advisory addresses the active exploitation described below, and the immediate steps customers should take to protect affected systems. Check Point Research has identified active exploitation of two vulnerabilities affecting Security Gateway and Security Management: A fix for CVE-2026-85102 has been available since September 9, and customers who have applied it are already protected. CVE-2026-93616 is a newly discovered zero-day vulnerability in Security Management, and a fix is available now as part of […]

The post Security Advisory – Action Required – Active Exploitation of CVE-2026-85102 and a Management Pre-Authentication Vulnerability CVE-2026-93616 appeared first on Check Point Blog.

  •  

Introducing Unit 42 Continuous Frontier AI Defense

Cybersecurity is in the middle of a generational shift. AI has disrupted a 30-year balance of power between defenders and adversaries.

Armed with agentic AI tools and open-weight models stripped of safety guardrails, threat actors are discovering, validating, and chaining exposures at machine speed. In a recent Unit 42 investigation, the attacker used more than 50 MITRE ATT&CK techniques to reduce weeks of methodical intrusion tradecraft into less than 10 hours—97% faster than a skilled red team could have done. Time-to-exfiltration has compressed to under an hour in real-world attacks. And when new CVEs are publicly disclosed, automated adversary scanners are weaponizing them within 15 minutes.

Defending at human speed is no longer viable. Organizations must close years of accumulated exposure while securing the AI they are rapidly adopting. That demands action on five fronts: continuously find and fix vulnerabilities, reduce exposure, secure AI infrastructure, unify attack prevention, and automate detection and response at machine speed.

Today, we are announcing Unit 42 Continuous Frontier AI Defense to put the first two priorities into practice. Powered by Anthropic's Mythos models and OpenAI's latest GPT cyber models, this always-on, agentic service combines our offensive security experts with proprietary multi-model harnesses to discover vulnerabilities, validate real-world exploitability, and accelerate remediation across applications, identities, cloud infrastructure, and network assets.

Led by our offensive security experts, this service discovers, validates and remediates exposures before they can be exploited. We use proprietary AI harnesses and gated capability models—powerful models restricted from public use—to discover vulnerabilities, prove real-world exploitability, and accelerate remediation across applications, identities, cloud infrastructure, and network assets as an organization’s environment changes.

Continuous Frontier AI Defense builds on Unit 42’s Frontier AI Defense, which launched in April and introduced Frontier AI Exposure Analysis, a point-in-time exposure analysis, and a security blueprint that benchmarks current capabilities to help organizations modernize their cybersecurity systems. In August, Unit 42 expanded the list of frontier AI models to include  OpenAI’s GPT-5.6-Cyber and Anthropic's Claude Mythos 5, giving organizations access to additional AI capabilities.

A Single AI Model Is Not a Security Strategy

Frontier models are powerful, but no single AI model is a cybersecurity silver bullet and the models require equally powerful AI scanning harnesses.

Unit 42 research evaluation of model performance across enterprise codebases and live environments revealed two stark operational realities:

  • Coverage caps: No single AI model catches more than 40% of vulnerabilities in a complex environment.
  • Visibility: Leading cyber models such as Anthropic Claude Mythos 5 and OpenAI GPT-5.6-Cyber have less than 10% overlap in the exposures they identify.

To solve the single model gaps, Continuous Frontier AI Defense runs on proprietary multi-model harnesses. These harnesses act as an intelligent orchestration layer, routing specific offensive testing tasks to the model best suited for the job. This approach aligns model strengths, eliminates individual gaps, and keeps compute spend economical.

We combine these frontier models with Unit 42 threat intelligence, and frontline security expertise to turn raw vulnerability data into verified, actionable protection. Zero Data Retention (ZDR) architectures protect enterprise source code and telemetry, so customer data is never retained or used to train public models.

What Happens When AI Meets Real Enterprise Architecture

We did not build this service on theoretical assumptions. We built and validated it internally  across Palo Alto Networks and across more than 100 customer engagements.

During our internal deployment, continuous Mythos-based scanning achieved over a year’s worth of traditional penetration testing results in just three weeks. The harness identified 3.2 times more high and critical vulnerabilities per product than legacy testing methods, and helped engineering teams cut mean time to remediate by 51%.

When we executed the service across customer environments, the frontline data delivered a clear warning:

  • Hidden exposures: In third-party applications, two out of three validated exposures had no known CVE. Vulnerability-only scanners will never see them.
  • High severity: 37% of identified exposures rated high or critical in severity.
  • Chained attack paths: Flaws rarely existed in isolation. In one financial sector engagement, our harness identified a sequence of individually minor flaws: an application payment link that failed to re-verify identity, a skipped one-time password check, and a session routing flaw. Chained together, an attacker could achieve complete account takeover and payment fraud without any victim action.

Moving from Discovery to Validated Protection

Finding weaknesses without fixing them only creates noise. And, security teams do not lack findings; they already have more alerts than they can act on. The bigger challenge is knowing which weaknesses an attacker can actually exploit and chain into a viable path to compromise, and then remediating them.

Unit 42 Continuous Frontier AI Defense translates findings directly into risk reduction:

  • Continuous Testing Engine: Provides a full-estate baseline scan followed by always-on testing as an organization’s environment changes.
  • Multi-Model AI Harness: Unit 42 deploys proprietary multi-model harnesses, the software architecture to route work to the model best suited for the task, improving efficacy and coverage while managing the cost of frontier AI at scale.
  • Leading Cyber Models: The harnesses are built around gated capability models, including Anthropic Claude Mythos 5 and OpenAI GPT-5.6-Cyber, as well as open weight models. 
  • Advanced Adversary Simulation: Proves real-world exploitability by validating end-to-end attack paths across first- and third-party web apps, APIs, cloud infrastructure, source code repositories, and network assets.
  • Accelerated Remediation: Delivers actionable and prioritized fixes, code-level guidance, and virtual patch recommendations. To implement virtual patches before vulnerabilities are publicly disclosed or official patches exist, organizations can pair this with Frontier Virtual Patching. 

Unit 42 Continuous Frontier AI Defense is available worldwide today on an annual subscription basis. Register for our upcoming virtual Threat Briefing to see how we apply Frontier AI, our proprietary multi-model harness, and offensive security expertise to protect Palo Alto Networks and our customers.

To learn more about Unit 42 Continuous Frontier AI Defense, register for the upcoming Virtual Threat Briefing here.

The post Introducing Unit 42 Continuous Frontier AI Defense appeared first on Palo Alto Networks Blog.

  •  

Transforming Bedrock Guardrails events into OCSF with CloudWatch

Security teams investigating possible AI-related security events need guardrail intervention data alongside their existing security telemetry. When a guardrail identifies or blocks a prompt injection attempt or redacts sensitive data, that intervention carries additional investigative value comparable to a failed sign-in or a network intrusion alert. AWS Bedrock publishes this telemetry to AWS CloudWatch metrics and model invocation logs for operational monitoring.

In this post, I show you how to transform AWS Bedrock Guardrails intervention events into structured Open Cybersecurity Schema Framework (OCSF) Detection Finding records and land them in the CloudWatch unified data store. Launched in December 2025, the unified data store consolidates operational, security, and compliance data from AWS services and third-party sources into a single platform. Security operations center (SOC) and threat analysts can query guardrail events alongside identity, network, and endpoint data, including AWS CloudTrail and AWS Virtual Private Cloud (AWS VPC) Flow Logs, using AWS Athena or CloudWatch Logs Insights.

Use case

Consider an organization deploying AWS Bedrock across many applications, with guardrails applied as a governance control. The guardrails detect and block several categories of activity: harmful content, off-topic queries, sensitive information such as personally identifiable information (PII), and prompt injection attempts. Each time a guardrail intervenes, it produces a signal the security team wants to investigate alongside the rest of its telemetry.

Without a consolidation layer, guardrail interventions stay siloed as per-AWS Region CloudWatch metrics and entries in raw model invocation logs, separate from the identity, network, and audit data the security team already relies on. The CloudWatch unified data store is built to remove this kind of silo: it consolidates operational and security data across accounts and Regions into one store. Routing normalized guardrail records into it is what makes them correlatable with the rest of your security telemetry. To investigate effectively, the team needs to answer questions that span multiple data sources:

  • Identify which user accounts trigger the most guardrail interventions, and whether those same accounts also show unusual AWS Identity and Access Management (IAM) activity such as failed API calls or privilege changes. A spike in prompt injection blocks from a role that’s also generating access-denied events is a stronger signal than either on its own.
  • Determine whether prompt injection attempts correlate with specific source IP addresses that also appear in VPC Flow Logs, which helps distinguish a single misbehaving client from a coordinated pattern across the environment.
  • Track the trend of guardrail violations across the organization and compare it against a baseline from 30 days ago, so the team can tell routine policy noise apart from an emerging change in attacker behavior or a misconfigured application.

AWS GuardDuty already helps here: its AI Protection feature analyzes CloudTrail data events from AWS Bedrock and produces managed threat findings, including a direct prompt injection finding and anomalous model invocation findings. GuardDuty AI Protection is a complementary managed detection layer for AWS Bedrock activity. The pipeline in this post works alongside it: it captures the raw guardrail intervention records themselves, normalizes them to OCSF, and lands them in the unified data store so you can run your own cross-source correlation and long-term trend analysis alongside GuardDuty findings, CloudTrail, and VPC Flow Logs.

Guardrail traces arrive as JSON embedded in the AWS Bedrock model invocation logs, in an AWS Bedrock-specific shape rather than a normalized security schema. After the pipeline transforms them to OCSF and ingests them into the CloudWatch unified data store, a single Athena query answers all three questions, because guardrail findings then share the same field structure as other security sources and sit in the same catalog as AWS CloudTrail events and VPC Flow Logs.

Solution overview

At a high level, the solution captures guardrail intervention events from AWS Bedrock model invocation logs, transforms them into OCSF Detection Finding records with an AWS Lambda function, and lands them in the CloudWatch unified data store, where SOC analysts query them with Athena or CloudWatch Logs Insights. The CloudWatch unified data store provides Apache Iceberg-compatible access through AWS S3 Tables, CloudWatch Logs Insights queries, and, for supported sources, built-in OCSF normalization at ingestion.

Why a custom transform step

CloudWatch offers native OCSF conversion through the ParseToOCSF log transformation processor for specific AWS log sources. As of this writing, that processor supports five AWS log sources: CloudTrail, AWS Route 53 Resolver, VPC Flow Logs, AWS EKS audit logs, and AWS WAF. AWS Bedrock Guardrails isn’t one of the sources that ParseToOCSF supports, so guardrail traces aren’t converted to OCSF automatically.

Guardrail traces also need transformation logic that ingestion-time processors don’t provide. A single model invocation log can contain multiple guardrail assessments (for example, a content policy filter and a sensitive information policy match in one request), and the transform step splits that one log entry into one OCSF Detection Finding per assessment rather than a single combined record. This one-to-many expansion, combined with conditional severity assignment based on policy type, is application logic rather than field normalization. For these two reasons, this solution uses a dedicated transform step to produce OCSF records, then uses built-in CloudWatch mechanisms for enrichment, storage, centralization, and query.

This solution captures AWS Bedrock model invocation logs containing guardrail trace data, filters for intervention events, transforms them into OCSF Detection Finding records (class_uid 2004), and writes the structured records to a CloudWatch Logs log group that is associated with AWS S3 Tables through the CloudWatch unified data store managed integration. Guardrail interventions are detection events: the guardrail detected and blocked prohibited content, so OCSF class 2004 (Detection Finding) under the Findings category is the appropriate classification.

How a source’s records are stored depends on whether it’s a vended source or a custom source. For the five vended sources that ParseToOCSF supports, the unified data store produces individual typed OCSF columns. For any custom source, including AWS Bedrock Guardrails in this solution, records land in the associated S3 Tables table as OCSF JSON in a single managed cwl__message column rather than as typed columns. This is a property of custom sources in general, not specific to AWS Bedrock. You read the OCSF fields at query time with Athena json_extract functions, and you can correlate them with the vended sources that share the same catalog. This post shows that query pattern.

The pipeline supports multiple AWS Bedrock event types by changing the filter pattern and OCSF mapping. This post demonstrates the guardrail interventions row:

Bedrock event source OCSF event class class_uid
Guardrail interventions (this post) DETECTION_FINDING 2004
Model invocation API calls API_ACTIVITY 6003
Agent guardrail traces DETECTION_FINDING 2004
Token consumption anomalies DETECTION_FINDING 2004

Architecture

The following diagram shows the end-to-end pipeline from guardrail intervention to CloudWatch unified data store ingestion. It shows the flow within a single account for clarity. In an organization, you deploy this transform pipeline in each workload account and use CloudWatch Logs centralization to bring the OCSF output into one central account, so you query organization-wide without standing up the query layer per account or per Region. The Multi-account deployment section later in this post covers this pattern.

Figure 1: End-to-end pipeline from guardrail intervention to CloudWatch unified data store ingestion

Figure 1: End-to-end pipeline from guardrail intervention to CloudWatch unified data store ingestion

The data flow consists of the following steps:

  1. An application calls AWS Bedrock (InvokeModel or Converse API) with a guardrail attached.
  2. AWS Bedrock evaluates the guardrail and logs the invocation, including guardrail trace data, to a CloudWatch Logs log group using model invocation logging. A subscription filter matches log entries where the guardrail action is INTERVENED (blocked or masked content).
  3. The subscription filter delivers matching records to a Lambda function (OCSF Transform). This step performs the custom transformation that native OCSF conversion doesn’t cover for AWS Bedrock, expanding each guardrail assessment into its own OCSF Detection Finding.
  4. The Lambda function writes the OCSF JSON records to a dedicated CloudWatch Logs log group and sets contextual fields (account ID and Region) on each record during transformation. If the Lambda function fails to process a record, the message routes to an AWS Simple Queue Service (AWS SQS) dead-letter queue for later analysis and redrive.
  5. The destination log group is associated with AWS S3 Tables through the CloudWatch unified data store managed integration, so the unified data store stores the OCSF records as an Apache Iceberg table. Because AWS Bedrock Guardrails is a custom source, each record is stored as OCSF JSON in a managed cwl__message column.
  6. SOC analysts query guardrail intervention data with Athena, using json_extract to read the OCSF fields, and correlate it with vended security sources (CloudTrail, VPC Flow Logs) that share the same catalog. For real-time operational queries, analysts can also query the destination log group directly with CloudWatch Logs Insights.

OCSF mapping

The following table shows how AWS Bedrock Guardrails intervention fields map to OCSF Detection Finding (class_uid 2004) attributes.

OCSF field Source Example value
class_uid Static 2004 (Detection Finding)
category_uid Static 2 (Findings)
severity_id Derived from policy type 3 (Medium) for content/topic; 4 (High) for prompt injection
activity_id Static 1 (Create)
time Invocation log timestamp 1721001600000
cloud.provider Static AWS
cloud.region Set by the transform function us-east-1
cloud.account.uid Set by the transform function 123456789012
actor.user.uid Invocation log identity.arn arn:aws:sts::123456789012:assumed-role/AppRole/session
finding_info.title Derived from policy type ContentPolicy Intervention
finding_info.desc Guardrail trace action/topic Blocked: HATE content detected on INPUT
resource.uid Model ARN arn:aws:bedrock:us-east-1::foundation-model/anthropic.claude-sonnet-4-20250514-v1:0
resource.type Static AwsBedrock:Model
metadata.product.name Static Amazon Bedrock Guardrails
metadata.product.vendor_name Static AWS
metadata.version Static 1.3.0
unmapped.guardrail_id Guardrail trace guardrailId my-content-guardrail
unmapped.guardrail_arn Guardrail trace guardrailArn arn:aws:bedrock:us-east-1:123456789012:guardrail/abc123
unmapped.guardrail_version Guardrail trace guardrailVersion 3
unmapped.guardrail_content_source Guardrail trace INPUT or OUTPUT
unmapped.guardrail_policy_type Guardrail trace ContentPolicy, TopicPolicy, SensitiveInformationPolicy, WordPolicy, ContextualGroundingPolicy, PromptAttack

Prerequisites

The following prerequisites are needed to deploy the reference implementation. Before you begin, clone the repository:

git clone https://github.com/aws-samples/sample-bedrock-guardrails-cloudwatch.git
cd sample-bedrock-guardrails-cloudwatch

Verify you have the following:

Implementation

The reference implementation deploys two CloudFormation stacks: TransformPipelineStack and MonitoringStack. The following commands deploy the stacks in dependency order:

cdk deploy TransformPipelineStack \
  -c destination_log_group=/aws/cloudwatch-uds/bedrock-guardrails-ocsf

cdk deploy MonitoringStack \
  -c alarm_email=your-team@example.com

Or deploy both stacks at once:

cdk deploy --all \
  -c destination_log_group=/aws/cloudwatch-uds/bedrock-guardrails-ocsf \
  -c alarm_email=your-team@example.com

Enable model invocation logging

Model invocation logging captures the guardrail trace data you need. Turn on full request and response logging to a CloudWatch Logs log group and configure textDataDeliveryEnabled to capture the text bodies that include the guardrail trace output when a guardrail is attached to the invocation. The following AWS Command Line Interface (AWS CLI) command enables it:

aws bedrock put-model-invocation-logging-configuration \
  --logging-config '{
    "cloudWatchConfig": {
      "logGroupName": "/aws/bedrock/model-invocation-logs",
      "roleArn": "arn:aws:iam::123456789012:role/BedrockLoggingRole"
    },
    "textDataDeliveryEnabled": true
  }'

Because logging is an account-level prerequisite rather than part of the pipeline, the CDK stacks don’t manage it. Enable it once for each account before deploying.

Deploying the transform pipeline

The TransformPipelineStack deploys the Lambda function, subscription filter, destination log group, and dead-letter queue.

  • Create the subscription filter: The stack creates a CloudWatch Logs subscription filter on your model invocation log group with a filter pattern that matches guardrail interventions. This captures only the events where a guardrail blocked or modified content, not the successful pass-through events, which reduces Lambda invocations and cost.
  • Transform to OCSF: The Lambda function parses each CloudWatch Logs event and produces one OCSF Detection Finding record (class_uid 2004) per guardrail assessment in the trace. The transformation maps guardrail trace fields to OCSF attributes as described in the OCSF mapping table and sets contextual fields such as account ID and Region. Severity is set to High for prompt injection interventions and Medium for content, topic, or sensitive information interventions. The records contain structural metadata only; no prompt or response content is included.
  • Dead-letter queue: If the Lambda function fails to process a record, the message routes to an AWS SQS dead-letter queue with error metadata (error type, message, timestamp) for investigation and redrive.

Configure S3 Tables integration

To make the OCSF records queryable through Athena, associate the destination log group with AWS S3 Tables. This is a two-step managed setup: create an S3 Tables integration, then associate the log group as a data source. The integration delivers to the managed aws-cloudwatch table bucket at no additional storage charge.

  1. Tag the destination log group so the unified data store recognizes it as a data source. Use the tags cw:datasource:name (for example, bedrock_guardrails) and cw:datasource:type (for example, ocsf). The generated table name joins the two tag values with a double underscore, so these example tags produce a table named bedrock_guardrails__ocsf.
  2. Create the integration with CreateS3TableIntegration (CloudWatch Observability Admin), supplying an encryption configuration and an IAM role. This returns an integration AWS Resource Name (ARN).
  3. Associate the data source with AssociateSourceToS3TableIntegration (CloudWatch Logs), passing the integration ARN and the dataSource name and type from step 1.

The reference implementation performs steps 2 and 3 with the CloudFormation resource AWS::ObservabilityAdmin::S3TableIntegration and a custom resource that calls AssociateSourceToS3TableIntegration, so cdk deploy sets up the association for you.

After association, the OCSF records become available as an Apache Iceberg table in the managed catalog, at the path "s3tablescatalog/aws-cloudwatch"."logs"."bedrock_guardrails__ocsf". You can query it with Athena, AWS Redshift, or any Iceberg-compatible tool.

As noted in the solution overview, AWS Bedrock Guardrails is a custom source, so each record is stored as OCSF JSON in a managed cwl__message column. You read the fields at query time with the Athena json_extract_scalar function, as shown in the next section, and correlate against vended sources such as CloudTrail in the same catalog.

Enable analytics access

The association delivers records to the managed table, but analytics engines can’t read them until you enable the AWS S3 Tables analytics integration and grant read permissions. Complete these steps once in each Region:

  1. In the AWS S3 console, choose Table buckets, then choose Enable integration. The first time you do this in a Region, AWS S3 creates a service role that lets AWS Lake Formation federate access to your tables in the AWS Glue Data Catalog. This is what makes the s3tablescatalog catalog visible to Athena.
  2. In the Lake Formation console, under Data lake permissions, choose Grant, and grant Select and Describe on the aws-cloudwatch table bucket (and the bedrock_guardrails__ocsf table) to each IAM principal that runs queries, such as your SOC analyst roles. Without this grant, Athena queries return an access denied error even when the IAM policy allows Athena.
  3. In the Athena query editor, choose the AWS S3 Tables catalog from the data source list, and select the logs database.

Deploy the monitoring stack

The MonitoringStack creates a CloudWatch dashboard and alarms for pipeline health. The dashboard includes widgets for intervention count by policy type, transform errors, Lambda duration, and dead-letter queue depth. Alarms notify your team when the error rate exceeds 5 percent, the dead-letter queue depth exceeds 0, or p99 Lambda duration exceeds 10 seconds. Notifications are sent through AWS Simple Notification Service (AWS SNS).

Query interventions

After deployment, guardrail interventions are available through two query paths. Use the one that matches your investigation:

  • Athena (through AWS S3 Tables) for cross-source correlation and historical analysis. Athena joins the OCSF guardrail records with vended OCSF sources in the unified data store (such as CloudTrail and VPC Flow Logs) over long time ranges. Because AWS Bedrock Guardrails is a custom source, its OCSF fields live inside the cwl__message column, so you read them with json_extract_scalar. Use Athena when you need to join guardrail findings against other security data or run trend analysis across weeks or months.
  • CloudWatch Logs Insights for real-time, operational queries against the destination log group. Use Logs Insights when you need results in seconds on recent data, without a table join, such as during an active investigation.

The Athena queries in this section run against the managed table "s3tablescatalog/aws-cloudwatch"."logs"."bedrock_guardrails__ocsf". For readability, the examples reference it as bedrock_guardrails_ocsf after selecting the s3tablescatalog/aws-cloudwatch catalog and logs database in the Athena query editor.

Correlate with IAM activity in Athena

The following example identifies users who trigger both prompt injection interventions and failed CloudTrail activity. The guardrail side extracts fields from cwl__message; the CloudTrail side is a vended source with typed OCSF columns.

WITH guardrail_violators AS (
    SELECT json_extract_scalar(cwl__message, '$.actor.user.uid') AS user_arn,
           COUNT(*) AS violation_count
    FROM bedrock_guardrails_ocsf
    WHERE json_extract_scalar(cwl__message, '$.unmapped.guardrail_policy_type') = 'PromptAttack'
    GROUP BY json_extract_scalar(cwl__message, '$.actor.user.uid')
),
iam_failures AS (
    SELECT "actor.user.uid" AS user_arn, COUNT(*) AS failure_count
    FROM aws_cloudtrail__management
    WHERE "status_id" = 2
    GROUP BY "actor.user.uid"
)
SELECT g.user_arn, g.violation_count, i.failure_count
FROM guardrail_violators g
JOIN iam_failures i ON g.user_arn = i.user_arn
ORDER BY g.violation_count DESC;

You can also track violation trends by policy type over time to establish baselines and detect spikes:

SELECT date_trunc('day', from_unixtime(
         cast(json_extract_scalar(cwl__message, '$.time') as bigint) / 1000)) AS event_day,
       json_extract_scalar(cwl__message, '$.unmapped.guardrail_policy_type') AS policy_type,
       COUNT(*) AS violation_count
FROM bedrock_guardrails_ocsf
GROUP BY 1, 2
ORDER BY event_day, violation_count DESC;

If you run these correlation queries frequently, you can materialize the extracted OCSF fields into a typed table with CREATE TABLE AS SELECT (CTAS) and refresh it on a schedule. Queries against the materialized table use plain column names instead of json_extract_scalar, which keeps recurring dashboards and joins concise.

Real-time queries in CloudWatch Logs Insights

For operational queries on recent data without a table join, query the destination log group directly in CloudWatch Logs Insights:

fields @timestamp, severity, finding_info.title, actor.user.uid, unmapped.guardrail_policy_type
| filter class_uid = 2004
| filter unmapped.guardrail_policy_type = "PromptAttack"
| stats count() as attack_count by actor.user.uid
| sort attack_count desc
| limit 10

This query returns results in seconds on recently ingested records.

Multi-account deployment

For organizations running AWS Bedrock across multiple accounts, the recommended pattern is to transform locally and centralize the OCSF output, rather than replicating raw invocation logs and transforming centrally.

Deploy the subscription filter and transform pipeline in each workload account where model invocation logging is enabled. Each account produces OCSF records in its own destination log group. Then use CloudWatch Logs centralization to replicate those OCSF records into a central logging account automatically. Centralization integrates with AWS Organizations and picks up new accounts as they join, and you create the AWS S3 Tables integration one time in the central account (rather than in every workload account) for organization-wide querying.

Transforming in each workload account keeps the guardrail trace parsing close to the source, avoids moving raw invocation logs (which might contain prompt and response text) across account boundaries, and centralizes only the sanitized OCSF findings. If your organization prefers to keep transformation logic in one place, an alternative is to centralize the raw invocation logs first and run a single transform pipeline in the logging account; this concentrates the parsing logic but moves more data, including request and response content, between accounts.

Clean up

To avoid ongoing charges, destroy the stacks in reverse dependency order:

cdk destroy MonitoringStack --force
cdk destroy TransformPipelineStack --force

Conclusion

In this post, you learned how to transform AWS Bedrock Guardrails intervention events into OCSF Detection Finding records and ingest them into the CloudWatch unified data store. This integration gives SOC teams structured guardrail telemetry that correlates with CloudTrail, VPC Flow Logs, and the other security sources already available in CloudWatch. Because guardrail interventions are a custom source, their OCSF fields are stored as JSON and read with Athena json_extract functions, so you can join them with the vended OCSF sources that share the same catalog.

The pipeline filters for intervention events only, which keeps costs low while capturing the security-relevant signals. Athena over AWS S3 Tables provides cross-source correlation and historical analysis, and CloudWatch Logs Insights provides real-time operational queries.

Clone the reference implementation and adapt the OCSF mapping and subscription filter to your guardrail configuration. To extend the pipeline, apply the same transform pattern to agent guardrail traces, which map to the same OCSF Detection Finding class.

References

If you have feedback about this post, submit comments in the Comments section below.


Dhananjay Karanjkar

Dhananjay Karanjkar

Dhananjay is a Senior Lead Consultant at AWS Professional Services, specializing in agentic AI systems, multi-agent orchestration, and generative AI security. He holds two US patents and serves as a Responsible AI Champion, with a background spanning financial services, enterprise consulting, and enterprise-scale AI delivery. When not architecting AI solutions, he trains for triathlons, paints oil portraits, and is an avid reader.

  •  

No Attacker Required: What a Two-Day Hackathon Taught Us About Agent Security

In this article Nineteen Check Point AI Security R&D teams spent two days on one prompt: build the demo customers would ask to see twice. Three of the results tell a single story about securing AI agents, and none of it starts with an attacker. →an autonomous agent took dangerous actions with no attacker involved, it simply hit a wall and improvised →a single poisoned file in a code repository turned a popular coding agent into a data exfiltration channel →questioning an off-track agent prevented as many attacks as blocking it, and completed more legitimate work →the lesson for anyone […]

The post No Attacker Required: What a Two-Day Hackathon Taught Us About Agent Security appeared first on Check Point Blog.

  •  

Defining the Standard for AI Security

Palo Alto Networks Named a Market Shaper in 2026 September Gartner® Emerging Market Quadrant for AI Application Security — Established Vendors.

When we set out to solve AI security, we knew it was an audacious challenge to take on. Securing AI Coding, which I wrote about last week, is one example of how we are tackling this multidimensional problem. 

Today marks yet another major milestone in that journey. I am so proud to share that Palo Alto Networks has been recognized as a ‘Market Shaper’ in the September 2026 Gartner® Emerging Market Quadrant for AI Application Security – Established Vendors. 


To us, this recognition reflects our core commitment to help organizations address all emerging AI use cases: securing AI coding, enterprise AI applications and governing autonomous agents, through a unified approach. 

What Modern Enterprise AI Security Requires

Artificial intelligence is fundamentally changing how enterprise software is built, how digital experiences are delivered, and how work gets done.

In the report, Gartner defines ‘Market Shapers' as those that are building comprehensive platforms by acquiring innovative companies and introducing centralized management tools for AI workflows. They are also expanding traditional security capabilities into broader agent-based controls, using advanced access control and runtime monitoring to secure agentic actions.

We believe our position as a ‘Market Shaper’ reflects four core capabilities we provide through our AI Security Platform, Prisma AIRS for effective enterprise AI security today:

  • Secure AI Coding: Gain visibility into coding agents, extensions, skills, models and MCP servers, assess the artifacts they rely on, and establish controls over data, identity and agent actions. 
  • Secure Enterprise AI Applications: Reduce risk across the AI application lifecycle, from models and components to testing and runtime interactions. This helps organizations build and deploy AI faster while safeguarding sensitive data and business-critical applications.
  • Govern Agent Actions: Maintain control and accountability as autonomous agents interact with enterprise data, tools and systems. Clear identities and permissions help reduce unauthorized activity and contain unintended behavior.
  • Accelerate AI Adoption Without Losing Control: Scale AI with consistent governance across coding, enterprise applications and autonomous agents. Maintain centralized control over access, usage and spend, through an AI Gateway. 

Defending the AI Frontier Requires a Platform

AI coding agents, enterprise AI applications and autonomous agents may look like separate security problems. In practice, they increasingly depend on the same models, data, identities, tools and infrastructure. Attempting to secure each one with its own isolated point product only creates fragmentation at the exact point when enterprises need greater visibility and control

This is why we built Prisma AIRS, as the comprehensive AI security platform. It gives security teams a unified approach to discover AI, assess risk, protect runtime interactions, control agent identity and access, and govern connections to enterprise data and systems.

The goal is not to slow AI adoption. It is to give developers and business teams the freedom to use AI while giving security teams the visibility and control they need.

Read the research report to learn more: Gartner® Emerging Market Quadrant for AI Application Security – Established Vendors, September 2026.

Ready to take the next step: Schedule an AI Security Demo / Briefing 


Disclaimer

Source: Gartner, Emerging Market Quadrant for AI Application Security – Established Vendors, September 2026.

Gartner is a trademark of Gartner, Inc., and/or its affiliates.

Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.

The post Defining the Standard for AI Security appeared first on Palo Alto Networks Blog.

  •  
❌