Last week, researchers at Citizen Lab revealed a horrifying new malware campaign, dubbed “AdFection.” It used an ad network to distribute spyware to journalist’s devices to infect them without the target ever needing to click anything. This sort of attack on journalists is dangerous and incredibly concerning, especially since it’s built on the backbone of a technology we already object to: behavioral advertising. Although this type of attack has only been described targeting journalists, you can take a few steps we outline in the next section to mitigate the risk no matter who you are.
A few factors combined to make this attack a noteworthy first-of-its-kind. First, it utilized the surveillance ad-tech ecosystem to specially target the malicious code. Second, the spyware it delivered was so-called “zero-click,” meaning it required no interaction from the user to be infected: all that is required is for the ad to be delivered and code bundled along with it to be run, which happens automatically. Neither malvertising nor zero-click attacks are new on their own. What’s novel about the AdFection attack is combining them, creating a highly targeted, extremely dangerous attack which is difficult to defend against and even harder to detect.
Let’s take a deeper look from the perspective of one of the Windows devices supplied to the researchers from Al Jazeera. Here’s how the report describes the infection happening:
Someone browsing the web or using an app on that machine is served an ad created by Discover-Tech, a company exposed in the report as “purporting to be a legitimate advertising company, [but] appears to be a front for large-scale ad espionage abuse.”
The ad contains a small snippet of JavaScript code which is automatically executed when rendered in the app or website.
This code reaches back out to a Discover-Tech server, referred to as their “NOAS server,” with detailed information about the machine rendering it: its cookie-set advertising ID, IP address, and more.
So far, nothing particularly unusual has happened. Ads that contain JavaScript code and reach back out to their servers with lots of information on your device—and by extension you—are commonplace. It’s all part of the data-driven advertising ecosystem. What happens next is more interesting:
The NOAS server uses this detailed information to determine it is an Al Jazeera machine requesting the ad.
Instead of returning an empty response (as it does most of the time), it responds with a malicious, zero-click spyware payload. That payload was created by Discover-Tech’s partner Candiru/Integrity Labs, a company previouslyexposed for involvement in sophisticated malware attacks.
The payload is then executed and infects the targeted machine.
Companies targeting zero-click malware attacks against journalists might seem like the plot of a blockbuster spy thriller. But this attack was enabled by the everyday practices of ad-tech companies, which unfortunately have extreme latitude in the collection of users’ data. By leveraging the tracking identifiers and data collected on devices for the purpose of delivering targeted ads to specific individuals, mercenary spyware companies can repurpose this data in order to fine-tune who they infect—and hide that they’re doing it from everyone else.
Most ads are not delivered directly by the ad creators, but rather by intermediaries that facilitate Real-Time Bidding auctions. Nonetheless, winning bidders are given the ability to execute JavaScript code in the browser of the person who receives the targeted ad. This allows for interactive ads to be displayed, but also (as we’ve seen) for the compromise of a device just by delivery of malicious code.
While the different components in this attack chain are not novel on their own, the exposure of this combined attack is significant because it reveals a technique to hyper-target individuals and organizations for infection. Luckily, there are steps you can take to protect yourself from the myriadofdangerspresentedby the ad-tracking industry. Here’s how.
What You Can Do About It
As we work towards fundamental fixes to the ad ecosystem and banning online behavioral ads altogether, the onus is on all of us to protect ourselves. This is especially important for higher risk individuals or journalists working in states with heavy surveillance. Citizen Lab outlines several steps, depending on your threat model, to take to help protect yourself:
Use a browser extension to reduce tracking. Our Privacy Badger extension is an excellent start. Network-wide ad blocking services are also worth considering if you’re comfortable handling the set up process.
On mobile phones, disable or reset your AD ID. Here are directions to do so for Android and iPhone.
These steps can be very helpful in protecting yourself, but there is only so much you can do as an individual. Banning behavioral ads like this would be a good place to start. Behavioral ads aren’t just a privacy nightmare as designed. They are the perfect vehicle for malvertising and similar threats, just as we see here.
Exciting news for Safari users: Privacy Badger is now available on Safari for macOS! You’ll need Safari version 26.5 or higher to use it.
Whether you want to protect yourself from data brokers or just don’t want Big Tech profiting off your browsing data, Privacy Badger is here to help. More than 4 million people already use EFF’s free tracker-blocking extension to take a stand against online surveillance. Safari users can now join them and EFF in the fight for a better web.
Safari support has been one of Privacy Badger’s most requested features for years. Thanks to recent improvements in Safari's extension support, we’ve finally made it happen for Safari version 26.5 and higher. Privacy Badger is now available on all major desktop browsers. And before you ask, yes, we will look into supporting Safari for iOS once we've ironed out any issues on macOS.
Why Install Privacy Badger on Safari?
Most websites contain invisible tracking code that lets companies collect, share, and profit from your personal data. Some of those companies are data brokers that sell your information to anyone willing to pay. Creepy ads are just the tip of the iceberg when it comes to the harms of online tracking: Once your information enters the data broker ecosystem, it’s nearly impossible to know who buys it or what they’re doing with it. Privacy Badger blocks online trackers to prevent your browsing data from being used against you.
Privacy Badger goes beyond Safari’s built-in privacy features to provide additional protection against online tracking. In its default browsing mode, Safari limits the information that trackers can access but still allows them to load. Privacy Badger blocks trackers from loading in the first place, preventing them from tracking you using techniques that bypass Safari’s protections.
For example, Privacy Badger blocks tracking from widgets like embedded tweets, comments sections, and video players. These widgets can share your data even if you never click on them. Privacy Badger prevents these trackers from loading and replaces them with click-to-activate placeholders.
Beyond tracker blocking, Privacy Badger automatically sends the Global Privacy Control (GPC) signal to tell websites not to sell or share your personal information. The GPC signal is already legally binding in a growing number of states, including California, Colorado, New Jersey, and Connecticut.
All these features (and more) work together to help keep your browsing activity private on Safari.
Try It Out and Spread the Word
If you use Safari on macOS, give Privacy Badger a try. You’ll install Privacy Badger through the App Store on your macOS device. Installing extensions is a little more complicated on Safari than other browsers, so follow Apple’s directions here if you’re having trouble.
This is our first release of Privacy Badger for Safari, and we will keep improving it based on your feedback. If you run into any problems, let us know by emailing extension-devs@eff.org, or by opening an issue on GitHub. And if blocking harmful trackers causes issues on a website you visit, you can disable Privacy Badger for that specific site while keeping it enabled and protecting you everywhere else. You can also let us know about broken sites by using the “Report broken site” button found next to the “Disable for this site” button in Privacy Badger’s popup window.
When you use Privacy Badger, you join EFF and millions of other users in the fight for a better web. Help spread the word by telling your friends and family who use Safari that they can use Privacy Badger too!
Online sports betting company DraftKings is using AI to target customers who are most likely to place losing bets and respond to gambling promotions. This kind of targeting is a form of online behavioral advertising, which is when companies personalize the ads they show you based on the data they’ve collected about you. The more data a company has, the more personalized the ad can be. While DraftKings is using AI to supercharge the harmful effects of online behavioral advertising, EFF has long argued that all behavioral advertising should be banned.
According to the New York Times, DraftKings is using its customers’ betting records to train a machine learning model to find losing gamblers. Once found, DraftKings sends these customers targeted advertising designed to lure them back to the site to place more bets—bets that DraftKings thinks will be losing ones. DraftKings has a business incentive to keep losing gamblers coming back to their site, because these are the users actually making DraftKings money. Unfortunately, those considered “problem gamblers” (people who repeatedly gamble despite harm to themselves, their finances, and their relationships) are highly likely to be targeted by this model. By re-engaging these individuals through targeted promotions aimed at keeping them on the platform, DraftKings is capitalizing on their vulnerability for profit instead of mitigating their risk.
Predatory online behavioral advertising isn’t new, but companies’ use of AI to process data and target customers has magnified its harms. Online behavioral advertising incentivizes the collection of vast quantities of data to power ad tech. Adding AI into the mix means that even more data is collected to train and refine models. Because AI operates as a black box, the humans building the models can rarely predict which data points are the most useful to the AI, driving them to continuously collect more data. AI also allows companies to process enormous data sets much faster, and, as a result, supercharges the harms of online behavioral advertising.
A direct consequence of online behavioral advertising is that it provides the data the surveillance industry needs to run. Data collected for targeted placement of ads is being sold to insurance companies, banks, and state and federal government law enforcement agencies such as CBP. ICE is also taking an interest in the data fueling ad tech: earlier this year, ICE published a Request for Information “seeking information to better understand how the industry’s commercial Big Data and Ad Tech providers can directly support investigations activities.”
DraftKings seems to be using solely “first party data” to target their ads, meaning that they’re using only the data they collect directly from their users and are not buying any additional data from third parties to fuel their machine learning model. This highlights how policy solutions that only limit third-party data sharing and selling would not be enough to prevent these predatory advertisements. Rather, policymakers must ban online behavioral ads.
What DraftKings is doing with their targeted promotions is just one example of how online behavioral advertising causes real harm to real people. But there are ways to take back control over your own data: EFF offers resources such as our Surveillance Self Defense project, along with other tips for how you can protect yourself on mobile apps and on websites.
DraftKings’ use of AI to target losing gamblers illustrates how ad tech evolves and how companies find new ways to use our data against us. This is why EFF believes that all behavioral advertising should be banned. If companies can’t send personalized ads, they’ll have less incentive to collect the behavioral data powering them.
Picture your computer keeping a diary — the kind kids used to keep logging their daily activities, or the kind travelers, merchants, and nobles kept centuries before that. Here’s what it might look like.
Thursday, September 10.
8:00 AM. User read the news on cnn.com and bbc.co.uk (Safari).
8:10 AM. User replied to John Kaufman’s email about delivery dates, then sent the same question to the logistics team (Gmail).
8:20 AM. User checked his to-do list, reviewed recent updates, and planned out the day’s priorities (Todo).
We’re not exaggerating. This is exactly what your Mac’s new diary looks like. It’s a set of text files that any app on your computer can read — as can anyone sitting at the keyboard. The feature responsible is called Computer History, and it was released by OpenAI in mid-August. At the moment, it only works in the ChatGPT app for Mac, requires a Pro subscription or higher, and is disabled by default. According to its developers, the idea behind History is to let the AI assistant quickly get up to speed on your work context, so it can answer even vague requests, like “send a reminder to whoever I was emailing about last week’s deliveries”. Of course, that convenience comes at a price, ranging from your data being processed on OpenAI’s servers, to the risk of it leaking off your Mac — whether to a nosy family member or straight into the hands of cybercriminals.
How ChatGPT Computer History works
If this sounds a lot like Microsoft’s similar Recall feature, or Chronicle, which OpenAI itself announced earlier, that’s no coincidence. Both were built with the same goal in mind, just using different methods. Having watched Recall turn into the PR disaster it was, the team behind Computer History decided against constantly taking and analyzing screenshots. Instead, ChatGPT relies on macOS’s Accessibility features to read the text on your screen and track your actions: mouse clicks, text typed into fields, switching between apps, and the like. All of this gets stored as a stream of raw activity data inside the ChatGPT container (app group), which only the ChatGPT app itself, or other apps you’ve specifically given permission, can access. In tests run by digital forensics researchers, just two hours of normal computer use generated around 3500 of these logged events.
That raw data remains on your computer for up to 48 hours. During this time, the ChatGPT app periodically runs hidden chat sessions behind the scenes, where it asks the AI to summarize related events into a single recap. Essentially diary entries, these summaries get saved as plain text files in a folder that any app on your Mac can open: ~/.codex/memories/extensions/skysight/.
When you chat with the assistant, or when certain automated features kick in, these notes can be pulled into the conversation for more context-aware responses. OpenAI is especially keen on pointing out that the assistant can spot patterns in your workflows and offer to automate them, creating what it calls “skills” that replicate your actions for you.
Once a summary is ready, the raw activity data behind it is deleted. OpenAI says it won’t keep those hidden background chats or use them to train its AI, except where required by law. The diary-style summaries that get pulled into your conversations, though, are stored on OpenAI’s servers under the exact same rules as your regular chats and the assistant’s memory, so your preexisting privacy settings will apply to them too.
What Computer History can see, and what you can turn off
Since the whole feature runs on accessibility tools, ChatGPT only picks up what your operating system is already willing to share with those tools. That includes window titles, blocks of text, image captions in your browser, text you’re typing into a field as you type it, and the names of interface elements you click on. Watching a video? The AI can’t see the video itself, but it can read the window title, the site name, and the video description. Browsing photos? It sees file and folder names, not the actual images. Audio is never recorded or saved in any situation. All that gets logged from a video call is the meeting window title, unless the call itself has live captions turned on. Password fields that are masked (shown as dots) aren’t read at all and, according to OpenAI, private browsing windows are never scanned.
One thing that sets this apart from Microsoft Recall is the clearly spelled out step-by-step procedure the user needs to go through to turn it on. Computer History never activates itself. You have to navigate to the settings menu, then Integrations → Computer History and turn it on manually after reading through the warnings and explanations. You’ll also need access to the agent’s memory enabled for the feature to work. From there, you choose which apps and websites you want it to track, and confirm a series of macOS permission prompts.
For companies using a business subscription, this requires approval at two levels: an administrator first has to enable Computer History for the whole organization, and then each employee has to turn it on individually.
At any point, you can go to Computer History → Permissions and either list specific apps and sites to exclude from tracking, or, conversely, set ChatGPT to only watch a limited list you choose (Include only these apps, Include only these websites).
To see what your own computer’s diary looks like, check Computer History → History. From there, you can delete individual entries or disable the tracking of specific apps directly from the list.
The risks of using ChatGPT Computer History
We covered the risks of centralized storage of someone’s entire activity in our earlier piece on Microsoft Recall, and most of what we said there applies to ChatGPT Computer History.
You might assume your chats and emails are private, protected by passwords and encryption. But a copy of the most important parts of those conversations is sitting in plain text files that anyone with access to your computer, and plenty of other apps, can open.
The people you’re messaging have no idea this extra copy exists. If they’ve turned on, say, a self-destructing chat feature, but the messaging app’s window itself isn’t marked as private, that precaution does nothing to protect them.
Even if you trust OpenAI completely and take its privacy promises at face value, your data can still be stolen directly off your computer by an infostealer. Mac-targeting infostealers have exploded over the past two years, so this isn’t a hypothetical risk. And the people who write this type of malware move fast, quickly updating it to grab whatever new type of data looks promising. OpenAI’s files are a boon for them: everything you’ve done, already summarized by AI into something easy to read. While there are no passwords or credit card numbers in there, the available details are likely enough to craft a convincing targeted urgent email from the boss.
And if a nosy coworker or family member gets their hands on your computer, reading through the diary of your work and life would take them all of five minutes.
Computer History: turn it off, or just configure it?
We’d recommend limiting or fully disabling Computer History if your work involves sensitive information. This especially applies to doctors, lawyers, and anyone else bound by professional confidentiality, or handling personal or medical data. The same goes for anyone living with an overly controlling family member, or working in an office with nosy coworkers.
If none of that applies to you and you’d like to try out how useful the AI’s search and auto-generated skills actually are, here’s how to set things up safely.
Lock down your Mac’s login. Turn off auto-login, and set your Mac to require a password immediately after the screensaver kicks in or it wakes from sleep. Use a strong password along with Touch ID, and make sure FileVault disk encryption is turned on.
Set up your exclusions. Manually add every messaging app you use for private conversations, along with any finance apps or sites, and anywhere else you keep sensitive information, to Computer History’s exclusion list.
Check in regularly. At least a couple of times a week, visit Computer History settings to see which apps and sites it’s been tracking. This helps you catch and remove any sources of private information you forgot to exclude earlier.
No matter how you configure Computer History, the two most common ways your data could end up in the wrong hands — on any Mac — are a macOS infostealer snatching it directly from your computer, and typing your information into a fake website. To guard against both, make sure you’re running full-featured security software on your Mac, such as Kaspersky Premium for macOS.
AI can create privacy risks you might never think to look for. You can read about more of them in our other posts:
Virtually every website selling products or services features a live chat widget. It usually appears as a small window in the corner of your screen, complete with an agent’s name and picture.
Sometimes these chats simply collect tickets for tech support or sales to process. But often there’s a real person on the other end of the screen. And here’s where many users get an unwelcome surprise: agents can see absolutely everything you type into the chat box, even if you have no intention of sending it. In this article, we break down why this happens and what you can do about it.
All in the name of customer experience
It’s all thanks to a feature known as live typing preview, or real-time typing view, which exists under one name or another in almost every popular customer chat platform. Here’s how the developer of LiveAgent, a customer support system used by more than 40 000 companies, describes it in its blog: “This live chat typing preview allows agents to anticipate questions and deliver faster responses. Additionally, real-time chat monitoring enables supervisors to oversee chat interactions, ensuring quality and timeliness.”
While that might sound helpful and harmless to some, having their unsent messages watched without their permission can trigger outright panic for others. To make matters worse, it’s almost impossible to tell whether the website uses the feature. That is, unless the chat agent admits it to you directly… or replies to a message you decided not to send.
As an alternative, you can run a quick test: type out a message in the chat box, wait 15 seconds, and see if the agent starts typing a response. If they do, you’re almost certainly dealing with real-time typing view. Whether to continue that conversation is up to you. Most importantly, never type personal information into a chat box — even if you are doing so from a Kaspersky Premium device.
Real-time typing view is just the tip of the iceberg. In reality, websites collect far more information than you might think. You’re likely already familiar with cookies, and have probably asked yourself at least once, “Should I accept these or not?” We answer that and other questions in our post Taking the biscuit: why hackers like cookies so much.
Tracking techniques that use web beacons and tracking pixels are not as widely known. To learn why they’re a concern and how to turn them off, check out our post Who is tracking you on the web and how.
Another technology that remains largely unknown to the general public is session replay scripts. These tools allow website owners to watch a recording of your visit: how fast you moved your cursor, where you clicked, which pages you browsed, and what you added to your shopping cart.
Of course, the primary goal of session replay is the same as real-time typing view: improving customer and user experience. It helps companies analyze your behavior, identify friction points, and make improvements. If a customer fails to complete a checkout or encounters a technical issue, developers can review the recording of their session to pinpoint what went wrong.
In theory, it sounds helpful enough: “We will collect a small amount of data about you to make the site better for you.” In practice, however, this approach comes with significant risks for users.
What’s the catch?
The primary risk here lies in whether websites collect this data legally, how they store it, and whether they share it with anyone. While you can usually gauge legality by reading their privacy policy, the terms of data storage and sharing are often described vaguely.
On top of that, users rarely realize an agent can read their message before it’s actually sent. If you change your mind about asking a question, edit a sentence, or delete your text entirely, that doesn’t mean no one saw the draft. Unlike cookies, opting out of this technology is practically impossible. Most chat widgets simply don’t offer a setting to disable typing previews.
As for tracking pixels, web beacons, and session replays, they’re essentially a form of digital surveillance. Beyond collecting vast amounts of data, they can also slow down your device’s performance. Even worse, if attackers compromise a website’s analytics system, they can gain access to this data, reconstruct your path through the site, and uncover details that can be leveraged in future attacks. To learn more about how scammers pull off these tricks and how social engineering works, check out our post They’re reading you like a book: scammers’ favorite tricks.
While you can’t prevent a potential breach on a third-party website, you can — and should — take steps to secure your own browsing session.
What you can do about it
First and foremost, pay close attention to what you type in a chat box. It’s critical never to share personal data, credit card numbers, logins, passwords, or any other sensitive information with live chat agents.
Beyond that, there’s always a risk of landing on a phishing site and entering your account credentials there. To prevent this, we recommend using our security solutions, which block visits to malicious and suspicious websites. We also suggest storing your credentials in Kaspersky Password Manager — our password manager won’t let you auto-fill saved logins and passwords on a fake site.
Users of Kaspersky Standard, Kaspersky Plus, and Kaspersky Premium have access to our Private Browsing feature (on Windows and macOS). It prevents third-party services from tracking your online activity and collecting real-time information about what you do on websites.
To minimize the risk of data leaks, keep these tips in mind:
Never type anything into a chat box that you aren’t prepared to send. On almost every website, the agent can see your text while you type, so deleting a message is no guarantee it stays private.
Keep in mind that your activity on a website may be recorded. These recordings can capture your clicks, page navigation, and form inputs. Treat every website as if your actions are being watched.
Pay attention to privacy policies. Reputable companies typically state whether they use analytics tools, session recording, or third-party support services.
Approach chat interactions with caution. Real-life rules apply here as well: never share verification codes, passwords, phone numbers, or other sensitive details in a chat.
Be smart about accepting cookies. Taking a moment to check what information a website collects is well worth the effort — it helps you make an informed choice about whether you’re comfortable sharing that data.
Tired of endless digital tracking? Here’s how you can protect yourself and your data:
A breakup is a major upheaval — the kind that turns life upside down. The familiar order of things, where two people shared the same interests, moments, and often even the same physical space, collapses in an instant, leaving each of you in a world of your own.
Besides that, couples are connected not just in real life, but digitally too. Shared subscriptions, saved addresses and passwords, access to joint cloud storage — all of that used to be woven into your day-to-day life. Moving on emotionally can take a long time, sure, but there are steps you can take right now that will tighten up your security — even if they won’t help you get over your ex.
Here’s what you need to check after a breakup, which services to disconnect, and why you should do it even if the split was amicable.
Digital hygiene: your insurance policy
Cutting off your ex’s access to your online accounts isn’t paranoia — it’s looking out for your own security. A breakup doesn’t automatically sever your digital ties: any access you granted each other during the relationship stays active until someone manually shuts it down. Most of the time, nobody’s plotting to actually exploit it, yet it can still lead to anything from awkward moments to a genuine risk of being tracked.
Take Aleta Dignard-Fung, of Las Vegas, who told NPR that after breaking up with her boyfriend, it didn’t immediately occur to her that he still knew her Spotify password. One day, in the shower with music playing, she noticed her playlist suddenly switch. Her ex had logged in from another device and started playing his own chosen tracks. “It was just kind of like the Spotify wars, and we’d just spend like 10 minutes trying to override each other’s songs,” she admitted. But the fallout isn’t always this lighthearted.
Relationship coach Susan Winter shared a case from her own practice in that same interview. One of her clients simply couldn’t let go of his ex-girlfriend after their breakup. The two had shared an OpenTable account — the restaurant reservation service — and she’d never revoked his access. He started tracking her bookings: where she was going, what time, how many people. That’s how he kept tabs on whether someone new had entered her life.
These two stories, while showing very different behavior from the exes involved, both trace back to the same root cause: accounts that were never properly locked down. In the former case, it led to an awkward moment. In the latter, it led to anxiety and a real sense of being watched. To make sure neither scenario happens to you, it’s worth running through a quick checklist.
Terminate your partner’s sessions
In the settings for your social media, messaging apps, email, and other key services, pull up the list of active sessions and log out everything except your current devices.
Change your passwords
Update the passwords to any key accounts your partner might have known — say, if you used a meaningful date as your password. If you reused the same password across multiple services, change it everywhere. While you’re at it, review your security questions and your backup email or phone number for account recovery — neither should still be tied to your ex. To skip the hassle of memorizing new credentials while still leveling up your security, we recommend using a password manager — it’ll generate a unique, strong password for every account, and save and sync it across all your devices; the only thing you need to remember is a single main password.
Check two-factor authentication and trusted devices
Make sure verification codes only go to your own device. Remove your partner’s devices from your trusted list — you can do this in your Apple and Google account settings.
Split up your shared Apple/Google accounts
If you shared an Apple or Google account, sign out of that. Turn off Family Sharing, iCloud, and backups. Check your shared photo albums too — anything that lands there automatically is visible to your ex as well.
Review your subscriptions
If you shared subscriptions — streaming services, family plans, that kind of thing — cancel them or set up new ones and link your own card.
Check your bank cards
If your ex’s card is linked to a marketplace, delivery app, or rideshare service account you own, remove it from your saved payment methods. If your card is linked to their account and you no longer have access to it, the safest move is to just get your card reissued.
Revoke smart home access
Cut off your ex’s access to cameras, video doorbells, GPS trackers, and smart speakers. If the devices were on a shared account, change the password or move them over to your own personal account.
Review your privacy settings
Check the privacy settings across your accounts on various services and social media using our free online tool, Privacy Checker. It walks you through a privacy configuration tailored to your operating system, platform, and even your browser.
If you notice signs of stalking
Reach out to advocacy or legal aid organizations — they can help you map out the best course of action. It’s also worth leaning on family and close friends who can support you through a tough situation. On Android devices, you can use our security suite with the Who’s Spying on Me feature. It’s designed to help you detect tracking and stalking so you can take the right steps to protect yourself. The feature includes:
Stalkerware Detection. Flags apps designed to secretly monitor your life and collect data you’d never want shared with anyone else.
Device Scanner. Finds planted trackers that let someone follow your movements and always know where you are.
Permissions Control. Shows which apps have access to permissions that could make it easier for someone to spy on you or compromise your privacy.
What can actually help — and what might make things worse — during this difficult time? Check out our other posts:
You have an expectation of privacy in location data that reveals your movements in the physical world, and even short-term surveillance of these movements is a search subject to the Fourth Amendment, the U.S. Supreme Court ruled today in Chatrie v. United States.
The case involved geofence warrants, a form of dragnet surveillance police have used to vacuum up location data from electronic devices of people who happen to be in the vicinity of a crime. EFF had joined the American Civil Liberties Union, the ACLU of Virginia, and the Center on Privacy & Technology at Georgetown Law in filing an amicus brief in the case.
The decision in Chatrie is important: It is the first digital surveillance decision by the Court since its landmark 2018 ruling Carpenter v. United States, which involved prolonged tracking of people’s movements using cell phone location data. The new case expands that ruling by confirming that even shorter-term surveillance of location data can constitute a search because it can still reveal “private matters,” including “a wealth of detail about a person’s familial, political, professional, religious, and sexual associations.”
The case is also important because the Court also recognized the records generated by the apps on a user’s phone—records we necessarily share with third-party tech company—are a user’s “own” and require Fourth Amendment protection. This is true, regardless of whether those records are “emails, documents, photographs, [ ] calendars” or location data. This will likely have broad implications for data generated by other apps on our phones, even if we click “agree” to sharing that data with third-party tech companies.
Geofence warrants don’t name a suspect or a specific individual or device the way typical warrants do. Instead, they compel companies—almost always Google—to provide information on every electronic device in a given area during a given time period. This creates a high risk of suspicion falling on innocent people and can reveal sensitive and private information about where individuals have traveled in the past.
Geofence warrants are the digital equivalent of police going person to person, home to home, without suspicion that any device holder has a connection to a crime. This turns innocent bystanders into suspects, just for being in the wrong place at the wrong time.
In Chatrie, a 2019 geofence warrant compelled Google to search the accounts of all its hundreds of millions of users to see if any one of them was within a radius police drew around a Northern Virginia crime scene. This area amounted to several football fields in size and encompassed numerous homes, businesses, and a church.
A federal district court in Virginia in 2022 held that the geofence warrant plainly violated the Fourth Amendment. If the police want to get information on every device in the area, they must also establish probable cause to search every person in the area, the court said. The judge noted the government lacked particularized probable cause as to every individual within the geofence, which swept up innocent people and covered over 70,000 square meters in a busy area.
The decision set an important precedent in finding the warrant overbroad and unconstitutional and was later followed by a 2024 federal Fifth Circuit Court of Appeals ruling holding that geofence warrants are “categorically prohibited by the Fourth Amendment.” However, the Chatrie lower court allowed the government to use the evidence it obtained because it relied on the warrant in “good faith.” A much divided en banc panel of the U.S. Court of Appeals for the Fourth Circuit in 2025 affirmed this “good faith” finding in the lower court’s opinion.
Google in 2023 announced changes to how it stores location data, with the effect of eventually making it impossible for the company to respond to geofence warrants. Since July 2025, mass geofence searches of Google users’ location data have not been possible.
However, Google is not the only company collecting location data, nor the only way for police to access mass amounts of data on people with no connection to a crime. As we’ve written about extensively, data brokers collect and aggregate location data from many different apps on our phones and provide that data to police. And police can use “cell tower dump” warrants to get access to data on everyone within range of specific cell towers. Suspicionless searches like these drag a net through vast swaths of information in hopes of identifying previously unknown suspects—ensnaring innocent bystanders along the way.
Chatrie could have wide-ranging implications beyond location data as well. The Supreme Court affirmed that app data is subject to the Fourth Amendment, because users “reasonably view” it as their own and reasonably expect it “to be shielded from the ‘inquisitive eyes’ of the government.” Justice Gorsuch, in an opinion concurring in the judgment, called location data a user’s “personal property,” no different from myriad other “effects” explicitly protected by the text of the Fourth Amendment. As the Court concluded, “the point of carrying smartphones is to use what is on them,” so the Fourth Amendment has to protect more than just location data generated by the act of carrying the phone itself.
The Court ultimately did not decide whether the particular warrant at issue in Chatrie was “reasonable” or whether the “good faith” doctrine applied. The case now heads back to the Fourth Circuit Court of Appeals to address these questions.
But regardless of how the Fourth Circuit rules on remand, this Chatrie opinion will shape how lower courts address police access to location and other data going forward. We look forward to citing Chatrie to press future courts to recognize broad Fourth Amendment protections for user data.
This Pride month, we’re calling on the dating app Grindr to prioritize LGBTQ+ user safety by making privacy the default across its platform. That means no more sharing personal data with advertisers or training AI on private information without users’ opt-in consent.
Grindr is a dating app for the LGBTQ+ community; and for queer people, privacy violations can have life-altering consequences. Information that reveals someone’s sexual orientation, gender identity, or HIV status can be used by employers, governments, family members, scammers, or bad actors to inflict harassment, discrimination, arrest, or violence. For example, data from Grindr and other gay dating apps was sold by data brokers and used to 'out' (the act of disclosing someone's sexual orientation without permission) a gay priest in 2021.
Despite being the world's most popular gay dating app, Grindr has repeatedly mishandled users' sensitive data. Grindr has been caught sharing users' HIV status and precise location with advertisers without obtaining valid consent, resulting in reprimands and fines in several countries. Its former Chief Privacy Officer even sued, alleging the company fired him for raising concerns about Grindr prioritizing “profit over privacy."
Grindr ended several of its mostegregious data sharing practices after they were exposed. But more changes are needed if Grindr wants to earn back trust and prove its commitment to users’ privacy and safety. This Pride month, we’re calling on Grindr to make privacy the default and ensure the immediate implementation of two changes to better protect its users:
Opt Users Out of Behavioral Advertising by Default
Grindr currently allows users to opt out of behavioral advertising, but that protection is not enabled automatically (except in some unspecified regions). As we’ve longwarned, behavioral advertising relies on the collection and sharing of personal data across a vast network of advertisers, intermediaries, and data brokers. Once information enters this ecosystem, users have little control over where it goes or how it is used: people’s most private and intimate information can be aggregated, sold, and combined with information from other sources to create detailed personal profiles.
By default, Grindr appears to share data with numerous advertising and tracking companies. Using TrackerControl, an app developed by privacy researcher Konrad Kollnig, we recorded Grindr contacting 20 third-party tracking domains during 15 minutes of app activity (see Grindr_TrackerControl_06-23-2026.csv for exported results). TrackerControl observed Grindr contacting Big Tech companies and ad-tech intermediaries, manyofwhich have faced significant legal scrutiny for privacy violations. Severalofthesecompanies auction off ad space through a process called “real-time bidding,” which can expose user data to hundreds of additional companies and be exploited by data brokers.
The dangers of Grindr’s default settings exposing users’ personal data to this ecosystem are not hypothetical. Between approximately 2017 to 2020, a location data broker collected the precise movements of millions of Grindr users from digital advertising networks and made them available for sale. The commercially available data was allegedly so detailed that, in some cases, it could be used to infer romantic encounters between specific Grindr users.
Although Grindr has stated that it no longer shares precise location data or profile information with advertisers, it acknowledges sharing other personal data, including mobile advertising identifiers (MAIDs)—unique, persistent device IDs that allow advertising companies and data brokers to connect data about the same individual across different sources. MAIDs are not anonymous, and an entire industry exists to link them to more directly identifying information, like emails and phone numbers. According to Grindr’s privacy policy, companies receiving users’ MAIDs “are aware that such data is being transmitted from Grindr,” which could expose a users’ sexuality to the advertising and data broker ecosystem.
Opt Users Out of AI Training on Personal Data by Default
Grindr should stop training its AI models on users’ personal data without opt-in consent.
Grindr claims to never use sensitive health information for AI training and requires users to opt-in to AI training on “special-category” data, which includes chat content and precise location. But Grindr automatically enrolls users in AI training on other private information, including profile photos, age, taps, and display names. Users must navigate several levels of Grindr settings to prevent these personal details from being used to train Grindr’s AI.
AI systems trained on personal data create new privacy risks, including the possibility that personal information may be retained, reproduced, or exposed in unexpected ways. For example, researchers have been able to extract training data from AI systems like ChatGPT.
Beyond AI training, Grindr enables AI-powered features by default and allows both “special-category” data and other personal information to be processed by those features. Even users without access to premium-subscription AI features could have their data automatically used to power those features for other users. “Behavior-based profile insights” (pictured below) could expose information that users would never choose to share publicly, like the types of people they interact with on Grindr, their typical online hours, and how often they initiate conversation with other users.
Image of the “Profile Insights” feature from a Grindr blogpost promoting its premium, AI-first subscription
Regardless of whether new AI features leak private information, users deserve meaningful control over how their personal data is used and by whom. Grindr notifies users that their personal information may be used to train AI and that they can opt out on a separate settings page, but this notice does not specify the type of data used (i.e. profile photos, taps) and it is unlikely that people carefully read or understand it. Closing the notice or clicking its only button (which is “Proceed”) maintains Grindr’s default of using personal information for AI training. To respect users’ autonomy, Grindr should require opt-in consent before training AI models on personal data.
Notice displayed in the Grindr app about the use of personal data for new AI features
Celebrate Pride by Demanding Better Privacy
Grindr must immediately stop prioritizing profits over users’ safety. The ability to opt-out is not an acceptable substitute for opt-in consent, especially given the added risks of data sharing for LGBTQ+ users. Defaults matter—studies show that most people cannot or do not change the default settings of technologies they use.
If Grindr wants to back up its claim that it “takes user privacy very seriously,” it should make privacy the default across its platform, rather than something users need to go through complicated processes to opt in to.
The surveillance company Leonardo wants more data:
A surveillance company plans to add sensors to automatic license plate readers (ALPRs) that would mean the devices, as well as capture the license plate of passing vehicles, would also sweep up unique identifiers of mobile phones, wearables, and other Bluetooth-enabled devices in those cars, potentially letting law enforcement identify specific drivers or passengers.
The technology, called SignalTrace, would turn ALPR cameras from devices focused on tracking cars to ones that can more readily track the location of particular people. ALPR cameras have become a commonly deployed technology all across the U.S.; SignalTrace would make some of those cameras capable of collecting much more data.
Yes, it’s bad that more companies are collecting this level of surveillance data. But all of this pales in comparison to the type and quantity of data our smartphones already collect about us.
A suspicious website is a web resource that cannot be definitively classified as phishing, but whose activities are unsafe. Such sites manipulate users, tricking them into voluntarily transferring money for non-existent services, signing up for hidden subscriptions, or disclosing personal data through carefully crafted terms of service. These include fake online stores, dubious crypto exchanges, investment platforms, and services with paid subscriptions.
Kaspersky has introduced a new web filtering category, “Sites with an undefined trust level,” into its security products (Kaspersky Premium, Android and iOS apps, etc.). The system analyzes the domain name and age, IP address reputation, DNS configuration, HTTP security headers, and SSL certificate to automatically detect suspicious resources.
According to Kaspersky data for January 2026, the most widespread global threat is fake browser extensions that mimic security products — they were detected in 9 out of 10 regions analyzed worldwide. Such extensions intercept browser data, track user activity, hijack search queries, and inject ads.
Kaspersky’s regional statistics reveal the specific nature of these threats: in Africa, over 90% of the top 10 suspicious websites are online trading scam platforms; in Latin America, fake betting services predominate; in Russia, fake binary options brokers and “educational platforms” with fraudulent subscriptions lead the way; in CIS countries — crypto scams and bots for inflating engagement.
Key indicators of a suspicious website to check: a strange domain name with numbers or random characters, cheap top-level domains (.xyz, .top, .shop), a recently registered domain (less than 6 months old according to WHOIS data), unrealistic promises (“100% guaranteed income,” “up to 300% profit”), lack of company contact information, and payments only via cryptocurrency or irreversible bank transfers.
Introduction
The online landscape is filled with various traps lying in wait for users. One such threat involves websites that can’t be strictly classified as phishing, yet whose activities are inherently unsafe. These sites often operate on the fringes of the law, even if they aren’t directly violating it. Sometimes they use a cleverly crafted Terms of Service document as a loophole. These agreements might include clauses such as no-refund policies or forced automatic subscription renewals.
Fake online stores, dubious financial platforms, and various online services that mimic legitimate business operations are all categorized as suspicious. Unlike actual phishing sites, which aim to steal sensitive data like banking credentials or passwords, these suspicious sites represent a far more cunning trap. Their goal is manipulation: tricking the victim into willingly paying for non-existent goods and services or signing them up for a subscription that’s nearly impossible to cancel. Beyond financial gain, these sketchy websites may also hunt for personal data to sell later on the dark web.
Our solutions categorize them as having an “undefined trust level”. This article explains what these sites look like, how to identify them, and what you can do to stay safe.
The dangers of shady websites
One of the biggest risks associated with making a purchase from an untrusted website that seems to be an online store is the financial loss and falling victim to fraud. Fake shops will entice you with attractive deals to get you hooked. After you pay, you may never receive what you paid for, or you may receive some cheap piece of unusable junk instead of the item you ordered. Investment or “guaranteed income” programs are another type of classic scam — they promise rapid returns, and once they take your deposits, they disappear without a trace.
Visiting or buying from untrusted suspicious websites can expose you to various risks that go beyond a single bad purchase. Fraudulent websites often collect your personal information even if you do not end up making a purchase. By completing a form or signing up for a “free offer”, you may be providing the scammer with access to your information.
Personal data collection can happen in a fairly straightforward and obvious way — for instance, through a standard order delivery form. In this scenario, attackers end up with sensitive information like the user’s full name, shipping and billing addresses, phone number, email address, and, of course, payment details. As we’ve previously discussed, fraudsters sell this kind of information, and there’re countless ways it can be used down the line. For example, this data might be leveraged for spam campaigns or more serious threats like stalking or targeted attacks.
Common types of suspicious sites
Let’s take a closer look at the different types of shady sites out there and how interacting with them can lead to financial loss, data leaks, the unauthorized use of personal information, and other consequences.
It’s worth noting that rogue websites can masquerade as legitimate ones in almost any industry. The first type of fraudulent site we’ll look at is fake online stores. These can appear as clones of real brand websites or as standalone stores. Usually, the scam follows one of two paths: the buyer either receives a counterfeit or poor-quality product, or they receive nothing at all. These sites lure victims in with suspiciously low prices and “exclusive” deals. Often, users are subjected to psychological pressure: the time to make a purchase decision is purposefully limited, provoking the victim, as with any other scam, into making an impulse purchase.
Another common type of shady site includes online exchanges and trading platforms. These primarily target cryptocurrency, as the lack of legislative regulation for digital currency in certain countries makes them a magnet for fraudsters. These suspicious sites often lure victims with supposedly favorable exchange rates or other enticing gimmicks. If the user attempts to exchange cryptocurrency, their tokens are gone for good. Beyond simple exchanges, rogue sites offer investment services and even display a fake balance growth to appear credible. However, withdrawing funds is impossible; when the victim tries to cash out, they’re prompted to pay some fee or fictional tax.
Subscription traps are also worth noting, offering everything from psychological tests to online video streaming platforms. The hallmark of these sites is that they deliberately withhold critical information, such as recurring charges, or hide the fact it even exists. Typically, the scheme works like this: a user is offered a subscription for a nominal fee, like $1. While that seems attractive, the next charge – perhaps only a week later – might be as much as $50. This information is intentionally obscured, buried in fine print or tucked away in the Terms of Service where it’s harder to find. Legitimate services always clearly disclose subscription terms and provide an easy way to cancel before a trial period ends. Scam services, on the other hand, do everything possible to distract the user from the actual terms of use and subscription.
Shady sites can also masquerade as providers of mediation services, such as legal or real estate assistance. In reality, the service is either never delivered or provided in a stripped-down, incomplete form. For example, a user might be prompted to pay for a service that’s normally provided for free. The danger here lies not only in losing money for non-existent services but also in the significant risk of exposing personal data, such as ID details, taxpayer identification numbers, social security numbers, or driver’s license information. Once in the hands of attackers, this data can become a tool for executing further scams or targeted attacks.
On the whole, suspicious sites are fairly difficult to distinguish from legitimate, trustworthy services. Masquerading as a legitimate business is the primary goal of these sites, and the fraudulent schemes they employ are not always obvious. Nevertheless, there are protective measures as well as certain indicators that can help you suspect a site is unsafe for purchases or financial transactions.
How to identify suspicious or fraudulent websites
Despite the increasingly convincing attempts to create fake shops, the majority of them still lack the quality of real online stores, and there are many signs that may give them away. Some of these signs can be caught by the eye while others require a bit of technical investigation. By combining visual inspection, technical checks, and trusted online tools, you can protect yourself from financial loss or data theft.
Visual and manual clues
You don’t need to be a cybersecurity expert to catch many red flags just by observing the site’s domain, visuals, language and behavior. For instance, scam sites often have strange or randomly generated names, filled with numbers, underscores, hyphens, or meaningless words, like best-shop43.com. In addition, such vague top-level domains as .xyz, .top, or .shop are also frequently used in scams because they’re cheap and easy to register.
Furthermore, most fake stores sites look unprofessional, with poor visuals, pixelated images, mismatched fonts, or copied templates. Many fraudulent websites borrow layouts or logos from other brands or free templates, which makes them appear generic and sketchy.
Another major giveaway lies in the content itself. Be aware of persuasive language, unrealistic promises, or emotional triggers such as No KYC, Risk-free returns, 100% guaranteed income, Up to 300% profit, or Passive income with zero effort. Unrealistic deals are another red flag. If the products are listed at extremely low prices, continuous countdown timers, and “limited time only” messages that are often used to pressure you into making a quick purchase, it’s a clear tell of a fraudulent website.
Legitimate businesses always provide verifiable contact details, such as a physical address, company name, and customer support. On the contrary, scam sites hide this information. You may also notice the non-functioning pages, broken or suspicious links leading to unrelated external sites which indicate poor maintenance or malicious intent.
Another important signal is the website’s social media presence. Legitimate online businesses usually maintain at least one active social media account to promote their products and communicate with customers. In most cases, these businesses have long-established social media accounts with harmonized posting history and engagement from real users, consistency between the brand website and social media profiles (same name, logo, and links). The links to social media profiles from the website are usually direct. In contrast, fraudulent or deceptive websites often lack any meaningful social media presence or display signs of superficial or artificial activity. This may include missing social media accounts altogether, social media icons that lead to non-existent, inactive, or unrelated pages, or recently created profiles with very few posts and minimal user engagement. In some cases, comment sections are disabled or dominated by spam and automated content, suggesting an attempt to avoid public interaction rather than engage with customers.
Lastly, the payment options offered by the site can also tell a lot about its legitimacy. Be extremely cautious if a website only accepts cryptocurrency, wire transfers, or third-party P2P payments. These payment methods are irreversible and are preferred by scammers. Legitimate e-commerce platforms typically offer secure and reversible payment options, such as credit cards or trusted payment gateways that include buyer protection policies.
However, the absence or existence of any of these factors alone does not necessarily indicate malicious intent. It should be evaluated in combination with technical, linguistic, and behavioral indicators, rather than treated as a standalone signal of legitimacy.
Technical indicators to check
Looking into technical signs can reveal whether a website is trustworthy or potentially fraudulent.
One of the first things to check is the domain age. Scam websites are often short-lived, appearing only for a few weeks or months before disappearing once users start reporting them. To check when the domain was created, use a WHOIS lookup. If it’s less than six months old, be cautious — especially for e-commerce or investment sites, where legitimacy and trust take time to build.
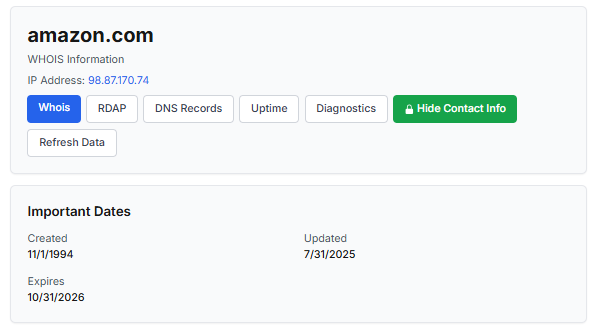
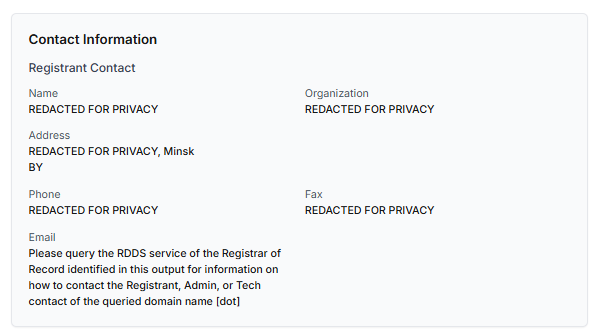
Let’s take a look at the registration details for the popular online marketplace Amazon. As we can see from the WHOIS information, it was registered in 1994.
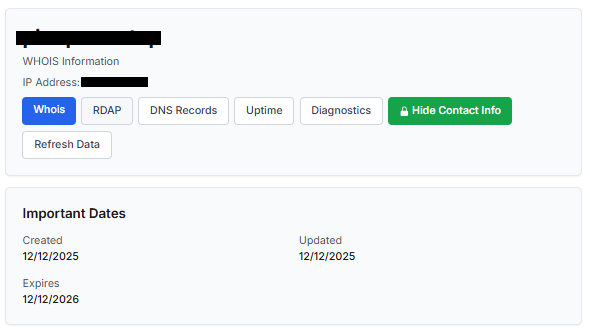
Meanwhile, a reported suspicious online store was created a couple of months ago.
Legitimate websites usually operate on stable hosting platforms and remain on the same IP addresses or networks for long periods. In contrast, fraudulent websites often move between servers (in most cases using a cheap shared hosting service) or reuse infrastructure already associated with abuse. Checking the IP address reputation can reveal if the website or the hosting server has previously been linked to suspicious activities. Even if the website looks legitimate, a poor IP reputation can expose it.
In addition to that, looking at the infrastructure behavior over time can reveal patterns about its legitimacy. Websites associated with fraudulent activity often show short lifespans, sudden spikes in activity, or rapid appearance and disappearance, which indicates a coordinated campaign rather than a legitimate business.
Another important clue is hidden ownership. When the WHOIS details show “Redacted for Privacy” or leaves the organization name blank, it may indicate that the website owner is deliberately hiding their identity.
We should point out that while this can raise suspicion during investigations, hidden WHOIS data is not inherently malicious. Many legitimate businesses use privacy protection services for valid reasons. These may include protection from spam and phishing after public email addresses are taken from WHOIS databases, personal safety for small business owners, and brand protection to prevent competitors or malicious actors from targeting the registrant. This means that some businesses can use services like WHOIS Privacy Protection, Domains By Proxy, or PrivacyGuardian.org to remove the WHOIS data while still operating transparently on their websites through clear contact details, customer support channels, and legal pages (e.g. terms of use).
Therefore, hidden ownership should be treated as a contextual risk indicator, not a standalone proof of fraud. It becomes more suspicious when combined with other signals such as newly registered domains, and lack of legal information.
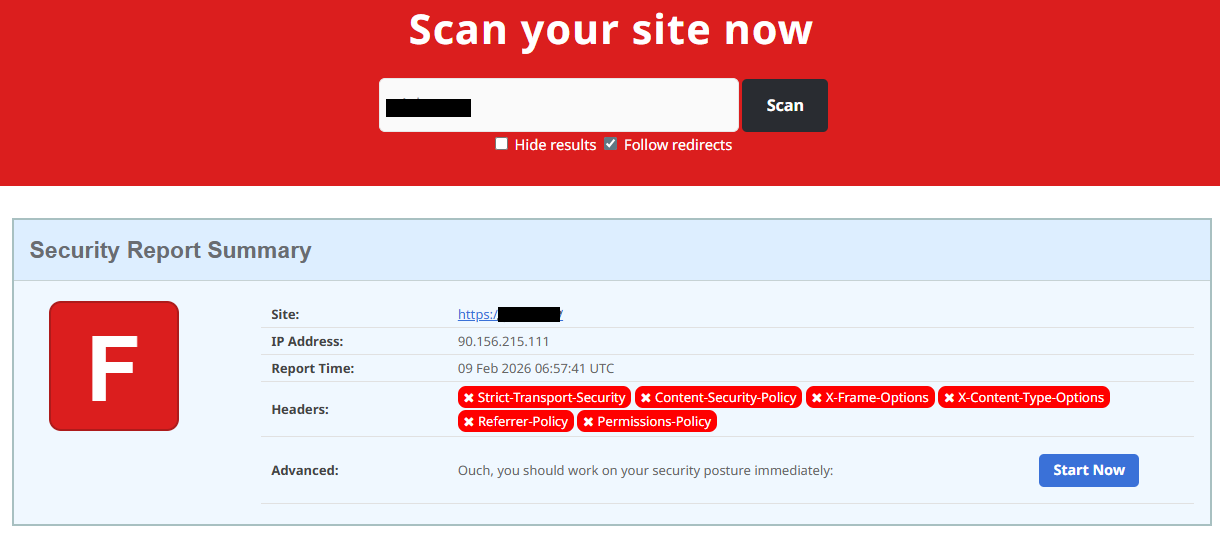
Next, you can check the security headers of the website. Legitimate websites are usually well maintained and include several key HTTP headers for protection. Some examples include:
Content-Security-Policy (CSP) provides strong defense against cross-site scripting (XSS) attacks by defining which scripts are allowed to run on the site and blocking any malicious JavaScript that could steal login data or inject fake forms.
HTTP Strict-Transport-Security (HSTS) forces browsers to connect to the site only over HTTPS. It ensures all communication is encrypted and prevents redirecting users to an insecure (HTTP) version of the site.
X-Frame-Options prevents clickjacking, which is a type of attack where a legitimate-looking button or link on a malicious page secretly performs another action in the background.
X-Content-Type-Options blocks MIME-type attacks by preventing browsers from misinterpreting file types.
Referrer-Policy controls how much information about your previous browsing (referrer URLs) is shared with other sites.
These headers form the “digital hygiene” of a website. Their absence doesn’t always mean a site is malicious, but it does suggest a lack of security awareness or professional maintenance — both strong reasons to be cautious.
You should also check the SSL certificate. Scam sites may use self-signed or short-lived SSL certificates. You can inspect this by clicking the padlock icon in your browser’s address bar — if it says “not secure” or the certificate authority seems unfamiliar, that’s a red flag.
You can check the security headers and the SSL certificate by sending an HTTP request programmatically or by using some online service.
Another indicator that provides insight into how well a website is done and managed is DNS configurations. Legitimate businesses typically use reliable DNS providers and maintain consistent DNS records. Missing the name server NS or mail exchange MX records may indicate poor DNS configuration. In addition to NS and MX, reputable sites also configure SPF and DMARC records to protect their brand from email spoofing and phishing. Something scam website developers won’t bother with because they don’t intend to build a long-standing reputation.
You can check the configurations of DNS records either programmatically or by using an online service.
Another recommendation is to pay attention to website behavior. If there are frequent redirects, pop-up ads, or background requests to unknown domains, this may indicate unsafe scripting or tracking.
How to protect yourself
Tools and databases for detecting suspicious websites
We at Kaspersky have built an intelligent system for detecting suspicious web resources and added this new type of protection into many of our products, including Kaspersky Premium, Kaspersky for Android and iOS, and others. Our detection model is based on many factors, including but not limited to the following:
domain name and age,
IP reputation,
stability of the infrastructure used,
DNS configurations,
HTTP security headers,
digital identity and popularity of the web resource.
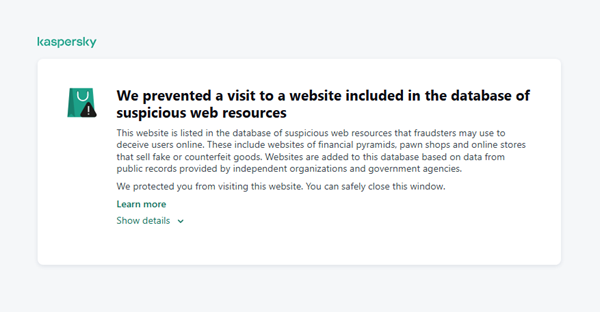
When a user tries to visit a site flagged as having an undefined trust level, our solutions show a warning to stop the visitor from becoming a victim of personal data leaks, financial losses or a bad purchase:
This component is on by default.
Moreover, there are several online tools and databases that can help assess a website’s legitimacy:
ScamAdviser analyzes trust based on WHOIS, server location, and web reputation.
APIVoid provides risk scoring using DNS, IP, and domain reputation databases.
National government databases often maintain official lists of fraudulent or blacklisted domains.
Preventive measures
To protect yourself from such threats, it might a good idea to take some additional preventive measures. Always double-check the URL and domain name, especially when you are about to click a link or make a payment. Make sure the site uses HTTPS and has a trusted certificate.
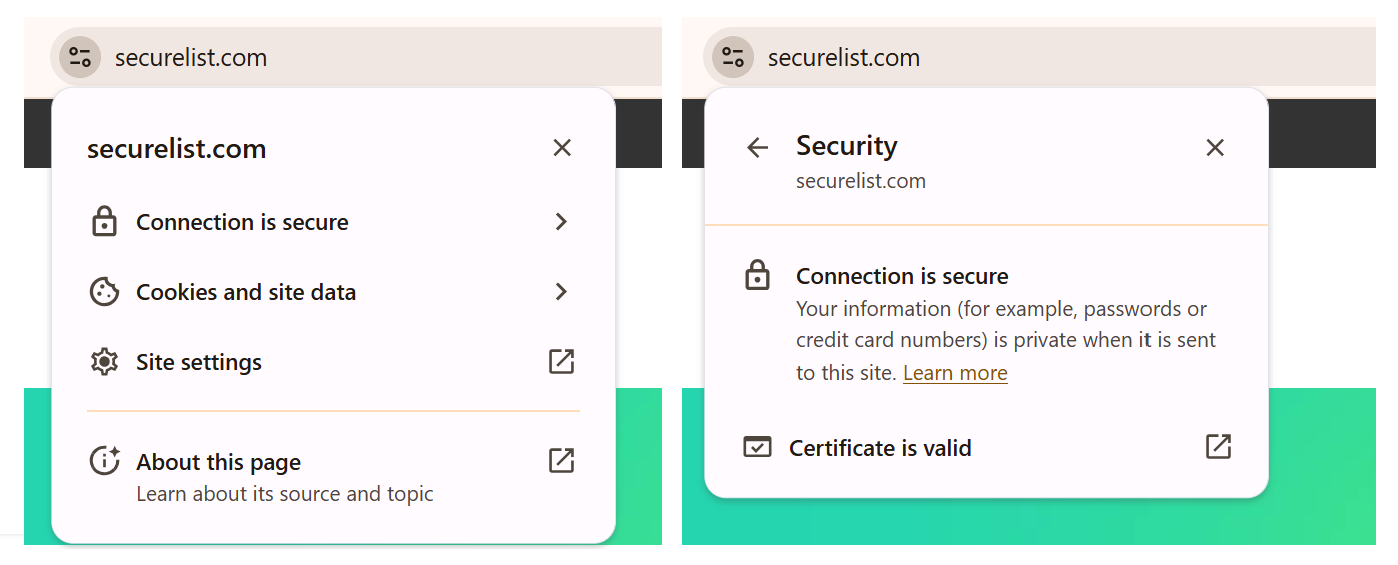
You can use standard browser tools to verify site security. For example, in Google Chrome, clicking the site information button (the lock or settings icon in the address bar) displays details about the connection security and the site’s certificate.
In the Security section, you can check whether the site supports HTTPS – it should say “Connection is secure” – and view the site’s digital certificate.
Additionally, keep reliable security software with real-time protection running on your device to stop you from accessing dangerous websites. Do not download any files or enter your personal information on websites that look unprofessional or suspicious. And finally, remember the golden rule: if a deal seems too good to be true, it often is.
If you realize that you’re on a scam website, it’s important to perform certain post-incident actions immediately. First, contact your bank or payment provider as soon as possible to block the transaction or card. Then, change your passwords for the services which might have been compromised, and run a full antivirus scan on your device to detect and remove any potential threats. Lastly, consider reporting the website to the cybercrime agency in your country or to the consumer protection agency. Sharing your experience online by leaving a review or warning will give notice to potential customers alike.
By staying careful and taking quick actions, you can significantly reduce the chances of being a target and help make the internet a safer place for everyone.
An overview of detection statistics for sites with an undefined trust level
To illustrate the types of suspicious sites prevalent in various regions around the world, we analyzed anonymized detection data from Kaspersky solutions for the “websites with an undefined trust level” category in January 2026. For each region, we identified the 10 most frequently encountered sites and calculated the share of each within that list. To maintain privacy, specific domains are not listed directly; instead, they’re described based on their functionality and characteristics.
Most visited suspicious sites
First, let’s examine the sites that appear across multiple regions, indicating a high prevalence.
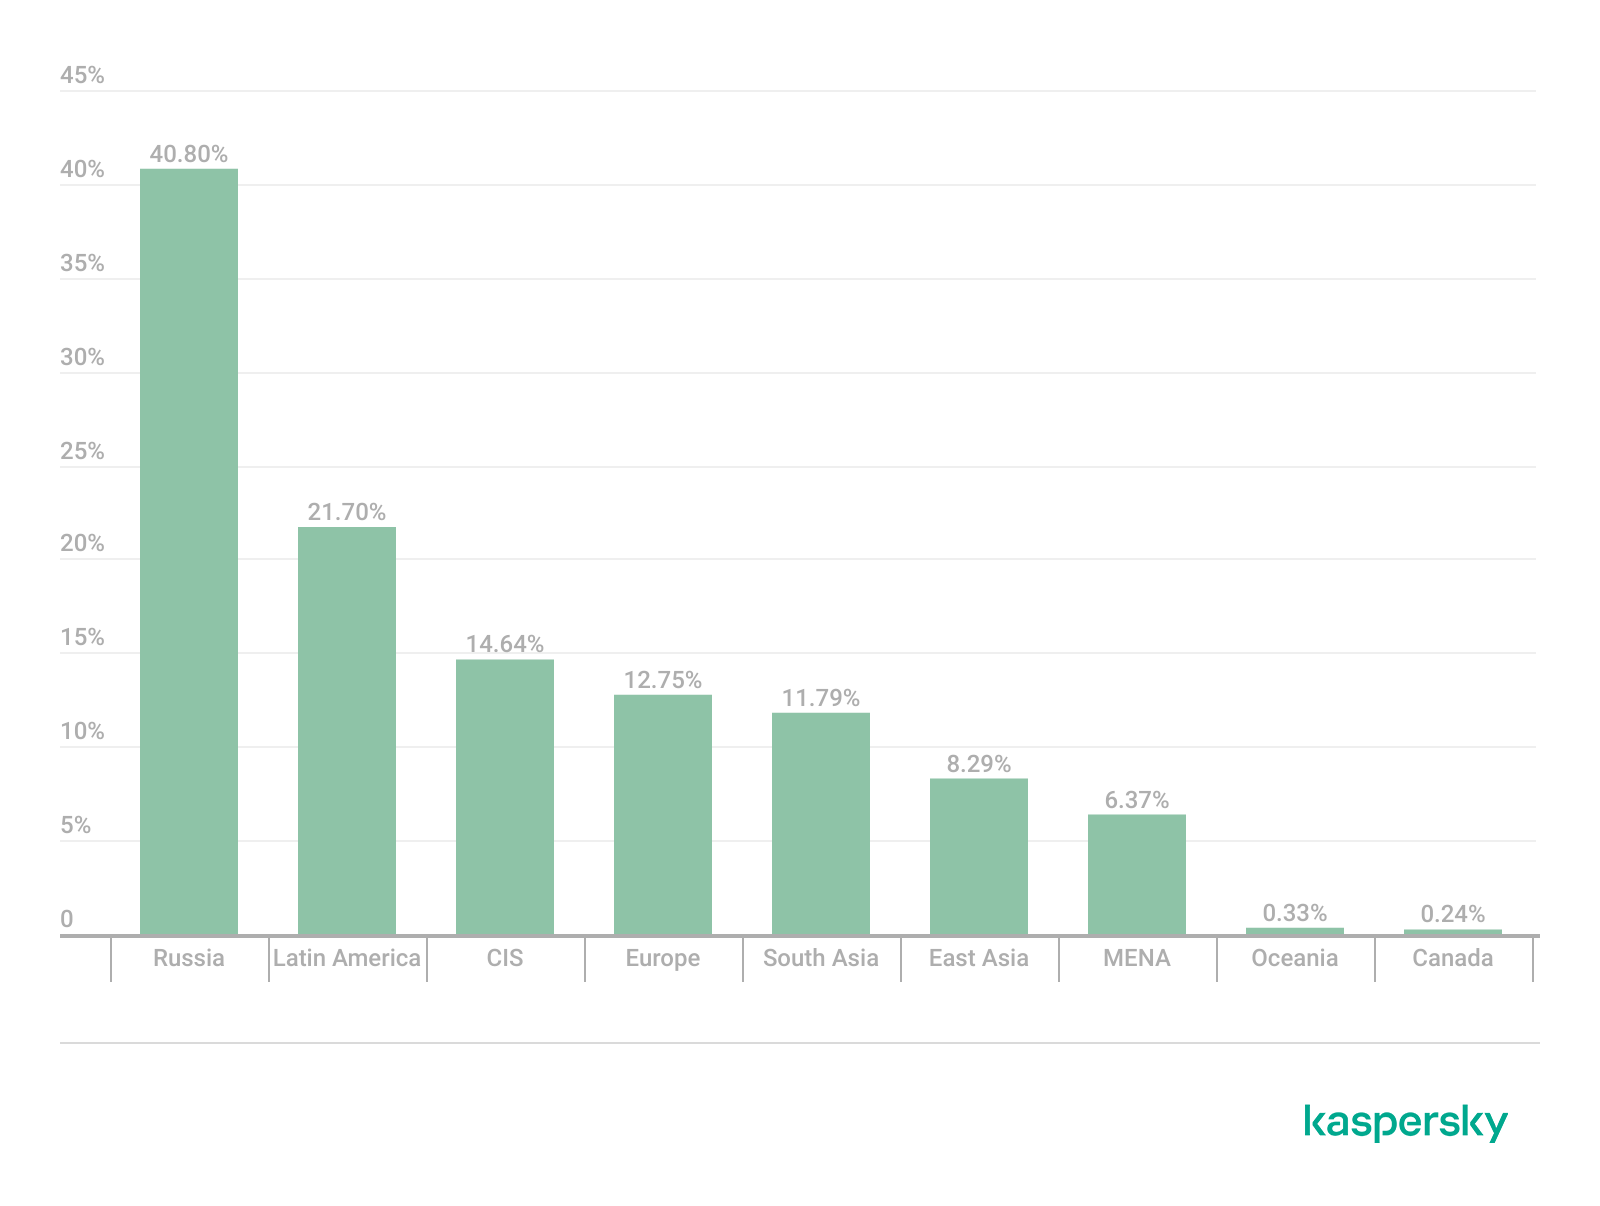
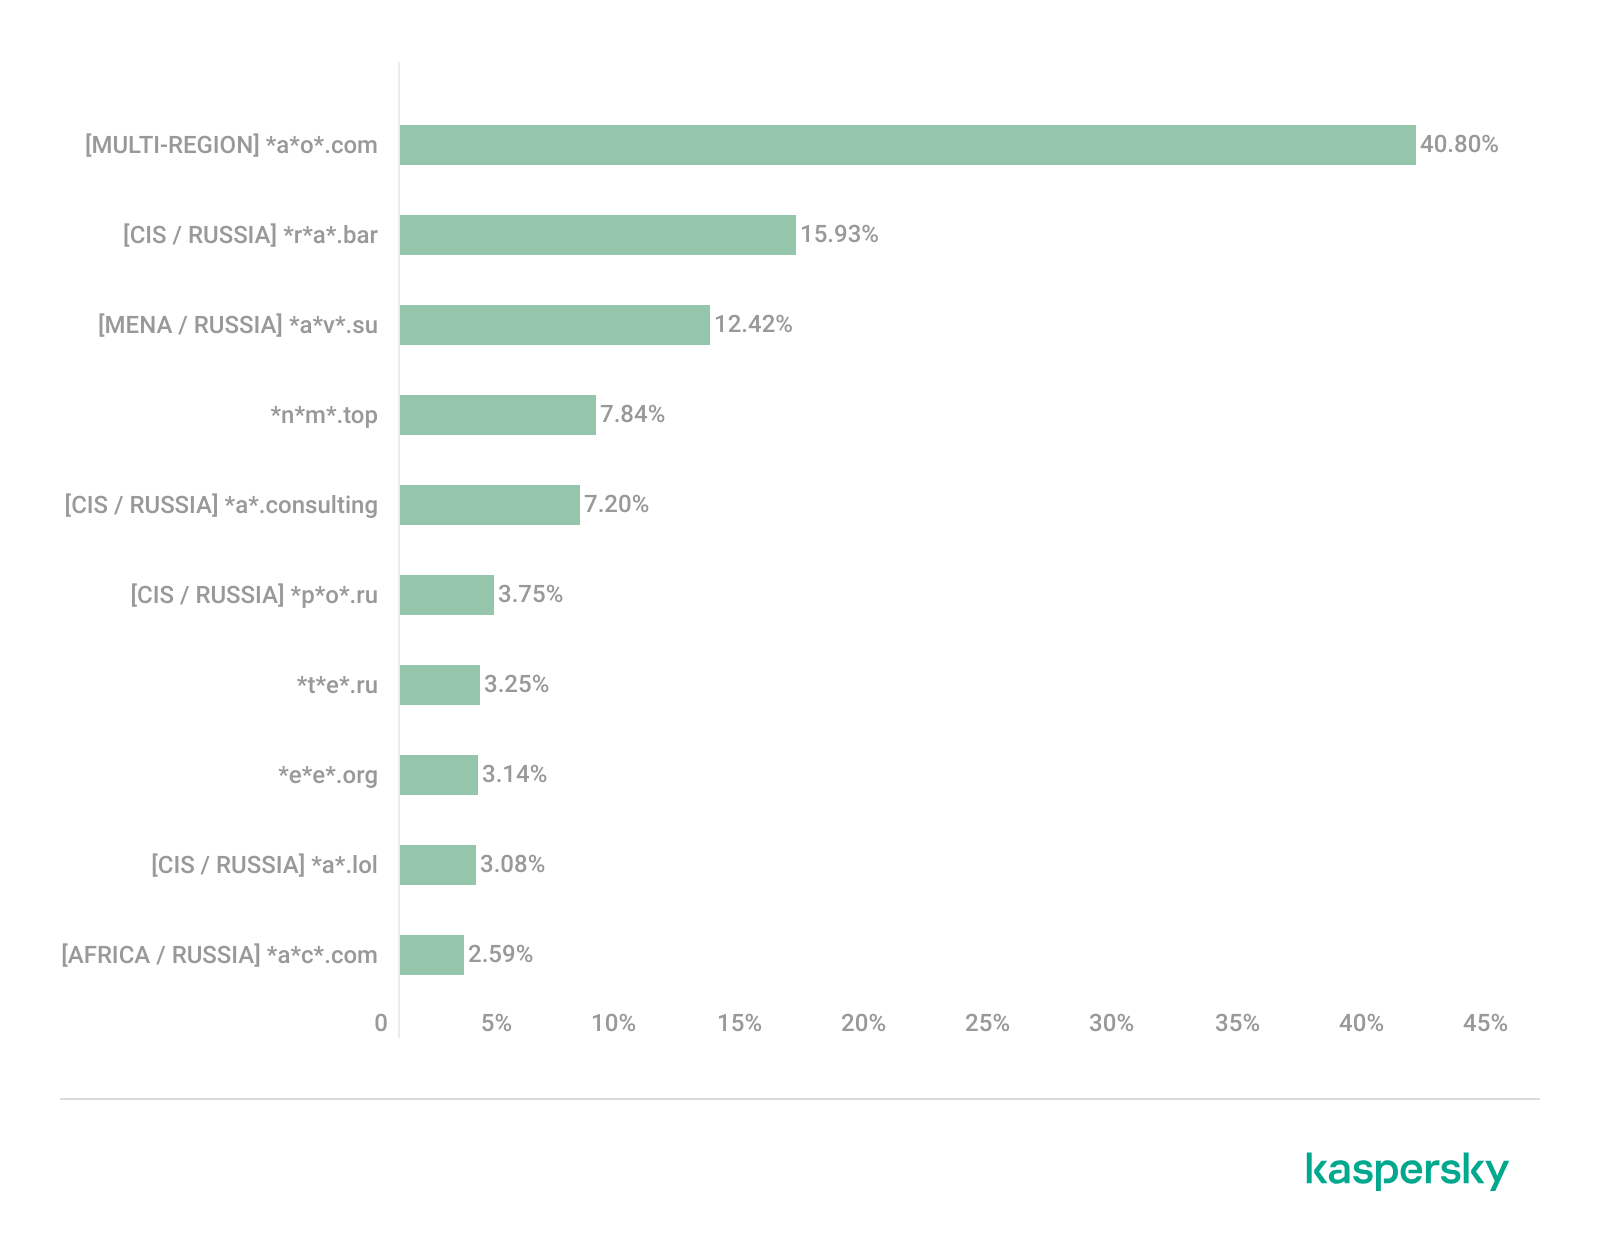
In 9 out of the 10 regions analyzed, we encountered a suspicious image processing platform (*a*o*.com). This site positions itself as a photo editing tool, but in reality, it serves as an intermediary server for uploading images used in phishing and other campaigns. By interacting with such a site, users risk exposing personal data under the guise of uploading images or falling victim to a phishing attack.
Percentage of the *a*o*.com domain detections by region, January 2026 (download)
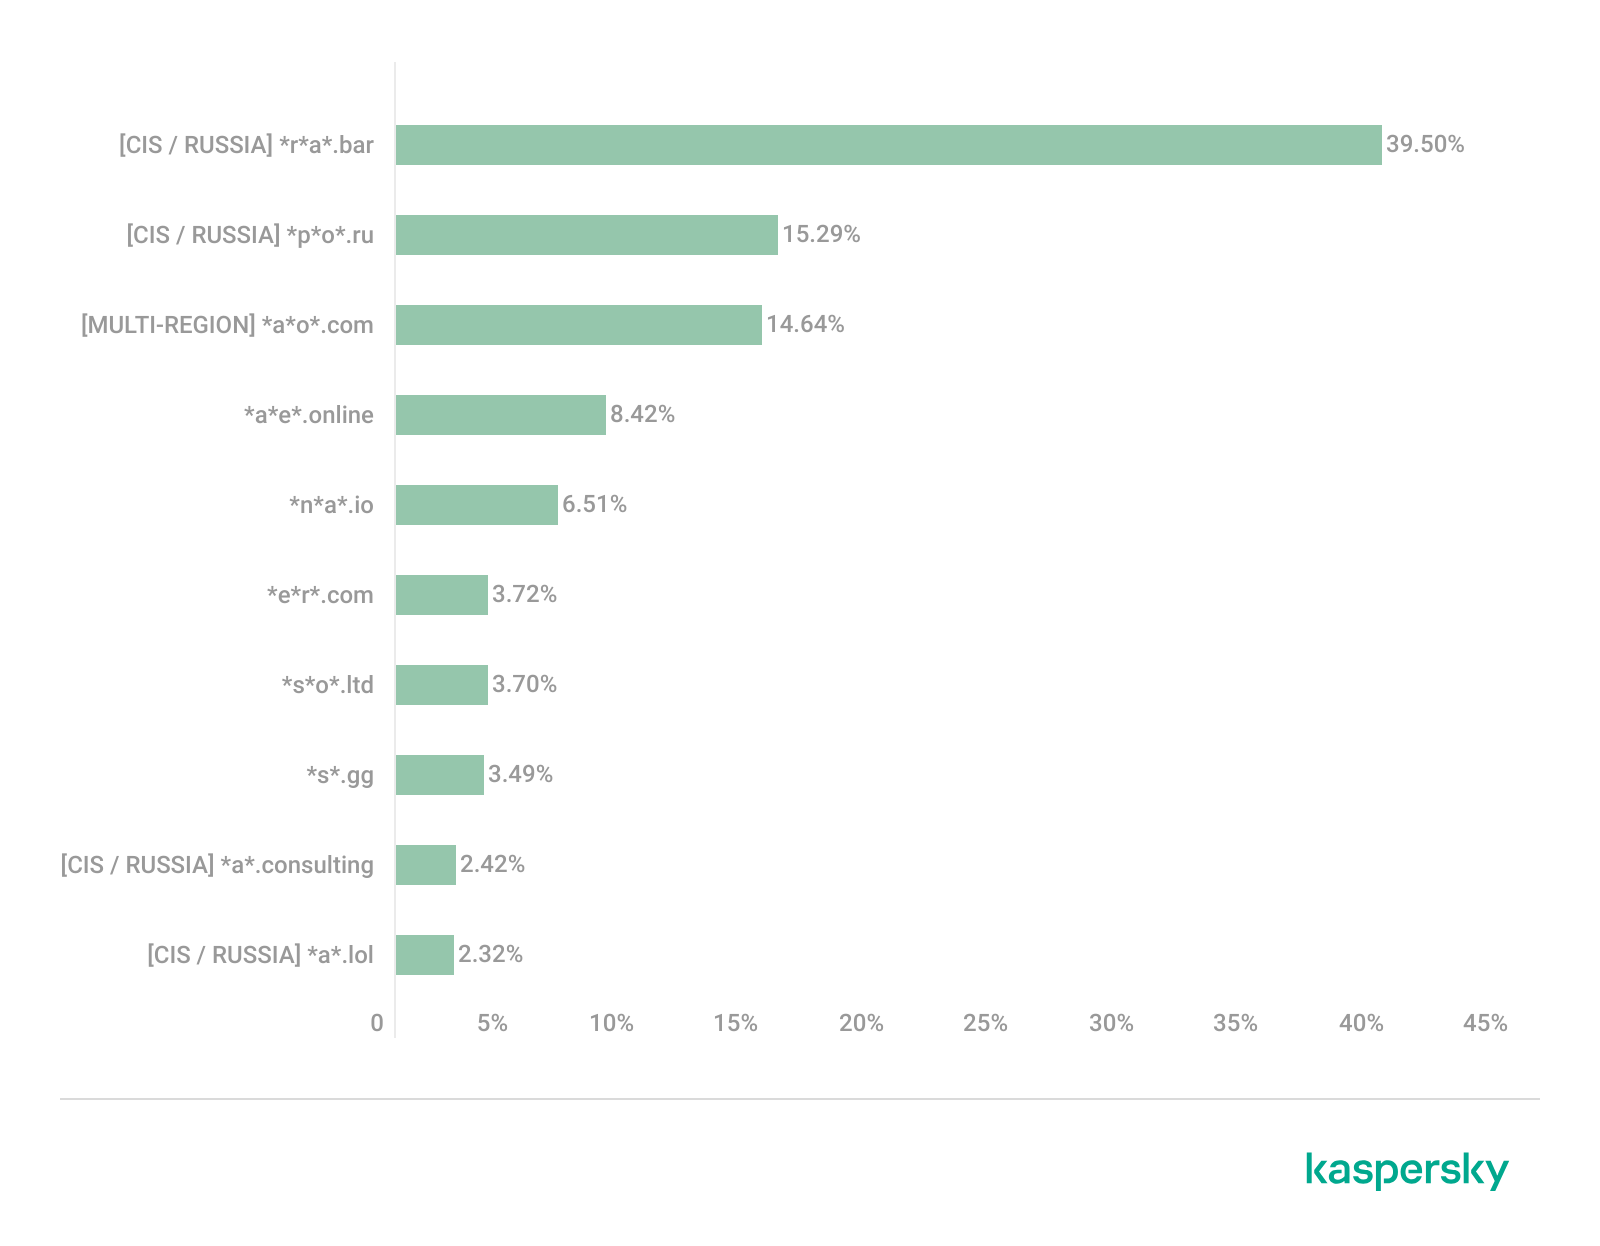
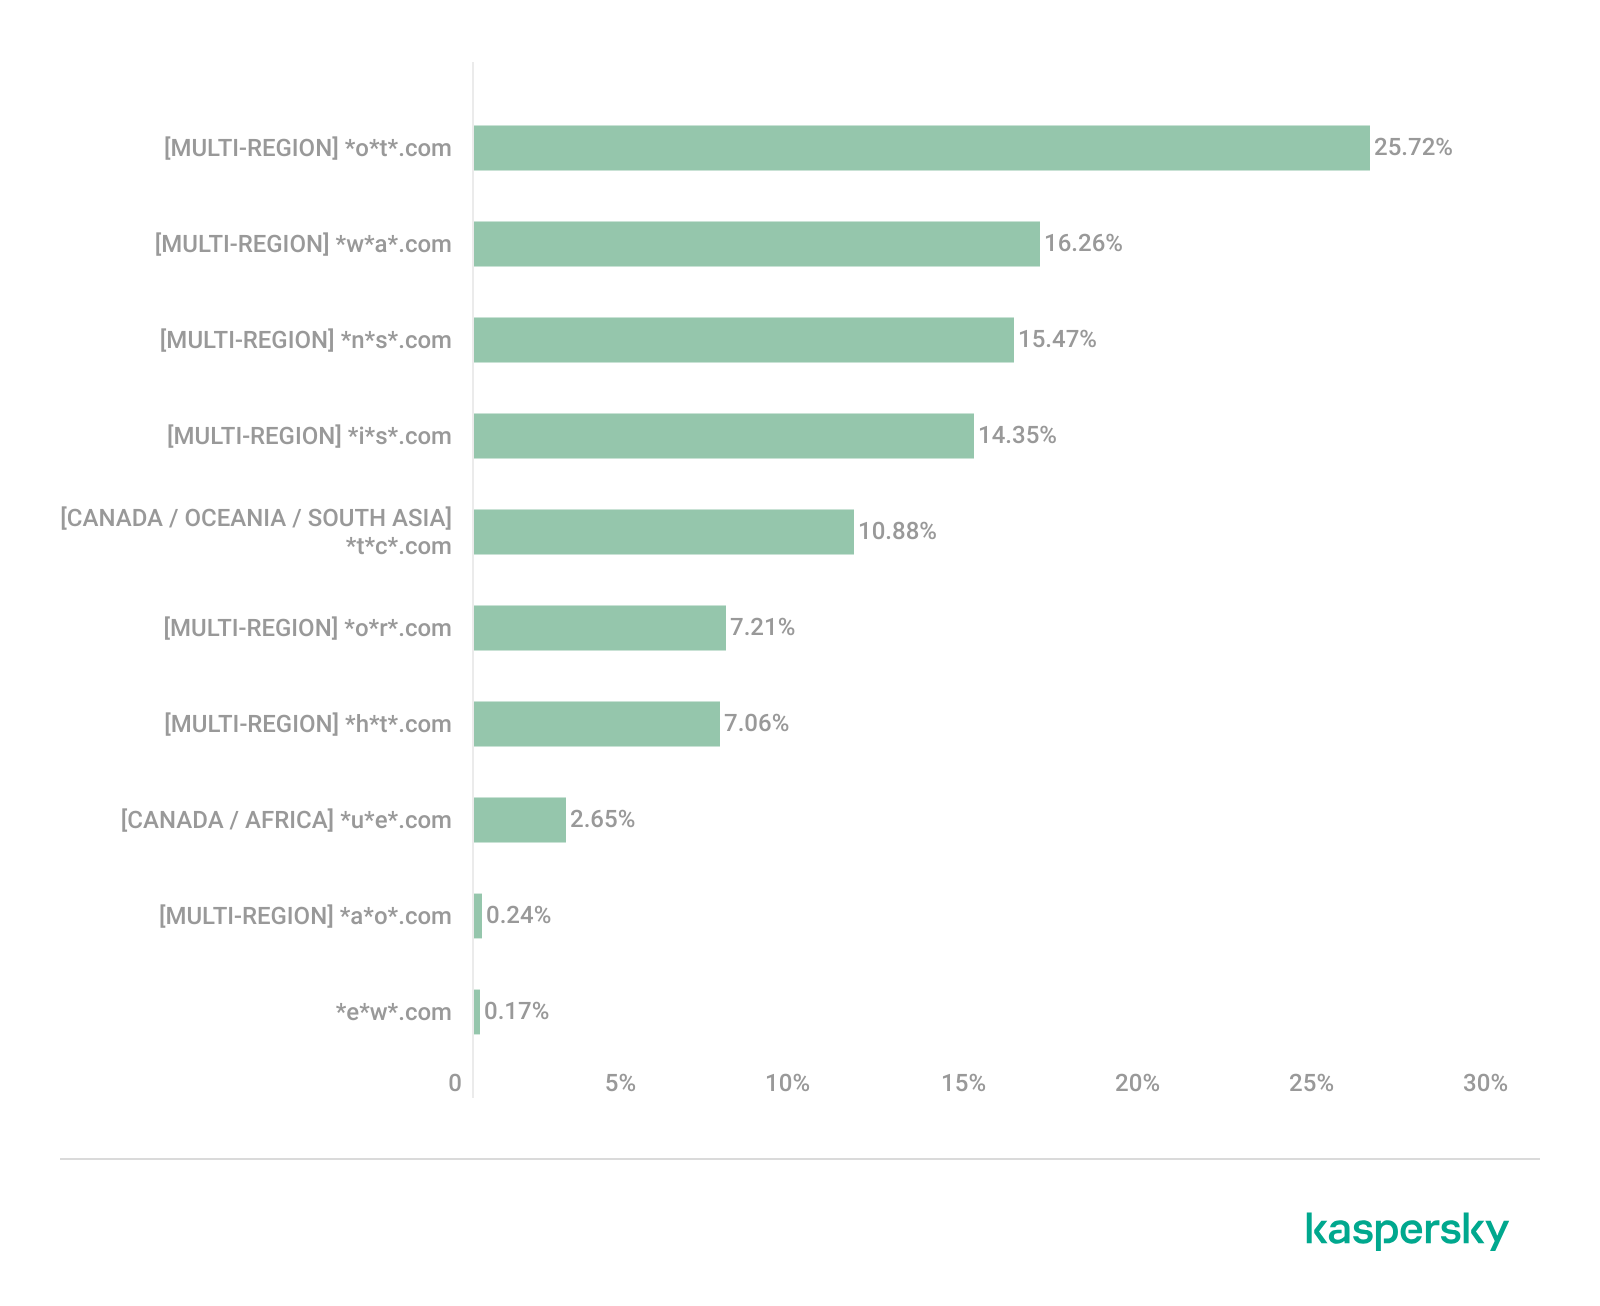
This site has the largest share of detections in the Russian Federation, where it ranks first in the TOP 10 with a 40.80% share. It is also prevalent in Latin American countries (21.70%) and the CIS (14.64%), while it’s least common in Canada at 0.24%.
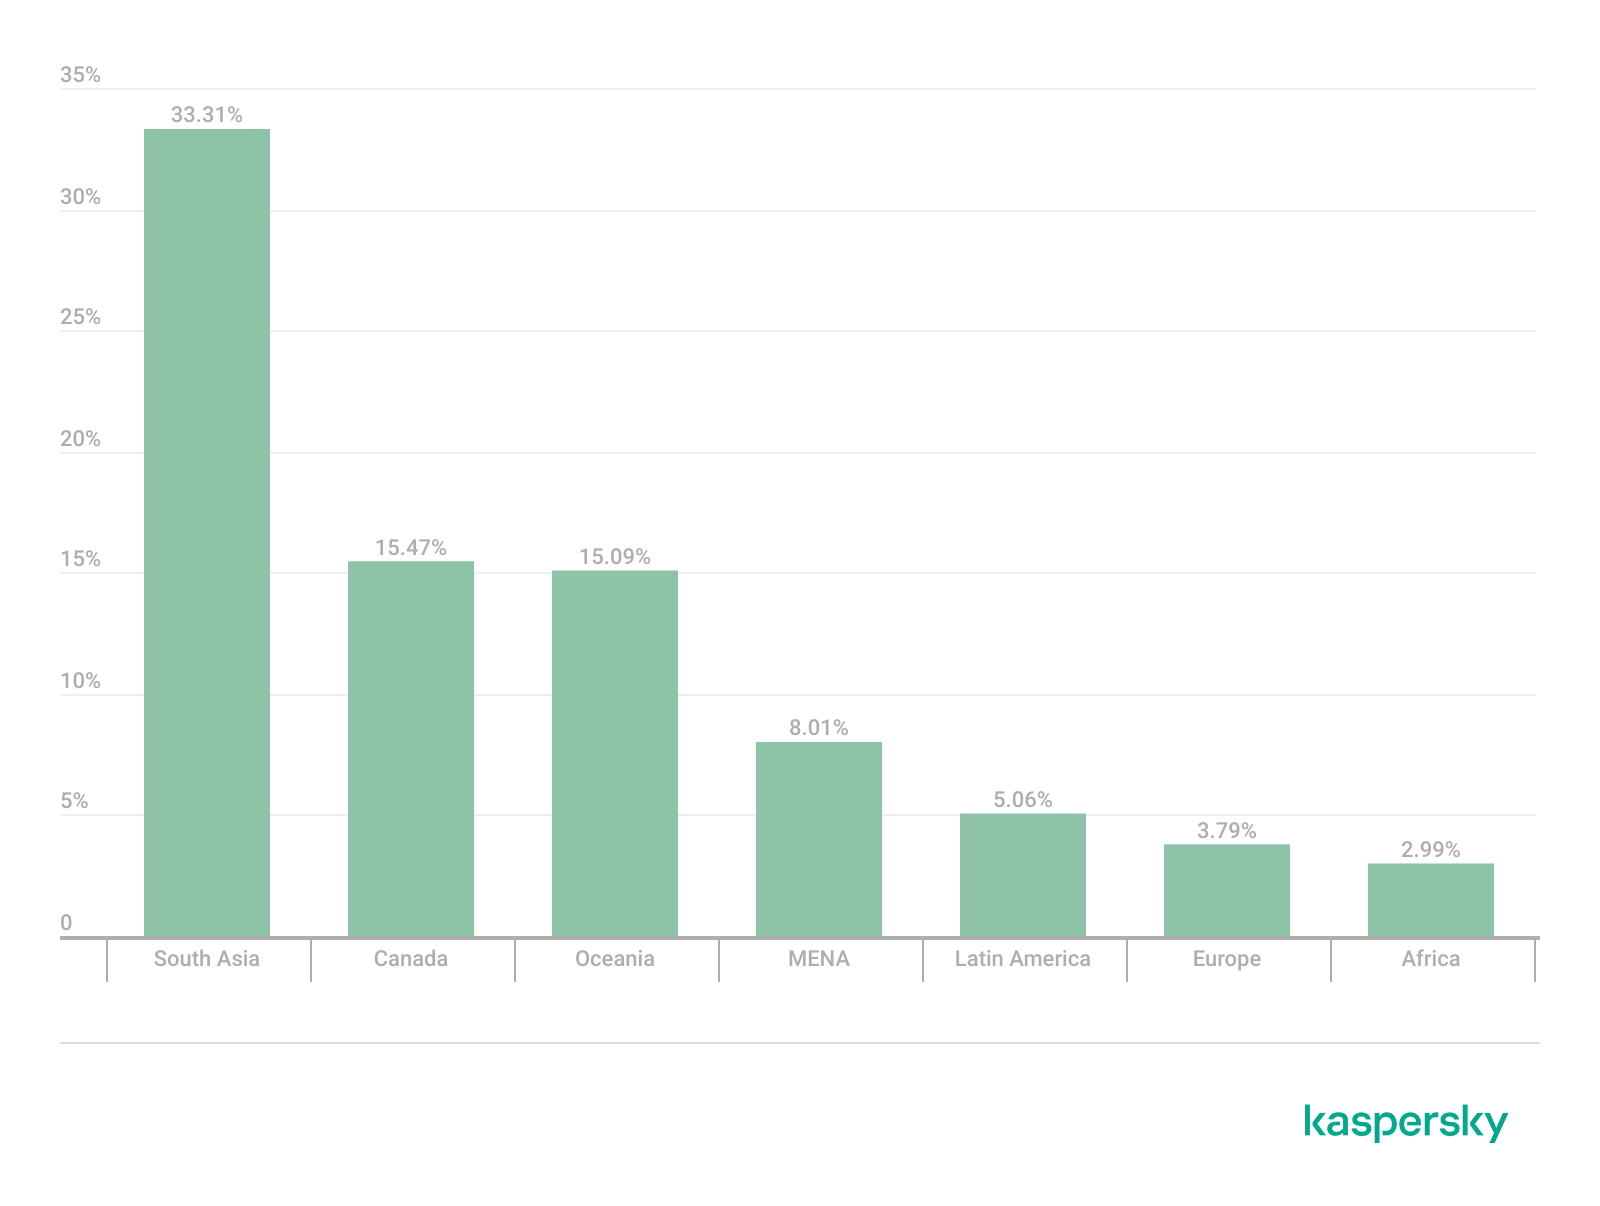
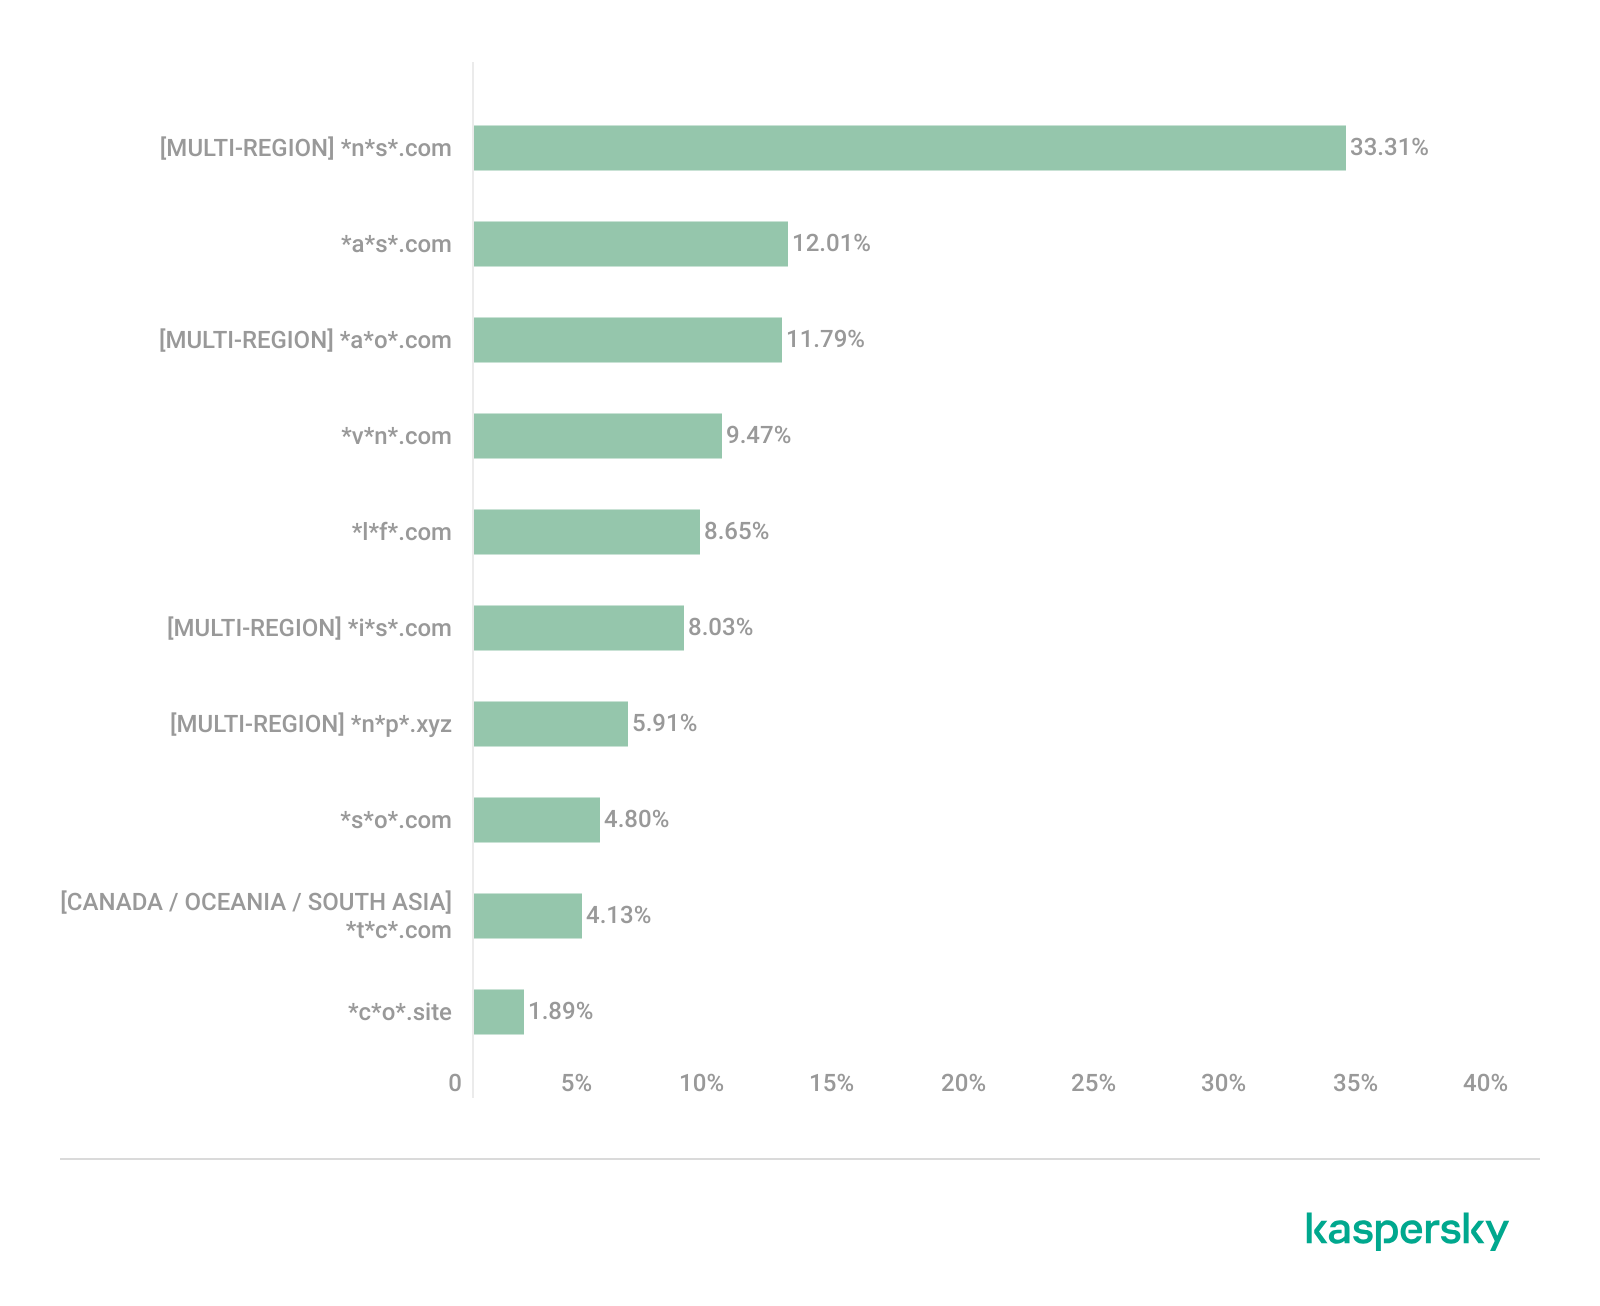
The next site appeared in 7 regions. It consists of a landing page for a fake antivirus solution presented as a browser extension (*n*s*.com). This extension redirects the user to a fake search engine page allowing it to collect data and track user activity, specifically search queries.
Percentage of the *n*s*.com domain detections by region, January 2026 (download)
This site is most frequently detected in South Asia, with a share of 33.31%. Its presence in Canada and Oceania is roughly equal (15.47% and 15.09%, respectively). We recorded the lowest number of detections in Africa, at 2.99%.
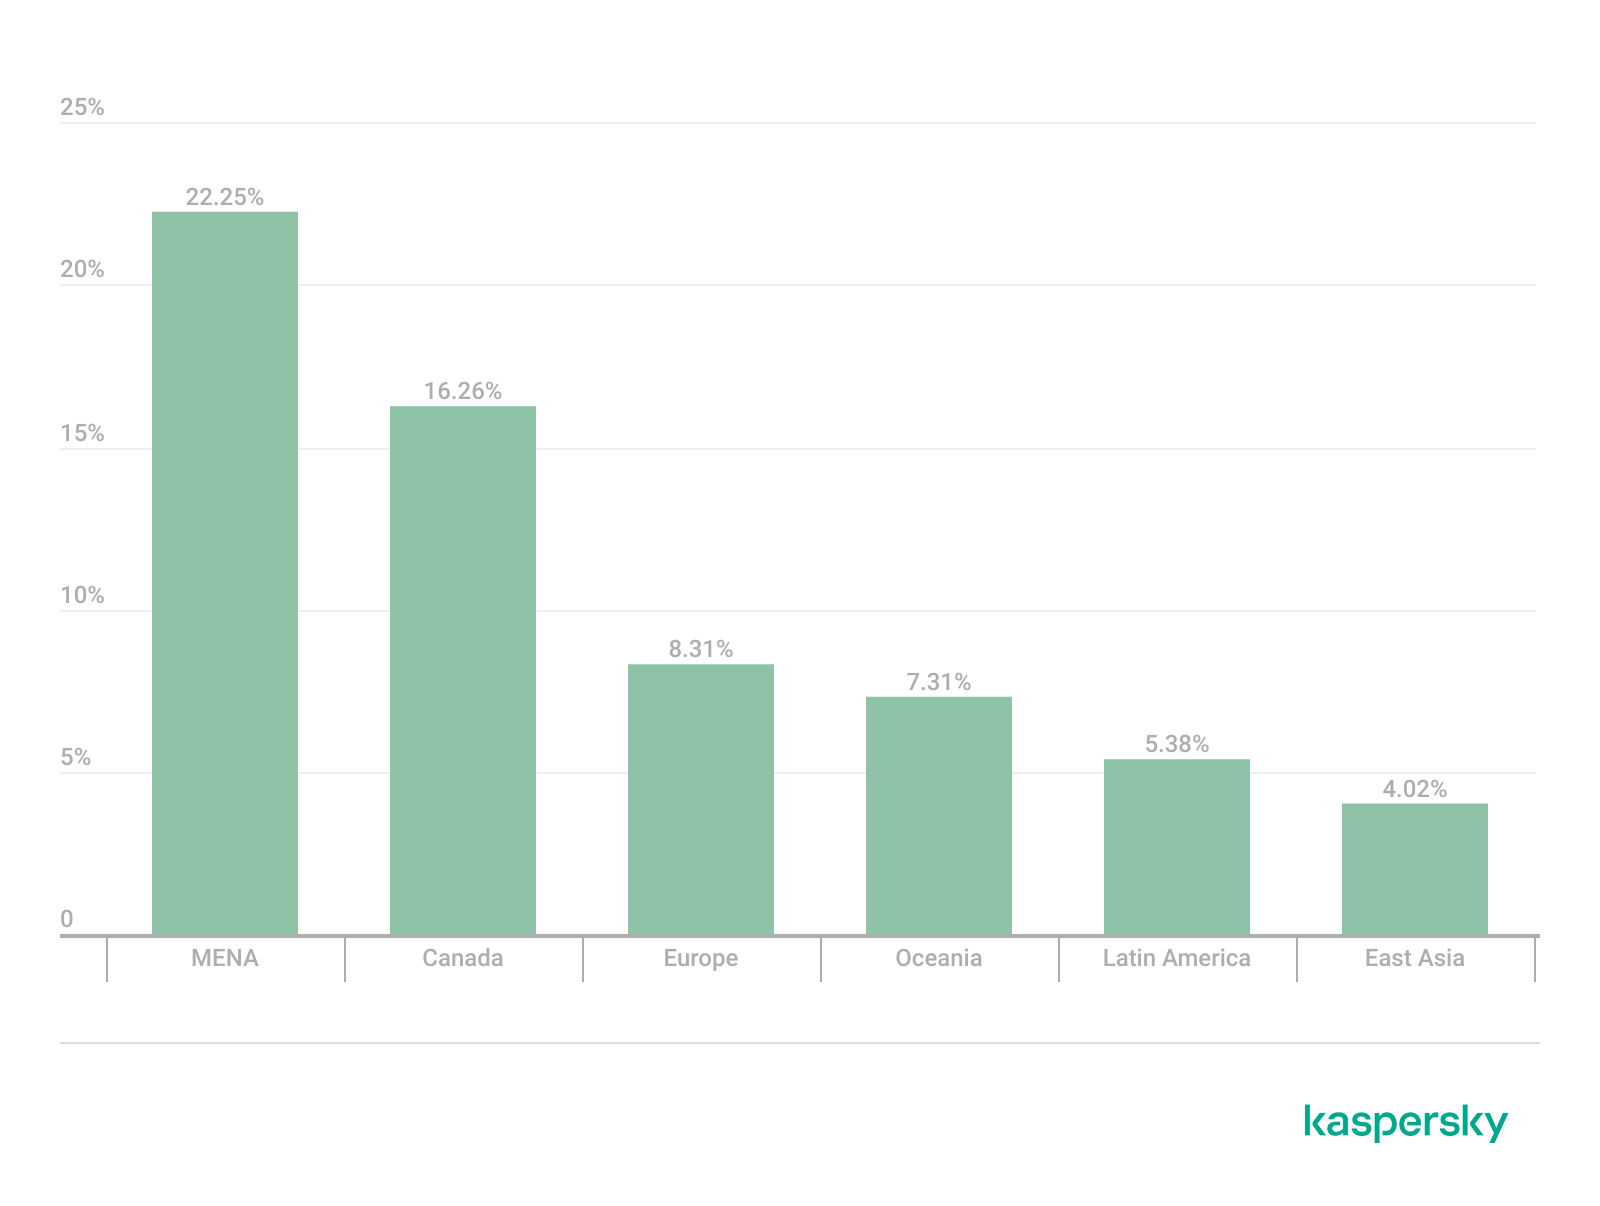
Another suspicious browser extension appeared in the TOP 10 in 6 out of the 10 regions. It’s a fake privacy-enhancing tool hosted at *w*a*.com. Instead of providing the advertised privacy features, this extension carries a high risk of intercepting browser data. It can modify browser settings, harvest user data, and swap the default search engine for a fake one. Furthermore, it maintains full control over all browser traffic.
Percentage of the *w*a*.com domain detections by region, January 2026 (download)
This “service” has its largest share, 22.25%, in the Middle East and North Africa, and is also quite common in Canada (16.26%). It’s least frequently encountered in Latin America (5.38%) and East Asia (4.02%).
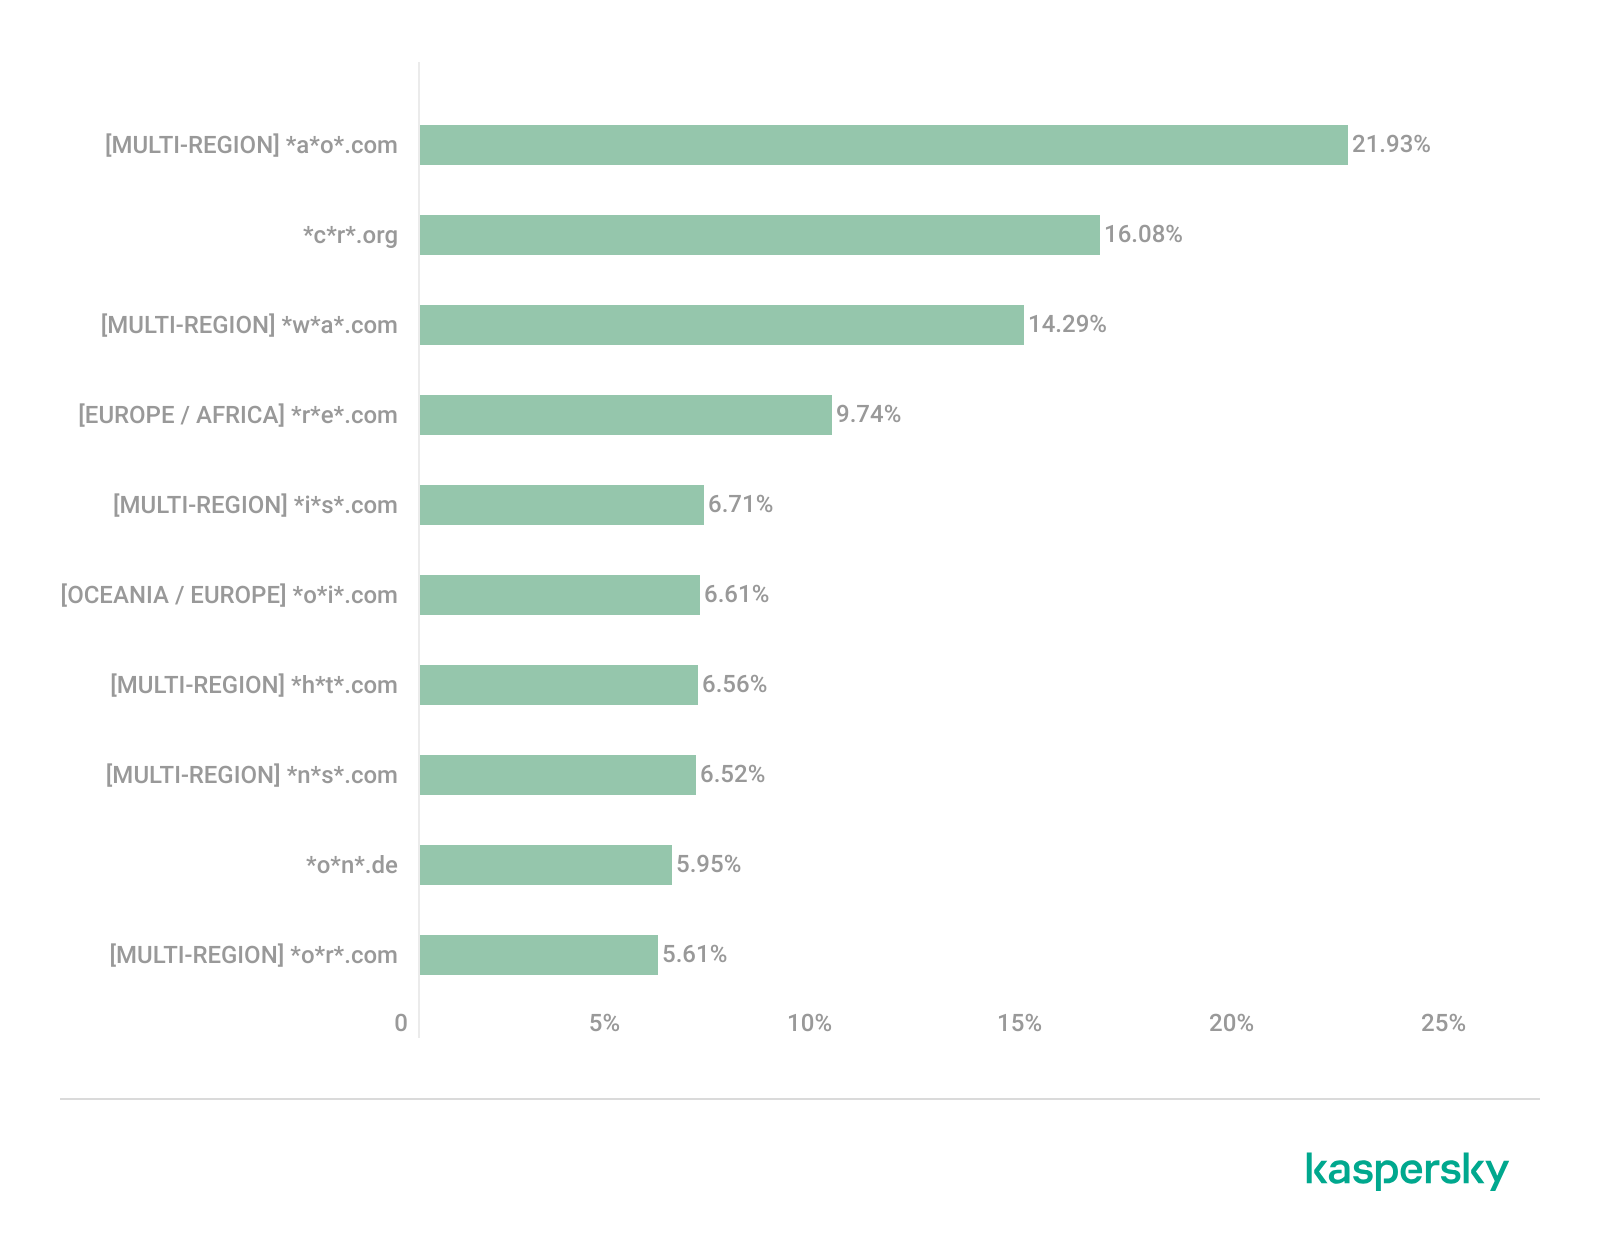
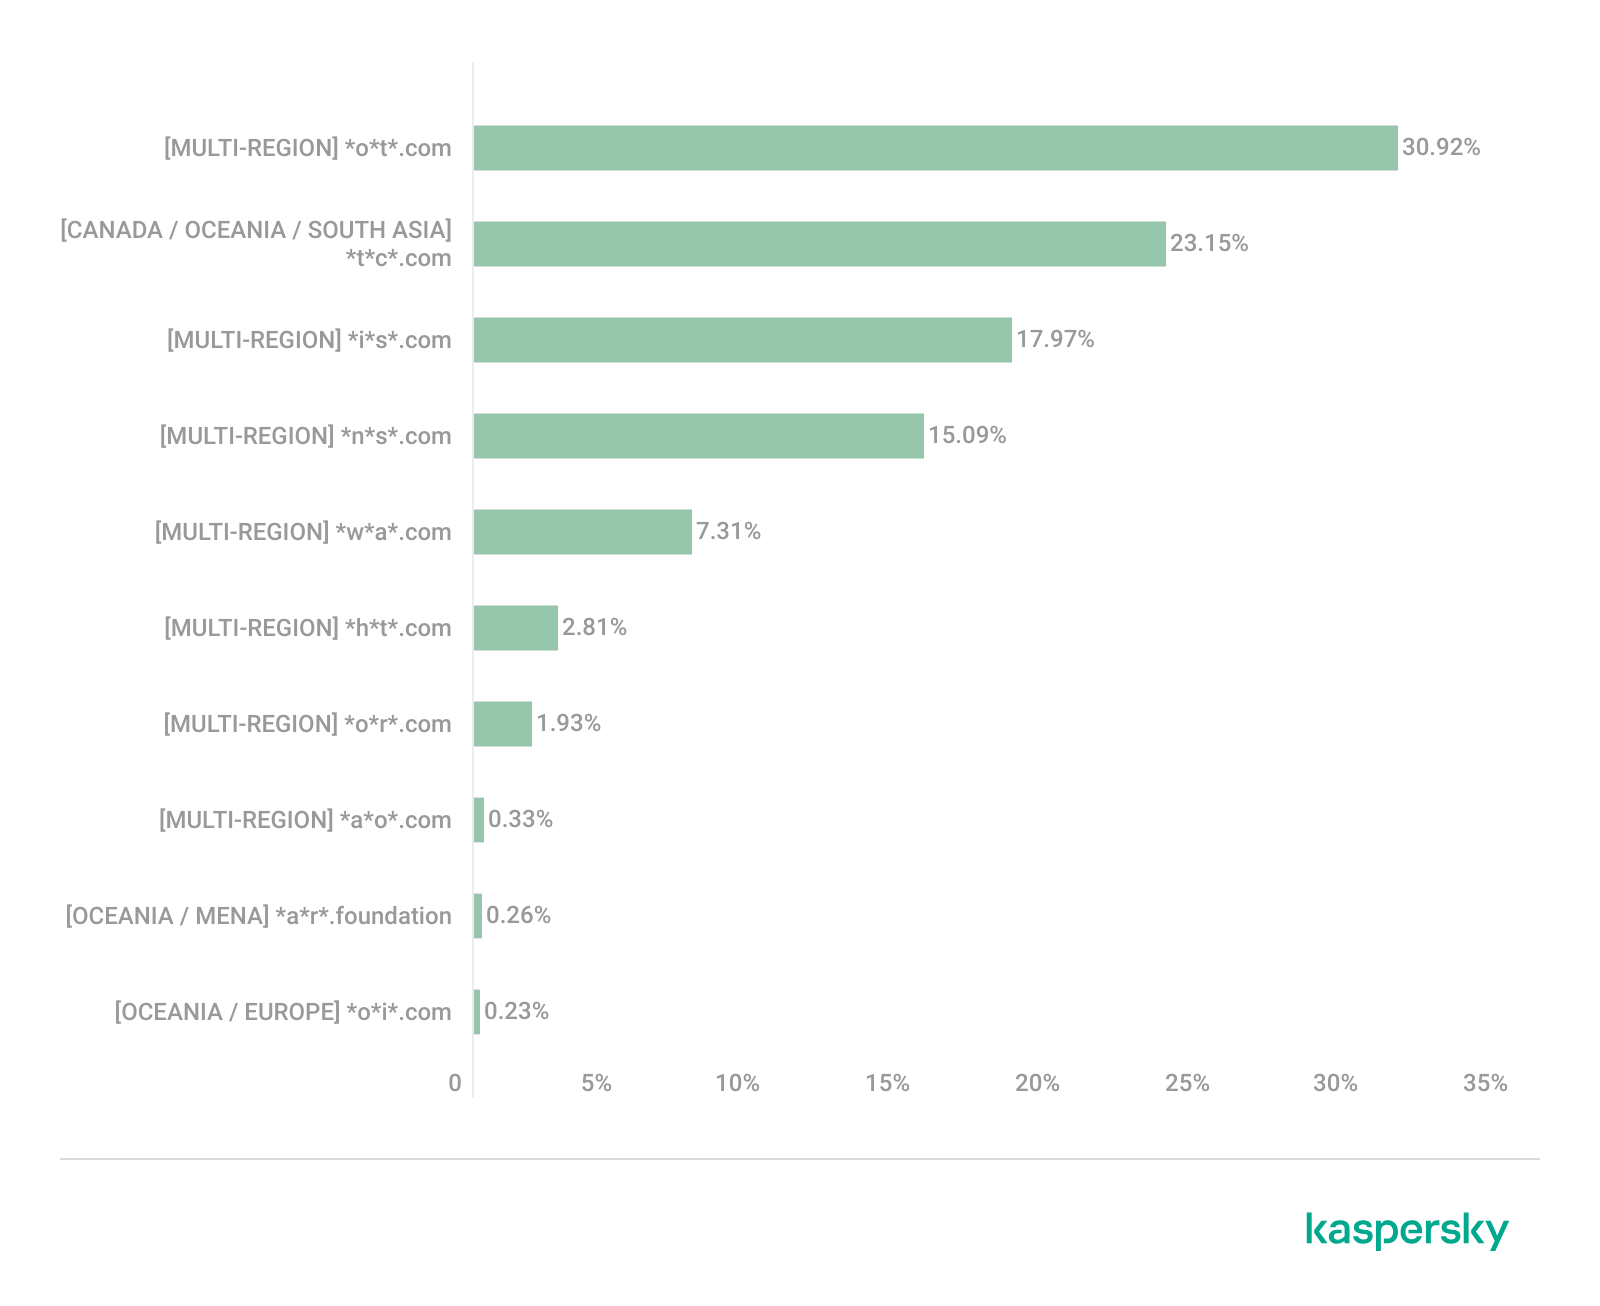
The site *o*r*.com appeared in five regional rankings. It’s a fake security service promising to provide online safety by warning users about malicious sites and dangerous search queries. This extension has the potential to steal cookies (including session cookies), inject advertisements, spoof login forms, and harvest browser history and search queries. We noted that this site made the TOP 10 in Africa (0.59%), the MENA (Middle East and North Africa) region (4.57%), Europe (5.61%), Canada (7.21%), and Oceania (1.93%).
In 4 out of the 10 regions, we identified several other recurring sites. One of them (*n*p*.xyz) mimics a repository for creative AI image generation prompts while capturing browser data. The domain hosting this site exhibits several red flags: it was recently registered, and the owner’s information is hidden. This site reached the TOP 10 in Africa (0.51%), the MENA region (7.04%), Latin America (22.54%, ranking first in that region), and South Asia (5.91%).
The second service (*i*s*.com) positions itself as a tool for safe searching, protecting the browser from threats, and verifying extensions. However, this is a typical browser hijacker, much like the others mentioned above. It made the TOP 10 in South Asia (8.03%), Oceania (17.97%), Europe (3.90%), and Canada (14.35%).
The third site (*h*t*.com) poses as a private browsing extension. In reality, it’s another potentially unwanted application designed for browser hijacking: it modifies settings, steals sensitive data (cookies, browser history, and queries), and can redirect the user to phishing pages. Users have specifically noted the difficulty involved in removing the extension. This site appears in the TOP 10 for the MENA region (10.17%), Canada (7.06%), Europe (3.81%), and Oceania (2.81%).
Another domain (*o*t*.com) that reached the TOP 10 in four regions is a service mimicking a browser extension for safe searching and web browsing. It’s dangerous because it injects ads and steals user data. It’s important to note that such extensions can be installed without explicit user consent – for example, via links embedded in other software. This service holds the number one spot in two regions: Canada (25.72%) and Oceania (30.92%), while also appearing in the TOP 10 for East Asia (8.01%) and Africa (0.88%).
Consequently, we can see that the majority of suspicious sites detected by our solutions worldwide are browser hijackers masquerading as security products. Nevertheless, other categories of sites also appear in the TOP 10.
Next, we’ll examine each region individually, focusing on descriptions of domains not previously covered. For clarity, the sites mentioned above will be marked as [MULTI-REGION], while those appearing in only two or three regions will include the names of those specific areas. We’ll observe several regional overlaps and similarities, allowing us to determine which types of suspicious sites are popular both within specific regions and globally.
Africa
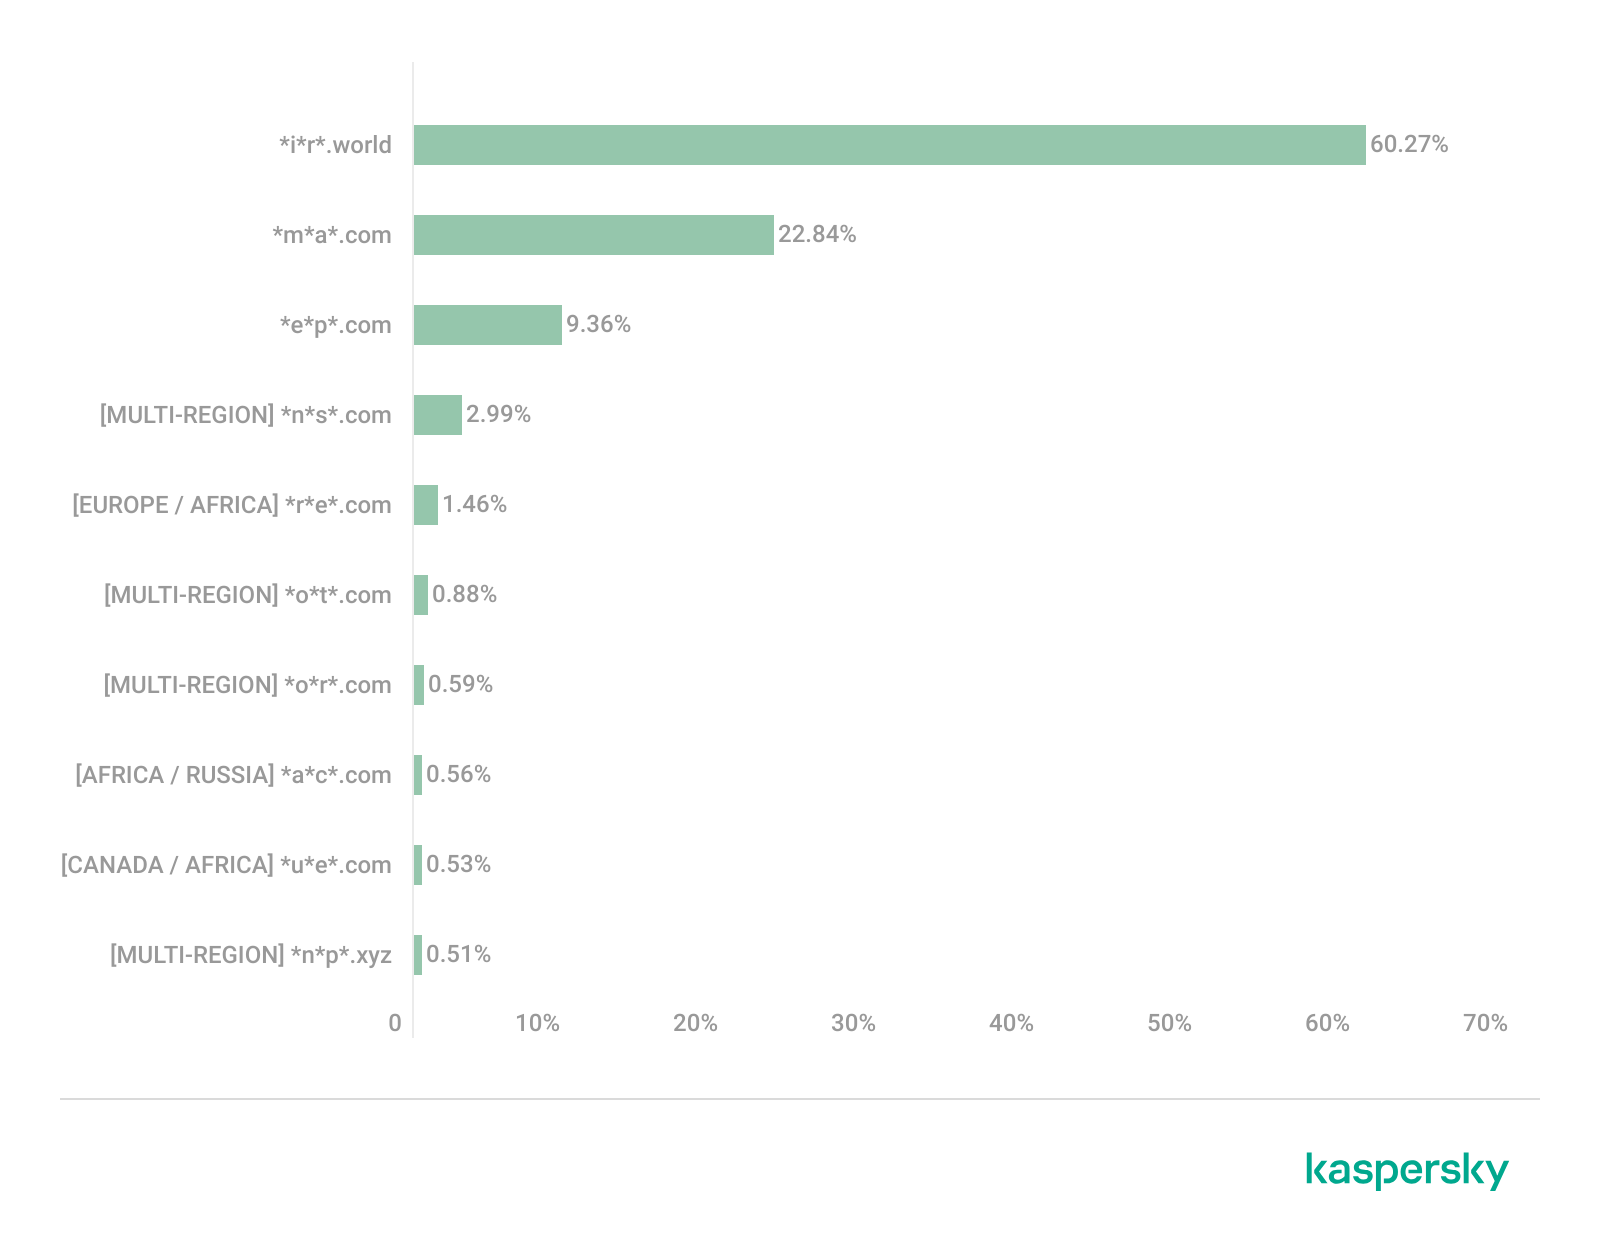
Distribution of the TOP 10 suspicious websites in Africa, January 2026 (download)
The three most prevalent domains in African countries are found exclusively in this region. All of them – *i*r*.world (60.27%), *m*a*.com (22.84%), and *e*p*.com (9.36%) – are potentially fraudulent online trading platforms suspected of using forged licenses. These sites employ classic scam schemes where it’s impossible to withdraw any alleged earnings. In fifth place is a domain we’ll also see in the European TOP 10, *r*e*.com (1.46%): a platform marketed as a tool for retail and semi-professional traders. It charges for services available elsewhere for free. Eighth place is held by a site that also appears in the Russian TOP 10: *a*c*.com (0.56%). This is a dubious AI tool that claims to offer free subscriptions to a premium graphics editor. In ninth place is a domain that also surfaces in the Canadian TOP 10: *u*e*.com (0.53%), a browser extension of the “web protection” variety that we’ve encountered previously.
In summary, the African region is dominated by financial scams within the online trading and brokerage sectors. These include fake platforms that make it impossible to withdraw funds and use fake licenses and classic schemes to steal users’ money. Additionally, Africa sees paid tools that duplicate free services and questionable AI-based subscriptions. The primary threat in this region is financial loss through fraudulent investment-themed sites.
MENA
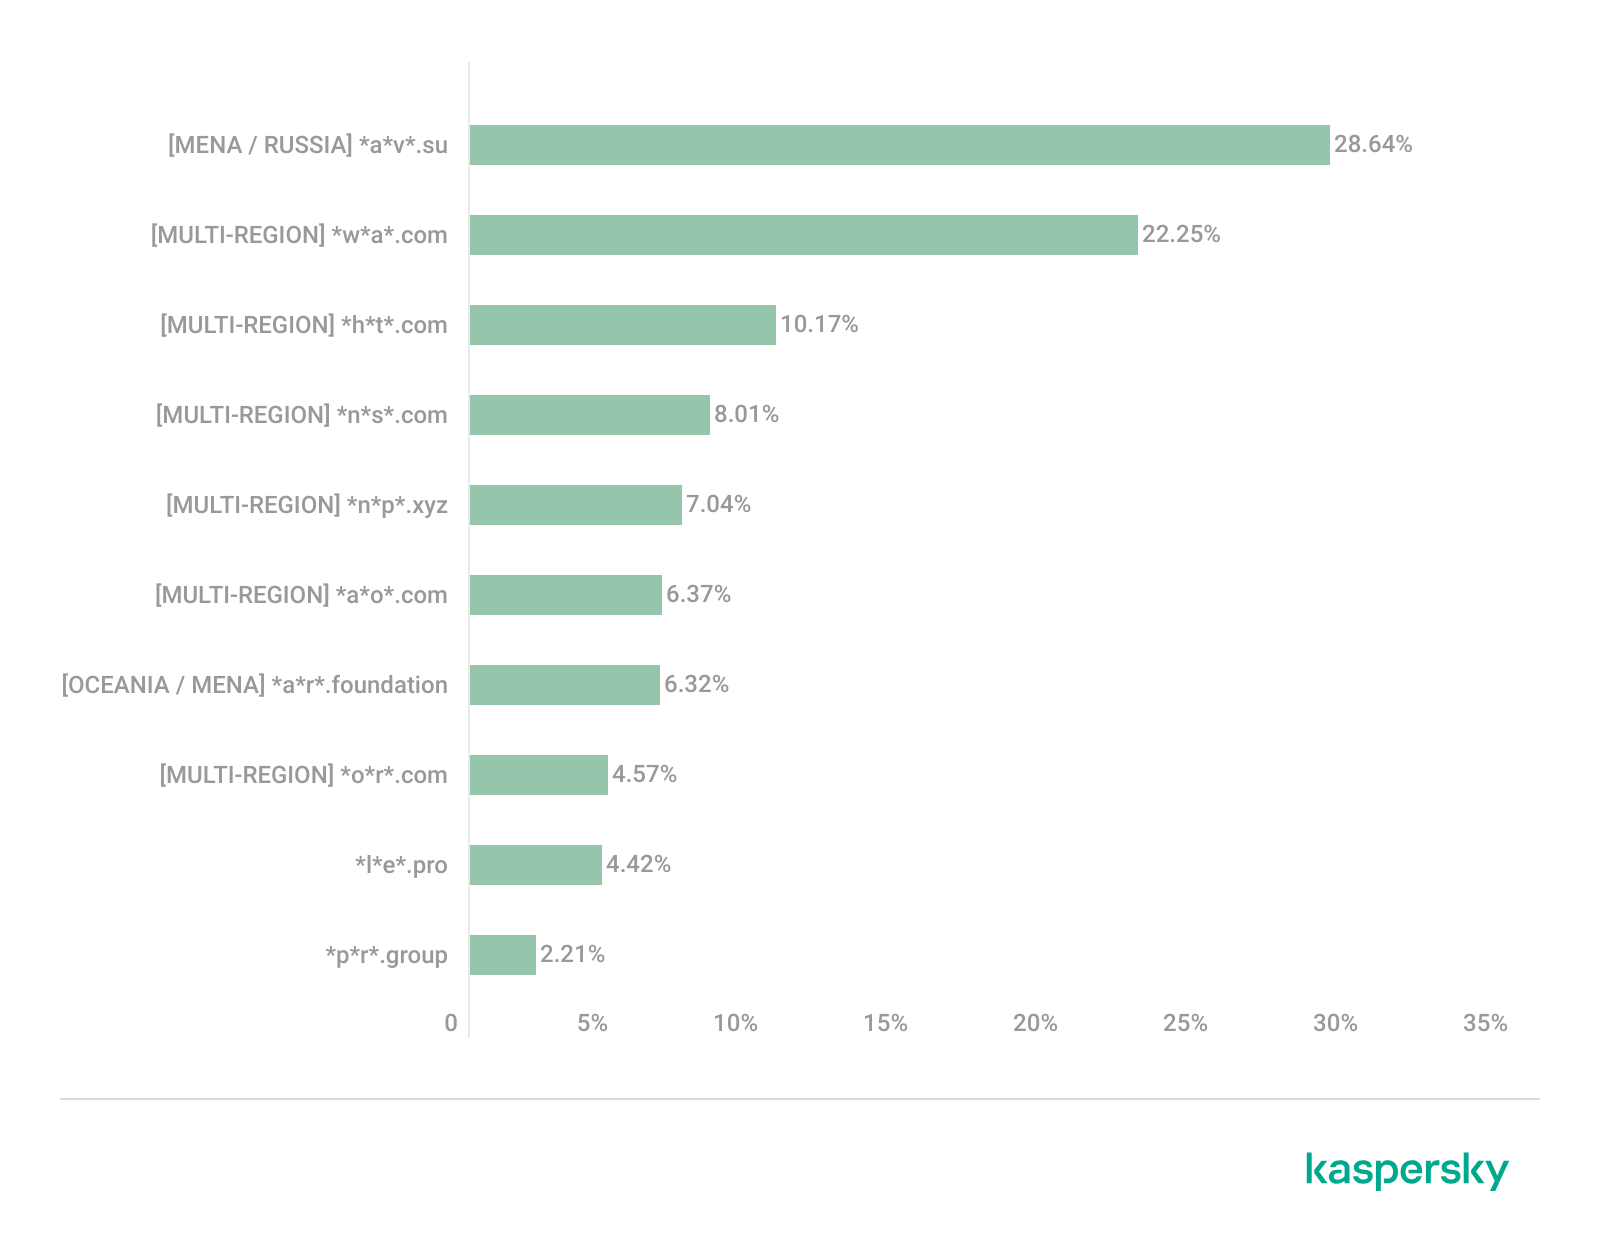
Distribution of the TOP 10 suspicious websites in the Middle East and North Africa, January 2026 (download)
In the MENA region, the site *a*v*.su holds the top spot with a 28.64% share; notably, this site also appears in the TOP 10 for Russia. It markets itself as a tool for building custom VoIP-PBX systems. However, it has an extremely low trust rating and is frequently associated with phishing, and hidden redirects. Using this service carries significant risks, including data leaks, and financial loss.
Ranked seventh is *a*r*.foundation (6.32%), an AI bot allegedly designed for trading, which we also identified in the TOP 10 for Oceania. This service has been flagged as an investment scam operating as a pyramid scheme with the hallmarks of a Ponzi scheme.
The ranking is rounded out by two domains not found in any other region. The first one, *l*e*.pro (4.42%), is a spoof of a popular betting service. The second, *p*r*.group (2.21%), is a clone of a well-known broker. Both sites are scams.
In the MENA region, the landscape is dominated by fake VoIP services as well as counterfeits of financial and betting platforms, which attackers use to conduct phishing attacks, and perform hidden redirects. A significant portion of suspicious sites consists of fake online privacy tools and browser hijackers masquerading as security extensions. Ponzi schemes and cryptocurrency scams are also prominent. The primary risks for the region are data theft, and financial loss.
Latin America
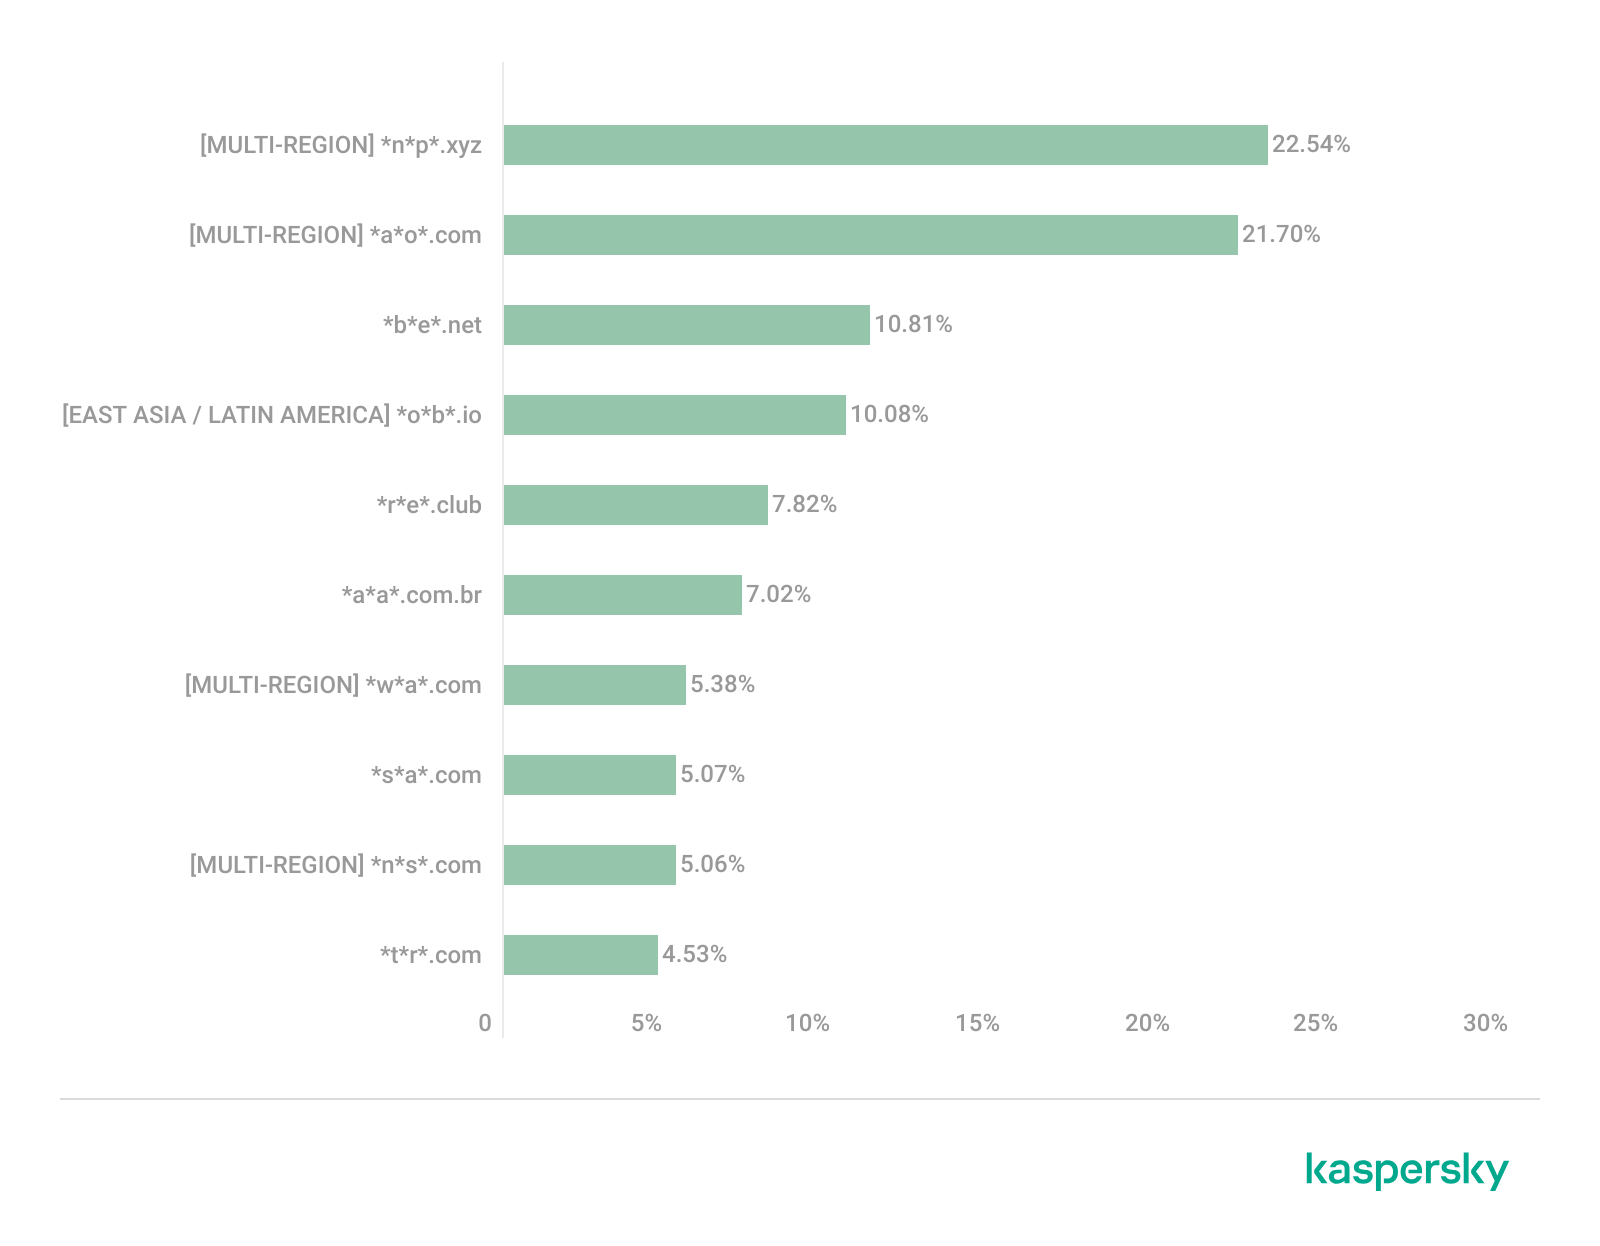
Distribution of the TOP 10 suspicious websites in Latin America, January 2026 (download)
In Latin America, we identified five popular suspicious sites specific to this region, which is unusual compared to other areas where more overlaps are typically observed. Ranking third with a share of 10.81% is the fake betting platform *b*e*.net. In fifth place is *r*e*.club, an illegitimate clone of a well-known bookmaker, with a share of 7.82%.
Further down the list of local threats are *a*a*.com.br (7.02%), a Brazilian Ponzi scam; *s*a*.com (5.07%), which offers dubious investment programs; and *t*r*.com (4.53%), a potentially dangerous trading platform.
In Latin America, the most-visited suspicious sites are betting-themed scams, including both clones of legitimate sites and those built from scratch. Also prevalent are Ponzi schemes, fake investment programs, and dubious online brokers. A significant portion of these sites consists of browser hijackers posing as crypto platforms and AI bots. The primary threats in Latin American countries include financial loss through gambling and Ponzi schemes, as well as the theft of NFTs and other tokens.
East Asia
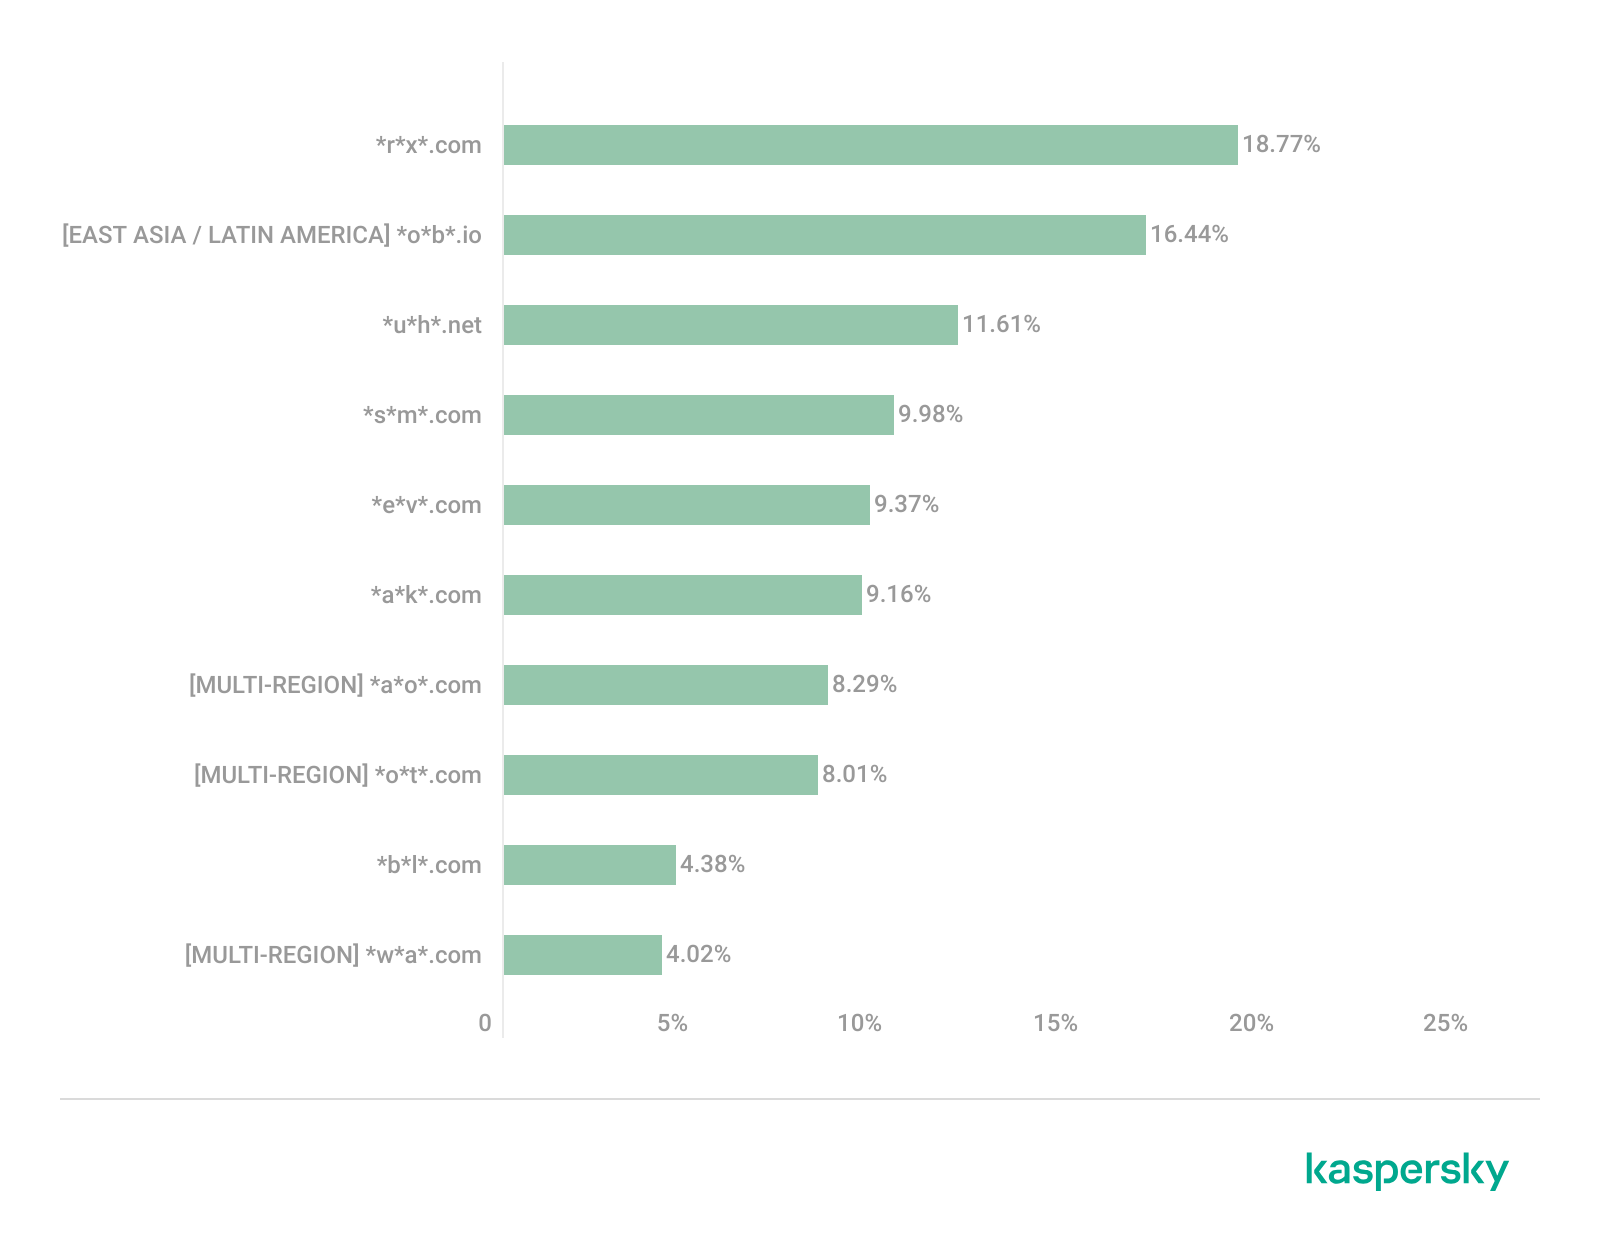
Distribution of the TOP 10 suspicious websites in East Asia, January 2026 (download)
In the East Asian TOP 10, we see the highest concentration of domains that are absent from other regional rankings.
In first place, with an 18.77% share, is the fake broker *r*x*.com, which can be used to steal personal data or funds. Second place is held by a crypto-gaming site (16.44%) that we previously encountered in the Latin American TOP 10. Visitors to this site risk losing NFTs and other tokens. In third place is the domain *u*h*.net (11.61%), used for redirects, which can hijack sessions. Following this is *s*m*.com (9.98%), a domain typically used as a browser-hijacking server and for phishing attacks, serving as a link in an infection chain.
Rounding out the local threats in East Asia are the following domains: *e*v*.com (9.37%), utilized in drive-by attacks; *a*k*.com (9.16%), an API-like domain associated with suspicious scripts and extensions; and *b*l*.com (4.38%), a domain potentially used for redirects.
East Asia has a high concentration of region-specific fake brokers, crypto gaming platforms, and NFT marketplaces. The primary threats for this region include the loss of financial data, NFTs, and other tokens, as well as session hijacking.
South Asia
Distribution of the TOP 10 suspicious websites in South Asia, January 2026 (download)
In South Asian countries, we also observe a concentration of local suspicious sites specific to the region.
The second most popular site in the region is *a*s*.com (12.01%), a poor-reputation, high-risk microloan service typical of South Asia. By interacting with these sites, users risk not only losing significant funds but also compromising their overall security. Following this are *v*n*.com with a 9.47% share and *l*f*.com with 8.65%. These domains are employed in various fraudulent schemes, ranging from phishing to spam.
The TOP 10 also includes *s*o*.com (4.80%), a free video downloading service associated with a high risk of infection. The final site we analyzed in the South Asia region is *c*o*.site (1.89%), a pseudo-tool for local SEO optimization that carries the danger of data loss and a high risk of financial fraud through subscription sign-ups.
In summary, the region is dominated by fake antivirus extensions, microloan services, dubious video downloaders, and counterfeit SEO tools. The primary risks for South Asia include financial fraud, phishing and spam distribution, and data theft.
CIS
When analyzing statistics for suspicious sites in CIS countries, we treat Russia as a separate region due to the unique characteristics of its online space which are not found in any other CIS member states. However, we’ve placed these two regions in the same section, as we’ve observed overlaps between them that are not seen in other parts of the world.
Distribution of the TOP 10 suspicious websites in the CIS, January 2026 (download)
The top two sites in the CIS TOP 10 also appear in the Russian TOP 10. The domain *r*a*.bar, which ranks first in the CIS (39.50%), holds the second spot in Russia (15.93%) and is a fake trading site. It’s worth noting that sites in the .bar domain zone are frequently used for scams. In second place in the CIS (15.29%) and sixth in Russia (3.75%) is the domain *p*o*.ru, which is often associated with bots for inflating follower counts and automating community management.
Domains from fourth to eighth place are specific only to the CIS region and don’t appear in the Russian TOP 10. These sites include:
*a*e*.online (8.42%): an online image editor that carries risks of data harvesting
*n*a*.io (6.51%): a high-risk cryptocurrency trading platform
*e*r*.com (3.72%): a site promising free cryptocurrency and posing the risk of compromising visitors’ private keys and digital wallets
*s*o*.ltd (3.70%): a domain with an extremely low trust rating
*s*.gg (3.49%): a scam site masquerading as a play-to-earn blockchain game
The ranking concludes with sites that overlap with the Russian region. *a*.consulting (2.42%) is a fake clone of a binary options site, and *a*.lol (2.32%) is a domain suspected of dubious activity.
The CIS landscape is dominated by fake trading platforms (particularly crypto exchanges), promises of easy profits, play-to-earn scams, and dubious investment projects. We also observe many bots for inflating social metrics and automation. The primary threat in the CIS is the theft of private keys, digital wallets, and funds through investment schemes and lures involving online promotion.
Distribution of the TOP 10 suspicious websites in Russia, January 2026 (download)
The Russian TOP 10 includes three unique domains not found in the rankings of other regions. The first, *n*m*.top (7.84%), is an imitator of a well-known binary options broker. This suspicious site was recently registered and has a tellingly low rating on domain verification services. The second, *t*e*.ru (3.25%), claims to be an educational platform and has a dubious subscription system with a high probability of fraud involving difficulties in canceling subscriptions. The third site, *e*e*.org (3.14%), positions itself as a tool for a popular media platform, but it’s actually a scam that fails to provide its stated services.
Overall, the Russian landscape is characterized by fake binary options brokers and sketchy sites with fraudulent subscriptions posing as e-learning platforms. There are also frequent instances of sites spoofing well-known legitimate services. The primary risks in Russia are scams related to the knowledge business sector, as well as the theft of money and personal data.
Europe
Distribution of the TOP 10 suspicious websites in Europe, January 2026 (download)
In the European region, we’ve found two unique domains. The first of these, *c*r*.org, has been identified as part of a chain for massive phishing and spam attacks. It accounts for a 16.08% share of the TOP 10. The second site, *o*n*.de, is an unofficial reseller with a poor reputation and a high likelihood of fraud. This domain ranks second to last in our statistics with a 5.95% share.
Among the sites not previously covered, the European TOP 10 includes one site that also appears in the Oceania TOP 10: *o*i*.com (6.61%). This is a classic cryptocurrency scam promising passive income.
A significant portion of suspicious sites in Europe consists of intermediary sites for phishing and spam, fake security extensions, and crypto scams. Unofficial sales services and paid trading tools are also on the list. The primary threats in the European region include session hijacking, data theft, spam, and investment fraud.
Canada
Distribution of the TOP 10 suspicious websites in Canada, January 2026 (download)
Canada has been designated as a separate region to illustrate prevailing trends within North America. The first four positions in the Canadian TOP 10 are held by multiregional domains discussed previously. In fifth place is *t*c*.com (10.88%), which also appears in the TOP 10 rankings for Oceania and South Asia. This is yet another browser extension masquerading as a security solution. Occupying the final spot is the domain *e*w*.com (0.17%), which is unique to the Canadian market. This site operates a dropshipping scam, offering products at prices significantly below market value. Customers typically either never receive their orders or get low-quality counterfeits.
The landscape of dubious websites in Canada is largely defined by fraudulent extensions capable of hijacking browser data, tracking user activity, spoofing search queries, harvesting cookies, and injecting ads. This is further compounded by dropshipping schemes involving counterfeit goods. The primary risks for users in Canada include data theft and financial loss from purchasing substandard products.
Oceania
Distribution of the TOP 10 suspicious websites in Oceania, January 2026 (download)
The final region under consideration is Oceania. Notably, we didn’t identify a single domain unique to this region. Every site appearing in the TOP 10 represents a global threat that’s already been detailed in previous sections. To summarize the findings for this region: the primary threats consist of fake security extensions and privacy products designed for browser hijacking, tracking user activity, displaying advertisements, and stealing data. There’s a minimal presence of crypto Ponzi schemes in this area. The main risk for users in Oceania is the loss of privacy and confidentiality through unwanted apps.
Conclusion
Suspicious websites are particularly dangerous because they often masquerade as legitimate sites with high levels of persuasiveness. They mimic online stores, subscription-based streaming platforms, repair firms, and various other services. Unlike standard phishing sites, they employ more sophisticated manipulations to deceive users, tricking them into voluntarily handing over their personal data and transferring funds.
By examining the TOP 10 suspicious sites across the world’s major regions, we can draw several conclusions. On average, the most prevalent threats globally are fraudulent extensions masquerading as security solutions and privacy services. Their true purpose is to hijack browser data, track user activity, and display ads. We also frequently encounter phishing platforms for image processing and financial scams involving trading, cryptocurrency, betting, and microloans. Our statistics demonstrate that these sites not only employ classic fraudulent schemes centered on easy money but also adapt to contemporary trends targeting younger audiences and specific regional characteristics. The primary risks for users interacting with these sites are a combination of privacy threats and financial loss.
To help protect users from these shady sites, we’ve introduced the category of “websites with an undefined trust level” as part of the web filtering features in our solutions. However, it’s important to note that user awareness and individual responsibility play a significant role in ensuring safe web browsing. It’s essential for users to be able to recognize suspicious sites and remain vigilant toward any that appear untrustworthy.
A suspicious website is a web resource that cannot be definitively classified as phishing, but whose activities are unsafe. Such sites manipulate users, tricking them into voluntarily transferring money for non-existent services, signing up for hidden subscriptions, or disclosing personal data through carefully crafted terms of service. These include fake online stores, dubious crypto exchanges, investment platforms, and services with paid subscriptions.
Kaspersky has introduced a new web filtering category, “Sites with an undefined trust level,” into its security products (Kaspersky Premium, Android and iOS apps, etc.). The system analyzes the domain name and age, IP address reputation, DNS configuration, HTTP security headers, and SSL certificate to automatically detect suspicious resources.
According to Kaspersky data for January 2026, the most widespread global threat is fake browser extensions that mimic security products — they were detected in 9 out of 10 regions analyzed worldwide. Such extensions intercept browser data, track user activity, hijack search queries, and inject ads.
Kaspersky’s regional statistics reveal the specific nature of these threats: in Africa, over 90% of the top 10 suspicious websites are online trading scam platforms; in Latin America, fake betting services predominate; in Russia, fake binary options brokers and “educational platforms” with fraudulent subscriptions lead the way; in CIS countries — crypto scams and bots for inflating engagement.
Key indicators of a suspicious website to check: a strange domain name with numbers or random characters, cheap top-level domains (.xyz, .top, .shop), a recently registered domain (less than 6 months old according to WHOIS data), unrealistic promises (“100% guaranteed income,” “up to 300% profit”), lack of company contact information, and payments only via cryptocurrency or irreversible bank transfers.
Introduction
The online landscape is filled with various traps lying in wait for users. One such threat involves websites that can’t be strictly classified as phishing, yet whose activities are inherently unsafe. These sites often operate on the fringes of the law, even if they aren’t directly violating it. Sometimes they use a cleverly crafted Terms of Service document as a loophole. These agreements might include clauses such as no-refund policies or forced automatic subscription renewals.
Fake online stores, dubious financial platforms, and various online services that mimic legitimate business operations are all categorized as suspicious. Unlike actual phishing sites, which aim to steal sensitive data like banking credentials or passwords, these suspicious sites represent a far more cunning trap. Their goal is manipulation: tricking the victim into willingly paying for non-existent goods and services or signing them up for a subscription that’s nearly impossible to cancel. Beyond financial gain, these sketchy websites may also hunt for personal data to sell later on the dark web.
Our solutions categorize them as having an “undefined trust level”. This article explains what these sites look like, how to identify them, and what you can do to stay safe.
The dangers of shady websites
One of the biggest risks associated with making a purchase from an untrusted website that seems to be an online store is the financial loss and falling victim to fraud. Fake shops will entice you with attractive deals to get you hooked. After you pay, you may never receive what you paid for, or you may receive some cheap piece of unusable junk instead of the item you ordered. Investment or “guaranteed income” programs are another type of classic scam — they promise rapid returns, and once they take your deposits, they disappear without a trace.
Visiting or buying from untrusted suspicious websites can expose you to various risks that go beyond a single bad purchase. Fraudulent websites often collect your personal information even if you do not end up making a purchase. By completing a form or signing up for a “free offer”, you may be providing the scammer with access to your information.
Personal data collection can happen in a fairly straightforward and obvious way — for instance, through a standard order delivery form. In this scenario, attackers end up with sensitive information like the user’s full name, shipping and billing addresses, phone number, email address, and, of course, payment details. As we’ve previously discussed, fraudsters sell this kind of information, and there’re countless ways it can be used down the line. For example, this data might be leveraged for spam campaigns or more serious threats like stalking or targeted attacks.
Common types of suspicious sites
Let’s take a closer look at the different types of shady sites out there and how interacting with them can lead to financial loss, data leaks, the unauthorized use of personal information, and other consequences.
It’s worth noting that rogue websites can masquerade as legitimate ones in almost any industry. The first type of fraudulent site we’ll look at is fake online stores. These can appear as clones of real brand websites or as standalone stores. Usually, the scam follows one of two paths: the buyer either receives a counterfeit or poor-quality product, or they receive nothing at all. These sites lure victims in with suspiciously low prices and “exclusive” deals. Often, users are subjected to psychological pressure: the time to make a purchase decision is purposefully limited, provoking the victim, as with any other scam, into making an impulse purchase.
Another common type of shady site includes online exchanges and trading platforms. These primarily target cryptocurrency, as the lack of legislative regulation for digital currency in certain countries makes them a magnet for fraudsters. These suspicious sites often lure victims with supposedly favorable exchange rates or other enticing gimmicks. If the user attempts to exchange cryptocurrency, their tokens are gone for good. Beyond simple exchanges, rogue sites offer investment services and even display a fake balance growth to appear credible. However, withdrawing funds is impossible; when the victim tries to cash out, they’re prompted to pay some fee or fictional tax.
Subscription traps are also worth noting, offering everything from psychological tests to online video streaming platforms. The hallmark of these sites is that they deliberately withhold critical information, such as recurring charges, or hide the fact it even exists. Typically, the scheme works like this: a user is offered a subscription for a nominal fee, like $1. While that seems attractive, the next charge – perhaps only a week later – might be as much as $50. This information is intentionally obscured, buried in fine print or tucked away in the Terms of Service where it’s harder to find. Legitimate services always clearly disclose subscription terms and provide an easy way to cancel before a trial period ends. Scam services, on the other hand, do everything possible to distract the user from the actual terms of use and subscription.
Shady sites can also masquerade as providers of mediation services, such as legal or real estate assistance. In reality, the service is either never delivered or provided in a stripped-down, incomplete form. For example, a user might be prompted to pay for a service that’s normally provided for free. The danger here lies not only in losing money for non-existent services but also in the significant risk of exposing personal data, such as ID details, taxpayer identification numbers, social security numbers, or driver’s license information. Once in the hands of attackers, this data can become a tool for executing further scams or targeted attacks.
On the whole, suspicious sites are fairly difficult to distinguish from legitimate, trustworthy services. Masquerading as a legitimate business is the primary goal of these sites, and the fraudulent schemes they employ are not always obvious. Nevertheless, there are protective measures as well as certain indicators that can help you suspect a site is unsafe for purchases or financial transactions.
How to identify suspicious or fraudulent websites
Despite the increasingly convincing attempts to create fake shops, the majority of them still lack the quality of real online stores, and there are many signs that may give them away. Some of these signs can be caught by the eye while others require a bit of technical investigation. By combining visual inspection, technical checks, and trusted online tools, you can protect yourself from financial loss or data theft.
Visual and manual clues
You don’t need to be a cybersecurity expert to catch many red flags just by observing the site’s domain, visuals, language and behavior. For instance, scam sites often have strange or randomly generated names, filled with numbers, underscores, hyphens, or meaningless words, like best-shop43.com. In addition, such vague top-level domains as .xyz, .top, or .shop are also frequently used in scams because they’re cheap and easy to register.
Furthermore, most fake stores sites look unprofessional, with poor visuals, pixelated images, mismatched fonts, or copied templates. Many fraudulent websites borrow layouts or logos from other brands or free templates, which makes them appear generic and sketchy.
Another major giveaway lies in the content itself. Be aware of persuasive language, unrealistic promises, or emotional triggers such as No KYC, Risk-free returns, 100% guaranteed income, Up to 300% profit, or Passive income with zero effort. Unrealistic deals are another red flag. If the products are listed at extremely low prices, continuous countdown timers, and “limited time only” messages that are often used to pressure you into making a quick purchase, it’s a clear tell of a fraudulent website.
Legitimate businesses always provide verifiable contact details, such as a physical address, company name, and customer support. On the contrary, scam sites hide this information. You may also notice the non-functioning pages, broken or suspicious links leading to unrelated external sites which indicate poor maintenance or malicious intent.
Another important signal is the website’s social media presence. Legitimate online businesses usually maintain at least one active social media account to promote their products and communicate with customers. In most cases, these businesses have long-established social media accounts with harmonized posting history and engagement from real users, consistency between the brand website and social media profiles (same name, logo, and links). The links to social media profiles from the website are usually direct. In contrast, fraudulent or deceptive websites often lack any meaningful social media presence or display signs of superficial or artificial activity. This may include missing social media accounts altogether, social media icons that lead to non-existent, inactive, or unrelated pages, or recently created profiles with very few posts and minimal user engagement. In some cases, comment sections are disabled or dominated by spam and automated content, suggesting an attempt to avoid public interaction rather than engage with customers.
Lastly, the payment options offered by the site can also tell a lot about its legitimacy. Be extremely cautious if a website only accepts cryptocurrency, wire transfers, or third-party P2P payments. These payment methods are irreversible and are preferred by scammers. Legitimate e-commerce platforms typically offer secure and reversible payment options, such as credit cards or trusted payment gateways that include buyer protection policies.
However, the absence or existence of any of these factors alone does not necessarily indicate malicious intent. It should be evaluated in combination with technical, linguistic, and behavioral indicators, rather than treated as a standalone signal of legitimacy.
Technical indicators to check
Looking into technical signs can reveal whether a website is trustworthy or potentially fraudulent.
One of the first things to check is the domain age. Scam websites are often short-lived, appearing only for a few weeks or months before disappearing once users start reporting them. To check when the domain was created, use a WHOIS lookup. If it’s less than six months old, be cautious — especially for e-commerce or investment sites, where legitimacy and trust take time to build.
Let’s take a look at the registration details for the popular online marketplace Amazon. As we can see from the WHOIS information, it was registered in 1994.
Meanwhile, a reported suspicious online store was created a couple of months ago.
Legitimate websites usually operate on stable hosting platforms and remain on the same IP addresses or networks for long periods. In contrast, fraudulent websites often move between servers (in most cases using a cheap shared hosting service) or reuse infrastructure already associated with abuse. Checking the IP address reputation can reveal if the website or the hosting server has previously been linked to suspicious activities. Even if the website looks legitimate, a poor IP reputation can expose it.
In addition to that, looking at the infrastructure behavior over time can reveal patterns about its legitimacy. Websites associated with fraudulent activity often show short lifespans, sudden spikes in activity, or rapid appearance and disappearance, which indicates a coordinated campaign rather than a legitimate business.
Another important clue is hidden ownership. When the WHOIS details show “Redacted for Privacy” or leaves the organization name blank, it may indicate that the website owner is deliberately hiding their identity.
We should point out that while this can raise suspicion during investigations, hidden WHOIS data is not inherently malicious. Many legitimate businesses use privacy protection services for valid reasons. These may include protection from spam and phishing after public email addresses are taken from WHOIS databases, personal safety for small business owners, and brand protection to prevent competitors or malicious actors from targeting the registrant. This means that some businesses can use services like WHOIS Privacy Protection, Domains By Proxy, or PrivacyGuardian.org to remove the WHOIS data while still operating transparently on their websites through clear contact details, customer support channels, and legal pages (e.g. terms of use).
Therefore, hidden ownership should be treated as a contextual risk indicator, not a standalone proof of fraud. It becomes more suspicious when combined with other signals such as newly registered domains, and lack of legal information.
Next, you can check the security headers of the website. Legitimate websites are usually well maintained and include several key HTTP headers for protection. Some examples include:
Content-Security-Policy (CSP) provides strong defense against cross-site scripting (XSS) attacks by defining which scripts are allowed to run on the site and blocking any malicious JavaScript that could steal login data or inject fake forms.
HTTP Strict-Transport-Security (HSTS) forces browsers to connect to the site only over HTTPS. It ensures all communication is encrypted and prevents redirecting users to an insecure (HTTP) version of the site.
X-Frame-Options prevents clickjacking, which is a type of attack where a legitimate-looking button or link on a malicious page secretly performs another action in the background.
X-Content-Type-Options blocks MIME-type attacks by preventing browsers from misinterpreting file types.
Referrer-Policy controls how much information about your previous browsing (referrer URLs) is shared with other sites.
These headers form the “digital hygiene” of a website. Their absence doesn’t always mean a site is malicious, but it does suggest a lack of security awareness or professional maintenance — both strong reasons to be cautious.
You should also check the SSL certificate. Scam sites may use self-signed or short-lived SSL certificates. You can inspect this by clicking the padlock icon in your browser’s address bar — if it says “not secure” or the certificate authority seems unfamiliar, that’s a red flag.
You can check the security headers and the SSL certificate by sending an HTTP request programmatically or by using some online service.
Another indicator that provides insight into how well a website is done and managed is DNS configurations. Legitimate businesses typically use reliable DNS providers and maintain consistent DNS records. Missing the name server NS or mail exchange MX records may indicate poor DNS configuration. In addition to NS and MX, reputable sites also configure SPF and DMARC records to protect their brand from email spoofing and phishing. Something scam website developers won’t bother with because they don’t intend to build a long-standing reputation.
You can check the configurations of DNS records either programmatically or by using an online service.
Another recommendation is to pay attention to website behavior. If there are frequent redirects, pop-up ads, or background requests to unknown domains, this may indicate unsafe scripting or tracking.
How to protect yourself
Tools and databases for detecting suspicious websites
We at Kaspersky have built an intelligent system for detecting suspicious web resources and added this new type of protection into many of our products, including Kaspersky Premium, Kaspersky for Android and iOS, and others. Our detection model is based on many factors, including but not limited to the following:
domain name and age,
IP reputation,
stability of the infrastructure used,
DNS configurations,
HTTP security headers,
digital identity and popularity of the web resource.
When a user tries to visit a site flagged as having an undefined trust level, our solutions show a warning to stop the visitor from becoming a victim of personal data leaks, financial losses or a bad purchase:
This component is on by default.
Moreover, there are several online tools and databases that can help assess a website’s legitimacy:
ScamAdviser analyzes trust based on WHOIS, server location, and web reputation.
APIVoid provides risk scoring using DNS, IP, and domain reputation databases.
National government databases often maintain official lists of fraudulent or blacklisted domains.
Preventive measures
To protect yourself from such threats, it might a good idea to take some additional preventive measures. Always double-check the URL and domain name, especially when you are about to click a link or make a payment. Make sure the site uses HTTPS and has a trusted certificate.
You can use standard browser tools to verify site security. For example, in Google Chrome, clicking the site information button (the lock or settings icon in the address bar) displays details about the connection security and the site’s certificate.
In the Security section, you can check whether the site supports HTTPS – it should say “Connection is secure” – and view the site’s digital certificate.
Additionally, keep reliable security software with real-time protection running on your device to stop you from accessing dangerous websites. Do not download any files or enter your personal information on websites that look unprofessional or suspicious. And finally, remember the golden rule: if a deal seems too good to be true, it often is.
If you realize that you’re on a scam website, it’s important to perform certain post-incident actions immediately. First, contact your bank or payment provider as soon as possible to block the transaction or card. Then, change your passwords for the services which might have been compromised, and run a full antivirus scan on your device to detect and remove any potential threats. Lastly, consider reporting the website to the cybercrime agency in your country or to the consumer protection agency. Sharing your experience online by leaving a review or warning will give notice to potential customers alike.
By staying careful and taking quick actions, you can significantly reduce the chances of being a target and help make the internet a safer place for everyone.
An overview of detection statistics for sites with an undefined trust level
To illustrate the types of suspicious sites prevalent in various regions around the world, we analyzed anonymized detection data from Kaspersky solutions for the “websites with an undefined trust level” category in January 2026. For each region, we identified the 10 most frequently encountered sites and calculated the share of each within that list. To maintain privacy, specific domains are not listed directly; instead, they’re described based on their functionality and characteristics.
Most visited suspicious sites
First, let’s examine the sites that appear across multiple regions, indicating a high prevalence.
In 9 out of the 10 regions analyzed, we encountered a suspicious image processing platform (*a*o*.com). This site positions itself as a photo editing tool, but in reality, it serves as an intermediary server for uploading images used in phishing and other campaigns. By interacting with such a site, users risk exposing personal data under the guise of uploading images or falling victim to a phishing attack.
Percentage of the *a*o*.com domain detections by region, January 2026 (download)
This site has the largest share of detections in the Russian Federation, where it ranks first in the TOP 10 with a 40.80% share. It is also prevalent in Latin American countries (21.70%) and the CIS (14.64%), while it’s least common in Canada at 0.24%.
The next site appeared in 7 regions. It consists of a landing page for a fake antivirus solution presented as a browser extension (*n*s*.com). This extension redirects the user to a fake search engine page allowing it to collect data and track user activity, specifically search queries.
Percentage of the *n*s*.com domain detections by region, January 2026 (download)
This site is most frequently detected in South Asia, with a share of 33.31%. Its presence in Canada and Oceania is roughly equal (15.47% and 15.09%, respectively). We recorded the lowest number of detections in Africa, at 2.99%.
Another suspicious browser extension appeared in the TOP 10 in 6 out of the 10 regions. It’s a fake privacy-enhancing tool hosted at *w*a*.com. Instead of providing the advertised privacy features, this extension carries a high risk of intercepting browser data. It can modify browser settings, harvest user data, and swap the default search engine for a fake one. Furthermore, it maintains full control over all browser traffic.
Percentage of the *w*a*.com domain detections by region, January 2026 (download)
This “service” has its largest share, 22.25%, in the Middle East and North Africa, and is also quite common in Canada (16.26%). It’s least frequently encountered in Latin America (5.38%) and East Asia (4.02%).
The site *o*r*.com appeared in five regional rankings. It’s a fake security service promising to provide online safety by warning users about malicious sites and dangerous search queries. This extension has the potential to steal cookies (including session cookies), inject advertisements, spoof login forms, and harvest browser history and search queries. We noted that this site made the TOP 10 in Africa (0.59%), the MENA (Middle East and North Africa) region (4.57%), Europe (5.61%), Canada (7.21%), and Oceania (1.93%).
In 4 out of the 10 regions, we identified several other recurring sites. One of them (*n*p*.xyz) mimics a repository for creative AI image generation prompts while capturing browser data. The domain hosting this site exhibits several red flags: it was recently registered, and the owner’s information is hidden. This site reached the TOP 10 in Africa (0.51%), the MENA region (7.04%), Latin America (22.54%, ranking first in that region), and South Asia (5.91%).
The second service (*i*s*.com) positions itself as a tool for safe searching, protecting the browser from threats, and verifying extensions. However, this is a typical browser hijacker, much like the others mentioned above. It made the TOP 10 in South Asia (8.03%), Oceania (17.97%), Europe (3.90%), and Canada (14.35%).
The third site (*h*t*.com) poses as a private browsing extension. In reality, it’s another potentially unwanted application designed for browser hijacking: it modifies settings, steals sensitive data (cookies, browser history, and queries), and can redirect the user to phishing pages. Users have specifically noted the difficulty involved in removing the extension. This site appears in the TOP 10 for the MENA region (10.17%), Canada (7.06%), Europe (3.81%), and Oceania (2.81%).
Another domain (*o*t*.com) that reached the TOP 10 in four regions is a service mimicking a browser extension for safe searching and web browsing. It’s dangerous because it injects ads and steals user data. It’s important to note that such extensions can be installed without explicit user consent – for example, via links embedded in other software. This service holds the number one spot in two regions: Canada (25.72%) and Oceania (30.92%), while also appearing in the TOP 10 for East Asia (8.01%) and Africa (0.88%).
Consequently, we can see that the majority of suspicious sites detected by our solutions worldwide are browser hijackers masquerading as security products. Nevertheless, other categories of sites also appear in the TOP 10.
Next, we’ll examine each region individually, focusing on descriptions of domains not previously covered. For clarity, the sites mentioned above will be marked as [MULTI-REGION], while those appearing in only two or three regions will include the names of those specific areas. We’ll observe several regional overlaps and similarities, allowing us to determine which types of suspicious sites are popular both within specific regions and globally.
Africa
Distribution of the TOP 10 suspicious websites in Africa, January 2026 (download)
The three most prevalent domains in African countries are found exclusively in this region. All of them – *i*r*.world (60.27%), *m*a*.com (22.84%), and *e*p*.com (9.36%) – are potentially fraudulent online trading platforms suspected of using forged licenses. These sites employ classic scam schemes where it’s impossible to withdraw any alleged earnings. In fifth place is a domain we’ll also see in the European TOP 10, *r*e*.com (1.46%): a platform marketed as a tool for retail and semi-professional traders. It charges for services available elsewhere for free. Eighth place is held by a site that also appears in the Russian TOP 10: *a*c*.com (0.56%). This is a dubious AI tool that claims to offer free subscriptions to a premium graphics editor. In ninth place is a domain that also surfaces in the Canadian TOP 10: *u*e*.com (0.53%), a browser extension of the “web protection” variety that we’ve encountered previously.
In summary, the African region is dominated by financial scams within the online trading and brokerage sectors. These include fake platforms that make it impossible to withdraw funds and use fake licenses and classic schemes to steal users’ money. Additionally, Africa sees paid tools that duplicate free services and questionable AI-based subscriptions. The primary threat in this region is financial loss through fraudulent investment-themed sites.
MENA
Distribution of the TOP 10 suspicious websites in the Middle East and North Africa, January 2026 (download)
In the MENA region, the site *a*v*.su holds the top spot with a 28.64% share; notably, this site also appears in the TOP 10 for Russia. It markets itself as a tool for building custom VoIP-PBX systems. However, it has an extremely low trust rating and is frequently associated with phishing, and hidden redirects. Using this service carries significant risks, including data leaks, and financial loss.
Ranked seventh is *a*r*.foundation (6.32%), an AI bot allegedly designed for trading, which we also identified in the TOP 10 for Oceania. This service has been flagged as an investment scam operating as a pyramid scheme with the hallmarks of a Ponzi scheme.
The ranking is rounded out by two domains not found in any other region. The first one, *l*e*.pro (4.42%), is a spoof of a popular betting service. The second, *p*r*.group (2.21%), is a clone of a well-known broker. Both sites are scams.
In the MENA region, the landscape is dominated by fake VoIP services as well as counterfeits of financial and betting platforms, which attackers use to conduct phishing attacks, and perform hidden redirects. A significant portion of suspicious sites consists of fake online privacy tools and browser hijackers masquerading as security extensions. Ponzi schemes and cryptocurrency scams are also prominent. The primary risks for the region are data theft, and financial loss.
Latin America
Distribution of the TOP 10 suspicious websites in Latin America, January 2026 (download)
In Latin America, we identified five popular suspicious sites specific to this region, which is unusual compared to other areas where more overlaps are typically observed. Ranking third with a share of 10.81% is the fake betting platform *b*e*.net. In fifth place is *r*e*.club, an illegitimate clone of a well-known bookmaker, with a share of 7.82%.
Further down the list of local threats are *a*a*.com.br (7.02%), a Brazilian Ponzi scam; *s*a*.com (5.07%), which offers dubious investment programs; and *t*r*.com (4.53%), a potentially dangerous trading platform.
In Latin America, the most-visited suspicious sites are betting-themed scams, including both clones of legitimate sites and those built from scratch. Also prevalent are Ponzi schemes, fake investment programs, and dubious online brokers. A significant portion of these sites consists of browser hijackers posing as crypto platforms and AI bots. The primary threats in Latin American countries include financial loss through gambling and Ponzi schemes, as well as the theft of NFTs and other tokens.
East Asia
Distribution of the TOP 10 suspicious websites in East Asia, January 2026 (download)
In the East Asian TOP 10, we see the highest concentration of domains that are absent from other regional rankings.
In first place, with an 18.77% share, is the fake broker *r*x*.com, which can be used to steal personal data or funds. Second place is held by a crypto-gaming site (16.44%) that we previously encountered in the Latin American TOP 10. Visitors to this site risk losing NFTs and other tokens. In third place is the domain *u*h*.net (11.61%), used for redirects, which can hijack sessions. Following this is *s*m*.com (9.98%), a domain typically used as a browser-hijacking server and for phishing attacks, serving as a link in an infection chain.
Rounding out the local threats in East Asia are the following domains: *e*v*.com (9.37%), utilized in drive-by attacks; *a*k*.com (9.16%), an API-like domain associated with suspicious scripts and extensions; and *b*l*.com (4.38%), a domain potentially used for redirects.
East Asia has a high concentration of region-specific fake brokers, crypto gaming platforms, and NFT marketplaces. The primary threats for this region include the loss of financial data, NFTs, and other tokens, as well as session hijacking.
South Asia
Distribution of the TOP 10 suspicious websites in South Asia, January 2026 (download)
In South Asian countries, we also observe a concentration of local suspicious sites specific to the region.
The second most popular site in the region is *a*s*.com (12.01%), a poor-reputation, high-risk microloan service typical of South Asia. By interacting with these sites, users risk not only losing significant funds but also compromising their overall security. Following this are *v*n*.com with a 9.47% share and *l*f*.com with 8.65%. These domains are employed in various fraudulent schemes, ranging from phishing to spam.
The TOP 10 also includes *s*o*.com (4.80%), a free video downloading service associated with a high risk of infection. The final site we analyzed in the South Asia region is *c*o*.site (1.89%), a pseudo-tool for local SEO optimization that carries the danger of data loss and a high risk of financial fraud through subscription sign-ups.
In summary, the region is dominated by fake antivirus extensions, microloan services, dubious video downloaders, and counterfeit SEO tools. The primary risks for South Asia include financial fraud, phishing and spam distribution, and data theft.
CIS
When analyzing statistics for suspicious sites in CIS countries, we treat Russia as a separate region due to the unique characteristics of its online space which are not found in any other CIS member states. However, we’ve placed these two regions in the same section, as we’ve observed overlaps between them that are not seen in other parts of the world.
Distribution of the TOP 10 suspicious websites in the CIS, January 2026 (download)
The top two sites in the CIS TOP 10 also appear in the Russian TOP 10. The domain *r*a*.bar, which ranks first in the CIS (39.50%), holds the second spot in Russia (15.93%) and is a fake trading site. It’s worth noting that sites in the .bar domain zone are frequently used for scams. In second place in the CIS (15.29%) and sixth in Russia (3.75%) is the domain *p*o*.ru, which is often associated with bots for inflating follower counts and automating community management.
Domains from fourth to eighth place are specific only to the CIS region and don’t appear in the Russian TOP 10. These sites include:
*a*e*.online (8.42%): an online image editor that carries risks of data harvesting
*n*a*.io (6.51%): a high-risk cryptocurrency trading platform
*e*r*.com (3.72%): a site promising free cryptocurrency and posing the risk of compromising visitors’ private keys and digital wallets
*s*o*.ltd (3.70%): a domain with an extremely low trust rating
*s*.gg (3.49%): a scam site masquerading as a play-to-earn blockchain game
The ranking concludes with sites that overlap with the Russian region. *a*.consulting (2.42%) is a fake clone of a binary options site, and *a*.lol (2.32%) is a domain suspected of dubious activity.
The CIS landscape is dominated by fake trading platforms (particularly crypto exchanges), promises of easy profits, play-to-earn scams, and dubious investment projects. We also observe many bots for inflating social metrics and automation. The primary threat in the CIS is the theft of private keys, digital wallets, and funds through investment schemes and lures involving online promotion.
Distribution of the TOP 10 suspicious websites in Russia, January 2026 (download)
The Russian TOP 10 includes three unique domains not found in the rankings of other regions. The first, *n*m*.top (7.84%), is an imitator of a well-known binary options broker. This suspicious site was recently registered and has a tellingly low rating on domain verification services. The second, *t*e*.ru (3.25%), claims to be an educational platform and has a dubious subscription system with a high probability of fraud involving difficulties in canceling subscriptions. The third site, *e*e*.org (3.14%), positions itself as a tool for a popular media platform, but it’s actually a scam that fails to provide its stated services.
Overall, the Russian landscape is characterized by fake binary options brokers and sketchy sites with fraudulent subscriptions posing as e-learning platforms. There are also frequent instances of sites spoofing well-known legitimate services. The primary risks in Russia are scams related to the knowledge business sector, as well as the theft of money and personal data.
Europe
Distribution of the TOP 10 suspicious websites in Europe, January 2026 (download)
In the European region, we’ve found two unique domains. The first of these, *c*r*.org, has been identified as part of a chain for massive phishing and spam attacks. It accounts for a 16.08% share of the TOP 10. The second site, *o*n*.de, is an unofficial reseller with a poor reputation and a high likelihood of fraud. This domain ranks second to last in our statistics with a 5.95% share.
Among the sites not previously covered, the European TOP 10 includes one site that also appears in the Oceania TOP 10: *o*i*.com (6.61%). This is a classic cryptocurrency scam promising passive income.
A significant portion of suspicious sites in Europe consists of intermediary sites for phishing and spam, fake security extensions, and crypto scams. Unofficial sales services and paid trading tools are also on the list. The primary threats in the European region include session hijacking, data theft, spam, and investment fraud.
Canada
Distribution of the TOP 10 suspicious websites in Canada, January 2026 (download)
Canada has been designated as a separate region to illustrate prevailing trends within North America. The first four positions in the Canadian TOP 10 are held by multiregional domains discussed previously. In fifth place is *t*c*.com (10.88%), which also appears in the TOP 10 rankings for Oceania and South Asia. This is yet another browser extension masquerading as a security solution. Occupying the final spot is the domain *e*w*.com (0.17%), which is unique to the Canadian market. This site operates a dropshipping scam, offering products at prices significantly below market value. Customers typically either never receive their orders or get low-quality counterfeits.
The landscape of dubious websites in Canada is largely defined by fraudulent extensions capable of hijacking browser data, tracking user activity, spoofing search queries, harvesting cookies, and injecting ads. This is further compounded by dropshipping schemes involving counterfeit goods. The primary risks for users in Canada include data theft and financial loss from purchasing substandard products.
Oceania
Distribution of the TOP 10 suspicious websites in Oceania, January 2026 (download)
The final region under consideration is Oceania. Notably, we didn’t identify a single domain unique to this region. Every site appearing in the TOP 10 represents a global threat that’s already been detailed in previous sections. To summarize the findings for this region: the primary threats consist of fake security extensions and privacy products designed for browser hijacking, tracking user activity, displaying advertisements, and stealing data. There’s a minimal presence of crypto Ponzi schemes in this area. The main risk for users in Oceania is the loss of privacy and confidentiality through unwanted apps.
Conclusion
Suspicious websites are particularly dangerous because they often masquerade as legitimate sites with high levels of persuasiveness. They mimic online stores, subscription-based streaming platforms, repair firms, and various other services. Unlike standard phishing sites, they employ more sophisticated manipulations to deceive users, tricking them into voluntarily handing over their personal data and transferring funds.
By examining the TOP 10 suspicious sites across the world’s major regions, we can draw several conclusions. On average, the most prevalent threats globally are fraudulent extensions masquerading as security solutions and privacy services. Their true purpose is to hijack browser data, track user activity, and display ads. We also frequently encounter phishing platforms for image processing and financial scams involving trading, cryptocurrency, betting, and microloans. Our statistics demonstrate that these sites not only employ classic fraudulent schemes centered on easy money but also adapt to contemporary trends targeting younger audiences and specific regional characteristics. The primary risks for users interacting with these sites are a combination of privacy threats and financial loss.
To help protect users from these shady sites, we’ve introduced the category of “websites with an undefined trust level” as part of the web filtering features in our solutions. However, it’s important to note that user awareness and individual responsibility play a significant role in ensuring safe web browsing. It’s essential for users to be able to recognize suspicious sites and remain vigilant toward any that appear untrustworthy.
Dutch journalist Just Vervaart, working for regional media network Omroep Gelderland, followed the directions posted on the Dutch government website and mailed a postcard with a hidden tracker inside. Because of this, they were able to track the ship for about a day, watching it sail from Heraklion, Crete, before it turned towards Cyprus. While it only showed the location of that one vessel, knowing that it was part of a carrier strike group sailing in the Mediterranean could potentially put the entire fleet at risk.
[…]
Navy officials reported that the tracker was discovered within 24 hours of the ship’s arrival, during mail sorting, and was eventually disabled. Because of this incident, the Dutch authorities now ban electronic greeting cards, which, unlike packages, weren’t x-rayed before being brought on the ship.
We've all had the unsettling experience of seeing an ad online that reveals just how much advertisers know about our lives. You're right to be disturbed. Those very same online ad systems have been used by the government to warrantlessly track peoples' locations, new reporting has confirmed.
For years, the internet advertising industry has been sucking up our data, including our location data, to serve us "more relevant ads." At the same time, we know that federal law enforcement agencies have been buying up our location data from shady data brokers that most people have never heard of.
Now, a new report gives us direct evidence that Customs and Border Protection (CBP) has used location data taken from the internet advertising ecosystem to track phones. In a document uncovered by 404 Media, CBP admits what we’ve been saying for years: The technical systems powering creepy targeted ads also allow federal agencies to track your location.
The document acknowledges that a program by the agency to use "commercially available marketing location data" for surveillance drew from the process used to select the targeted ads shown to you on nearly every website and app you visit. In this blog post, we'll tell you what this process is, how it can and is being used for state surveillance, and what can be done about it—by individuals, by lawmakers, and by the tech companies that enable these abuses.
Advertising Surveillance Enables Government Surveillance
The online advertising industry has built a massive surveillance machine, and the government can co-opt it to spy on us.
In the absence of strong privacy laws, surveillance-based advertising has become the norm online. Companies track our online and offline activity, then share it with ad tech companies and data brokers to help target ads. Law enforcement agencies take advantage of this advertising system to buy information about us that they would normally need a warrant for, like location data. They rely on the multi-billion-dollar data broker industry to buy location data harvested from people’s smartphones.
We’ve known for years that location data brokers are one part of federal law enforcement's massive surveillance arsenal, including immigration enforcement agencies like CBP and Immigration and Customs Enforcement (ICE). ICE, CBP and the FBI have purchased location data from the data broker Venntell and used it to identify immigrants who were later arrested. Last year, ICE purchased a spy tool called Webloc that gathers the locations of millions of phones and makes it easy to search for phones within specific geographic areas over a period of time. Webloc also allows them to filter location data by the unique advertising IDs that Apple and Google assign to our phones.
But a document recently obtained by 404 Media is the first time CBP has acknowledged the location data it buys is partially sourced from the system powering nearly every ad you see online: real-time bidding (RTB). As CBP puts it, “RTB-sourced location data is recorded when an advertisement is served.”
Even though this document is about a 2019-2021 pilot use of this data, CBP and other federal agencies have continued to purchase and use commercially obtained location data. ICE has purchased location tracking tools since then and recently requested information on “Ad Tech” tools it could use for investigations.
The CBP document acknowledges two sources of location data that it relies on: software development kits (SDKs) and RTB, both methods of location-tracking that EFF has written about before. Apps for weather, navigation, dating, fitness, and “family safety” often request location permissions to enable key features. But once an app has access to your location, it could share it with data brokers directly through SDKs or indirectly (and often without the app developers' knowledge) through RTB. Data brokers can collect location data from SDKs that they pay developers to put in their apps. When relying on RTB, data brokers don’t need any direct relationship with the apps and websites they’re collecting location data from. RTB is facilitated by ad companies that are already plugged into most websites and apps.
RTB is the process by which most websites and apps auction off their ad space. Unfortunately, the milliseconds-long auctions that determine which ads you see also expose your information, including location data, to thousands of companies a day. At a high-level, here’s how RTB works:
The moment you visit a website or app with ad space, it asks an ad tech company to determine which ads to display for you.
This ad tech company packages all the information they can gather about you into a “bid request” and broadcasts it to thousands of potential advertisers.
The bid request may contain information like your unique advertising ID, your GPS coordinates, IP address, device details, inferred interests, demographic information, and the app or website you’re visiting. The information in bid requests is called “bidstream data” and typically includes identifiers that can be linked to real people.
Advertisers use the personal information in each bid request, along with data profiles they’ve built about you over time, to decide whether to bid on the ad space.
The highest bidder gets to display an ad for you, but advertisers (or the adtech companies that represent them) can collect your bidstream data regardless of whether or not they bid on the ad space.
A key vulnerability of real-time bidding is that while only one advertiser wins the auction, all participants receive data about the person who would see their ad. As a result, anyone posing as an ad buyer can access a stream of sensitive data about billions of individuals a day. Data brokers have taken advantage of this vulnerability to harvest data at a staggering scale. For example, the FTC found that location data broker Mobilewalla collected data on over a billion people, with an estimated 60% sourced from RTB auctions. Leaked data from another location data broker, Gravy Analytics, referenced thousands of apps, including Microsoft apps, Candy Crush, Tinder, Grindr, MyFitnessPal, pregnancy trackers and religious-focused apps. When confronted, several of these apps’ developers said they had never heard of Gravy Analytics.
As Venntel, one of the location data brokers that has sold to ICE, puts it, “Commercially available bidstream data from the advertising ecosystem has long been one of the most comprehensive sources of real-time location and device data available.” But the privacy harms of RTB are not just a matter of misuse by individual data brokers. RTB auctions broadcast the average person’s data to thousands of companies, hundreds of times per day, with no oversight of how this information is ultimately exploited. Once your information is broadcast through RTB, it’s almost impossible to know who receives it or control how it’s used.
What You Can Do To Protect Yourself
Revelations about the government's exploitation of this location data shows how dangerous online tracking has become, but we’re not powerless. Here are two basic steps you can take to better protect your location data:
Disable your mobile advertising ID (see instructions for iPhone/Android). Apple and Google assign unique advertising IDs to each of their phones. Location data brokers use these advertising IDs to stitch together the information they collect about you from different apps.
Review apps you’ve granted location permissions to. Apps that have access to your location could share it with other companies, so make sure you’re only granting location permission to apps that really need it in order to function. If you can’t disable location access completely for an app, limit it to only when you have the app open or only approximate location instead of precise location.
For more tips, check out EFF’s guide to protecting yourself from mobile-device based location tracking. Keep in mind that the security plan that’s best for you will vary in different situations. For example, you may want to take stronger steps to protect your location data when traveling to a sensitive location, like a protest.
What Tech Companies and Lawmakers Must Do
Legislators and tech companies must act so that individuals don’t bear the burden of defending their data every time they use the internet.
Ad tech companies must reckon with their role in warrantless government surveillance, among other privacy harms. The systems they built for targeted advertising are actively used to track people’s location. The best way to prevent online ads from fueling surveillance is to stop targeting ads based on detailed behavioral profiles. Ads can still be targeted contextually—based on the content people are viewing—without collecting or exposing their sensitive personal information. Short of moving to contextual advertising, tech companies can limit the use of their systems for government location tracking by:
Stopping the use of precise location data for targeted advertising. Ad tech companies facilitating ad auctions can and should remove precise location data from bid requests. Ads can be targeted based on people’s coarse location, like the city they’re in, without giving data brokers people’s exact GPS coordinates. Precise location data can reveal where we work, where we live, who we meet, where we protest, where we worship, and more. Broadcasting it to thousands of companies a day through RTB is dangerous.
Removing advertising IDs from devices, or at minimum, disabling them by default. Advertising IDs have become a linchpin of the data broker economy and are actively used by law enforcement to track people’s location. Advertising IDs were added to phones in 2012 to let companies track you, and removing them is not a far-fetched idea. When Apple forced apps to request access to people’s advertising IDs starting in 2021 (if you have an iPhone you’ve probably seen the "Ask App Not to Track" pop-ups), 96% of U.S. users opted out, essentially disabling advertising IDs on most iOS devices. One study found that iPhone users were less likely to be victims of financial fraud after Apple implemented this change. Google should follow Apple’s lead and disable advertising IDs by default.
Lawmakers also need to step up to protect their constituents' privacy. We need strong, federal privacy laws to stop companies from spying on us and selling our personal information. EFF advocates for data privacy legislation with teeth and a ban on ad targeting based on online behavioral profiles, as it creates a financial incentive for companies to track our every move.
Legislators can and must also close the "data broker loophole" on the Fourth Amendment. Instead of obtaining a warrant signed by a judge, law enforcement agencies can just buy location data from private brokers to find out where you've been. Last year, Montana became the first state in the U.S. to pass a law blocking the government from buying sensitive data it would otherwise need a warrant to obtain. And in 2024, Senator Ron Wyden's EFF-endorsed Fourth Amendment is Not for Sale Act passed the House before dying in the Senate. Others should follow suit to stop this end-run around constitutional protections.
Online behavioral advertising isn’t just creepy–it’s dangerous. It's wrong that our personal information is being silently harvested, bought by shadow-y data brokers, and sold to anyone who wants to invade our privacy. This latest revelation of warrantless government surveillance should serve as a frightening wakeup call of how dangerous online behavioral advertising has become.
EFF has longwarnedabout the dangers of the “real-time bidding” (RTB) system powering nearly every ad you see online. A proposed class-action settlement with Google over their RTB system is a step in the right direction towards giving people more control over their data. Truly curbing the harms of RTB, however, will require stronger legislative protections.
What Is Real-Time Bidding?
RTB is the process by which most websites and apps auction off their ad space. Unfortunately, the milliseconds-long auctions that determine which ads you see also expose your personal information to thousands of companies a day. At a high-level, here’s how RTB works:
The moment you visit a website or app with ad space, it asks an ad tech company to determine which ads to display for you. This involves sending information about you and the content you’re viewing to the ad tech company.
This ad tech company packages all the information they can gather about you into a “bid request” and broadcasts it to thousands of potential advertisers.
The bid request may contain information like your unique advertising ID, your GPS coordinates, IP address, device details, inferred interests, demographic information, and the app or website you’re visiting. The information in bid requests is called “bidstream data” and typically includes identifiers that can be linked to real people.
Advertisers use the personal information in each bid request, along with data profiles they’ve built about you over time, to decide whether to bid on the ad space.
The highest bidder gets to display an ad for you, but advertisers (and the adtech companies they use to buy ads) can collect your bidstream data regardless of whether or not they bid on the ad space.
Why Is Real-Time Bidding Harmful?
A key vulnerability of real-time bidding is that while only one advertiser wins the auction, all participants receive data about the person who would see their ad. As a result, anyone posing as an ad buyer can access a stream of sensitive data about billions of individuals a day. Data brokers have taken advantage of this vulnerability to harvest data at a staggering scale. Since bid requests contain individual identifiers, they can be tied together to create detailed profiles of people’s behavior over time.
The privacy harms of RTB are not just a matter of misuse by individual data brokers. RTB auctions broadcast torrents of personal data to thousands of companies, hundreds of times per day, with no oversight of how this information is ultimately used. Once your information is broadcast through RTB, it’s almost impossible to know who receives it or control how it’s used.
Proposed Settlement with Google Is a Step in the Right Direction
As the dominant player in the online advertising industry, Google facilitates the majority of RTB auctions. Google has faced several class-action lawsuits for sharing users’ personal information with thousands of advertisers through RTB auctions without proper notice and consent. A recently proposed settlement to these lawsuits aims to give people more knowledge and control over how their information is shared in RTB auctions.
Under the proposed settlement, Google must create a new privacy setting (the “RTB Control”) that allows people to limit the data shared about them in RTB auctions. When the RTB Control is enabled, bid requests will not include identifying information like pseudonymous IDs (including mobile advertising IDs), IP addresses, and user agent details. The RTB Control should also prevent cookie matching, a method companies use to link their data profiles about a person to a corresponding bid request. Removing identifying information from bid requests makes it harder for data brokers and advertisers to create consumer profiles based on bidstream data. If the proposed settlement is approved, Google will have to inform all users about the new RTB Control via email.
While this settlement would be a step in the right direction, it would still require users to actively opt out of their identifying information being shared through RTB. Those who do not change their default settings—research shows this is most people—will remain vulnerable to RTB’s massive daily data breach. Google broadcasting your personal data to thousands of companies each time you see an ad is an unacceptable and dangerous default.
The impact of RTB Control is further limited by technical constraints on who can enable it. RTB Control will only work for devices and browsers where Google can verify users are signed in to their Google account, or for signed-out users on browsers that allow third-party cookies. People who don't sign in to a Google account or don't enable privacy-invasive third-party cookies cannot benefit from this protection. These limitations could easily be avoided by making RTB Control the default for everyone. If the settlement is approved, regulators and lawmakers should push Google to enable RTB Control by default.
The Real Solution: Ban Online Behavioral Advertising
Limiting the data exposed through RTB is important, but we also need legislative change to protect people from the online surveillance enabled and incentivized by targeted advertising. The lack of strong, comprehensive privacy law in the U.S. makes it difficult for individuals to know and control how companies use their personal information. Strong privacy legislation can make privacy the default, not something that individuals must fight for through hidden settings or additional privacy tools. EFF advocates for data privacy legislation with teeth and a ban on ad targeting based on online behavioral profiles, as it creates a financial incentive for companies to track our every move. Until then, you can limit the harms of RTB by using EFF’s Privacy Badger to block ads that track you, disabling your mobile advertising ID (see instructions for iPhone/Android), and keeping an eye out for Google’s RTB Control.
Unlike many of Flock’s cameras, which are designed to capture license plates as people drive by, Flock’s Condor cameras are pan-tilt-zoom (PTZ) cameras designed to record and track people, not vehicles. Condor cameras can be set to automatically zoom in on people’s faces as they walk through a parking lot, down a public street, or play on a playground, or they can be controlled manually, according to marketing material on Flock’s website. We watched Condor cameras zoom in on a woman walking her dog on a bike path in suburban Atlanta; a camera followed a man walking through a Macy’s parking lot in Bakersfield; surveil children swinging on a swingset at a playground; and film high-res video of people sitting at a stoplight in traffic. In one case, we were able to watch a man rollerblade down Brookhaven, Georgia’s Peachtree Creek Greenway bike path. The Flock camera zoomed in on him and tracked him as he rolled past. Minutes later, he showed up on another exposed camera livestream further down the bike path. The camera’s resolution was good enough that we were able to see that, when he stopped beneath one of the cameras, he was watching rollerblading videos on his phone.
In this BHIS podcast, originally recorded as a live webcast, we cover some new techniques and tactics on how to track attackers via various honey tokens. We cover how to […]

 Login