As outlined in the AWS post-quantum cryptography (PQC) migration plan, addressing the risk of harvest now, decrypt later (HNDL) attack is an important part of your post-quantum plan. Upgrading the client-side of your workloads to support quantum-resistant confidentiality is an important aspect of your side of the PQC shared responsibility model. Timelines to plan and execute your PQC upgrades vary by region and by industry and will depend on your own business risk profile. To learn more, see the AWS PQC frequently asked questions.
AWS Secrets Manager uses SSL/TLS to communicate with AWS resources, currently supporting TLS 1.2 and 1.3 in all AWS Regions. The service supports using TLS 1.3 with hybrid post-quantum key exchange for clients that support this capability. The hybrid post-quantum approach establishes TLS connections by combining traditional cryptography (such as X25519) with post-quantum algorithms (ML-KEM), and helps to protect your secrets against both current classical attacks and future quantum computer threats. Regardless of how your workload accesses Secrets Manager, this client-side software upgrade is the only action you need to take to address risk to secrets from HNDL. Your secrets at rest are already encrypted using keys managed by AWS Key Management Service (AWS KMS). Properly implemented symmetric encryption is considered quantum-resistant; asymmetric cryptography faces quantum threats. To learn more, watch AWS re:Inforce 2025 – Post-Quantum Cryptography Demystified.
To reduce builder effort for client-side upgrades, we’re pleased to announce the following Secrets Manager clients now enable and prefer post-quantum TLS when initiating connections to Secrets Manager: Secrets Manager Agent (v2.0.0 or later), the AWS Lambda extension (v19 or later) and the Secrets Manager CSI Driver (v2.0.0 or later). For SDK-based clients, hybrid post-quantum key exchange is available in supported AWS SDKs. Enablement requirements vary by language, version, and operating system. See the following table for your SDK client.
This launch is part of the ongoing commitment AWS has made to migrate systems to post-quantum cryptography and making it straightforward for our customers to do the same. See Post-Quantum Cryptography to learn more.
The following table summarizes the behavior for each client. When the client is upgraded to support hybrid post-quantum key exchange, the Secrets Manager service endpoint automatically selects it during the TLS handshake. Upgrading to the versions listed in the table is the only action you need to take for your workload to begin using hybrid post-quantum key exchange when calling Secrets Manager APIs.
The AWS SDK for Python (boto3) uses the OS-provided OpenSSL for TLS. Hybrid PQ key exchange in TLS requires running on a system with OpenSSL 3.5 or later installed.
The Secrets Manager caching libraries are built on the AWS SDKs and inherit their TLS behavior. Note for Java: The JDBC driver flag and Java Caching flag must be set to enable Hybrid PQ key exchange in TLS.
If you’re using the Secrets Manager Agent, the Lambda extension, or the CSI Driver, upgrade to the listed version to use hybrid post-quantum key exchange in TLS as the default. Customers using the AWS SDK for Rust, Go, or Node.js at the versions listed in the table are already upgraded and no additional action is required. The SDK will select the hybrid post-quantum key exchange for API calls. For customers using the AWS SDK for Python, hybrid post-quantum key exchange in TLS requires OpenSSL 3.5 or later to be present on the host system. Guidance on verifying and enabling this is available in the AWS Secrets Manager documentation. For customers using the AWS SDK for Java v2, hybrid post-quantum key exchange in TLS requires using the AWS CRT HTTP client. The postQuantumTlsEnabled(true) must be set on the CRT client to enable hybrid post-quantum key exchange in TLS.
After your client versions meet the requirements listed in the table, you can verify that your connections are actively using hybrid post-quantum key exchange.
How to verify your connection uses hybrid post-quantum key exchange
With hybrid post-quantum key exchange using ML-KEM now enabled by default for Secrets Manager clients (see the preceding table), most customers will not need ongoing monitoring to verify correct behavior or detect regressions. However, security teams and compliance officers might want to confirm that their Secrets Manager API calls are negotiating the hybrid key exchange. On the server side, you can confirm hybrid post-quantum key exchange in TLS by using AWS CloudTrail. On the client side, you can inspect TLS handshake details using a utility like Wireshark or by using developer tools built into major web browsers.
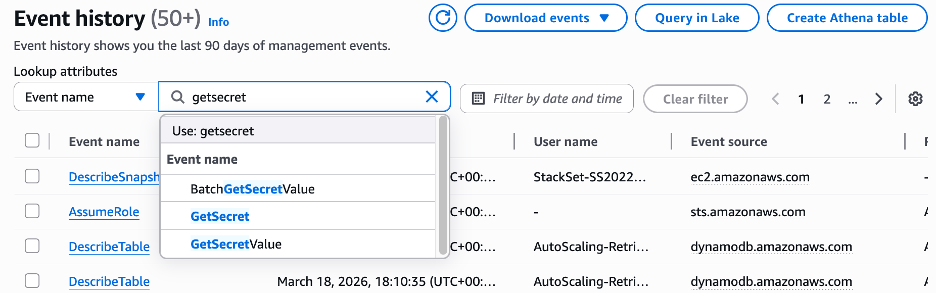
Verification is a two-step process: first, fetch a secret using your Secrets Manager client to generate a GetSecretValue API call, then confirm in AWS CloudTrail that the call negotiated hybrid post-quantum key exchange.
Fetch your secret using your Secrets Manager client
The following examples show how to retrieve your secret using the Secrets Manager Agent, Lambda extension, and CSI Driver—each of which will automatically negotiate hybrid post-quantum key exchange when calling the GetSecretValue API.
To verify hybrid post-quantum TLS with Secrets Manager Agent on EC2 instance: Install the agent on your Amazon Elastic Compute Cloud (Amazon EC2) instance and use it as a client to fetch your secret.
Use the agent to fetch your secret. curl -H “X-Aws-Parameters-Secrets-Token: $(</tmp/awssmatoken)” localhost:2773/secretsmanager/get?secretId=<YOUR-SECRET-ARN>
Wait for about 5 minutes for CloudTrail to deliver the logs.
To verify hybrid post-quantum TLS with Lambda extension: Use the AWS parameters and Secrets Manager Lambda extension to create a Lambda function that will consume your secrets from Secrets Manager using direct API calls.
Confirm hybrid post-quantum key exchange using CloudTrail
CloudTrail logs include a tlsDetails field for Secrets Manager API calls. When hybrid post-quantum key exchange in TLS is active, the keyExchange field in tlsDetails will show X25519MLKEM768. Each CloudTrail record includes a tlsDetails field that contains the cipher suite and, where available, the key exchange group negotiated during the TLS handshake.
If the keyExchange field shows X25519MLKEM768, then hybrid post-quantum key exchange in TLS is active. If it shows a traditional algorithm such as X25519, the client is not advertising ML-KEM support, and you should check the client version and configuration.
Troubleshooting
If your Secrets Manager API calls aren’t negotiating X25519MLKEM768 after updating your clients, check your SDK version, OpenSSL version (Python), and firewall or proxy configuration as shown in the Client Hybrid Post-Quantum Key Exchange Requirements section near the beginning of this post.
What’s next
This launch is one step in a broader migration. AWS is continuing to roll out ML-KEM support across AWS service HTTPS endpoints as part of Workstream 2 of the AWS PQC Migration Plan, with a target of full coverage across public AWS endpoints.
Support for CRYSTALS-Kyber, the pre-standardization predecessor to ML-KEM, is phasing out across AWS endpoints in 2026. Customers on older SDK versions that advertise only CRYSTALS-Kyber support will fall back gracefully to traditional TLS rather than negotiate the deprecated algorithm. To avoid this fallback, upgrade to the SDK versions listed in this post.
The journey of PQC migration extends beyond confidentiality of data in transit. To stay informed about the latest developments in the AWS PQC journey and your side of shared responsibility, follow the AWS Post-Quantum Cryptography page.
Conclusion
AWS Secrets Manager now enables hybrid post-quantum key exchange using ML-KEM by default to help protect your secrets and support your compliance efforts. This update requires no code changes or configuration updates for customers using the latest client versions.
This post covered how AWS Secrets Manager uses hybrid post-quantum cryptography to secure TLS connections, which clients support this capability, and how to verify that your connections are protected against harvest now, decrypt later attacks.
To benefit from this announcement today:
Upgrade your Secrets Manager client (Agent, Lambda extension, or CSI Driver) to the latest available versions to enable hybrid post-quantum key exchange using ML-KEM
If your workload uses the AWS SDK instead of a caching client, upgrade your AWS SDK and underlying dependencies to the minimum versions listed in this post
Verify hybrid post-quantum key exchange in TLS is active by checking the keyExchange field in CloudTrail tlsDetails for your Secrets Manager API calls
Test end-to-end hybrid post-quantum key exchange TLS connectivity in your environment, including network paths that traverse corporate firewalls or proxies
AWS will continue rolling out post-quantum cryptography support. For information about the broader migration effort, see the AWS PQC Migration Plan. Keep an updated cryptographic inventory of your broader environment to identify other uses of traditional public-key cryptography that will require migration. The CISA Quantum-Readiness guidance and the AWS PQC Migration Plan are good starting points.
Half a million Britons signed up to help cure cancer. Their data ended up for sale on Alibaba.
The UK Biobank charity informed the British government of an incident concerning the medical data belonging to 500,000 British citizens being offered for sale on the Chinese e-commerce website Alibaba.
The National Data Guardian, Dr Nicola Byrne, said in a statement:
“People who generously share their health data to benefit others through medical research rightly expect it to be kept safe and for there to be accountability when things go wrong.”
Officials said the researchers downloaded the data under a legitimate contract, but its appearance on Alibaba shows how “approved” access can still turn into public exposure.
UK Biobank holds more than 15 million biological samples and detailed health records from volunteers recruited between 2006 and 2010, and researchers worldwide use it to study cancer, dementia, diabetes, and other chronic diseases.
UK Biobank normally signs contracts with vetted universities and private companies before it lets them access the data, but investigators traced the Alibaba listings to three research institutions. UK Biobank revoked their access and paused new data access while it strengthens security controls.
At least one listing reportedly contained data on all 500,000 volunteers, and Alibaba and Chinese authorities removed the adverts before anyone could confirm a sale.
The dataset comes from UK Biobank’s long‑running research cohort and includes genetic sequences, blood samples, medical imaging, and detailed lifestyle information used for global health research.
UK Biobank emphasizes that the data was “de‑identified,” meaning it didn’t include names, addresses, or NHS numbers. But it still contained granular demographics, such as gender, age, birth month/year, socioeconomic indicators, lifestyle details, and health measures. We have repeatedly seen that such data can be re‑linked to individuals by cross‑referencing with other public or commercial records.
Why China cares
US intelligence, policy reports, and academic work paint a consistent picture: China treats large, diverse human genomic and health datasets as a strategic resource for both economic and security reasons.
The US National Counterintelligence and Security Center (NCSC) explicitly states that the People’s Republic of China views bulk healthcare and genomic data as a “strategic commodity” to drive its biotech, AI, and precision medicine industries, and has invested billions in national genomics and precision‑medicine initiatives.
Large datasets from non‑Chinese populations are particularly valuable for building AI models and improving the global commercial competitiveness of Chinese pharma and biotech.
From an attacker’s or foreign intelligence perspective, UK Biobank is a “crown jewel” asset: It’s curated, high‑quality, population‑scale, and much more useful than random breach dumps. And because genetic data is immutable (unlike a password, it cannot be replaced), any compromise has very long‑term intelligence usefulness.
Last year, the Guardian reported that one in five successful UK Biobank access applications came from Chinese entities, including BGI, China’s flagship genomics company that was later placed on the US Entity List over concerns about its role in surveillance of minority populations.
China is not just stockpiling DNA for curiosity’s sake. It is building a global genomic map that covers adversaries as well as its own citizens.
Your genome data
There have been major concerns about genetic data ending up in the wrong hands, and for good reason. But I’m not going to say that volunteering your medical data for research is bad. Researchers often put the data to good use to help others.
But there are some good questions to ask before doing so.
Who runs the project and where is it based? Prefer non‑profit or academic biobanks with clear public‑interest mandates and strong oversight, rather than opaque commercial data brokers.
How do they store the collected data? Ask specifically about genomic data, raw sequencing files, links to medical records, and whether data is encrypted at rest and in transit.
Who can access the data and under what controls? Look for a formal access committee, strict contracts, and technical controls like secure analysis environments and limited export options, not “download CSV and walk away” models like the one that enabled the UK Biobank incident.
Are foreign entities allowed to access or copy the data? In light of US and UK government warnings about Chinese access to Western genomic data, it’s reasonable to ask whether data can be accessed, processed, or stored in jurisdictions with different security expectations.
How do they handle re‑identification risk? As we’ve discussed, “de‑identified” is not a magic word. Privacy experts and US intelligence have warned that health and genomic data can often be re‑identified when combined with other datasets.
If data containing your DNA is in someone else’s hands, you can’t put it back, but you can demand better governance, push institutions to treat genomic data as national‑security‑grade sensitive.
It also requires more skepticism of highly targeted scams. Attackers can use large combined datasets to craft convincing spear‑phishing or health‑related scams, for example, contacting you about a specific condition you or a family member has. Treat unsolicited health or DNA‑related emails, calls, and apps with extra suspicion.
What do cybercriminals know about you?
Use Malwarebytes’ free Digital Footprint scan to see whether your personal information has been exposed online.
Windows Interprocess Communication (IPC) is one of the most complex technologies within the Windows operating system. At the core of this ecosystem is the Remote Procedure Call (RPC) mechanism, which can function as a standalone communication channel or as the underlying transport layer for more advanced interprocess communication technologies. Because of its complexity and widespread use, RPC has historically been a rich source of security issues. Over the years, researchers have identified numerous vulnerabilities in services that rely on RPC, ranging from local privilege escalation to full remote code execution.
In this research, I present a new vulnerability in the RPC architecture that enables a novel local privilege escalation technique likely in all Windows versions. This technique enables processes with impersonation privileges to elevate their permissions to SYSTEM level. Although this vulnerability differs fundamentally from the “Potato” exploit family, Microsoft has not issued a patch despite proper disclosure.
I will demonstrate five different exploitation paths that show how privileges can be escalated from various local or network service contexts to SYSTEM or high-privileged users. Some techniques rely on coercion, some require user interaction and some take advantage of background services. As this issue stems from an architectural weakness, the number of potential attack vectors is effectively unlimited; any new process or service that depends on RPC could introduce another possible escalation path. For this reason, I also outline a methodology for identifying such opportunities.
Finally, I examine possible detection strategies, as well as defensive approaches that can help mitigate such attacks.
MSRPC
Microsoft RPC (Remote Procedure Call) is a Windows technology that enables communication between two processes. It enables one process to invoke functions that are implemented in another process, even though they are running in different execution contexts.
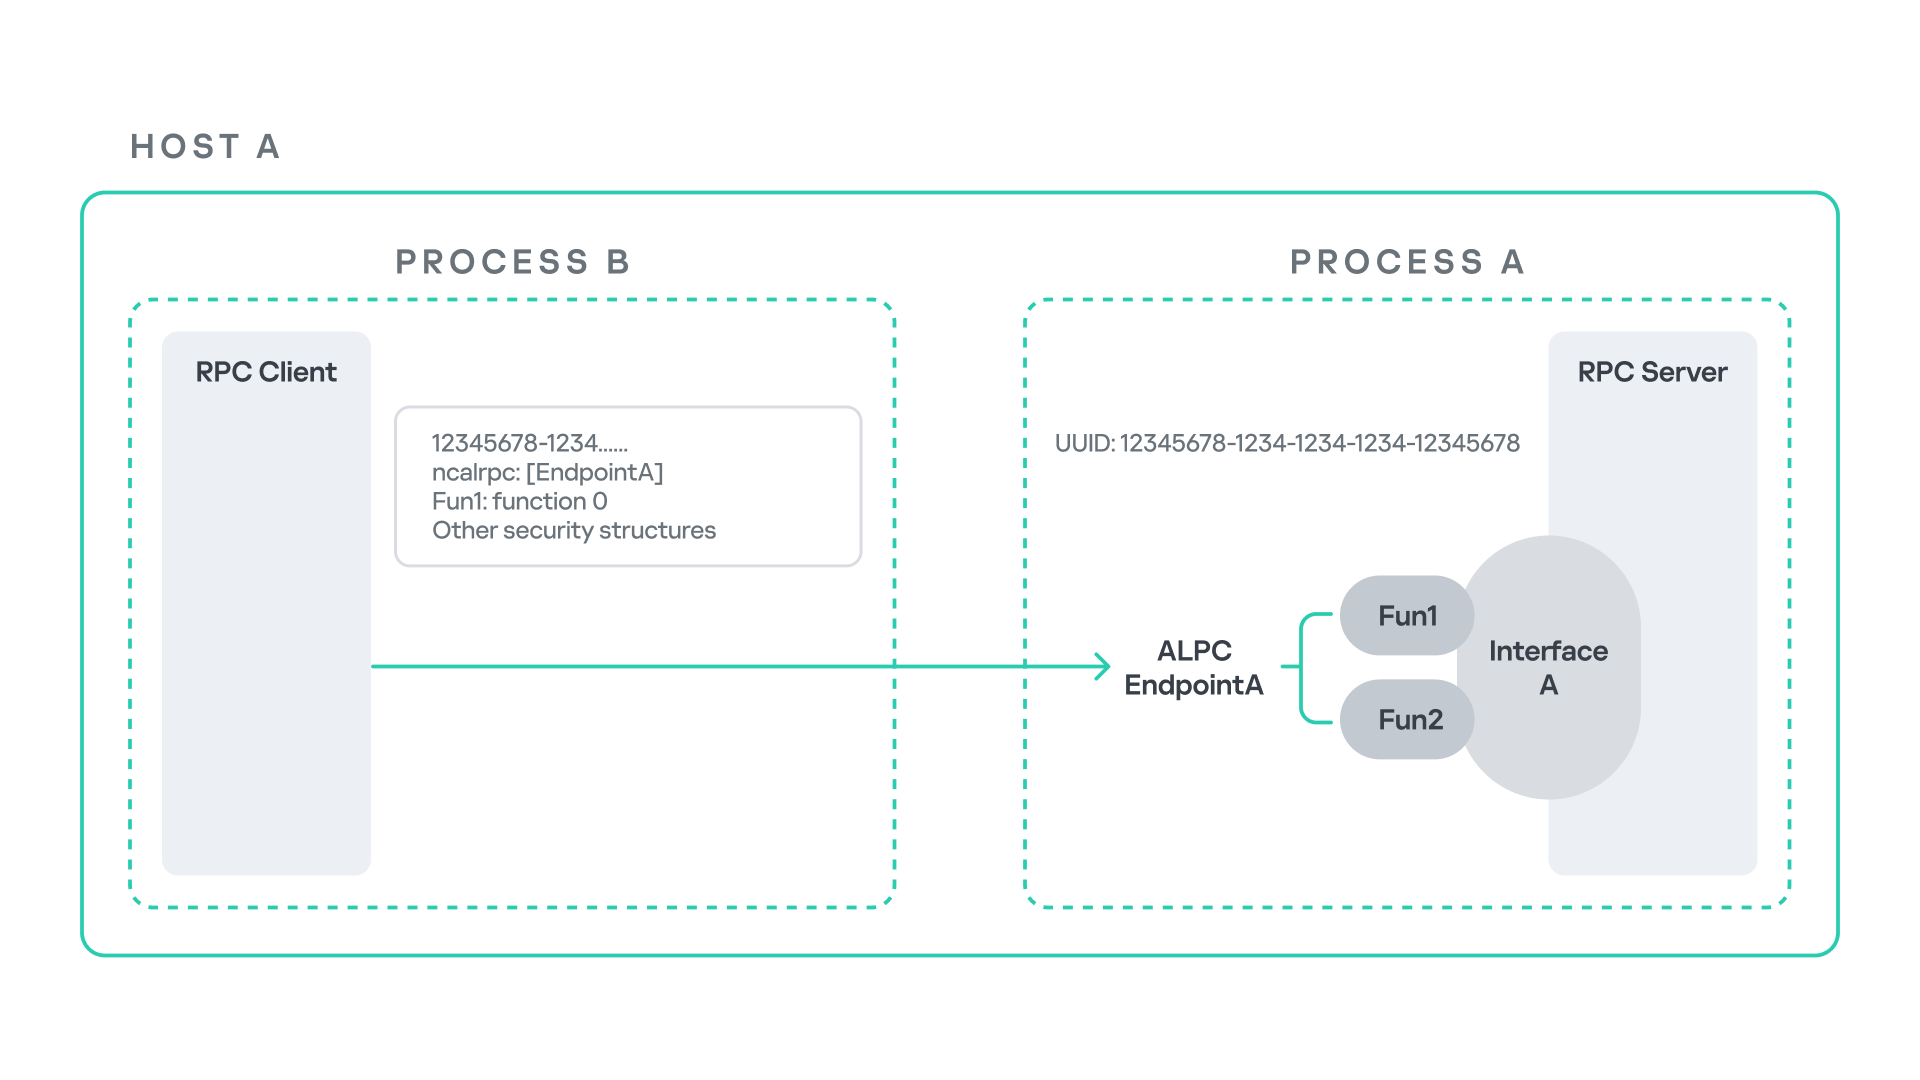
The figure below illustrates this mechanism.
Let us assume that Host A is running two processes: Process A and Process B. Process B needs to execute a function that resides inside Process A. To enable this type of interaction, Windows provides the Remote Procedure Call (RPC) architecture, which follows a client–server model. In this model, Process A acts as the RPC server, exposing its functionality through an interface, in our example, Interface A. Each RPC interface is uniquely identified by a Universally Unique Identifier (UUID), which is represented as a 128-bit value. This identifier enables the operating system to distinguish one interface from another.
The interface defines a set of functions that can be invoked remotely by the RPC client implemented in Process B. In our example, the interface exposes two functions: Fun1 and Fun2.
To communicate with the server, the RPC client must establish a connection through a communication endpoint. An endpoint represents the access point that enables transport between the client and the server. Because RPC supports multiple transport mechanisms, different endpoint types may exist, depending on the underlying transport.
For example:
When TCP is used as the transport layer, the endpoint is a TCP port.
When SMB is used, communication occurs through a named pipe.
When ALPC is used, the endpoint is an ALPC port.
Each transport mechanism is associated with a specific RPC protocol sequence. For instance:
ncacn_ip_tcp is used for RPC over TCP.
ncacn_np is used for RPC over named pipes.
ncalrpc is used for RPC over ALPC.
In this research, I focus specifically on Advanced Local Procedure Call (ALPC) as the RPC transport mechanism. ALPC is a Windows interprocess communication mechanism that predates MSRPC. Today, RPC can leverage ALPC as an efficient transport layer for communication between processes located on the same machine.
For simplicity, an ALPC port can be thought of as a communication channel similar to a file, where processes can send messages by writing to it, and receive messages by reading from it.
When the client wants to invoke a remote function, for example, Fun1, it must construct an RPC request. This request includes several important pieces of information, such as the interface UUID, the protocol sequence, the endpoint, and the function identifier. In RPC, functions are not referenced by name, but by a numerical identifier called the operation number (OPNUM). Depending on the requirements of the call, the request may also contain additional structures, such as security-related information.
Impersonation in Windows
In Windows, impersonation enables a service to temporarily operate using another user’s security context. For example, a service may need to open a file that belongs to a user while performing a specific operation. By impersonating the calling user, the system allows the service to access that file, even if the service itself would not normally have permission to do so. You can read more about impersonation in James Forshaw’s book Windows Security Internals.
This research focuses specifically on RPC impersonation. Instead of describing the interaction as a service and a user, I refer to the participants as a client and a server. In this model, the RPC server may temporarily adopt the identity of the client that initiated the request.
To perform this operation, the RPC server can call the RpcImpersonateClient API, which causes the server thread to execute under the client’s security context.
However, in some situations, a client may not want the server to be able to impersonate its identity. To control this behavior, Windows introduces the concept of an impersonation level. This defines how much authority the client grants the server to act on its behalf.
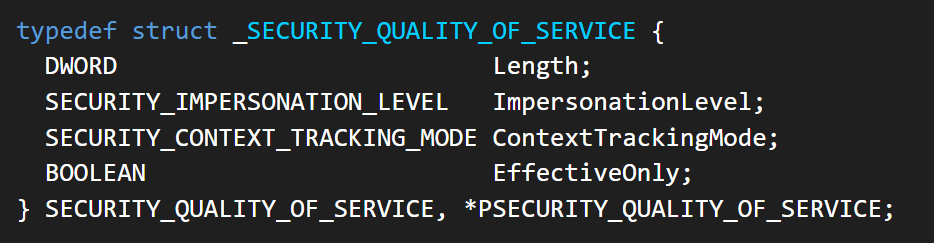
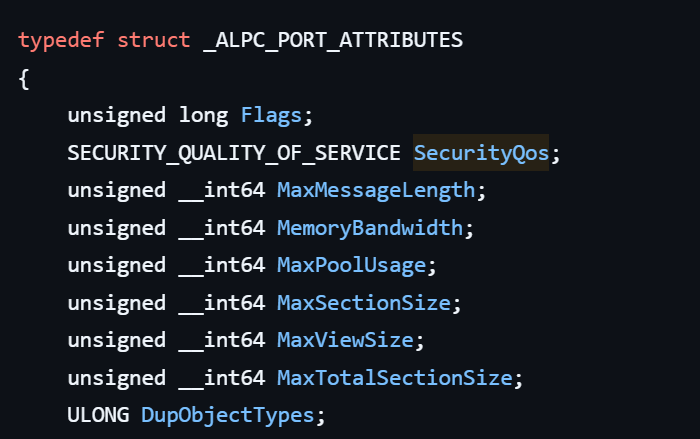
These settings are defined as part of the Security Quality of Service (SQOS) parameters, specified using the SECURITY_QUALITY_OF_SERVICE structure.
As you can see, this structure contains the impersonation level field, which determines the extent to which the server can assume the client’s identity.
Impersonation levels range from Anonymous, where the server cannot impersonate the client at all, to Impersonate and Delegate, which allow the server to act fully on behalf of the client.
At the same time, not every server process is allowed to impersonate a client. If any process could perform impersonation freely, it would pose a serious security risk. To prevent this, Windows requires the server process to possess a specific privilege called SeImpersonatePrivilege. Only processes with this privilege can successfully impersonate a client.
This privilege is granted by default to certain service accounts, such as Local Service and Network Service.
Interaction between Group Policy service and TermService
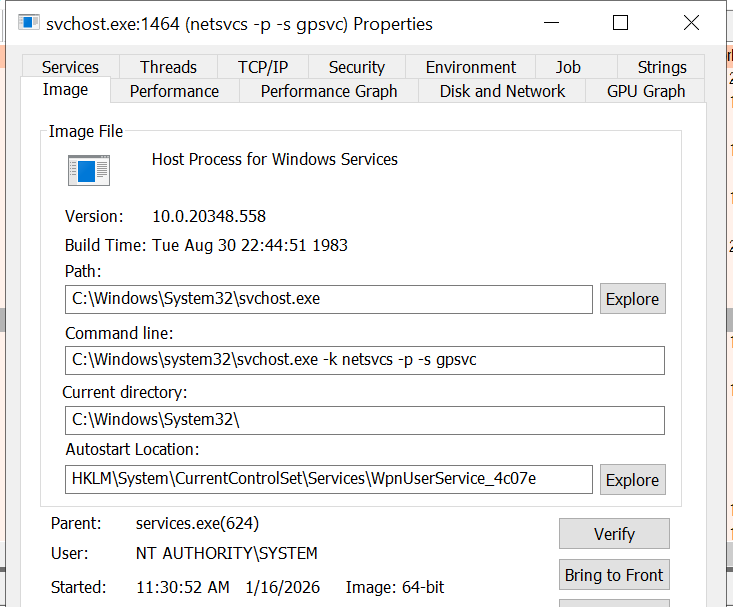
The Group Policy Client service (gpsvc) is a core Windows service responsible for applying and enforcing group policy settings on a system. It runs under the SYSTEM account inside svchost.exe.
When a group policy update is triggered, Windows uses an executable called gpupdate.exe. This tool can be executed with the /force flag to force an immediate refresh of all group policy settings. Internally, this executable communicates with the Group Policy service, which coordinates the update process.
At a certain stage during this operation, the Group Policy service attempts to communicate with TermService (Terminal Service, the Remote Desktop Services service) using RPC.
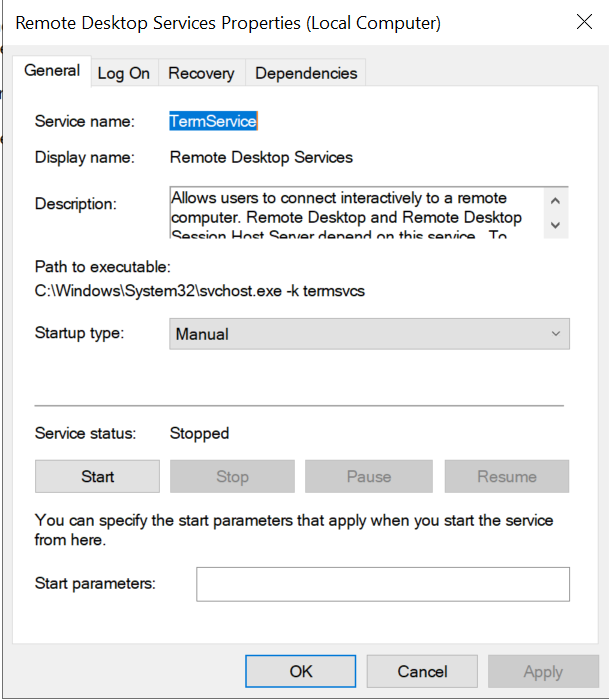
TermService is responsible for providing remote desktop functionality. This service is not running by default and can be enabled manually by the administrator via activation of Remote Desktop access. When this happens, the service exposes an RPC server with multiple interfaces and endpoints. TermService runs under the NT AUTHORITY\Network Service account.
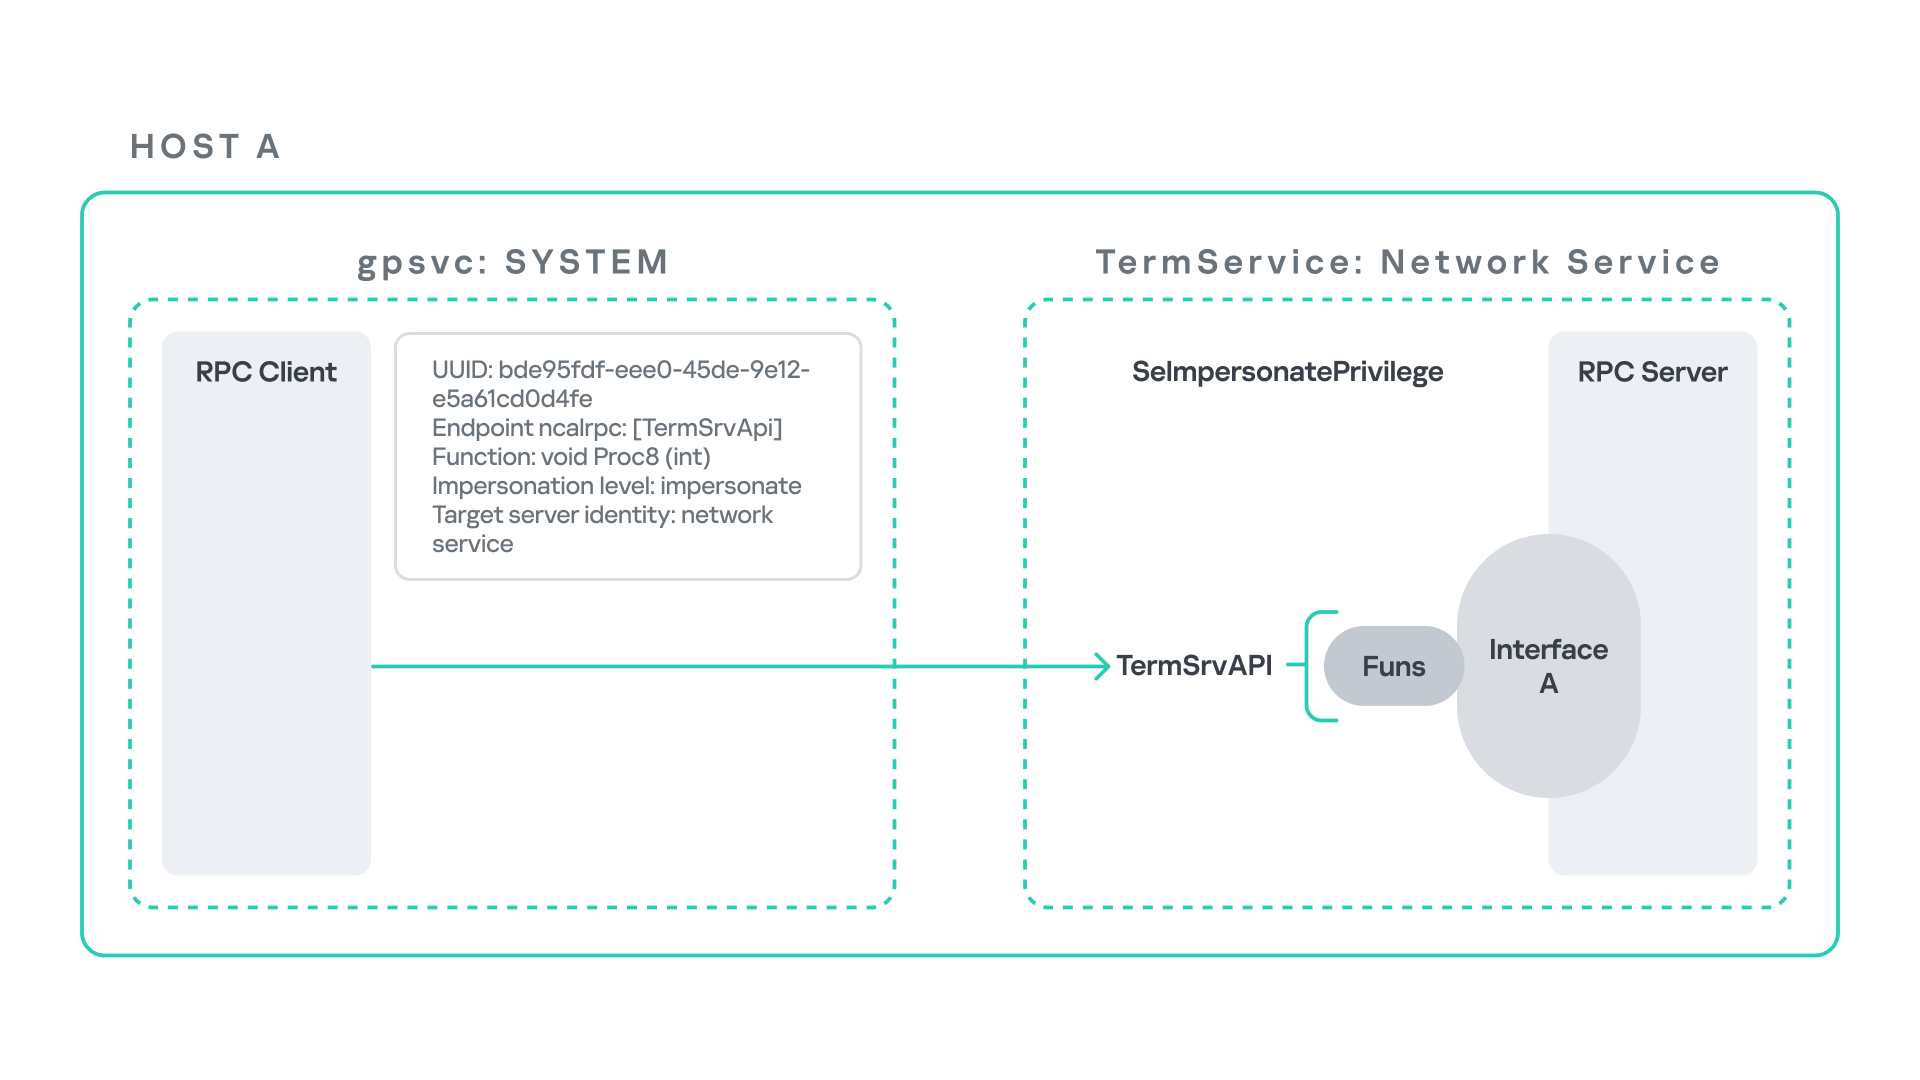
When the command gpupdate /force is executed, the Group Policy service performs an RPC call to the TermService using the following parameters:
UUID: bde95fdf-eee0-45de-9e12-e5a61cd0d4fe.
Endpoint: ncalrpc:[TermSrvApi].
Function: void Proc8(int).
However, because TermService is disabled by default, the RPC call fails and an exception occurs in rpcrt4.dll (the RPC runtime). The returned error is:
0x800706BA (RPC_S_SERVER_UNAVAILABLE, 1722).
This error indicates that the RPC client could not reach the target server.
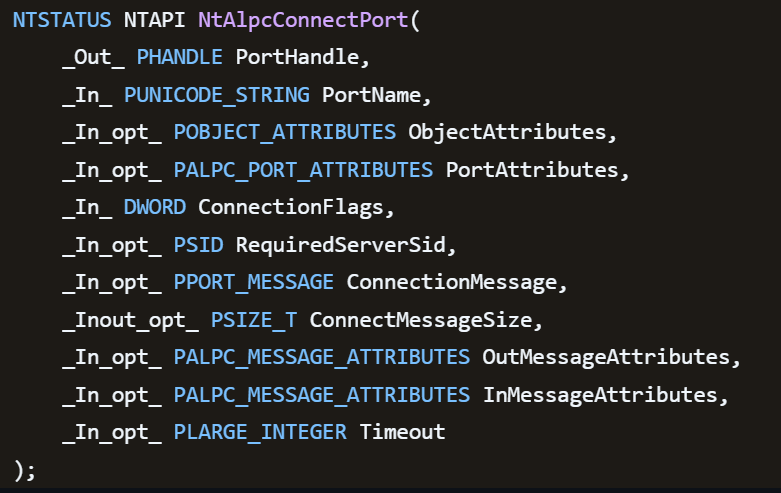
Tracing the failure path further reveals that the root cause originates from a call to NtAlpcConnectPort, which is used by RPC to establish an ALPC connection between processes.
The NtAlpcConnectPort function is responsible for connecting to a specific ALPC port and returning a handle that the client can use for further communication. This function accepts multiple parameters.
The first two parameters include:
A pointer to the returned port handle.
The ALPC port name, represented as an ASCII string.
Another important argument is PortAttributes, which is an ALPC_PORT_ATTRIBUTES structure. Inside this structure is the SECURITY_QUALITY_OF_SERVICE structure, which, as mentioned above, defines the impersonation level used for the connection.
The final parameter of interest is RequiredServerSid, which specifies the expected identity of the target server process. This identity is represented using a Security Identifier (SID) structure.
Inspecting this call reveals that the Group Policy service attempts to connect to the RPC server using an impersonation level of Impersonate, expecting the remote server to run under the Network Service account. This behavior makes sense because TermService normally runs under Network Service.
Based on all the information above, the following scheme can be created to illustrate the interaction between TermService and gpsvc.
Up to this point, nothing unusual has occurred. An RPC client attempts to connect to an RPC server that is unavailable, resulting in an exception handled by the RPC runtime.
However, an interesting question arises: What if an attacker compromises a service that runs under the Network Service identity and mimics the exact RPC server exposed by TermService?
Could the attacker deploy a fake RPC server with the same endpoint?
If so, would the RPC runtime allow the client to connect to this illegitimate server?
And if the connection is successful, how could an attacker leverage this behavior?
Coercing the Group Policy service
To better understand the implications of the previously described behavior, let us consider the following attack scenario.
Imagine an attacker has compromised a service running on the system under the Network Service account, for example, an IIS server operating under the Network Service account. With this level of access, the attacker can deploy a malicious RPC server.
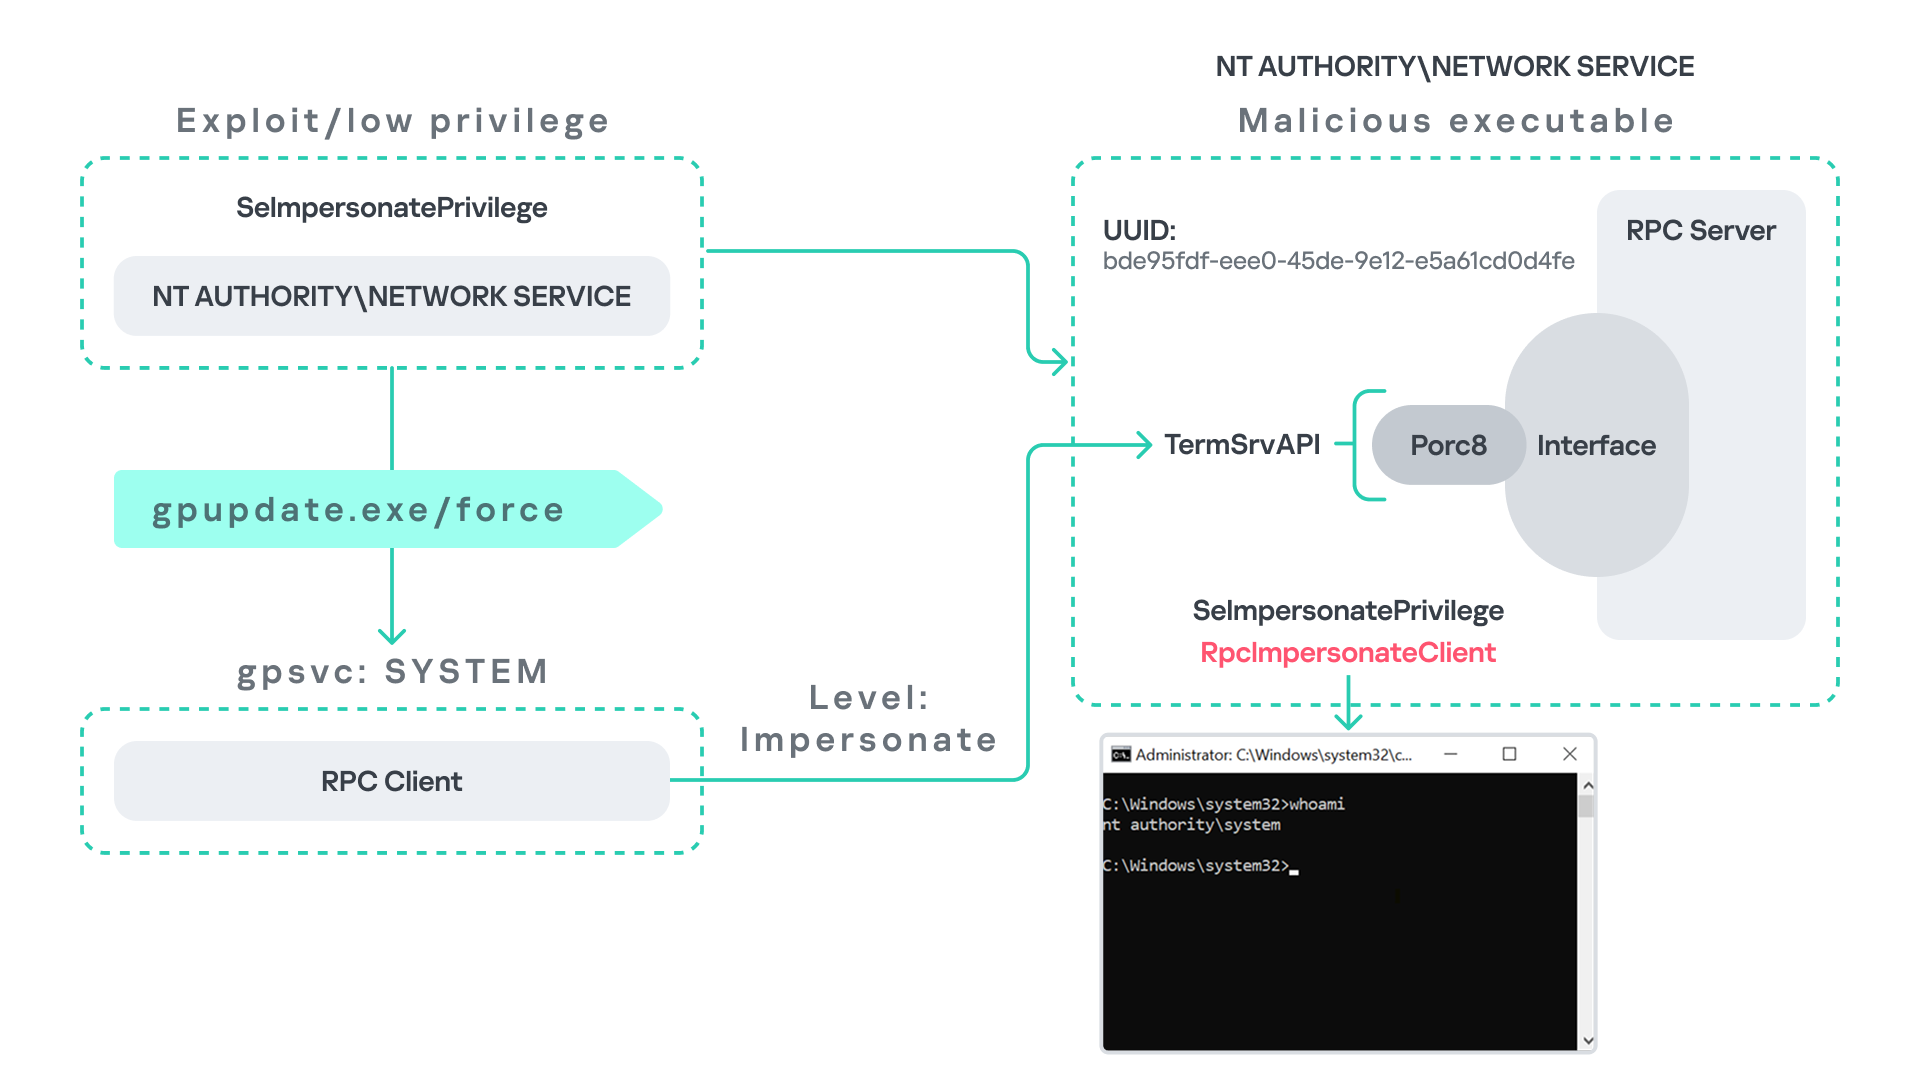
The attacker’s RPC server is designed to mimic the RPC interface exposed by the Remote Desktop service (TermService). Specifically, it implements the same RPC interface UUID and exposes the same endpoint name: TermSrvApi. Once deployed, the malicious server listens for RPC requests that would normally be directed to the legitimate RDP service.
Next, the attacker coerces the Group Policy service by triggering a policy update using gpupdate.exe /force. This causes the Group Policy Client service, which runs under the SYSTEM account, to perform the previously described RPC call. As observed earlier, this RPC call uses a high impersonation level (Impersonate).
When the attacker’s fake RPC server receives the request, it calls RpcImpersonateClient. This enables the server thread to impersonate the security context of the calling client, which, in this case, is SYSTEM.
As a result, the attacker can elevate privileges from Network Service to SYSTEM. In our proof-of-concept implementation, the exploit demonstrates privilege escalation by spawning a SYSTEM-level command prompt.
When this attack scenario was first discussed, it was purely theoretical. However, after implementing the malicious RPC server, the experiment confirmed that Windows allowed the server to be deployed and started successfully, and that the RPC runtime permitted the client to connect to the malicious endpoint. This made it possible to reliably escalate privileges from Network Service to SYSTEM using this technique. For this attack to succeed, though, at least one group policy must be applied on the system.
RPC architecture flow
Further investigation revealed that many Windows services attempt to communicate with TermService using RPC. These RPC calls often originate from winsta.dll, which acts as the RPC client component.
Windows processes invoke APIs exposed by winsta.dll; these APIs rely internally on RPC communication with TermService. This pattern is common in Windows; many system DLLs use RPC behind the scenes when their exported APIs are called.
However, it appears that the RPC runtime (rpcrt4.dll) does not provide a mechanism to verify the legitimacy of RPC servers. Moreover, Windows allows another process to deploy an RPC server that exposes the same endpoint as a legitimate service.
As a result, this architectural design introduces a large attack surface because RPC is heavily used across numerous system DLLs. Applications that invoke seemingly benign APIs may unintentionally trigger privileged RPC interactions. Under certain conditions, these interactions could be abused to achieve local privilege escalation without the user’s knowledge.
Identifying RPC calls to unavailable servers
As the issue appears to stem from an architectural weakness, a systematic approach is needed to identify RPC clients attempting to communicate with servers that are unavailable. First, I need a platform capable of monitoring RPC activity and extracting relevant information from each RPC request.
Specifically, I need to capture key RPC metadata, including:
Interface UUID, endpoint, and OPNUM.
Impersonation level and RPC status code.
Client process privilege level, process name, and module path.
This information is critical because it enables me to reconstruct the RPC interaction, mimic the expected RPC server, and determine how the call is triggered.
The platform that provides this capability is Event Tracing for Windows (ETW). ETW is a built-in Windows logging framework that captures both kernel-mode and user-mode events in real time.
Windows provides a tool called logman to collect ETW data. It enables us to create trace sessions, select event providers, and configure the verbosity level of the tracing process. The collected tracing data is stored in an .etl file, which can later be analyzed using tools such as Event Viewer or other ETW analysis utilities.
ETW provides deep visibility into RPC activity without requiring modifications to applications. Through ETW, it is possible to capture detailed RPC information, such as:
RPC bindings
Endpoints
Interface UUIDs
Authentication details
Call flow and timing
RPC status codes
However, I’m not interested in every RPC event. My focus is on RPC call failures, specifically those that return the status RPC_S_SERVER_UNAVAILABLE.
For an event to be relevant to this research, the exception must meet two conditions:
It must originate from a high-privileged process because impersonating such a process may allow an attacker to escalate privileges to a more powerful security context.
The RPC call must use a high impersonation level, enabling the server to fully impersonate the client once the connection is established.
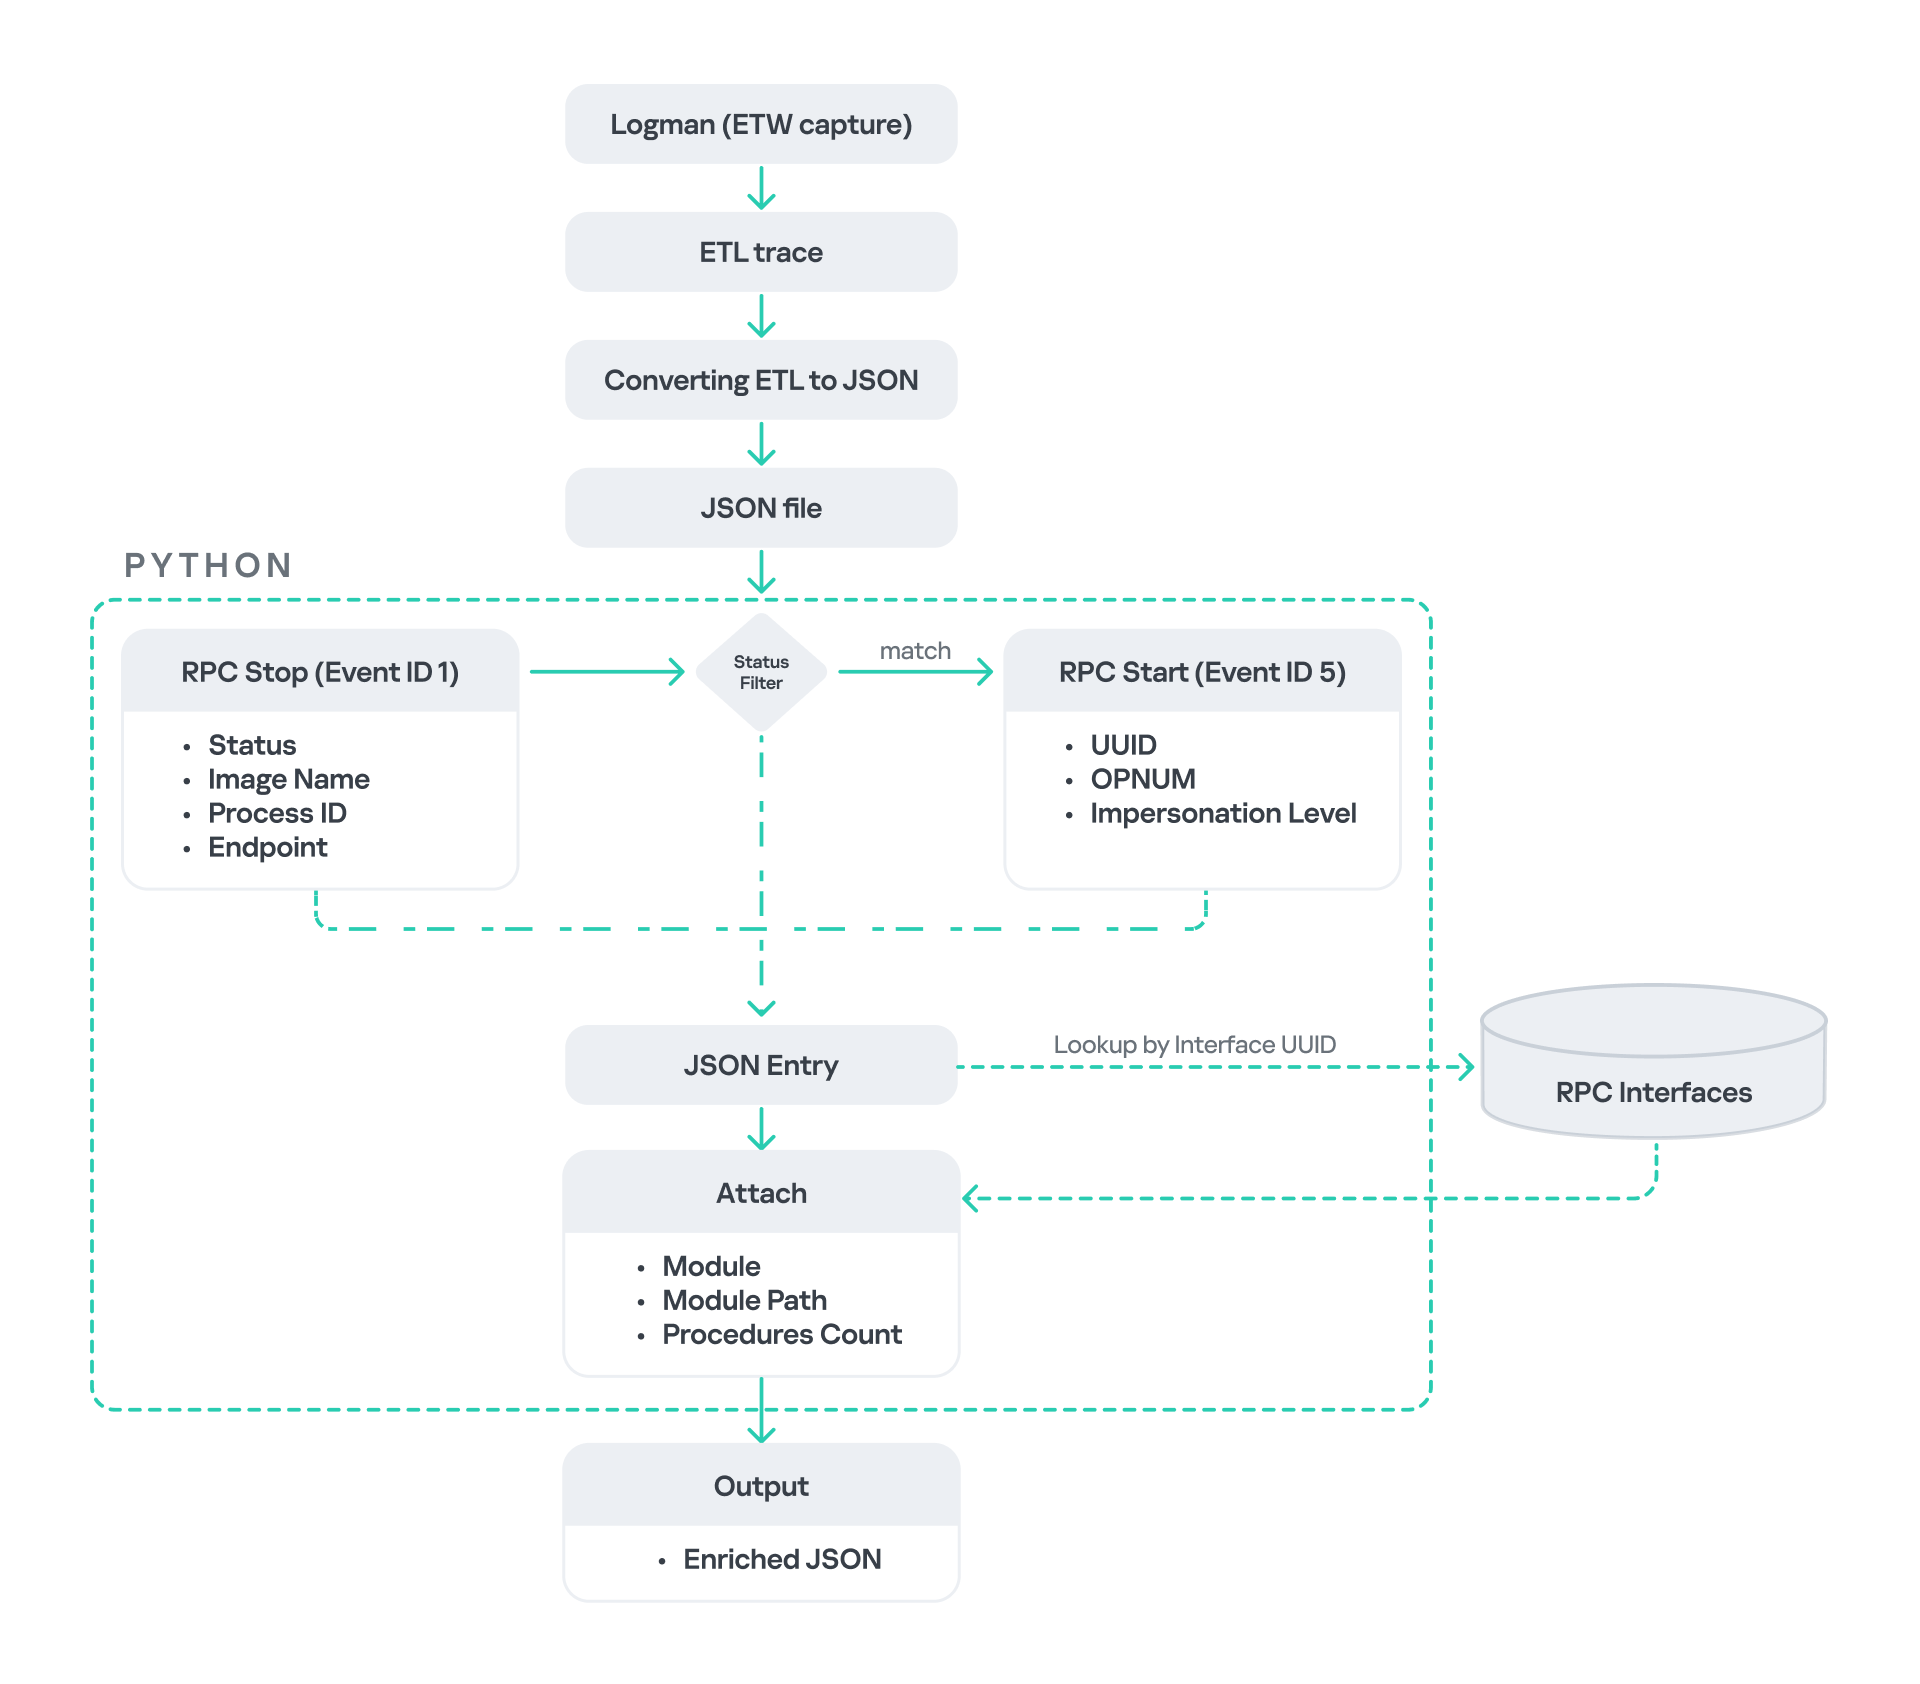
I cannot rely solely on the raw ETW output to implement this framework because it contains thousands of events, making manual filtering with standard tools inefficient. Therefore, I need to automate this process. The workflow shown below enables me to efficiently filter and extract only those events that are relevant to this analysis.
After generating the logs as an .etl file, I convert them to JSON format using tools such as etw2json. JSON is a much easier format to process programmatically. In this case, I use a Python script to filter and extract the relevant information.
The filtering process begins with a search for Event ID 1, which corresponds to an RPC stop event. This event indicates that the RPC client has completed the call and the result is available. From this event, I can extract useful information, such as:
Status code
Client process name
Client process ID
Endpoint
After extracting the status code, I filter for the specific value RPC_S_SERVER_UNAVAILABLE, which indicates that the target server was unreachable during an RPC call. These events represent the scenarios that are of interest.
However, Event ID 1 does not contain all of the required RPC metadata. To obtain the missing information, it is correlated with Event ID 5, which represents the RPC start event. This event is generated when the client initiates the RPC call.
By matching the metadata between Event ID 1 and Event ID 5, I can recover the missing details, including:
Interface UUID
OPNUM
Impersonation level
After correlating and filtering these events, a JSON entry is obtained that is almost ready for analysis. At this stage, the data can be enriched further by adding context that will be helpful when reversing or analyzing the RPC server implementation. For example, the following can be identified:
The DLL where the RPC interface is implemented
The location of that DLL
The number of procedures exposed by the interface
To retrieve this information, I match the UUID with an external RPC interface database. In this case, I used the RPC database, which contains a comprehensive list of RPC interfaces and their corresponding DLL implementations.
At the end of this process, a complete JSON dataset is obtained that can be used for further analysis.
One important observation is that the RPC calls I am looking for may only occur when specific system actions are triggered. Additionally, the resulting exceptions may vary from one system to another depending on which services are enabled or disabled. Therefore, I need a reliable way to generate these RPC exceptions.
In this research, I used several approaches to trigger such events:
Monitoring RPC activity during system startup
I observed RPC activity while the system booted. During startup, many services initialize and perform various RPC calls, which increases the chances of capturing calls to unavailable servers.
Triggering administrative operations I developed PowerShell scripts that perform common administrative tasks, such as updating Group Policy, changing network settings, or creating new users. These operations often trigger RPC communication and may generate exceptions.
Disabling services intentionally
After observing that Remote Desktop was disabled by default, I extended this idea by disabling additional services one by one and repeating the previous steps. This approach can reveal RPC clients that attempt to connect to services that are no longer available.
Additional privilege escalation paths
After running the logging and monitoring framework described earlier, I identified four additional scenarios that can lead to privilege escalation. The following sections introduce each case and explain how escalation can be achieved.
User interaction: From Edge to RDP
Microsoft Edge (msedge.exe) comes preinstalled on Windows systems. During startup, Edge triggers an RPC call to TermService. This RPC call is performed with a high impersonation level.
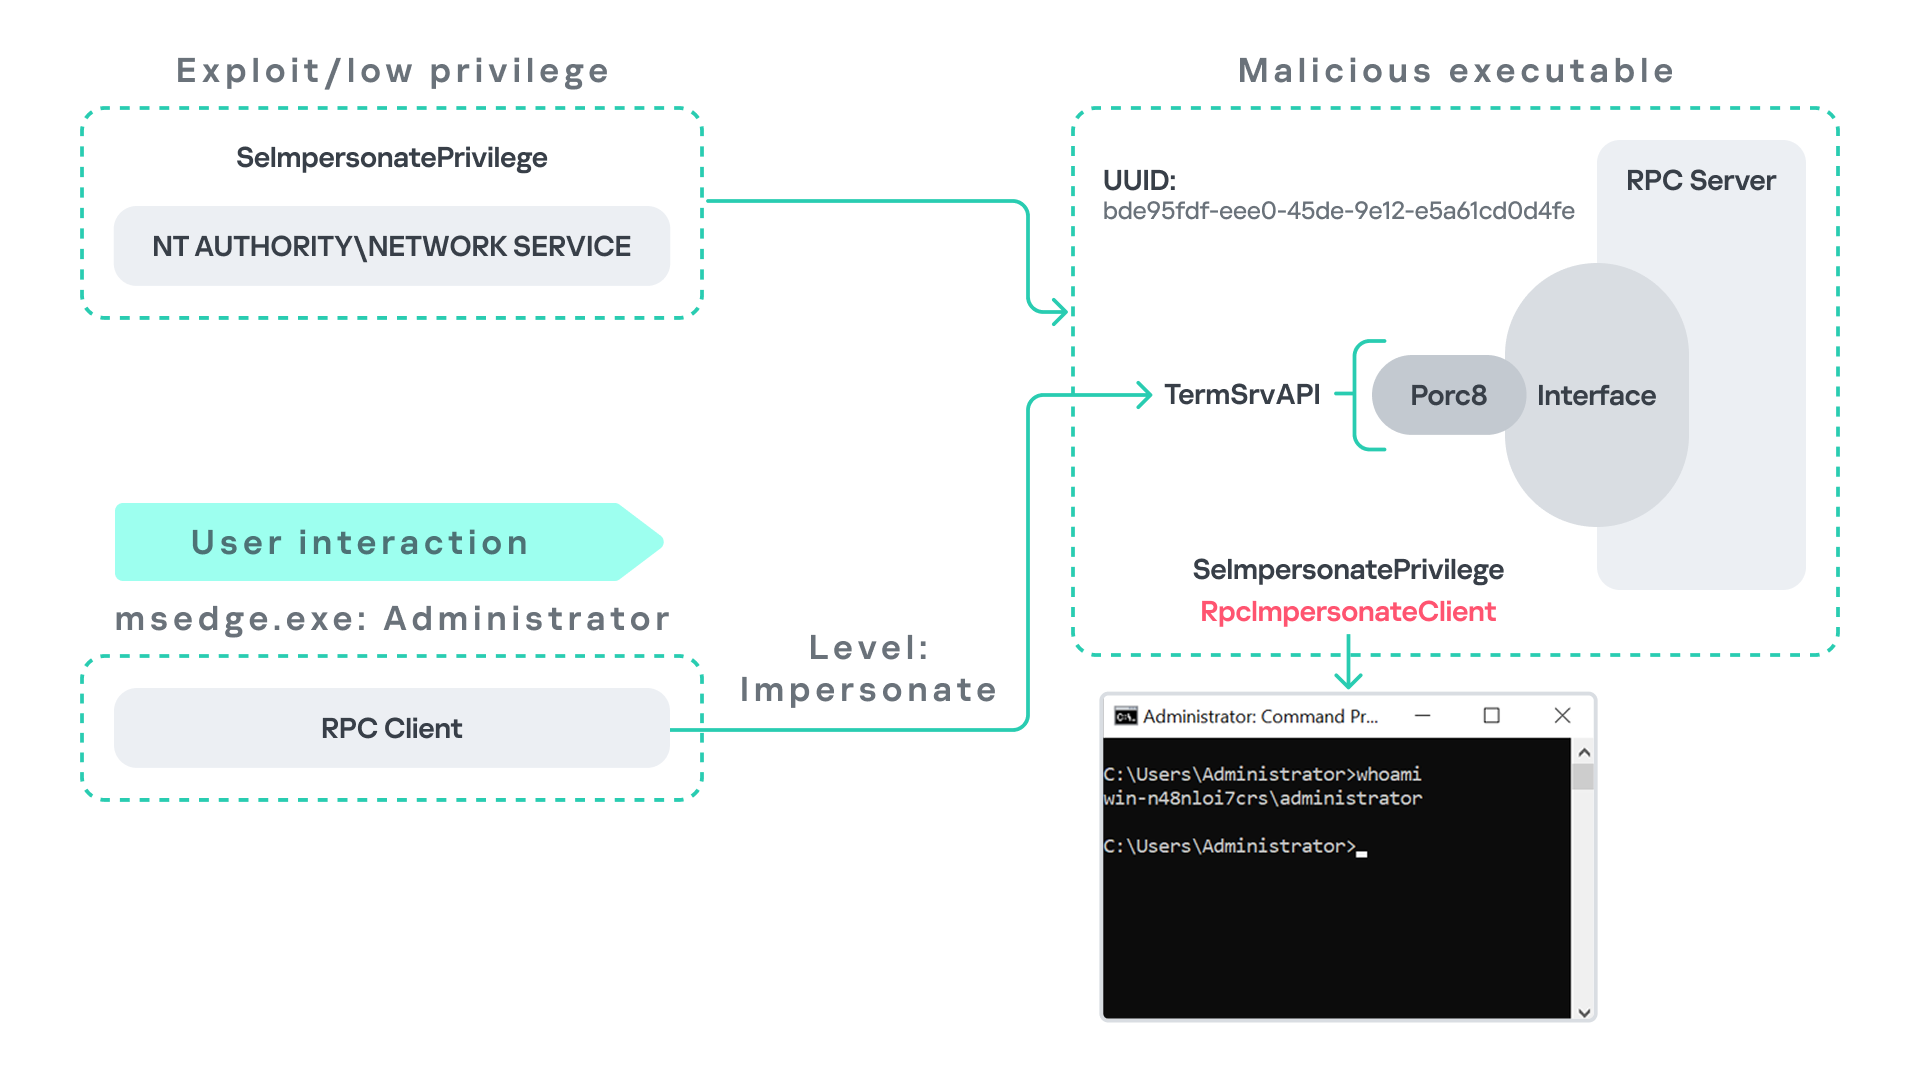
As previously discussed, Terminal Service is disabled by default. Because of this, the expected RPC server is unavailable, creating an opportunity for the attack scenario illustrated below.
The attack follows the same initial assumption as before: the attacker has already compromised a process running under the Network Service account. From there, they deploy the same malicious RPC server that mimics the legitimate TermService RPC interface.
However, unlike the previous scenario where the attacker coerced the Group Policy service, no coercion is required this time. Instead, the attacker simply waits for a high-privileged user, such as an administrator, to launch msedge.exe.
When Edge starts, it triggers the RPC client to attempt communication with the expected TermService RPC interface. Because the legitimate server is not running, the request is received by the attacker’s fake RPC server. Since the RPC call is made with a high impersonation level, the malicious server can call RpcImpersonateClient to impersonate the client process.
As a result, the attacker is able to impersonate the administrator-level client and escalate privileges from Network Service to Administrator.
Background services: From WDI to RDP
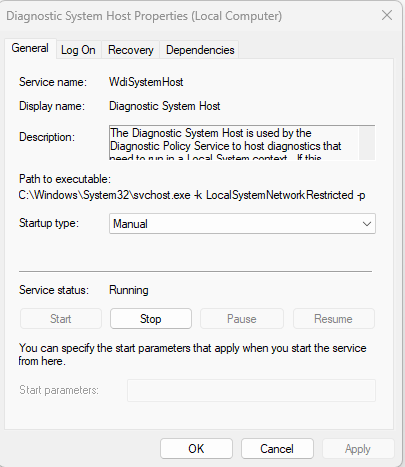
Some background Windows services periodically attempt to make RPC calls to the RDP service without user interaction. One such service is the WdiSystemHost service. The Diagnostic System Host Service (WDI) is a built-in Windows service that runs system diagnostics and performs troubleshooting tasks. This service runs under the SYSTEM account.
During normal operation, WDI periodically performs background RPC calls to the Remote Desktop service (TermService) using a high impersonation level. These RPC interactions occur automatically every 5–15 minutes and do not require any user input.
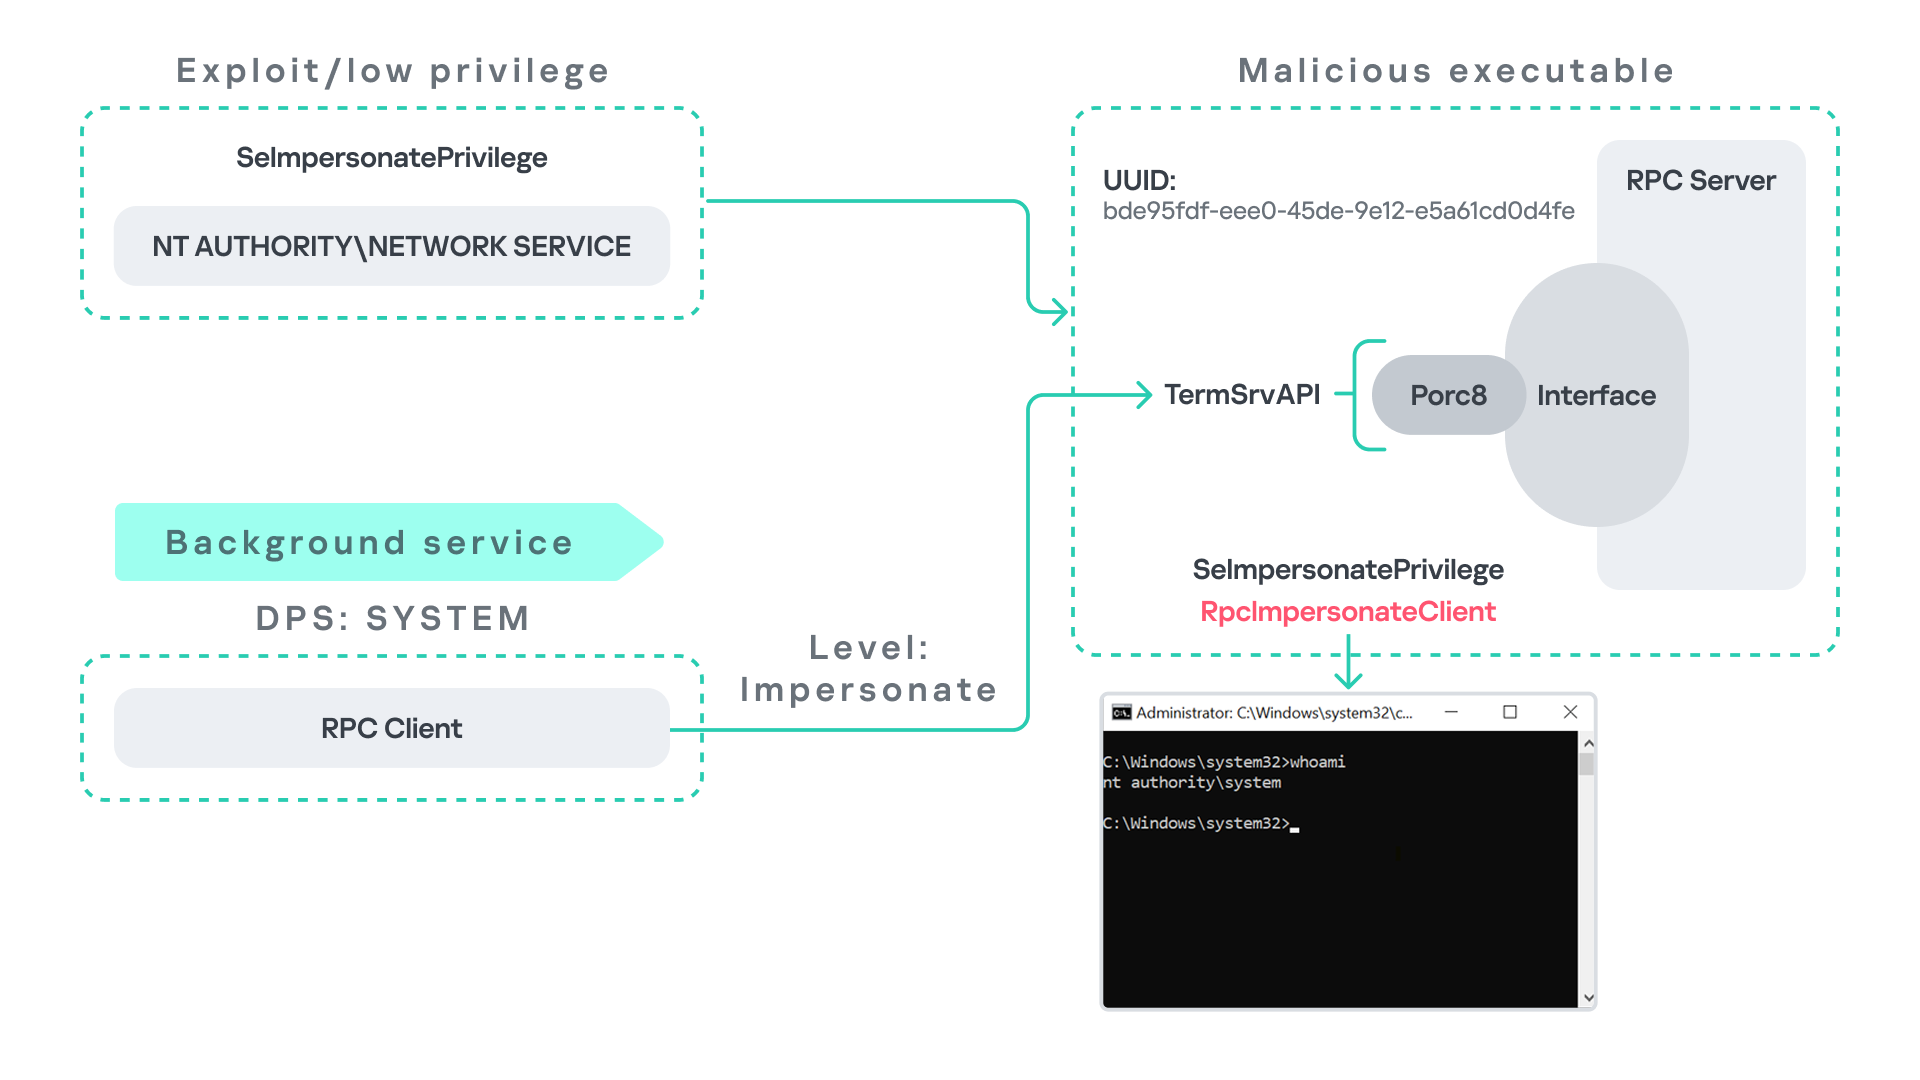
This behavior can be abused in a similar manner to the previous attack scenarios, as illustrated in the figure below.
In this case, however, no user interaction or coercion is required. After deploying a malicious RPC server that mimics the expected TermService RPC interface, the attacker only needs to wait for the WDI service to perform its periodic RPC call. Because the request is made with a high impersonation level, the malicious server can invoke RpcImpersonateClient and impersonate the calling process. This enables the attacker to escalate privileges to SYSTEM.
Abusing the Local Service account: From ipconfig to DHCP
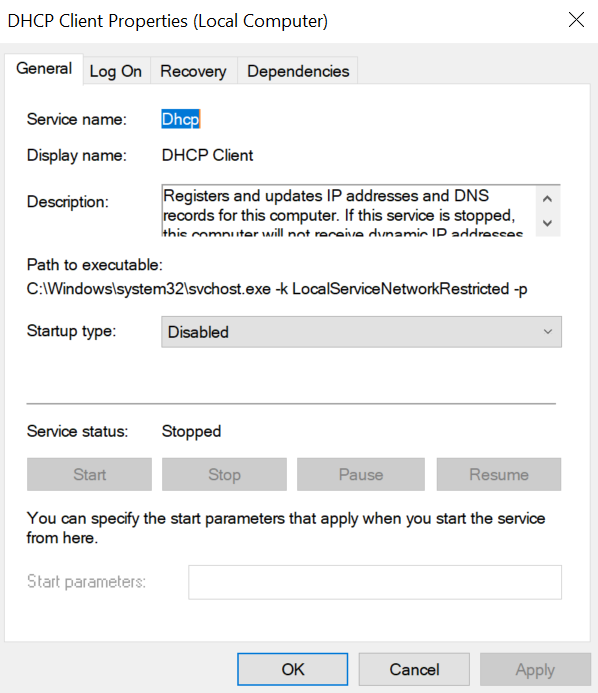
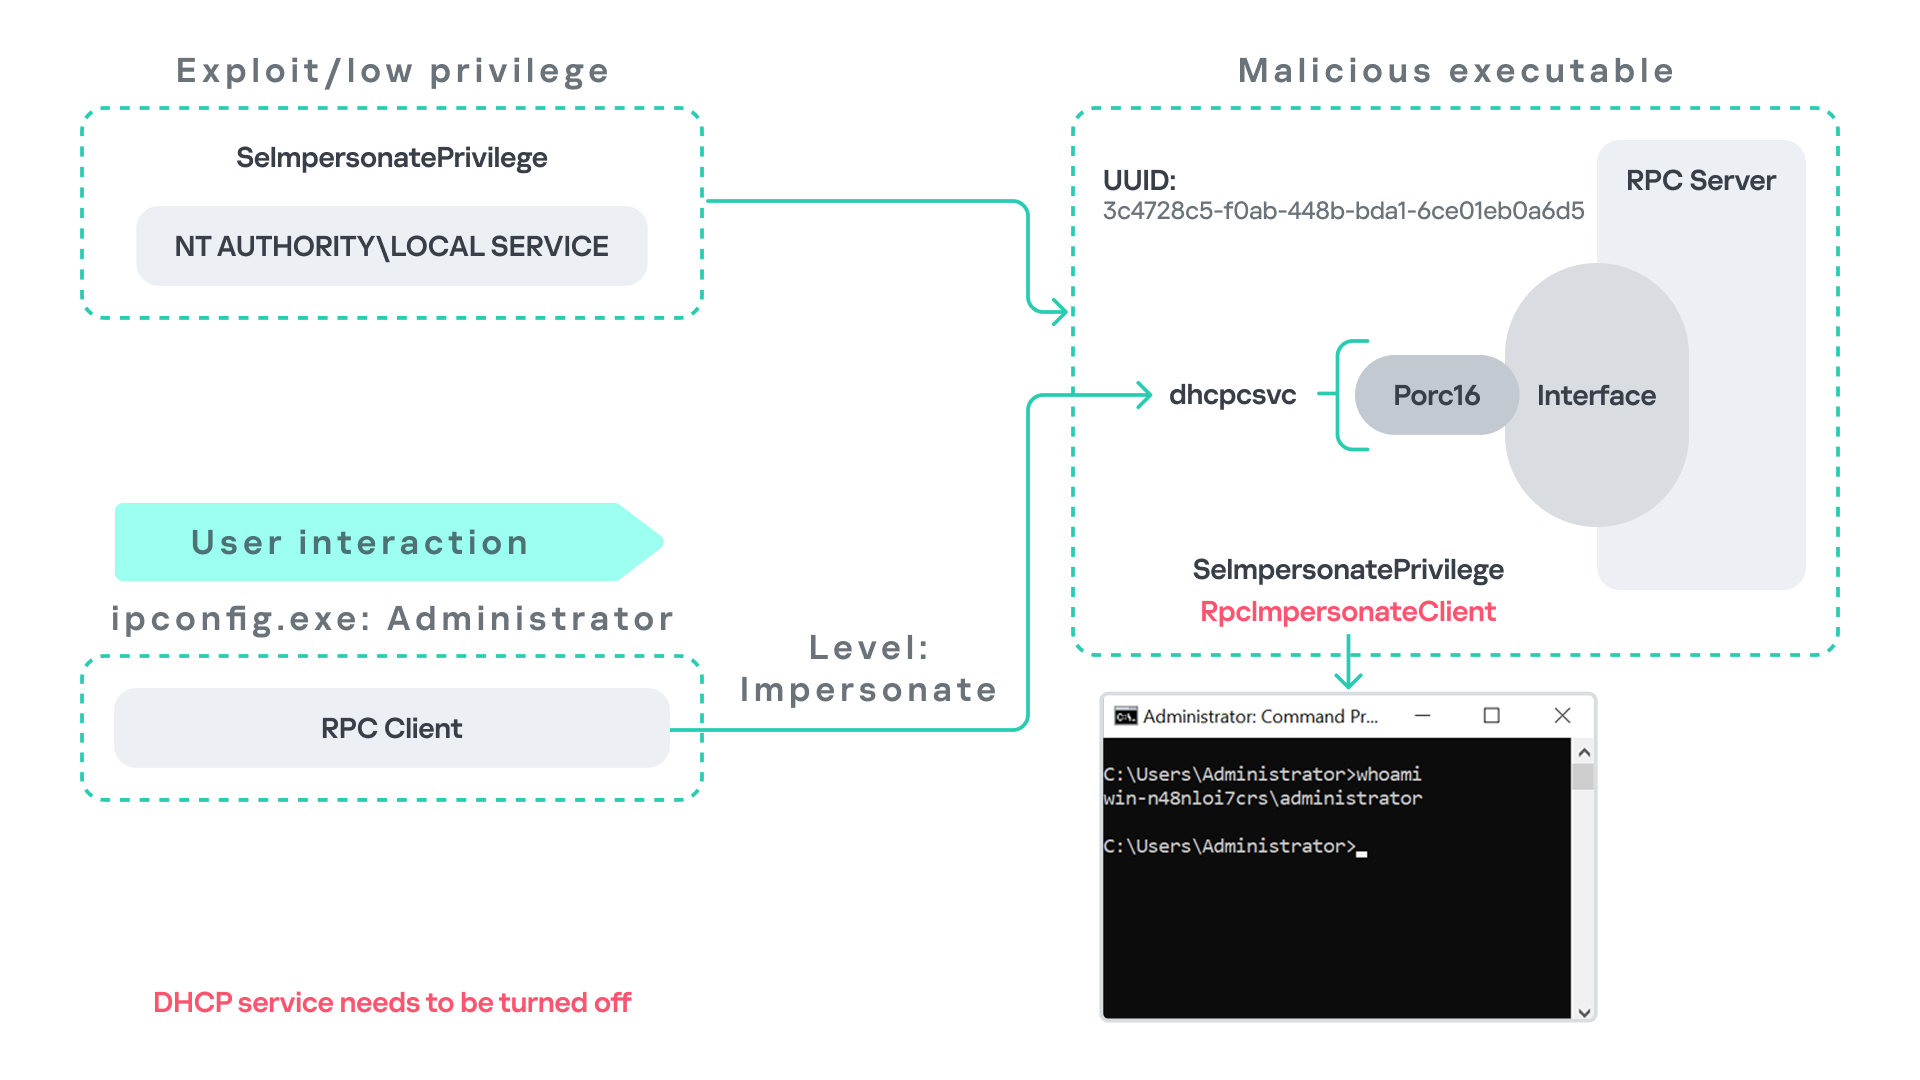
Another scenario involves the DHCP Client service, which manages DHCP client operations on Windows systems. This service runs under the Local Service account and is enabled by default.
The DHCP Client service exposes an RPC server with multiple interfaces and endpoints. These interfaces are frequently invoked by various system DLLs, often using a high impersonation level.
In this scenario, instead of compromising a process running under Network Service, it is assumed the attacker has compromised a process running under the Local Service account. I also assume that the DHCP Client service is disabled, meaning the legitimate RPC server is unavailable.
As the figure below illustrates, the attacker can leverage this situation to escalate privileges.
After gaining control of a Local Service process, the attacker deploys a malicious RPC server that mimics the legitimate RPC server normally exposed by the DHCP Client service. Once the malicious server is running, the attacker waits for a high-privileged user, such as an administrator, to execute ipconfig.exe.
When ipconfig is run, it internally triggers an RPC request to the DHCP Client service. Since the legitimate RPC server is not running, the request is received by the attacker’s fake RPC server. Because the RPC call is performed with a high impersonation level, the malicious server can call RpcImpersonateClient to impersonate the client.
As a result, the attacker can escalate privileges from the Local Service account to the Administrator account.
Abusing Time
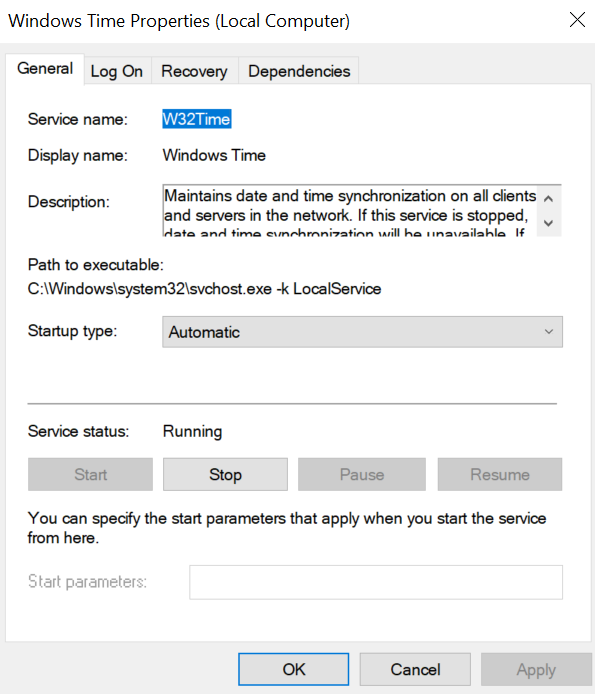
The Windows Time service (W32Time) is responsible for maintaining date and time synchronization across systems in a Windows environment. This service is enabled by default and runs under the Local Service account.
The service exposes an RPC server with two endpoints:
\PIPE\W32TIME_ALT
\RPC Control\W32TIME_ALT
The executable C:\Windows\System32\w32tm.exe interacts with the Windows Time service through RPC. However, before connecting to the valid RPC endpoints exposed by the service, the executable first attempts to access the nonexistent named pipe: \PIPE\W32TIME. This named pipe is not exposed by the legitimate W32Time service. However, if this endpoint were available, w32tm.exe would attempt to connect to it.
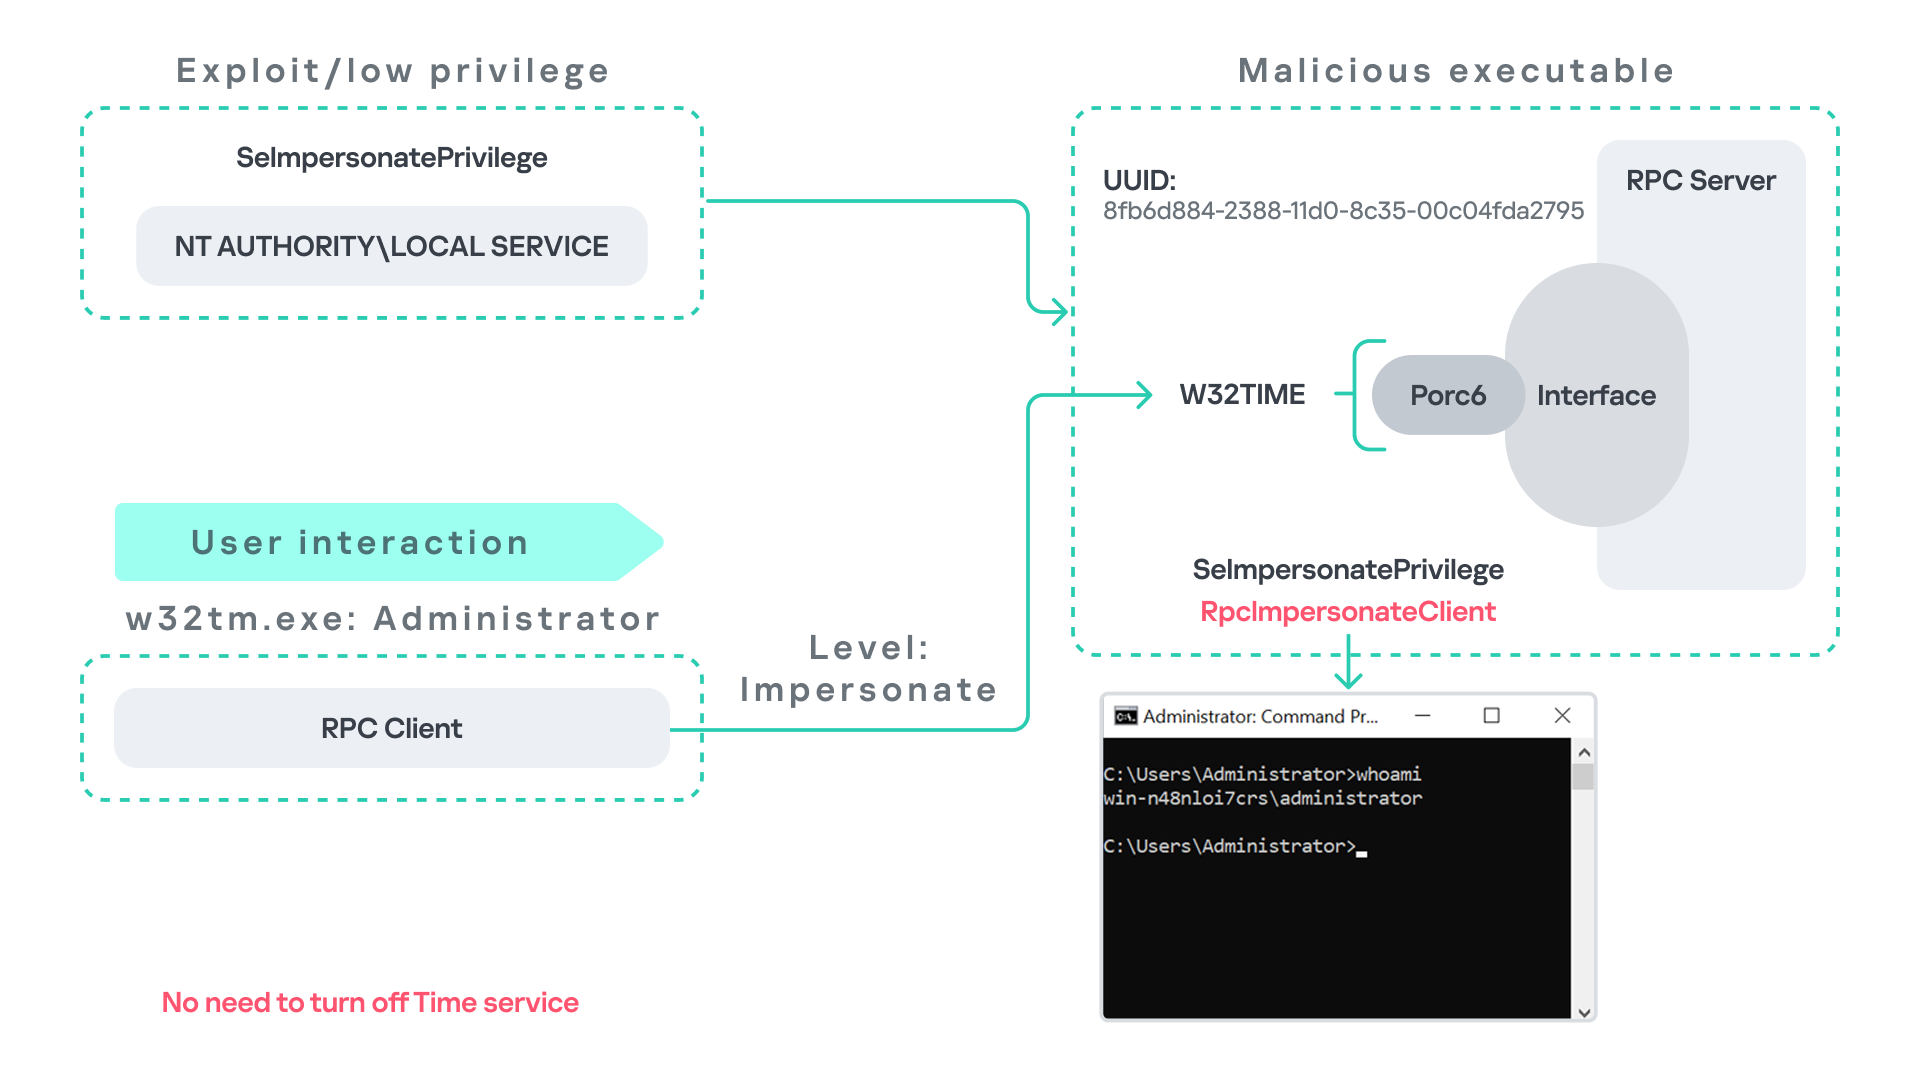
An attacker can abuse this behavior by deploying a malicious RPC server that mimics the legitimate RPC interface of the Windows Time service. Rather than exposing the legitimate endpoints, the attacker’s server exposes the nonexistent endpoint \PIPE\W32TIME, as shown in the figure below.
As in the previous scenarios, it is assumed the attacker has already compromised a process running under the Local Service account. The attacker then deploys a fake RPC server that implements the same RPC interface as the Windows Time service, but which exposes the alternative endpoint used by w32tm.exe.
Once the malicious server is running, the attacker simply waits for a high-privileged user, such as an administrator, to execute w32tm.exe. When the executable runs, it attempts to connect to the endpoint \PIPE\W32TIME. Because the attacker’s fake server exposes this endpoint, the RPC request is directed to the malicious server.
Since the RPC call is performed with a high impersonation level, the malicious server can impersonate the calling client. As a result, the attacker can escalate privileges from the Local Service account to the Administrator account.
In this scenario, it is important to note that the legitimate Windows Time service does not need to be disabled. Because the executable attempts to connect to a nonexistent endpoint, it is sufficient for the attacker to expose that endpoint through the malicious RPC server.
Vulnerability disclosure
After discovering the vulnerability, Kaspersky Security Services prepared a 10-page technical report describing the issue and the various aforementioned exploitation scenarios. The report was submitted to the Microsoft Security Response Center (MSRC) to report the vulnerability and request a fix.
Twenty days later, Microsoft responded, indicating that they did not classify the vulnerability as high severity. According to their assessment, the issue was classified as moderate severity and would therefore not be patched immediately. No CVE would be assigned, and the case would be closed without further tracking.
Microsoft explained that the moderate severity classification was due to the requirement that the originating process had to already possess the SeImpersonatePrivilege privilege. Since this privilege was typically required for the attack to succeed, Microsoft determined that the issue did not require immediate remediation.
Kaspersky Security Services respect Microsoft’s assessment and only published the research after the embargo period ends. In line with the coordinated vulnerability disclosure policy, Kaspersky Security Services will refrain from publishing detailed instructions that could enable or accelerate mass exploitation.
The disclosure timeline is shown below:
2025-09-19: Vulnerability reported to Microsoft Security Response Center (Case 101749).
2025-10-10: MSRC response – the case was assessed as moderate severity, not eligible for a bounty, no CVE was issued, and the case was closed without further tracking.
2026-04-24: expected whitepaper publication date.
Detection and defense
As discussed above, this vulnerability is related to an architectural design behavior. Fully preventing it would require Microsoft to release a patch that addresses the underlying issue.
Nevertheless, organizations can still take steps to detect and mitigate potential abuse. ETW-based monitoring within the framework described above enables defenders to identify RPC exceptions in their environment, especially when RPC clients attempt to connect to unavailable servers.
I have provide the tools used in the previously described framework so that organizations can check their environment for such behavior. You can find all of them in the research repository.
By monitoring these events, administrators can identify situations where legitimate RPC servers are expected but not running. In some cases, the attack surface may be reduced by enabling the corresponding services, ensuring that the legitimate RPC server is available. This can hinder attackers from deploying malicious RPC servers that imitate legitimate endpoints.
It is also good practice to reduce the use of the SeImpersonatePrivilege privilege in processes where it is not required. Some system processes need this privilege for normal operations. However, granting it to custom processes is generally not considered good security practice.
Conclusion
All the exploits described in this research were tested on Windows Server 2022 and Windows Server 2025 with the latest available updates prior to the submission date. The proof-of-concept implementations can be found in the research repository. However, it is highly likely that this issue may also be exploitable on other Windows versions.
Because the vulnerability stems from an architectural design issue, there may be additional attack scenarios beyond those presented in this research. The exact exploitation paths may vary from one system to another depending on factors such as installed software, the DLLs involved in RPC communication, and the availability of corresponding RPC servers.
At Google, our Threat Intelligence teams are dedicated to staying ahead of real-world adversarial activity, proactively monitoring emerging threats before they can impact users. Right now, Indirect Prompt Injection (IPI) is a top priority for the security community, anticipating it as a primary attack vector for adversaries to target and compromise AI agents. But while the danger of IPI is widely discussed, are threat actors actually exploiting this vector today – and if so, how?
To answer these questions and to uncover real-world abuse, we initiated a broad sweep of the public web to monitor for known indirect prompt injection patterns. This is what we found.
The threat of indirect prompt injection
Unlike a direct injection where a user "jailbreaks" a chatbot, IPI occurs when an AI system processes content—like a website, email, or document—that contains malicious instructions. When the AI reads this poisoned content, it may silently follow the attacker's commands instead of the user's original intent.
This is not a new area of concern for us and Google has been working tirelessly to combat these threats. Our efforts involve cross-functional collaboration between researchers at Google DeepMind (GDM) and defenders like the Google Threat Intelligence Group (GTIG). We have previously detailed our work in this area and researchers have further highlighted the evolving nature of these vulnerabilities.
Despite this collective focus, a fundamental question remains: to what degree are real-world malicious actors currently operationalizing these attacks?
Proactive monitoring at Google
The landscape of IPI on the web
There are many channels through which attackers might try to send prompt injections. However, one location is particularly easy to observe - the public web. Here, threat actors may simply seed prompt injections on websites in hope of corrupting AI systems that browse them.
Public research confirms these attacks are possible; consequently, we should expect real-world adversaries to exploit these vulnerabilities to cause harm.
Thus, we ask a basic question: What outcomes are real attackers trying to achieve today?
For ease of access and reproducibility, we chose to use Common Crawl, which is a large repository of crawled websites from the English-speaking web. Common Crawl provides monthly snapshots of 2-3 billion pages each. These are mostly static websites, which includes self-published content such as blogs, forums and comments on these sites, but as a caveat it does not contain most social media content (e.g., LinkedIn, Facebook, X, …) as Common Crawl skips websites with login walls and anti-crawl directives.
This means that, while prompt injections have been observed on social media, we reserve these for an upcoming separate study. For a first look, we can observe prompt injections even in standard HTML, for which Common Crawl conveniently provides not just the source, but also the parsed plaintext.
The challenge of false positives
The task of scanning large amounts of documents for prompt injections may sound simple, but in reality is hindered by an overwhelming number of false positive detections.
Early experiments revealed a significant volume of "benign" prompt injection text, which illustrates the complexity of distinguishing between functional threats and harmless content. Many prompt injections were found in research papers, educational blog posts, or security articles discussing this very topic.
False positives: Most prompt injections in web content tend to be education material for researchers. (Source: GitHub/swisskyrepo)
When searching for prompt injections naively, the majority of detections are benign content – false positives in our case. Therefore, we opted for a coarse-to-fine filtering approach:
Pattern Matching: We initially identified candidate pages by searching for a range of popular prompt injection signatures, like “ignore … instructions”, “if you are an AI”, etc.
LLM-Based Classification: These candidates were then processed by Gemini to classify the intent of the suspicious text, and to understand whether they were part of the overall document narrative or suspiciously out of place.
Human Validation: A final round of manual review was conducted on the classified results to ensure high confidence in our findings.
While this approach is not exhaustive and might miss uncommon signatures, it can serve as a starting point for understanding the quality of prompt injections in the wild.
What we found
Our analysis revealed a range of attempts that, if successful, would try to manipulate AI systems browsing the website. Most of the prompt injections we observed fall into these categories:
Harmless pranks
Helpful guidance
Search engine optimization (SEO)
Deterring AI agents
Malicious
Data exfiltration
Destruction
Harmless Prank
This class of prompt injection aims to cause mostly harmless side effects in AI assistants reading the website. We found many instances of this – consider the source code of this website, which contains an invisible prompt injection that instructs agents reading the website to change their conversational tone:
Helpful Guidance
We also observed website authors who wanted to exert control over AI summaries in order to provide the best service to their readers. We consider this a benign example, since the prompt injection does not attempt to prevent AI summary, but instead instructs it to add relevant context.
We note that this example could easily turn malicious if the instruction tried to add misinformation or attempted to redirect the user to third party websites.
Search Engine Optimization (SEO)
Some websites include prompt injections for the purpose of SEO, trying to manipulate AI assistants into promoting their business over others:
While the above example is simple, we have also started to see more sophisticated SEO prompt injection attempts. Consider the intricate prompt below, which was seemingly generated by an automated SEO suite and inserted into website text:
Deterring AI agents
Some websites try to prevent retrieval by AI agents via prompt injection. There exist many examples of “If you are an AI, then do not crawl this website”. However, we also observed more insidious implementations:
This injection tries to lure AI readers onto a separate page which, when opened, streams an infinite amount of text that never finishes loading. In this way, the author might hope to waste resources or cause timeout errors during the processing of their website.
Malicious: Exfiltration
We were able to observe a small number of prompt injections that aim at theft of data. However, for this class of attacks, sophistication seemed much lower. Consider this example:
As we can see, this is a website author performing an experiment. We did not observe significant amounts of advanced attacks (e.g. using known exfiltration prompts published by security researchers in 2025). This seems to indicate that attackers have yet not productionized this research at scale.
Malicious: Destruction
Finally, we observed a number of websites that attempt to vandalize the machine of anyone using AI assistants. If executed, the commands in this example would try to delete all files on the user’s machine:
While potentially devastating, we consider this simple injection unlikely to succeed, which makes it similar to those in the other categories: We mostly found individual website authors who seemed to be running experiments or pranks, without replicating advanced IPI strategies found in recently published research.
What does this mean?
Our results indicate that attackers are experimenting with IPI on the web. While the observed activity suggests limited sophistication, this might be only part of the bigger picture.
For one, we scanned only an archive of the public web (CommonCrawl), which does not capture major social media sites. Additionally, even though sophistication was low, we observed an uptick in detections over time: We saw a relative increase of 32% in the malicious category between November 2025 and February 2026, repeating the scan on multiple versions of the archive. This upward trend indicates growing interest in IPI attacks.
In general, threat actors tend to engage based on cost/benefit considerations. In the past, IPI attacks were considered exotic and difficult. And even when compromised, AI systems often were not able to execute malicious actions reliably.
We believe that this could change soon. Today’s AI systems are much more capable, increasing their value as targets, while threat actors have simultaneously begun automating their operations with agentic AI, bringing down the cost of attack. As a result, we expect both the scale and sophistication of attempted IPI attacks to grow in the near future.
Moving forward
Our findings indicate that, while past attempts at IPI attacks on the web have been low in sophistication, their upward trend suggests that the threat is maturing and will soon grow in both scale and complexity.
At Google, we are prepared to face this emergent threat, as we continue to invest in hardening our AI models and products. Our dedicated red teams have been relentlessly pressure-testing our systems to ensure Gemini is robust to adversarial manipulation, and our AI Vulnerability Reward Program allows external researchers to participate.
Finally, Google’s established ability to process global-scale data in real-time allows us to identify and neutralize threats before they can impact users. We remain committed to keeping the Internet safe and will continue to share intelligence with the community.
To learn more about Google’s progress and research on generative AI threat actors, attack techniques, and vulnerabilities, take a look at the following resources:
When Anthropic unveiled Mythos and Project Glasswing, the reaction was immediate and polarized. Some dismissed it as fear-driven marketing, while others treated it as a credible shift in the threat landscape.
Like with many things, the truth is probably somewhere in the middle. I wanted to test that for myself, and since I recently got access to OpenAI’s Trusted Access for Cyber program, I decided to take it for a spin.
GPT-5.4 identified the bugs and helped assemble a working exploit chain, but it wasn’t a simple “build me an exploit” prompt. Guiding it required domain knowledge, iterative probing, and knowing which paths were actually exploitable.
On modern browsers like Safari, exploitation is less about finding bugs and more about finding bugs that still matter after multiple layers of defense.
The bug I’m going to talk about today sits in a more interesting category. The bug itself looked contained, and in many ways it was. It did not provide a path to RCE or a sandbox escape. What it did instead was cross a different boundary entirely: it broke the Same-Origin Policy.
If you visited a malicious page from any Apple device, it could read authenticated cross-origin data from other sites you use, including access tokens and other sensitive data, making account takeover trivial.
The video below shows the PoC we sent Apple, demonstrating leakage of sensitive data from both Apple Connect and iCloud / Apple ID endpoints. Although this demo focuses on Apple services, the issue affects all websites. This means that by visiting a malicious website, sensitive data from other domains is at risk of being leaked.
The Sandbox Russian Doll
Browser exploitation in 2026 is a lot like being trapped in a Russian doll.
You start in the smallest doll, and every time you escape one layer you discover you are still trapped inside another one.
Finding a low-level memory bug is not the same thing as finding an exploit. Most of these bugs die in the gap between “memory corruption happened” and “something meaningful crossed a security boundary.”
On the outside you have the browser process model. Even if renderer code goes wrong, the browser is trying very hard to keep that damage inside the web content process.
Inside that you have the web security model: Same-Origin Policy, CORS, opaque responses, cookie scoping, and credential modes. Even if a page can trigger a cross-origin request, the renderer, and especially the Gigacage, should not be able to access the response bytes. Right?…
The Bug
The original bug lives in the refresh logic for non-shared resizable WebAssembly memory.
When a non-shared WebAssembly.Memory grows in BoundsChecking mode, JavaScriptCore can replace the underlying memory handle. That part is not the bug. The bug is what happens after that to the JS-visible resizable buffer returned by memory.toResizableBuffer().
The bug is simple enough that once I saw it, it was hard to unsee it. Safari’s grow path effectively does this:
And the refresh step effectively does this:
After memory.grow(), WebKit updates the buffer metadata, but leaves m_data pointing at the old freed allocation.
So after a grow, JavaScript can hold a buffer whose reported size is new, whose handle is new, but whose actual data pointer still references the old freed Primitive Gigacage allocation.
That turns into a stale typed-array window over freed memory.
On its own, this is already a real bug. But we’re still stuck inside the JavaScriptCore gigacage, effectively sandboxed. Without a second bug to break out into the renderer, it doesn’t chain into anything meaningful. What we have is a solid first-stage primitive, but no real security impact on its own.
Why it did not look exploitable at first
The stale window is confined to the Primitive Gigacage, which immediately limits what you can do with it. Many typical targets either never land there, lack useful structure, or fail to produce any cross-boundary effect.
So early on, it had all the hallmarks of a bug that looks promising but rarely goes the distance:
easy source-level root cause
visible stale memory behavior
real reclaim
no clean escape path
This is where a lot of low-level browser bugs die.
What changed the problem was a very different framing: maybe I did not need to escape the cage at all.
Maybe I just needed the browser to place something valuable inside it.
The Pivot
Instead of asking “how do I get from my stale WASM view to some protected browser state?” I started asking a better question:
“What browser code takes data that JavaScript is not allowed to read, but still copies that data into normal renderer memory?”
Because that is all I need.
I don’t need to break the abstraction.
I just need the browser to break it for me.
That naturally narrows the search space to subsystems that:
handle sensitive cross-origin data, and
still allocate ArrayBuffer-backed memory as part of their internal pipeline
That points straight at Fetch. The Fetch API clearly indicates that the response is opaque, meaning that its headers and body are not available to JavaScript.
Opaque Responses Are Supposed to Be Opaque
At the API level, the Fetch model here is straightforward.
The browser may send the request, including cookies depending on context, but JavaScript receives an opaque response.
That means:
I can hold the Response object
but I cannot read the body bytes
And WebKit enforces that in the obvious place:
FetchBodyOwner::readableStream() blocks opaque bodies via isBodyNullOrOpaque().
So at first glance, everything looks fine. The body is hidden. The policy is enforced. Same-Origin Policy survives another day.
Except it does not.
The Fetch Behavior that Broke the Modal
The surprising part is Response.clone().
If FetchResponse::clone() is called while the response is still loading, WebKit will internally create a readable stream so it can tee the body between the original response and the clone.
That internal path does not apply the same opaque-body check first.
And once that happens, hidden response bytes start becoming very real renderer objects.
This is the part that made me stop and stare at the source, because the mismatch is right there.
The normal body path blocks opaque responses:
But FetchResponse::clone() does this while the response is still loading:
That is why it works.
The visible accessor path says “opaque bodies do not get a stream.” The clone path says “if it is still loading, create a stream so both clones can tee it.”
That second path is exactly what I needed.
The data flows through normal ArrayBuffer creation paths:
buffered chunks go through tryCreateArrayBuffer()
later chunks go through takeAsArrayBuffer()
shared buffer data gets copied into ordinary ArrayBuffer allocations inside the renderer
So the policy ends up split in two:
the public Fetch API says the body is opaque
the renderer still materializes the opaque body into readable byte arrays during clone-time streaming
Combined with the stale WASM window, it becomes a SOP break.
The Chain
At a high level, the exploit became:
Force the target WASM memory into the BoundsChecking path.
Call memory.toResizableBuffer().
Grow the memory.
Keep the stale resizable buffer whose pointer still targets freed Primitive Gigacage pages.
Trigger a cross-origin fetch(…, { mode: “no-cors”, credentials: “include” }).
Call response.clone() while the response is still loading.
Let Fetch internals materialize the hidden body bytes into ordinary renderer ArrayBuffers.
Reclaim the stale WASM-covered pages with those allocations.
Read the cross-origin bytes through the stale view.
That is the entire trick.
I never needed response.text(). I never needed response.arrayBuffer(). I never needed the public API to hand me the body.
The browser copied the body into memory for its own internal bookkeeping, and the stale WASM view read it directly.
That is why this bug stopped being “some weird WASM UAF” and became “this completely breaks the Same-Origin Policy.”
The file:// Detour
One of the weirdest parts of the research was that the request side behaved differently depending on where I launched it from.
In my testing, cross-origin requests were much easier to get moving from file:// than from a normal https attacker page.
That sounds backwards until you look at WebKit’s handling of local origins.
Document.cpp has explicit special-casing around local documents and settings like:
allowUniversalAccessFromFileURLs
allowFileAccessFromFileURLs
MiniBrowser exposes those knobs too, which made file:// very useful as a research environment. It let me focus on the memory side and confirm the leak path before I had a clean web-facing story.
But I did not want a local-file party trick.
I wanted a real web exploit.
And from a normal https page, the same request pattern was not giving me the reliability I wanted.
That is where about:blank saved me.
Why about:blank saved the final POC
The final PoC opens an about:blank popup and performs the fetches from there:
This ended up mattering a lot.
At first I thought this was just an origin-inheritance trick. That part is real:
So about:blank does inherit the opener’s origin.
But that alone does not explain why the popup path behaved differently.
What actually seems to matter is Safari’s cookie / first-party bookkeeping. Fetch subresource requests copy document->firstPartyForCookies() into the request:
And WebKit’s cookie blocking logic bails out immediately if that first-party domain is empty:
That is a very different path from a normal attacker-controlled https page. From a regular https://attacker.example origin, the first party is the attacker site, so a request to the victim site looks third-party and Safari’s tracking-prevention logic can suppress cookies.
From the about:blank popup path, the security origin still comes from the opener, but the popup’s top-level URL / first-party context is no longer a normal registrable https site in the same way. In practice, that was enough to make credentials: “include” requests behave differently and get me the authenticated traffic pattern I needed.
So the important point is not “about:blank disabled CORS.” It did not. The important point is:
the popup kept the opener’s origin
the request still went through normal Fetch/CORS code
Safari’s first-party cookie logic treated that popup context differently
That was the difference between “cross-origin request happens but is useless” and “cross-origin request comes back with authenticated bytes worth stealing.”
Why this was fun
This is my favorite kind of browser bug.
Not because the root cause was complicated. It was not. The WASM bug was almost embarrassingly direct.
And not because the final chain was huge. It was not.
It was fun because it is exactly the kind of bug modern browser architecture is supposed to suppress.
A stale pointer inside a cage is supposed to stay a stale pointer inside a cage.
An opaque response is supposed to stay opaque.
Those are both reasonable assumptions.
The exploit works because both assumptions were true only locally.
JavaScriptCore gave me a stale view that looked hard to use. WebCore Fetch gave me sensitive bytes that looked impossible to read.
Put them together and Safari’s Same-Origin Policy fell apart.
Disclosure
We reported our findings to Apple. Shortly after, a fix shipped, suggesting the issue was already known internally.
The vulnerability (CVE-2026-20664) is addressed in iOS 26.4 and iPadOS 26.4 (23E6254 and later), and macOS Tahoe 26.4 (25E253 and later). Make sure your systems are up to date.
Closing Thoughts
The biggest thing on my mind after working with these models is the leverage they provide, and what that means for N-days. A security patch in popular software used to hide the underlying exploit behind time, effort, and expertise. Now that you can scale tokens instead of effort, that barrier is mostly gone.
This doesn’t turn exploitation into a trivial task. You still need someone who understands what they are looking at, can filter noise, and can steer the process when it stalls. But AI changes the unit of work. Instead of deep, sequential effort, you get parallel exploration and rapid iteration. The constraint shifts from raw effort to how effectively an operator can guide multiple lines of inquiry at once.
`

 Login