❌

Reading view

How APT41 revived the BlackLotus bootkit to attack diplomatic organizations in Central Asia
Introduction

Back in October 2022, Kaspersky GReAT was looking into a peculiar advertisement on a hacking forum. A cybercriminal had been advertising a UEFI bootkit, dubbed BlackLotus, that could bypass Secure Boot, for $5,000. Given the low price for such powerful capabilities, the cybersecurity community initially took this advertisement with a grain of salt. As no BlackLotus samples were found in the wild, no one could at the time verify the claims made in the forum post.
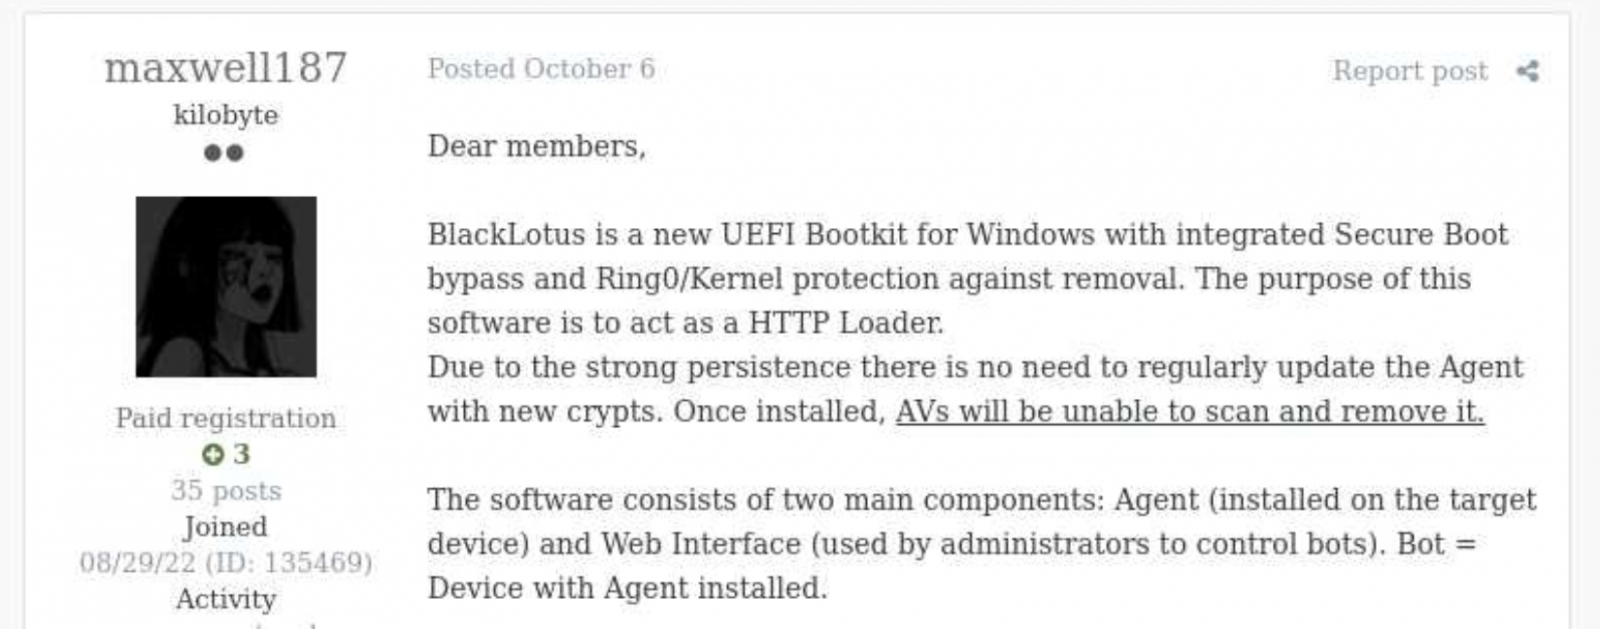
BlackLotus advertisement

BlackLotus advertisement

However, about half a year later, in March 2023, ESET confirmed that the BlackLotus advertisement was genuine. The researchers tracked down samples of this bootkit and confirmed that it can indeed bypass Secure Boot through a vulnerability called Baton Drop (CVE-2022-21894). As this vulnerability was still exploitable in 2023, Microsoft had to release multiple security updates to address it.

Since the release of these updates, the BlackLotus bootkit has gone quiet — no publicly known attacks have used it. Yet in early 2026, we discovered a malware sample similar to BlackLotus that was used in an APT campaign in Central Asia. In this report, we share our findings, including new payloads and possible attribution of this campaign.

The return of the infamous bootkit

In early 2026 we identified a complex APT attack targeting diplomatic agencies in Central Asian countries — namely Tajikistan, Uzbekistan, and Turkmenistan. This attack involved a UEFI bootkit that we dubbed BlackX. Having examined it, we found it to be similar to BlackLotus.

Attackers have been deploying BlackX after compromising the victim machine networks and obtaining administrator privileges. To install the bootkit, we observed them dropping the following files:

  • inst.exe, an installer executable
  • PVMDIJGKAX2, an RC4-encrypted extensionless file containing files and strings required for the installation

The installer was launched with the command line C:\ProgramData\Intel\inst.exe PVMDIJGKAX2 Q46F6MDLI3RX2KV1. The last argument here is the RC4 key used for decryption.

Curiously, the file inst.exe does not contain any malicious strings or embedded blobs. All the files needed to install the malicious payload are inside PVMDIJGKAX2, which makes it harder for incident responders to retrieve the bootkit components.

The installer package drops a set of files to both system and UEFI partitions, designed to exploit the Baton Drop vulnerability. We noted that the implementation of the exploit is remarkably similar to the one used in the BlackLotus malware. As with BlackLotus, the goal of the exploit is to install custom Machine Owner Keys (MOK), which allows loading arbitrary EFI files on the target machines to manipulate Secure Boot.

While the vulnerability exploitation chain was implemented very similarly to BlackLotus, we spotted differences between the exploits in BlackLotus and BlackX. That said, the source code of the BlackLotus bootkit has never been published online. This could mean that the attackers behind BlackX either reverse-engineered the BlackLotus bootkit or purchased its source code from cybercriminals. Either way, this is an interesting observation, as we rarely see APT actors borrow ideas or code from cybercrime actors.

Payload launched by the bootkit

The UEFI payload delivered during the Baton Drop exploitation has a classic bootkit goal — to inject a malicious driver into the Windows kernel. This driver differs from the one deployed by BlackLotus and is signed with a certificate belonging to an organization named 温江区明宇网络技术服务工作室 (English: Wenjiang District Mingyu Network Technology Service Studio). At the time of writing, this certificate (serial number: 0bcdf5e0da32d68900b8b7638459d072) has been revoked by its issuer.

The driver aims to tamper with security solutions installed on the machine. For example, it disables process, thread, and registry callbacks related to security solutions. It also tampers with ETW providers so that security solutions cannot access their output. Curiously, some of the tampering procedures are designed to run only if Kaspersky or Avast solutions are installed on the infected machine. However, during dynamic analysis of this driver, we found that these procedures are useless — they fail to interfere with Kaspersky products in any way.

The driver also protects the bootkit’s files from tampering. It intercepts kernel requests to open these files and returns a handle to calc.exe instead of a malicious file handle.

User-mode second-stage payloads

Apart from tampering with security solutions, the driver also deploys a user-mode payload. We observed two such payloads, used for cyberespionage, in the wild. One of them is a RAT that can load further-stage .NET payloads. This RAT uses cloud storage for C2 server communications — we observed its versions using Google Drive, OneDrive, and Yandex.Disk. Having connected to a cloud storage service, this RAT iterates over files available there and interprets them depending on the file suffix. Below is a list of supported suffixes:

File suffix Description Type
0X01 A .NET file. The task is to parse it and run the method TEST.Class1.RunCMD(argument_array) from the module Input
0X02 Result of the call TEST.Class1.RunCMD(argument_array) Output
0X03 Task to upload a file to the drive Input
0X04 Uploaded file Output
0X05 Task to download a file to an infected machine Input
0X06 File download status Output
SSSR Contains initial system info Output

We also observed another payload delivered through the bootkit, which we dubbed OxiDLLRunner. It is a malicious DLL obfuscated with OLLVM. It is loaded by the legitimate file googleupdate.exe (original filename: jcef_helper.exe, MD5: AF8A983B9ADA07EAE1259BF2953ABD40), which is also delivered by the bootkit. The DLL decrypts the contents of the file v8_context_snapshot.bin, which resides in the same folder, and then jumps to the beginning of the decrypted content. The decrypted data starts with shellcode followed by a PE file, which is a Rust payload designed to communicate with the www[.]archivetj[.]com C2 server. During communication, this payload is supposed to receive DLL files exporting a function named create_plugin, which are then executed in separate threads.

Attribution

Based on the following facts, we have attributed this attack to the APT41 threat actor with medium confidence:

  • In June 2026, ESET published a blog post on attacks by the FishMonger threat actor, which the community assumes to be related to APT41. This post describes a kernel implant with a PDB path starting with C:\Users\xdd\Desktop. While describing the campaign, the post also suggests the possible use of an unspecified UEFI bootkit component, which might exploit CVE‑2023‑24932. We observed the identifier “xdd” used multiple times in the BlackX bootkit payloads, so we assess that BlackX is the UEFI bootkit referenced in the ESET blog post;
  • The payloads deployed by BlackX are loaded using a legitimate executable abused via DLL sideloading, and an encrypted file — this pattern is common among Chinese-speaking threat actors;
  • The OxiDLLRunner file has been obfuscated with OLLVM, an obfuscator commonly used by Chinese-speaking actors.

Why did the target organizations get infected?

During our initial analysis of BlackX, we thought that attackers succeeded in deploying it due to the negligence of the target organizations. Baton Drop, the vulnerability used to deploy BlackX, was disclosed back in 2023 and was patched, so we first thought that the infected machines lacked the relevant updates. However, our investigation proved this wrong — the targeted machines were fully patched.

Instead, we found out that the problem was with the patch itself. As it turned out, the patch for the Baton Drop vulnerability is designed to revoke the “Windows Production PCA 2011” certificate used to sign vulnerable UEFI components. However, this revocation does not happen automatically upon patch installation — the user has to trigger it manually. This is done with the following steps:

  • A registry flag is set inside HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Control\Secureboot;
  • A scheduled task named Secure-Boot-Update is created.

This patch is designed to be applied manually — for instance, applying it automatically could break dual-boot systems relying on the “Windows Production PCA 2011” certificate to load. At the same time, this patch deployment practice creates a problem — as it is extremely unusual for a system administrator to take extra steps after installing an update. Usually, when applying patches, system administrators take no further action unless an installation failure occurs. These instructions for activating the patch are buried deep on the Microsoft website, and we assess that they are quite hard for an average IT administrator to notice.

Curiously, Microsoft’s plan for deploying the Baton Drop patches mentions an “Enforcement Phase” that involves revoking the “Windows Production PCA 2011” certificate automatically, without user interaction. At the time of publishing this post, this stage has not been implemented. On October 19, 2026, this certificate expired, but this does not prevent the vulnerable binaries from loading unless the certificate is blocklisted.

It is likely that the threat actor behind this campaign took into account that few organizations realized the importance of manually activating the Baton Drop patch. As such, we believe they decided to invest time in understanding how BlackLotus works and creating a copycat of this bootkit.

Conclusion

Patch management is important for every organization, as updates from vendors help protect software and hardware against known vulnerabilities. However, sometimes installed patches fail to protect against the flaws they address. The BlackLotus story we described is not the only such example — for instance, in 2025 Microsoft released an update against the ToolShell vulnerability that also had to be applied manually.

However, modern security solutions are designed to account for such cases when installed patches fail to protect against security flaws for one reason or another. For instance, the Exploit Prevention component available in Kaspersky products prevents exploits from running if the patch is not applied, or if it is a zero-day vulnerability with no available patch. It is thus crucial to equip all machines in an organization with security solutions and constantly monitor the alerts they raise.

  •  

How APT41 revived the BlackLotus bootkit to attack diplomatic organizations in Central Asia

Introduction

Back in October 2022, Kaspersky GReAT was looking into a peculiar advertisement on a hacking forum. A cybercriminal had been advertising a UEFI bootkit, dubbed BlackLotus, that could bypass Secure Boot, for $5,000. Given the low price for such powerful capabilities, the cybersecurity community initially took this advertisement with a grain of salt. As no BlackLotus samples were found in the wild, no one could at the time verify the claims made in the forum post.

BlackLotus advertisement

BlackLotus advertisement

However, about half a year later, in March 2023, ESET confirmed that the BlackLotus advertisement was genuine. The researchers tracked down samples of this bootkit and confirmed that it can indeed bypass Secure Boot through a vulnerability called Baton Drop (CVE-2022-21894). As this vulnerability was still exploitable in 2023, Microsoft had to release multiple security updates to address it.

Since the release of these updates, the BlackLotus bootkit has gone quiet — no publicly known attacks have used it. Yet in early 2026, we discovered a malware sample similar to BlackLotus that was used in an APT campaign in Central Asia. In this report, we share our findings, including new payloads and possible attribution of this campaign.

The return of the infamous bootkit

In early 2026 we identified a complex APT attack targeting diplomatic agencies in Central Asian countries — namely Tajikistan, Uzbekistan, and Turkmenistan. This attack involved a UEFI bootkit that we dubbed BlackX. Having examined it, we found it to be similar to BlackLotus.

Attackers have been deploying BlackX after compromising the victim machine networks and obtaining administrator privileges. To install the bootkit, we observed them dropping the following files:

  • inst.exe, an installer executable
  • PVMDIJGKAX2, an RC4-encrypted extensionless file containing files and strings required for the installation

The installer was launched with the command line C:\ProgramData\Intel\inst.exe PVMDIJGKAX2 Q46F6MDLI3RX2KV1. The last argument here is the RC4 key used for decryption.

Curiously, the file inst.exe does not contain any malicious strings or embedded blobs. All the files needed to install the malicious payload are inside PVMDIJGKAX2, which makes it harder for incident responders to retrieve the bootkit components.

The installer package drops a set of files to both system and UEFI partitions, designed to exploit the Baton Drop vulnerability. We noted that the implementation of the exploit is remarkably similar to the one used in the BlackLotus malware. As with BlackLotus, the goal of the exploit is to install custom Machine Owner Keys (MOK), which allows loading arbitrary EFI files on the target machines to manipulate Secure Boot.

While the vulnerability exploitation chain was implemented very similarly to BlackLotus, we spotted differences between the exploits in BlackLotus and BlackX. That said, the source code of the BlackLotus bootkit has never been published online. This could mean that the attackers behind BlackX either reverse-engineered the BlackLotus bootkit or purchased its source code from cybercriminals. Either way, this is an interesting observation, as we rarely see APT actors borrow ideas or code from cybercrime actors.

Payload launched by the bootkit

The UEFI payload delivered during the Baton Drop exploitation has a classic bootkit goal — to inject a malicious driver into the Windows kernel. This driver differs from the one deployed by BlackLotus and is signed with a certificate belonging to an organization named 温江区明宇网络技术服务工作室 (English: Wenjiang District Mingyu Network Technology Service Studio). At the time of writing, this certificate (serial number: 0bcdf5e0da32d68900b8b7638459d072) has been revoked by its issuer.

The driver aims to tamper with security solutions installed on the machine. For example, it disables process, thread, and registry callbacks related to security solutions. It also tampers with ETW providers so that security solutions cannot access their output. Curiously, some of the tampering procedures are designed to run only if Kaspersky or Avast solutions are installed on the infected machine. However, during dynamic analysis of this driver, we found that these procedures are useless — they fail to interfere with Kaspersky products in any way.

The driver also protects the bootkit’s files from tampering. It intercepts kernel requests to open these files and returns a handle to calc.exe instead of a malicious file handle.

User-mode second-stage payloads

Apart from tampering with security solutions, the driver also deploys a user-mode payload. We observed two such payloads, used for cyberespionage, in the wild. One of them is a RAT that can load further-stage .NET payloads. This RAT uses cloud storage for C2 server communications — we observed its versions using Google Drive, OneDrive, and Yandex.Disk. Having connected to a cloud storage service, this RAT iterates over files available there and interprets them depending on the file suffix. Below is a list of supported suffixes:

File suffix Description Type
0X01 A .NET file. The task is to parse it and run the method TEST.Class1.RunCMD(argument_array) from the module Input
0X02 Result of the call TEST.Class1.RunCMD(argument_array) Output
0X03 Task to upload a file to the drive Input
0X04 Uploaded file Output
0X05 Task to download a file to an infected machine Input
0X06 File download status Output
SSSR Contains initial system info Output

We also observed another payload delivered through the bootkit, which we dubbed OxiDLLRunner. It is a malicious DLL obfuscated with OLLVM. It is loaded by the legitimate file googleupdate.exe (original filename: jcef_helper.exe, MD5: AF8A983B9ADA07EAE1259BF2953ABD40), which is also delivered by the bootkit. The DLL decrypts the contents of the file v8_context_snapshot.bin, which resides in the same folder, and then jumps to the beginning of the decrypted content. The decrypted data starts with shellcode followed by a PE file, which is a Rust payload designed to communicate with the www[.]archivetj[.]com C2 server. During communication, this payload is supposed to receive DLL files exporting a function named create_plugin, which are then executed in separate threads.

Attribution

Based on the following facts, we have attributed this attack to the APT41 threat actor with medium confidence:

  • In June 2026, ESET published a blog post on attacks by the FishMonger threat actor, which the community assumes to be related to APT41. This post describes a kernel implant with a PDB path starting with C:\Users\xdd\Desktop. While describing the campaign, the post also suggests the possible use of an unspecified UEFI bootkit component, which might exploit CVE‑2023‑24932. We observed the identifier “xdd” used multiple times in the BlackX bootkit payloads, so we assess that BlackX is the UEFI bootkit referenced in the ESET blog post;
  • The payloads deployed by BlackX are loaded using a legitimate executable abused via DLL sideloading, and an encrypted file — this pattern is common among Chinese-speaking threat actors;
  • The OxiDLLRunner file has been obfuscated with OLLVM, an obfuscator commonly used by Chinese-speaking actors.

Why did the target organizations get infected?

During our initial analysis of BlackX, we thought that attackers succeeded in deploying it due to the negligence of the target organizations. Baton Drop, the vulnerability used to deploy BlackX, was disclosed back in 2023 and was patched, so we first thought that the infected machines lacked the relevant updates. However, our investigation proved this wrong — the targeted machines were fully patched.

Instead, we found out that the problem was with the patch itself. As it turned out, the patch for the Baton Drop vulnerability is designed to revoke the “Windows Production PCA 2011” certificate used to sign vulnerable UEFI components. However, this revocation does not happen automatically upon patch installation — the user has to trigger it manually. This is done with the following steps:

  • A registry flag is set inside HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Control\Secureboot;
  • A scheduled task named Secure-Boot-Update is created.

This patch is designed to be applied manually — for instance, applying it automatically could break dual-boot systems relying on the “Windows Production PCA 2011” certificate to load. At the same time, this patch deployment practice creates a problem — as it is extremely unusual for a system administrator to take extra steps after installing an update. Usually, when applying patches, system administrators take no further action unless an installation failure occurs. These instructions for activating the patch are buried deep on the Microsoft website, and we assess that they are quite hard for an average IT administrator to notice.

Curiously, Microsoft’s plan for deploying the Baton Drop patches mentions an “Enforcement Phase” that involves revoking the “Windows Production PCA 2011” certificate automatically, without user interaction. At the time of publishing this post, this stage has not been implemented. On October 19, 2026, this certificate expired, but this does not prevent the vulnerable binaries from loading unless the certificate is blocklisted.

It is likely that the threat actor behind this campaign took into account that few organizations realized the importance of manually activating the Baton Drop patch. As such, we believe they decided to invest time in understanding how BlackLotus works and creating a copycat of this bootkit.

Conclusion

Patch management is important for every organization, as updates from vendors help protect software and hardware against known vulnerabilities. However, sometimes installed patches fail to protect against the flaws they address. The BlackLotus story we described is not the only such example — for instance, in 2025 Microsoft released an update against the ToolShell vulnerability that also had to be applied manually.

However, modern security solutions are designed to account for such cases when installed patches fail to protect against security flaws for one reason or another. For instance, the Exploit Prevention component available in Kaspersky products prevents exploits from running if the patch is not applied, or if it is a zero-day vulnerability with no available patch. It is thus crucial to equip all machines in an organization with security solutions and constantly monitor the alerts they raise.
  •  

3 lessons from frontier AI vulnerability research

The mission of Microsoft Security’s Frontier Offensive Research & Generative Exploitation (FORGE) Lab is to advance the frontier of autonomous security engineering. We’re building a team that enables AI-native vulnerability research at Microsoft, pushing the boundaries of finding and fixing zero-day vulnerabilities. Four principles guide that work: autonomy over labor, defense through offense, building ecosystems over individual examples, and understanding over findings. This post reflects those principles in practice across Windows, the Linux kernel, and widely used open-source projects.

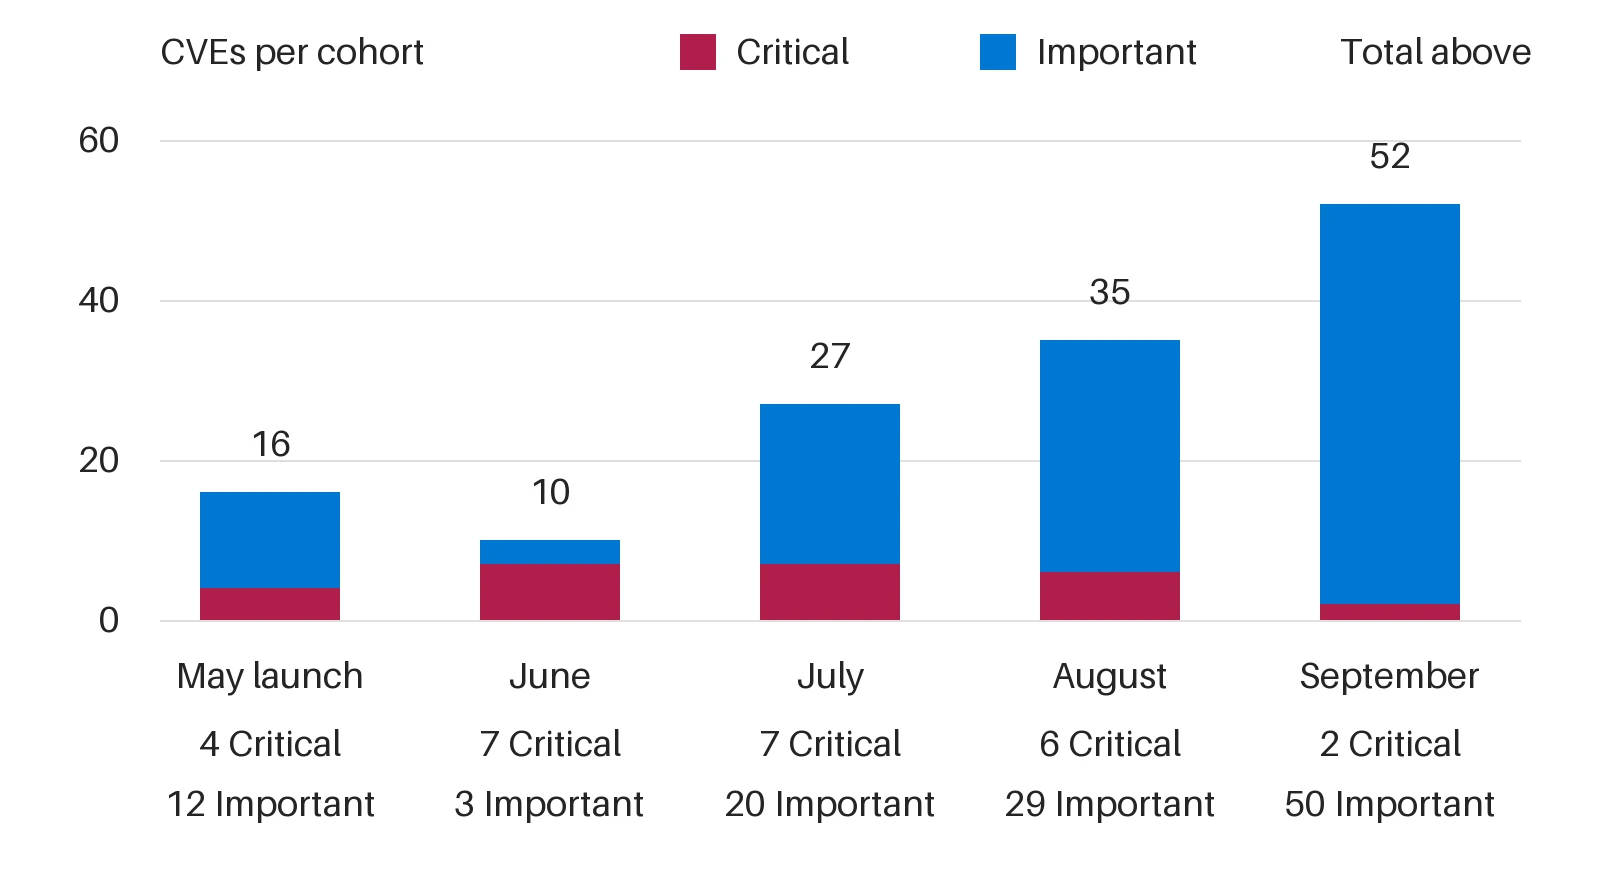
From May 2026 through September 2026, FORGE helped discover Windows vulnerabilities assigned 140 common vulnerabilities and exposures (CVEs), including 52 addressed in September 2026’s security release alone. The work reaches well beyond Windows. FORGE members submitted 155 internally validated reports across 23 open-source projects, including the Linux kernel. And through Akrites, a Linux Foundation initiative that coordinates confidential remediation and disclosure for vulnerabilities in critical open-source software, one of our Linux reports became the first Akrites submission to result in a patch merged into the Linux kernel.

These results demonstrate that agentic discovery can operate at meaningful volume, but they also expose the next constraint. Finding a difficult vulnerability proves an agent’s frontier capability. Repeatedly converting such findings into security updates requires a different kind of system—one that can move credible work through validation, remediation, and release. Discovery creates security value only when validation and remediation can keep pace. For security leaders, the question is no longer only whether AI can find vulnerabilities, but whether an organization can validate and fix them as fast as they are found.

Three lessons follow, each marking a shift in how we approach vulnerability research:

  1. From frontier capability to scale.
  2. From token consumption to reasoning economics.
  3. From isolated discovery to coordinated validation and remediation.

The scarce resource is not always model intelligence. It can be a working build and deployment, a reproducible trigger, or even an engineer’s time.

At FORGE Lab, we use the multi-model agentic scanning harness, codename MDASH, to organize this work. Our May 2026 introduction detailed its design, while the June 2026 update covered pipeline improvements and benchmark analysis. Here, we focus on what those experiences teach us about operating vulnerability research at scale—across Windows and open-source projects.

Stacked bar chart titled “CVEs per cohort” shows Critical and Important  vulnerabilities by month from May launch through September. Totals are 16 CVEs in May (4 critical and 23 important), 10 in June (7 critical, 3 important), 27 in July (7 critical, 20 important), 35 in August (6 critical, 29 important), and  52 in September (2 Critical and 50 Important).
140 CVEs addressed through Microsoft Patch Tuesday since May 2026. Monthly totals reflect announcement and servicing cohorts, not discovery dates or scan throughput. Source: Microsoft FORGE Lab study, May 2026 to September 2026.

Shift 1. From frontier capability to scale

The frontier question is whether a system can find a bug that demands deep reasoning, as we explored in our early work on the CyberGym benchmark. The scale question is whether it can repeat that result across targets without rebuilding every environment, investigation, and review process from scratch. Better models still matter, especially for difficult or unfamiliar bug classes. But once discovery becomes repeatable, model capability is only one constraint on useful output.

Adding auditors can increase candidate volume without increasing the rate of validated findings or shipped fixes. If reports arrive faster than reviewers—in our case, Microsoft Security Response Center (MSRC)—can resolve them, the immediate result is a growing queue. A larger search budget can even reduce useful throughput when duplicate or poorly supported reports consume attention that stronger findings need.

The unit to optimize, therefore, is neither the scan nor the report. It is a reproducible finding that advances with enough evidence for the next stage to act. Reusable preparation, deduplication, and review capacity are therefore core components of the research system.

As agentic systems produce more candidates, the bottleneck shifts from discovery to determining which reports are real, reachable, and security-relevant. Project-specific automated provers—such as proof of vulnerability (PoV)/proof of concept (PoC) generators, harness builders, and trigger-input finders—turn plausible reports into reproducible evidence that engineers and maintainers can act on. By finding crashing inputs, confirming reachable execution paths, and producing regression-ready triggers within each project’s build and test environment, these tools can help reduce human triage, accelerate remediation, and make vulnerability research sustainable at scale. For example, by leveraging deterministic algorithms such as abstract syntax tree (AST), one of our internal projects reduced about 45% duplicate findings across multiple scans of the same code which reduced the load on the PoC generator and subsequently human triage effort.

More candidates do not create more throughput when the review queue grows faster than fixes ship.

Shift 2. From token consumption to reasoning economics

At scale, every repeated orientation, speculative branch, and redundant debate carries a cost. But minimizing tokens alone is the wrong objective. A short, ambiguous report may be cheap to generate yet expensive to investigate; a longer analysis that establishes the missing execution path may reduce total system cost.

The key question is where the next unit of reasoning will change a decision. If an index can identify callers, asking a frontier model to rediscover them wastes capacity. If the uncertainty is whether two lifetime conditions can coexist across callbacks, deeper reasoning may be warranted. If the question is whether an input triggers the failure, an executable check can provide evidence that more prose cannot.

MDASH combines frontier and distilled models, specialized auditors, and code-analysis tools, enabling work to be allocated by task. That flexibility does not guarantee optimal allocation. Routing routine work to cheaper models, reusing verified context, and escalating unresolved questions to stronger reasoning are hypotheses to test—not efficiency gains to assume.

A useful allocation policy starts by identifying what remains unknown: a caller, a build configuration, a reproducer, or a causal explanation. The next action should close that specific evidence gap. Repeating a review without adding evidence spends more tokens while preserving the same uncertainty. Early filtering can also discard real bugs, so any savings must be measured against coverage and missed findings.

Scan outcomes can also become training data. At scale, vulnerability scanning should become a training loop, not only a discovery pipeline. Each MDASH run produces signals that can improve future models: true-positive and false-positive verdicts, duplicate findings, failed reachability claims, reviewer feedback, verifier results, severity assessments, patch outcomes, and regression-test evidence. Capturing those signals with the code context and causal argument behind each candidate creates the dataset needed for reinforcement learning and fine-tuning specialized cyber models. The goal is for future models to learn not just what a vulnerability looks like, but which findings survive validation, which explanations help humans and provers act, and which patterns lead to useful remediation.

Spend reasoning to remove uncertainty, not simply to produce more analysis.

Shift 3. Validation and remediation as a continuous learning loop

Validation and remediation are not downstream cleanup; they are part of the discovery loop. Each candidate should move through automated verification, human review, patch development, and regression testing, with every stage returning evidence to the system. A reproducible trigger strengthens the report, guides the fix, and can seed a regression test. A failed validation is also useful when it records why: an unreachable path, missing precondition, incorrect build configuration, insufficient attacker control, duplicate report, or incomplete causal explanation.

That evidence is how the system improves. Project-specific provers, harnesses, and trigger generators accumulate operational knowledge about how each target builds, runs, fails, and accepts fixes. Remediation outcomes show the discovery pipeline which evidence changed a decision, which assumptions failed, and which bug patterns warrant more or less attention. The objective is to make every investigation leave reusable capacity behind: a validated trigger, clearer invariant, better harness, stronger regression test, or routing rule that prevents the same mistake.

Human attention remains essential, but it should concentrate where judgment has the highest leverage: assessing security impact, reviewing patches, and determining whether a change restores the component’s intended invariant. Automation can handle the repeatable work of establishing reachability, reproducing behavior, and preserving evidence. Over time, this loop converts individual findings into system knowledge—raising the quality of future discovery while shortening the path from credible report to shipped fix.

A reproducible defect is not yet a serviced fix. To shorten the path from discovery to remediation, MDASH needs to operate as part of the engineering loop: continuously scanning code, connecting findings to the builds and artifacts produced by continuous integration and continuous delivery (CI/CD), and feeding validation results back into development, as described in the Windows team’s blog post. Broad analysis can identify suspicious code paths, but component-specific proving needs the right binaries, symbols, configurations, harnesses, and runtime conditions to reproduce a candidate defect against the version that matters for customers and releases. Each handoff should be both owned and machine-usable: research supplies the candidate claim, causal path, and uncertainty; proving supplies execution evidence from the relevant build artifact; component teams assess the violated invariant, repair strategy, compatibility risk, and related variants; and servicing connects the approved change to release validation. A failed reproduction, rejected finding, incomplete patch, or regression result should feed back into MDASH as structured evidence, not simply move a ticket into another queue. The goal is not to remove human code review or release validation, but to automate the repeatable work around them—finding candidates, selecting artifacts, reproducing behavior, preserving evidence, suggesting related paths, and returning what was learned to the next scan.

The goal is to build an organization-wide system that automates repeatable work while preserving clear engineering accountability.

Transferring security research to help open source projects

In open source, all three constraints apply at once. Each project has its own setup costs, mix of analysis and execution work, and maintainer workflows and review capacity. Within Windows, vulnerability research connects to established component owners and servicing infrastructure. Across open-source projects, reusable methods can reduce repeated setup, but they cannot replace the technical and human context required to move a finding toward a fix.

Open-source vulnerability reporting snapshot

Over three months, FORGE members audited open-source projects spanning kernels, runtimes, networking libraries, container technologies, and media parsers. The team submitted 155 internally validated reports across 23 projects. At the time of writing, 93 reports across 14 projects or project families had documented maintainer acknowledgement or acceptance: apple/container, apple/containerization, curl, Escargot, FFmpeg, Hyperlight, Linux, llama.cpp, Node.js, PyRIT, Rust, SQLite, vLLM, etc.

Since the reports are at different stages of that process, only subsets are publicly disclosed today, such as curl’s CVE-2026-9545 and CVE-2026-13608, Node.js’s CVE-2026-56848, and Linux kernel CVE-2026-64563. Our public CVE index lists the CVEs currently cleared for disclosure, and you can find all our public channel Linux kernel reports through lore.kernel.org query.

Measured costs of automated validation

MDASH surfaced thousands of suspicious locations in the Linux kernel, and our validation agents produced supporting evidences for 627 findings. The figures below summarize automated validation costs for a subset of these efforts. Across 182 confirmed crash findings, generating a PoC averaged $3.61 in model cost and 21.5 minutes. For six selected cases, using automatic exploit generation (AEG) to test local privilege-escalation potential averaged $8.56 and 25.4 minutes.

Paired horizontal bar charts compare average model cost in USD and average completion time in minutes for two security-testing tasks. Blue bars show crash PoC generation (182 confirmed findings) at $3.61 and 21.5 minutes, versus local privilege-escalation testing (6 selected cases) at $8.56 and 25.4 minutes.
Average model and time cost for Linux kernel automated validation. Per-case averages reflect all attempts for successful cases using GPT-5.5. Source: Microsoft FORGE Lab Linux kernel automated validation study, 2026.

These evaluations used GPT-5.5, without extensive task-specific tuning of either the model or the harness. These averages include all attempts associated with the successful cases shown, but exclude initial screening, candidates that failed or were filtered out, and human investigation and patch preparation. Within those limits, the results still strongly indicate that automated validation can produce useful results at practical cost and latency, even at Linux-kernel scale. Tighter co-design of models and agent harnesses could improve both validation yield and efficiency. If costs fell by another order of magnitude, for example, 10x or even 50x, the range of findings that could be economically validated would expand substantially, further reshaping vulnerability research.

FORGE OSS Bug Hunt Party: Human coordination at scale (Hackathon)

Looking back to those efforts, technical evidence was only part of the job. Getting it fixed also required understanding and respecting each project’s context and workflow: some required a patch while others did not; some preferred private disclosure while others used public channels; and maintainers sometimes differed on whether an issue crossed a security boundary. In practice, this meant adapting to each project’s submission requirements, working with maintainers to reproduce the issue, and, where applicable, refining and retesting a proposed fix. As AI-assisted discovery increases report volume, open-source security research can scale only if research teams absorb the resulting complexity rather than pass it on to maintainers.

Scaling this work also requires more developers who understand the full security workflow. At Microsoft’s annual Hackathon, we hosted the FORGE Open Source Software (OSS) Bug Hunt Party (Project Sunshine) as a forum where developers across Microsoft could exchange security research practices and gain hands-on experience with vulnerability investigation, validation, and responsible reporting. With MDASH and supporting guidance, 50 participants produced 39 reports across six projects, including Microsoft’s open-source Hyperlight project, Linux, vLLM, Gemini CLI, and llama.cpp. Those 39 reports are included in the 155-report snapshot above. Project Sunshine has continued beyond the Hackathon as a forum for open-source security collaboration within Microsoft.

Akrites: Coordinated effort to remediate vulnerabilities

Akrites is a Linux Foundation initiative that coordinates confidential remediation and disclosure for vulnerabilities in critical open-source software. FORGE has submitted nine Linux findings with internally assessed common vulnerability scoring system (CVSS) scores above 7.0. Together with submissions from other participants, including Google, these cases helped test and refine Akrites’ early Coordinated Vulnerability Disclosure (CVD) workflow. One of those reports was the first Akrites submission to result in a patch merged into the Linux kernel. FORGE will keep contributing to those responsible disclosure efforts.

The work also showed that a systematic approach is not just a larger scan. It is a repeatable path from a finding to an upstream fix and coordinated disclosure. Each case needs reproducible evidence, a clear causal explanation, a severity assessment, and an understanding of which downstream projects may be affected. The right owners and collaborators can then be brought in at the right time and on a need-to-know basis.

What’s next for FORGE Lab?

In a matter of months, FORGE Lab has helped discover Windows vulnerabilities and assigned 140 CVEs, including 52 in September 2026’s security release. Beyond Windows, FORGE submitted 155 internally validated reports across 23 open-source projects—93 of which had documented maintainer acknowledgement or acceptance at the time of writing—and one of our Linux reports became the first Akrites submission to result in a patch merged into the Linux kernel. Our Linux kernel results also indicate that automated validation can work at practical cost, with proofs of concept averaging $3.61 in model cost and 21.5 minutes per successful case. The lesson behind those numbers: once agents can find difficult bugs, progress depends on the system around them, how it scales, where it spends reasoning, and how quickly it turns discoveries into validated fixes.

These three lessons are becoming foundational guidelines for FORGE’s next phase of research:

  1. Moving from frontier capability to scale means measuring the full pipeline, not just the number of findings: candidate arrivals, duplicates, rejected reports, validated defects, queue age, unresolved cases, and time through each stage.
  2. Moving from token consumption to reasoning economics means evaluating model and execution cost alongside human review time, and asking whether each additional pass removes uncertainty, improves coverage, or produces independently validated findings.
  3. Moving from isolated discovery to continuous validation and remediation means tracking reproduction success, patch rework, regression evidence, and elapsed time from validated defect to approved fix and release.

For security leaders evaluating AI-powered vulnerability discovery, these are useful measures too: count validated fixes, not just findings, and weigh model cost alongside the human review time it takes to act on them.

The next advance won’t come from a better model alone. It will come from research systems that combine frontier capability, systems engineering, and reasoning economics, focusing machine reasoning and human attention on turning credible findings into validated fixes.

Our team is growing. Check out our open positions at FORGE Lab.

Further reading:

To learn more about Microsoft Security solutions, visit our website. Bookmark the Security blog to keep up with our expert coverage on security matters. Also, follow us on LinkedIn (Microsoft Security) and X (@MSFTSecurity) for the latest news and updates on cybersecurity.

The post 3 lessons from frontier AI vulnerability research appeared first on Microsoft Security Blog.

  •  
❌