❌

Reading view

Rethinking Vulnerability Management: “If It’s Not in the Scanner, It Didn’t Happen” Needs to Go

Recently, somebody from a fairly mature security team told me something I did not want to hear: if software vendors run “Mythos-class” models on their own code and fix what they find, they must publish a CVE for every fixed vulnerability.

CVE art

My first reaction (vendor hat firmly on, since I now work at Cisco) was: huh? Why? These bugs were found by the vendor, fixed by the vendor and were never public. A vast majority (but not all!) are not exploited. CVE CNA rules make assignment a SHOULD, not a MUST, and whether a quietly shipped fix even counts as “publicly disclosed” is something considered debatable. Why would anybody want it?

My second reaction, a bit later in the conversation was: oh, that!

They have a point. Sort of. They were simply describing how their vulnerability management program works. And, I suspect, how many of yours work too. Their problem is about to become everybody’s problem; they just noticed it first.

The Problem In One Sentence

Many VM programs start with a vulnerability scan, not with a patch, a vendor release or … a news headline about a new terrible security issue.

The chain looks like this:

old sad VM

Note what is not on this list: the vendor advisory. It is not an input in their case.

Before anybody snickers or ROFLs about it: this was a sound design for about 20 years. In the 2000s and 2010s, an issue that mattered usually got a CVE (yes, before the “vuln-purists” tear me to shreds, there were some exceptions to this even back then!). And a CVE got a check from your vulnerability scanner vendor, usually within days (in my Gartner days, we called them “Q/R/T” for the reasons you can easily guess…). Auditors want evidence, ticketing systems need an ID, and SLAs need an event that starts the clock. A “scan-first” program is what you get when you optimize for all of that at scale. It is a property of the pipeline, not a failure of the people running it.

So a software or an OS vendor can shout “URGENT, upgrade now!” all it wants. If the fix has no CVE, the scanner (usually) has no finding, there is no ticket, no SLA clock, no change request, and no patch (at the companies that follow that model).

Here are the two paths side by side:

Paths table

Why This Matters Now: Hello, Vulnerability Apocalypse

I hate the “post-Mythos” label as much as the next person, but these numbers are not marketing. (BTW, every time you say “post-Mythos” for marketing purposes, Claude kills a kitten.)

In Patch Sound Barrier Part 2 I defined the “vulnerability apocalypse” as four things arriving together: massive vulnerability volume, fast exploit development, exploitation at scale and resulting incident damage. Factor #1 is no longer theoretical: high and critical CVEs from notable vendors ran at roughly 3.5x the prior monthly record in June 2026, and at about 5x in July.

Now the twist: those charts only count the fixes that got a CVE. The pile of internally found, internally fixed, never-CVE’d bugs is not on any chart. For scale: Anthropic said in May that Mythos Preview had been used to find more than 10,000 high- or critical-severity bugs, not all of them publicly reported.

That is the part of the iceberg your scanner cannot see (usually). So a big chunk of the AI era’s fixes may be exactly the ones that scan-first programs miss! Your patch SLA dashboard stays green while your actual exposure grows. Green-but-wrong is worse than red.

BTW, “internally found” does not mean “nobody else knows.” Attackers have access to capable models too, AI makes patch diffing cheap, and some vendor advisories now list “internally discovered” bug classes that also contain actively exploited bugs. Found internally means “we found it too,” not “we found it first and only.” Yes, I know, Captain Obvious strikes again, but a scan-first program behaves as if this were not obvious at all.

Timing makes it worse. Here is one real example (via X post): CVE-2026–72529, a remote, unauthenticated script execution bug in TrueConf Server. The issue was found in June, the patch was also released in June, exploitation was spotted in July, and the CVE was assigned in August, by Kaspersky as a third-party CNA, not by the vendor. For a scan-first program, that bug did not exist for about two months, including the month it was being exploited. Note that even the “exploited bugs get a CVE” metric ran a month behind the exploitation here — away too slow. (Yes, it is a niche product. Niche is exactly where scanner coverage is thinnest.)

Who Taught Us to Think This Way?

Naturally, I also asked on X, and I got my share of thoughtful responses like “ask if adversaries will delay exploitation until a CVE and severity score exist”, “FYI, vulnerabilities without CVEs, or with low scores, regularly cause damage” and a reminder that “a CVE reflects severity after discovery, not exploit probability.” All true, all ignored by scan-first vulnerability management programs…

The best answer IMHO was this point: somewhere along the way, “a lookup key [CVE] became a proxy for risk.” Indeed, how did that happen?

“Scan-first” did not appear out of nowhere. Scanner vendors taught the market to think this way, and the market went along happily.

Some of the blame here is well deserved:

  • Coverage was sold in CVEs. For years, the headline number in every bake-off was how many CVEs a product detects and how fast a new check ships. Many customers learned that the CVE list is the threat model.
  • The CVE became the unit of work. Dashboards, risk scores, SLA reports and ticketing integrations were all built around CVE IDs. Anything without one is a second-class citizen in the product, and therefore in the program.
  • “Clean scan” became audit evidence. Compliance scanning made “the scan report is clean” the proof that auditors still ask for. In PCI DSS ASV scanning, pass or fail is largely decided by the CVSS scores of the findings. (Yes, I co-wrote a book on PCI, so I am not innocent here either.)
  • Non-CVE coverage exists, but nobody marketed and sold it. Many scanners do have checks keyed to vendor bulletins, and most flag outdated or unsupported versions. In practice, those often land as low-priority findings that no SLA tracks. They were never the thing on the slide…

And before you say “just use KEV and EPSS”: both are keyed on … CVE IDs. KEV only lists vulnerabilities that have an assigned CVE, and EPSS only scores CVEs. “Risk-based” Vulnerability Management built on CVE-keyed inputs inherits the exact same blind spot. Not very risk-aware, that is.

To be fair, all of this was once rational. A CVE is a clean, shared, countable unit, and you can build a product (and a business) on countable units. This worked kinda OK in 2015, worked poorly in 2021, and really, really does not work in 2026.

So a market that was essentially taught “if it’s not in the scanner, it didn’t happen” now needs to learn something new, and the people who taught the first lesson are best placed to teach the next one.

The Three Obvious Fixes Are Suboptimal

CVEs are not only a scanner input; they are also a public accountability ledger. This industry has a long and not very proud history of silent patching, and “trust us, we fixed it, this matters to you” has earned all the skepticism it gets.

At the same time, the vendor-side point also stands. Defenders at software companies will use those models to fix their code, and their code is getting better and more secure. Flooding the market with huge piles of CVEs will not help anybody. Both things are true at once, and that is what makes this problem interesting.

So, the quick fixes, each with a catch:

  • Option 1: A CVE for every internally found bug. At AI scale, this floods scanner queues with hundreds of findings that a single upgrade closes. We have actually run this experiment: after the Linux kernel became a CNA in 2024, it started assigning CVEs for thousands of backported fixes, and people have complained about the noise ever since. Even Epoch had to footnote it as noise in their CVE charts.
  • Option 2: Bundled CVEs. Cisco now ships scheduled security releases with CVEs bundled by weakness type (CWE), and still assigns an individual CVE when a bug is exploited or needs a compensating control. It is a pragmatic middle path. If a bundle is scored by its worst member, it also pushes you toward handling exceptions per release rather than per CVE, which, as you will see below, is exactly where I think you should end up anyway…
  • Option 3: Read vendor advisories manually. Ah, the good old days! Mapping advisories from hundreds of vendors onto thousands of assets by hand does not scale, and frankly never did.

Note that Option 3 is wrong about the how, not the what. The advisory does need to reach your program. A human with a browser and 200 vendor websites just cannot be the delivery mechanism.

So What Would Actually Work? Make the Advisory an Input

In my strictly private opinion, the vendor advisory must become a first-class input to vulnerability management, next to the scan, not behind it. Not “instead of the scan,” and not “if the scanner vendor gets around to it.”

The chain should look like this:

new cooler VM

Obviously, better programs do this today, so for a decent percentage of this blog’s readers this should really not be news. This blog is not for you.

Getting there needs three parties to move, not one (plus your auditor):

  • Vendors: publish machine-readable advisories (CSAF much?) with fixed versions, urgency and exploitation status. And keep the accountability ledger honest: assign an individual CVE the moment a bug is exploited or needs a compensating control. (Yes, this is close to what my employer committed to in June. This is the easy part; the next bullets are the hard ones.)
  • Scanner vendors: you taught the market that the scanner is the source of truth, so you get the first job. Ingest those feeds and create findings under your own IDs, no CVE required, at real severity rather than as an informational footnote. You already flag “outdated version”; this is the same idea, driven by vendor data. (Yes, the risk is that coverage follows market share. Niche OT vendors, I am looking at you.)
  • VM programs: add a currency metric next to CVE closure, e.g., percent of assets within N releases of the vendor’s latest security release. In other words, patch the release, not just the CVE. If your remediation speed is capped by the patch sound barrier, spend that limited throughput on upgrades, not on ticket accounting.
  • Your auditor: if audit accepts only CVE closure as evidence, nothing above will change. Bring them in early and show them the currency metric before it shows up in an audit finding.

What To Do This Week

Run the 30-minute self-test:

  1. Pick your top vendor by asset count (or by internet exposure).
  2. Pull their last three security releases and count the security fixes vs. the CVEs. (If the release notes just say “multiple security fixes” with no count, congrats, that is a finding too.)
  3. Check what your scanner flagged for those releases.

The difference between what the vendor fixed and what your scanner flagged is your blind spot, in numbers.

Ask your scanner vendor:

  • What do you do with a vendor advisory that has no CVE?
  • Do you ingest CSAF advisories, and from which vendors?
  • What is your median lag from a vendor advisory to a detection?
  • Can you show me every asset more than N releases behind the vendor’s latest security release, and at what severity?

Change your program:

  • For edge and crown-jewel asset classes, start the SLA clock at the vendor security release, not at the scanner finding.
  • Grant exceptions per release, not per CVE.
  • Report a currency metric next to CVE closure, e.g., “percent of internet-facing assets on the vendor’s latest security release within 30 days.”
  • Put it in contracts: vendors provide machine-readable advisories with fixed versions and exploitation status, and scanner vendors cover non-CVE vendor fixes at real severity.

So?

With my vendor hat on, I still don’t think every internally found bug needs its own CVE. With my VM hat on, it should not matter: your program should not need one to act. Patch the release, not just the CVE. If the gap is zero, congrats, and please tell me how you did it. If it is not, you have found your blind spot… have fun!

Related blogs:


Rethinking Vulnerability Management: “If It’s Not in the Scanner, It Didn’t Happen” Needs to Go was originally published in Anton on Security on Medium, where people are continuing the conversation by highlighting and responding to this story.
  •  

GTA 6 before release: fake leaks, “early access”, and other scams | Kaspersky official blog

Gamers around the world are holding their breath for November 19, 2026, the day Grand Theft Auto VI is expected to drop. Many of them have been waiting for the next installment in the hit series for over a decade. For die-hard fans, the final months before launch could prove especially agonizing. Sadly, scammers know all about this hotly anticipated release too, and they’ve decided to use it as a lure to launch all sorts of attacks on gamers. We’ve spotted a great many bait sites aimed at impatient GTA VI fans. Today, we walk you through exactly how these crooks try to trick gamers, and how you can avoid becoming their next target.

1. “GTA VI has already leaked, and all you have to do is pay”

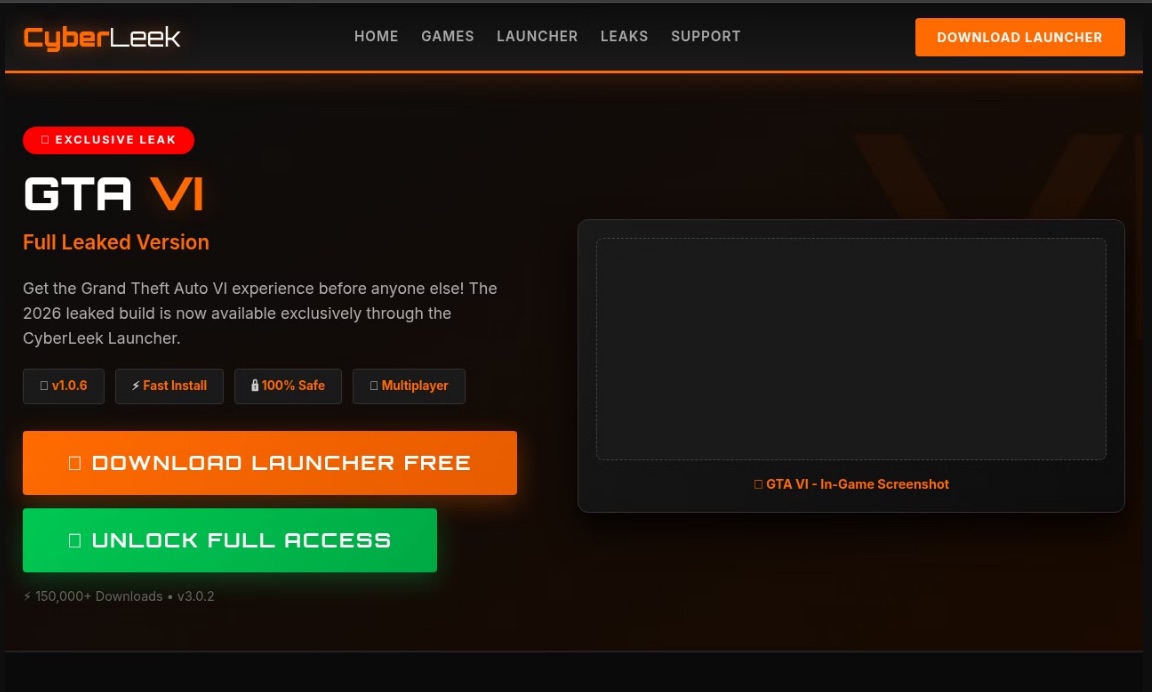
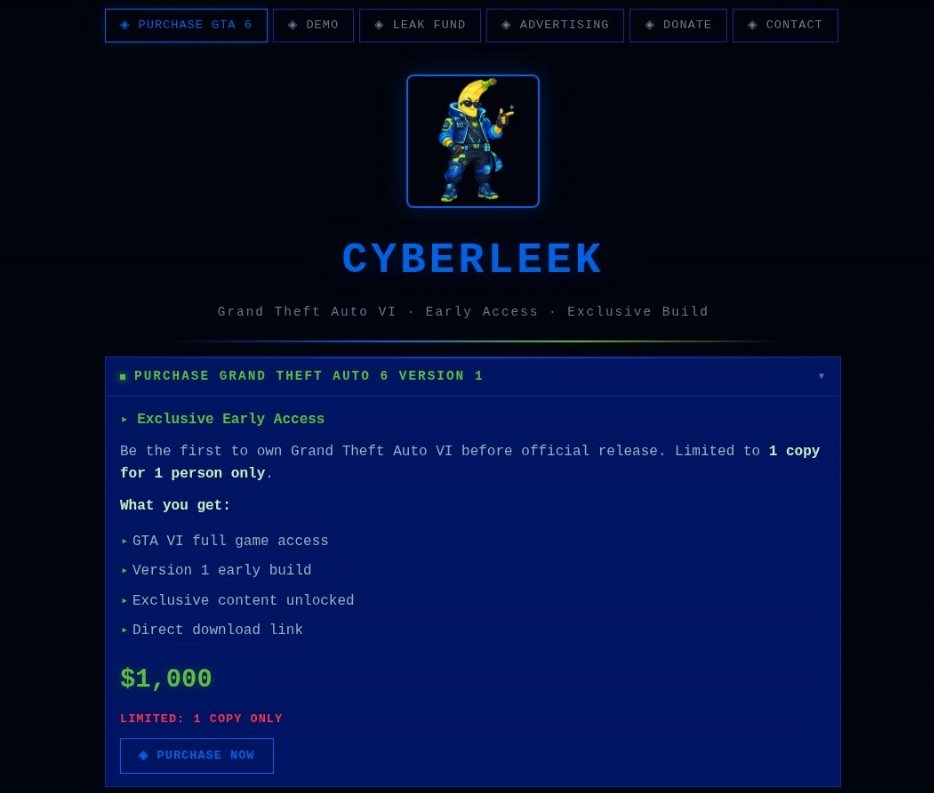
One site our experts found, called CyberLeek, claims to have an early build of GTA VI, and pretends to offer three different ways to get hold of the game before its official release. The first and priciest option is to buy the “full game” of GTA VI for US$1000. For that price, buyers are offered an early build of the game, exclusive content, and a direct download link. This is claimed to be a limited offer: only one copy per customer.

CyberLeek offers buyers a full early build of the game, exclusive content, and a direct download link

An alleged GTA VI leak advertised for US$1000

For those not ready to part with a thousand dollars, there’s a cheaper option: for a hundred dollars, users can get 24-hour access to the GTA VI demo.

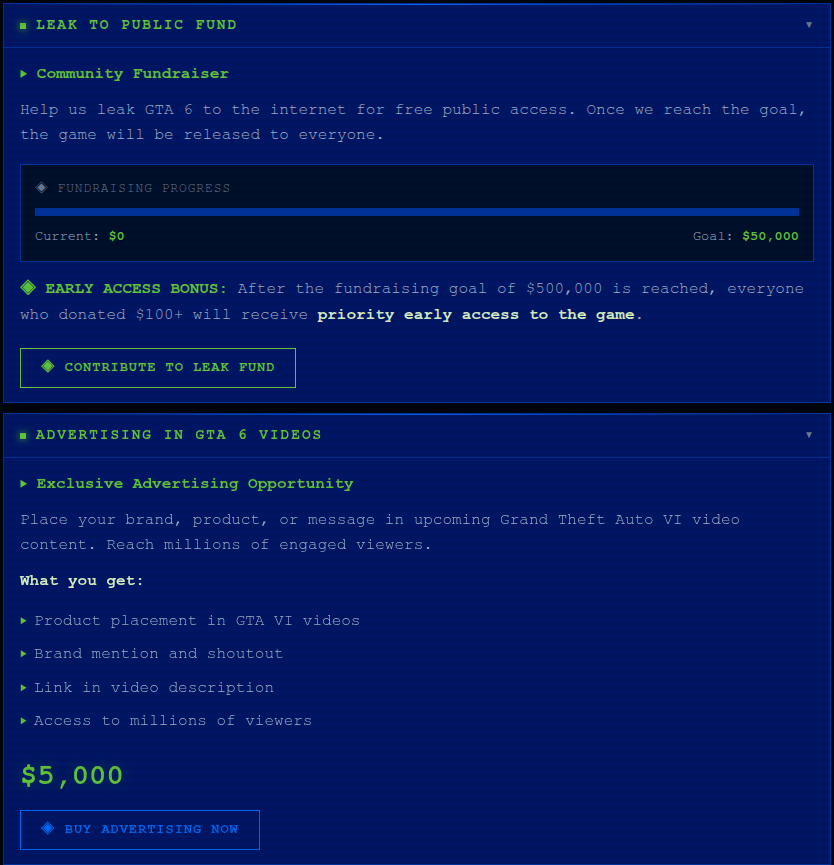
Finally, the third option relies on crowdfunding. Playing modern-day Robin Hoods, the site’s creators claim they’ll raise $50,000 and then release the game to the public for free, with everyone who donates at least $100 getting priority early access. But dig into the fine print, and the fundraising goal for that paid early access suddenly jumps from $50,000 to $500,000. Looks like one of the scammers sat on their keyboard hit an extra zero by accident.

Raising money to release GTA VI

An urgent fundraiser for US$50,000 — or is it US$500,000? — to release a leaked GTA VI build, plus advertising opportunities for businesses

But CyberLeek’s lineup of tempting “offers” doesn’t stop there; there are also services for businesses. For US$5000, the site’s creators offer to place an ad right inside Grand Theft Auto VI: a logo, a product, or a brand mention that will supposedly show up in some unspecified “upcoming Grand Theft Auto video content”. What exactly that means is unclear: in-game clips or cutscenes, trailers, or just some gameplay footage. And honestly, the price seems suspiciously low for product placement in one of the most anticipated games in recent years.

This offer looks especially amusing next to the supposedly complete early build of the game with full access available on the same website. So, apparently, the game is already finished enough to sell in full, but you can still somehow slap ads into it.

One can only pay for all these incredible services with cryptocurrency. CyberLeek accepts Bitcoin, Ethereum, USDT, and Litecoin, and the site’s creators make a point of saying that all payments are final and no refunds are possible. Well, we weren’t expecting refunds anyway.

That said, this is just one example. CyberLeek started out as the nickname of the hacker behind both the recent Rockstar Games breach and GTA VI content leak. Later on, other cybercriminals began using that same name to build a whole bunch of fake sites. Despite having completely different designs, all of these sites attempt to project an association with CyberLeek, enticing users with (false) promises of access to “official” leaked versions of GTA VI. Whichever of these sites you come across, we’d strongly advise against using your own computer to check what’s actually hiding inside the archives and installers they hand out.

Yet another CyberLeek site advertising an

Another CyberLeek site offering access to a “leaked build” of GTA VI invites the user to download some unknown launcher, or “unlock” the full version of the game — whatever that means

2. Preordering Grand Theft Auto VI — with a catch

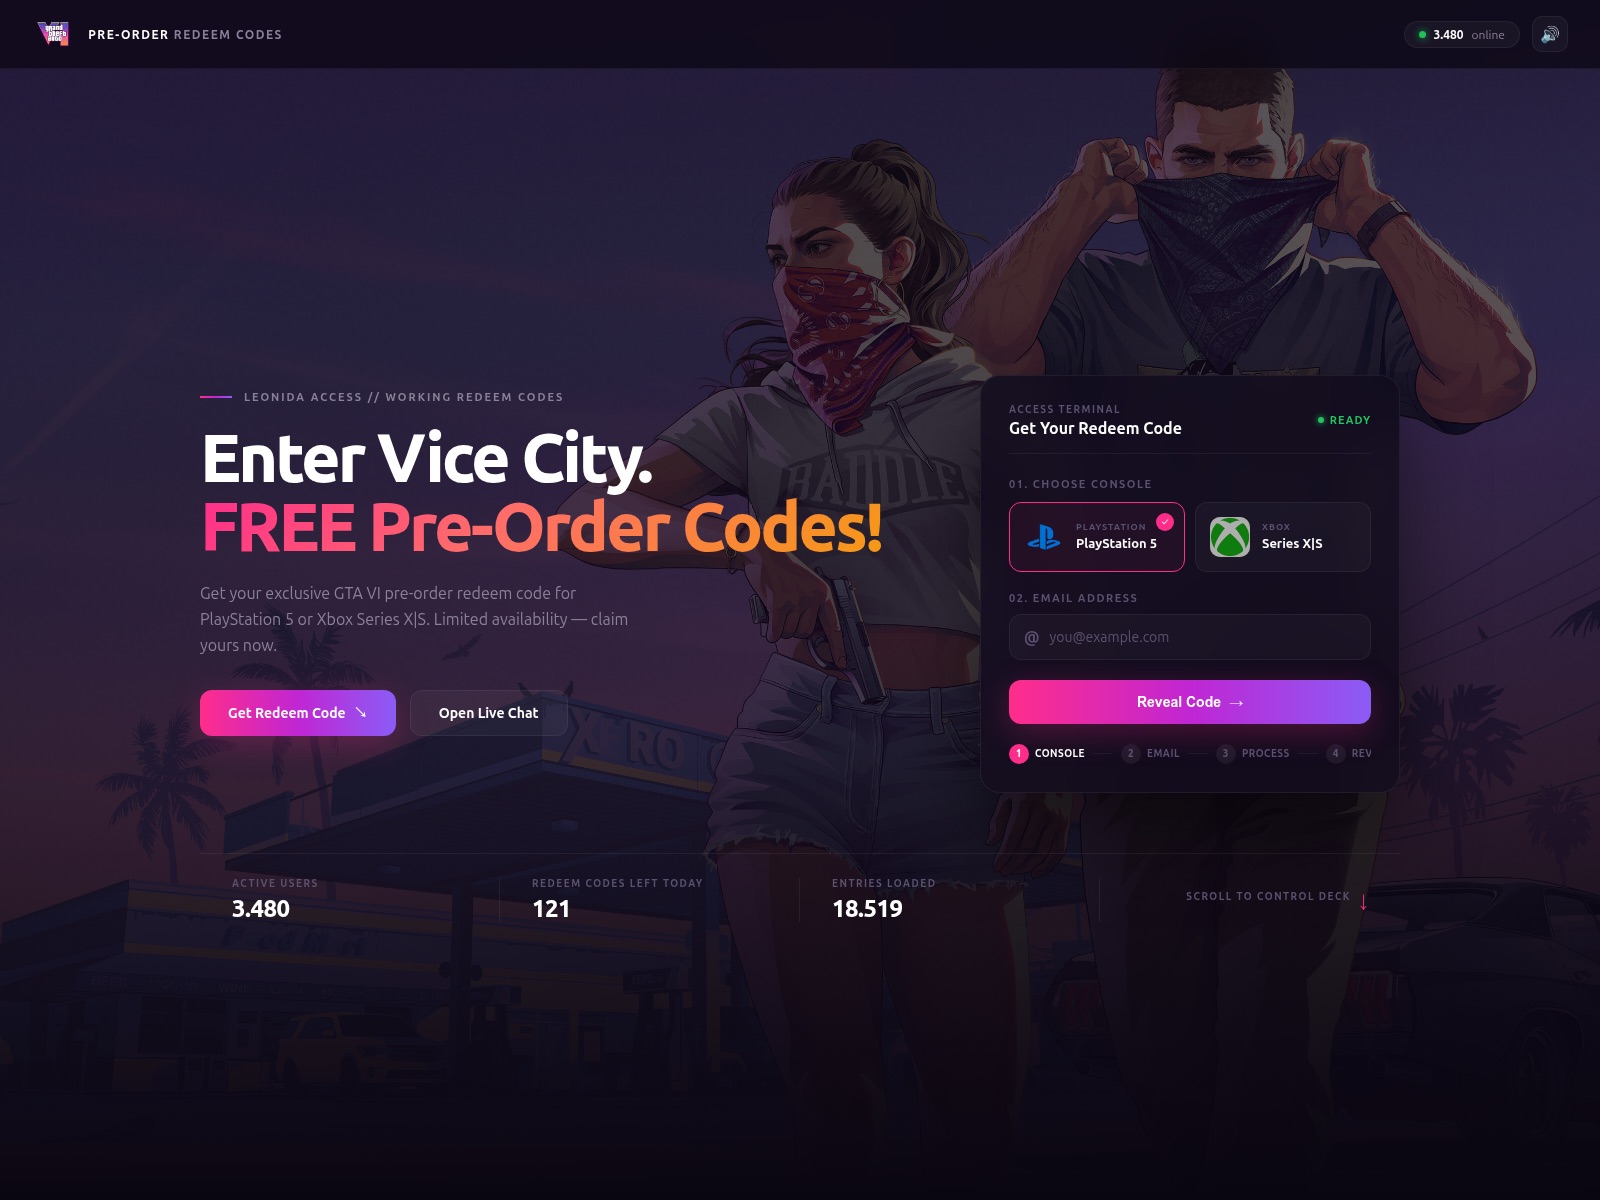
This bait targets slightly more sensible gamers — the kind who aren’t trying to download GTA VI right this second but wouldn’t say no to grabbing a free preorder code ahead of time. Our experts found a site that is claiming to hand out a redeem code for the PlayStation 5 or Xbox Series X|S. All one needs do is pick a platform and provide an email address.

To make it all look convincing, the site even shows off its own “statistics”: it supposedly has 3480 active users, and only 121 codes are still available as of today.

Free GTA VI preorder codes

To get the “exclusive code”, the user is asked to pick a console and provide their email address

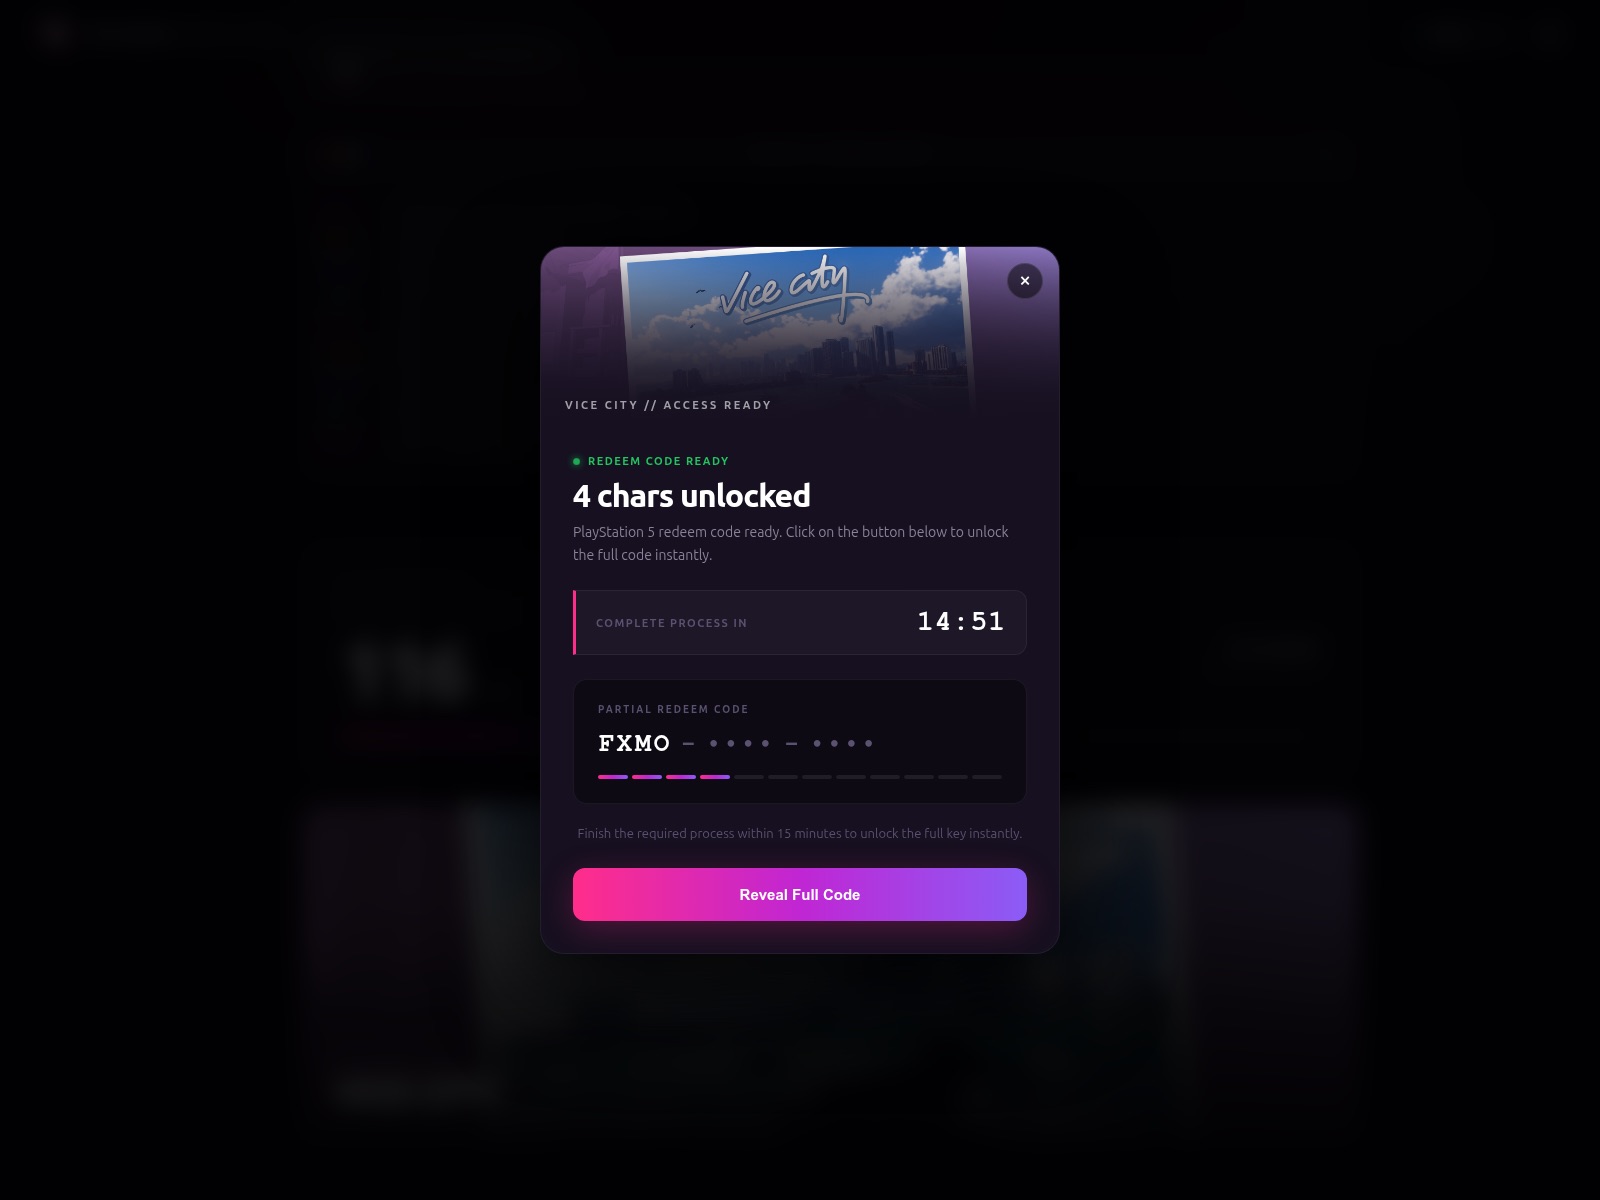
After picking a console, entering an email address, and clicking Reveal Code, the user lands on a new page. It shows the first four characters of a supposedly generated code, and to get the rest the user is asked to complete an additional check. They’re given 15 minutes to do so.

Four characters from the promised code

The site shows the first four characters of the coveted code, and promises to send the rest after an additional check, which the user has 15 minutes to complete

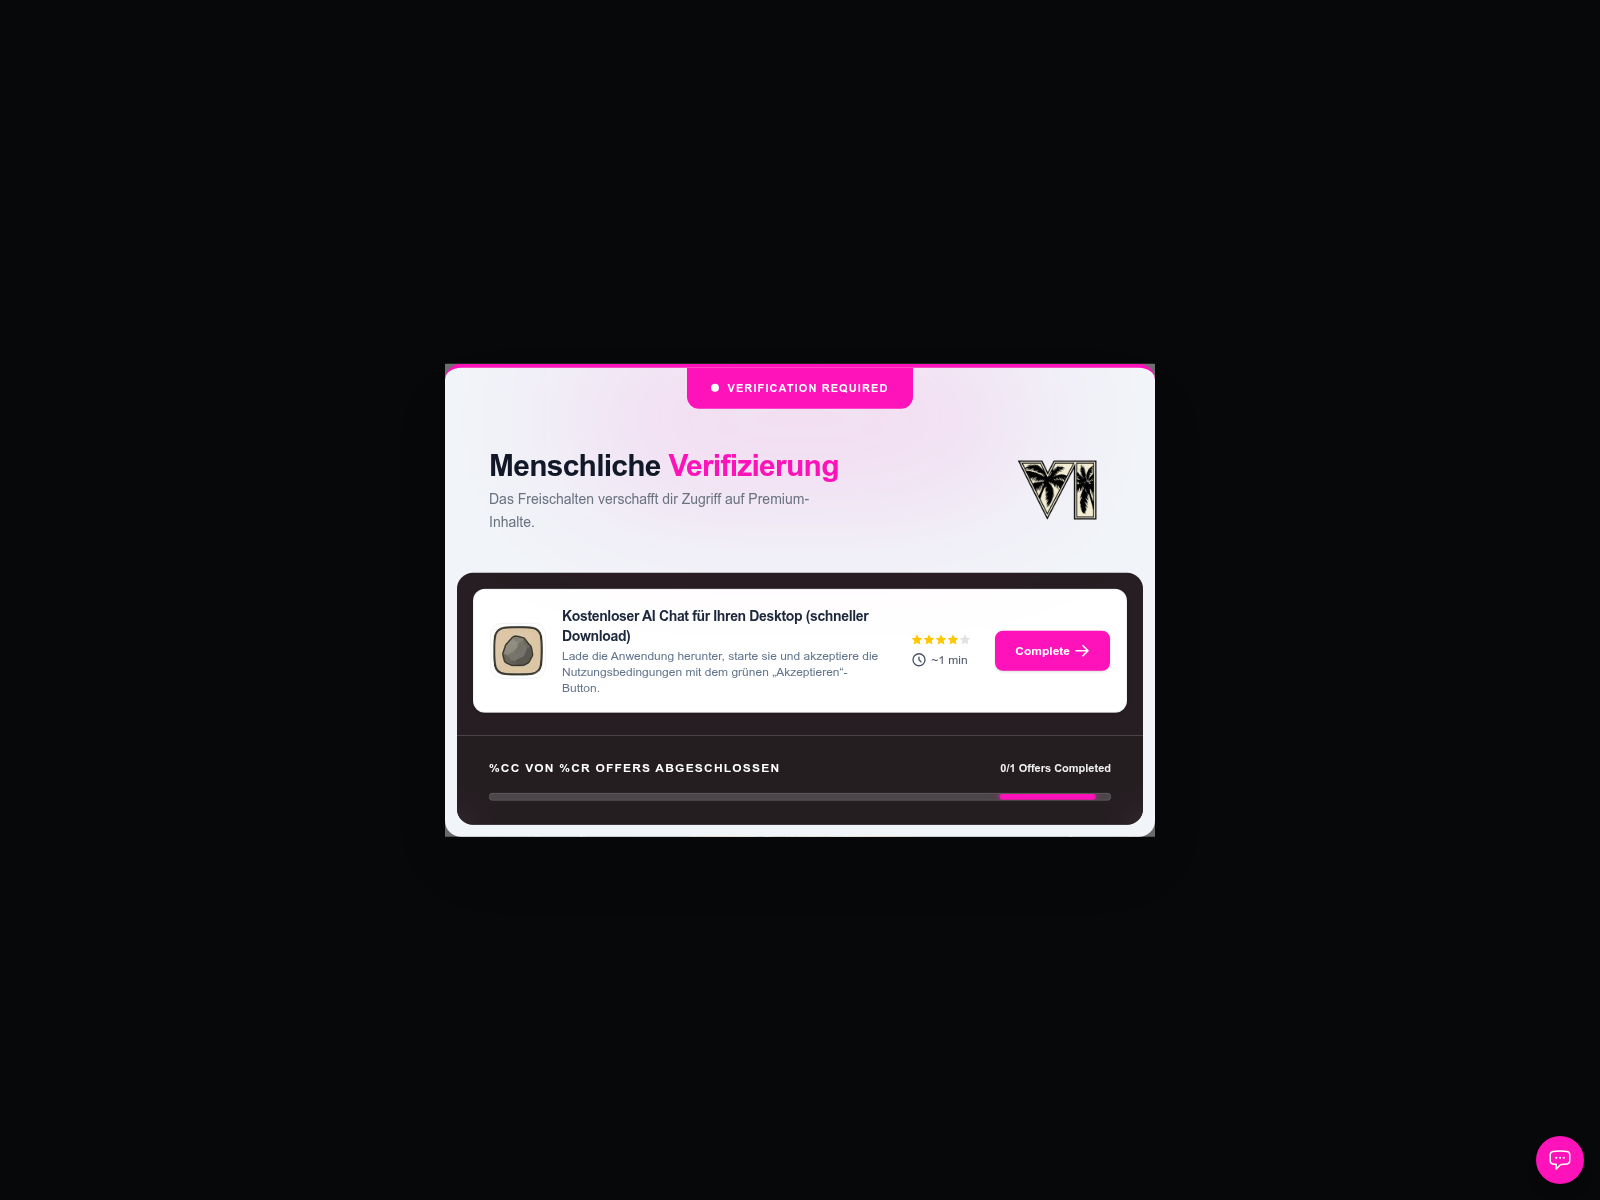
Nobody tells the gamer upfront what this check actually involves. But the next page, which opens after clicking Reveal Full Code, inexplicably turns out to be in German. Here, the user is asked to pass a “human verification”: download a free AI chat app for their computer, run it, and accept the terms of use.

The real point of this “verification” most likely boils down to driving traffic to third-party, often shady, or outright fraudulent sites, with GTA VI simply used as bait to pump up visitor numbers.

Unknown app instead of a GTA VI code

To get the rest of the “code”, the site demands that the user download and run an AI chat app and accept its terms of use

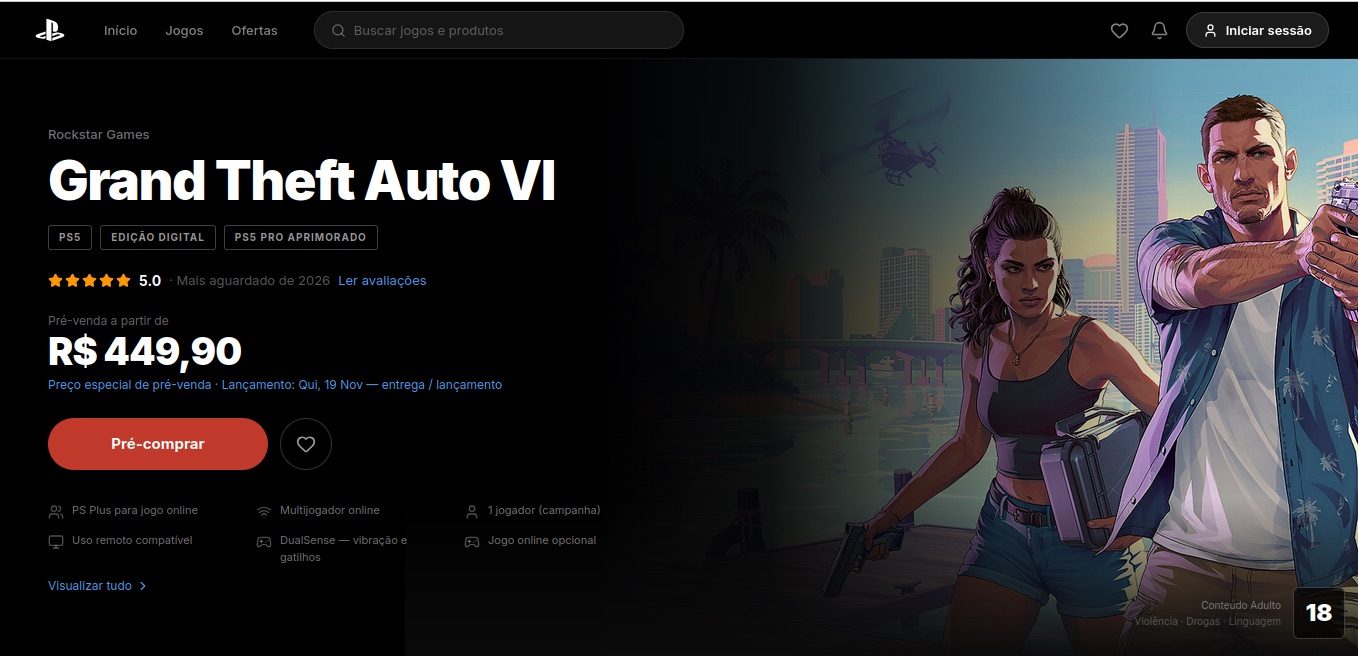
A simpler variation involves fake sites that simply collect money under the pretext of placing preorders for Grand Theft Auto VI. For example, a fake PlayStation Store site targeting Brazilian users offers preorders for R$449.9, which actually matches the official price in the real PS Store. The user can pay with a credit card or through Pix (Brazil’s instant payment system), but along with their money, they’d also have to hand over personal data, including their CPF — the Brazilian equivalent of a taxpayer identification number.

Fake GTA VI preorder at the official price

In Brazil, a fake PlayStation Store site collects money for GTA VI preorders at a price that looks legit

3. You’ve missed it: GTA VI is already out!

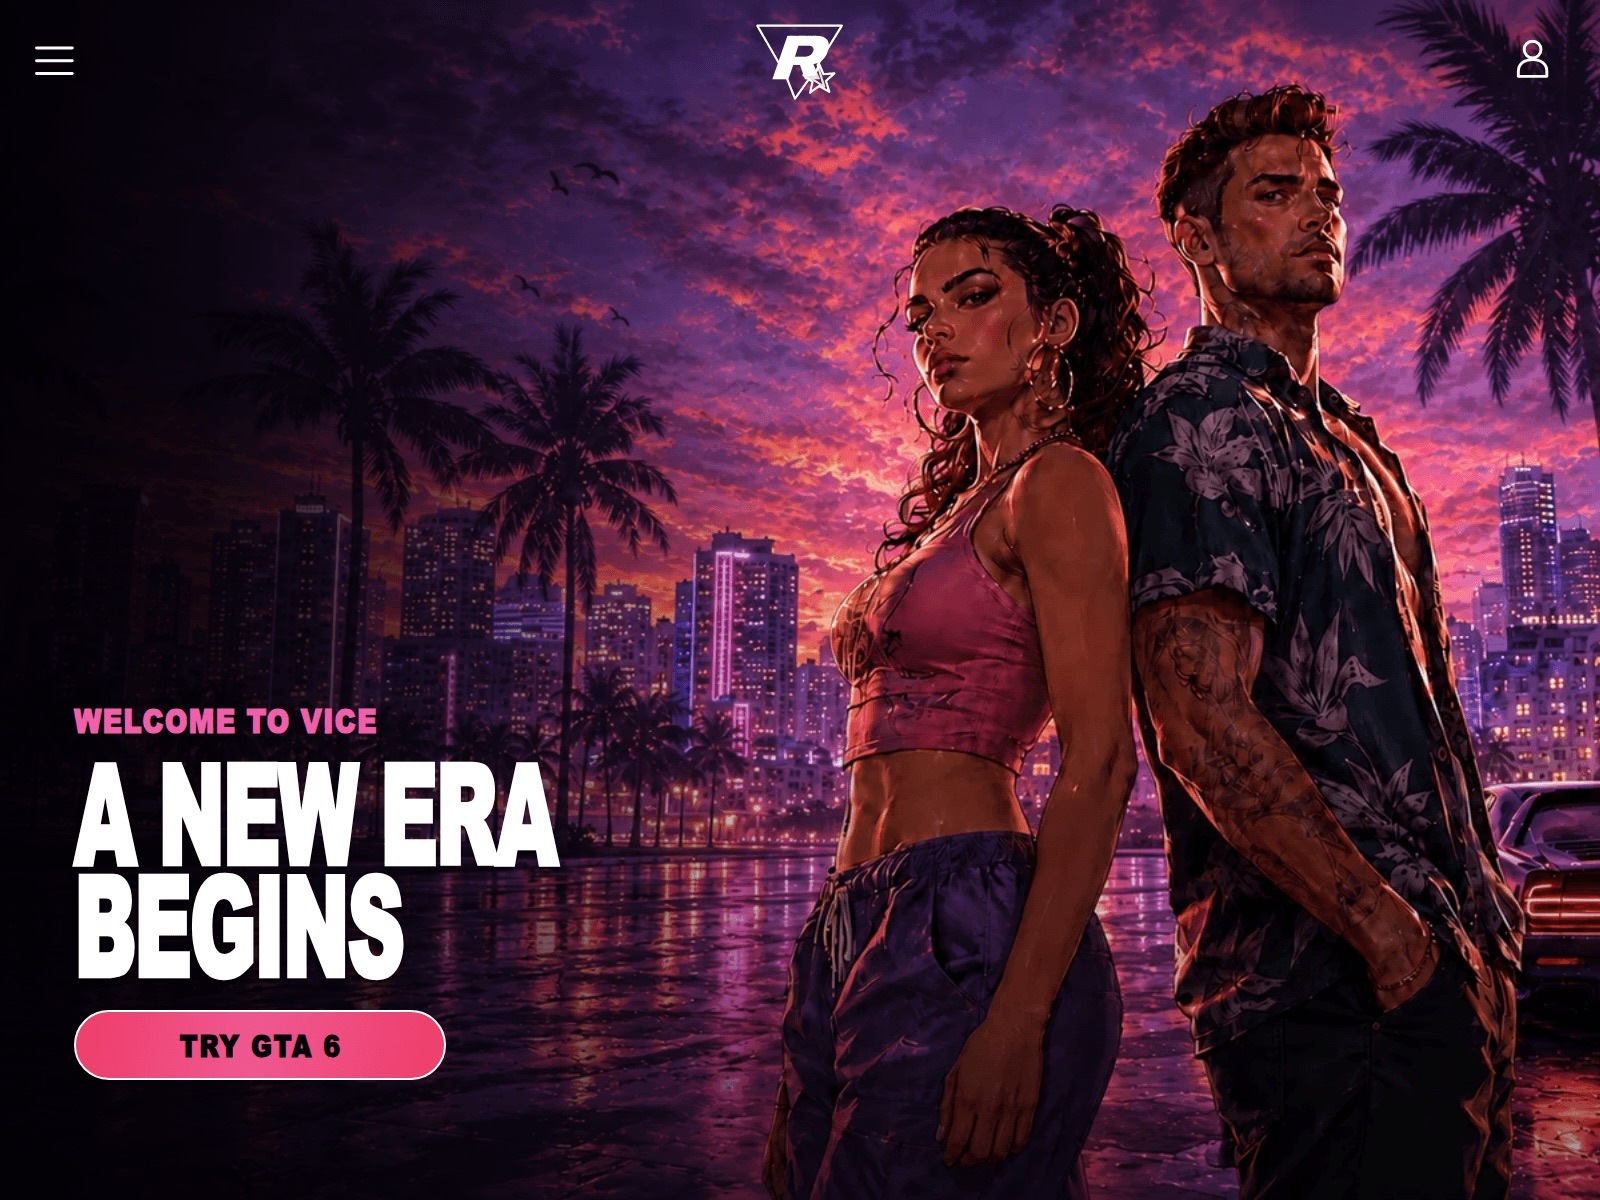
Some scammers don’t even bother with elaborate stories about leaks, beta tests, or preorder deals. They simply build websites that copy the look and feel of GTA, and invite users to start playing GTA VI right here, right now. We came across a few examples of these sites.

GTA VI — right here, right now

No leaks, no tests, no codes needed: visitors are simply invited to click Try GTA 6 and start playing

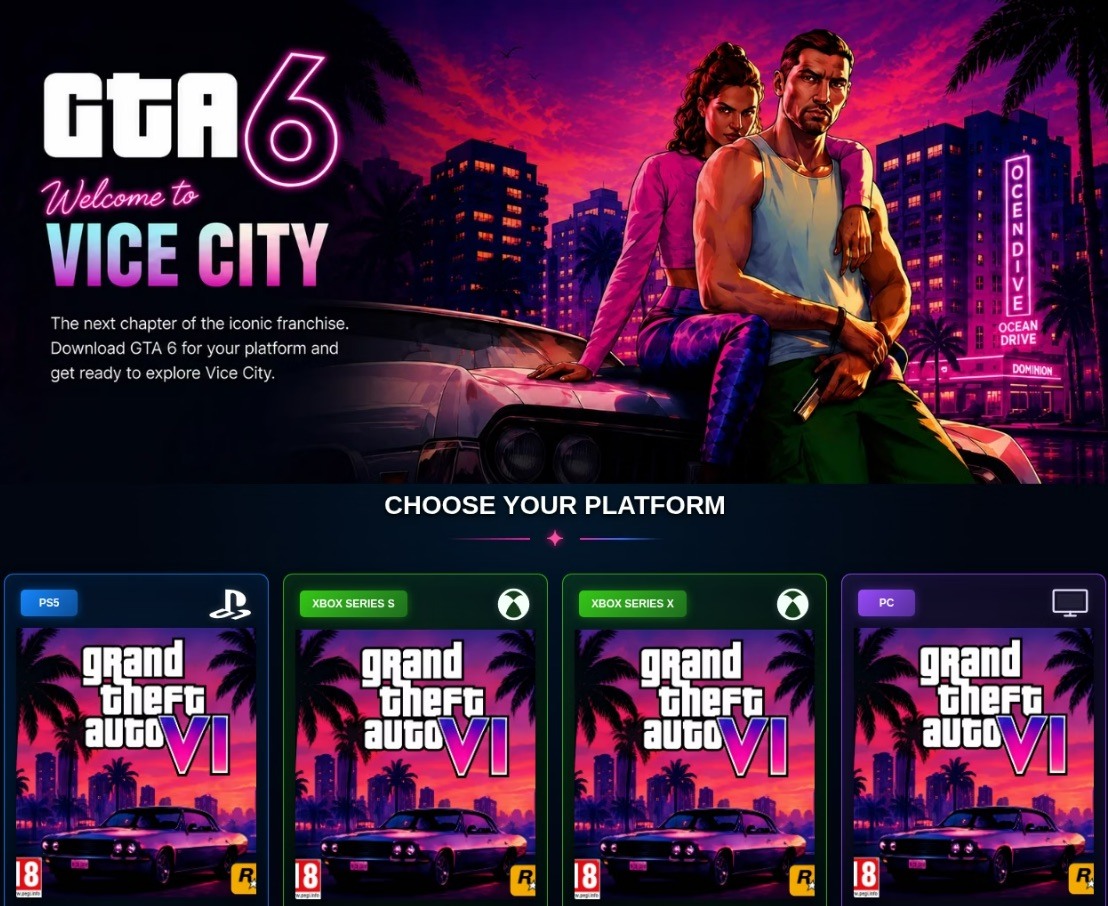
One of these sites tells users they can download GTA VI, as long as they first pick their platform. The range of options is surprisingly generous: a PC version as well as versions for PlayStation 5 and Xbox Series X|S.

GTA VI on any platform

Users are invited to pick a version of GTA VI for PlayStation 5, Xbox Series X|S, or PC

Just to be clear, GTA VI’s official release is still more than a month away, so there’s no way one can download and install the game right now. Nobody knows exactly what users would be getting on their devices instead of the game if they download from one of these sites, but it’s definitely nothing useful. And no matter how carefully scammers copy GTA’s signature style and slap on the Rockstar logo, the address bar usually gives the game away: check the domain and compare it with the official Rockstar Games website address.

4. The icing on the cake: GTA VI for tokens

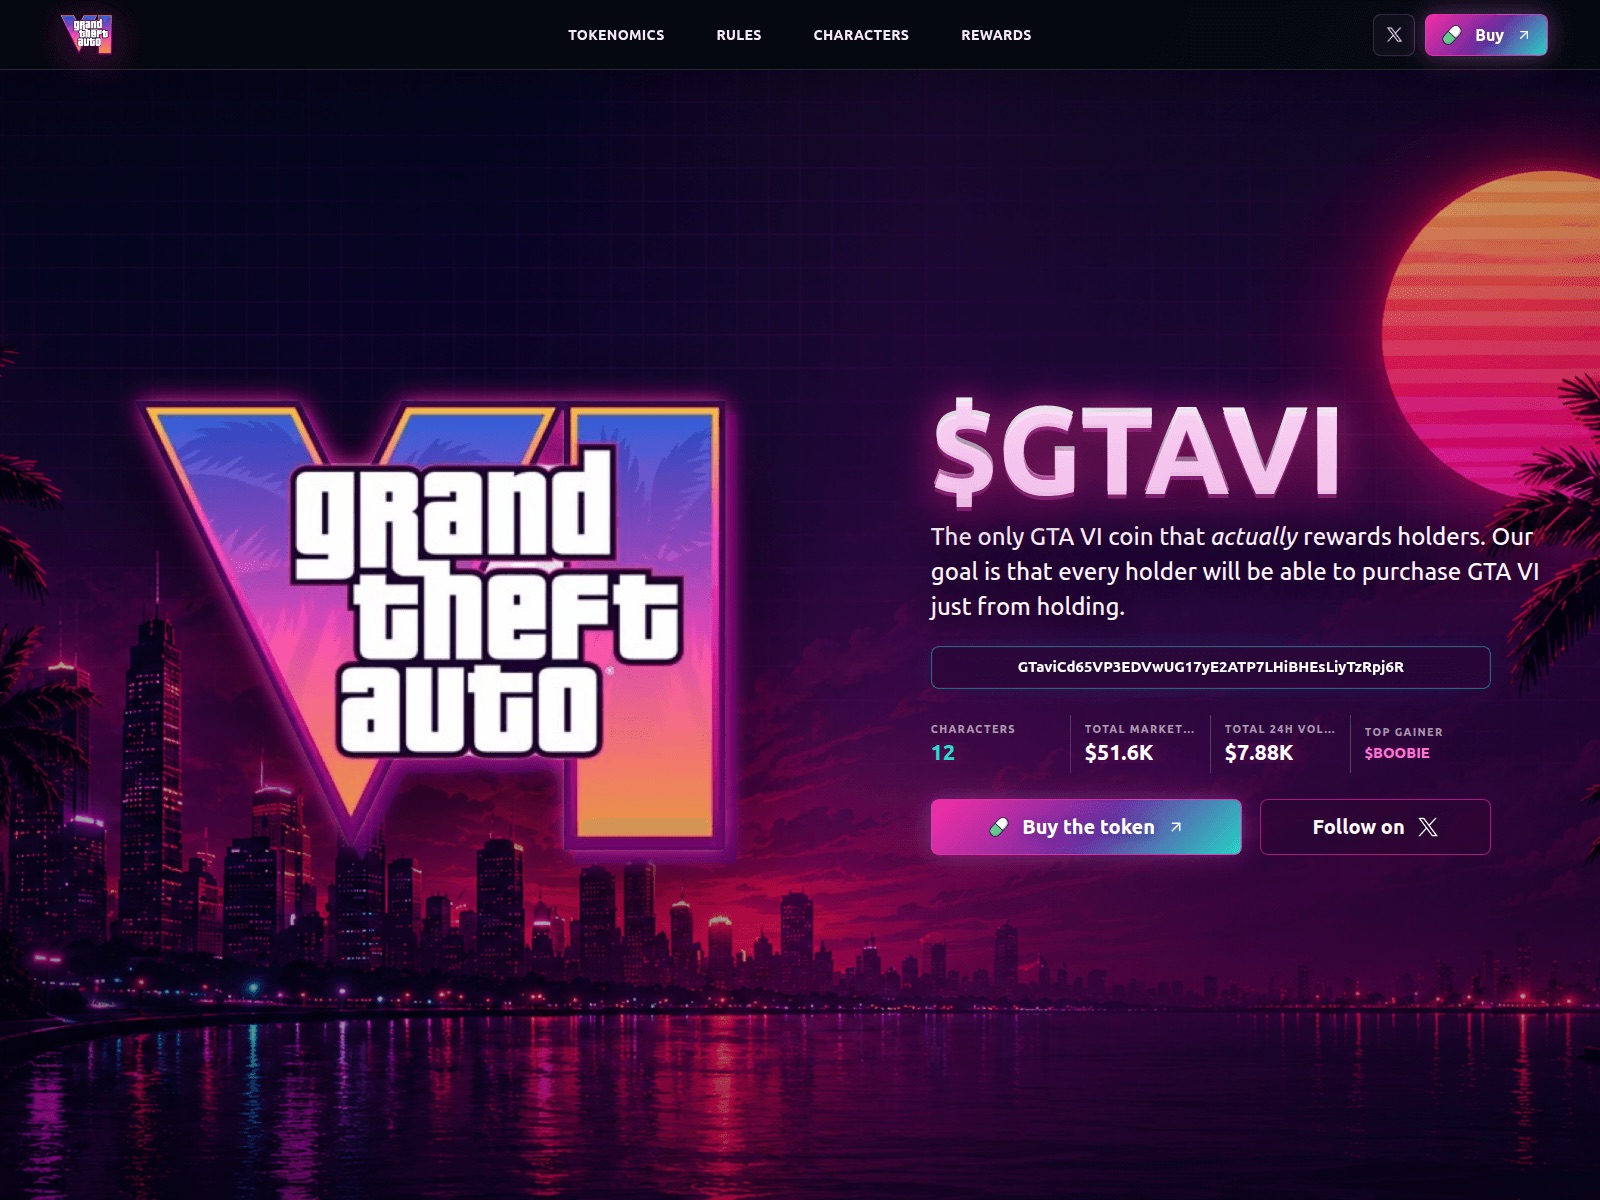
And finally, what would 2026 be without cryptocurrency? We found a site whose creators were probably inspired by the CyberLeek story and decided to ride the wave of GTA VI’s popularity to promote a token with the refreshingly straightforward name $GTAVI. The whole site is styled after GTA VI and Vice City.

The creators of the project have gone out of their way to highlight the perks of holding the token. They call $GTAVI “the only GTA VI coin that actually rewards its holders”. Whatever the meaning of that tagline, the project’s declared ultimate goal sounds even more tempting: every token holder will get access to Grand Theft Auto VI just by virtue of owning $GTAVI. Think about that for a second: it’s not exactly a direct promise of a free copy of GTA VI, but more like an aspiration on the part of the crypto developers.

GTA VI as a reward for holding $GTAVI

The token’s creators claim that they’re striving to eventually provide every $GTAVI holder with access to GTA VI

To add a bit of credibility, the page also throws in some crypto stats. The claimed market cap of $GTAVI is 51,600 dollars, with a 24-hour trading volume of 7880 dollars. There’s also a mysterious metric called “Characters” with a value of 12, and what exactly it means is anyone’s guess. There’s also a separate mention of a certain $BOOBIE as the Top Gainer — apparently, this is how the site’s creators labeled whoever supposedly made the most money off $GTAVI. The site doesn’t explain where any of these numbers come from or how accurate they actually are.

All in all, this looks like an attempt to hype up yet another meme coin by riding the wave of GTA VI’s popularity. Projects like this often end up following the classic pump-and-dump playbook: the token gets promoted for a while to drive its price up, and then the insiders and major holders cash out, leaving everyone else stuck with heavily devalued crypto. As for the stated goal behind $GTAVI — letting every token holder get a copy of GTA VI just for owning it — the site gives us no reason to believe that’s actually going to happen.

How to wait for GTA VI without falling for scammers

Unfortunately, we don’t know of a legitimate way to get early access to GTA VI, and honestly, we doubt anyone else does either. It looks like we’ll all just have to wait until November. To make sure you don’t fall for tempting scam offers in the meantime, here’s what we recommend:

  • Only install games from official sources.
  • Check the website address. Even if a page looks like the official Rockstar Games website or the PlayStation Store, carefully examine the domain in the address bar.
  • Never enter your payment details on sites promising GTA VI before its official release — especially if they ask you to pay in some unusual way like with cryptocurrency.
  • Don’t download unknown launchers, archives, or installation files, even if they’re billed as a “leaked build” or as software you need in order to be a beta tester.
  • Don’t hand over your personal information for a “beta test”, “key”, “early access”, or any other offer that sounds too good to be true.
  • Never disable security features just because a website tells you to. If a site asks you to ignore a Windows warning, run some mysterious command, or launch an unknown file as an administrator, treat it as a giant red flag.
  • Install a reliable security solution built for gamers, one that warns you before you land on a scam site and blocks malicious files, but won’t slow your games down.

What other tricks do scammers pull to fool even the tech-savviest gamers? Find out in our other posts:

  •  

Critical Atlassian Flaw Lets Unauthenticated Attackers Read Known Files Across 8 Products

A critical flaw in 8 Atlassian Data Center products, which customers host themselves, allows an attacker with no login access to read specific files in each product's web application root directory. The attacker must already know a file's exact name and path and cannot list what the directory holds. Atlassian disclosed the flaw, CVE-2026-21589, on October 5, rated it 9.3 out of 10, and

  •  

FBI Removes Accenture Contractor After Patch Failure Led to ShinyHunters Breach

The U.S. Federal Bureau of Investigation (FBI) has removed an Accenture contractor for their alleged role in a ShinyHunters-breach that led to the theft of personal details of thousands of bureau employees. That's according to a report from Reuters, citing two sources familiar with the matter. "To date, our review has determined that the incident occurred as the result of a security failure ​

  •  

The Hidden DoS Vector in SQL Parsers

SQL parsers are critical components of the modern data stack. They validate queries before they reach the database, transpile between dialects, and lint codebases for style violations. Increasingly, they also power AI-driven SQL generation in LLM-integrated data tools. 

Our research focused on two popular Python-based parsers: SQLGlot and SQLFluff, both with around 10k GitHub stars each. These libraries sit at the foundation of the data ecosystem, trusted by thousands of projects, and we believe the underlying issues are relevant to other parsers and other programming languages as well. 

But these parsers carry a hidden flaw. They are highly susceptible to resource exhaustion from seemingly “simple,” syntactically valid SQL queries. Not injection. Not malformed input. Just normal-looking SQL that happens to be shaped in the wrong way. 

In this post, we describe our findings of new vulnerabilities stemming from two root causes: Recursive Stack Overflow and Parser AST Object-Inflation. We show how these flaws cascade into downstream applications, giving concrete examples from several major projects we found vulnerable, with many more still to be explored. We then explain the underlying mechanics and conclude with practical fix suggestions for both parser maintainers and application developers. We reported every issue to the respective maintainers and contributed to the fixes that now ship upstream; the SQLFluff findings were assigned CVE-2026-46373 and CVE-2026-46374. 

The First Clue: A Query That Crashes the Interpreter 

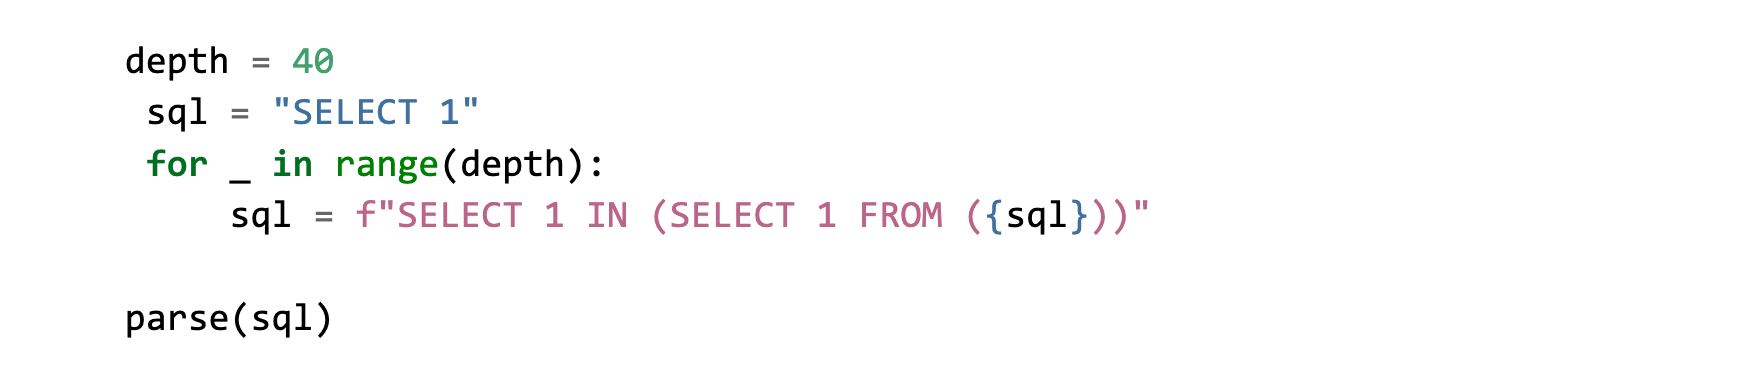
Our research began with a simple question: what happens when you feed a deeply nested query to a SQL parser? 

Screenshot 2026 10 05 at 2.36.42 PM

The answer: the Python interpreter crashes with a RecursionError. At higher concurrency, it segfaults. 

This isn’t a contrived edge case. The query is syntactically valid SQL. Any database would reject it for being absurd, but a parser’s job is to parse it – and both SQLGlot and SQLFluff attempt to do so without any depth limit. At 50+ levels of nesting, the recursive descent parser exhausts the call stack. 

The fix seems obvious in hindsight: enforce a maximum recursion depth (e.g., 30 levels) and abort gracefully. But neither parser does this. 

Going Wider: AST Object Inflation 

The recursion crash was just the beginning. As we explored further, we discovered a more insidious problem: AST amplification. 

SQL parsers work by converting raw SQL text into an Abstract Syntax Tree (AST) – a structured representation where each token (literal, identifier, operator, dot) becomes a Python object. These objects carry metadata: type information, position tracking, parent references. They’re heavyweight. 

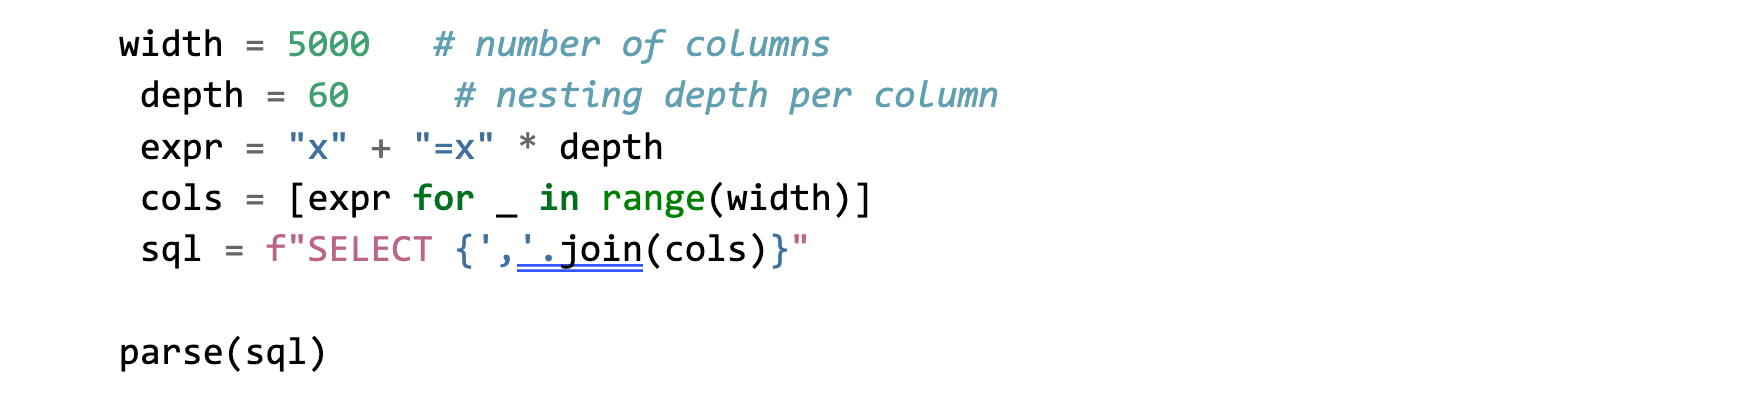
The question became: what if we crafted a query that was short but produced an enormous number of AST nodes? 

Screenshot 2026 10 05 at 2.37.14 PM

The result was striking. In SQLGlot, a SQL string under 2MB in size demanded over 1.5GB of RAM to parse – roughly a 750x amplification ratio. SQLFluff showed the same pattern: at width=5000, it consumed over 1GB. 

This is the core vulnerability: each SQL token gets wrapped in a heavy Python object. A compact input with thousands of columns and deep expression chains generates millions of AST nodes, far exceeding what any reasonable container or server can handle. The process is killed by the OOM killer – or simply hangs until it starves out everything else on the machine. 

The Amplification Chain 

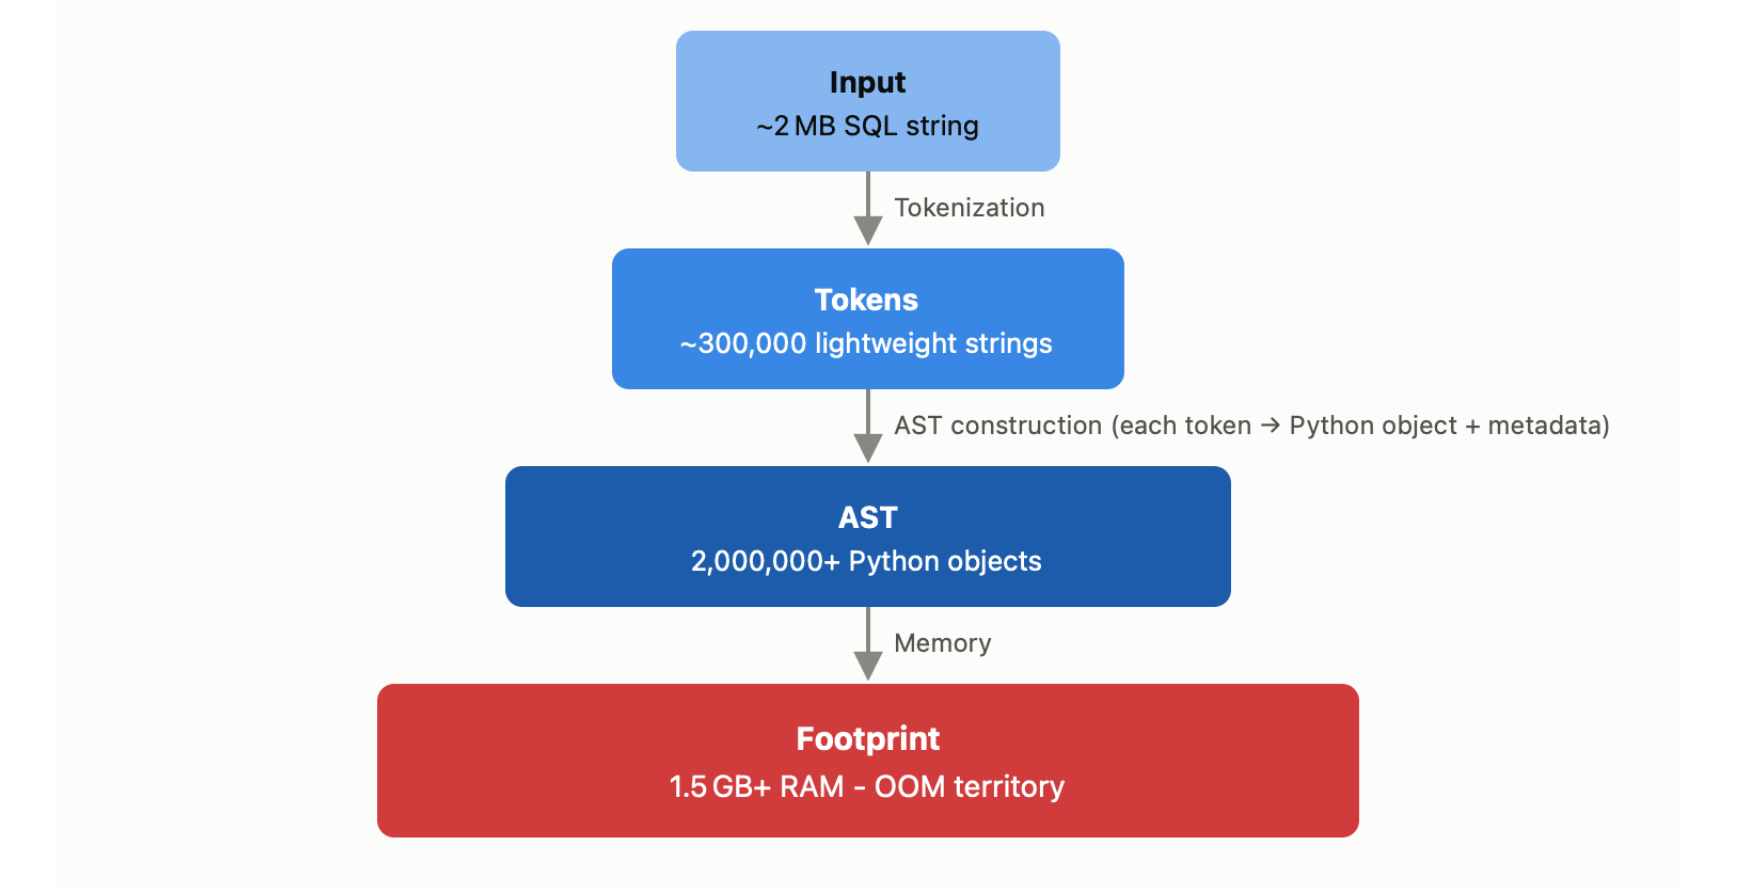
To see where the cost comes from, it helps to follow the input through each stage of parsing. The payload starts small, but every step multiplies it: tokenization splits the string into hundreds of thousands of pieces, AST construction wraps each one in a heavyweight Python object, and the resulting tree balloons into gigabytes of memory. The diagram below traces that roughly 750x expansion from a 2MB string to a 1.5GB+ footprint. 

Screenshot 2026 10 05 at 2.37.45 PM

The key insight is that object inflation is the root cause. It isn’t about the input being “large”, it’s about the multiplicative cost of turning each token into a rich object. A 2MB string is a perfectly normal payload by any standard. But the parser amplifies it by orders of magnitude. 

The Cascade: From Parser to Platform – Examples 

A vulnerability in a parser library is concerning on its own. But parsers don’t exist in isolation, they’re embedded deep in application stacks. When the parser crashes, the application may crash with it. 

We traced this cascade through several major projects. 

Apache Superset: Complete Service Outage 

Apache Superset (~75k stars) uses SQLGlot under the hood. Its SQL Lab feature allows authenticated users to write and execute queries. 

The weakness lives in the pre-execution phase. When a user submits a query through SQL Lab, Superset hands the raw SQL to SQLGlot for parsing and validation before it ever reaches the database and before any complexity checks are applied. There is no limit on query size, nesting depth, or AST node count at this boundary. An authenticated user with ordinary SQL Lab access is enough; the query never has to run. 

Depending on the payload size, the attack produces two distinct denial-of-service states: 

  • Memory exhaustion (OOM crash): Large payloads (roughly 5 MB and up) drive AST allocation past available system RAM. The worker is terminated with a SIGKILL and restarted, dropping in-flight requests. 
  • CPU/thread exhaustion (zombie hang): Moderate payloads (around 1.5 MB) don’t trip the OOM killer but saturate CPU and hold the GIL, so parsing never completes. The GIL (Global Interpreter Lock) is a mutex in CPython that lets only one thread execute Python bytecode at a time; a thread stuck in a long, pure-Python parse keeps the lock and starves every other thread in the process. Every user sees persistent timeouts while the worker is pinned. 

The attack is simple: authenticate as a normal user, then send a batch of concurrent requests to /api/v1/sqllab/execute/, each carrying a payload built from a large number of columns of a deeply nested x=x=x… expression. The number of columns determines which failure mode you hit: 

  • A wide payload (on the order of tens of thousands of columns) makes container memory climb steadily until the worker is killed within a few minutes, emitting the tell-tale log line: 
  • [ERROR] Worker (pid:14) was sent SIGKILL! Perhaps out of memory? 
  • A smaller payload hangs the server with consistent timeouts for all users without triggering the OOM killer. 

The exact thresholds depend on available memory – a 16 GB host behaves differently from a 4 GB container – but either way, a single authenticated user takes down SQL Lab, and the shared worker pool, for everyone. 

Dify: Plugin Framework Collapse 

Dify (~150k stars) Uses SQLGlot within its plugin ecosystem. We found two vulnerable plugins – db-client-node and dify-bigquery-plugin – and that the plugin framework’s architecture amplified the parser vulnerability into a system-wide failure. 

A large SQL payload (10,000 columns x 60 depth) executed through a workflow that triggers 5 concurrent database queries caused a 5GB RAM spike. This didn’t just kill the plugin – it destroyed the IPC bridge between Dify’s Go-based daemon and its Python workers. 

PluginDaemonInternalServerError: write |1: file already closed failed to write request 

The daemon lost track of healthy workers. The system entered a “Blackout” state for approximately 60 seconds, during which all tool calls across the entire framework returned errors – not just those involving the parser. 

SQLFluff Online: Backend Exhaustion via Missing Input Limit 

SQLFluff Online (source) exposes the parser through a web API. The frontend enforces a 3,000-character input limit. The backend does not. 

By sending a crafted payload directly to the /fluffed endpoint – bypassing the frontend – a single request consumed 2GB+ of RAM and saturated the CPU. The service locked up entirely. 

Pathway: OOM in the SQL Interface 

Pathway (~60k stars) uses SQLGlot internally and exposes a pw.sql interface that accepts user queries. We submitted a crafted query (10,000 columns x 70 depth) and watched memory grow unboundedly, consuming 8GB+ of RAM. The server was killed with OOMKilled: true and ExitCode: 137. Pathway produced no error or warning before the crash. 

The Bigger Picture: Parser Exhaustion 

The security community has spent decades hardening systems against SQL Injection, the manipulation of query structure to execute unauthorized commands. This is a different class of attack entirely. 

Parser Exhaustion doesn’t inject anything. It doesn’t exploit string concatenation or missing parameterization. The queries are syntactically valid. They would parse correctly on any SQL grammar. They just happen to be shaped in a way that overwhelms the parser’s resource consumption. 

This distinction matters because Parser Exhaustion bypasses many traditional defenses: 

  • Parameterized queries aren’t relevant for generated queries, where the whole structure is dynamic 
  • Input sanitization won’t catch it – there are no special characters to escape 
  • WAFs typically look for injection patterns, not resource-exhausting shapes 

As the industry moves toward automated SQL generation and LLM-integrated data tools, this attack surface grows. LLMs can generate arbitrarily complex SQL. If that SQL passes through a parser – for validation, linting, or transpilation – the parser becomes an attack vector. Not because the SQL is malicious in the traditional sense, but because it’s expensive. 

The parser is no longer just a utility. It’s a trust boundary. 

Practical Mitigations 

The good news: these vulnerabilities are straightforward to mitigate. Simple limits on recursion depth and AST size can harden parsers against this entire class of attack. 

At the Parser Level

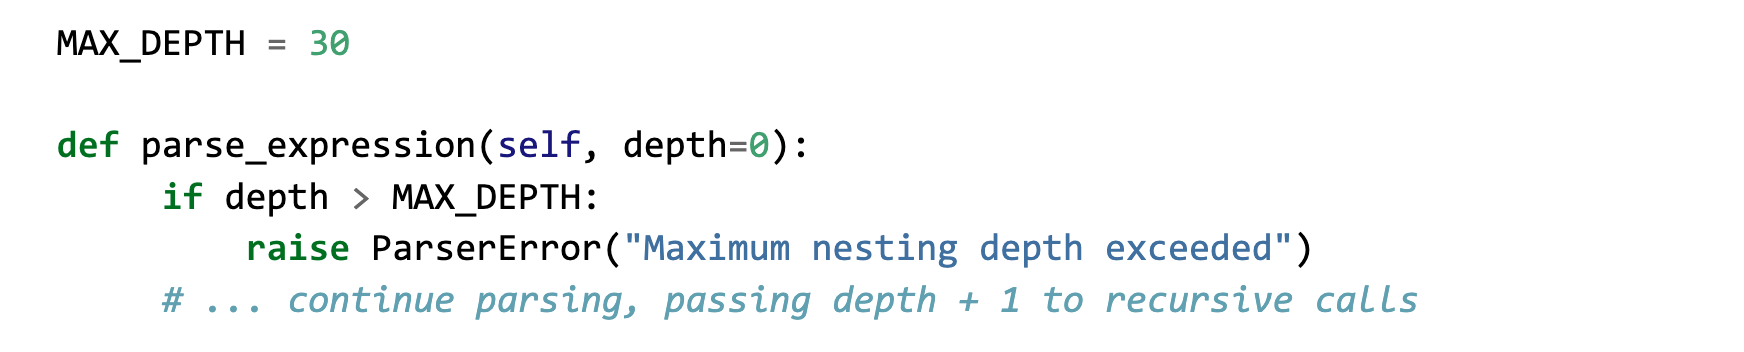
1. Recursion depth limit: abort parsing if nesting exceeds a threshold:

Screenshot 2026 10 05 at 2.42.57 PM

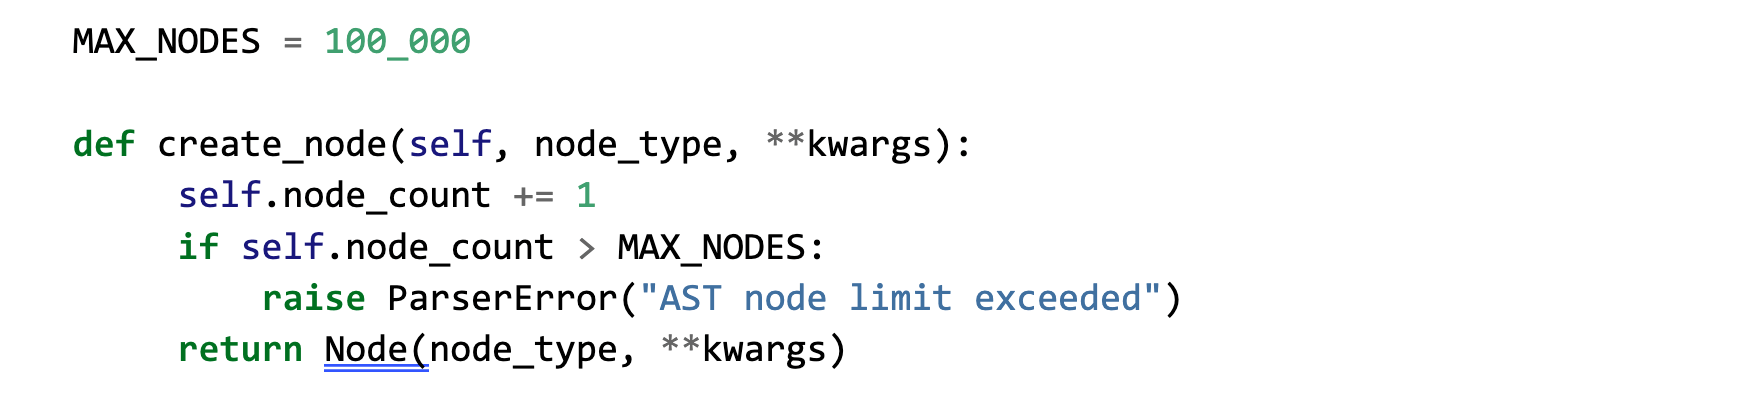
2. AST node limit: count nodes during construction and abort if a threshold is exceeded: 

Screenshot 2026 10 05 at 2.43.08 PM

We reported both issues to the maintainers of SQLGlot and SQLFluff and contributed to the fixes. SQLGlot now enforces a configurable recursion/complexity limit during parsing (merged ahead of the v30.5.0 release), and SQLFluff adopted comparable guards. If you depend on either library, upgrade to a patched version and keep the default limits enabled. 

At the Application Level 

The bad news: not all parsers support limits. If the parser you use enforces a recursion or node limit, enabling it is the best way to mitigate these vulnerabilities. If it doesn’t, defend at the application level: 

  • Enforce input limits: reject queries before parsing based on cheap, pre-parse metrics: raw byte size, token count, nesting/parenthesis depth, and column count. These caps cost almost nothing to check and stop the pathological shapes before a single AST node is allocated. Apply them on the server, not just the client – the SQLFluff Online case shows that a frontend-only limit is trivially bypassed. 
  • Set execution timeouts for parsing operations: don’t let a single query consume a worker indefinitely 
  • Implement memory limits via container constraints (Docker –memory) to contain blast radius 
  • Rate limit query submissions, especially in multi-tenant environments
  • Isolate plugin execution: use network namespaces or sandboxed processes so a plugin crash doesn’t cascade 

Not Only SQL 

SQL parsers are not special. The root causes – unbounded recursion and object inflation – are properties of recursive-descent parsers in general. We found the same patterns in query languages built on entirely different grammars. 

Cypher (Neo4j) 

Neo4j’s Cypher query language (~17k stars) exhibits both failure modes: 

  • Deep nesting: A query with ~1,500+ nested parentheses, lists, or maps causes the connection to hang for 240 seconds before timing out. 
  • CPU exhaustion: Parsing exhibits quadratic time on long chains of AND/OR operators. A query with 30,000 chained operators takes 172+ seconds to parse, with a peak heap of ~1.3 GB and worker-thread starvation – a small input that pins a worker for minutes. 

GraphQL 

GraphQL (~20k stars) is the instructive counter-example: the spec supports a max_tokens limit, but whether it’s enforced by default varies by implementation. 

  • graphql-java – ships a sensible default 15,000-token limit. But even that budget is enough for ~1,800 fragments (~50 KB) to saturate CPU for several minutes on every request. A default limit helps, but the threshold still has to be tuned to resource cost, not just token count. For further reading, see our write-up on remote DoS attacks against graphql-java. 
  • graphql-js (no token limit by default) – a single unauthenticated POST expands a 6.9 MB payload into ~1.77 GB RSS (~256x amplification) and blocks the worker for ~14.6 s. Under –stack-size=65500 (common in production) it crashes outright. Confirmed against Apollo Server v5.5.1. 
  • graphql-core (Python, no token limit by default) – ~7 MB expands to ~2 GB RSS (~276x amplification), blocking the worker for ~23.4 s. A payload under 1 KB triggers a RecursionError at depth ~300. 

The takeaway: this is a parser-design problem, not a SQL problem. Any parser that turns untrusted text into a rich object tree without bounding depth or node count is exposed. 

Conclusion 

We disclosed vulnerabilities in SQLGlot, SQLFluff (CVE-2026-46373, CVE-2026-46374), and several downstream applications – all stemming from the same root cause: parsers that trust their input to be reasonable. Beyond reporting, we worked with both maintainer teams and contributed to the fixes that now ship upstream, so every project depending on these libraries benefits by upgrading. The fixes themselves are straightforward: depth limits, node counting, input size validation. But the lesson is broader. 

Parsers have quietly become critical infrastructure. They’re embedded in data platforms, CI/CD pipelines, AI agents, and production workflows. Yet they’ve historically been treated as safe, deterministic utilities that “just work.” Our findings show that even syntactically correct queries can be weaponized to dismantle the systems that depend on them. 

As the industry moves toward automated SQL generation and LLM-integrated data tools, the parser is no longer a passive utility – it’s an active attack surface. Hardening it requires the same discipline we apply to any other trust boundary: validate input, limit resource consumption, and assume that anything coming from outside the system is potentially adversarial. 

It’s time to move beyond SQL Injection. Welcome to Parser Exhaustion. 

The post The Hidden DoS Vector in SQL Parsers appeared first on Blog.

  •  

Denmark Says Attackers Accessed CPR Data for 8.8 Million People via Company Account

Unauthorized parties have gained access to the names, addresses, and personal identification numbers of about 8.8 million people, living and dead, in Denmark's national population register, the country's digitalization ministry said on October 5. They used a private Danish company's lawful right to look up records in the Central Person Register (CPR). The ministry has told people never to

  •  

ClickFix Smuggles Payloads Through Browser Cache to Bypass Windows Run Limits

A new type of ClickFix attack is using compromised websites to trick users into executing a malicious payload cached in a web browser's cache. "Instead of downloading and executing remote payloads like the typical attack pattern, in this attack, the websites pre-fetch a script payload into the browser cache disguised as a PNG file," the Microsoft Threat Intelligence team said in a post on X.

  •  

Atlassian warns of critical file access flaw in its datacenter products

Atlassian has told its users to patch its datacenter products, pronto, to prevent attackers accessing their files. The Australian collaborationware company on Monday sent users an email that opens with the words “Action required” and points to a security bulletin that explains CVE-2026-21589. The 9.3-rated arbitrary file access vulnerability is present in the datacenter versions of its Bitbucket, Confluence, Jira Service Management, Jira Software, Bamboo, Crowd, Crucible, and Fisheye products. Atlassian says the vulnerability “allows an unauthenticated attacker to access specific files within the web application root directory in affected versions.” That’s scary because Atlassian warns “In some configurations, there may be sensitive files present that increase your risk.” There’s also some good news in that attackers must know the exact filename and path to exploit the vulnerability, and the mess doesn’t allow anyone to see the contents of a directory. Another piece of good news is that Atlassian has updated its products – so users only need to find a change window in which to upgrade to a safe version of their software. Atlassian advised those who can’t patch ASAP to remove their instances from the internet, if possible. “Instances accessible to the public internet, including those with user authentication, should be restricted from external network access until you can take action,” the company warned. Its advisory also includes mitigations and advice on how to determine if your instances need the fix. Users who made the move from datacenter products to the Atlassian cloud have nothing to do, as Atlassian fixed the flaws in its own SaaS. That state of affairs rather vindicates Atlassian’s 2020 decision to stop developing its low-end server products and require users to shift into its cloud, and last year’s sequel in which it decided to discontinue its datacenter software, too. Atlassian admitted it hasn’t made that migration easy, because it somehow released a lift and shift tool that was worse than an earlier version. In March 2026, Atlassian axed ten percent of staff. The company’s share price was on a year-long slide at the time, as pundits suggested it might fall victim to the SaaSPocalypse, a theory that AI would replace business software. The price of Atlassian scrip has tripled since then, suggesting investors are more confident the company’s plan to use AI to power workflows represents a moat LLMs cannot cross. ®

  •  

Security researcher claims they found KVM guest-host escape flaw

Linux KVM, the hypervisor favoured by hyperscale clouds, apparently has a full VM escape bug. That nasty news came from security researcher Paulos Yibelo, who on X shared a screenshot of a bug bounty award he won for discovering what he described as “Full VM escape zeroday (guest>host root in industry standard hypervisors)!” The bug bounty Yibelo participated in is run by Vercel, a company that provides MicroVMs as sandboxes for AI agents to work inside. The company’s Sandbox uses Firecracker MicroVMs, a technology created by AWS, which relies on Linux KVM – the kernel level hypervisor in Linux. Vercel CEO Guillermo Rauch named KVM as the hypervisor identified by Yibelo. “We’ve confirmed a KVM 0day through our Vercel Sandbox bounty program. Affecting the industry’s gold standard solution for Linux virtualization,” he wrote. And that’s all the info that has made it into the public view at this time. The Register can find no chat on relevant mailing lists. We have asked Rauch and Yibelo for additional details. Hopefully, we don’t hear from either of them for days or weeks, for two reasons. One is that guest-host escapes are the nightmare virtualization scenario because they mean whoever runs a guest VM could take over an entire server, and perhaps gain the ability to control other guests. The other is that KVM is astoundingly prevalent: AWS and Google both use it to power their public clouds. Enterprise virtualization players Nutanix, HPE, and Proxmox also rely on KVM. And of course KVM is also in Firecracker, which is open source and could therefore be running in all sorts of places. Whatever Yibelo discovered therefore very much needs a responsible disclosure process, because if hints about the flaw emerge it could allow attackers to do a lot of damage. Once a fix is found, the next question is whether implementing it will require disruption or downtime. It’s possible to hot-patch KVM, and to migrate live VMs from vulnerable hosts to machines running a patched version of Linux. Hopefully those techniques will work. This might be the second nasty bug discovered in KVM this year, after the so-called Januscape flaw. Beyond the potential risks this bug created, observers have suggested the potential seriousness of the flaw means Yibelo’s reward should exceed the $50,000 available under Vercel’s bug bounty program. ®

  •  

AWS Continuum sets a new standard in autonomous code security

As AI models become more capable, they uncover more security vulnerabilities and identify increasingly sophisticated paths to exploit them, raising the bar for how quickly defenders must respond. Security teams now face more potential vulnerabilities than their existing processes were designed to handle — each requiring investigation, reproduction, and a repair that must be tested to confirm it closes the vulnerability without breaking expected behavior.

AWS Continuum for code vulnerabilities accelerates this work with autonomous security at machine speed. To measure Continuum against a concrete public standard, we chose CyberGym-E2E, which asks an agent to find a vulnerability in a real codebase, demonstrate it with a working proof of concept, and repair it without breaking behavior covered by the project’s tests. Continuum passed 819 of 920 tasks within the benchmark’s 90-minute limit, achieving an 89.0% end-to-end success rate. This establishes a new standard 23.1 percentage points up from the previous public high of 65.9%.

Measuring the full vulnerability lifecycle

Many security benchmarks test a single task in isolation. Detection benchmarks test whether a system can identify suspicious code, while patching benchmarks begin with a known flaw and ask for a fix. CyberGym, the predecessor to CyberGym-E2E, also begins with a known vulnerability and focuses on exploit generation. By contrast, CyberGym-E2E evaluates the full vulnerability lifecycle, requiring a system to identify and demonstrate a vulnerability before producing a tested repair. This broader scope more closely reflects the work facing security teams.

Each CyberGym-E2E task places an agent in a container with a vulnerable revision of a real open-source project and the tools needed to build and test it. An agent can inspect and modify the source, but receives no vulnerability description, proof of concept, crash log, or original patch. External network access is blocked, and protected benchmark files cannot be modified. Within 90 minutes, the agent must submit an input demonstrating a vulnerability and a source-code patch. The full benchmark contains 920 tasks based on historical OSS-Fuzz vulnerabilities across 139 open-source projects. The median project contains more than 600,000 lines of code.

The benchmark evaluates each submission in four cumulative stages:

  1. S1 checks whether the agent produced an input that crashes the vulnerable program.
  2. S2 checks whether the agent’s patch prevents that crash.
  3. S3 checks whether the patched project still passes its functionality tests.
  4. S4 checks whether the patch also fixes the specific historical vulnerability selected by the benchmark.

CyberGym-E2E defines S3 as its main measure of end-to-end success. S4 is diagnostic because a repository may contain several valid vulnerabilities: an agent can find and repair a real flaw that differs from the benchmark’s selected target.

Continuum sets a new standard

Continuum for code vulnerabilities reached a new standard for every stage of CyberGym-E2E. The table below compares its performance with the previous best public results.

Stage

What it measures

Continuum

Previous public high

Difference

S1

Finds and reproduces a vulnerability

92.5%

67.9%

+24.6%

S2

Repairs its generated crash

89.6%

66.2%

+23.4%

S3

Preserves tested functionality

89.0%

65.9%

+23.1%

S4

Also repairs the benchmark’s selected vulnerability

37.8%

26.2%

+11.6%

On S3, the benchmark’s main measure of end-to-end success, Continuum passed 819 of 920 tasks. Its 89.0% success rate exceeds the previous public high of 65.9% by 23.1 percentage points. The result reflects both the capability of the underlying frontier models and Continuum’s design as a multi-agent security system. The next section examines how that system adds value beyond the models alone.

The official 89.0% result applies CyberGym-E2E’s 90-minute limit. When tasks were allowed to continue beyond that limit, Continuum’s end-to-end pass rate reached 93.7%, indicating higher potential coverage when longer-running analyses can complete.

We conducted the evaluation under CyberGym-E2E’s network-isolation and submission-review requirements. External retrieval was blocked during execution, and post-run trajectory review confirmed that successful results came from vulnerability analysis rather than retrieval of public historical fixes.

Harness design for end-to-end security

Continuum for code vulnerabilities is a multi-agent system organized around the main phases of the code vulnerability lifecycle: discovery, validation, and remediation. Each phase uses specialized agents adapted to the evidence and decisions it requires. The system carries evidence forward so that each phase builds on the work completed before it.

During discovery, Continuum analyzes the repository and develops candidate vulnerability findings. Its agents identify code paths that warrant deeper investigation and record the source evidence supporting each candidate.

During validation, specialized agents attempt to turn a candidate finding into a demonstrated security issue. They construct a proof of concept, run it against the vulnerable program, and determine whether the observed behavior supports the finding. This converts a potential code-level weakness into executable evidence.

During remediation, agents trace the vulnerability to its root cause and produce a patch. Continuum then verifies that the patch prevents the demonstrated failure and that the project’s functionality tests continue to pass. The repair is therefore evaluated against the same evidence used to establish the vulnerability.

Together, these phases create a connected record from suspicious code to a demonstrated vulnerability and tested repair. The architecture allows Continuum to adapt its tools, instructions, checks, and models to each phase while maintaining a consistent standard of evidence. It also supports a multi-model approach that can leverage complementary strengths and incorporate new models as they become available.

In customer environments, Continuum can also combine code-level evidence with available deployment context, including service exposure, network paths, permissions, and configuration. This context helps distinguish vulnerabilities with limited production impact from exposures that demand immediate action. CyberGym-E2E evaluates the code-level process but does not provide deployment context, placing this broader prioritization capability outside the benchmark’s scope.

Beyond CyberGym-E2E

CyberGym-E2E advances security evaluation by turning a complex, multi-stage process into a large public benchmark with reproducible tasks and outcomes that can be verified by running code. The CyberGym-E2E authors’ careful work on task construction, scoring, and submission standards gives the field a concrete foundation for measuring end-to-end progress.

To keep evaluation consistent and reproducible across 920 tasks, CyberGym-E2E focuses on memory-safety vulnerabilities in C and C++ projects. Sanitizer-detected crashes provide objective evidence of a defect, while subsequent checks determine whether a repair blocks the proof of concept and preserves functionality covered by the project’s tests. This design necessarily leaves many languages and vulnerability classes outside the benchmark’s current scope, including many of the most common and impactful bug classes observed in production systems. Evaluating these areas will require different task environments and equally rigorous forms of validation.

Our view of end-to-end security also extends beyond producing a tested code-level repair. In production systems, deployment context such as service exposure, network paths, permissions, and configuration often determines whether a vulnerability presents limited risk or demands immediate action. Future evaluations should test whether autonomous systems can reason about this context and prioritize findings according to their effect on the safety of the deployed system.

CyberGym-E2E’s value extends beyond the dataset itself. It makes the case that end-to-end security is worth defining and measuring as a task in its own right. That involves hard design choices about scope, evidence, and what counts as success, and CyberGym-E2E gives the field a concrete starting point for working through those choices. This system-level view complements our work on the Deception Benchmark, which evaluates a narrower but related capability: how reliably individual frontier models distinguish real vulnerabilities from safe code. Together, they examine security performance at both the model and system levels.

To learn how AWS Continuum for code vulnerabilities helps teams discover, validate, prioritize, and remediate vulnerabilities at machine speed, visit the AWS Continuum product page.


Alexander Greaves

Alexander Greaves-Tunnell

Alec is a scientist working on the design and evaluation of AWS Continuum for code vulnerabilities. At AWS, he has led projects across search, security, and observability that bring the AI state-of-the-art to complex application domains beyond the expertise of existing models. His academic background is in statistics.

Neha Rungta

Neha Rungta

Neha is a scientist and builder who has spent her career making machines reason about complex systems at scale. Her work spans automated reasoning, formal verification, security, and AI, shaping systems including Cedar, IAM Access Analyzer, and Continuum. Today, she is forging the next generation of machine reasoning, combining LLMs, formal methods, and agentic systems.

  •  

Citrix NetScaler security snafus get even worse amid more 0-day reports

The attackers just keep coming after Citrix NetScaler appliances, as both the feds and private security researchers warn that someone found - and has already exploited - yet another Citrix bug before it had a patch. This latest vulnerability, tracked as CVE-2026-88779, is a memory overflow bug that leads to denial of service attacks. It only affects NetScaler ADC and Gateway appliances configured as a SAML (Security Assertion Markup Language) service provider or identity provider, used for single sign-on authentication. Late Friday, amid exploitation reports, Citrix confirmed that it was investigating a “newly observed issue related to SAML authentication in customer-managed NetScaler deployments.” By Saturday night, the vendor released a security advisory for NetScaler ADC and NetScaler Gateway with patches, urging vulnerable customers to “install the relevant updated versions as soon as possible.” Citrix also posted a blog about the vulnerability, confirming that it has observed targeted attacks on unmitigated NetScaler deployments that can lead to denial of service. Citrix did not answer our questions about CVE-2026-88779 - including how many instances have been affected and what attackers are doing after exploiting the bug - but urged customers to "quickly apply" the fix to NetScaler instances. "We were recently alerted to a new issue that affects service availability for some NetScaler deployments," a Citrix spokesperson told The Register. "After we were alerted to this issue we immediately developed and published a mitigation while concurrently developing, testing and deploying a fix." On Sunday, the US Cybersecurity and Infrastructure Security Agency (CISA) confirmed CVE-2026-88779 was under active exploitation and ordered federal agencies to patch the bug by Wednesday. While the new vulnerability is not technically related to the earlier eight CVEs finally disclosed by Citrix on September 27 - weeks after miscreants began abusing two of these security holes (CVE-2026-88772 and CVE-2026-88771) - watchTowr researchers told us they suspect it has been used to purposefully crash machines, making exploitation of CVE-2026-88771 faster. “This vulnerability is incredibly simple to trigger, with a single specially crafted request being all that is needed to knock an appliance offline,” watchTowr’s head of threat intelligence, Jake Knott, told The Register. “Exploitation is already occurring in the wild, and disrupting an authentication gateway can prevent legitimate users from accessing the services behind it.” WatchTowr reproduced the vulnerability on Friday, and Citrix credited the attack-surface management company along with Bishop Fox with helping it address the issue. “Citrix provides an indicator-of-compromise script that teams can run to check exposed appliances for signs of compromise, though a clean result is not definitive proof,” Knott said. “Security teams should prioritize appliances configured as a Gateway or AAA virtual server with SAML authentication enabled, and affected organizations should apply the fixed build or Citrix’s interim mitigation if an immediate upgrade is not possible.”®

  •  
❌