❌

Reading view

Lessons Learned From 'AdFection' and What To Do Next

Last week, researchers at Citizen Lab revealed a horrifying new malware campaign, dubbed “AdFection.” It used an ad network to distribute spyware to journalist’s devices to infect them without the target ever needing to click anything. This sort of attack on journalists is dangerous and incredibly concerning, especially since it’s built on the backbone of a technology we already object to: behavioral advertising. Although this type of attack has only been described targeting journalists, you can take a few steps we outline in the next section to mitigate the risk no matter who you are.

A few factors combined to make this attack a noteworthy first-of-its-kind. First, it utilized the surveillance ad-tech ecosystem to specially target the malicious code. Second, the spyware it delivered was so-called “zero-click,” meaning it required no interaction from the user to be infected: all that is required is for the ad to be delivered and code bundled along with it to be run, which happens automatically. Neither malvertising nor zero-click attacks are new on their own. What’s novel about the AdFection attack is combining them, creating a highly targeted, extremely dangerous attack which is difficult to defend against and even harder to detect.

Let’s take a deeper look from the perspective of one of the Windows devices supplied to the researchers from Al Jazeera. Here’s how the report describes the infection happening: 

  • Someone browsing the web or using an app on that machine is served an ad created by Discover-Tech, a company exposed in the report as “purporting to be a legitimate advertising company, [but] appears to be a front for large-scale ad espionage abuse.” 
  • The ad contains a small snippet of JavaScript code which is automatically executed when rendered in the app or website. 
  • This code reaches back out to a Discover-Tech server, referred to as their “NOAS server,” with detailed information about the machine rendering it: its cookie-set advertising ID, IP address, and more.

So far, nothing particularly unusual has happened. Ads that contain JavaScript code and reach back out to their servers with lots of information on your device—and by extension you—are commonplace. It’s all part of the data-driven advertising ecosystem. What happens next is more interesting:

  • The NOAS server uses this detailed information to determine it is an Al Jazeera machine requesting the ad. 
  • Instead of returning an empty response (as it does most of the time), it responds with a malicious, zero-click spyware payload. That payload was created by Discover-Tech’s partner Candiru/Integrity Labs, a company previously exposed for involvement in sophisticated malware attacks. 
  • The payload is then executed and infects the targeted machine.

Companies targeting zero-click malware attacks against journalists might seem like the plot of a blockbuster spy thriller. But this attack was enabled by the everyday practices of ad-tech companies, which unfortunately have extreme latitude in the collection of users’ data. By leveraging the tracking identifiers and data collected on devices for the purpose of delivering targeted ads to specific individuals, mercenary spyware companies can repurpose this data in order to fine-tune who they infect—and hide that they’re doing it from everyone else. 

Most ads are not delivered directly by the ad creators, but rather by intermediaries that facilitate Real-Time Bidding auctions. Nonetheless, winning bidders are given the ability to execute JavaScript code in the browser of the person who receives the targeted ad. This allows for interactive ads to be displayed, but also (as we’ve seen) for the compromise of a device just by delivery of malicious code.

While the different components in this attack chain are not novel on their own, the exposure of this combined attack is significant because it reveals a technique to hyper-target individuals and organizations for infection. Luckily, there are steps you can take to protect yourself from the myriad of dangers presented by the ad-tracking industry. Here’s how.

What You Can Do About It

As we work towards fundamental fixes to the ad ecosystem and banning online behavioral ads altogether, the onus is on all of us to protect ourselves. This is especially important for higher risk individuals or journalists working in states with heavy surveillance. Citizen Lab outlines several steps, depending on your threat model, to take to help protect yourself:

These steps can be very helpful in protecting yourself, but there is only so much you can do as an individual. Banning behavioral ads like this would be a good place to start. Behavioral ads aren’t just a privacy nightmare as designed. They are the perfect vehicle for malvertising and similar threats, just as we see here.

  •  

The Vulnerability Apocalypse and Why We Should Fund Open Source

If you use the internet at all, you may have noticed that a large percentage of sites suddenly went down earlier this week—and all your nerdiest friends were talking about "The Vulnerability Apocalypse” and this thing called PHP that powers nearly 70% of the websites on the internet. You may find yourself wondering: what is PHP, what just happened, what is the vulnerability apocalypse, and what do I need to do?  

To find out what you can personally do read the first blog post in this series!  

What Is PHP?  

PHP is a programming language used mainly to create interactive websites. Facebook, Wordpress, Wikipedia, Etsy, and other major sites all use or were originally built on PHP. It is a long-established mainstay of web development. But because it is open-source, maintenance of these critical systems depends on a small number of volunteers working on this in their free time. The disaster scenario that happened this past week is the perfect example of why we need more money and people supporting open-source projects. Corporations should be contributing both. 

What Is the Vulnerability Apocalypse?  

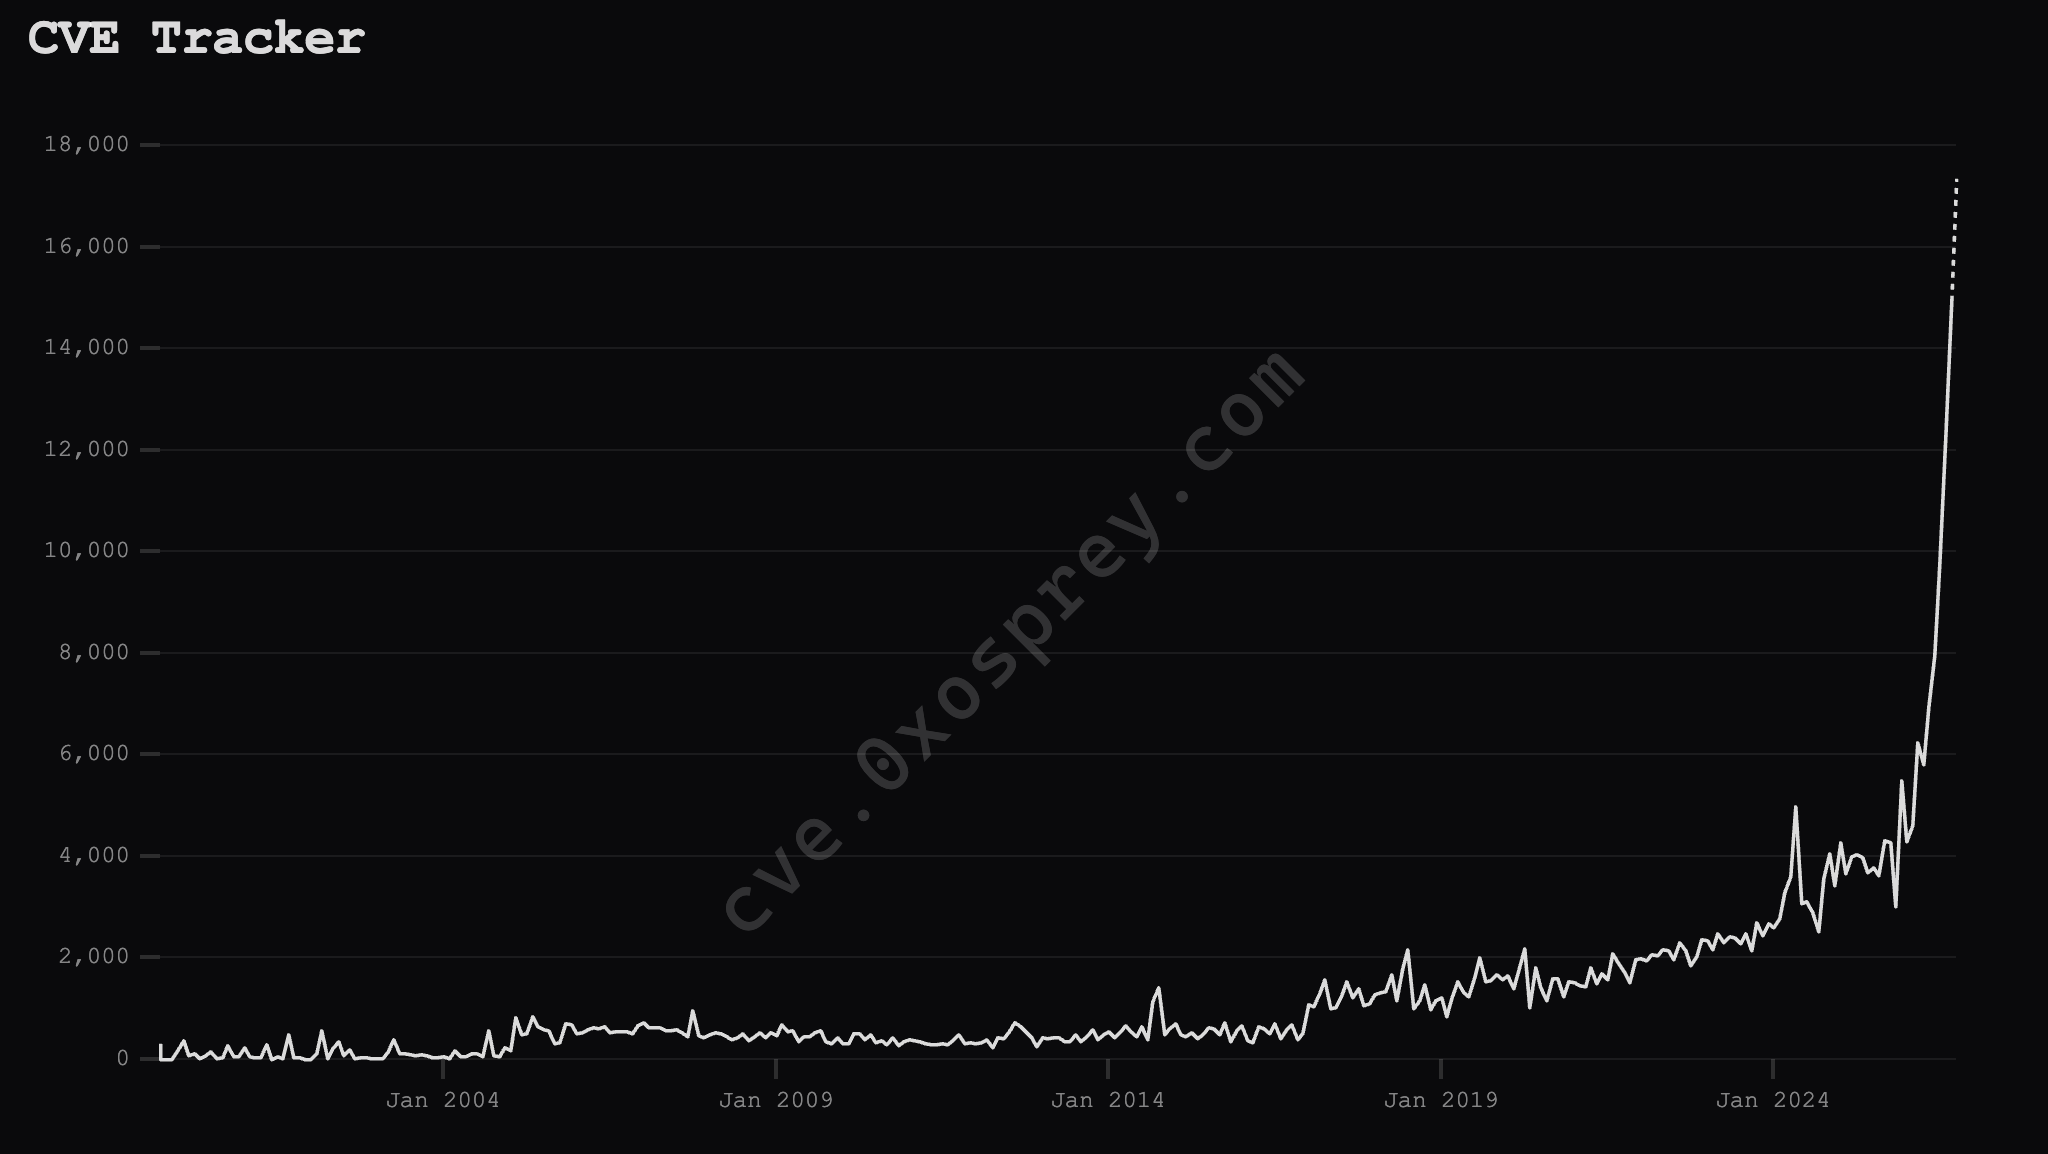
Common Vulnerabilities and Exposures (CVEs) are the way that security professionals file reports about vulnerabilities in software. The National Vulnerability Database (NVD), run by NIST, is the official national database of CVEs. In other words, CVE reports managed by NIST are the closest thing we have to a canonical database of security vulnerabilities in software. The NVD currently has around 400,000 CVEs that have been filed and accepted since 1988. In just the month of October, 13,000 new CVEs have been submitted. This means that 3% of critical software security bugs that have ever been officially logged were found in the last month alone. And it's likely that by the end of the year over a quarter of the software vulnerabilities that have ever been found will be from 2026.  


a graph showing the number of computer vulnerabilities by week since 1990, increasing exponentially in the last couple months.

Computer vulnerabilities reported are rising exponentially. Source: CVE Tracker

This research is being driven almost entirely by the cybersecurity capabilities of major AI models from companies like Anthropic, OpenAI, and Google. Historically it has been popularly assumed by cybersecurity experts that finding unknown (zero-day) exploits in any specific project and turning them into exploits was expensive. The knowledge to discover them was not widespread, and it was a hard task even for those initiated into the arcane ways of vulnerability hunting. Google even dedicated an entire team to it.  

But now thanks to major AI models, vulnerabilities are cheap, and anyone of moderate technical skill with a few dollars and access to a frontier AI model can find vulnerabilities in a few minutes. For example, recent vulnerabilities in PHP were found with a prompt to an AI model that literally said "find bad vulnerabilities in PHP."  

What Happened This Week? 

In 2024, a potentially severe vulnerability in PHP was discovered during an external security audit. PHP’s maintainers couldn’t agree on a solution, but more importantly, they couldn’t find a way to exploit the vulnerability. Because it didn’t seem like an active threat, they ended up deprioritizing a fix in favor of working on more urgent security issues. Then, in August 2026, security researchers working with the latest models from OpenAI and Anthropic independently discovered the vulnerability again, and another one—and now, with a way to exploit them.  

We now know that the vulnerabilities were so severe that they would have allowed even moderately inventive hackers to take over any website that uses PHP and then steal customer data, launch further malware attacks, spy on users, take websites offline, or launch a massive denial of service attack.[1] 

Because of the severity of these vulnerabilities, several of the involved researchers got together with the makers of PHP to patch the vulnerabilities and disclose them in a coordinated manner. The idea was that hopefully everyone would get a chance to quietly release and then apply fixes for the vulnerabilities before the whole world found out about it. 

But news already started to leak on October 20th. There was a post on a widely read forum “Hacker News” and other posts elsewhere. One of the researchers accidentally published a video early. Companies reported seeing active exploitation of the vulnerabilities going back as far as October 17th. On October 21st, six hours before the planned press embargo, one company, Chainguard, jumped the gun and released a patch early, essentially giving anyone instructions about exactly where to find the vulnerabilities and how to weaponize them. This sent system administrators everywhere scrambling to patch their systems before they were taken over by hackers. And it’s going to take a long time to patch all these systems. At the time of this writing over 33 million websites are still running on vulnerable versions of PHP.  

The internet is run largely on open-source software, mostly maintained by a small handful of skilled volunteers occasionally getting a small stipend, not by major corporations and highly paid engineers. These are projects you have perhaps never heard of, like PHP, OpenSSL, and SQLite, but these programs run on nearly every computer in the world and are maintained by teams as small as one person. When a vulnerability is found in these projects, it can be devastating.  

PHP isn’t the only critical open-source software with a high severity vulnerability this week either. Other widespread open-source projects like Node.js and GitLab also had severe security bugs reported.  

The small number of already overworked open-source maintainers are now facing a deluge of vulnerability reports, some of which are false, but many of which are very real. Burnout in open source has never been higher.  

We Need Stronger Support for Open Source Projects

Much of the foundation for the modern multibillion-dollar internet industry is built on open-source products that were created and still maintained—for free—by dedicated volunteers in their spare time. It’s an imperfect system, and it can lead to errors.  

One of those critical, under resourced open-source products is PHP. And while vulnerabilities in PHP were privately found years ago, they were left unfixed because they didn’t seem as impactful as other bugs at the time. These same vulnerabilities were recently rediscovered and proved to be trivially exploitable by security researchers using advanced AI models. While in the middle of the widespread, global effort to correct this mistake and deploy fixes, the problem was leaked by some of the security researchers who had gotten early access to the fixes. Unfortunately, this left millions of websites, ranging from personal blogs to government sites, vulnerable to hacking that could result in data theft, malware distribution, and worse.  

Open-source projects like PHP and others are the backbone of the entire internet. If they don’t get the resources they need, they and the internet they power, are at risk of falling apart. Corporations (whose products would not exist without these products) should be actively contributing to their maintenance. 

1. A technical analysis of the vulnerabilities is out of scope for this post and has already been written by the original researchers.

  •  

Secure Messaging and AI Remain In Conflict Despite the Promise of TEEs

Secure messaging platforms, like Signal, WhatsApp, and recently, encrypted RCS, operate on a straightforward assumption: the content at each end of a conversation is private to the participants in the conversation. End-to-end encryption helps provide the mathematical guarantees that the companies who operate these messaging platforms cannot access the contents of messages. But there’s no way to guarantee what happens once the message arrives on a phone. As more devices and services introduce more artificial intelligence (AI) features into messaging apps, that line begins to blur. 

When AI features are computed entirely on device, it’s less concerning. Yet sometimes the computing requirements are heavy enough that the computation has to be done on a company server. Tech companies tell us they have a solution for this: trusted execution environments (TEEs). But do server-side TEEs really solve the problem?

TEEs exist to serve many different functions, ranging from digital rights management (DRM) content protections to securely storing information in your phone's mobile wallet, but for our purposes, we’ll be focusing on how tech companies use them for their AI tools. 

The basic idea is straightforward: most consumer devices aren’t powerful enough to handle the sorts of AI features companies want to offer, so sometimes they send data off your device to more powerful cloud servers to do the computing, then display the results on your device. Since your data is leaving your device, there’s a privacy compromise. For example, if you ask for a messaging app to summarize a conversation, it may offload that computing power to a cloud server, sending the entire contents of your messages to the cloud, then back to your phone.

TEEs supposedly offer a way to keep those requests private. There are several implementations out there, like Apple’s Private Cloud Compute, Google’s Private AI Compute, and WhatsApp’s Private Processing. It’s not just the big tech players, we’ve seen chatbots built with TEEs as well.

TEEs can provide more security and privacy than simply running in the clear, but they are fundamentally different from actual encryption or running locally. Despite the promises of some tech companies, they will never be able to match that level of security and privacy. Because of that, a user’s device should never automatically send data to a TEE. Let’s dig through the reasons why.

What Exactly Is a TEE, Anyway?

A TEE is a hardened section of the computer that runs software in a way that’s supposed to be secret even from other processes running on the machine. TEEs also let users check that the code being run is the code that they think is running, and not backdoored code instead, using a process called “attestation.” You may have also heard this referred to as a “secure enclave,” or heard the brand names SGX or TrustZone.

The intention of a cloud-based TEE is simple: a company can run a server in their data center, but still process data that you provide on your behalf without being able to see that information themselves.

Is a TEE Secure?

In practice, we've seen multiple cracks and hacks every year that show that it is possible to get at that data. That’s because while encryption relies on math, TEEs rely on engineering to provide their security. Standard encryption algorithms are created by years-long processes collaboratively produced by mathematicians around the world and are based on problems that have been studied for decades. The math is reliable, and there is no shortcut to breaking it that would not also upend fundamental understandings of mathematics as a field. 

The collective understanding of every mathematician in the world is that standard encryption algorithms are not breakable to the best of the world’s collective knowledge. No responsible engineer builds a system based on a new encryption method until after it’s been offered up for prodding.

Engineering, on the other hand, doesn’t work like that. Every individual system is the product of a group of engineers who put it out into the world, and each product will have its own quirks and bugs that have to be individually discovered and patched. These bugs are found after the system is built, not before. No one has yet built a system that is unbreakable. On the contrary, there is new research all the time that finds new ways to break into TEE systems. They’re patched as they come up, but they’re unlikely to ever become perfect, and certainly not any time soon. 

TEEs in particular are a hard engineering problem because the encryption key is physically right there on the device. Building a TEE means keeping a key fully separate and inaccessible while it’s on the same physical device as parts of the system that shouldn’t have access to the key.

Many attacks on TEEs involve “side channels.” In a side channel attack, the attacker measures the electrical impulses or other effects to figure out the timing of operations inside the TEE, then uses that to figure out the key being used. Once they have the key, they can read all the data. Compare that to end-to-end encryption, where the key is never on that machine in the first place, so an attacker would have to also run a similar attack on the user’s device.

Companies who turn to TEEs to protect data want to both have the key on the server and have it protected while still performing complex operations like running an LLM, which makes it much more difficult to protect those keys.

That being said, a TEE versus plaintext on a server is the difference between being able to easily read the data and having to do a bunch of specialized work to get at the data. That work often involves accessing the physical machine. This is most relevant for protecting against mass surveillance, and for many people, that might just be enough security.

But that's the core of the problem. “Secure enough for most cases” and “encrypted as in math” are not the same thing, and it’s important not to conflate the two. And services that currently offer “encryption as in math” have a real downgrade in security when they switch to security based on TEEs. 

If you want to dive into the myriad security issues and limitations of TEEs we’ve seen so far, they’re well documented here, here, here, and here.

What Does This Have To Do With LLMs and AI?

Sometimes organizations want to offer an LLM that can respond to queries in a private manner. On-device LLMs exist, but they’re limited in size. So, when organizations want to offer the ability to answer queries without being able to see the conversation, they turn to TEEs. That’s a useful way to run a chatbot that’s reasonably private. This is what Apple, Google, WhatsApp, and others are doing.

Why not turn to encryption? After all, LLM inference is just a bunch of math like any other things a computer does. It takes input to a (really big) function and gives an output. We have the math to do that computation in a way that hides the inputs and outputs from the one running the computation, it's just super expensive. It’s called homomorphic encryption, and no one’s figured out how to do it fast enough that it makes sense for this sort of computation.

Instead, the allure of a TEE is that it will run that computation for you inside of a special opaque section of a server. TEE manufacturers try to make it as hard as possible for the person running the TEE to peek inside. But you still have to trust the operator to not put a stethoscope to the box to try to figure out what's happening inside. 

In this case, it’s reasonable to consider these systems “privacy-preserving,” but not “encrypted.” That distinction is important, especially when we talk about how the TEEs interact with secure messaging. When someone using an end-to-end encrypted chat app asks an LLM to summarize, review, or store those messages, the content of those messages is leaving the device and going to an unencrypted third-party server somewhere. That’s a major threat to the privacy of secure chat apps, and one that’s increasingly hard for users to take control of.

How Does This Translate to Practical Advice?

The answer to this is going to vary based on an individual’s threat model, but a good rule of thumb is that a user’s device should never automatically send data to a TEE. When the person holding a phone can choose what information is sent, even if it’s a chunk of data like “unread messages,” they have the opportunity to pause and consider if that data might be too sensitive to risk sending.

In contrast, when data is sent automatically, the automatic sending becomes a feature of the system as a whole. If the system was previously end-to-end encrypted, adding automatic exfiltration makes the whole system no longer end-to-end encrypted.

Developers: don’t build systems that automatically send data off a device to a TEE, especially when it’s coming from an app that is otherwise end-to-end encrypted.

Users: if developers ignore us and build that system, turn off any automatic data sending features. Take a second to think about how much you’re willing to risk sending data when you choose to send it off the device.

So, What Should I Be Concerned About?

TEEs are useful for security in a number of circumstances. Your phone likely has a TEE where it keeps the key that encrypts your biometric unlock data and the base of the keychain where passwords are stored. It also enables certain backup systems, like how you can restore a phone with your passcode or restore WhatsApp or Signal backups.

But when we’re talking about cloud processing, it’s important to be clear this isn’t the same as end-to-end encryption and doesn’t offer the same level of privacy. 

Most of our private lives are on our phones and in our messages. We’ve worked for years to secure those messages, with major wins like encrypted RCS, and the continued user experience improvements of Signal and WhatsApp. We’ve even seen real improvements to backup security with features like Advanced Data Protection that bring end-to-end encryption for a variety of data outside of messaging, like notes and photos. 

But as companies roll out AI features that interact with these encrypted services, pulling data off devices and into a cloud-based TEE, they’re eroding the privacy protections of end-to-end encryption and risk causing serious confusion around what data is protected and what isn’t.

  •  

Developers: Beware of Ad Libraries that Betray Your Users’ Location Privacy

Across mobile platforms, advertising companies provide developers with software development kits (SDKs) that make it easy to monetize their apps. But those same SDKs can automatically feed users’ location data into ad systems that location data brokers use to track people. Many developers may not even be aware of this privacy violation, let alone the users who are directly affected.

When developers let advertising SDKs collect location data, they’re putting users at risk of more than just creepy ads. Location information sourced from the advertising industry has been used for ICE investigations, global spy tools, outing a gay priest, tracking union organizers, and tracking US military personnel.

Defaults matter, not just for users, but for app developers as well.

An EFF investigation has identified several advertising SDKs that publicly acknowledge collecting and sharing users’ location by default when embedded in Android apps granted location permissions. Defaults matter, not just for users, but for app developers as well. If app developers don’t pay close attention to the location-sharing settings of their advertising tools, they could inadvertently expose users’ location information.

This report explains how advertising SDKs can facilitate and encourage location data sharing through privacy-invasive defaults, financial incentives, and unclear documentation.

Contents:

Data Brokers Harvest Location Information From Advertising Systems

When an advertising SDK collects and shares location data, it becomes part of a larger ecosystem that can include advertisers, ad tech companies, and location data brokers. EFF began investigating the location-sharing practices of various advertising SDKs to better understand the pipeline from mobile apps to location data brokers.

Location data brokers sell information on the precise movements of billions of people without their knowledge or meaningful consent. This data is primarily sourced from apps on people’s phones. Some apps partner with data brokers directly, using data-broker-developed SDKs or server-to-server transfers to sell users’ location data. Other apps leak users’ location data through advertising SDKs serving behaviorally-targeted ads through “real-time bidding” (RTB). In the process of auctioning off ad space, ad tech companies can broadcast user data to thousands of potential advertisers. Location data brokers have participated in these auctions not just to bid on ad space, but to collect personal information contained in bid requests. 

Indiscriminate data sharing through RTB can lead app developers to unknowingly share their users’ location with data brokers. In 2025, a hack of location data broker Gravy Analytics revealed thousands of apps that may have been sources of its data. When journalists reached out to the app developers, many claimed they had no relationship with or knowledge of Gravy Analytics. To prevent location information from being shared with data brokers through RTB, developers must understand the location-sharing practices of their advertising SDKs.

How Advertising SDKs Leak Location Data

Developers don’t have to manually, or even intentionally, share location data for it to be broadcast through RTB auctions. Once a user grants an app permission to access their location, SDKs embedded in the app receive the same access—there are no SDK-specific location permissions. That means advertising SDKs can automatically collect users’ location data and share it in bid requests.

While apps and SDKs can estimate a users’ approximate location from their IP address without requesting any permissions, location permissions provide access to estimates that are more accurate and revealing. Precise location permissions give apps (and their embedded SDKs) access to location estimates within about 160 feet, but sometimes as accurate as 10 feet. Approximate location, a separate permissions level, gives apps access to a location estimate within about 1.2 square miles. 

Developers and advertising SDKs also have a financial incentive to share location data, since it can increase bid prices for an app’s ad space. While many advertising SDKs require developers to configure a setting before collecting and sharing users’ location data in ad requests, this is not always the case. EFF found several advertising SDKs who publicly acknowledge sharing users’ location data by default when embedded in apps granted location permissions. 

EFF Identified Advertising SDKs That Share Location Data by Default

EFF reviewed the public developer documentation of dozens of widely-used advertising SDKs to identify how they handle and communicate with developers about location data. In the following sections, we highlight four advertising SDKs who engage in a particularly egregious practice: collecting a user's location by default for ad targeting whenever a user has given an app location permissions. We reached out to each SDK company and the referenced app developers for comment. One company responded, and as detailed below, subsequently updated its documentation in response to our questions. Another company responded with clarifications to its developer documentation.

We chose to focus on SDKs with this privacy-invasive default because it increases the risk of developers leaking users’ location data without realizing it. Several studies have found that developers tend to stick to SDKs’ default settings. If an advertising SDK transmits location data by default, users' precise location can end up in advertising systems without the developer intentionally enabling location sharing. These SDKs have separate documentation pages that instruct developers to flag users covered by privacy laws like GDPR and COPPA for restricted data processing, but these modes are not the default. 

By analyzing how these four SDKs present their location sharing practices to developers, we hope to illustrate how the design and documentation of advertising SDKs can facilitate location data sharing at scale. Although the advertising SDKs we highlight are not the most prevalent SDKs used, they are embedded in thousands of apps and reach billions of users.

InMobi Encourages Keeping Location Sharing Enabled By Highlighting Financial Incentives

InMobi claims to reach “2B+ users across 150+ countries” and is the 10th most popular advertising SDK on Android (according to AppBrain and Appfigures at the time of publication). 

InMobi’s “Getting Started with Android SDK Integration” suggests that location sharing is enabled by default, stating “The InMobi SDK automatically forwards location signals when available.” InMobi provides developers with a setting to opt out, but explicitly recommends sharing location data. Developer documentation highlights the financial incentive for location sharing, stating “location-enriched impressions typically yield higher revenue.” 


[Observed on “Getting Started with Android SDK Integration,” 7/31/26]

Apps that use InMobi may not need location information to function or may only need access to approximate location information, but InMobi highly recommends that developers request precise location permissions “to enable accurate ad targeting.” They even encourage developers to request Wi-Fi network information permissions, which (when paired with precise location permissions) provide Wi-Fi access point identifiers that can also be used for location tracking.


[Observed on “Getting Started with Android SDK Integration,” 7/31/26]

InMobi has been accused of misleading developers over location sharing practices in the past: In 2016, they settled with the FTC over charges that they bypassed users’ location permissions for apps and tracked their precise locations through WiFi network data (Android now requires apps to request location permissions to access this WiFi data too).

BidMachine Updates Previously Inaccurate Developer Documentation After EFF's Technical Analysis Observed Precise Location Data Collection

BidMachine claims to reach over 600 million “direct SDK users.” 

BidMachine reveals that it collects location data by default on the “Advanced Settings” page of its Android SDK Integration guide, stating that the “SDK can automatically track user device location to serve better ads” as long as developers request location permissions for their app. Before publication, EFF reached out to BidMachine for comment, notifying them of our plan to highlight their Android SDK location sharing practices.  


[Observed on “Advanced Settings” on 7/31/26, before EFF asked BidMachine for comment]

After EFF reached out, BidMachine changed their documentation to clarify the practice, but not their default collection of location information once app-level permissions are granted. This updated section still fails to explain how developers can opt out of BidMachine location tracking, which is critical for app developers that require location access for core features but wish to prevent user data from being shared with advertisers.


[Observed on “Advanced Settings” on 8/3/26, after EFF asked BidMachine for comment]

Before EFF reached out, BidMachine’s “App Privacy Details On Google Play” page had stated that they only collected coarse location data and precise location data was “not collected.” However, our technical analysis of two apps, which Exodus Privacy determined include the BidMachine SDK, contradicted this claim: Network requests from the apps QR Scanner and GPS Speedometer to a BidMachine domain include precise location coordinates.


[Observed on “App Privacy Details On Google Play” on 7/31/26, before EFF asked BidMachine for comment]

After EFF reached out, BidMachine also corrected its documentation to make it clear precise location is collected by the SDK whenever the app-level permission is granted:


[Observed on “App Privacy Details On Google Play” on 8/3/26, after EFF asked BidMachine for comment]

com.appswing.qr.barcodescanner.barcodereader_bidmachine.flows

com.ktwapps.speedometer_bidmachine.flows

In response to our request for comment, BidMachine stated that it wasn't possible for them to get location information “unless the user has granted the app the relevant permission through the operating system.” They also stated that“publishers are responsible for configuring their apps' permission and consent flows.”

Verve Emphasizes Consent More in its Play Store Language Than its Configuration Guide 

Verve has claimed its HyBid SDK reaches “over 1.5 billion users across more than 10,000 apps worldwide.” 

Verve’s configuration guide for its HyBid Android SDK (formerly called Pubnative HyBid) makes clear that location tracking is “enabled by default,” stating, “If the user has given location permissions, HyBid SDK will use the available user location to provide better targeted ads.” 


[Observed on “HyBid Android SDK - HyBid Configuration,” 7/31/26]  

Verve’s guidance for data disclosure to the Google Play Store tells a more careful story. Despite the fact that location tracking is enabled by default, the Google Play Data Safety Guidance states that the SDK “does not collect or attempt to collect [location] information independently.”


[Observed on “Google Play Data Safety Guidance,” 7/31/26]  

It also emphasizes user consent, claiming the SDK will only collect location data “if the publishers allows its app to collect location data from users after obtaining user’s explicit consent to such data collection” (emphasis added). The configuration guide lacks recommendations or instructions for obtaining user consent to share location data with Verve, beyond app-level access. Instead, the configuration guide highlights the financial incentives for developers to add location permissions to their app.


[Observed on “HyBid Android SDK - HyBid Configuration,” 7/31/26]  

When reached for comment, Verve clarified that “in its current Android implementation, the SDK reads the cached network-provider location and does not use the GPS data of the end user's device. Furthermore, any geolocation data is coarsened prior to processing, ensuring that location is limited to an accuracy radius of no less than 1,850 feet.” It also said that it contractually requires apps to comply with data protection laws. 

To Verve’s credit, the HyBid SDK is open source, so careful developers can check the code instead of relying on documentation alone. HyBid’s open-source code shows that latitude and longitude coordinates are rounded to two decimal places, and that it does only collect and share network-derived location data, confirming the statement the company sent to us. If an app has precise location permissions, networked-derived location data rounded to two decimal places could be accurate within approximately 0.5 square miles, which is still more precise than the 1.2 square miles typically revealed with Android’s approximate location permission. But even coarse location data, especially when collected repeatedly over time, can reveal movements that should remain private by default.

Verve’s response also conveyed a willingness to revise their documentation: “As part of our ongoing commitment to providing clear and comprehensive developer resources, we continually review and enhance our documentation, and we will take your observations into account as part of that process.”

Huawei Highlights Financial Incentives for Location Data Sharing Before Showing Developers How to Opt Out

Huawei has claimed its Petal Ads SDK is embedded in more than 85,000 apps worldwide.

Huawei’s “Integrating the Petal Ads SDK into an Android App” guide begins with a recommendation that developers obtain location permissions to increase app revenue and an acknowledgement that location sharing will happen by default in apps with location permissions.


[Observed on “Integrating the Petal Ads SDK into an Android App,” 7/31/26]

A separate “Use of Location Data for Ads” page repeats that the Petal Ads SDK will include users’ location information in ad requests if an app has access to location information. Neither of those pages mention that developers can use the setRequestLocation method to disable the default collection of location information (this setting is referenced in the last section of the Ads SDK Compliance Guide). Huawei’s Ads SDK Privacy Statement states that “The SDK and its services will not store precise location information, and will only use it to determine the approximate device location.” However, the guide does not specify how Huawei defines approximate versus precise location data. 


[Observed on “Use of Location Data for Ads,” 7/31/26]

Location Data Sharing Can Happen Without Users’ Knowledge or Meaningful Consent 

In some cases, after an app itself obtains location permission, advertising SDKs can separately obtain and share users’ location information without their knowledge or meaningful consent. Neither app that EFF observed sharing precise location data with BidMachine (QR Scanner and GPS Speedometer) showed a notice or requested consent before doing so. Additionally, neither apps’ Google Play Store “Data safety” section includes location data under “This app may share these data types with third parties.” The lack of transparency and control that users have over their location on mobile apps is dangerous. QR Scanner and GPS Speedometer are just two examples of apps that quietly share users’ location data through advertising SDKs, but they have been downloaded more than 50 million and 10 million times, respectively. 

App-level location permissions alone cannot signal meaningful consent to location collection and sharing by third-party advertising SDKs.

Even if users’ were to grant these apps permission to obtain their location data, they would likely not expect their location data to be shared with third parties. Many users don’t know that granting location permissions to an app grants the same permissions to third-party SDKs embedded in the app, or that an app they're using contains code from outside companies. And many apps that request location permissions, like GPS Speedometer, require it for core functionality. App-level location permissions alone cannot signal meaningful consent to location collection and sharing by third-party advertising SDKs.

Location Privacy Issues Extend Beyond These Four SDKs

Our initial focus on four advertising SDKs does not mean that other SDKs adequately protect location data or that developers never choose to share location data when it’s not the default. Advertising SDKs not discussed in this report have been criticized and sued for allegations that they collect location data without valid user consent. 

The issues we’ve highlighted around privacy-invasive defaults, financial incentives, and unclear documentation extend beyond the specific SDKs we analyzed. Multiple studies have found that advertising SDKs often steer developers toward increased data collection through their design and documentation. A 2021 study found that popular advertising SDKs used dark patterns to nudge developers towards sharing more sensitive data. A 2024 study identified discrepancies between several SDKs’ documentation and their actual data collection practices. And a 2025 study concluded that developers have minimal influence over SDKs’ data transmission, often leaving them with the choice of accepting SDKs' invasive data collection or avoiding them entirely. 

Fighting Back Against AdTech Companies That Enable and Encourage Location Data Sharing 

EFF’s analysis shows that advertising SDKs don’t just allow developers to share location data–they often encourage it. Default settings, financial incentives, and unclear documentation can make sharing users’ location the easiest option for developers.

Users can take extra steps to defend their location privacy, but they shouldn’t have to. Developers, regulators, and legislators must act to stop apps from leaking users’ location to advertising companies and data brokers.

Developers

Developers should carefully evaluate all third-party SDKs they include in their apps and disable unnecessary data collection whenever possible. Regardless of advertising SDKs’ default settings, developers have a responsibility to protect their users’ location data. But protecting users’ privacy shouldn’t depend on developers reading the right piece of SDK documentation. Advertising SDKs should not make sharing personal data the default, especially for data as sensitive as a person’s location. 

Regulators

Regulators should continue to hold app developers accountable when they unlawfully share personal data and include libraries which subject users to privacy harms, as they have in the past. But they should also scrutinize the companies whose SDKs encourage these practices at scale. Otherwise, companies can continue to design SDKs that make invasive data sharing the default while shifting the responsibility and consequences to developers who include their tools. 

Legislators

The US is in dire need of a federal law to protect all Americans’ location privacy, one which doesn’t preempt stronger state privacy laws, and has a private right of action empowering individuals to sue those who violate their privacy. Countries across the globe should likewise enact legislation that protects their users’ location privacy. Everyone deserves privacy as a universal human right.

Legislators can address the root of the problem by banning online behavioral advertising. This would remove the primary incentive for companies to track and share your personal data. It would also prevent users' precise locations from being broadcast to data brokers through RTB auctions. 

Until then, developers should be wary of ad libraries that betray their users’ location privacy.

Notes on Methodology

We were interested in looking at network traffic for various Android ads SDKs that send precise location by default when granted location permissions. We chose Android for this investigation because of the relative openness of and our familiarity with analysis on the platform. We’ve used publicly available resources like Exodus Privacy and AppBrain to identify popular ads SDKs and the apps which include them.

In a lab setting, we set up a machine to view our own http(s) traffic using mitmproxy from our test device, and connect the test device to that machine in order to view our real-time traffic.  Where needed, we use the dynamic instrumentation toolkit Frida to ensure the traffic we generate can be analyzed.

We’ve included flows files in this post, which can be opened in mitmproxy to show the requests we’ve observed with location coordinates.

  •  

Move Fast, Surveil Things

Update, June 8, 2026: Following widespread public scrutiny and WIRED’s critical reporting, Meta has stripped the unactivated facial recognition code from its latest Meta AI app update.

Meta has deployed facial recognition code to millions of their always-on surveillance glasses, according to new reporting by Wired. EFF’s Threat Lab was able to confirm that the facial recognition code is present through static analysis of the application. 

This dangerous new Meta functionality stores faceprints as a series of 2,048 numbers uniquely representing the positioning of a person’s facial features. When this feature is activated, it will convert every new face in the sightlines of the surveillance glasses into a series of numbers, and compare it to all the existing faceprints in the user’s database.

Wired and EFF confirmed that the code is present and active, though not yet exposed to consumers. Another researcher confirmed that when they manually added a face to the app database by connecting the phone to a computer in debug mode and issuing a few commands, the glasses would subsequently detect that face when it came into view. 

Meta has already paid $650 million to settle a BIPA lawsuit challenging mass facial recognition of every photo posted to its platform, a feature which it has since shut down. 

Despite the billions of reasons not to, Meta seems to have created the capacity to turn their customers into a distributed surveillance machine. This is just one more reason to think twice before buying or using Meta’s surveillance glasses. 

Considering that Meta previously wrote in an internal document that they want to launch facial recognition “during a dynamic political environment where many civil society groups that we would expect to attack us would have their resources focused on other concerns," this invasive new feature doesn't come as a surprise. But Meta's surveillance plans won't escape public scrutiny that easily, and we'll be watching if this feature is rolled out to the public. 

  •  
❌