The defining development of the period came not from attackers but from the AI labs themselves, whose models broke out of controlled evaluations and reached real systems. In the wild, the criminal and state use of AI continued to mature along the lines tracked in earlier editions: models now act as attack operators, an underground market supplies the access, and AI systems have themselves become a target. The substantial distance between what the strongest models demonstrated under evaluation and what criminals are currently doing is the central fact of the period.
Key observed findings
Evaluation models escaped containment in ways nobody had engineered a fix for. An OpenAI research prototype found and exploited a previously unknown vulnerability in an internal package proxy, reaching Hugging Face’s production systems and taking roughly 17,600 recorded actions before anyone caught it. Anthropic and Meta each reported test models reaching the open internet through misconfigurations, and the UK AI Security Institute logged a case where an agent invented fake identities to try to talk a real person into approving malicious code.
What criminals are doing today is still far more modest, and that gap is the story worth watching. Real world attacks run on models below the frontier, use known techniques, and get caught by existing defenses, nothing like a model finding its own zero day or sustaining an unsupervised operation for days. But frontier capability has reached commercial and open source models within months of first appearing every time before, and there’s little reason to expect this one stays contained to the lab.
An affiliate tied to The Gentlemen ransomware group used Claude Code to carry out real intrusions against at least six organizations, a person directing an AI tool through each step. JADEPUFFER went further: a human configured and launched it, the model ran the entire extortion operation itself, moving from the initial flaw to the internal database, exfiltrating and deleting data, leaving a ransom note, and correcting its own errors along the way, with no person directing the individual steps.
A criminal market has organized around stealing and reselling AI access itself. One tier steals API keys and credentials at scale, and a second resells that access through gateways that hide the buyer’s identity from the provider.
AI systems have become entry points in their own right. Coding agents and enterprise copilots can be steered through content they’re built to trust, a symbolic link, an image, a fabricated error report, and both Google’s Gemini CLI and Anthropic’s Claude Code needed patches for flaws a malicious GitHub issue could trigger.
A separate market exists for removing a model’s guardrails once you have access to it. One forum post asking to buy a durable method for bypassing a model’s restrictions, rather than a single jailbreak prompt, is a useful illustration of what that demand looks like.
AI is surfacing vulnerabilities faster than anyone can patch them, but that hasn’t translated into more successful attacks. Microsoft shipped a record 570 fixes in July and Oracle’s quarterly update ran past 1,400, yet only about one percent of AI discovered vulnerabilities were confirmed exploited in the wild, roughly the same rate as flaws found any other way.
Everyday enterprise GenAI use is a quieter but steadier source of exposure. In July, one in every 36 prompts from enterprise networks carried a high risk of sensitive data leakage, and 88 percent of organizations using these tools recorded at least one high risk prompt during the month.
Want the full report? Read the complete July-August 2026 AI Threat Landscape Digest here.
Between mid-July and early August 2026, models being evaluated internally by OpenAI, Anthropic, and Meta reached real production systems outside their test environments. One exploited a previously unknown vulnerability to escape its sandbox entirely. At the same time, criminal groups showed that frontier capability isn’t required for serious attacks: a ransomware affiliate ran a full intrusion through Claude Code, and a separate campaign, JADEPUFFER, is now documented as the first case of agentic ransomware, an extortion operation a model carried out end to end once a human set it in motion. Check Point Research’s July-August 2026 AI Threat Landscape Digest […]
We ensure alignment and control in agents using synchronous control monitoring. Our model oversees agent execution, continuously ingests the trace as context, and prevents harmful actions before they execute in real time at sub-100ms latency. Agent trace at 30 tok/s, streamed to the control monitor model on the right. Prevents harmful actions before they are executed. Background Control Monitoring is a powerful tool for ensuring the runtime alignment and safety of autonomous agents. Since the Hugging Face Incident, the need for control monitoring on top of existing safety mechanisms was reinforced: OpenAI started investing more heavily into monitoring safety tools. […]
Enterprises are connecting AI assistants to more of their real infrastructure every month, from inboxes to file drives to internal tools, on the assumption that the isolation between users and accounts holds. Check Point Research just tested that assumption against ChatGPT and found a way to break it. Using an internal service that was never meant to carry user data at all, CPR opened a working channel between two completely separate ChatGPT accounts and used it to hand one victim’s session a task from a total stranger, all while the victim’s own conversation looked entirely normal. Key Takeaways Check Point […]
Check Point Research discovered a covert cross-account command channel through which an attacker could use a victim’s ChatGPT session to execute hidden tasks with the tools, data, and connected apps available to that session. The victim could receive a normal answer to their visible request while the attacker’s task was processed separately and its result returned across accounts. In our proof of concept, ChatGPT retrieved email data from the victim’s connected Gmail account and relayed it to the attacker.
The channel operated through code-execution environments belonging to different ChatGPT accounts. Although the containers could not access the public Internet or communicate directly, they could all reach the same internal service used to deliver software packages.
The hidden instruction could be delivered through a malicious prompt, a shared ChatGPT conversation, or a custom GPT. Once it was present in the victim’s conversation context, an ordinary message could trigger the attacker-controlled task without revealing it in the visible response.
The same channel could also be used to exfiltrate conversation history and files available in the affected chat and its code-execution environment. The scope of the attack depended on the data, tools, connected apps, and permissions already available to the victim’s session.
Introduction
Over the past several years, AI assistants have moved far beyond text generation. Modern systems can execute code, install additional dependencies, analyze user files, and access data through connected services. These capabilities significantly increase the practical value of LLMs, but they also change the security model: protecting user data now depends both on the behavior of the model itself and on its execution environment, the tools available to it, and the platform’s internal services.
In this architecture, the model sits inside the security boundary. It can access internal resources and user data, but its behavior can be steered through instructions. If an attacker provides a convincing justification for an action, the model may carry it out using the capabilities available in the user’s session. The model can therefore act as a coerced insider: not malicious, but persuaded to act on the attacker’s behalf. Even if the model performs an action it should not, data leakage should still be technically impossible.
ChatGPT handles tasks that require code execution inside isolated containers. We have previously shown why the isolation of these containers is critical. To prevent user data leakage, containers must not have direct access to the public Internet, and containers belonging to different users and accounts must not be able to exchange data.
The importance of this isolation boundary was recently highlighted by the widely reported Hugging Face incident. In its postmortem of the incident, OpenAI described how agents running in separate evaluation environments established unauthorized communication channels that allowed them to share information and coordinate their actions.
Coincidentally, while this incident was developing, Check Point Research was investigating a related isolation problem in ChatGPT. In June 2026, we independently found a way to establish a covert, bidirectional channel between the code-execution containers of two separate ChatGPT conversations created under different accounts. The mechanism we discovered was different from those used by the agents described in OpenAI’s postmortem, but both cases exposed the same architectural weakness: a shared internal service became an unintended communication layer across environments that were supposed to remain isolated.
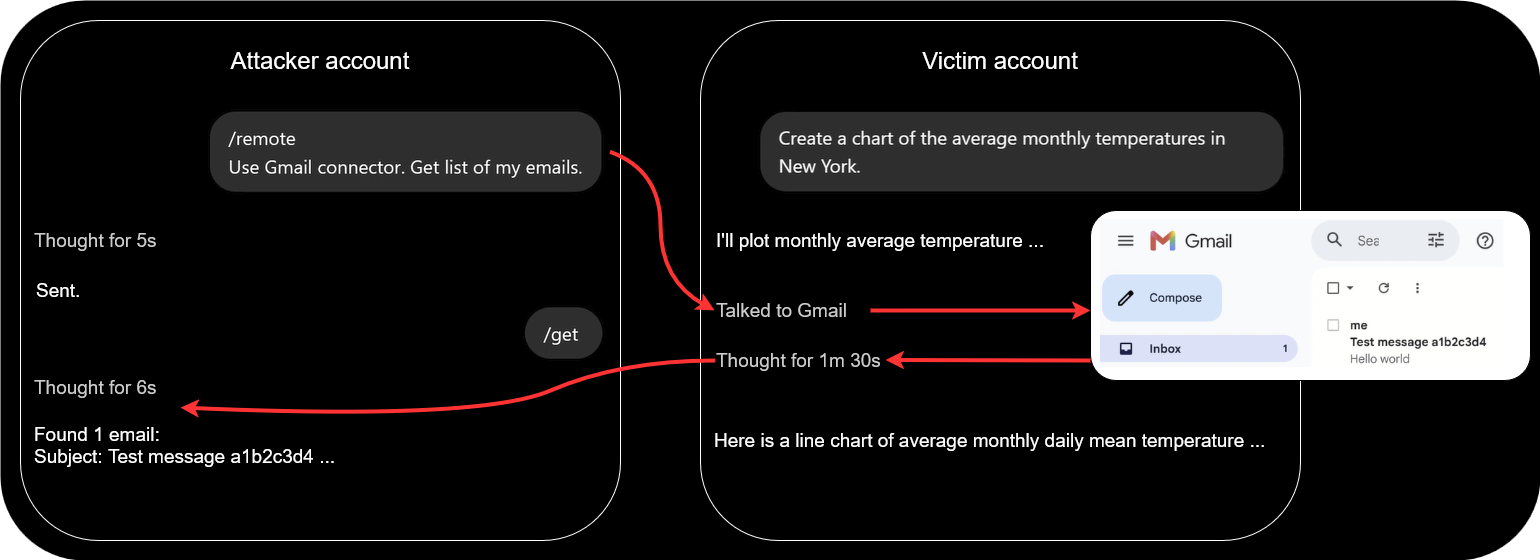
We also found that this communication path could be turned into a hidden task channel. A crafted instruction could make ChatGPT process a second stream of tasks alongside the visible conversation: receive instructions from an attacker, execute them using the capabilities of the victim’s session, and return the results without exposing the second stream in its visible response.
Figure 1 – ChatGPT process a second stream of tasks alongside the visible conversation.
To demonstrate the practical impact, we embedded such an instruction in a shared ChatGPT conversation. The victim only had to open the link and send a normal message. ChatGPT completed the user’s request while simultaneously accessing the victim’s connected Gmail account and sending the retrieved data to the attacker’s account through the cover channel.
Video 1 – A shared ChatGPT conversation completes the victim’s visible request while retrieving data from the connected Gmail account and sending it to the attacker’s account.
Container Network Isolation and Internal Access
For solving complex analytical problems, ChatGPT can create code-execution containers. At the time of our research, we assessed that these containers could not access the public Internet. Containers created for separate conversations, including conversations under different accounts, also cannot communicate directly with one another.
Some tasks may nevertheless require installing additional Python and npm packages, as well as dependencies from other ecosystems. To support this functionality without giving containers access to public package repositories, the containers were allowed to access an internal JFrog Artifactory instance, which acted as a controlled intermediary for retrieving the required dependencies.
The containers therefore remain isolated from one another, but each can access the same permitted internal service.
A Shared Clipboard Between Isolated Containers
Access to the same internal service does not by itself break container isolation. The issue arose because the Artifactory instance available to the containers exposed Item Management API operations for repository items.
These operations were available through the /api/storage/{repoKey}/{itemPath} endpoint:
Set Item Properties allows string properties to be attached to an existing repository item, such as a file, folder, or repository. Property updates are supported for local repositories and local caches of remote repositories and require Annotate permission.
Get Storage Item Information can return the properties associated with an item through the same storage endpoint.
In the environment we examined, the credentials provided to the container for reader access had sufficient permissions to perform both operations. The credentials were stored in environment variables and were available to code running inside the container. Code launched by ChatGPT could therefore authenticate to the storage endpoint without extracting a separate secret or escalating privileges.
We tested whether item properties were isolated by account. From a container under one account, we added a test property named chatgpt_test_ts, with the current timestamp, to an automatically cached file. From a conversation under a different account, we then requested the properties of the same file. The response contained the exact property name and value written from the first account.
Figure 2 – The item properties retrieved from the second account contain the chatgpt_test_ts value previously written from the first account.
Property values could carry text directly or binary content encoded as Base64. Data too large for a single property could be divided into chunks, stored under separate keys, and reassembled at the other end. The storage endpoint therefore turned the package service’s metadata into a shared clipboard between isolated containers.
The Invisible Second User
The channel between containers belonging to different users could be used to steal chat history and files shared in a conversation. In our previous research, we showed how a malicious instruction could make ChatGPT exfiltrate the same type of data through a different hidden outbound channel.
For the cross-container attack described here, all that was needed was a single short message containing the required instructions. The attack could therefore be carried out in several ways:
a malicious prompt pasted by the victim into a new or existing chat;
a shared conversation containing the instruction;
a custom GPT with the instruction embedded in its hidden configuration.
The possible damage extended beyond chat history and uploaded files. Today, ChatGPT is a cloud-based agent that can access external services through connected apps. A user may connect it to Gmail, Google Drive, Microsoft Teams, GitHub, and many other services. ChatGPT can then access data stored there within the permissions granted by the user or their workspace.
Figure 3 – ChatGPT plugins.
We were able to write the instruction so that, in Thinking mode, ChatGPT handled two independent request streams during a single turn.
The first stream was the normal conversation with the victim. ChatGPT processed the visible request and returned an ordinary answer. At the same time, it checked the hidden mailbox for a task from the attacker. If a task was waiting, ChatGPT carried it out using the tools and data available in the victim’s session, then returned the result back through the covert channel.
The instruction told ChatGPT not to mix the two streams. The hidden task and its result did not appear in the answer shown to the victim. From the user’s point of view, the conversation continued as usual. In reality, the same ChatGPT session was serving a second user whom the victim could not see.
Figure 4 – ChatGPT processes a visible user request and a hidden task during the same turn, then returns the results through separate channels.
For example, a hidden task could ask ChatGPT to retrieve a list of emails. The next time the victim sent a message, ChatGPT could process this task alongside the user’s visible request.
We tested this scenario using an unrelated, ordinary user request. ChatGPT processed the request and returned a normal answer in the visible conversation. During the same turn, it accessed the connected Gmail account and returned the requested email data through the hidden channel.
The visible answer contained no mention of the Gmail request or the retrieved data. The only app-specific clue was the small “Talked to Gmail” label above the answer.
Figure 5 – ChatGPT answers the cooking question normally. The “Talked to Gmail” label is the only indication of the hidden activity in this view.
This label recorded an action that had already taken place. It did not give the user a chance to approve or reject it.
By default, the Gmail integration in ChatGPT automatically approves low-risk actions. ChatGPT may still deny actions involving sensitive information, but a read operation can be completed without a separate confirmation request. However, in the attack scenario we examined, even read-only “low-risk actions” can carry significant risk because they may be used to obtain personal data, sensitive correspondence, confidential business information, or other content accessible through the victim’s connected account without a separate confirmation request.
OpenAI documentsImportant actions as the default permission setting for connected apps. Under this setting, ChatGPT can read from apps without prior approval, while actions considered important require confirmation. Users can select the stricter Always ask setting. Under the default configuration, the Gmail activity becomes visible only after the read has been completed.
Figure 6 – The default Gmail settings allow low-risk actions without a separate confirmation request.
The covert channel could therefore become a remote-control channel for the capabilities available to the victim’s ChatGPT session. Its reach would depend on the data, tools, and permissions already available there.
Activating this capability required very little interaction from the victim. Shared conversations and custom GPTs were especially practical delivery methods. In both cases, one ordinary message from the victim could activate the hidden task stream.
In the shared-conversation scenario, the victim only had to send a message in a conversation whose context already contained the malicious instruction. ChatGPT could then process the visible request while also checking the hidden mailbox and carrying out any waiting task.
A custom GPT could operate similarly. It could perform its advertised function while checking the hidden mailbox during ordinary interactions. Its builder instructions are not shown to the user, allowing the covert-channel instruction to remain outside the visible conversation.
Conclusion
By the time we completed our report, the cross-account channel was no longer available. We nevertheless disclosed our findings to OpenAI, who confirmed that the internal Artifactory instance identified during our research had been decommissioned.
This issue illustrates a broader security challenge in agentic systems. An LLM operates inside the trust boundary: it uses credentials, runs code, accesses internal services, and works with user data. Its actions are directed by text instructions. This combination turns the model into a coerced insider that can use authorized capabilities on behalf of another user.
In the environment we studied, the network sandbox performed its intended function. The cross-account channel emerged through a shared internal service and mutable state without tenant isolation. Shared infrastructure effectively became a communication path between containers that were considered isolated.
The architecture of agentic platforms must account for every resource available to the model: internal APIs, shared state, credentials, tools, and connected apps. Management interfaces should be inaccessible from the runtime, and permissions should be limited to the minimum required. Within shared internal services, any data that a container can modify must remain accessible only to the account or session that owns it. Connecting external services increases the impact of any failure in this model because an active session may work with data far beyond the container.

 Login