Amazon Threat Intelligence identified a PHP2Shell exploitation attempt dating to Oct. 17, 2026, in MadPot telemetry, four days before public disclosure of CVE-2026-109618 and CVE-2026-109619. The exploit attempt originated from an IP address associated with a commercial anonymization network. While the vulnerability was under embargo, the targeting of a honeypot from an anonymized IP address suggests the activity was conducted by a threat actor, though it remains unclear how the actor acquired exploit information prior to disclosure.
The PHP embargo window was set to be lifted on 2026-10-21 1400 UTC. On the day of the release, Amazon Threat Intelligence identified multiple proof of concept exploits for the vulnerability, with the earliest around 2026-10-21 0200 UTC. Subsequently, from 2026-10-21 0200 UTC to 2026-10-21 0800 UTC, Amazon Threat Intelligence identified additional exploitation attempts of PHP2Shell targeting MadPot from additional anonymized infrastructure. The actual payloads and choices in anonymization infrastructure varied, suggesting these were multiple actors. Technical analysis is ongoing, and it’s unclear if any of these attempts would have succeeded in real-world systems.
The actual release of the embargo window was 2026-10-21 1400 UTC. Once the embargo was lifted and the patch was released, additional proof-of-concept exploits appeared within hours, and we saw them used against our sensors almost immediately. PHP2Shell is now seeing broad exploitation attempts in the wild.
Two lessons from this event apply well beyond this one vulnerability:
An embargo protects defenders only until someone else finds the same bug. Coordinated disclosure is still the right model. But defenders should not assume the public disclosure date is the earliest date of exploitation. With PHP2Shell, compromise may predate the advisory.
The time from patch to working exploit is shrinking for structural reasons. In the past, most exploitation we observed came after a public proof of concept was released. A small number of capable actors built exploits, and everyone else waited for them. That dependency is weakening. AI-assisted analysis makes it cheaper to turn a patch diff or advisory into a working exploit. As a result, more actors can act within hours or even minutes once technical details of a vulnerability are disclosed.
For security leaders, this changes several working assumptions:
For critical vulnerabilities in internet-facing systems, measure patch and mitigation timelines in hours. A 7-day or 30-day SLA assumes a delay that no longer exists.
Start investigations from the earliest known exploitation, not from the disclosure date. For PHP2Shell, investigate from at least starting on October 17th.
Invest in detections that don’t rely on a signature for a specific CVE. The first exploitation will often come before those signatures exist.
How AWS helps protect customers
AWS deploys multiple layers of protection to help safeguard customers. Our internal threat intelligence system automatically detected and restricted malicious scanning attempts targeting this vulnerability. We analyze over 200 billion events per minute and integrate threat intelligence from our MadPot honeypot network to identify and block known exploitation attempts in real time. Our honeypot system provides us with early detection of exploitation attempts, enabling rapid response and threat analysis.
Immediate recommended actions
Upgrade immediately to the fixed PHP versions. Upgrading is the only complete remediation for both CVE-2026-109618 and CVE-2026-109619. There are no configuration-only workarounds that fully address both issues.
Consider blocking multi-part file uploads in PHP deployments that cannot be patched immediately, but determine how this would affect your application prior to deploying.
Look for POST requests with the PHP_SESSION_UPLOAD_PROGRESS string in form uploads.
Review web server logs for suspicious activity.
Check for unexpected process execution or file modification on web application servers.
Indicators of Compromise (IOCs)
IP Address
Observed Date
103.216.220.92
10/17/2026
31.223.184.166
10/21/2026
37.19.200.5
10/21/2026
134.209.159.64
10/21/2026
103.114.163.188
10/21/2026
95.217.98.37
10/21/2026
The identified IP addresses include shared anonymization infrastructure and are not exclusive to this threat activity. Organizations should investigate any observations involving these addresses as opposed to blocking.
Amazon is sharing new findings about how a threat actor linked to the Democratic People’s Republic of Korea (DPRK) is targeting open source software libraries, the shared building blocks that companies around the world use to develop applications. Amazon Threat Intelligence has linked several recent compromises of popular Node Package Manager (NPM) libraries to the same DPRK-linked threat actor, a connection that hasn’t been publicly reported until now. The analysis also describes how generative AI is already changing what malicious software packages look like and how threat actors are beginning to probe AI-based code systems. We’re sharing this research to help the open source community and security teams better identify and address these types of events.
These developments come 2 years after the XZ Utils backdoor, which demonstrated how a patient attacker can compromise critical open source software by exploiting the trust and limited time of volunteer maintainers. Open source software underpins much of the internet’s infrastructure: operating systems, web servers, encryption libraries, and the application frameworks that businesses rely on daily. When an attacker compromises a widely used open source package, every organization that depends on that package is potentially affected. Since then, Amazon Threat Intelligence has observed the volume and sophistication of software supply chain attacks increase, driven in large part by DPRK‑linked threat actors and cybercriminal groups.
In this post, Amazon Threat Intelligence and the Amazon Inspector team share new details about recent campaigns against popular NPM packages, including evidence that the compromises of the axios, debug, chalk, and typo-crypto libraries were carried out by the same DPRK-linked threat actor tracked by the security community as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. We also outline how the techniques used to compromise open source repositories are evolving, why these changes matter for organizations that depend on open source software, and what Amazon Web Services (AWS) is doing to help customers detect and respond to these threats.
One DPRK–linked group behind multiple NPM compromises
In March 2025, the DPRK-linked threat actor compromised the typo-crypto package. In September 2025, the same threat actor compromised the debug and chalk NPM packages. In March 2026, the same operational playbook appeared in a compromise of the axios package, one of the most widely used JavaScript libraries with more than 100 million weekly downloads. In each case with debug, chalk, and axios, the threat actor gained access by socially engineering a trusted maintainer of the package, then published a software update containing malicious code. Any organization that automatically pulled the latest version of these packages received the compromised update.
While the axios compromise has been publicly attributed to this DPRK-linked threat actor, the typo-crypto, debug, and chalk incidents haven’t previously been connected to it. Amazon Threat Intelligence identified shared tactics, techniques, and procedures (TTPs) across these supply-chain campaigns, including trojanized NPM packages, use of post-install hooks (scripts that run automatically when a package is installed), and code reuse. Based on analysis of command-and-control (C2) indicators and TTPs, Amazon Threat Intelligence assesses with medium confidence that these campaigns are attributable to the DPRK-linked threat actor tracked as SAPPHIRE SLEET, STARDUST CHOLLIMA, BlueNoroff, CageyChameleon, and Alluring Pisces. This is the first time these compromises have been publicly tied to this DPRK-linked threat actor.
Amazon Threat Intelligence assesses this as part of a financially motivated pattern: by compromising a small number of highly popular packages, the group gains potential access to thousands of downstream environments simultaneously. For a financially motivated threat actor, this approach is far more efficient than targeting organizations one at a time.
The aggregate impact of these incidents underscores the efficiency of targeting share dependencies. As reported by Wiz Research, roughly 1 in 10 cloud environments were affected by the debug and chalk supply chain event within a two‑hour window.
A smaller campaign that foreshadowed later activity
During routine analysis of indicators and TTPs related to the axios threat actor, Amazon Threat Intelligence identified a connection to a domain registered in 2025, prompting a full investigation into its historical activity. That investigation uncovered that the same DPRK-linked threat actor had committed a trojanized file to the typo-crypto NPM package in March 2025. The malicious file, core.js, masquerades as the legitimate core-js NPM package within the typo-crypto repository.
Based on the limited number of observed downloads, Amazon Threat Intelligence assesses that this campaign was small scale and likely served as a testing ground for the more visible supply chain operations that followed in late 2025 and 2026. The group appears to have been refining supply chain techniques more than a year before the larger campaigns that drew public attention. Amazon Inspector reported this malware to the Open Source Vulnerabilities (OSV) database, where it’s now tracked as MAL‑2026‑3400, so that the broader security community can benefit from these findings.
The trojanized file executes when it receives a hash input beginning with the value 0098273. When triggered, it downloads a second-stage payload from a hardcoded C2 server, then executes the payload based on the victim’s operating system, with behavior tailored for Windows, macOS, or Linux. The malware implements file-based persistence with payload rotation and uses multi-layer obfuscation, combining base64‑encoded text with an XOR cipher keyed to 01042025.
Amazon Threat Intelligence assesses that the group was experimenting with techniques that later appeared in the higher-impact campaigns against axios, debug, and chalk. Although the observed download volume was low, the tradecraft aligns with what we later observed in attacks on more popular packages.
How attacker tradecraft is shifting
Over the past year, Amazon Threat Intelligence and Amazon Inspector have observed threat actors changing the techniques they use to target open source libraries. These changes matter because open source packages remain attractive targets: they’re widely trusted, automatically updated in many environments, and maintained by communities that welcome new contributors. The following patterns describe how attackers are adapting their methods to evade modern defenses. Each is designed to exploit the gap between the moment a dependency is inspected and the moment it actually executes. A year ago, we looked for malicious packages. Today, we look for malicious behaviors split across packages that appear harmless on their own.
From package‑level attacks to fragment‑level attacks
Amazon Inspector has observed attackers increasingly splitting a single malicious workflow across several ordinary-looking packages. One package stores an encrypted blob disguised as configuration. A second ships the decryption logic. A third, often published later, fetches and executes the payload.
Viewed on its own, each package looks benign. There are no install hooks that stand out, no obvious evaluation of untrusted input, no network calls that look suspicious. The malicious behavior only appears when the components are used together in the intended sequence. This approach is designed to defeat scanners that evaluate packages one by one instead of reasoning about how they interact in a real dependency graph.
Long-horizon campaigns that invest in trust
We’re also observing threat actors taking a long view of trust accumulation. Instead of publishing obvious malware and waiting for downloads, they publish something genuinely useful and maintain it. They behave like real maintainers for weeks or months, shipping features, fixing bugs, and gaining dependents.
The same patience shows up on the human side. In some cases, the goal isn’t to launch a new package at all, but to become a contributor to an existing project. That’s the through line from XZ Utils backdoor to the debug, chalk, and axios maintainer compromises. In each case, the adversary treated legitimacy as an asset to be spent once, at the moment of maximum access.
Decoupling the package from its behavior
In many recent cases, a library is clean on the public registry yet still dangerous, because its real behavior depends on resources the attacker controls elsewhere. These can include guard or license scripts fetched from an external repository at runtime, configuration files that gate certain behaviors, or remote endpoints consulted at startup.
As long as those external resources remain benign, code reviews pass and automated scans return clean results. When an attacker flips the content or arms an endpoint that previously returned a placeholder, every installed copy can become malicious at once, without any new package release. A package that shows no malicious behavior today isn’t the same as a package that’s is safe by design.
From basic obfuscation to real cryptography
Where attackers used to rely on simple obfuscation such as minification or single-layer base64 encoding, we now observe multi-stage payloads that use stronger cryptographic techniques. Examples include AES‑GCM encrypted blobs gated by passphrases, RC4-style string arrays with per-call keys, layered XOR over base64, and native loaders that hold the next stage as an encrypted field decrypted only in memory.
The common design choice is that the decryption key is never stored in the package itself. It’s derived from runtime context, fetched from a server at execution time, or supplied as a license key. That means even an analyst with full source access can’t reliably decrypt the payload statically. Stage one looks like a simple decryptor; the malicious content remains ciphertext until it runs on a real target with the real key.
Payloads that avoid detonating in sandboxes
As defenders have scaled automated analysis in cloud sandboxes, attackers have made their code more environment aware. The payload decides whether it’s being analyzed before it acts. We see execution gated behind real package install lifecycles, single-use environment variables, and checks for signals of a genuine developer or build environment. These include interactive terminals, realistic usernames and hostnames, domain membership, plausible uptime, local file history, specific operating systems, and cloud metadata that helps distinguish analysis infrastructure from normal workloads.
Some delivery servers also tailor what they serve based on the client. A benign decoy goes to generic browser-like requests, while the live payload only appears for the exact user agent used by the malware. The result is that a clean verdict from a cloud sandbox often tells you more about how convincing your environment looks than how safe the package is.
How generative AI is reshaping both attacks and defenses
Generative AI is changing what attackers can produce and what defenders can rely on. Adversaries can generate novel code and content at scale. Historically, many malicious packages were caught because they looked wrong, with broken language, thin documentation, obvious copy-paste, or a telltale function reused across samples. Generative AI erases many of those signals.
Attackers can now produce thousands of lines of coherent, idiomatic, well-commented code, complete with convincing documentation, plausible commit histories, and synthetic maintainer identities, wrapped around a backdoor. Because each variant can be mutated, renamed, restructured, and re-encrypted, there is no single stable signature to match. Pattern-based detection loses ground against malware that looks one of a kind in every deployment.
AI is also creating new initial access vectors. One emerging technique is slopsquatting, where attackers register package names that exist only because an AI coding assistant hallucinated them. When a developer or an autonomous coding agent asks for help and the model confidently recommends a nonexistent package, an attacker can pre-register that name and wait. The next person who follows the recommendation might receive malware, despite not mistyping anything or visiting a malicious site, because the AI effectively delivered the bad dependency for them. As organizations move toward agents that install dependencies with limited human review, this path looks less like a curiosity and more like a scalable delivery channel.
Most significantly, AI changes the calculus for defensive automation. Attackers are no longer just writing malware for humans to miss. They’re writing malware for AI reviewers to approve. As organizations rely on AI systems to review code and triage packages, those AI systems themselves become part of the attack surface. We expect that indirect prompt injection, a technique where hidden instructions manipulate an AI system into taking unintended actions, will increasingly be embedded in malicious packages to fool AI-based code scanners. These instructions can be hidden in source comments, README files, docstrings, or test fixtures, and crafted to convince an automated system to mark malicious code as safe, skip a specific file, or perform an unintended action during analysis. The same content the malware needs to function can carry a second, separate message aimed at the machine that inspects it.
How AWS is responding
We’re investing across Amazon Threat Intelligence and Amazon Inspector to help customers adapt to this shifting landscape of software supply chain risk. Amazon remains committed to helping protect the security of our customers and the internet by actively hunting for and mitigating threats from sophisticated threat actors. We will continue working with Amazon teams, industry partners, and the security community to share intelligence and mitigate threats. Upon discovering this campaign, Amazon Threat Intelligence worked with Amazon Inspector so the malicious package was tracked, mitigated, and shared with the community through the OSV database. Additionally, the observed indicators were shared with Amazon GuardDuty to alert our customers of this activity.
Amazon Inspector uses these insights to refine our detection logic, broaden coverage across registries, and prioritize signals that reflect the tradecraft shifts described in this post, and is collaborating with industry partners such as package registries and Open Source Security Foundation (OpenSSF) to share findings.
We’re also investing in helping open source maintainers better secure their projects. In 2026, AWS joined the Linux Foundation and other industry leaders to launch Akrites, a collaborative initiative to defend critical open source software against AI-enabled cyber threats. AWS has also jointly invested $12.5 million alongside other organizations to defend the open source ecosystem from AI-driven attacks. These efforts reflect a broader commitment: the security of open source software is a shared responsibility, and defending it requires sustained investment from the organizations that depend on it.
Our goal is to help customers understand where their environments rely on open source components, identify suspicious behavior early, and respond quickly when the software supply chain is used as an entry point.
August 11, 20206: This post was updated to clarify that the social engineering of a trusted maintainer applied to the debug, chalk, and axios compromises specifically. The underlying attribution and findings remain unchanged.
Amazon threat intelligence has identified an active Interlock ransomware campaign exploiting CVE-2026-20131, a critical vulnerability in Cisco Secure Firewall Management Center (FMC) Software that could allow an unauthenticated, remote attacker to execute arbitrary Java code as root on an affected device, which was disclosed by Cisco on March 4, 2026.
After Cisco’s disclosure, Amazon threat intelligence began research into this vulnerability using Amazon MadPot’s global sensor network—a system of honeypot servers that attract and monitor cybercriminal activity. While looking for any current or past exploits of this vulnerability, our research found that Interlock was exploiting this vulnerability 36 days before its public disclosure, beginning January 26, 2026. This wasn’t just another vulnerability exploit, Interlock had a zero-day in their hands, giving them a week’s head start to compromise organizations before defenders even knew to look. Upon making this discovery, we shared our findings with Cisco to help support their investigation and protect customers.
A misconfigured infrastructure server—essentially, a poorly secured staging area used by the attackers—exposed Interlock’s complete operational toolkit. This rare mistake provided Amazon’s security teams with visibility into the ransomware group’s multi-stage attack chain, custom remote access trojans (backdoor programs that give attackers control of compromised systems), reconnaissance scripts (automated tools for mapping victim networks), and evasion techniques.
AWS infrastructure and customer workloads on AWS were not observed to be involved in this campaign. This advisory shares comprehensive technical analysis and indicators of compromise to help organizations identify potential compromise and defend against Interlock’s operations. Organizations running Cisco Secure Firewall Management Center should immediately apply Cisco’s security patches and review the indicators provided below.
Discovery and investigation timeline
Amazon threat intelligence identified threat activity potentially related to CVE-2026-20131 beginning January 26, 2026, predating the public disclosure. Observed activity involved HTTP requests to a specific path in the affected software. Request bodies contained Java code execution attempts and two embedded URLs: one used to deliver configuration data supporting the exploit, and another designed to confirm successful exploitation by causing a vulnerable target to perform an HTTP PUT request and upload a generated file. Multiple variations of these URLs were observed across different exploit attempts.
To advance the investigation and obtain additional threat intelligence, we performed the expected HTTP PUT request with the anticipated file content—essentially, we pretended to be a successfully compromised system. This successfully prompted Interlock to proceed to the next stage, issuing commands to fetch and execute a malicious ELF binary (a Linux executable file) from a remote server.
When analysts retrieved the binary, they discovered the same host (attacker-controlled server) is used for distributing Interlock’s entire operational toolkit. The exposed infrastructure organized artifacts into separate paths corresponding to individual targets, with the same paths used for both downloading tools to compromised hosts and uploading operational artifacts back to the staging server.
Attribution to Interlock ransomware
The ELF binary and associated artifacts are attributable to the Interlock ransomware family based on convergent technical and operational indicators. The embedded ransom note and TOR negotiation portal are consistent with Interlock’s established branding and infrastructure. The ransom note’s invocation of multiple data protection regulations reflects Interlock’s documented practice of citing regulatory exposure to pressure victims, essentially threatening organizations not just with data encryption, but with regulatory fines and compliance violations. The campaign-specific organization identifier embedded in the note aligns with Interlock’s per-victim tracking model.
Interlock has historically targeted specific sectors where operational disruption creates maximum pressure for payment. Education represents the largest share of their activity, followed by engineering, architecture, and construction firms, manufacturing and industrial organizations, healthcare providers, and government and public sector entities.
Temporal analysis performed on timestamps from observed threat activities, artifacts stored on the misconfigured infrastructure server, and metadata embedded within recovered threat artifacts indicates the actor most likely operates in UTC+3 with 75–80% confidence. Systematic analysis across all UTC offsets showed UTC+3 produced the best fit: first activity around 08:30, peak activity between 12:00 and 18:00, and a probable sleep window of 00:30–08:30.
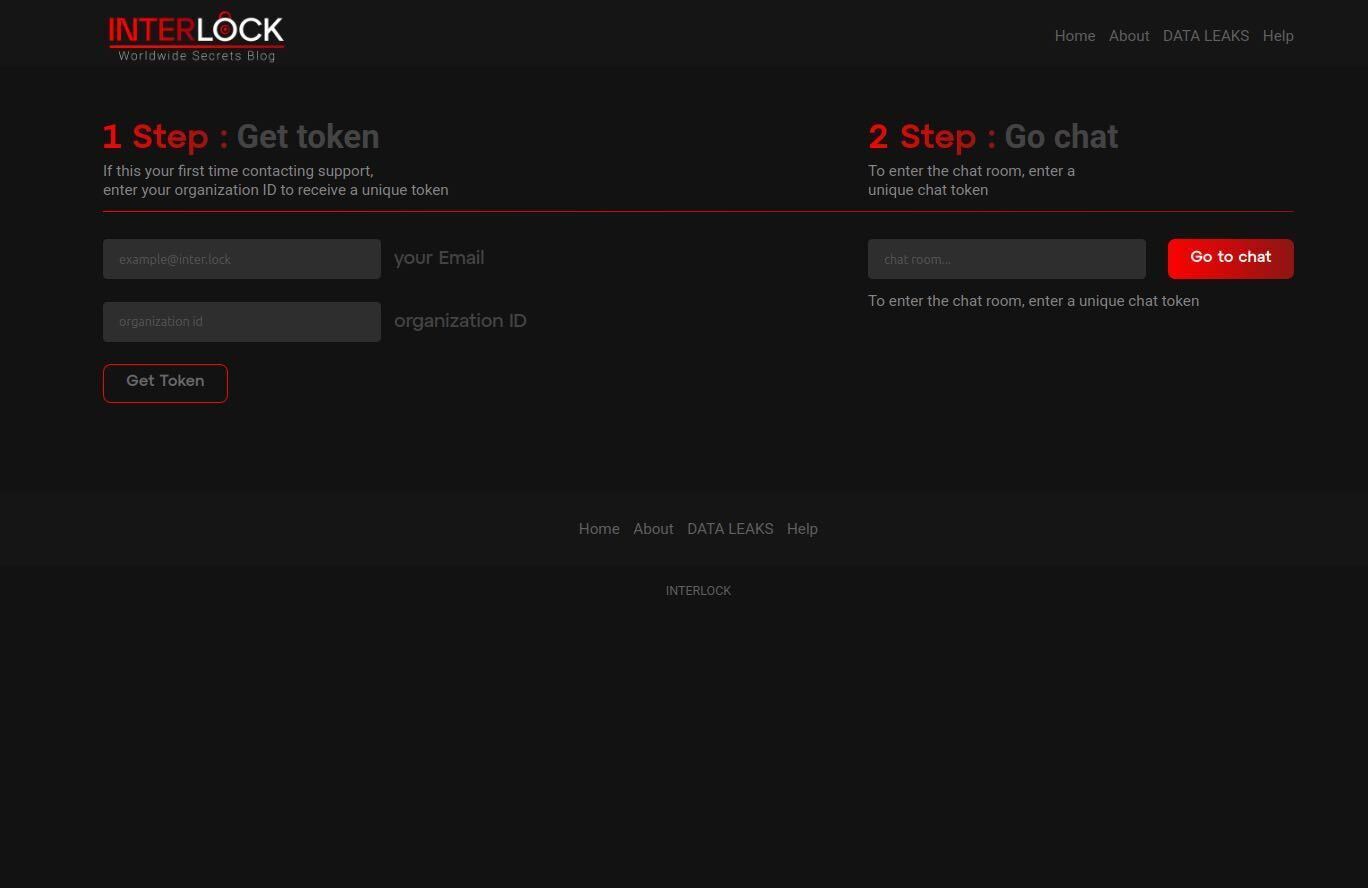
Figure 1: Interlock ransomware negotiation portal where victims enter their organization ID and email address to receive an auth token to begin a negotiation chat session.
Once Interlock gains initial access, they use a variety of priority tools to complete their attack. Amazon threat intelligence teams recovered a PowerShell script designed for systematic Windows environment enumeration (automated information gathering about the victim’s network). The script collects operating system and hardware details, running services, installed software, storage configuration, Hyper-V virtual machine inventory, user file listings across Desktop, Documents, and Downloads directories, browser artifacts from Chrome, Edge, Firefox, Internet Explorer, and 360 browser (including history, bookmarks, stored credentials, and extensions), active network connections correlated with responsible processes, ARP tables, iSCSI session data, and RDP authentication events from Windows event logs.
The script stages results to a centralized network share (\JK-DC2\Temp) using each system’s fully qualified hostname to create dedicated directories—essentially creating a folder for each compromised computer. Following collection, it compresses data into ZIP archives named after each hostname and removes original raw data. This structured per-host output format indicates the script operates across multiple machines within a network—a hallmark of ransomware intrusion chains that prepare for organization-wide encryption.
Custom remote access trojans
Remote access trojans (RATs) are malicious programs that give attackers persistent control over compromised systems, functioning like unauthorized remote desktop software.
JavaScript implant: Amazon threat intelligence recovered an obfuscated JavaScript remote access trojan that suppresses debugging output by overriding browser console methods (hiding its activity from basic detection tools). On execution, it profiles the infected host using PowerShell and Windows Management Instrumentation (WMI), collecting system identity, domain membership, username, OS version, and privilege context before transmitting this data during an encrypted initialization handshake.
Command-and-control communication occurs over persistent WebSocket connections with RC4-encrypted messages using per-message 16-byte random keys embedded in packet headers—essentially, each message uses a different encryption key, making interception more difficult. The implant cycles through multiple operator-controlled hostnames and IP addresses in randomized order with exponential backoff between reconnection attempts.
The implant provides interactive shell access, arbitrary command execution, bidirectional file transfer, and SOCKS5 proxy capability for tunneling TCP traffic (routing malicious traffic through other systems to hide its origin). Self-update and self-delete capabilities allow operators to replace or remove the implant without reinfection, supporting operational cleanup to hinder forensic investigation.
Java implant: A functionally equivalent client implemented in Java provides identical command-and-control capabilities. Built on GlassFish ecosystem libraries, it uses Grizzly for non-blocking I/O transport and Tyrus for WebSocket protocol communication. In simpler terms, Interlock built the same backdoor in two different programming languages, ensuring they maintain access even if defenders detect one version.
Infrastructure laundering script
Sophisticated threat actors don’t attack from their own infrastructure, they build disposable relay networks to hide their tracks. Amazon threat intelligence teams identified a Bash script that configures Linux servers as HTTP reverse proxies (intermediary servers that forward traffic to hide the attacker’s true location). The script performs system updates, installs fail2ban with SSH brute-force protection, and compiles HAProxy 3.1.2 from source. The HAProxy instance listens on port 80 and forwards all inbound HTTP traffic to a hardcoded target IP, with systemd ensuring persistence across reboots.
A notable component is a log erasure routine running as a cron job every five minutes. The routine truncates all *.log files under /var/log and suppresses shell history by unsetting the HISTFILE variable. This aggressive evidence destruction, wiping logs every five minutes, combined with the purpose-built HTTP forwarding proxy, indicates the script establishes disposable traffic-laundering relay nodes. These nodes obscure exploit traffic origin, relay command-and-control communications, or proxy data exfiltration, making it nearly impossible to trace attacks back to their source.
Memory-resident webshell
Amazon threat intelligence teams observed a Java class file delivered as an alternative to the ELF binary drop. When loaded by the Java Virtual Machine (JVM), its static initializer registers a ServletRequestListener with the server’s StandardContext, essentially installing a persistent memory-resident backdoor that intercepts HTTP requests without writing files to disk. This “fileless” approach evades traditional antivirus scanning that looks for malicious files.
The listener inspects incoming requests for specially crafted parameters containing encrypted command payloads. Payloads are decrypted using AES-128 with a key derived from the MD5 hash of the hardcoded seed “geckoformboundary99fec155ea301140cbe26faf55ed2f40″ (using the first 16 characters: 09b1a8422e8faed0). Decrypted payloads are treated as compiled Java bytecode, dynamically loaded into the JVM, and executed—a technique designed to evade file-based detection by running malicious code entirely in memory.
Connectivity verification tool
Amazon threat intelligence teams recovered Java class files implementing a basic TCP server listening on port 45588 (encoded as Unicode character 넔 to obscure the port number from static analysis). The server accepts connections, logs connecting IP addresses, sends a greeting message, and immediately closes connections. This operational profile is consistent with a lightweight network beacon—essentially a “phone home” tool used to verify successful code execution or confirm network port reachability following initial exploitation.
Legitimate tool abuse
Interlock deployed ConnectWise ScreenConnect, a legitimate commercial remote desktop tool, alongside custom implants. When ransomware operators deploy legitimate remote access tools alongside their custom malware, they’re buying insurance—if defenders find and remove one backdoor, they still have another way in. This indicates multiple redundant remote access mechanisms—a pattern consistent with ransomware operators seeking to maintain access even if individual footholds are removed. The tool’s legitimate network footprint helps blend with authorized remote administration traffic, making detection more challenging.
Amazon threat intelligence teams also recovered Volatility, an open-source memory forensics framework typically used by incident responders (the same tool defenders use to investigate attacks). While no artifacts indicated automated use, its presence alongside custom implants and reconnaissance scripts is consistent with advanced threat operations. Both ransomware groups and nation-state actors have been observed deploying Volatility during intrusions. The tool’s focus on parsing memory dumps provides access to sensitive data such as credentials stored in RAM, which can enable lateral movement (spreading through the network) and deeper environment compromise in support of ransom operations or espionage objectives.
Interlock also used Certify, an open source offensive security tool designed to exploit misconfigurations in Active Directory Certificate Services (AD CS). For ransomware operators, Certify provides a pathway to identify vulnerable certificate templates and enrollment permissions that allow requesting authentication-capable certificates. These certificates can be used to impersonate users, escalate privileges, or maintain persistent access. These capabilities directly support both initial compromise and long-term persistence objectives in ransomware operations.
Indicators of compromise (IoCs)
The following indicators support defensive measures by organizations that may be affected. Due to Interlock’s use of content variation techniques, most file hashes are not included as reliable indicators. The threat actor modified most artifacts like scripts and binaries downloaded to different targets. This resulted in different file hashes for functionally identical tools. The customization allowed each attack to evade signature-based detection that looks for exact file matches.
206.251.239[.]164
Exploit source IP
Active Jan 2026
199.217.98[.]153
Exploit source IP
Active Mar 2026
89.46.237[.]33
Exploit source IP
Active Mar 2026
Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:136.0) Gecko/20100101 Firefox/136.0
Organizations should take the following actions to protect against Interlock ransomware operations.
Immediate actions:
Apply Cisco’s security patches for Cisco Secure Firewall Management Center
Review logs for the indicators of compromise listed above
Conduct security assessments to identify potential compromise
Review ScreenConnect deployments for unauthorized installations
Detection opportunities:
Monitor for PowerShell scripts staging data to network shares with hostname-based directory structures
Detect Java ServletRequestListener registrations in web application contexts (unusual modifications to Java web applications)
Identify HAProxy installations with aggressive log deletion cron jobs (proxy servers that erase their own logs every five minutes)
Watch for TCP connections to unusual high-numbered ports (e.g., 45588)
Long-term measures:
Implement defense-in-depth strategies with multiple layers of security controls
Maintain continuous threat monitoring and hunting capabilities
Ensure comprehensive logging with secure, centralized log storage (stored separately from systems that could be compromised)
Regularly test incident response procedures for ransomware scenarios
Educate security teams on Interlock’s tactics, techniques, and procedures
The real story here isn’t just about one vulnerability or one ransomware group—it’s about the fundamental challenge zero-day exploits pose to every security model. When attackers exploit vulnerabilities before patches exist, even the most diligent patching programs can’t protect you in that critical window. This is precisely why defense in depth is essential—layered security controls provide protection when any single control fails or hasn’t yet been deployed. Rapid patching remains foundational in vulnerability management, but defense in depth helps organizations not to be defenseless during the window between exploit and patch.
Amazon Threat Intelligence teams continue to monitor Interlock ransomware operations and will provide updates as additional information becomes available. The intelligence gathered from this campaign is being integrated into AWS security services to protect customers proactively.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Commercial AI services are enabling even unsophisticated threat actors to conduct cyberattacks at scale—a trend Amazon Threat Intelligence has been tracking closely. A recent investigation illustrates this shift: Amazon Threat Intelligence observed a Russian-speaking financially motivated threat actor leveraging multiple commercial generative AI services to compromise over 600 FortiGate devices across more than 55 countries from January 11 to February 18, 2026. No exploitation of FortiGate vulnerabilities was observed—instead, this campaign succeeded by exploiting exposed management ports and weak credentials with single-factor authentication, fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This activity is distinguished by the threat actor’s use of multiple commercial GenAI services to implement and scale well-known attack techniques throughout every phase of their operations, despite their limited technical capabilities. AWS infrastructure was not observed to be involved in this campaign. Amazon Threat Intelligence is sharing these findings to help the broader security community defend against this activity.
This investigation highlights how commercial AI services can lower the technical barrier to entry for offensive cyber capabilities. The threat actor in this campaign is not known to be associated with any advanced persistent threat group with state-sponsored resources. They are likely a financially motivated individual or small group who, through AI augmentation, achieved an operational scale that would have previously required a significantly larger and more skilled team. Yet, based on our analysis of public sources, they successfully compromised multiple organizations’ Active Directory environments, extracted complete credential databases, and targeted backup infrastructure, a potential precursor to ransomware deployment. Notably, when this actor encountered hardened environments or more sophisticated defensive measures, they simply moved on to softer targets rather than persisting, underscoring that their advantage lies in AI-augmented efficiency and scale, not in deeper technical skill.
As we expect this trend to continue in 2026, organizations should anticipate that AI-augmented threat activity will continue to grow in volume from both skilled and unskilled adversaries. Strong defensive fundamentals remain the most effective countermeasure: patch management for perimeter devices, credential hygiene, network segmentation, and robust detection for post-exploitation indicators.
Campaign overview
Through routine threat intelligence operations, Amazon Threat Intelligence identified infrastructure hosting malicious tooling associated with this campaign. The threat actor had staged additional operational files on the same publicly accessible infrastructure, including AI-generated attack plans, victim configurations, and source code for custom tooling. This inadequate operational security provided comprehensive visibility into the threat actor’s methodologies and the specific ways they leverage AI throughout their operations. It’s like an AI-powered assembly line for cybercrime, helping less skilled workers produce at scale.
The threat actor compromised globally dispersed FortiGate appliances, extracting full device configurations that yielded credentials, network topology information, and device configuration information. They then used these stolen credentials to connect to victim internal networks and conduct post-exploitation activities including Active Directory compromise, credential harvesting, and attempts to access backup infrastructure, consistent with pre-ransomware operations.
Initial access: Mass credential abuse
The threat actor’s initial access vector was credential-based access to FortiGate management interfaces exposed to the internet. Analysis of the actor’s tooling supported systematic scanning for management interfaces across ports 443, 8443, 10443, and 4443, followed by authentication attempts using commonly reused credentials.
FortiGate configuration files represent high-value targets because they contain:
SSL-VPN user credentials with recoverable passwords
Administrative credentials
Complete network topology and routing information
Firewall policies revealing internal architecture
IPsec VPN peer configurations
The threat actor developed AI-assisted Python scripts to parse, decrypt, and organize these stolen configurations.
Geographic distribution
The campaign’s targeting appears opportunistic rather than sector-specific, consistent with automated mass scanning for vulnerable appliances. However, certain patterns suggest organizational-level compromise where multiple FortiGate devices belonging to the same entity were accessed. Amazon Threat Intelligence observed clusters where contiguous IP blocks or shared non-standard management ports indicated managed service provider deployments or large organizational networks. Concentrations of compromised devices were observed across South Asia, Latin America, the Caribbean, West Africa, Northern Europe, and Southeast Asia, among other regions.
Following VPN access to victim networks, the threat actor deploys a custom reconnaissance tool, with different versions written in both Go and Python. Analysis of the source code reveals clear indicators of AI-assisted development: redundant comments that merely restate function names, simplistic architecture with disproportionate investment in formatting over functionality, naive JSON parsing via string matching rather than proper deserialization, and compatibility shims for language built-ins with empty documentation stubs. While functional for the threat actor’s specific use case, the tooling lacks robustness and fails under edge cases—characteristics typical of AI-generated code used without significant refinement.
The tool automates the post-VPN reconnaissance workflow:
Ingesting target networks from VPN routing tables
Classifying networks by size
Running service discovery using gogo, an open-source port scanner
Automatically identifying SMB hosts and domain controllers
Integrating vulnerability scanning using Nuclei, an open-source vulnerability scanner, against discovered HTTP services to produce prioritized target lists.
Post-exploitation methodology
Once inside victim networks, the threat actor follows a standard approach leveraging well-known open-source offensive tools.
Domain compromise: The threat actor’s operational documentation details the intended use of Meterpreter, an open-source post-exploitation toolkit, with the mimikatz module to perform DCSync attacks against domain controllers. This allowed the actor to extract NTLM password hashes from Active Directory. In confirmed compromises, the attacker obtained complete domain credential databases. In at least one case, the Domain Administrator account used a plaintext password that was either extracted from the FortiGate configuration through password reuse or was independently weak.
Lateral movement: Following domain compromise, the threat actor attempts to expand access through pass-the-hash/pass-the-ticket attacks against additional infrastructure, NTLM relay attacks using standard poisoning tools, and remote command execution on Windows hosts.
Backup infrastructure targeting: The threat actor specifically targeted Veeam Backup & Replication servers, deploying multiple tools for extracting credentials, including PowerShell scripts, compiled decryption tools, and exploitation attempts leveraging known Veeam vulnerabilities. Backup servers represent high-value targets because they typically store elevated credentials for backup operations, and compromising backup infrastructure positions an attacker to destroy recovery capabilities before deploying ransomware.
Limited exploitation success: The threat actor’s operational notes reference multiple CVEs across various targets (CVE-2019-7192, CVE-2023-27532, and CVE-2024-40711, among others). However, a critical finding from this analysis is that the threat actor largely failed when attempting to exploit anything beyond the most straightforward, automated attack paths. Their own documentation records repeated failures: targeted services were patched, required ports were closed, vulnerabilities didn’t apply to the target OS versions, . Their final operational assessment for one confirmed victim acknowledged that key infrastructure targets were “well-protected” with “no vulnerable exploitation vectors.”
AI as a force multiplier
Amazon Threat Intelligence analysis revealed that the actor uses at least two distinct commercial LLM providers throughout their operations.
AI-generated attack planning: The threat actor used AI to generate comprehensive attack methodologies complete with step-by-step exploitation instructions, expected success rates, time estimates, and prioritized task trees. These plans reference academic research on offensive AI agents, suggesting the actor follows emerging literature on AI-assisted penetration testing. The AI produces technically accurate command sequences, but the actor struggles to adapt when conditions differ from the plan. They cannot compile custom exploits, debug failed exploitation attempts, or creatively pivot when standard approaches fail.
Multi-model operational workflow: Amazon Threat Intelligence identified the actor using multiple AI services in complementary roles. One serves as the primary tool developer, attack planner, and operational assistant. A second is used as a supplementary attack planner when the actor needs help pivoting within a specific compromised network. In one observed instance, the actor submitted the complete internal topology of an active victim—IP addresses, hostnames, confirmed credentials, and identified services—and requested a step-by-step plan to compromise additional systems they could not access with their existing tools.
AI-generated tooling at scale: Beyond the reconnaissance framework, the actor’s infrastructure contains numerous scripts in multiple programming languages bearing hallmarks of AI generation, including configuration parsers, credential extraction tools, VPN connection automation, mass scanning orchestration, and result aggregation dashboards. The volume and variety of custom tooling would typically indicate a well-resourced development team. Instead, a single actor or very small group generated this entire toolkit through AI-assisted development.
Threat actor assessment
Based on comprehensive analysis, Amazon Threat Intelligence assesses this threat actor as follows:
Motivation: Suspected financially motivated, based on widespread, indiscriminate targeting and low sophistication
Language: Russian-speaking, based on extensive Russian-language operational documentation
Skill level: Low-to-medium baseline technical capability, significantly augmented by AI. The actor can run standard offensive tools and automate routine tasks but struggles with exploit compilation, custom development, and creative problem-solving during live operations
AI dependency: Extensive reliance across all operational phases. AI is used for tool development, attack planning, command generation, and operational reporting across multiple commercial LLM providers
Operational scale: Broad. Compromised devices across dozens of countries, with evidence of sustained operations over an extended period
Post-exploitation depth: Shallow. Repeated failures against hardened or non-standard targets, with a pattern of moving on rather than persisting when automated approaches fail
Operational security: Inadequate. Detailed operational plans, credentials, and victim data stored without encryption alongside tooling
Amazon’s response
Amazon Threat Intelligence remains committed to helping protect customers and the broader internet ecosystem by actively investigating and disrupting threat actors.
Upon discovering this campaign, Amazon Threat Intelligence took the following actions:
Shared actionable intelligence, including indicators of compromise, with relevant partners
Collaborated with industry partners to broaden visibility into the campaign and support coordinated defense efforts
Through these efforts, Amazon helped reduce the threat actor’s operational effectiveness and enabled organizations across multiple countries to take steps to disrupt the efficacy of the campaign.
Defending your organization
This campaign succeeded through a combination of exposed management interfaces, weak credentials, and single-factor authentication—all fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This underscores that strong security fundamentals are powerful defenses against AI-augmented threats. Organizations should review and implement the following.
1. FortiGate appliance audit
Organizations running FortiGate appliances should take immediate action:
Ensure management interfaces are not exposed to the internet. If remote administration is required, restrict access to known IP ranges and use a bastion host or out-of-band management network
Change all default and common credentials on FortiGate appliances, including administrative and VPN user accounts
Rotate all SSL-VPN user credentials, particularly for any appliance whose management interface was or may have been internet-accessible
Implement multi-factor authentication for all administrative and VPN access
Review FortiGate configurations for unauthorized administrative accounts or policy changes
Audit VPN connection logs for connections from unexpected geographic locations
2. Credential hygiene
Given the extraction of credentials from FortiGate configurations:
Audit for password reuse between FortiGate VPN credentials and Active Directory domain accounts
Implement multi-factor authentication for all VPN access
Enforce unique, complex passwords for all accounts, particularly Domain Administrator accounts
Review and rotate service account credentials, especially those used in backup infrastructure
3. Post-exploitation detection
Organizations that may have been affected should monitor for:
Unexpected DCSync operations (Event ID 4662 with replication-related GUIDs)
New scheduled tasks named to mimic legitimate Windows services
Unusual remote management connections from VPN address pools
LLMNR/NBT-NS poisoning artifacts in network traffic
Unauthorized access to backup credential stores
New accounts with names designed to blend with legitimate service accounts
4. Backup infrastructure hardening
The threat actor’s focus on backup infrastructure highlights the importance of:
Isolating backup servers from general network access
Patching backup software against known credential extraction vulnerabilities
Monitoring for unauthorized PowerShell module loading on backup servers
Implementing immutable backup copies that cannot be modified even with administrative access
AWS-specific recommendations
For organizations using AWS:
Enable Amazon GuardDuty for threat detection, including monitoring for unusual API calls and credential usage patterns
Use Amazon Inspector to automatically scan for software vulnerabilities and unintended network exposure
Use AWS Security Hub to maintain continuous visibility into your security posture
Use AWS Systems Manager Patch Manager to maintain patching compliance across EC2 instances running network appliances
Review IAM access patterns for signs of credential replay following any suspected network device compromise
Indicators of compromise (IOCs)
This campaign’s reliance on legitimate open-source tools—including Impacket, gogo, Nuclei, and others—means that traditional IOC-based detection has limited effectiveness. These tools are widely used by penetration testers and security professionals, and their presence alone is not indicative of compromise. Organizations should investigate context around matches, prioritizing behavioral detection (anomalous VPN authentication patterns, unexpected Active Directory replication, lateral movement from VPN address pools) over signature-based approaches.
IOC Value
IOC Type
First Seen
Last Seen
Annotation
212[.]11.64.250
IPv4
1/11/2026
2/18/2026
Threat actor infrastructure used for scanning and exploitation operations
185[.]196.11.225
IPv4
1/11/2026
2/18/2026
Threat actor infrastructure used for threat operations
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

 Login