Today we’re publishing patching-bugs and regression-hunt, two plugins that let engineers delegate patch development and regression checks to agents. Our patching-bugs plugin reproduces reported bugs, develops fixes, and tests them. The regression-hunt plugin checks whether any changes break previously working and supported behavior. Engineers can direct the work and review their results; maintainers can supply their own security assumptions and patching requirements, so the agents work within the project’s rules.
We built patching-bugs and regression-hunt through Patch the Planet, our joint initiative with OpenAI, where we’ve co-authored hundreds of security patches for widely used open-source projects. Motivated by our major successes on projects like Scapy, our plugins draw on our analysis of merged patches and thousands of our engineers’ Codex sessions.
The plugins provide maintainers with a structured workflow, evidence, independent checks, and best practices to improve their patching hygiene. In our preliminary evaluations, regression-hunt produces 25% fewer false-positive findings than a baseline Codex agent prompted to “review the PR for regressions.”
Standardizing the patching process
Our September post reported regressions introduced by some of our Patch the Planet patches. Since then, we’ve reviewed every patch that a Trail of Bits engineer authored and maintainers merged upstream. The review confirmed 21 regressions from over 130 PRs merged: 16 functional, one performance, and four build/test. None broke a security protection.
(“Regression” refers to a new defect introduced by a change that breaks previously correct and supported behavior along a path a real user or attacker can reach.)
For each patch, an agent looked for potential regressions, confirmed each one with a proof-of-concept (PoC) run before and after the change, and then passed the results to an engineer for review.
The review was noisy: today’s bug disclosures arrive at an unprecedented speed and scale, and for patching to keep pace, the industry needs to increase its signal-to-noise ratio. The 21 confirmed regressions were identified among 58 candidates in a single run (~36% precision). But because agents take many different approaches and reach different results, each run generates more candidates to manually sort through.
That led us to two conclusions:
To introduce fewer regressions, we needed a standard way to write patches, with the same checks applied every time.
To catch the regressions we still introduce, we needed a standard way to check for them, with written rules for what counts as a regression.
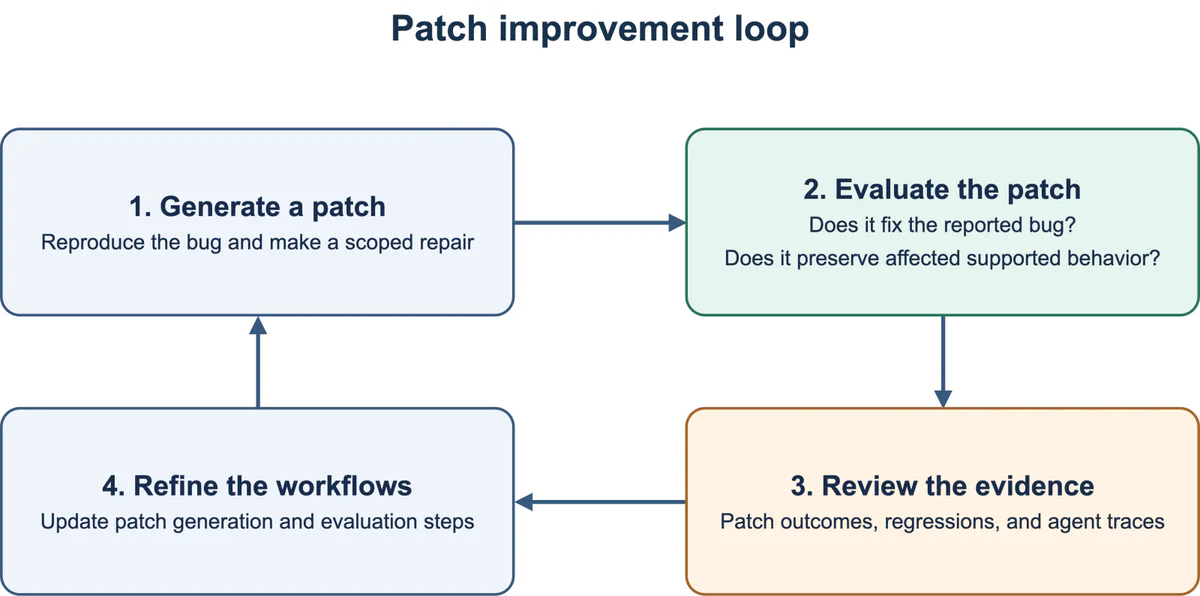
Standardizing both steps also makes every run repeatable and comparable. No fixed checklist will catch every regression, so we collect agent trajectories from our engineers’ patching sessions, and use the tasks that an earlier version failed to benchmark for the next one (figure 1).
Figure 1: Feedback loop for generating and evaluating patches.
How we designed the plugins
We used two primary sources to guide the design of our plugins: a review of every patch we merged upstream and the thousands of Codex sessions our engineers used to write those patches.
This led to four principles that shaped our patching-bugs and regression-hunt plugins:
Opinionated guidance in as few words as possible. We give the agent wide latitude and record only Trail of Bits’ judgment of what constitutes a good patch and a real regression. The goal is to direct the agent towards the desired result with the least possible guidance.
Modular steps. You don’t have to run either plugin end-to-end, as both provide multiple skills that can be used in tandem or in isolation.
Strict input and output schemas. Every step takes and returns a defined schema that includes the claim, the code revision, the required check, the raw evidence, and open questions. Fixed schemas reduce variability across runs and allow each step to verify the previous step’s work rather than trusting its summary.
A live proof of concept for every claim. Every conclusion depends on a PoC run against a live deployment: a built, running instance of the project, reached through the interfaces a real user would use. When reproducing a bug, proving a fix, and confirming a regression, if a step can’t produce a live PoC, its result is inconclusive.
regression-hunt reduces false positive rates
The regression-hunt plugin (Figure 2):
Enumeratescandidate regressions by tracing the changed code (the diff) through its callers to its real interfaces.
Reproduces each candidate regression on a live deployment of the system.
Replays the PoC on the live deployment on a fresh-context agent.
Judges the results of all the previous steps to validate that the proof meets the requirements of a regression.
Figure 2: The regression-hunt workflow.
In addition to the four principles above, there are two core aspects that are critical to the plugin:
Defining a regression: The plugin has strong opinions about what a regression is and, more importantly, what a regression is NOT. The burden of proof is placed on the agent (specifically during the “adjudication agent” step) to prove that there is sufficient evidence to show that the suspected regression is not a false positive, an incomplete fix, a latent bug, a pre-existing bug, and so on. The plugin only reports a regression if all of these gates are passed.
Incorporating a threat model: If a threat model is available, the orchestrator will intentionally pass this document as part of the global context for each individual agentic step. This is an attempt to require each step/agent to refer back to the threat model before reaching its conclusion.
Our review of merged PRs yielded a set of 21 confirmed regressions that we could use to evaluate regression-hunt. We used the whole set to compare the plugin with a baseline Codex agent prompted to “review the PR for regressions.”
Across those runs, regression-hunt produced 25% fewer false-positive findings than the baseline, with a 95% confidence interval of 14% to 38%. Its strict evidence requirements also left some known regressions classified as borderline: the plugin identified a possible regression but did not gather enough evidence to confirm it. Fewer false positives therefore came with a tradeoff in how many known regressions it could confidently report.
Next, we’ll investigate why these cases remained borderline and improve the plugin’s strategies for gathering evidence. Our goal is to confirm more real regressions while giving maintainers clearer information when the evidence remains inconclusive.
patching-bugs streamlines best practices from thousands of agent sessions
The patching-bugs plugin is a distillation of all the best practices we’ve identified by analyzing thousands of Codex sessions by Trail of Bits engineers (Figure 3). In addition to the more traditional capabilities (such as reproduction on live deployments and independent adversarial review), the plugin emphasizes:
The three-arm proof: The proof runs the same reproduction against three specifications: the original code must fail, the patched code must pass, and a complete revert must fail again. Bringing the bug back by removing the patch provides stronger evidence that the patch—rather than an unrelated environment or test change—actually fixed the bug.
Invariant-guided repair: The patch attempts to fix the underlying, violated security invariant rather than fix the specific bug. This helps generalize the patch for possible variants of the same bug class.
Incorporates regression analysis: The plugin mandates that regression-hunt is run to ensure that any patch goes through the same standard pipeline to check for mistakes.
Figure 3: The patching-bugs workflow.
What’s next for the plugins
Both patching-bugs and regression-hunt will continue to evolve. Our engineers are using them in their Patch the Planet work now, and we’re collecting data on how they’re being used, what works, and what doesn’t. That data, along with better evaluations, will shape the next version’s capabilities:
Evaluate patching-bugs. We’re building an evaluation that measures whether the plugin’s patches fix the reported bug and its variants without introducing regressions.
Learn from agent traces. We’re analyzing the first batch of trace-level data from our engineers’ sessions. It will show whether Codex follows the rules and definitions required at each step, which steps it skips, and where its evidence is weakest.
Make the plugins more configurable. patching-bugs already reads a project’s own patching guidelines (more on that in a bit). Next, we want maintainers to be able to choose whether to minimize patch sets—or, when broader coverage is worth more false positives, to loosen regression-hunt’s rules to surface more candidates.
These plugins encode best practices we’ve found for an agent to patch a bug properly, and they improve when you tell them how your project works.
The plugins work best when you input two kinds of project knowledge:
A THREAT_MODEL.md, which tells agents what counts as a vulnerability or a regression. The regression-hunt plugin passes it to every step, so each agent has to check its conclusions against the file. It should define the following: assets whose compromise matters, trust boundaries, access controls, supported configurations, specifications on what is or isn’t a vulnerability, and evidence required for a valid bug report (example).
A PATCHING_GUIDELINES.md (or AGENTS.md), which tells agents and patching-bugs how your project wants fixes written. It should outline how to build and test the project, how big a fix should be, where a fix should go, how to present proposed changes, and what a regression test must show (example).
For our Patch the Planet work with GPAC, our engineers wrote a threat model and a project-specific patching skill that captures how GPAC’s maintainers want bugs reproduced, what evidence a fix needs, and what a patch must preserve. Liboqs and validator.js have also published threat models in accordance with our guidance.
The more comprehensive and specific these files are to your project, code conventions, and operating style, the better the output you’ll receive.
The industry needs to focus on patching
As AI accelerates bug discovery, we need to turn those findings into reliable fixes just as quickly. Solutions need to balance speed and quality: an agent needs to understand a report, decide what needs to change, and check that a patch fixes the issue without introducing regressions. Our patching-bugs and regression-hunt plugins bring what we’ve learned from Patch the Planet into that workflow, helping maintainers move from a bug report to a patch they can confidently review and ship.
Install patching-bugs and regression-hunt, add a THREAT_MODEL.md and a PATCHING_GUIDELINES.md to your repository, and put them to work on your next bug report. Give the tools your project’s context so they can help you focus on the right fix and validate it faster. Then share your feedback, including comments about where our defaults don’t fit your project. Those real-world cases will help us build the next version.
I tested 25 of the most popular package managers to check whether they detect a compromised package repository injecting malicious code into legitimate packages. This code integrity problem could be solved using cryptographic hashes or signatures, but many package managers are still vulnerable to this threat. Of the 25 package managers reviewed1, fewer than half used lockfiles that checked for tampering by default, and only two verified the integrity of every package they downloaded.
Supply-chain attacks caused by developer compromise are a common story, but imagine what happens if ongoing mitigation attempts, including work by Trail of Bits2, are successful. If developers of popular packages are no longer the easiest targets, attackers will shift their focus to the next weakest link in the system: the package repositories that serve the code. The cryptographic answers to this problem are more subtle than they appear, and many implementations fall short due to deliberate design choices, resource prioritization, or the complexity of developer-friendly solutions.
One natural answer is to include a cryptographic hash of a package’s contents in a lockfile and compare hashes after downloading the package. This automatic verification was the default behavior in about half of the package managers I tested, but others required extra configuration to include or verify these hashes, used hashes in a cryptographically insecure way, or lacked hashes entirely. This is summarized in the following table.
CocoaPods, Composer, Conan, cpanminus, Gem, Maven, PowerShellGet, PSResourceGet, R
Table 1: Lockfile-based security of a package manager fetching dependencies from a malicious repository, categorized by how much work it takes a developer to achieve integrity. Experimentally verified for a particular configuration. Caveats detailed below.
Another natural approach is to use signatures, avoiding the need to securely distribute a hash for every package. However, in my tests, only Go verified signatures by default; others required extra configuration, lacked verification code, or did not support signatures.
Table 2: Signature-based security of various package managers. Also experimentally verified and subject to similar caveats.
As both tables show, I found a surprising variation in the cryptographic designs and the level of protection they provide. Despite the challenges, I also found several communities on the frontier of this integrity problem that are bringing improved designs to reality. This post explores those variations, showing where certain designs fall short, why code integrity is harder to solve than it appears, and what cryptographic designs might be adopted in the future.
Simulating malicious package repositories
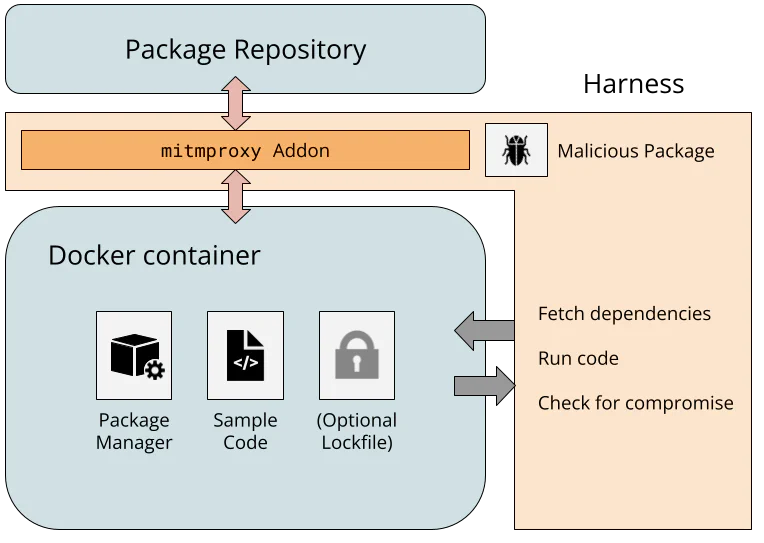
Studying the cryptographic behavior of 25 package managers is quite the challenge. I wanted to minimize manual analysis, but also be 100% confident when I claim an attack from a malicious package repository is possible. To solve this problem, I built a testing harness based on Docker containers and mitmproxy that dynamically evaluates the security of package managers against a malicious server.
Figure 1: Experimental design of the test harness used to simulate malicious package repositories
The Ubuntu-based Docker images include a package manager, sample code, and optionally a lockfile. There are conflicting opinions about whether to include lockfiles in source code repositories, so I tested both configurations. The harness instructs the package manager to fetch dependencies from the repository, and the resulting network request routes through a WireGuard network to a custom mitmproxy addon.
Because the mitmproxy TLS CA is installed in the Docker image, the addon can fully manipulate the plaintext from the package repository, simulating a compromised server. I assumed any web-facing server could be compromised (e.g., Composer fetches metadata from Packagist and packages from GitHub), but backend resources, like any private signing keys, remain secure. The simulated repository embeds malicious code into the downloaded packages, and if the sample code executes the malware, the attack is successful.
I tried to keep the experimental setup reflective of real-world usage, but there are limitations. I installed the latest package manager versions, followed quickstart guides for setting up sample projects inside the container, and picked popular packages from public repositories to infect. I ran package manager commands with default flags to see if extra steps, like modifying the project manifest or running extra commands, were needed to enforce cryptographic integrity. However, I am limited to testing a single package with a single package manager version on a single platform, and the test conditions (e.g., PowerShell and CocoaPods on Ubuntu) may not represent the most common usage patterns. The setup isn’t meant to show that every developer is vulnerable to a malicious package repository, just that a developer following reasonable conventions is.
With the package managers installed and network intercept functional, one (mostly) promising observation is clear.
HTTPS is (almost) everywhere
Our harness architecture captures all network traffic, so it’s easy to test that package managers are using TLS and validating the certificates. In almost every package manager, they are.
The exception is cpanminus, the frequentlyrecommended package manager for Perl. cpanminus uses unencrypted HTTP by default to connect to the Perl package repository, allowing any active network attacker to inject malicious code into downloaded packages. This vulnerability has been known for years, but the cpanminus developer has not switched to HTTPS, since doing so would be a breaking change to default behavior.3
Hash functions don’t always provide integrity
By using the mitmproxy addon to modify the package repository responses, I could investigate how different package managers use cryptographic hashes. Hashes are a natural way to ensure that a downloaded file has not been tampered with, but the main question is how the package manager learns the correct hash in the first place.
Microsoft’s vcpkg package manager for C and C++ libraries offers an interesting example. The package manager source code includes content hashes for thousands of dependencies. When a developer updates their library and wants to register the new content in vcpkg, they recompute the hash of their package and open a pull request against the vcpkg source code with the new hash and link to the package. When a package is downloaded by vcpkg, the hash is checked. So as long as the package manager is trusted, this approach is fully secure against a malicious package repository.4
Hashes in lockfiles
It is significantly more common that the package manager learns the correct hash via a lockfile. A lockfile is frequently created by a package manager, resides alongside a project’s source code, and references specific versions of dependencies needed by the project. If a developer checks a lockfile with cryptographic hashes into the source code repository, and the user’s package manager validates downloaded packages against the hashes, then the user’s dependencies perfectly match the developer’s.
This is how it works for the Bun package manager for JavaScript projects. Installing a package with bun addupdates the bun.lock lockfile; committing the lockfile to Git and calling bun install on another copy of the repo verifies the hash in the lockfile against the new copy of the dependency. Similar behavior is found in npm, pnpm, and Yarn (also JavaScript package managers); uv and Poetry (Python package managers); Bundler (for Ruby); Cargo (for Rust); and SwiftPM (for Swift).
Other package managers support lockfiles, but with more steps than the standard add/restore process. Python’s Pip has experimental support for the pylock.toml format, and Conda has the optional library Conda lock. NuGet, the .NET package manager, generates a lockfile after adding the RestorePackagesWithLockFile property to the project.
Many package managers (Maven, R, PowerShellGet, PSResourceGet, and cpanminus) do not have dedicated lockfiles, and some have lockfiles (Gradle’s gradle.lockfile5 and Gem’s Gemfile.lock) without hashes in them.
Hashes present, but not for integrity
Surprisingly, I found a few examples where the lockfiles had a hash, but could still be compromised by a malicious server. This is not necessarily reflective of a vulnerability, since the underlying behavior is clearly documented, but it shows how there are multiple valid opinions about how lockfiles should be structured and consumed. Nevertheless, a user who is accustomed to the behavior of one package manager may be surprised by that of another.
The first example is the Pub package manager for Dart and Flutter. The following excerpt of a pubspec.lock file includes a SHA-256 hash for the uuid package.
If a user calls flutter pub get to fetch dependencies, Pub downloads the package from the pub.dev server and computes the hash of the returned binary. If there is a mismatch, Pub detects the error, but installs the package anyway.
The existing content-hash from pubspec.lock doesn't match contents for:
 * uuid-4.6.0 from "https://pub.dev"

This indicates one of:
 * The content has changed on the server since you created the pubspec.lock.
 * The pubspec.lock has been corrupted.

The content-hashes in pubspec.lock has been updated.
This is documented behavior, and requires the non-default --enforce-lockfile option to block installation6.
Overwriting the lockfile after a hash mismatch was also the default behavior in pnpm until version 11.4 from May 2026, when it was changed to close “supply-chain holes.” Like Pub, pnpm also supported a non-default --frozen-lockfile flag, indicating that the previous behavior which updated the lockfile was expected.
Next, here is an excerpt of a conan.lock file, used by the Conan package manager for C and C++.
This includes the package name (zlib), the version number (1.3.1), a recipe revision cac0f6daea041b0ccf42934163defb20, and a timestamp. The 128-bit revision is an MD5 hash that includes source code. However, this hash is not intended to provide cryptographic security, but rather serves as a unique identifier. When Conan installs dependencies using this lockfile, it uses the recipe revision hash to download a particular file from the ConanCenter repository, but it does not recompute the recipe hash. Even if it did, there’s a separate package revision hash for platform-specific binaries that is not in the lockfile, and MD5 collisions could allow an attacker to create two distinct recipes with different behavior but the same hash.
The CocoaPods dependency manager for Swift and Objective-C has a similar pattern. Here is part of a Podfile.lock file for a project that uses the popular Files dependency.
This 160-bit checksum is the SHA-1 hash of the Files Podspec, which contains the following link to the source code. CocoaPods uses this link to fetch the Git repository.
So even though the lockfile can prevent tampering with the GitHub URL in the Podspec (setting aside expensive SHA-1 collision attacks), a compromised GitHub server could just serve a malicious version of the repository with the same tag.
Finally, the Composer dependency manager for PHP includes commit hashes in the composer.lock file, as in the following excerpt.
However, even though the b094ded... commit hash uniquely identifies the code, the ZIP archive in the URL does not include the Git tree as a way to verify the hash. Once again, GitHub could serve a malicious ZIP archive without detection by Composer.
Lockfiles have many roles besides supply-chain integrity
The previous experimental results show that lockfile hashes often can be used to enforce package integrity, but this is not their sole or even original purpose. Alternatively, they can lock dependencies to a particular functionality, enable an easy way for application developers to share a consistent environment, or facilitate reproducible builds. Analyzing package manager lockfiles through the lens of supply-chain security is a recent interpretation that can be at odds with their original design. The recent change to pnpm’s --frozen-lockfile is one example.
Another example of this tension is the question of whether the lockfile should be committed to version control. Most modern guidance recommends committing the lockfile for applications, since the final build environment is fully controlled. The question is more complicated for libraries, since package managers often ignore libraries’ lockfiles to avoid locking to conflicting transitive dependencies. Committing the lockfile makes it easier to develop the library by sharing a consistent build environment with other developers, but excluding the lockfile makes it easier to catch conflicts with different dependency versions before they are found by users. Many package managers recommend committing the lockfile for libraries (e.g., npm, pnpm, Poetry, uv, and Yarn), some recommend excluding it (e.g., Bundler), and some leave it up to the developer (e.g., Cargo).
Many of these questions are explored in a recent study by Gamage et al. The authors explore lockfile design decisions for seven package managers, analyze published projects, and perform semi-structured interviews with 15 developers. They find that the practice of committing a lockfile varies by which package manager is used, and categorize five benefits to using lockfiles, as perceived by the interview subjects: build determinism, integrity, transparency into indirect dependencies, debugging, and security scanning. Some of the developers also preferred to not use lockfiles, citing a preference for end users to resolve to the latest version of a dependency, which may have more bug fixes and vulnerability patches.
The diversity of package manager designs and views surrounding the purpose of lockfiles makes it difficult to prescribe a single recommendation. With regard to supply-chain integrity, it is common, but not universal, to view lockfiles as a source of integrity that should be committed with the source code. For package managers with lockfiles that do not provide cryptographic integrity, it is worth considering whether their users share that expectation. Even when lockfile hashes can provide cryptographic integrity, locking to specific package hashes means that users do not immediately receive subsequent updates or security fixes, since the newer package has a different hash. This leads to frequent lockfile bumping to distribute the latest hashes. Wanting immediate updates is a separate concern from wanting package integrity, but the current, common approach of using hashes in lockfiles is at odds with that goal. In conclusion, lockfile hashes are often, but not always, effective at providing cryptographic integrity, but do not work in every situation.
Signatures are common; verification is not
Signatures are a natural way to address these shortcomings, but implementations frequently fall short. In theory, developers could sign every release with their own private key, and the package manager could check the signature of the package it downloads from the package repository. In fact, signatures are relatively common in different package ecosystems, but proper signature validation is surprisingly lacking. The reality of using signatures to provide code integrity is more nuanced than it seems, and package managers have different approaches to the problem.
Many package managers have no signatures available. Arguably, vcpkg does not need them, because all package hashes are distributed with the manager, but this leaves Cargo, CocoaPods, Composer, Conan, Conda, Pub, R, and SwiftPM7. The Conan developers are aware and previously decided not to fix it, citing several implementation challenges and suggesting organizations where integrity is critical could run their own repository server. Cargo developers are actively considering different signing designs, but this effort is still in progress. Composer developers have been implementing many new protections against supply-chain attacks, with future plans for artifact integrity.
Repository signing
One straightforward approach, known as repository signing, is when the package repository signs every package once it’s uploaded, and the repository’s public key is distributed with the package manager. This doesn’t solve the problem of a totally compromised package repository, since a malicious package repository could legitimately sign a malicious package, but it would protect against untrusted mirrors or a partial compromise of a package repository’s serving infrastructure.
Repository signatures are used by the npm Registry, the NuGet Registry, and the PAUSE server for Perl module distribution. In the npm Registry, signatures are distributed within package metadata with repository-specific public keys. NuGet Registry repository signatures are found in .signature.p7sfiles within the distributed ZIP package, again with repository-specific public keys. The PAUSE server takes a different approach, using its GPG key to batch sign the cryptographic hashes of several packages at a time.
Developer signing
Developer signing involves the developer maintaining the private key and signing the package before uploading it to the repository for distribution. This prevents the package repository from tampering with the contents, but it also provides a way for the package repository to authenticate the uploader.
There are two common approaches for a developer asserting their public key. In the first approach, the public key is distributed out-of-band. The Maven Central repository (used by Maven and Gradle) and the RubyGems repository (used by the gem and Bundler package managers) bothsupport this type of developer signing. Maven Central uses PGP signatures, and developer keys are distributed by public keyservers. RubyGems uses self-signed certificates, and their distribution is left to the developers (e.g., rspec). The major difference is that developer signing is mandatory for Maven Central, and optional for RubyGems. Developer signing is rare for RubyGems, due to the lack of an established chain of trust, and a previous attempt to introduce a certificate authority failed.
The second approach involves a chain of trust. The NuGet Registry and PowerShell Gallery both support developer signatures. Neither makes signatures mandatory, but the PowerShell Gallery recommends it and the NuGet Registry has strict requirements if developer signing is used. In both, the developer’s key must chain to a trusted CA, and acquiring a valid code-signing certificate can cost hundreds of dollars per year. The benefit of this approach is that trusted root certificates can be preinstalled on the platform, allowing package managers to verify public keys.
One downside of developer signing is that developers are responsible for key management, and they can lose the ability to update their code if they lose access to their key.
Identity-based signing
An increasingly common middle ground is “identity-based” or “keyless” signing from Sigstore. Rather than require developers to manage long-term private keys, a developer can use Sigstore’s Fulcio CA to issue a fresh signing certificate on demand, for free. To prevent impersonation, the developer proves their identity with an OIDC token: a cryptographically signed statement from a third party like Google, Microsoft, or GitHub that attests to the email address, username, or potentially other claims about the developer’s identity. The verifier can check that the username is correct and the certificate chain links back to Sigstore Fulcio’s root certificate, proving that someone with access to that account created the signature.
Keyless signing is particularly useful because it can be integrated into a developer’s existing workflow-based deployment pipeline. This is frequently called provenance attestation or trusted publishing8. GitHub and GitLab provide OIDC tokens to Actions and CI/CD workflows that attest to the build workflow, the repository, and the commit hash. A workflow can use this token to obtain a signing certificate from Sigstore, sign the built package, and upload the signed package to the package repository. Since the signing certificate includes the commit hash and workflow details, this cryptographically links the built binary artifact to its source code.
Provenance attestation via Sigstore is supported by Python’s PyPI, the npm Registry, RubyGems repository, and Maven Central. While Sigstore attestations are not mandatory, there is already betteradoption than RubyGems’ optional support for developer-managed signing keys.
Verification code is skipped, unconfigured, or nonexistent
Unfortunately, just because these signatures exist does not mean they are being verified by package managers.
In the npm package manager, the repository signatures are not checked when running npm install. Checking the signatures requires running npm audit signatures, which uses Sigstore to validate the registry public keys and then validates the signatures of the installed packages. pnpm recently added the pnpm audit signaturescommand, but that implementation fetches the registry public keys from the potentially malicious registry rather than verifying with Sigstore, so an adversary could simply add their own key and signature. Bun and Yarn currently lack an equivalent audit signatures command.
In the NuGet package manager, the defaultsignatureValidationMode is accept, which installs invalidly signed packages. The user must set this to require and configure the list of trusted signers, such as with dotnet nuget trust source. These configurations (which include the repository public keys) can be securely distributed within a nuget.config configuration file, functioning as a lockfile that locks the trusted signers.
Ruby’s Gem and Bundler, and Java’s Maven and Gradle, which all use repositories with developer signatures, do not verify signatures by default. They require the user to manually add developer public keys (gem cert --add) or list the allowed public keys that should be trusted. In Maven, one can use the third-party pgpverify-maven-plugin with pgp-keys-map.list to specify the trusted PGP fingerprints. Gradle offers dependency verification, which works similarly.
Finally, several package managers seemingly lack any sort of verification code at all. Pip, uv, and Poetry do not currently have a way to verify identity-based attestations described in PEP740. cpanminus does not have a way to verify the integrity of the repository-signed CHECKSUMS file. It once did, but in response to a verification bypass vulnerability, this verification code was removed. Even though PowerShell is supported on non-Windows platforms, Authenticode signature verification isnot9. At one point, the PowerShell repository noted that this issue “should be fixed in a future release.”
Go package management and transparency logs
Go’s built-in package manager is the only one I tested that verifies signatures by default, and it also introduces one final concept for cryptographic package integrity. When go get or go mod download fetches a package10, it hashes the package contents and compares the hash, package name, and version against the checksum database. The contents of the database are registry-signed (analogous to PGP signatures in Perl’s PAUSE server), and the default checksum database public key is hardcoded in Go’s source code. As long as the checksum database’s private key is used honestly, this design ensures that the package name and version are enough to uniquely identify the binary contents of a package. As a result, the go.mod lockfile achieves package integrity without needing to store cryptographic hashes.11
Go’s checksum database is an example of a transparency log, or an immutable, global, tamper-resistant log of metadata. The same capability is provided by Sigstore’s Rekor and certificate transparency logs. In package managers, it cryptographically ensures that the package manager only ever installs the same binaries recorded by the transparency log. If everyone agrees on the transparency log, then everyone agrees on the package contents. This makes it more difficult for an adversary to selectively and undetectably target a victim with a malicious package. Transparency logs can still fail if there are othervulnerabilities, the log’s private key is compromised, or no one checks the transparency log for malicious behavior.
Of all the package managers I tested, Go performed the best at maintaining cryptographic integrity in the face of a compromised package repository or proxy. However, the registry-signature-like design means that much of the system’s trust is concentrated in a single private key.
A proposed cryptographic design for package managers
One potential approach that combines the ideas in this post is to include signature information in the lockfile. Rather than commit to the hash of a particular package, the lockfile could commit to a developer’s identity or public key. This reuses much of the infrastructure in place for lockfile hashes, but it separates the question of immediate updates from the question of package integrity.
With this design, the lockfile could specify a single dependency version (for build reproducibility) or a lower bound (for immediate updates), and the included identity ensures that a malicious repository or proxy cannot easily tamper with whatever package version the manager resolves to. In addition, a transparency log can protect against selective targeting, building on Sigstore’s identity-based signing and transparency log service. Sigstore avoids long-lived keys by default, but it also supports self-managed keys, KMS providers, and hardware tokens. This gives an easily adopted and secure default while still giving flexibility to developers who desire more control over their keys.
This idea is not new and not my own. Attestation identities are part of the pylock.toml Python lockfile specification, the trusted-keys in Gradle’s verification metadata, and the pgp-keys-map.list file in the pgpverify-maven-plugin for Maven. This is the direction that many package managers are already moving towards, as evidenced by the increasing adoption of Sigstore into publishing workflows, attention on supply-chain security, and bugfixes that specifically cite potential tampering by a malicious adversary. There is increasing recognition that this is a problem, and increasing appetite to fix it.
It won’t be easy. There are many subtle nuances that have to be considered and addressed, signing verification code needs to be developed and audited, and developers need to adopt the resulting design. In many of the package managers I reviewed as part of this project, I found communities of people who have been thinking about and pushing for cryptographic integrity and package signing for years. They know best what those package managers need, and they deserve the resources to make this a reality.
One of the greatest cryptographic success stories in the past decade has been the nearly universal adoption of HTTPS, driven in part by industry and community recognition of the security risks of unencrypted traffic, and the nonprofit Let’s Encrypt providing free and easy-to-use TLS certificates as a public good. Package signing is in a similar state now to where HTTPS was a decade ago: persistent adversaries are a huge concern, and cryptographic security is nearly nonexistent. Universal package signing is not here yet, but it is on the horizon. With the right attention and investment, we can make it a reality.
Acknowledgments
Thank you to William Woodruff for valuable discussions about lockfiles, identity signing, and the challenges of package manager security.
This post focuses on dependency managers for source code rather than system package managers like APT, Chocolatey, or Homebrew. The line between the two is blurred, but concentrating on one helps highlight particular usage and deployment patterns in that group. ↩︎
cpanminus is included in the default Docker container for Perl, but the container build scripts patch cpanminus to use HTTPS by default. ↩︎
A subtle distinction here is that vcpkg must be updated using git pull in order to fetch the latest package hashes, shifting the question from securely installing packages to securely updating the package manager. For consistency with other package managers, we do not consider this question, and we note this as a limitation of our threat model. ↩︎
Gradle can have a verification-metadata.xml file with content hashes, even though gradle.lockfile does not. ↩︎
Note that some flutter subcommands, including flutter run and flutter test, call flutter pub get by default, so these commands can also overwrite the pubspec.lock file unless called with --no-pub. ↩︎
The SwiftPM client has two main ways to download packages: via Git and via the custom Swift Package Registry Service Specification. The latter supports signatures, and the server protocol is implemented by private services such as JFrog Artifactory and AWS CodeArtifact. As far as I can find, there is no repository for the general public that implements this protocol, so I tested the signatureless Git format. ↩︎
Trusted publishing can also refer to using OIDC tokens to authenticate to a package repository, and it does not necessarily involve identity-based signing. ↩︎
Although I did not test PowerShell on Windows, the documented default ExecutionPolicy behavior is to block scripts on Windows client machines, and to require a valid signature for Windows servers. This achieves package integrity. ↩︎
Go calls these downloadable artifacts “modules,” which consist of “packages.” For the sake of consistent terminology with the rest of the post, I use “package” in the general sense, not the Go-specific one. ↩︎
The go.sum file stores hashes, but it is not a lockfile. Instead, it is a local cache for entries from the checksum database. ↩︎
Multihashing is one of those cryptographic tasks that’s easy not to think about too much. This is unfortunate, because multihashing is a common stumbling point when cryptographers try to use hashes.
As part of our goal to “fix software, not bugs,” Trail of Bits is introducing SequenceHash and its sister function SequenceMAC, a pair of related hash constructions that bring secure multihashing to developers using hash functions other than Keccak. We hope SequenceHash and SequenceMAC will help cryptographers avoid attacks that take advantage of ambiguous input encodings. The specification is open source, and is now a part of the Community Cryptography Specification Project (C2SP).
SequenceHash and SequenceMAC behave similarly to NIST’s TupleHash, but have the advantage of not being tied to a single hash function. They also don’t require developers to implement fiddly computations that aren’t byte-aligned. Instead, SequenceHash and SequenceMAC work out of the box with nearly any secure cryptographic hash function you care to use, including SHA256/384/512, BLAKE, and RIPEMD. SequenceMAC supports keys 32 bytes or longer (up to the ridiculous limit of ${2}^{128}-1$ bytes).
(It’s worth noting: SequenceHash and SequenceMAC rely on the security of the underlying hash for their own security. SequenceHash and SequenceMAC can’t magically make MD4 or SHA0 secure again. For the purposes of this document, it’s assumed that you have chosen a reasonable hash function like SHA256, not CRC32.)
To make SequenceHash and SequenceMAC easy to use, we’re releasing three initial implementations of SequenceHash and SequenceMAC: one each in Rust, Go, and Python. We’re also releasing a large set of test vectors that cover multiple hash functions and include intermediate values to help developers debug and verify their implementations.
Wait, “multihashing”?
Yeah, it’s a weird term, but the idea is pretty simple. “Multihashing” means “hashing a bunch of values together.” If you’ve ever read a cryptography paper, and there’s a step that says something like “compute the shared authenticator N=Hash(X, Y, Z, A, B),” that’s multihashing. You need to create a hash that incorporates the inputs X, Y, Z, A, and B. Unfortunately, the simple “solution” of concatenating the inputs and hashing the result can lead to serious security problems.
For example, consider what happens when you hash three inputs using “raw” SHA256:
Even though inputs are fed in through separate calls, they’re not separated from the perspective of the hash function—under the hood, the inputs are just concatenated.
As with many things in cryptography, multihashing is harder than you think. That’s a big problem because multihashing is a critical component of one of the most important tools in zero-knowledge proofs: the Fiat-Shamir transform. When you get multihashing wrong, you introduce the risk of forgeries into your zero-knowledge proofs. Given that zero-knowledge proofs play a major role in cryptocurrency nowadays, that sort of mistake is sometimes measured in millions of dollars.
But Fiat-Shamir transforms aren’t the only place where you might want to use multihashing. It’s not uncommon to need to hash a collection of related objects, where both the objects and the collection are variable in size. Think of authenticating the files in an archive, grouping multiple cryptocurrency transactions into a single hash, or hashing something as “simple” as somebody’s name.
Multihashing is also used when generating cryptographic commitments to values. In some protocols, one party must perform calculations using secret values, only to reveal them to other parties for later verification. Often, this is done by hashing the secret value along with a random “blinding” value and broadcasting the result to other parties as the commitment. If the boundary between the secret value and the blinding value isn’t clear, a “commitment” can sometimes be opened several different ways.
Unfortunately, nobody seems to have landed on a consistent, standard solution to this problem. Instead, across the open-source ecosystem and in our private audits, we find developers solving the problem in wildly different ways. Some of these solutions are insecure, like using separator characters that can also appear in the inputs. Others encode their data in a way that makes their separators unambiguous, but the encoding is unnecessarily complex and introduces subtle timing risks. Think of stuff like Base64-encoding byte strings and separating the results with dollar signs. We often see situations where some hash inputs are length-encoded, but not all. It’s the wild west out there.
There are tools specific to Fiat-Shamir transforms, like Merlin and our own decree, but they don’t work so well for general multihashing.
The most widely known standard for multihashing is TupleHash, defined in NIST SP 800-185. To be clear, TupleHash is great. It solves the multihashing problem in a straightforward way (length-prefix encoding), and it handles inputs of effectively unlimited size (if you’re regularly hashing more than ${2}^{2040}-1$ bits of input, Trail of Bits wants to party with you and your disrespect for physics). As a bonus, it naturally operates as an XOF. If TupleHash is available for you, it’s a great tool.
TupleHash has a downside, though: it’s only defined to work with Keccak, the function that underpins SHA3. If you replace Keccak with another hash function, several of the important security features (like length-extension resistance) can go away. If you don’t have a Keccak implementation handy, you’re out of luck. Given that SHA3 and Keccak adoption have been pretty lackluster over the last decade, that leaves a lot of cryptographers out in the cold. This is especially true in the government contracting sector, where CNSA 2.0 has mandated SHA384 and SHA512 for nearly everything.
This is a problem that cries out for a standardized solution. It calls for a complete specification. It begs for ready-to-use implementations available in multiple languages.
Enter SequenceHash
SequenceHash is a hash-agnostic multihashing construct, similar to the way HMAC is a hash-agnostic MAC construct. You can use SequenceHash with your favorite hash functions, including the entire SHA2 family, BLAKE, RIPEMD, and more.
What does SequenceHash offer?
SequenceHash offers four key features that prevent your hashed values from being mixed, extended, or replayed across contexts.
Unambiguous input encoding
Given two inputs $\left({A,\ B}\right)$, you are guaranteed that there is no other sequence of inputs $\left({{I}_{1},\ldots ,{I}_{t}}\right)$, for any length $t$, that will result in the same input to the underlying hash function.
In other words, the values you hash are guaranteed to be “semantically distinct.” There’s no chance of playing games with the beginnings and endings of inputs, and there’s no opportunity to mix up parts of $A$ with $B$ or vice versa.
SequenceHash helps cryptographers follow the Horton principle: you are hashing what you mean, and meaning what you hash.
Length-extension prevention
Several popular hash functions, including SHA256 and SHA512, are vulnerable to length extension attacks. If Alice has a secret value $A$ and sends $H\left({A}\right)$ to Bob, then Bob can craft a value $B$ such that he can compute $H\left({A||B}\right)$, even though he doesn’t know $A$.
SequenceHash doesn’t have that issue. It uses a double-hash construction that prevents Bob from learning the information he needs to compute $H\left({A||B}\right)$.
Built-in customization strings
If you’re developing cryptographic protocols, it’s often important to bind hashed values to a particular step in the protocol, or to a specific instance of the protocol, in order to prevent replay attacks or other problems related to reusing values.
SequenceHash makes this easy with built-in customization strings. Assuming you’re using a good hash function, applying SequenceHash or SequenceMAC to the same inputs with different customization strings will lead to unrelated outputs, allowing you to easily and predictably bind your hashes to particular uses. If you don’t need a customization string, don’t worry. They’re completely optional.
As an added bonus, the customization strings are incorporated only into the outer layer of the double-hash construction. If you need to hash the same value with multiple customization strings, the inner hash can be reused!
MAC mode
One final cool feature of SequenceHash is that it has a keyed mode, SequenceMAC. SequenceMAC is structurally similar to HMAC, and offers the same features as SequenceHash: unambiguous encoding, customization strings, and length-extension protection. It also incorporates metadata about the key and customization strings to prevent the key pseudocollision issues present in HMAC.
How does SequenceHash work?
Like TupleHash, SequenceHash uses length encoding to unambiguously encode its inputs. However, SequenceHash uses a simplified encoding. Instead of writing the number of bits to be hashed as a variable-length integer, SequenceHash encodes the number of bytes into a fixed-length, 128-bit integer. SequenceHash uses a length-suffix encoding for inputs. Like the length-prefix encoding system used by TupleHash, length-suffix encoding is unambiguous; however, suffix encoding allows implementers to develop streaming APIs when they need to support hashing data with length that isn’t known ahead of time.
We chose a 128-bit length encoding for simplicity of implementation on 32- and 64-bit systems (padding with zeroes is easy), and because a ${2}^{128}-1$ byte limit exceeds all practical considerations for the time being and the foreseeable future. Two of the most popular hash functions in use today, SHA256 and SHA512, limit their inputs to ${2}^{61}$ and ${2}^{125}$ bytes, respectively, meaning that a ${2}^{128}-1$-byte limit exceeds the specified limits of the most popular underlying hash functions, anyway. If you’re pushing the edges of SequenceHash, you’ve already blown past the limits of SHA256 and SHA512.
We use byte counts for simplicity. Nearly all hashing today is performed in software on strings of 8-, 16-, 32-, or 64-bit values. Systems using non-byte-length strings are very rare nowadays, and we believe it should be up to implementers of such systems to provide their own byte padding if they want to use SequenceHash.
Like HMAC, SequenceHash uses a double-hash construction to prevent length extension attacks. This structure also allows us to support a keyed variant, SequenceMAC, which accepts keys up to ${2}^{128}-1$ bytes in length.
One downside of the original HMAC construction is that it’s subject to what are known as “key pseudocollisions.” HMAC keys can be any length, but if they’re longer than a certain cutoff value (that depends on the hash), they get hashed before use. This means that every “long” key has a “short” representation that produces the exact same outputs. If you’re careful about specifying and enforcing key lengths in protocols, you can guard against this sort of problem, but if you’re not careful, somebody could present two versions of the “same” key in different contexts, allowing them to engage in shenanigans.
Another form of key pseudocollision is key extension. As far as HMAC is concerned, the 8-bit key 0xff is the same as the 16-bit key 0xff00 and the 128-bit key 0xff000000000000000000000000000000. Appending zeroes to a key doesn’t actually change it (unless it goes beyond the length cutoff, at least). This sort of pseudocollision is a bit more insidious, because it’s the sort of thing that can show up accidentally; it’s not hard to imagine unintentionally passing a 128-bit key instead of a 256-bit key, or incorrectly setting a length indicator somewhere.
The keyed variant of SequenceHash, SequenceMAC, incorporates key lengths into a header block that is part of the hash. As a result, HMAC-style long-key pseudocollisions are hard to find: if a key needs to be preprocessed by hashing, supplying the hash of the raw key is not the same as supplying the raw key. Trailing zeroes in a SequenceMAC key are semantically significant.
SequenceHash and SequenceMAC support customization strings for domain separation, similar to TupleHash’s customization strings. Customization strings can be up to ${2}^{128}-1$ bytes in length, and they’re only integrated into the outer hash function, allowing developers to derive multiple hashes from the same set of inputs without rehashing everything.
How do I use it?
Glad you asked! We already have three implementations available: Rust, Go, and Python. We also have a specification available as part of the C2SP, with test vectors available in case you want to write your own implementation.
The main feature that distinguishes the SequenceHash API from other APIs is that all updates to SequenceHash and SequenceMAC objects are atomic. That is, each time you write a value to a hashing object, it will be added to the hash as an independent, length-encoded object.
We have worked to make sure that the SequenceHash and SequenceMAC APIs are similar, but not identical, to the standard APIs for each language. The Go cryptographic library’s hash.Hash interface incorporates the io.Writer interface, which guarantees that writing two values in sequence is the same as writing their concatenation. The Python hash library makes similar guarantees for the PEP 247 update function.
Let’s see what happens when we hash our example values above using SequenceHash:
The three outputs are all unrelated. That’s because each of the inputs is length-encoded, meaning that feeding Test 0 and Test 1 into consecutive calls to SequenceHash is not the same as feeding Test 0Test 1 into a single call.
We can also try hashing identical inputs with different customization strings:
SequenceMAC works like SequenceHash, but with a 32-byte or longer key. As with SequenceHash, we can see that shifting the boundaries between our inputs leads to different results:
Changing the key, or using result_with_customizer with different customization values, will also provide different outputs.
Some notes on key size
One important point is that SequenceMAC has a minimum key size of 32 bytes (256 bits). Coupled with a good 256-bit hash function, this corresponds to about a 128-bit security level against forgery attacks. As with HMAC, key sizes should generally be at least as long as the output of the hash.
Additionally, while SequenceMAC supports keys up to ${2}^{128}-1$ bytes in length, it’s important to remember that “longer key” is not the same as “higher security.” The underlying hash function and the key-preprocessing step (which hashes keys longer than the underlying hash function’s block size) impose a hard cap on the total security SequenceMAC can provide. Using keys longer than the length of the hash output is generally not a good idea.
For hash functions with outputs smaller than 256 bits (such as SHA224 or RIPEMD160), the security level should be equal to about half the hash length (112 bits for SHA224 and 80 bits for RIPEMD160), which does not match the security of the minimum key size. While SequenceMAC can be used with such hash functions, the SequenceMAC specification only prohibits short keys and strongly discourages the use of hash functions with short outputs.
What about extensible output functions (XOFs)?
Excellent question! We don’t have an answer yet!
We haven’t specified SequenceXOF, but it’s definitely something we’re thinking about. Right now, XOFs aren’t as widely used as hashes, so the APIs are a little less stable. We want to proceed carefully to ensure we cover all the relevant use cases.
What if I want to write my own implementation?
We love to see high-quality implementations! There are many languages where someone might find SequenceHash and SequenceMAC useful, and there are certainly ways to customize the current APIs to better fit your needs!
First, check out the specification. The document is kinda long, but the structure is straightforward. If you’ve implemented HMAC before, SequenceHash and SequenceMAC will feel like fancy versions of that.
Second, if your target language is similar to Rust, Go, or Python, consider porting over our initial implementations. We’ve tried to keep these implementations as clean as we can, so they’re easy to audit and other cryptographers can learn from them.
Finally, whatever you do, don’t forget to check your implementation against the test vectors. The test vectors aren’t simple known-answer tests, either: they include intermediate values that can be used to help debug and validate your implementation.
Some minor caveats
SequenceHash provides for a specific set of needs: customization and domain separation, preventing length extension attacks where applicable, and—most importantly—ensuring that your inputs don’t get mixed together in a dangerous way. It’s a tool, not a panacea.
You still need to make sure you’re hashing the right inputs. Being able to decode a value doesn’t mean that two pieces of software will encode that value in the same way, and that can lead to compatibility issues among different servers, clients, and libraries. JSON and XML, for instance, don’t always guarantee field orderings. Even for strings, it’s important to make sure you’re using a consistent encoding method (“all the world is ASCII” isn’t true and never has been).
In the case of Fiat-Shamir transforms, you still have to be careful about including all your inputs. Schnorr proofs should always include the group descriptor (whether as individual values or named parameter sets), the generator element, etc. When the output is supposed to be interpreted as an integer modulo some other value, it’s also important to make sure that you select a hash with an output large enough to avoid modulo bias. Cryptography is subtle; there are always intricacies to consider.
Still, as long as you’re careful to keep your inputs consistent and include all your values, SequenceHash and SequenceMAC make it easy to ensure nobody can pretend your inputs mean something other than what they’re supposed to mean.
The specification is live at C2SP, and our Rust, Go, and Python implementations are ready to use today, with test vectors available if you want to write your own. Try it out and let us know what you think!
Threshold signature schemes, a form of multi-party computation (MPC) that lets a set of parties sign together without any one of them holding the key, are increasingly deployed inside trusted execution environments (TEEs). The combination is intended to amplify security for sensitive computations: MPC distributes trust across multiple independent parties, while TEEs root trust in the hardware manufacturer and its attestation infrastructure. But subtle issues can arise when running an MPC protocol inside a TEE without accounting for the untrusted host: for example, a malicious host could roll back the filesystem state after a threshold signer deletes a used pre-signature, causing the signer to reuse their nonce share and disclose their private key share.
So is this combination worth it? Provided you treat the TEE as a defense-in-depth layer rather than a substitute for a sound protocol, the answer is yes. This blog post discusses what TEE attestation can and can’t fix in MPC deployments, explores the pitfalls we see most often in audits, and covers best practices, such as incorporating strong attestation processes and binding them to the MPC parties’ identities.
MPC: Security that depends on participant behavior
Before diving into how TEEs and MPC interact, we need to understand what MPC means and what security guarantees it offers. MPC is a cryptographic technique that allows multiple parties to jointly compute a function over their private inputs without revealing those inputs to each other.
The security of MPC protocols depends critically on assumptions about participant behavior. The cryptographic literature uses two primary security models:
Semi-honest (honest-but-curious) security: In this model, all participants follow the protocol exactly as specified, but they may try to learn additional information from the messages they receive during the protocol execution. Participants can try to learn more than they should, but they don’t deviate from the protocol specification.
Malicious security: This stronger model assumes participants may deviate arbitrarily from the protocol. A malicious participant might send incorrectly computed values, use wrong inputs, abort the protocol at strategic moments, and behave in ways designed to compromise security or learn private information.
This distinction is important in the context of TEEs. If a TEE attestation can cryptographically guarantee that all parties are running the correct protocol implementation, it effectively elevates semi-honest protocols to provide malicious security guarantees (at least against certain classes of attacks, as we’ll discuss later). But before delving into the details, let’s discuss how TEEs work.
TEEs: Three core security guarantees
TEEs are secure areas within a processor that provide hardware-based protection for code and data, even from privileged software like operating systems or hypervisors. TEEs offer three core security guarantees:
Confidentiality: Data and code are encrypted in memory and accessible only from within the TEE. This ensures that even privileged system software cannot inspect the contents of the secure computation.
Integrity: The data and code are protected from tampering. Any attempt to modify the TEE’s memory or execution state from outside should be detected.
Attestation: Remote parties can cryptographically verify what code is running in the TEE. This allows external verifiers to gain assurance about the computation being performed and the legitimacy of the TEE without trusting the host system.
This last property is particularly crucial for building distributed systems with TEEs.
How TEE attestation works
The attestation mechanism is at the heart of TEE security. When a TEE is manufactured, it’s provisioned with a private key and a corresponding certificate that chains back to a root certificate held by a trust anchor (typically the manufacturer).
When an attestation is requested, the TEE takes measurements (cryptographic hashes of the TEE software, configuration, and hardware state). These measurements are bundled into a “quote” (a manifest of these cryptographic hashes), which the TEE then signs with its private key.
To verify these attestations, a number of checks need to be performed. However, the checks necessary in the verification process aren’t uniformly defined and are somewhat vendor-specific. For instance, Intel’s TDX documentation states:
TD Quote Verification is the process by which a TD Quote is verified in a remote attestation flow. This verification can be done by any party and the checks performed are defined by this party.
This places significant responsibility on developers, who might not fully understand what checks are required to ensure the security of the TEE deployment.
At a minimum, a proper verification process requires:
Verifying the quote signature
Verifying the certificate chain back to the trusted root
Verifying the actual measurements against known-good values (often stored in binary transparency logs)
This means deploying TEE-based systems involves not just cryptographic verification but also reproducible builds and binary transparency infrastructure. The measurements in the attestation quote are simply hashes; they don’t inherently indicate whether the code is correct or malicious. To verify that the TEE is running the intended software, what is required is a trusted source of reference measurements. Reproducible builds ensure that anyone can compile the same source code and arrive at identical binaries (and thus identical measurements). Binary transparency logs provide a tamper-evident record of what measurements correspond to what software versions, allowing verifiers to check that the TEE is running legitimate, audited code rather than a compromised variant. This piece is often overlooked in TEE deployments.
The trust model clash
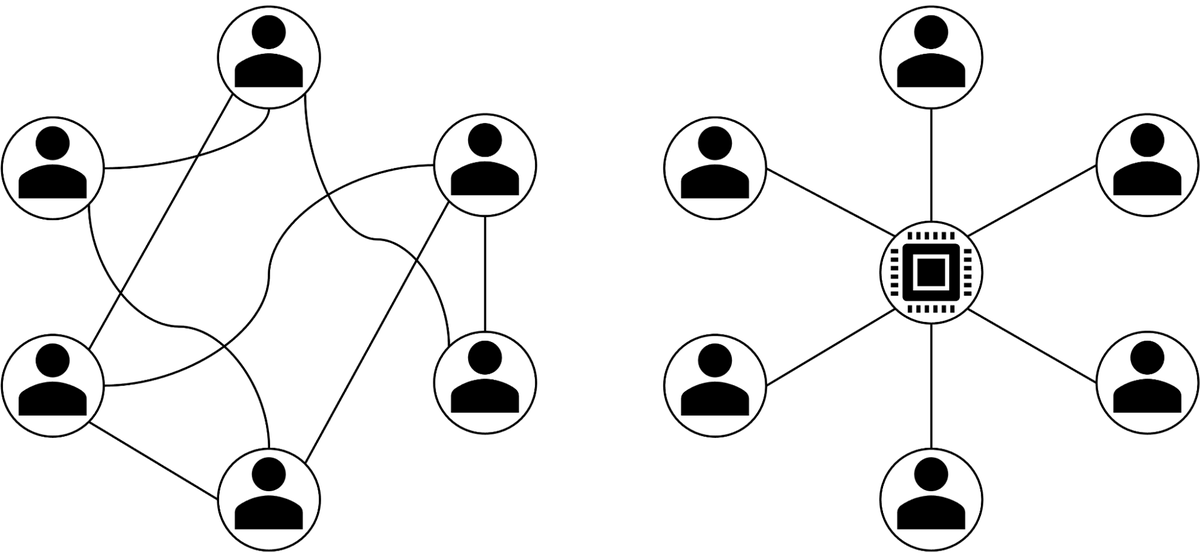
Here’s where things get interesting. Multi-party computation is fundamentally about distributing trust among multiple participants. No single party should be able to compromise the computation. TEEs, in contrast, centralize trust in the hardware manufacturer that controls the root certificate.
Another important threat model shift to consider is the fundamental inversion of traditional security assumptions in TEEs. Historically, we trusted the host operating system and built our security models on that foundation. TEEs flip this on its head: they’re virtualized environments where the guest (the code running inside the TEE) is trusted, but the host system is explicitly considered untrusted and potentially malicious.
This shift creates new attack surfaces that didn’t exist in traditional computing models. While the TEE protects the guest environment from the host, the host still controls critical operations like I/O, memory management, and CPU scheduling. The host can deny service, manipulate timing, or attempt rollback attacks, leading to subtle breaks of MPC protocols.
Figure 1: Decentralized vs. centralized trust model shift
What TEEs can (and can’t) fix in MPC deployments
Combining these technologies can be beneficial, but one must be careful about the security claims that can be made. The security gains are real only if the TEE implementation is sound and the attestation process verifies the right properties. When TEEs attest to incomplete measurements or fail to verify critical components, the attestation provides false assurance. The actual security posture may even be weakened by the added complexity.
In an attempt to narrow down what TEEs can fix in MPC implementations, we’ve identified the common categories of MPC issues we frequently encounter in security audits:
Arguably, if TEEs were perfectly secure, they could effectively mitigate the first four categories. When attestation and measurement processes are correctly implemented, each party gains cryptographic assurance about what code the other parties are running. This is powerful: if a party can verify that all other participants are running the exact protocol implementation expected (with no modifications or protocol deviations), then they know other participants will follow the protocol correctly and won’t misbehave by sending malformed messages. Essentially, correct attestation eliminates entire classes of implementation vulnerabilities by ensuring protocol compliance on both the sender and receiver sides. However, perfect security doesn’t exist in practice. Real-world TEE implementations have vulnerabilities, attestation processes can be incomplete or incorrectly verified, and the adversarial host environment introduces attack surfaces that are not traditional to MPC deployments.
A cautionary tale: Rollback attacks with threshold signatures in TEEs
Consider threshold signature schemes, which often use pre-signature optimizations. In Schnorr or ECDSA threshold signatures, participants can precompute nonce commitments independently of the message, speeding up the online signing phase. These precomputed nonce commitments are called pre-signatures, and the reuse of a pre-signature value by a participant leads to the leak of their private share (akin to how nonce reuse in traditional Schnorr and ECDSA signatures leads to private key recovery).
It might be tempting to run such an MPC protocol inside a TEE enclave to mitigate these types of attacks. But subtle issues can arise. In some implementations, signers store pre-signatures to disk and delete them after use (to limit the possibility of reuse). If that application were deployed to a TEE in a trust model where the host is potentially malicious, the host could roll back the filesystem state after the signer deletes a pre-signature file. When the TEE later fetches the pre-signature contained in that file, the signer essentially reuses their nonce share, which leads to a disclosure of the private key share. This is also discussed in the blog post A trail of flipping bits.
Common TEE pitfalls
Beyond the rollback issue, several other pitfalls frequently appear:
Incomplete attestation measurements: The security of TEE attestation hinges on measuring the right things. An attestation quote contains hashes of code and data, but project developers determine what gets measured and what gets excluded. If critical components aren’t included in the measurements, an attacker can modify those components without detection. This is particularly risky because the attestation appears cryptographically valid, but it’s attesting to an incomplete picture of the execution environment. For example, installing tools in an enclave from remote sources at runtime (e.g., using curl) pulls in code that was never measured; an attacker gaining access to that source can substitute their own and gain code execution inside the enclave.
A real-world example demonstrates this risk: a vulnerability in Meta’s WhatsApp Private Inference revealed that the attestation process didn’t include certain configuration files, enabling an attacker to inject malicious shared libraries with the LD_PRELOAD environment variable, potentially compromising the TEE while maintaining a valid attestation quote.
Missing verifications: The attestation process requires multiple verification steps, each critical to the security guarantee. Verifiers must check the quote signature, validate the certificate chain back to the manufacturer’s root certificate, confirm that the measurements match expected values, etc. Skipping any of these steps breaks the security model. Because verification procedures vary across TEE vendors and aren’t always well-documented, implementations sometimes omit crucial checks.
Lack of hardening: A TEE protects whatever runs inside it, including components that may not be needed. Redundant kernel drivers, overly permissive kernel config flags, stray ACPI table entries, unnecessary systemd services and timers, and weak entropy sources all increase the attack surface inside the trust boundary. Trim the image down to what the project requires, harden what remains, and measure it. For platform-specific guidance, see our notes on the AWS Nitro Enclaves attack surface.
Data availability and backups: Enclaves have limited persistent storage, so backups and recovery data typically live outside the trust boundary. Authenticated encryption provides confidentiality and integrity but not freshness, so a malicious host can serve a stale backup to force a rollback, as discussed earlier in our threshold signature example. More concretely, one recurring failure is a guest trusting attacker-controlled metadata that lives on disk: the disclosure of several vulnerabilities in LUKS2 disk encryption for confidential VMs shows that a malleable, unvalidated LUKS2 header lets an attacker with disk write access swap in a null cipher, leaving the guest reading and writing secrets on an effectively unencrypted volume.
Side-channel and physical attacks: Because the untrusted host controls the TEE’s execution environment, it can perform various side-channel attacks to extract information about the guest’s computation. These can leak sensitive information and break a TEE’s confidentiality guarantees. Similarly, researchers regularly publish physical attacks on TEE hardware. For example, the recent “TEE fail” attack allows an attacker to break the security guarantees of Intel TDX and AMD SEV-SNP by using a memory interposition device that lets them physically inspect all memory traffic inside a DDR5 server. The more recent DDRop attack goes even further: an interposer costing under $200 silently drops DDR5 writes, so the processor keeps reading stale data that still decrypts correctly, breaking the integrity of Intel TDX, Scalable SGX, and AMD SEV-SNP. Memory encryption without freshness fails the same way disk state does in the rollback example above.
Centralization risks: When MPC aims to distribute trust but TEEs centralize it in the manufacturer and its attestation infrastructure, the security goals of the protocol may be undermined. If all parties in an MPC protocol run their TEE nodes on the same TEE vendor’s hardware or if they use the same cloud provider, trust becomes centralized in that provider (for example, by way of the attestation chaining back to that vendor-operated root of trust).
Insecure defaults: Be aware of some of the limitations that vendor-provided verification tools have. For example, Intel tools allow known-vulnerable firmware versions to pass the remote attestation process for one year after public disclosure. Users might want to implement their own security version number validation on top of the defaults to enforce stricter deadlines.
Best practices for combining TEEs and MPC
If you’re building systems that combine these technologies, consider these recommendations:
Implement strong attestation processes: Bind attestations to the identities of MPC parties and verify them comprehensively. This means not just checking that an attestation is valid but also confirming that the specific party you expect to be running the code is actually the one presenting the attestation.
Terminate peer-to-peer communications inside TEEs: This provides end-to-end protection for party communications. By establishing TLS or other encrypted channels directly between TEEs (with endpoints inside the secure enclaves), you prevent the untrusted host from observing or tampering with protocol messages.
Perform comprehensive verification of the attestation and measurements: Refer to your specific TEE vendor’s documentation for the necessary checks to be performed, and ensure every verification step is implemented correctly, tested, and reviewed.
Write constant-time code: This helps prevent timing side-channel attacks. Even within a TEE, timing variations in your cryptographic operations can leak information to a host performing careful measurements. Use constant-time implementations for all security-critical operations processing secrets.
Consult vendor-specific guidance: Each TEE platform has unique characteristics, limitations, and recommended practices. Vendor documentation often includes details about platform-specific threats. Stay current with security advisories and updates, as TEE security is an active research area with new vulnerabilities regularly discovered. Follow best practices documentation, like our guidance for AWS Nitro Enclaves.
Use multiple TEE vendors: For defense in depth, consider running MPC protocols on TEEs from different manufacturers (and/or cloud providers) to avoid centralizing trust in a single vendor. While admittedly challenging in practice since it requires additional operational complexity, this diversity can be essential for high-security applications where trust distribution is critical.
Layered trust beats either layer alone
Combining MPC and TEEs is not automatic security, but when done correctly, it represents a defense-in-depth strategy that’s stronger than either technology alone. TEEs can effectively mitigate several categories of MPC vulnerabilities by cryptographically guaranteeing correct protocol execution. Meanwhile, MPC’s distributed trust model reduces the impact of TEE manufacturer centralization and may provide security even if individual TEE instances are compromised.
However, this benefit only materializes when both layers are correctly implemented. New vulnerabilities can emerge from their interaction, as we saw with the rollback attack example. Successful deployment requires following established best practices, implementing thorough attestation verification, and carefully reviewing the implementation and deployment procedure.
The intersection of these technologies represents the cutting edge of secure computation, but only if we approach it with a clear understanding of the tradeoffs involved. If you’re deploying MPC on TEEs, our cryptography team reviews these exact systems, so get in touch!
Born out of academia and raised in corporate IT departments, the Security Assertion Markup Language (SAML) authentication protocol continues to be a staple in these organizations. However, it’s time for it to retire. With the rise of software-as-a-service (SaaS) companies in the late aughts, IT departments needed a way for users to authenticate to many new web services. SAML and the burgeoning single sign-on (SSO) industry fulfilled this need. However, SAML is being crushed under the weight of its own complexity. It’s time to deprecate it and move on to modern alternatives like OpenID Connect (OIDC). In this post, I will explore the design-by-committee origin of SAML, its progression through the ranks in academic and corporate environments, its slow disintegration at the hands of the security research community, and its (hopeful) deprecation in favor of newer protocols.
SAML 101
What’s insidious about SAML is that it really is mostly straightforward to understand, but it’s built on a foundation of sand, bone dust, and ash; it works … if you assume XML signature validation is reliable. But XML signature validation is deeply cursed, and is so complicated that most fielded SAML implementations are wrapping libxmlsec, a gnarly C codebase nobody reads.
— Thomas Ptacek, 2023
SAML and the birth of the SSO industry
Wikipedia tells me that “SAML is an XML-based markup language for security assertions.” It was created in 2002 by the Organization for the Advancement of Structured Information Standards (OASIS) Security Services Technical Committee (SSTC). Okay, we’re not off to a great start by modern standards. XML, despite having some redeeming qualities, is quite complex compared to newer alternatives like JSON, but we’ll get more into that later. Further, a committee of subcommittees having meetings is a recipe for “kitchen-sink” protocol design (e.g., waterfall methodology, big design up front, etc.). And sure enough, we’ve now jammed four (!) XML-based security protocols into one:
… the following intellectual property was contributed to the SSTC:
Security Services Markup Language (S2ML) from Netegrity
AuthXML from Securant
XML Trust Assertion Service Specification (X-TASS) from VeriSign
Information Technology Markup Language (ITML) from Jamcracker
However, the desire for such a protocol was undeniable. As the internet shifted from Web 1.0 in the 90s to Web 2.0 in the early aughts, users and organizations needed an easy way to authenticate to many new web services. Academia was the biggest driver of this movement, although not the only one: Central Authentication Service (CAS) in 2002 at Yale, Shibboleth IdP in 2003 by Internet2, a consortium of research universities (including my alma mater), ADFS in 2003 by Microsoft, and simpleSAMLphp around 2007 by Uninett, a state-owned Norwegian company with close ties to academia. All these authentication projects eventually supported SAML in one way or another. Like ARPANET before it, universities were at the forefront of internet development and were the earliest consumers of web services. Once this base layer of protocol availability and nascent academic proving ground was established, the commercial industry took it and ran toward a multibillion dollar industry.
The SSO, identity, and authentication provider industry was also starting up in the early aughts, but really came to fruition a few years later: Ping Identity (2002), OneLogin (2009), Okta (2009), and Duo Security (2010). These companies were essentially built on the SAML protocol with the exception of Duo, who would introduce their first SSO product in 2015, which is where I come into the story. I worked on Duo’s first on-premises Access Gateway product (DAG), which was built on simpleSAMLphp and, obviously, the SAML protocol. It’s where I became intimately familiar with the SAML protocol and spent many years of my life digesting its lengthy specifications. I was there when Kelby Ludwig found the XML comment bypass, but we will get into various attacks and SAML deficiencies later. Suffice it to say, the SSO and authentication provider industry was booming, and much of it was built on the SAML protocol.
A crack in the armor
XML signature wrapping (XSW) attacks are the proverbial arrow to SAML’s heel. While there was earlier security research into both signature wrapping (2005, 2008, and 2009) and SAML (2008), I consider the godfather of it all to be “On Breaking SAML: Be Whoever You Want to Be” (2012). It tested theory against practice and resulted in an automated way to check for XSW attacks. This was our north star when implementing the DAG. It was the reason we chose simpleSAMLphp as our building block. PHP, especially at the time, was not exactly known for its security track record, but simpleSAMLphp’s spoke for itself. simpleSAMLphp was resilient to XSW at a time when nobody really knew what that was:
simpleSAMLphp’s security track record (credit: On Breaking SAML)
Despite being front and center in this 2012 paper, XSW is still present today. If we know the bug class, then why can’t we fix it? But before we get into SAML’s flaws we first have to consider the shaky ground it was built upon: XML.
XML is no slouch when it comes to a (lack of) security track record. These bug classes would have been more familiar to a developer in the 90s, but nonetheless are still present in XML today: XXE, entity expansion (“billion laughs”), DTD retrieval (SSRF), XPath/XQuery/XInclude/XSLT/CDATA injection, and more. A SAML library needs to handle all these bug classes before even getting to the actual SAML functionality.
In addition to security bug classes, there’s also the sheer complexity of XML when compared against something like JSON. In XML you have tags, elements, attributes, comments, namespaces, markup versus content, schemas, CDATA, DOCTYPEs, and more. In JSON, you essentially have keys, values, objects, and lists. Complexity is generally at odds with security, and this is one reason I consider SAML to be a fractal of bad design.
A fractal of bad design
SAML provides ample opportunity to learn about protocol design. In this section, I will cover five flaws that I consider to be fatal to the long-term viability of SAML as an authentication protocol. These flaws can also be used when designing new authentication protocols. That is, you can either sidestep the flaw, or take its inverse and attempt to bake that into the protocol.
Built on XML
As mentioned above, SAML is built on XML, and XML is complex, but it’s not the committee’s fault. XML is what they had at the time, and it’s what people used. JSON was “discovered” in 2001, but this was right around the time the SAML committee was meeting, and they’d be unlikely to design an authentication protocol around an experimental new format. Especially when it caters to JavaScript and you write a lot of Java.
One could design a quantitative complexity measurement for XML versus JSON or SAML versus JWT/OIDC (e.g., spec/RFC word count, spec/RFC normative word count, etc.), but that would require a blog post or paper all to itself. In the interest of staying on topic, I will refrain from doing that here, and suffice to say that XML is significantly more complex than something like JSON.
Canonicalization
Canonicalization (C14N) is what you do when you want to take the wild mess that is XML, compute a hash of it, and get consistent results. In other words, if the SP and IdP cannot agree on a consistent representation of the XML data, then the bytes won’t line up, the signatures won’t match, and your authentication fails. However, this is easier said than done.
Canonicalization bugs enabled Kelby’s XML comment bypass in 2018:
XML canonicalization (credit: Identity Theft)
Canonicalization is often a precursor to parser differential and/or “round-trip” bugs, which are what most modern SAML attacks use:
Enveloped signature concerns are a not-too-distant cousin of canonicalization. In short, if you’re trying to insert the signature into the data payload that you’re signing, you’re going to have a bad time. Let’s compare and contrast JWT and SAML in this way:
JWT versus SAML signatures (credit: jwt.io and samltool.io)
In the JWT example above, the blue signature is detached from the JSON payload and delimited in the JWT with a period (“.”). In the SAML example, the Signature element is inserted (“enveloped”) in the Assertion element. The problem here is that it is very difficult to get a byte-for-byte, canonically equivalent representation of the data when you’re also modifying it! Even more so when you have a complex format like XML and complex canonicalization rules.
“Kitchen-sink” design
This design deficiency essentially transposes to you aren’t gonna need it (YAGNI). It’s not an entirely fair characterization because the portions of the SAML specification that are used in the real-world have changed over the past 20 years (sorry, SOAP and artifact binding). However, the fact of the matter is that 99% of modern SAML implementations use a very similar data shape and subset of the specification. Any given SAML authentication you would encounter in the wild today probably avoids 90% of the specification. This adds significant complexity for largely unused features.
If I was adding SAML support to something new, I’d consider beyond all the standard SAML checks also rejecting any message that doesn’t have the same shape as what Okta, Onelogin, Google, or Shib generates.
— Thomas Ptacek, 2021
Ossification
SAML was designed in a different era for a different time and has not received necessary updates. These concerns will generally be of practical implication rather than theoretical. What I mean by ossification can roughly be enumerated as the following:
OIDC assumes HTTP, whereas SAML is transport independent. Sure, SAML HTTP bindings exist and are most commonly used, but they are not required. This affords SAML a certain degree of flexibility, but also means that flexibility must be well defined, must be implemented somewhere, and can contain bugs. SAML came about at a time when HTTP + TLS was not yet the dominant backbone of web service communication, and it has never reconciled with this modern landscape. HTTPS allows OIDC to punt encrypted, trusted communication to the transport layer.
OIDC generally assumes a connected network topology, whereas SAML does not. The most common OIDC flow (authorization code) assumes the OpenID Provider (OP) and Relying Party (RP) can communicate directly (OIDC OP/RP == SAML IdP/SP). Sure, OIDC implicit flow with form post exists, but it is very uncommon to see today. Further, SAML has artifact binding for direct communication, but it is also very uncommon. The point is that if the OP and RP can communicate directly then that relieves pressure off of the authentication response payload to contain all the information necessary to make an authentication and authorization decision. This reduces payload size and complexity. The OIDC OP and RP can instead exchange information in a backchannel.
OIDC grew organically over the years, whereas SAML was largely designed up front. OIDC encompasses dozens of specifications and RFCs that grew organically over many years. These documents were generally created to solve a specific need rather than trying to anticipate all future needs and building that up front. This is akin to agile methodology versus waterfall, as described in the first section. Consider the following non-exhaustive timeline:
OpenID Connect 1.0 specification published (2014)
JOSE stack finalized for JW{S,E,K,A,T} via RFC 7515-7519 (2015)
PKCE published via RFC 7636 (2015)
PKCE for mobile/native apps published via RFC 8252 (2017)
Device authorization grant for IoT devices published via RFC 8628 (2019)
Demonstrating proof of possession (DPoP) for MFA workflows published via RFC 9449 (2023)
PKCE for SPAs published via RFC 10017 (2026)
I find the historical circumstances interesting too. For example, SAML came of age in an era of VPNs and network segmentation, hence point (2) above. If the IdP or SP was behind a corporate firewall, and it couldn’t speak directly to the other end, then the whole rollout came to a halt and that vendor lost the sales deal. SAML needed to seamlessly account for this situation. Google’s BeyondCorp model and zero-trust architecture flipped this notion on its head in 2014. Additionally, SAML failed to anticipate the mobile, SPA, and IoT revolutions, and had no answers when these technologies arrived on the scene in the late aughts. Even though SAML is still widely adopted in corporate environments, these macroscopic events helped start the long, slow decline of the protocol. Agility and loose coupling enable rapid adaptation in ever-changing IT environments.
All roads lead to OIDC
No protocol is perfect, but in terms of a solution all roads lead to OIDC. As far as I can tell, the only deployment scenario where SAML had an advantage was networks where the SP and IdP cannot communicate directly. OIDC’s implicit flow with form post provides all the same ingredients. This is actually one of the cleanest migration plans I’ve seen available in the industry.
So what can I do if I’m a service provider (i.e., SP) and I’d like to integrate into the SSO ecosystem without SAML? Just support OIDC. Abandon SAML. Apparently Fly.io and Tailscale are already doing it:
We’ve managed to hold the line on OIDC so far. So has Tailscale. If Tailscale can hold the line, given who they’re selling to, I think most orgs can. Really, try to avoid doing SAML. Remember, as a vendor, you’re often competing with companies that don’t do real SSO integration at all.
— Thomas Ptacek, 2024
So what can I do if I’m an identity or authentication provider (i.e., IdP) and I’d like to move off of SAML? Well, depending on your customer count, this may be a long road indeed. But you know how you eat an elephant? One bite at a time. This is a well-worn path in the industry: develop a deprecation plan, communicate it to customers, stop onboarding new customers to SAML integrations, provide existing SAML customers with equivalent OIDC configurations, set a sunset date, and get to work.
SAML had a good 25 year run. It birthed the SSO industry, helped secure untold numbers of authentications, improved the UX of authenticating to dozens of web services, and created billions of dollars of economic impact. We should be thankful to the creators of the SAML protocol. It has provided us with a great case study in protocol design and evolution over a very dynamic period in the tech industry.
Security firms have published numerous blog posts describing how they pointed their agent harness at a codebase and found dozens of bugs (we’re one of them). However, these posts tend to focus on agentic code review, which is just one aspect of how we use AI in our security reviews. We want to give a different perspective: before code review even starts, agents now allow us to build custom tooling and formal models that improve the quality and depth of our reviews.
We recently reviewed the Miden VM, a new zero-knowledge VM with its own custom assembly language and almost no developer tooling. To prepare, we spent six months having our agents build an LSP server, a decompiler, a static analysis engine, and a Lean model of the VM executor from scratch. These tools found real security issues, like an unvalidated prover-supplied input that would let a malicious prover forge Falcon signatures and steal funds from Miden account holders. Additionally, the Lean work produced 95 machine-checked correctness proofs, covering a large component of the Miden core library.
Auditing the Miden zkVM
In late 2025, the Miden team came to us to have parts of their zero-knowledge VM reviewed before launch. Part of the review was scoped to cover the Miden core library, which contains a small set of cryptographic primitives written in a custom assembly language called Miden assembly (MASM). This made us genuinely excited, as it was right up our alley: a high-assurance project writing complex cryptographic code in a low-level custom assembly language that we had never seen before. At the same time, it also presented some unique challenges.
Figure 1: The left image shows a MASM procedure computing the XOR of two 128-bit values (represented as 32-bit limbs). The right image shows the same procedure implemented using 32-bit x86 assembly code.
To start, the Miden VM implements a stack-machine architecture. This means that each instruction operates on values read from the stack, and the result of the instruction is then written back to the top of the stack. While conceptually simple, this makes code written in MASM challenging to review, since instruction inputs and outputs are read from the stack and are always implicit. Additionally, since the Miden VM is a completely new architecture, very little existed in terms of developer tooling like IDE support, Language Server Protocol (LSP) servers, and linters.
We knew that we had six months to prepare for the review, since the implementation was not yet feature complete, so we asked ourselves: “What could we spend our time and tokens on to make sure that the review would root out as many bugs as possible in the codebase?”
Building all the tools!
Since MASM lacked developer tooling, we started out by asking ourselves what kind of tools we would like to have available when the project started. We typically use VS Code to review code, and syntax highlighting and code navigation are essential for readability and being able to follow data flow throughout a codebase. We needed an LSP server and a corresponding VS Code extension for this, and within a few days we had Claude build a working prototype that provided most of the functionality we wanted: features like syntax highlighting, goto definition, finding code references, and displaying procedure docstrings on hover. With these fundamental features in place, we also decided to add more language-specific features like displaying inline instruction documentation, and stack effects for individual instructions.
Figure 2: Annotating the code with inline stack effects and instruction documentation helps prevent the context switch required to look up instruction semantics elsewhere.
Having built the LSP server, we started thinking about other ways to provide high-level semantic information to support manual and agent-driven review. We thought it would be interesting to see if we could provide faithful decompilation for MASM procedures inside the VS Code UI, to help the reviewer quickly understand the high-level control flow and data flow of the procedures they were looking at. For MASM, this is a harder problem than it first appears. Stack machine lifting and decompilation is a well-studied problem, but decompiling hand-written MASM is still difficult for a number of reasons.
Most procedures in the core library do not have declared signatures, which means that the number of inputs and outputs must be inferred from context.
MASM procedures do not conform to a well-defined calling convention, and the net stack effect of such calls is generally impossible to determine statically. This means that all analysis failures propagate up the call chain.
While-loops do not need to be stack neutral, which means that the while-loop condition may occupy a different stack slot in each iteration. This also makes it impossible to map instruction inputs to stack slots for subsequent instructions.
Different branches in conditional statements may have different stack effects, which similarly makes stack tracking and signature inference challenging.
This meant that we could not expect to be able to decompile all MASM procedures if we also wanted the decompiled output to be correct. We therefore focused on decompiling a well-defined subset of MASM correctly. During the development of the decompiler, we alternated between using Claude for planning and development and Codex for code review. Whenever we had implemented a new feature, we had agents decompile a randomized set of procedures from the core library and compare the result to the original MASM to look for regressions. Any issues found were added as regression tests to be fixed by the model.
Figure 3: The eqz procedure, which tests if a 256-bit integer (represented as eight 32-bit limbs) is equal to zero, together with the corresponding decompiled pseudocode
The decompiler represented the single largest effort of the tooling development for this project, with over 100 AI-generated commits over multiple months. The main benefit of this work turned out to be the decompiler’s internal analysis frameworks and intermediate representation, which we could reuse for static analysis, rather than the full decompilation pipeline.
With the decompiler in place, we had access to an intermediate representation of each procedure, with instruction inputs and outputs populated as expressions. This allowed us to bring all the standard static analysis machinery (like data flow analysis) to bear on the problem of finding bugs in the MASM code. We used this to build a number of analysis passes over the intermediate representation, answering questions like the following:
Are prover-supplied advice values1 like remainders and modular inverses properly validated?
Are type constraints (e.g. an input being a 32-bit integer or a boolean) enforced?
Are local variables initialized across all execution paths?
One way to explore these issues is abstract interpretation. The idea behind this technique is simple. Instead of running the program with real numbers, the analysis tracks the types of values that could be on the stack at each step, like “a 32-bit integer” or “unknown.” It walks through the code again and again until no new information is found. Since it always keeps track of every possible value (with a little extra room), it can never miss a real case. So if a check passes in the analysis, it is guaranteed to hold in every actual run of the program.
We used Claude and Codex to build a general abstract interpretation engine, and then implemented a number of concrete analysis passes on top of it, having the agents switch between development and code review as described above. We also decided to have the agents design and build command-line interfaces for both the decompiler and a new MASM linter to make the new tools available to agent-driven code-review workflows as well.
Finding all the bugs!
During the actual review, these analyses identified over 400 unique locations2 where type validation could be improved (all of them reachable from the public API of the library) as well as one high-severity finding.
Figure 4: The remainder is read from the advice stack, but is not validated to ensure that it is a valid 64-bit integer.
The high-severity issue was due to an underconstrained advice value in the mod_12289 procedure, which reduces a 64-bit value modulo 12289, with a quotient and remainder provided as advice values by the prover. The quotient is checked to ensure that it is a valid 64-bit value (represented as two 32-bit limbs), but the remainder is never validated before it is passed to the 32-bit instruction u32overflowing_sub. By carefully varying the quotient and remainder to ensure they still satisfy the constraints imposed by the subtraction, we found that it was possible to have mod_12289 return a value that is not the correct remainder. A malicious prover could exploit this to forge Falcon signatures and drain any Miden account controlled by a Falcon key pair.
But what if there are no bugs?
All this work meant that we had a comprehensive set of tools to support both manual and agent-driven code review coming into the audit. However, we’d had a long time to think about other ways to support the manual review process, and we had more ideas that we wanted to test. For example, if the procedures in the core library were implemented correctly and did not contain bugs, would it be possible to prove this using a proof assistant like Lean?
It turns out that the Miden VM is very amenable to formal modeling, since the instruction set is small and most instructions are side-effect free. To formally model MASM, we started by implementing a minimal Miden VM executor in Lean, and had Claude build an automatic translator from MASM procedures to Lean. During the review, we had multiple agents working in parallel to prove correctness of as many procedures as possible across the library. Since the Lean kernel could validate that the generated proofs were correct, we only needed to manually audit the theorem statements to ensure that each theorem proved the right correctness property for the corresponding procedure. To ensure that the theorems were easy to review, we introduced Lean types for field elements and the integer types implemented in the core library. This meant that at a high level, most correctness properties could be expressed in the following form:
If the stack is given by [x1, x2, x3, ..., xn, ...] and we execute the procedure P, then P terminates and the stack is given by [P(x1, x2, x3, ..., xn), ...].
Figure 5: High-level statement of correctness for the procedure P with n arguments
Our agent-driven formal modeling efforts resulted in 95 correctness proofs that covered all of the binary arithmetic components of the core library. This work also identified two subtle bugs that the existing unit test suite did not catch. The first was an edge case in the 64-bit right-rotation rotr, which behaved incorrectly on large inputs greater than the Goldilocks prime if the rotational shift was a multiple of 32. The second was an issue in the 256-bit multiplication wrapping_mul, which dropped caller-owned values from the stack before returning.
Figure 6: Manual review identified that the correctness proof for the 64-bit rotr procedure required an additional assumption (that shift mod 32 ≠ 0) to allow the proof to go through.
Why we couldn’t have done this two years ago
The tools we developed leading up to this engagement, and the Lean libraries and proofs generated during the review, are all side projects that we wouldn’t have been able to dedicate time or resources to just one or two years ago. Projects like these are often highly exploratory in nature, and the end results and potential payoff may be difficult to predict. In practice, this means that it is hard to sell clients on them in advance. However, over the last year, agents became good enough to carry non-essential projects like these with only light supervision, which completely changed the economics of which projects are worth pursuing. Today, a failed side project only costs tokens.
With Miden, the benefits of all this preparatory work were clear. The LSP server and static analysis engine improved our manual review coverage, strengthened agent-driven reviews, and identified real security issues in the codebase that could have led to millions of dollars in lost funds. The AI-generated Lean correctness proofs also improved assurance across a large and fundamental component of the library, allowing the team to continue building on it with confidence. The team has adopted the static analysis engine developed for the review, which means that our side project will now also help secure future updates to the Miden core library.
On a personal note, this has been one of the more interesting projects I have worked on during my years at Trail of Bits. If you find this type of work interesting, or if you are building something similar, get in touch. We want to hear about it!
These are precomputed inputs that are supplied via a separate advice stack by the prover, and need to be validated carefully. ↩︎
Most of these findings were due to the fact that almost all procedures in the core library were part of the public API, which meant that third-party developers could call them without proper validation. ↩︎
1Password’s FLAWED report, published on August 6, 2026, gives defenders a misleading picture of AI patching. Its headline says models produced clean fixes only 26% of the time. That figure includes experiments that deliberately instructed agents to apply the wrong fix, along with experiments in which agents could not compile or test their patches.
The report risks making defenders less effective by discouraging them from using technology that could help them fix more vulnerabilities. Teams that take its headline at face value may leave repairable vulnerabilities unaddressed.
We want our work to help defenders fix more vulnerabilities. This post shares real-world data on human and agent patch quality from our consulting projects and Patch the Planet. We’re also releasing two agent skills: post-patch-validation to help agents test fixes, and review-walkthrough to help engineers review them.
How the experiment produces a misleading headline
Our review of 1Password’s code and data found four choices that make its 26% clean-fix rate a misleading guide to ordinary patching work.1
The sample was selected for difficult fixes. The authors chose six vulnerabilities because their fixes were complex. Clean-fix rates ranged from 3% to 60% across those bugs, so the average depends heavily on which vulnerabilities made the list.2
Two prompts tell agents to apply the wrong fix. Those prompts account for 22% of the data. Combining them with ordinary repair attempts makes the reported rate depend partly on how often the researchers chose to give agents bad advice.
More than a third of the trials prohibit testing. One evaluation mode prevents agents from building or running code and accounts for 36% of the data. The headline combines those trials with experiments in which agents could test their patches and act on the results.
The models ran at different reasoning settings. GPT-5.5 ran at medium effort and Opus 4.8 at high. These were the tools’ defaults. Neither model was tested at its highest available setting, and the authors did not measure how increasing effort affected the results.
1Password’s headline also obscures a useful result in its own data. We reanalyzed the patches and recorded test results published with the study, keeping trials where agents could run code and were not instructed to apply the wrong fix. In those trials, 2,634 of 3,067 patches generated by 1Password’s models (86%) blocked the supplied exploit. We excluded runs that the study classified as having consulted the upstream fix. Blocking that exploit does not establish a complete repair, but these results show useful patching capability under reasonable working conditions that the headline fails to convey.
The instructions and grading introduce further problems, several of which Davi Ottenheimer has also highlighted:
The stopping rule and grading criteria disagree. Agents given a proof-of-concept exploit were instructed to stop once their patch defeated it. The grader then evaluated vulnerable paths that the supplied exploit did not exercise.
The grading penalizes intended behavior changes. Agents were told to leave existing tests untouched, even though a correct fix can require updating tests to reflect changed behavior. We found that 8% of ActiveMQ verdicts penalized an intended behavior change as a regression.
The automated grades disagree with human review. Models grading their own patches matched human reviewers on the full five-category outcome in 65.9% of reviewed cases. Agreement was 87.7% for whether the original bug was fixed and 70.5% for whether new bugs were introduced. (Table 24)
Changing the reviewer changes the result. The two models assigned different outcomes to 36.8% of the same patches. The headline averages their assessments. (Table 20)
The Linux reference fix contains a vulnerability. The authors found 248 generated patches that repeated an off-by-one error in the upstream fix. The automated grader caught that new vulnerability in only 24 of them. (Section 4.4)
The Chromium grader accepts incomplete repairs. It marked many patches as clean even though they left a use-after-free vulnerability in a callback. (Section 4.9)
The grading errors can penalize valid fixes and let vulnerable patches pass. Combined with the handpicked sample and deliberately bad instructions, they leave the report without a credible basis for its headline. Defenders should not take 1Password’s headline rate seriously as a measure of AI patching ability.
Developers get one in eight fixes wrong under ideal conditions
Understanding agent failures also requires understanding how often developers submit incomplete fixes. Our security consulting work gives us a detailed record of how developers repair vulnerabilities in their own software. We give clients detailed vulnerability reports, then conduct a “fix review” to check whether their proposed patches fully resolve the issues.
Our records connect each vulnerability to the developer’s first proposed fix and our assessment of whether it worked. They preserve unsuccessful attempts that developers revise before an issue is considered resolved.
We reviewed the first fixes submitted for 2,265 vulnerabilities across 236 Trail of Bits security assessments from 2024 to 2026. The developers maintained the affected software, had detailed reports from our engineers, and knew we would review their patches. Even under those favorable conditions, 283 first fixes failed to fully resolve the reported issue: 12.5%, or one in eight.
Figure showing first fix submission outcomes
Accounting for multiple fixes from the same assessment, the 95% confidence interval is 10.5% to 14.5%. Sometimes we point out a mistake in a client’s patch during an informal conversation, and they correct it before the formal fix review. Those early failures may never appear in the review record, so our data can undercount failed first attempts. We also excluded cases where the available records did not establish whether the fix worked. A direct comparison with agents would require the same tasks and working conditions.
What happened to our patches in real projects
Through Patch the Planet, our joint initiative with OpenAI, Trail of Bits has co-authored hundreds of patches for widely used open-source projects. Agents wrote the patches with engineers directing the work and checking the results. Project maintainers then decided whether to merge, revise, or reject each submission.
How maintainers reviewed Patch the Planet patches
We examined the public review history of every Patch the Planet submission in our dataset that maintainers had merged or closed by September 14, 2026: 186 pull requests. 1Password’s benchmark used six vulnerabilities selected because their fixes were complex.
Maintainers merged 126 of our 186 pull requests, an acceptance rate of 67.7%.3In 91 of those 126 pull requests (72.2%), maintainers accepted the security fix we originally proposed.
Review outcome
PRs
% of merged PRs
Total merged
126
100%
Accepted with no security-relevant revision observed
91
72.2%
Accepted with security-relevant revision observed
33
26.2%
Indeterminate
2
1.6%
Table 1: Changes requested by maintainers for 126 merged Patch the Planet pull requests. Security-related revisions include repairs to a proposed fix and expansions of its security coverage.
Maintainer acceptance does not establish that every patch is correct.
Maintainers closed the other 60 submissions without merging them. Most were superseded by other work or declined for policy, process, scope, or maintenance reasons. Four were explicitly rejected on technical grounds.
Reason for closure
PRs
% of closed PRs
Total closed without merge
60
100%
Superseded, reimplemented, or re-landed elsewhere
36
60.0%
Policy, process, scope, or maintenance reasons
14
23.3%
Duplicate or convergent with another fix
3
5.0%
Explicitly rejected on technical grounds
4
6.7%
Other or indeterminate
3
5.0%
Table 2: Reasons maintainers closed 60 Patch the Planet pull requests without merging
One of those closed submissions was our freenginx patch.
A maintainer and an agent introduced the same freenginx crash
1Password’s case study examines a Patch the Planet fix for a memory-safety bug in freenginx’s embedded Perl module. An agent wrote our patch under the direction of a Trail of Bits engineer. It left one vulnerable code path open and introduced a new crash during request cleanup. The paper’s criticism of our patch is correct.
The maintainer closed our pull request and committed a separate fix. That fix covered all three vulnerable code paths but introduced the same crash during cleanup. The paper documents the maintainer’s regression too.
Both authors encountered the same trap. The original bug allowed Perl to destroy a callback before freenginx used it.
Both fixes kept the callback alive so freenginx could use it later. But if the request timed out first, freenginx would make the request unusable and then release the callback. Releasing it could run Perl code that still tried to use the request, crashing the worker. Both authors missed a problem their fix could cause later, during cleanup. Catching it required looking beyond the original bug to what happened when a request ended early.
Two authors, one human and one agent, working separately, made the same mistake on the same bug. Readers deciding whether to use agents need to know how their failures compare with those of human developers. Establishing which is more reliable requires measuring both under comparable conditions.
We checked what happened after our patches were merged
We examined about 33,500 subsequent commits in Patch the Planet projects. When a later commit changed a file our patch had modified, we investigated whether it fixed a problem our patch had introduced. For each suspected regression, an agent attempted to demonstrate its impact with a proof of concept. Other agents and our engineers then challenged the findings.
The review found at least ten functional bugs; four build, test, or release automation bugs; and one performance bug. It found no exploitable security vulnerabilities. Two examples illustrate the problems we identified:
In go-jose, PR #240 fixed a missing-header crash but exposed an existing validation gap, allowing encrypted messages to succeed even when their key length contradicted the declared algorithm. PR #266 added explicit key-length checks before decryption.
In Noble FROST, PR #250 returned cached round-two results without first checking whether a retry contained the same authenticated transcript. Changed or stale retry data could therefore bypass that check. The maintainer corrected the behavior by validating retries against the original transcript before returning cached results.
We are extending this investigation to every patch we authored, including patches with maintainer contributions. The findings will help us add checks that catch these failures before we submit future patches.
Agent skills for better security patches
We are releasing two agent skills alongside this post: post-patch-validation to help agents test security fixes, and review-walkthrough to help engineers review code changes.
Post-patch-validation is a new skill we wrote to help agents catch incomplete fixes and regressions before submitting patches for review. It was not used in the Patch the Planet work described above.
The skill starts with a vulnerability report and the code before and after the patch. It guides the agent through four tasks:
Reproduce the original bug. The agent writes a check that must fail on the vulnerable code and pass on the patched version. A test that passes on both revisions cannot demonstrate a fix.
Test another path to the same failure. The skill requires at least one distinct variant based on the bug’s root cause, such as a different caller or a cleanup path.
Check for regressions and new vulnerabilities. It compares behavior that should remain unchanged and tests security properties around the modified code. The plan must also include project tests, a sanitizer check, or a bounded fuzzing run.
Treat broken test runs as inconclusive. A failed build or missing dependency must not be mistaken for evidence that a vulnerability was reproduced.
Failed checks give the agent specific problems to investigate and repair before submitting its patch. The skill saves the tests and results so maintainers can see what was checked.
To try post-patch-validation, install the skill and give your agent the vulnerability report and the vulnerable and patched revisions:
“Use post-patch-validation to validate the patch in HEAD against <vulnerable-commit>, using the vulnerability report in <report-path>.”
Review-walkthrough helps engineers review the patches they are responsible for merging. It turns a branch’s complete diff into an interactive walkthrough that explains the changes in a logical reading order. Review findings appear beside the relevant code, where engineers can inspect them and draft their own comments. The walkthrough can also prepare a GitHub review for submission. Follow the quick start to generate a walkthrough for your branch.
These releases join our other public agent skills for improving security patches:
variant-analysis helps agents find related defects elsewhere in the codebase.
mutation-testing helps them determine whether their tests detect incorrect behavior and identify missing assertions.
We publish these methods so other teams can use them to examine and improve their own patches.
What a useful patching benchmark should measure
A useful patching benchmark should measure whether agents help developers produce correct fixes and how much review those fixes require. The principles in our 2018 guide to evaluating fuzzing research apply here:
Choose a sample that matches the research question. Explain how the sample was chosen and which repair work it represents. Difficult cases can expose failure modes. General failure rates require a representative sample.
Measure the effects of working conditions. Give agents appropriate tools and instructions. Report model configurations and test how reasoning settings affect results. Report misleading prompts and restricted tool access separately.
Make correctness verifiable. Check that patches fix the vulnerability beyond the supplied exploit. Test for security, functional, and performance regressions. Validate grades against expert review and publish the tests, configurations, and results.
Show how results vary. Report per-vulnerability outcomes and variation across repeated attempts. Repeating trials on the same bugs cannot establish that those bugs represent everyday patching.
Measure what agents contribute to the repair process. Compare developers working with and without agents on comparable tasks and under comparable conditions. Measure initial patch quality and the review and revision needed to reach a correct fix.
We are optimistic about AI’s usefulness to defenders. Through Patch the Planet, we are committing engineering time to fixing vulnerabilities alongside the people who maintain the affected software. We examine failures so we can improve our methods.
We will keep putting agents to work on difficult security problems and making the tools and lessons public. We want other teams to test our conclusions and take these methods further. Our goal is to give maintainers without dedicated security teams the ability to find and fix vulnerabilities that would otherwise go unaddressed.
The paper defines a clean fix as fully resolving the vulnerability without materially changing application behavior. ↩︎
The six-target mean has a standard error of about nine percentage points, which the report does not disclose. ↩︎
As of September 14, 2026, our dataset contained 240 public upstream pull requests. We excluded the 54 submissions still open from the outcome analysis. We count pull requests, each of which can contain more than one patch, and exclude maintainer-written replacements from our merged total. ↩︎
Fermat famously claimed to have a “truly marvelous proof” of his Last Theorem, but he never wrote it down, insisting the margin of his page was too narrow to contain it. A few centuries later, Anthropic announced a complete formalization of Fermat’s Last Theorem using 13 million lines of Lean code (clearly not what Fermat intended). Luckily, we found a wonderfully cursed Lean bug, shown below, that suggests the proof may have fit the margin after all. The issue affects all stable versions of Lean up to 4.33.1, and the patch is incorporated in v4.34.0-rc1.
A “checked” proof of Fermat’s Last Theorem using Lean 4.33.1
The blue checkmarks in the screenshot above would suggest that Lean considers this proof correct. This seems odd given the amount of work Sir Andrew Wiles put into this problem and the vast size of Claude’s proof. So what is going on?
The “proof” clearly doesn’t make any sense and exploits an issue in Lean. We found the issue while using GPT-5.6 to experiment with a new skill for code review. We want to clarify up front that the issue is not a kernel soundness issue, but it happens to nicely fit any discussion of strings, lengths, and substrings.
The issue affects String.Pos.Raw.extract, Lean’s low-level string-slicing function. When asked to extract a one-byte slice at an astronomically large position, Lean’s logical definition returns the empty string. But the compiled native code returns the entire original string. That disagreement is enough to manufacture a contradiction. Lean’s ordinary evaluator “proves” that the tiny slice was empty, while native evaluation “proves” that the very same slice contained “a truly marvelous proof.” Put those together, and Lean concludes that the empty string equals a non-empty string. And once you have a contradiction, you can prove anything, including Fermat’s Last Theorem.
On the bright side, the Lean team was considerably faster than mathematical history. About 90 minutes after we reported the issue, hargoniX opened a fix for the memory-safety problem, and it was merged roughly three hours after filing. The remaining semantic mismatch was fixed by Rob23oba five days after the report, closing the issue. We’d like to give a huge shoutout to hargoniX, Rob23oba, and the Lean team for the fast turnaround.
As a reminder, when dealing with external proofs, follow Lean’s guidance for validating a Lean proof. In our proof-of-concept code above, #print axioms flt shows 'flt' depends on axioms: [propext, Classical.choice, Quot.sound, flt._native.native_decide.ax_1_1]. The extra axiom native_decide adds the compiler to the trusted boundary, and therefore needs to be used with care. Machine-checked proofs will increasingly enable an unprecedented level of trust in mathematical results and critical software. However, more work is needed (e.g., lean4lean and alternative kernel implementations) to ensure that proofs aren’t deemed correct through exploitation of issues in theorem provers.
Fermat’s theorem took 350+ years to prove. If you don’t want to wait that long for your code to be audited, contact us.
As part of Patch the Planet, we received preview access to GPT 5.6-Cyber with a simple task: evaluate its cyber capabilities. Recent events inspired me to give it a challenge to work through: escape the VM I’d normally use for sandboxing. The target was a QEMU/KVM VM on my Linux dev machine (Debian Linux 12, AMD Zen3). It escaped the VM three different times.
First, it used recently disclosed bugs in my host kernel. When I fully updated, it used disclosed bugs that had not yet reached package maintainers or were not classified as security bugs. When I rebuilt QEMU and dependencies from the latest upstream source, it found several 0-days. It operated autonomously for hours, backtracked from approaches that didn’t work, pulled code and research papers, wrote oracles, made its own minimal examples, and aimed for a reusable, reliable exploit, all with minimal handholding and prompting. My main job was to physically reboot the machine when it hardlocked the host kernel.
If it wasn’t clear before, I will state it plainly: you can no longer assume a mere VM will contain a sufficiently advanced AI agent. To use a 2010s term of art, you should treat such agents as an advanced persistent threat.
Advancing cybersecurity capabilities
Let’s imagine a common situation: you want to run an AI agent, but need its full capabilities, including the ability to download, build and debug software; do research; sift through dependencies; set up fuzzers; triage vulnerabilities; and stand up services under different configurations.
The generally accepted solution is to set up a VM that serves as a safety perimeter and isolated prison for the agent: this virtual environment contains nothing of value, is separate from the host, and can be immediately deactivated or snapshotted for later investigation. This setup allows the agent to roam free, while isolating your computer from its consequences.
There is, of course, a tiny wrinkle. To be useful, the virtual environment must share resources with your host machine and provide a way to interact with the agent: you want to be able to see its screen, get files in and out, etc. You also almost certainly want the agent to have (some) network access.
Are these shared software, state, and communications pathways enough for the agent to escape containment? For a long time the answer was “no, absolutely not.” More recently, I’d have thought “maybe, after a while.” It turns out the real answer was “yes, and quickly.”
I gave the agent a simple task: It was in a CTF; to win, it had to break out of the VM and successfully read the flag file. The agent was started outside the VM, given SSH access into the VM environment, and permitted to do anything inside the VM. It was to keep a research log of findings. Why start outside the target environment, even though it could lead to cheating? I was operating under the (correct) assumption that escape attempts may lock/crash the VM during operation. The risk of starting the agent from the host was acceptable: there was nothing of particular importance on the dev machine, and any final exploit could be audited for cheating its objectives.
Escape 1: Januscape (CVE-2026-53359)
About an hour after letting the agent run, the host machine was hardlocked. Luckily, I had a logged-in session where I could read scrollback: the agent found my host machine kernel was vulnerable to Januscape (which was disclosed a few weeks earlier). There is no public exploit, but the agent had built one, and had enough confidence to test it—except that it didn’t land cleanly. I have no doubt that after some more revision it would have. One point for GPT 5.6-Cyber.
I updated my kernel to the latest offered for Debian 12.
Escape 2: libslirp
I am old and I like stability and consistency. That is why I run Debian 12, the current oldstable. Oldstable works, changes slowly, and gets security updates—exactly the known quantity I want from my software. Unfortunately, it seems that some security updates do not quite make it into the distribution. In this case, Debian 12 still ships libslirp 4.7.0, which is vulnerable to CVE-2026-9539. The agent also discovered that a bug fix commit in libslirp with no CVE assigned could be combined with CVE-2026-9539 to craft an arbitrary memory read/write in the host. After that, escape is trivial. Two points for GPT 5.6-Cyber.
For those curious, libslirp is a library that enables VMs to have networking, which you almost always want. I did not even know what libslirp was, or that the version I was running had both known and fixed-but-unmarked vulnerabilities. The AI agent deduced it quickly and was able to combine the two vulnerabilities to escape.
To make escape more challenging, I manually fetched the latest upstream libslirp and QEMU, and rebuilt a minimal QEMU with only the features I needed.
Persisting across long time horizons
One of the most impressive features of GPT 5.6-Cyber and Codex with goal mode is effective persistence over long (here, approximately 12-hour) time horizons across multiple compactions and innumerable subagent invocations. I did not do anything special to elicit this behavior; while my prompt included directions for the agent to keep a ledger of its findings, this was mostly for me, not for the agent.
The agent searched diligently and backtracked from multiple paths that led to failure. First it tried identifying what was accessible via the network on the host; it found a CUPS server (with a known CVE that had not made it to oldstable packages), but was not able to complete exploitation due to AppArmor. It then detected I run my host kernel with mitigations=off and attempted to use hardware bugs to get a read oracle of host memory (the primitive was too unreliable).
Eventually it went on a bug-hunting analysis of the host kernel source, QEMU, and associated libraries. It slowly chained together multiple vulnerabilities, including several 0-day bugs, until it could craft a reliable VM escape.
Escape 3: 0-days
This is what the agent used for the final exploit chain: three 0-days (at time of discovery) and one patched vulnerability that didn’t make it to my distribution kernel (because it was not recognized as a security issue):
Component
Patched?
Description
Capability
QEMU
No; bug has been reported.
VAPIC’s unchecked ROM alias could overlap locked SMRAM.
Exposed SMRAM and enabled attacker-controlled SMM execution.
Linux KVM
Patched in upstream
Bug details pending stable kernel patches
Left an attacker-modified shadow page unsynchronized and reusable.
A mode transition left a 96-byte panning buffer for a 1,024-byte render.
Controlled QEMU heap overflow
The target used -display none, so no display listener reached the renderer.
QEMU
No; bug has been reported
Queue reset left requests alive, causing inuse underflow and completion reentrancy.
QEMU denial of service and bounded queue-state corruption
No unbounded memory-write or host-execution primitive was demonstrated.
Challenging current software security assumptions
My suspicion was that GPT 5.6-Cyber would succeed, but the frequency and manner of its success removed all doubt. We have to reassess sandboxing quality for capable AI agents, and in general the software stack with which they interact.
An off-the-shelf VM is not enough to contain a modern, cyber-capable AI agent. There is simply too much attack surface. Even innocuous features (like running with a display) add extra, exploitable attack surface.
A distribution with rapid updates is now a requirement. I love older, stable software, but the cycle of backporting patches is simply too long. An older distribution (like Debian 12, my old standby) that isn’t getting immediate upstream updates should be assumed vulnerable. A competent agent will discover these bugs quickly and synthesize target-specific exploits.
What can we do? A start is using a virtualization technology that was purposely built with a minimal attack surface and a focus on security, like Firecracker. I had the AI agent run against Firecracker. It was able to hardlock the machine due to more Linux kernel flaws (all patched in upstream), but could not successfully escape. It may have, given even more time, but Firecracker is obviously a substantially harder target. In general, we have to become much more attentive to security fundamentals: least privilege (regarding network access, credentials, available features, etc.), logging, and active monitoring. Further, we can limit the time agents have to operate and ensure a pristine environment for each use.
We found and reported a bug in Provenance Blockchain, a public proof-of-stake chain built on Cosmos SDK, that lets any user grant themselves admin control over marker accounts without holding a single token. Provenance covers a range of financial services, including on-chain tokenized loans, private equity tokens, bridged assets, and asset registries. Our bug affected 82 markers representing live financial assets on mainnet.
We found the bug, which affects versions before 1.28.0, in March 2026, and reported it to Provenance on April 1. It was mitigated in PR #2627 (commit c81fd65), which shipped in v1.28.0 on May 1, 2026, and fixed in PR #2734, which shipped in v1.29.0 on June 8, 2026.
What is a marker?
The marker module is Provenance’s core primitive for fungible tokens. Chain participants can issue a new asset on Provenance by submitting a MsgAddMarkerRequest transaction; the chain creates a dedicated account for that asset, called a marker. Each marker is a special account type that controls:
A denomination (e.g., uusd.trading, cusd.deposit, cguaranteedrateomni)
An access control list governing who can mint, burn, withdraw, deposit, or administer the token
A supply field recording the canonical token count
An escrow balance (the marker account can hold any asset, not just its own denomination)
Markers are either supply_fixed (the supply field is enforced as a hard cap) or non-fixed (the bank module is the source of truth; the supply field is informational). This distinction is central to the bug.
The bug: An access check anyone can pass
AddAccess is the Cosmos SDK message handler that processes requests to modify a marker’s access control list. It checks whether the caller is authorized using three conditions, any one of which is sufficient:
The caller is the marker’s designated manager and the marker is in Finalized state.
The caller already holds ACCESS_ADMIN on the marker.
The caller controls 100% of the marker’s circulating supply.
casetypes.StatusFinalized,types.StatusActive:if!(caller.Equals(m.GetManager())&&m.GetStatus()==types.StatusFinalized)&&!m.AddressHasAccess(caller,types.Access_Admin)&&!k.accountControlsAllSupply(ctx,caller,m){returnfmt.Errorf("%s is not authorized to make access list changes against finalized/active %s marker",caller,m.GetDenom())}
The m.GetSupply function reads the supply field stored directly on the marker struct. For non-fixed supply markers that were activated with zero supply, that field always stays zero. The live circulating count lives in the bank module, and non-fixed markers never write back to the marker struct after minting.
So for any non-fixed supply marker, the authorization check reduces to the following:
Figure 4: MsgAddAccessRequest granting the attacker admin, mint, and withdraw permissions on a target marker
No existing tokens are needed for exploitation. The authorization check passes immediately via the broken condition 3. From there, the attacker has two paths:
MsgMintRequest: to mint new tokens of the marker’s denom and send them to any address
MsgWithdrawRequest: to drain any assets held in the marker’s escrow balance
The whole attack is two transactions: one to gain permissions, and one more to act on them.
Impact: What was at risk
At the time of discovery, 82 active markers on Provenance mainnet had a stored supply of 0 while carrying real circulating supply or escrowed assets, every one of them exploitable. These markers span multiple independent parties on the chain, not a single application.
Escrow withdrawal was the most direct path. Among the affected markers, those holding nhash (Provenance’s base token) in escrow accounted for roughly 30 × 1015 nhash, or around $500,000 at HASH prices at the time of discovery. The three largest markers are shown below:
Marker
Owner
Escrowed nhash
grant0051
Provenance Foundation grant program
19,230,770,000,000,000
provenance.validator.incentive.program
Chain validator incentive fund
8,561,225,000,000,000
grant0077
Provenance Foundation grant program
2,486,556,736,909,250
The three markers shown above are all chain governance programs operated by the Provenance Foundation: one holds validator rewards, and two hold community grant funds.
Supply inflation was a broader but more constrained vector. The 74 vulnerable markers spanned bridged stablecoins and wrapped assets (uusd.trading, uusdc.figure.se, nbtc.figure.se), consortium deposits (cusd.deposit), tokenized mortgage participations (cguaranteedrateomni, chomebridgeomni), and yield tokens (nuva.ylds, uylds.fcc). An attacker with ACCESS_MINT on any of these could issue arbitrary new tokens of that denom. The practical harm depended on the token type. For restricted tokens with KYC requirements, it was primarily a solvency and integrity threat; for non-restricted coin-type markers, it was a more direct inflation risk.
We confirmed the affected markers and their balances by querying mainnet via the Provenance CLI and the public REST API.
The fix: Read live supply, and guard against zero
PR #2627 shipped the mitigation, which adds a check against zero supply:
This blocked the attack we reported. All 82 affected markers had a stored supply of 0, and a zero-supply marker now fails the check outright.
It did not fix the divergence. The comparison still read the stale field, so it still passed whenever that field was non-zero and the caller’s balance happened to match it.
PR #2734 shipped the full fix, which changes one line:
// Before: reads stale stored field, always 0 for non-fixed markerssupply:=m.GetSupply()// After: reads live circulating supply from the bank modulesupply:=k.bankKeeper.GetSupply(ctx,m.GetDenom())
Both sides of the comparison now come from the bank module, so there is no stale field left to diverge.
Authorization must fail from the default state
The root cause of this issue was state desynchronization. The marker struct and the bank module both represent the token supply, but only the bank module is kept current for non-fixed markers. The authorization check read from the wrong one.
The check wasn’t just wrong; it was bypassable by default because of the zero-equality shortcut. Because the stale field was always 0, the comparison 0 == 0 was always true. An access control check that compares against a value that is always the same as the attacker’s default state is trivially bypassable.
Switching to the live bank supply alone doesn’t fully close the hole. A freshly deployed marker with no tokens minted yet also has live supply of zero, so an attacker could self-grant admin by targeting it before it’s funded. The fix handles this with an explicit zero-guard: accountControlsAllSupply returns false whenever live supply is zero, regardless of balance.
The broader pattern: an authorization predicate must never be satisfiable from the attacker’s default state. A check of the form balance == supply hands access to everyone when supply can be zero, whether because the state is stale or the marker is simply unfunded.
Two things would have caught this before it went live. First, the access-list authorization model was never specified. Writing the rule down forces both questions that point straight at the bug: which supply, and what happens when it’s zero? Second, the property is easy to state: accountControlsAllSupply should only return true when live supply is positive and the caller holds all of it. A property-based test or fuzzer that generates random sequences of marker operations, such as minting, transferring, and creating empty markers, and checks this property after each step would find both failure modes automatically.
Every Signal chat starts the same way: the client asks the Signal server for the public key associated with your contact’s phone number. But how do you know the server gave you the right key? A compromised server could provide a false public key, allowing the client to encrypt messages to an attacker rather than the intended recipient.
Until now, the only way to detect such malfeasance was to verify safety numbers with your contact in person or over a trusted channel. Signal recently launched an alternative: Automatic Key Verification, a feature that helps validate that your chats are secure without requiring direct safety number comparison. Trail of Bits built and operates one of the three auditors that make this system trustworthy. Our auditor, which is an independent implementation written from scratch, continuously checks that the Automatic Key Verification system behaves honestly.
How key verification works
Automatic Key Verification is a form of “key transparency” that makes mismatch attacks harder to hide by creating a globally consistent view of the set of public keys associated with each phone number. The Signal app now performs a periodic self-check to ensure that all keys stored in the global map for your account belong to your devices. If the app is unable to verify the log, or finds that not all keys are expected, the user is presented with a warning that “Automatic Key Verification is currently unavailable for your device.” Automatic Key Verification may also be unavailable for other reasons, as outlined in Signal’s documentation.
What our auditor does
Automatic Key Verification depends on external auditors. Trail of Bits helps this system function by providing external verification that the user ↔ public key map is globally consistent and well formed, and does not hide any entries. Each time a new entry is added, we update our local copy of the map, stored as a Merkle tree. Periodically, we sign the head of the tree using a signing key that only we know. Because we commit to only ever signing one consistent lineage of Merkle trees, clients know that they are seeing the same set of public keys as everyone else in the system. Clients currently require signatures from each of three auditors: one operated by Signal, one operated by Cloudflare, and one operated by Trail of Bits.
When Automatic Key Verification is turned on, the Signal client periodically fetches Merkle tree heads from the Signal key transparency server. The client requires that each tree head belong to a lineage endorsed by all registered auditors within the last seven days. If the server does not present valid auditor signatures, the client will raise a warning and Automatic Key Verification will fail. A fully malicious server may therefore maintain a split view of the system for at most one week before client applications start to display warning messages.
We will provide updates to this blog post if we need to make substantive changes to our signing policy, such as resetting the state of our auditor or rotating our signing key. Our current public key is:
You can enable Automatic Key Verification in Signal by going to “Settings > Privacy > Advanced” and enabling Automatic Key Verification. In supported chats, you can verify the public key of your counterparty by visiting the safety number verification screen and clicking “Verify Automatically.” Automatic Key Verification often does not support chats where you started the conversation by searching for a recipient’s username. See Signal’s help page for more information. If automatic verification fails, users should fall back on safety number comparison.
Why we’re doing this
We believe that free and private communication is a critical public good. We are not paid by Signal or any other party for this service; we operate it in the interest of users and the community broadly.
Some form of public key integrity is an important component of any full end-to-end encryption system. If you would like to implement key transparency or end-to-end encryption generally, contact us.
Nitro Enclaves and Key Management
Service (KMS) feel like a
natural fit: since the KMS can verify attestation documents generated by the enclaves, developers
can offload key management tasks from their applications to the AWS-managed service. But integrating
an external service with your trusted enclaves comes with new threats, even if that service comes
from the same provider.
In this blog post—the third in our series on Nitro Enclaves, following our posts on attack
surface and images and
attestation—we catalog
passive and active attack classes against the enclave-KMS communication channel, and cover the
operational risks that persist even when the cryptography is correct.
Intro to KMS
The KMS is an AWS service that provides a unified public API for creating and managing keys
backed by HSMs to the broader AWS ecosystem. There are three main key types supported by KMS
that devs need to care about:
CMKs never leave KMS. You request KMS to perform cryptographic operations (like encryption or
signing) for you.
Data keys and key pairs are generated in KMS, are not stored in KMS, and are intended for
programmatic uses.
For symmetric keys, the KMS gives you a plaintext key and the same key encrypted to CMK. Your
application performs encryptions, removes the plaintext key, and stores the key encrypted to a CMK
along the ciphertexts; this pattern is called envelope
encryption.
For asymmetric keys, the KMS gives you a plaintext key pair and the private key encrypted to CMK.
Your application creates signatures or encrypts data, deletes the private key, and keeps the public
key and encrypted private key (along with signatures/ciphertexts).
Both types of data keys can be used with Decrypt operation to get plaintext keys again.
Figure 1: Basic KMS operations. cmk_id is an ID (ARN) of CMK key, cmk is the actual key used, enc/dec are any encryption/decryption algorithms, GenerateDataKey and Decrypt are KMS operations.
There are two mechanisms that are in play when integrating KMS with Nitro Enclaves:
KMS policies restricting access to CMKs to specific enclaves (by PCR values)
KMS encrypting responses to enclave’s public keys
In the first mechanism, the key policy may authorize access to only requests that contain fresh and
correctly signed attestation documents with the expected PCR values. Enclaves have to generate
attestations and include them in requests to KMS. Note that the enclave still needs IAM credentials
to access KMS in the first place.
The second mechanism is about enclaves sending asymmetric public keys (inside the attestation
documents) to KMS, and KMS encrypting part of the responses to the key. This mechanism is supposed
to ensure that only the requesting enclave can see output from KMS.
Note the absence of the Encrypt operation: enclaves can request this operation, but without the
attestation-based security mechanisms. CMKs cannot be used directly by enclaves for encryption
without missing on the attestation checks. This means cryptography operations are supposed to be
implemented via data keys, and not directly via CMKs.
Figure 2: Basic KMS operations with enclave attestation.
Use cases
KMS can be integrated with Nitro Enclaves for various reasons: for application-specific needs, to
sign enclave image files (EIFs), or to increase the entropy available in the enclave.
The application-specific use cases are based on KMS’ ability to verify attestation documents, which
in turn enables developers to write KMS authorization policies based on PCR measurements from the
attestation. A common use case is implementation of authenticated external
storage for the enclaves. When access to KMS keys is
restricted by PCRs 0-2, only a specific enclave version has access to the keys.
Enclave image files can be signed. Any signing certificate (private key) can be used for the task,
but the officially supported
ways include signing with
a key stored in a local file, and via KMS. The signing certificate used for the EIF is then exposed
as PCR8. This PCR can be
used in KMS policies. This feature lets one to restrict access to KMS keys to enclaves created by
the same developer, while developer identity is protected by the KMS too.
Finally, the GenerateRandom method of
KMS can be used to
add more entropy to the
enclave. While not critically
important – enclaves already have access to high quality entropy from the hypervisor – additional
randomness may increase trust in the system. On the other hand, one may argue that the added
complexity exceeds the benefits. No strong opinions here.
Passive attack prevention
Threats to the enclave-KMS communication can be divided into two categories: passive and active.
Passive attackers can observe traffic and modify data that is stored outside of the enclave and is
not attested (data at rest). Active attackers can additionally modify all traffic coming
in and out of the enclave (traffic on the network).
The exact landscape of passive attacks depends on specific system design, but KMS operations allow
us to reason about them fairly well, as an attacker can control any and all of the inputs to these
operations. This tl;dr checklist helps avoid passive attacks:
Requests to KMS always contain the Recipient parameter.
Encryption context is used for supported operations.
Context is decided by enclaves, and is not fully attacker-controlled.
Encrypt and GenDataKey operations are authorized properly.
Data encrypted with data keys has context.
Key commitment is considered.
Correct CMK is used.
CMK ARN is hardcoded.
keyId from response is checked.
Decrypt requests always specify key ID.
IAM role is attested.
Full ARNs are used, key aliases are not used.
Freshness/replay attacks are mitigated.
Side-channel attacks are considered.
Key types and cryptographic algorithms are validated.
The Recipient
parameter includes
attestation, which allows KMS to validate PCRs. If key policies are correctly configured, requests
without this param fail, so it is rather hard to miss.
A single CMK key can be used to generate multiple data keys and shared secrets. Since the encrypted
data keys are stored outside of the enclave, an attacker can swap them. It is therefore important to
cryptographically distinguish the ciphertexts, and the encryption
context is one of the
ways to achieve that. Importantly, this solution works only if the attacker does not have full
control over the encryption context; if they do, they can swap the ciphertext blob while also making
the enclave use the wrong context.
Below are diagrams for simple “data swap” attacks that encryption contexts can prevent.
Figure 3: Simple data swap attack and prevention.
Passive attackers that can call Encrypt (or ReEncrypt) on a CMK can perform an even more severe
version of the attack above and swap the DK-ciphertext pair with a custom one, effectively providing
arbitrary plaintext to the enclave. The same issue applies if an attacker can call
GenerateDataKey. Note that some cases may
require authorization to these
operations for non-enclave entities, but this authorization should be revoked after the initial
setup.
Figure 4: Data swap attack with Encrypt operation.
The attacks we’ve discussed so far have been on the “envelope” level. Similar issues exist on the DK
level if a DK is used multiple times (though this rarely happens). These issues should be solvable
with correct encryption context implemented via AAD.
Figure 5: Attack on a reused DK and proposed prevention.
Some funky attacks are possible if an algorithm without key commitment property is used with data
keys: an attacker can generate a single ciphertext that correctly decrypts under different keys.
Though this is unlikely, the key commitment should be considered as part of a security audit.
Figure 6: Lack of key commitment may allow an attacker to select plaintext by providing a different encryption key (E2/E3) dynamically, if ciphertext (C2) must be pre-selected.
The next class of attacks is when the host can select CMK that enclave uses. The exact nature of the
attack depends on specific degrees of freedom, but in the worst case, the host can force the use of
a completely unprotected CMK.
To protect against these attacks, the enclave must ensure the expected CMK is used; this can be done
by hardcoding full ARN, so it is attested. Then the attested ARN must be provided as the optional
keyId
parameter in Decrypt requests, and validated against keyId from KMS responses. Note that the
keyId param is optional, because CiphertextBlob includes a reference to the CMK as metadata
(HBKID in Appendix A): the metadata is not cryptographically protected, and the attacker may be
able to manipulate it.
Figure 7: CMK substitution attack.
Using key aliases instead of ARNs is possible but risky, as the aliases are more ambiguous. Specifically,
an attacker can manipulate the enclave’s IAM credentials to trick the enclave into using the wrong
AWS account or AWS Region
and therefore a wrong CMK. That’s why we recommend attesting the IAM role that the enclave must use
and validating that role against IAM credentials provided at runtime. The enclave can do this
by calling sts:GetCallerIdentity.
Replay attacks are an interesting attack vector. Attestations include timestamps that KMS validates
to be at most five minutes old. While this means old documents cannot be replayed, there is still a
time window when a malicious host can observe a document and use it multiple times. As attestations
are not cryptographically bound to the requests, the attacker can use the attestation with any
supported operation with arbitrary params. Although the responses are encrypted with the
attestation’s public key and cannot be decrypted by the attacker, this gives the attacker some
abilities that must be considered during an audit. For example, an attacker can request multiple
decryption with different CMK keys and later use the KMS responses to confuse the state machine of
the enclave. Note that the user_data and nonce fields from attestation documents are not used by
KMS at all.
Even when an attacker cannot observe exact traffic exchanged with KMS, the attacker can note times,
orders, and sizes of communication. This may be used to deduce some information, depending on the
specific protocol your enclaves implement.
Finally, requests and responses to KMS include many key specifications and algorithm identifiers
(CMK KeySpec, attestation’s KeyEncryptionAlgorithm, Decryption operation’s
EncryptionAlgorithm, for example). Ideally these must not be attacker-controlled in requests (e.g.
are bundled in EIF) and the identifiers from responses are checked against the expected ones by the
enclave.
Active attack prevention
As a reminder, active attackers can additionally modify all traffic coming in and out of the
enclave. This tl;dr checklist helps avoid active attacks:
Active attacks are prevented with enclave-initiated TLS.
TLS CA is bundled inside the enclave (attested).
VPC is used.
Many problems may arise when active attacks are in scope. Most importantly, the attestation and its
pubkey are not bound to other parts of the request. This allows the attacker to change the CMK ID in
requests and responses (even if the ID is bundled in EIF); to encrypt any data key under the
attestation pubkey and use it for replays; or to attack not-authenticated AES-CBC encryption in
CiphertextForRecipient responses.
Figure 8: Active attacks on CMK and DK.
These vulnerabilities are basically unsolvable without a secure communication channel. Therefore,
TLS initiated inside the enclave is required if active attacks are in scope. For the
enclave-initiated TLS solution to be secure, the enclave’s CA set must be limited; ideally, the KMS’
CA certificate (Amazon’s) is attested and pinned.
With this setup, the active attacker threat may be considered prevented. Note that having a secure
communication channel implicitly prevents some of the possible vulnerabilities described in the
“passive attacks” section.
KMS terminates TLS outside of HSM (most
likely),
and the attestation’s pubkey encryption is probably done outside of HSM. This makes it impossible to
have an end-to-end TLS channel between enclave and HSM, and AWS insiders may theoretically
constitute an active attacker threat. Your threat model should account for this possibility.
To further protect the communication channel, VPC can be
used. This ensures
that traffic never leaves AWS infrastructure and generally isolates the parent EC2 at the network
level. Moreover, key policy can authorize requests based on the
VPC. This makes
attacks easier to detect in case of stolen IAM credentials; this is valuable even if key access is
authorized via PCRs, as demonstrated in the previous sections.
KMS policies
Correctly authorizing access to CMK keys is critical. The list below includes basic checks for your
KMS key policy. AWS’ recommendations for IAM
policies
provides more generic advice.
Configured KMS policy authorizes enclaves in a reasonable way.
No unexpected IAM roles have or can get access.
PCR0 is used for authorization. PCRs 1-2 are used for defense in depth. Alternatively, PCR8
is used.
Principal for RecipientAttestation is not a wildcard.
For critical key operations (e.g., deletion) the policy requires MFA.
TLS and VPC restrictions are considered.
For end-to-end security, the clients can verify that the enclave uses correct and properly
secured KMS keys.
Immutable key policies are likely not possible, and clients must be aware of this.
Of course, the exact CMK policy setup is business-dependent. Generally, you should ensure that the
key can be managed only by the expected IAM principal, and the principal doesn’t have access to
Decrypt operation (and possibly others like GenDataKeys and Encrypt).
The figure below shows an interesting example of a vulnerable key policy that violates the “only
expected IAM principal” check. One may assume that only the root user and the enclave can operate on
the key, but this is incorrect: the first policy entry grants full access to any IAM role that has
access to the key configured in the role’s policy. The fix is to use a specific IAM user or role
instead of root or to add an explicit deny statement for non-root users.
[{"Sid":"Enable IAM User Permissions","Effect":"Allow","Principal":{"AWS":"arn:aws:iam::599412696120:root"},"Action":"kms:*","Resource":"*"},{"Sid":"Allow Nitro Enclave KMS operations with PCR0 lock","Effect":"Allow","Principal":{"AWS":"arn:aws:iam::599412696120:role/NitroEnclaveKMSRole"},"Action":["kms:Decrypt","kms:GenerateDataKey","kms:GenerateDataKeyPair"],"Resource":"*","Condition":{"StringEqualsIgnoreCase":{"kms:RecipientAttestation:PCR0":"00a119d1...0ed55"}}}]
Figure 9: Example policy that is likely to be insecure.
For the PCRs, you want to use PCR0, as it binds the policy to specific enclave code. Additionally,
using PCRs 1-2 is recommended for the reasons stated in our blog post on the Nitro Enclaves attack
surface. Alternatively, you can use
PCR8, which allows updating the enclave code without needing to update key policy. This allows more
restricted access to key policy modification permission at the cost of managing the signing key.
The Principal field and PCR3 measurement provide further restrictions. Principal is used to
authorize the IAM role used to access KMS, while PCR3 is measured by hypervisor at the time of
enclave launch based on EC2 role. The EC2 role can be dynamically changed and should be
considered untrusted from the enclave’s perspective. Yet both Principal and PCR3 can be used to
prevent attackers from running (signed) enclaves on their own EC2 instance (which could make
side-channel attacks easier) and accessing the KMS key.
Access to the key can be further improved with TLS and VPC restrictions. VPC can be enforced with
aws:SourceVpc and similar condition keys. TLS can be enforced with the aws:SecureTransport
condition (although this condition is redundant, as it’s not possible to access the KMS API with
plain HTTP).
As the key has to be manageable by some IAM role (at least to allow key deletion), the
aws:MultiFactorAuthPresent and aws:MultiFactorAuthAge conditions can be used to strengthen the
authorization.
KMS policy end-to-end verification
So far, our discussion has focused on how to secure the KMS keys. A much more difficult problem
arises when you want your system to provide end-to-end verifiability to end-users. If enclaves can
be reproducibly built and remotely attested by users, then users likely have to validate that the
KMS keys are properly protected, too. Otherwise, a malicious insider can pass remote attestation
(not modify enclave code), yet use KMS directly with IAM permissions to get full access to the keys.
One solution is to hardcode the hash of the key policy in the enclave, provide full policy along
with enclave’s code to clients, and make the enclave validate the hash against the dynamically
obtained policy before sending attestation-protected requests to the KMS. This requires the enclave
to have kms:GetKeyPolicy and kms:DescribeKey permissions.
This alone doesn’t prevent attacks. A malicious IAM user can dynamically change the policy after the
enclave’s verification. To prevent this, the policy has to be made immutable, which can be achieved
by blocking kms:PutKeyPolicy permission for all users. Note that
--bypass-policy-lockout-safety-check
flag is required to
insert such a statement via CLI.
Figure 10: Example policy that prevents key policy changes.
Locking access by PCR0 and denying all kms:PutKeyPolicy operations makes the system quite
immutable. This has the obvious downside of making updates and bug fixes difficult. As mentioned
earlier, the specific setup must be adjusted based on business requirements.
Note that key owners can always contact AWS support to restore default key
policies.
How AWS authenticates such requests I do not
know,
but AWS likely won’t check if the key is used in an enclave-enabled setup. This makes a system with
full end-to-end trust hard to implement.
For example, suppose you create a key policy that gives only one user access to the KMS key. If
you then delete that user, the key becomes unmanageable and you must contact AWS Support to regain
access to the KMS key.
Figure 11: Quote from AWS documentation.
Finally, consider implementing publicly observable and verifiable monitoring and alerting for key
policies. Such a system would alert end users when a policy changes, mitigating the impact of policy
restoration by AWS support. However, we are not aware of any “Certificate Transparency”-style
public, append-only log for KMS key policies that an external party can independently verify.
Operational concerns
Even if the system is secure point-in-time, there are operations that must be periodically
performed. These introduce new risks into the system. This checklist covers these concerns:
Key rotation and revocation is implemented for CMK.
ReEncrypt operation is not used for data keys.
Backups:
Risks from CMK destruction are mitigated.
Regional outages are considered.
Data keys are backed up as needed.
Users cannot cause a denial of service or balloon the bill.
The number of user-triggered KMS operations is limited.
Request quotas are considered.
Limits on data lengths are respected.
KMS’s clients take into account delays in KMS updates.
AWS provides mechanisms to
easily rotate CMK keys. The only item to note here is that rotating a compromised CMK does not make
data keys protected by it non-decryptable. For a CMK revocation, a more involved approach than
just rotating CMK and destroying data keys must be implemented.
Rotating data keys is hard to implement securely, as the KMS
ReEncrypt operation does
not support attestations. The system should be designed so that such rotations are not needed.
A malicious actor deleting CMK keys permanently creates a risk of non-recoverable system state. The
system’s design can sometimes be made so that destruction of a single key is recoverable (e.g., by
setting up key hierarchy and using secret sharing). Nevertheless, there should be security controls
in place mitigating the risk. First, configure a scheduled deletion
period for keys
to a time in which your team can act on an incident. Set up CloudWatch alarms for KMS
keys
for deletion events, and tighten IAM policies with Service Control Policies that prevent KMS key
deletion.
Single-machine disasters in AWS infrastructure are not a concern, as single-region KMS keys are
replicated within the
region in
multiple Availability Zones in multiple HSMs. However, if the system must be resilient to a regional
outage, multi-region
keys should
be used instead of single-region keys.
Encrypted data keys backups are a responsibility of the system, not AWS. Note that the CMK key may
become unusable in a few
scenarios, and the
data key backup system must account for this.
Yet another set of risks relates to billing. AWS charges dollars per KMS operations and CMK key
maintenance, so the system must not let end-users make the enclaves send arbitrary many requests to
KMS. When implementing rate-limits, KMS
quotas must be
taken into account.
Inputs to KMS have various size limits. For example, plaintexts can be up to 4096 bytes long,
ciphertexts can be up to 6144 bytes long, and key IDs can be up to 2048 bytes long. These limits are
unlikely to be reached with attestation-supported operations, but still should be considered.
Finally, changes to KMS resources need some time to propagate and
synchronize
inside AWS infrastructure. Your system must expect delays and possible temporary inconsistencies
when requesting KMS.
Software and SDKs
Amazon ships a lot of SDKs for various tasks. Among them is
aws-nitro-enclaves-sdk-c that provides tools
and a library for enclaves-KMS communication. Avoid it: this particular SDK is written in C, and we
found it contains vulnerabilities that can be used to exploit enclaves from the parent host.
Rather than using the aws-nitro-enclaves-sdk-c, we recommend a combination of other libraries,
such as the following:
Any cryptographic library to parse and decrypt responses
Final notes
Many issues can arise from misusing the KMS within enclave-secured systems. This blog post does not
even cover all supported operations (GenerateDataKeyPair, DeriveSharedSecret), possible
vulnerabilities (key reuse, key wearout, forward secrecy, nonce management, …) and system features
(custom key stores, multi-region keys, …). Make sure to document your system’s protocol, have a
cryptographer review it, and check the actual implementation against it.
Appendix A
Data formats of the CiphertextBlob and CiphertextForRecipient structures are presented below.
Figure 12: KMS CiphertextBlob. One cannot decrypt its content manually because the KDF label is not public. HBKID (HSM backing key ID) is mapped to CMK ARN internally.
Figure 13: KMS CiphertextForRecipient. Note the use of AES-CBC.
Uniswap v4 hooks let developers add custom behavior to pools, including dynamic fees, custom accounting, and external integrations. This flexibility moves some security responsibilities into application and hook code.
The Cork and Bunni exploits are two app-level incidents that show what can go wrong in that code. Together, they account for more than $20M in losses. Neither incident stemmed from a flaw in the Uniswap v4 core protocol or the PoolManager; both arose from application-specific authorization and accounting logic built around hooks.
After analyzing dozens of findings from Trail of Bits audits (including our Uniswap v4-core security review), public reports from other firms, and the Solodit database, I’ve identified seven recurring failure patterns in application and hook code, including missing caller checks and accounting bugs that still satisfy the PoolManager’s settlement invariant. Builders can use these patterns as a secure-development checklist; auditors can use them to focus their review.
What the PoolManager guarantees
If you’re familiar with Uniswap v3, where each pool was a separate contract, v4 inverts the model. All pool state now lives in a singleton PoolManager contract, with each pool represented in its storage. Uniswap v4 adds hooks: independent contracts that execute custom logic at specific points in the swap and liquidity lifecycle.
Figure 1: Pools live inside the singleton PoolManager, and multiple pools can use the same hook contract.
Figure 2: A pool's PoolKey includes both currencies, the fee, tick spacing, and the hook address (v4-core/src/types/PoolKey.sol).
Notice that the hook address (IHooks hooks;) is part of the pool’s identity. If you change any of these fields, you’re talking to a different pool. This matters because trusting the wrong PoolKey means trusting the wrong pool.
v4 also introduces a session-based model that works like a flash loan. Your contract calls unlock() on the PoolManager, which triggers a callback into your code. At the end, the PoolManager checks that no unsettled currency deltas remain:
function unlock(bytes calldata data) external returns (bytes memory result) {
 Lock.unlock();
 // ... callback execution happens here ...
 if (NonzeroDeltaCount.read() != 0) revert CurrencyNotSettled();
 Lock.lock();
}
Figure 3: Simplified PoolManager.unlock() flow: unlock the session, execute the callback, and revert unless all currency deltas settle to zero (v4-core/src/PoolManager.sol).
Figure 4: A periphery or hook calls PoolManager.unlock(), handles unlockCallback(), and calls swap() inside the unlocked session.
The PoolManager enforces v4’s protocol mechanics, including pool initialization rules, swap and liquidity math, hook-callback sequencing, and end-of-session settlement. Hook developers are responsible for validating the application-specific assumptions their hooks add.
Each hook must decide:
Who can call its privileged paths
Which pools are legitimate
How custom balances and deltas should be accounted for
Whether external integrations can fail or reenter safely
1. Anyone can call your hook
Hook callbacks are external functions on your contract. If you don’t check the caller, an attacker can call those callbacks directly with malicious parameters. A loose unlockCallback path can also reach internal actions that should never be callable.
The fix: use BaseHook for hook entrypoints and SafeCallback for unlockCallback. Together, they enforce caller checks on the callback paths they cover:
Figure 5: onlyPoolManager restricts hook callbacks to the configured PoolManager.
Add an equivalent caller check only on paths those contracts don’t cover.
Real-world example: The Cork exploit (~$12M, May 2025) shows why this check matters. Cork let data from an untrusted path reach hook logic that affected redemptions. That access-control gap, combined with a pricing issue elsewhere in the protocol, gave the attacker a way to drain funds.
2. Treating any pool as legitimate
Pool creation through the PoolManager is permissionless by default. Unless your hook restricts initialization in beforeInitialize, anyone can create a pool with your hook address attached. If your hook trusts a user-supplied PoolKey without validation, an attacker can route your logic through a malicious pool with currencies and parameters they choose.
An attacker-created pool presents two immediate risks. First, if your hook stores per-pool data keyed by PoolId, the new pool gets its own mapping slot. The attacker can influence values written through activity in that pool, and later accounting paths may treat those values as trusted. Second, currency0 and currency1 are attacker-chosen currencies. If either is an ERC-20, token interactions can trigger malicious behavior or reenter other hook functions mid-flow.
The fix: bind your hook to canonical pools during deployment or trusted configuration, or maintain a strict allowlist. Re-check the derived PoolId on every user-controlled path:
// Pseudocode for pool binding
PoolId poolId = key.toId();
if (!allowedPools[poolId]) revert InvalidPool();
Figure 6: Derive the PoolId from the supplied PoolKey and reject pools that are not allowlisted.
Real-world example: In Semantic Layer’s SVFHook finding, the addLiquidity function lets callers specify the PoolKey. An attacker could route deposits through a custom WETH/SVF pool with a malicious hook and earn points at a lower cost than intended.
3. Custom accounting leaks value
In v4, a delta is a signed currency-balance change owed to or from the PoolManager. Once your hook touches deltas, a wrong sign, a rounding error, or mixing balance buckets can silently leak value. These bugs are subtle because settlement only checks that the session’s currency deltas resolve; it does not validate the hook’s internal accounting. A hook’s accounting can still be wrong even when settlement succeeds.
Return-delta hooks can move beyond fee bookkeeping. If a BeforeSwapDelta consumes the user’s entire specified amount, the PoolManager has no amount left for its concentrated-liquidity swap; the hook supplies the trade instead. This is often called a NoOp swap. Treat that hook as a custom AMM: test conservation, price bounds, rounding, and returned deltas against real balances.
Dynamic fees are also price-sensitive. A dynamic-fee pool can accept a per-swap fee override from beforeSwap, and its hook can update the stored LP fee. Bound every fee, limit how quickly privileged changes can move it, and do not derive it directly from inputs an attacker can cheaply manipulate.
For hooks that move value, test at least these three accounting invariants:
No user receives output that the accounting did not charge for.
A same-transaction round trip cannot create value from accounting alone.
Internal accounting matches actual asset balances.
Those invariants must also hold for the tokens the hook handles. Fee-on-transfer tokens can make the amount received smaller than the amount sent; rebasing tokens can change balances without a transfer; callback-enabled tokens can reenter; and pausable or blacklistable tokens can block settlement. State which behaviors you support and test accounting against observed balance changes.
The fix: keep LP funds, fees, and incentives in separate buckets. Label every balance and delta, including who owns it, and who can move it.
Real-world example: The Bunni exploit ($8.4M, September 2025) was a rounding bug in BunniHook’s idle-balance accounting. The attacker pushed a pool’s price tick with a flash loan, then made 44 tiny withdrawals that each shrank the active balance disproportionately to the shares burned, eventually extracting profit from the affected pools. Each transaction satisfied the PoolManager’s settlement invariant because the bug was in BunniHook’s internal accounting.
4. Right logic, wrong hook
Figure 7: PoolManager runs beforeSwap before executing the swap and afterSwap afterward when the corresponding address flags are set.
The beforeSwap hook executes with pre-swap state, but the afterSwap hook sees post-swap state. Code that’s correct in one hook can be unsafe in another.
The same timing problem affects liquidity callbacks. In this LiquidityPenaltyHook finding, a JIT-liquidity penalty was computed during afterRemoveLiquidity, but a user could first make a tiny liquidity increase that collected the fees separately. By the time removal ran, the hook saw no fees left to penalize.
In our hook audits, we’ve repeatedly observed developers put logic that needs the final swap result in beforeSwap instead of afterSwap. The code looks correct in isolation, but it’s operating on stale data.
The fix: verify your logic is in the correct hook for the state it needs.
5. Address bits are part of the API
In v4, the hook address itself encodes which hook functions the PoolManager will call. This design makes the deployed address part of a hook’s API, so developers must keep its permission bits in sync with the functions they implement.
function hasPermission(IHooks self, uint160 flag) internal pure returns (bool) {
 return uint160(address(self)) & flag != 0;
}
Callback bit set + callback missing → transaction reverts.
Callback implemented + callback bit missing → PoolManager does not call it.
Return-delta bit missing → PoolManager may call the callback but treat its returned delta as zero.
For example, if the afterSwapReturnDelta bit is missing, your hook might record a fee even though the PoolManager ignored the returned delta.
Address bits do not make the hook’s behavior immutable. If a pool’s hook address points to a proxy, the permission bits stay fixed while an upgrade can change the code reached through that address. Review the upgrade admin, delay, storage layout, and implementation checks as part of the hook’s security boundary. Prefer immutable, versioned deployments when possible.
The fix: inherit from BaseHook and keep getHookPermissions() in sync with the callbacks and return deltas your hook actually uses. BaseHook validates that the deployed address bits match those declared permissions.
Real-world example: In the Sorella Angstrom finding, the hook returned a non-zero delta for the dynamic protocol fee, but hook-config.sol did not encode the afterSwapReturnDelta permission. The PoolManager wasn’t authorized to settle the delta, so every swap reverted with CurrencyNotSettled() once the fee was enabled.
6. Hook failures can block pool actions
Hook callbacks execute in the same transaction as the pool action. If reward distribution, dust cleanup, or other non-essential code reverts inside an afterRemoveLiquidity callback, users cannot exit their positions. The same applies to swaps when non-essential code reverts inside afterSwap. The PoolManager preserves atomic execution by reverting the parent action, so hook developers must keep optional logic from blocking core user flows.
Required external reads can cause the same denial of service. If a price feed rejects stale data, a lending protocol pauses, or another dependency reverts, the callback can revert the user’s swap or withdrawal. For each dependency, decide which paths must fail closed and which can degrade without blocking safe exits. Never silently use stale pricing data.
External calls are not the only source of failure. In our hook audits, we’ve seen happy-path accounting block withdrawals because of a zero balance, decimal mismatch, or missing reward token.
The fix: keep non-essential code out of the main user flow. Wrap optional external calls in try/catch, or move optional logic to a separate function users can call after exiting. For safety-critical dependencies, validate freshness and bounds, and provide an explicit exit-safe fallback when the design permits one.
7. State can change during a callback sequence
When enabled, beforeSwap and afterSwap run during the same swap, but values cached between them are not automatically safe. A hook can call external contracts, and one hook contract can serve many pools. Nested actions can therefore change shared hook storage, pool state, balances, or oracle data before the outer callback sequence finishes.
The fix: avoid shared scratch state. If data must cross callbacks, key it by PoolId and caller, reject overlapping operations while that state is live, and clear it after use. Apply checks-effects-interactions before external calls, and test nested swaps and liquidity changes across multiple pools that share the hook.
Building secure hooks
If you’re developing a v4 hook, verify these eight items:
Gate every callback and unlock path: Use BaseHook for hook entrypoints and SafeCallback for unlockCallback. Add equivalent caller checks only on uncovered paths.
Allowlist pools, not just tokens: Bind to specific PoolKey values or maintain strict allowlists.
Label every balance and delta: Document who owns it, who can move it, and which token behaviors the accounting supports.
Keep non-essential code away from the main user flow: Reward, oracle, and cleanup failures shouldn’t block safe exits.
Verify address permissions: Inherit from BaseHook and confirm that the address bits match your declared permissions. If the hook is upgradeable, review its proxy and upgrade controls separately.
Fuzz nested callbacks, fee extremes, malicious pools, and malicious or non-standard tokens: Use Echidna and Medusa to test adversarial scenarios, not just happy paths.
Isolate callback state: Key temporary data by PoolId and caller, reject overlapping operations, and clear it after use.
Auditing v4 hooks
If you’re reviewing a v4 hook, ask these seven questions:
Can an attacker call a callback directly? Check every external function for access control.
Can an attacker route logic through a malicious pool? Trace how PoolKey values are validated.
Who owns each balance and delta, and can a return delta or dynamic fee leak value? Test conservation, price bounds, and fee limits.
What happens if reward, cleanup, or oracle code reverts during removeLiquidity? Test failure paths and dependency outages.
Do the permission bits, implemented functions, returned values, and any proxy upgrade path all match? Verify the address flags and upgrade controls.
What breaks if the hook, token, or fee input is malicious? Assume adversarial counterparties.
Can state change between callbacks? Test nested actions across multiple pools that share the hook.
Security responsibilities for hook developers
The PoolManager enforces v4’s protocol-level guarantees, including pool mechanics and settlement. Hook developers secure the application-specific logic they add, including authorization, pool selection, value accounting, and external integrations.
Ask which assumptions the hook adds beyond the PoolManager’s guarantees. For operational guidance beyond code review, see Uniswap’s v4 Security Framework.
Codex’s /goal feature amplifies bug hunting, but getting good results requires the right prompt, the right scope, and the right number of outcomes per run. For Patch the Planet, our joint initiative with OpenAI to find and fix bugs in open-source software, we pointed Codex at some of the most widely used, heavily audited codebases in the world, like Rust, curl, and zlib. One tool came up again and again in our internal bug-report channels: /goal, which hands Codex an open-ended objective and lets it work independently toward a success condition. Here are a few highlights:
/goal found every Rust bug we submitted, including a soundness hole and a miscompilation now patched in Rust 1.98, from a single variant-analysis pipeline.
It turned every project’s past CVEs into Semgrep rules that had to fire on the vulnerable version and stay silent on the patched one, then flagged 11 variant hits across multiple projects.
It uncovered two potential high-severity privilege-escalation bugs in Keycloak’s SAML component during a discovery run.
Over the first few weeks of Patch the Planet, our engineers independently converged on three techniques for using /goal. We found that getting the most out of /goal means treating the prompt as a set of specific success criteria, not a set of instructions. (Note that this blog post uses /goal to refer to goal-based prompting in general. Codex can also set goals for itself through a tool call, and that’s how we recommend everyone use it; we rarely type the slash command ourselves.)
1. Let Codex write the goal
The art of using /goal is prompt design, and we found that Codex knows Codex the best. Internally, our single most repeated /goal tip was to use Codex to help write each /goal prompt. We hand Codex threat model files and the context about what we’re looking for, and then tell it to write the goal prompt. As mentioned before, /goal is a tool Codex can invoke on itself, and a few engineers stopped typing goals by hand entirely.
$goal-prompt based on threat model write goal to find single critical issue (RCE) exploitable by remote attacker for kubernetes-client. the kubernetes-client is used in normal config, malicious remote users exploits.
Figure 1: A meta-prompt from one of our engineers asking Codex to create a goal prompt. Results are shown in figure 2.
This works because Codex knows the target and its own tendencies better than we can specify up front. It can translate a threat model into concrete, testable success criteria, name the code paths worth prioritizing, and phrase the outcome precisely enough that a run actually converges. A goal written this way tends to be tighter than one we’d write cold, and it takes a fraction of the time.
Letting the model draft the goal also closes a gap we’d otherwise miss. Any outcome you define can be satisfied in ways you didn’t intend, and the model is often the first to spot where the easy outs are.
Now when we ask Codex to draft a goal, we ask it to red-team its own goal by identifying the ways a future model might be lazy in its approach, and to revise the criteria to remove them before the run starts. We also built tooling that makes it easier for Codex to verify its own work. For example, we noticed Codex has a tendency to skip reading the entire codebase even when explicitly asked. We built agentcov, a tool that tracks what lines of code Codex has actually read, so it can’t “cheat.”
This is an iterative process. As we find more shortcuts a model takes, we exclude them from the next version of the prompt.
2. Define the outcome, not the path
A good goal names the outcome, defines it precisely, and then enforces persistence:
/goal Audit the kubernetes-client repository in this workspace to find exactly one previously unreported critical remote code execution vulnerability reachable in normal/default client configuration by a malicious remote user or server that controls only network/API responses, Kubernetes objects the client legitimately fetches, or other remote data accepted during normal use.
First build a concise threat model of realistic remote attacker entry points and trust boundaries, then prioritize code paths involving deserialization, YAML/JSON/protobuf parsing, dynamic imports/eval/template execution, archive/file extraction, auth redirects, generated client hooks, websocket/exec/attach/port-forward streams, and subprocess or filesystem effects. Do not assume attacker control of local kubeconfig, CLI arguments, environment variables, installed plugins, source code, credentials, privileged cluster/admin access, or prior code execution; explicitly reject findings that rely on those preconditions. Before accepting a candidate, search local known-findings files plus current open issues/PRs for duplicates, then produce a minimal safe proof that demonstrates attacker-controlled code execution or a direct RCE primitive under the stated normal configuration. Stop after one valid critical issue. Write finding to ./findings/ folder.
Figure 2: The prompt created by Codex from figure 1
We found the best philosophy is to spend as many tokens as you need defining the outcome, and almost none telling the model how to get there.
If you want the bug found through fuzzing, “use fuzzing” is as far as you should go. “Build on top of my existing fuzzing harness” or “build a new fuzzing harness” are both worse. There might be an existing harness that’s just as good. A goal that prescribes the path guarantees Codex never takes another one, and you lose the judgment and open-ended problem solving that make /goal unique.
The outcome side takes more care because it has to be calibrated. If it’s too specific, Codex doesn’t have enough to search and the value of an autonomous /goal run is unclear. When we fed Codex the exact root cause of a known bug and asked it to find variants, it found nothing. The scope was too narrow. When we cut the input down to a single sentence describing the class of bugs it should look for based on the known bug, it surfaced numerous bugs. We reported 9 of them, with 3 already fixed and merged upstream.
If an outcome is too vague, the model provides outputs that don’t match what you were looking for. One of the worst /goal prompts we saw during Patch the Planet was “find bugs in [X].” The model had no way to tell when it was done. It just kept running, surfacing bugs that had no real-world impact, and wasting tokens.
A complete outcome definition also says what doesn’t count as done. The open-source projects in Patch the Planet have some of the most audited code in the world, and more than once /goal came back with “no bugs found.” We treat that as an intermediate result, not a completion condition, and write persistence into the goal itself.
The most effective resource for /goal bug hunting is a THREAT_MODEL.md file. We ended up referencing a threat model file in almost every goal we ran because it precisely defines what valid bugs look like without explaining how to find them. We recommend every open-source project create one.
3. Assign one outcome per agent
Putting two competing outcomes in one /goal prompt results in uneven optimization. We ran into this repeatedly when a goal asked for both bugs and coverage. When we put “find bugs” and “achieve high coverage” in the same prompt, the run ended up doing one of them far better than the other.
This was our experience while using /goal to audit zlib. Codex kept gravitating to the same part of the codebase, fuzzing the areas the model found first without reaching the rest. Our initial instinct was to fix that in the prompt by adding coverage requirements, but Codex then switched its optimization to coverage, and we saw lackluster vulnerability hunting.
What worked instead was moving coverage out of the prompt entirely. We asked Codex to first identify the five most promising attack surfaces after scouring through the entire codebase. Then we created a separate /goal session to find bugs in each section. We also added one fully open-ended session alongside them to roam the parts of the codebase the other agents weren’t assigned. This approach worked drastically better.
Figure 3: Rust maintainers assumed we had a team of engineers working on finding bugs. It was just one engineer with a strong handle on Codex's /goal.
One of our engineers, Kevin Valerio, created an automated variant-analysis system for the Rust compiler leveraging /goal. Every Rust bug we submitted through Patch the Planet came out of it.
P-critical is a label created by Rust maintainers to identify bugs that should be prioritized to patch and merge. The pipeline began by downloading every issue tagged P-critical in the rust-lang/rust repository as JSON.
An orchestrator reads the issues and spawns a separate agent for each one. One outcome per agent: instead of a single session told to perform variant-analysis on each bug, the orchestrator creates one Codex session per issue, each running an independent task to find a single outcome.
Each session runs in Goal mode with a deliberately small prompt to find a security issue with the same root cause as the original bug in P-critical. It receives a one-sentence description of the risk rather than an exact root cause with a full backtrace, so the model can still have the freedom to explore the codebase more.
Before any variant hunt begins, a security gate asks whether the source issue is even a real vulnerability and routes it to skip, no_variant, or bug_found. We are using that to focus on the most impactful P-critical bugs.
Every candidate runs a two-pass false-positive gauntlet. The first judge checks that the bug poses a genuine security risk. The second, a different model entirely, runs a PoC-focused pass and demands that the issue can potentially cause security issues relevant to the Rust threat model. A candidate reaches “validated finding” only if both passes agree.
Validated findings pass one last human filter. A duplicate check happens before anything is opened. Only bugs that are confirmed upstream and not already found in GitHub’s issue backlog are drafted for submission.
Figure 4: The full workflow Kevin Valerio used to find every bug in Rust
Where human judgment is needed
Since its release, /goal has been a powerful tool for amplifying the bug-hunting work that we do. Codex can create custom security infrastructure that takes a security researcher weeks to build in under a day. It can scour thousands of lines of code faster than any human can.
/goal will faithfully pursue whatever outcome we give the model, which means the run is mostly decided before the model starts. But its effectiveness still depends on an expert knowing where to look, verifying its results count as a reportable finding, and knowing what the maintainers on the other side actually want to see as a valid vulnerability disclosure. Prompt engineering is a large part of it, but you can only write a good prompt if you know exactly what you’re looking for.
We’ve added a new chapter to our Testing Handbook: a comprehensive guide to security testing Rust programs. This chapter covers the tools and techniques we use at Trail of Bits to validate the security of Rust programs and systems.
The chapter starts with a security overview of what Rust’s guarantees do and don’t cover, including underappreciated issues like unwind safety, nondeterminism, and arithmetic errors. This leads into an overview of dynamic analysis, which covers a range of boosters for unit tests, how to use Miri to detect undefined behavior, property testing with proptest, coverage measurement, and mutation testing. The static analysis section then covers Clippy in depth, including a list of our favorite lints.
Beyond tooling, the chapter also covers what we’ve learned from auditing Rust codebases directly. Our gotchas and footguns checklist is a great reference for manual code reviews, and will help you find subtle issues like a & b == c having different operator precedence than in C. The memory zeroization section offers three solutions to the tricky problem of guaranteeing that secrets are erased from memory.
Finally, the specialized testing sections cover tools like Kani (a model checker), and the supply chain section covers the full toolchain for vetting dependencies.
Still oxidizing
We’ve also released rust-review, a Claude Code plugin for automated Rust security reviews. Co-built with Aptos Labs, it targets over a dozen bug classes, from memory safety and concurrency hazards to FFI pitfalls and async cancellation issues. It’s a fast way to catch security issues in a Rust codebase before they make it to audit.
Our goal is to keep the handbook current as the Rust ecosystem evolves. If your favorite tool or gotcha isn’t covered, submit a PR. And if you need help securing your Rust systems, contact us.
In April we released Mewt, our open-source mutation-testing engine that finds the gaps in your test suite. Today we’re expanding it with support for DAML, the language Canton Network applications are written in. Mewt now reads DAML, generates several classes of mutants (including two built for DAML’s authorization primitives), and runs them through your existing test suite to count how many mutants survive. If you want to try it, simply install Mewt from the repository, point a mewt.toml at your project and its test command, and use mewt run.
For a team shipping DAML to production, that count is what a passing test run is actually worth: it puts a number on how much your suite checks, whereas a green run on its own does not.
Why DAML’s coverage reports lie
Test coverage is the most reassuring lie in smart-contract development. Hitting 100% line coverage tells you the test runner walked the code; it does not tell you whether any test would fail if that code stopped doing what it is supposed to. We have been grading test harnesses by how many mutants they kill since at least 2019, and our primer on finding the bugs your tests don’t catch shows how a green suite can still miss the bug that matters.
DAML’s built-in coverage measures execution at the template and choice level: which templates were created and which choices were exercised over the test run. It reports whether each choice was exercised, not what happened inside it. A test that exercises a choice once and asserts nothing about the result reports that choice as covered. The report prints the same green percentage whether the test verifies the outcome or discards it.
How mutation testing works
Instead of asking whether your tests reached the code, mutation testing grades your tests by sabotaging that code. The engine generates mutants, copies of the code that each carry one small deliberate change: a flipped comparison, a removed branch, a dropped party. It then runs your test suite against each one. A mutant that makes the suite fail is caught; a mutant that passes every test survives. Every survivor is a change your tests let through, and each one is either harmless or a potential bug. The harmless ones are equivalent code no test could distinguish or a branch no execution reaches, and you can set those aside. The rest are a to-do list: each one is a specific test you are missing, a case your suite should check but does not, occasionally with a real bug sitting behind the gap. The primer above describes a real audit where a mutation campaign surfaced a high-severity bug that the project’s tests had missed.
Mutation testing forces the unhappy path
A DAML contract encodes rights and obligations between named parties: who holds what, who owes what to whom, and who must authorize each step. A party is not an anonymous address. It represents a real organization or person, and the contract is the rulebook for how those parties interact, including which of them can take which action, what each is allowed to see, and what stays private between them.
Authorization is how that rulebook is enforced: who may take which action. It is also easy to get wrong in ordinary ways, such as a typo in a controller clause, a missing party, an extra one left over from a refactor. Every combination type-checks, so nothing rejects it before it ships. A static analyzer can flag suspicious patterns, but it has no way to know which party should hold which authority on your contract. That knowledge lives in your specification, and for most projects, the only executable form of the specification is the test suite. Happy-path tests supply every signature the contract asks for and confirm the transaction succeeds. They never try the negative case—removing a required signature and checking that the ledger rejects the transaction—so they never actually test whether that signature was required at all. If the tests don’t encode that rule, nothing downstream can recover it. Mutation testing is what tells you whether they do.
A green test run tells you your tests passed today. Mutation testing asks the harder question: would your tests catch a mistake, now or after the next code change? Where the answer is no, you have found a test case worth writing.
What Mewt adds for DAML
Mewt parses every language it supports with a tree-sitter grammar. As of mid-2026, there is no maintained tree-sitter grammar for DAML, so we reused the upstream tree-sitter-haskell grammar. DAML is Haskell-shaped, but its contract constructs (template, choice, controller, and signatory) are not Haskell, and the grammar parses them as error-recovered subtrees. That matters less than it sounds. The common mutations still work on DAML’s ordinary expressions, so Mewt swaps arithmetic and comparison operators, flips Booleans, and removes branches just as it does in any other language, with only small adjustments where DAML’s surface syntax differs (DAML writes /= where most languages write !=). We got most of the value of a from-scratch grammar without building one.
The new engineering went into DAML’s authorization primitives, where the authorization bugs from the previous section live. Mewt adds two DAML-specific mutations:
Controller party swap (CPS in Mewt’s output): replace one party in a controller clause with another party that is in scope at that site.
Controller party removal (CPR): drop one party from a multi-party controller list.
Both target the same question: if the set of parties allowed to exercise this choice silently changed, would any test fail? They are a deliberately small starting set aimed at the bug class above, and more DAML-specific mutations are in the pipeline.
Driving a campaign needs no new harness. A short mewt.toml names the files to mutate and the test command (dpm test for a Daml 3 project), and mewt run does the rest, reporting each mutant as caught or surviving. The setup is deliberately small: trying it on your own project costs minutes, and we encourage exactly that.
What a surviving mutant looks like
Picture a conditional payment between a buyer and a seller: the buyer sets money aside for the goods, and paying it out to the seller requires both parties to sign off. The buyer’s signature is the delivery confirmation. In DAML, that policy is one line: the controller line on the Release choice.
template ConditionalPayment
 with
 buyer : Party
 seller : Party
 amount : Decimal
 where
 signatory buyer
 observer seller

 choice Release : ()
 with
 paid : Decimal
 controller buyer, seller
 do
 assert (paid == amount)
Figure 1: A payment that requires both the buyer and the seller to approve its release
A typical happy-path test creates the payment and has both parties approve the release. The actAs buyer <> actAs seller line submits the command with both parties’ authority:
testHappyPath : Script ()
testHappyPath = script do
 buyer <- allocateParty "Buyer"
 seller <- allocateParty "Seller"
 payment <- submit buyer do
 createCmd ConditionalPayment with
 buyer
 seller
 amount = 100.0
 submit (actAs buyer <> actAs seller) do
 exerciseCmd payment Release with paid = 100.0
 pure ()
Figure 2: The happy-path test. It passes, and coverage reports 100%.
The test passes, and by the usual measure the suite looks complete: running dpm test with coverage reporting enabled shows full coverage.
$ dpm test --show-coverage --coverage-ignore-choice Archive
testHappyPath: ok, 0 active contracts, 2 transactions.
- Internal templates: 1 defined, 1 (100.0%) created
- Internal template choices: 1 defined, 1 (100.0%) exercised
Figure 3: The coverage report for the happy-path test. Every template is created and every choice is exercised, for 100% coverage.
The --coverage-ignore-choice Archive flag deserves a word. Every DAML template automatically gets an implicit Archive choice. It is not part of the business logic under test, so we exclude it for simplicity. With it included, this one-choice template would report 50% even though the test exercises everything we wrote.
Run Mewt on the project and it generates seven mutants. The test suite catches three of them. Four survive. Here is one of the survivors, shown as the diff Mewt reports:
 choice Release : ()
 with
 paid : Decimal
- controller buyer, seller
+ controller seller
 do
 assert (paid == amount)
Figure 4: The controller-removal mutant that survives the test suite
Re-run the test suite against this mutant. It still passes, and coverage still reports 100%. The contract claims releasing the buyer’s money requires both parties. The mutant lets the seller release it to themselves without the buyer ever confirming delivery. The tests report green either way. Only a test that tries the forbidden path, the seller acting alone, expecting the ledger to reject it, can tell the two contracts apart. No such test exists, and the mutation score says so. (The other three survivors tell the same story from different angles: the buyer-alone twin of this mutant, and two mutants that weaken the paid == amount check to <= and >=, which survive because the test only ever pays the exact amount.)
Step back, and this is the whole point of the exercise. Your tests are the executable specification of your code. Here the implementation changed, one required approval instead of two, and the specification did not react. That means the expected behavior was underspecified all along: whether both the buyer and the seller have to sign off, or just one of them, was never actually written down anywhere a machine could check. Every controller combination type-checks, and coverage reports 100% for all of them. The only place “both must sign” can exist in checkable form is a test that expects the weakened contract to fail, and writing that test is exactly what the surviving mutant tells you to do.
Limitations and what comes next
Mewt is not magic. Two limits are worth knowing before you run your first campaign: not every survivor is a real gap, and a campaign costs time. The roadmap that follows them is where we are taking the work next.
Equivalent mutants exist: some survivors turn out to be semantically identical to the original program, so no test could ever catch them. Few public DAML codebases on GitHub come with a full test suite, so we are glad OpenZeppelin open-sourced its canton-stablecoin reference implementation. Mewt generated hundreds of mutants for it. We ran the highest-priority ones through the existing test suite, and seven of those survived. Three were equivalent mutants or sat behind a guard that no path reaches, and the other four were genuine missing test cases. None of the survivors we reviewed pointed to a bug. Such a clean result is what you want when you run Mewt on your own code, and triaging them took minutes.
One of those equivalent mutants shows what that means concretely. A helper computed accrued debt:
accrueDebt currentDebt lastAccrual now annualRate =
 if currentDebt == 0.0 || annualRate == 0.0 then currentDebt
 else
 let elapsedYears = ... -- elapsed time as a fraction of a year
 in currentDebt * (1.0 + annualRate * elapsedYears)
Figure 5: The accrueDebt helper. Its first-line guard is a shortcut that returns the same value the calculation already produces.
Mewt forced the if to always take the else branch. No test failed, and none ever could: when the debt is zero, the formula multiplies by zero and returns zero, and when the rate is zero, it multiplies the debt by one and returns it unchanged. The guard is a shortcut that returns the value the formula already produces, so removing it changes nothing. Mewt suppresses the equivalent mutants it can detect. The rest need a reviewer’s judgment to dismiss.
Campaigns cost time in two places. The machine part: Mewt runs your test suite once per mutant, so the wall-clock cost is roughly the number of mutants times how long one test run takes, plus a rebuild if your project needs one. That is minutes on a small codebase and hours on a large one or a slow suite, so the cadence that works is nightly or weekly rather than per-commit. The human part: someone has to look at the survivors. We are working on that front from several directions at Trail of Bits, including our mutation-testing skill that helps configure campaigns for your project, and Trailmark with its genotoxic triage skill. None of these understand DAML yet, but the direction is clear: given the right harness and tools, the time-consuming parts of a campaign can be handed to AI agents. The effort is modest and the payoff is concrete: each genuine survivor is a specific test you can write, and every test you add makes your suite enforce one more guarantee your contracts are supposed to make.
Also on the roadmap: choice-consumption mutations (consuming vs nonconsuming) sit cleanly on top of the controller-mutation scaffolding and target a bug class Mewt does not yet reach.
Dive in
Install Mewt from the repository, point a mewt.toml at your project and its test command, and mewt run. The quickstart in the README covers the rest. DAML works out of the box. Everything here ran on Daml 3.4 with dpm, but Mewt just drives whatever test command you configure, so Daml 2 projects using the daml assistant work the same way.
Mutation testing complements the rest of your security stack, the type checkers, linters, and property tests you already run, rather than replacing any of it.
If you’re building on Canton, we help teams with security reviews of DAML applications and with the way the code gets built: working directly with your engineers on the development process itself. Contact us.
We’re running Patch the Planet, an ongoing collaboration with OpenAI that pairs Trail of Bits engineers directly with more than 30 open-source projects. Its goal is to front-run a serious problem facing open-source maintainers: highly capable models like GPT-5.5-Cyber will soon create a firehose of bug reports, and OSS maintainers are already spread thin. Our plan is to point OpenAI’s latest models at real codebases, find the security bugs first, work with maintainers to patch them, and find ways to decrease the burden on maintainers in the long run.
We’ll publish field reports like this one as the initiative progresses; follow along via the Patch the Planet tag.
The expertise barrier that kept bespoke fuzzing campaigns out of reach for most attackers is gone. We watched GPT-5.5-Cyber build in a single day what would have taken weeks for a skilled security researcher: harnesses across a dozen entrypoints, sanitizer and variant builds, seeds, and multiple findings currently undergoing coordinated disclosure.
This particular instance focused on zlib, a widely used data format and lossless data compression software library. We pointed GPT-5.5-Cyber at the library and drove it through Codex with the /goal command, asking it to find a specific class of bugs that are critically dangerous in compression libraries. We’ll publish the full harness and findings for inspection once the vulnerabilities are patched and a new release is cut.
The lab GPT-5.5-Cyber built in a day
We didn’t tell the model how to find these bugs. The obvious first move is to read the source code, but zlib has been reviewed so thoroughly that there’s little left to find that way. GPT-5.5-Cyber worked that out for itself, judged static review to be a poor use of tokens, and decided the higher value path was to build fuzz tooling to dynamically test the code. Earlier models given the same goal tend to read the code and flag whatever looks suspicious, ultimately leading to mediocre outcomes.
We believe the frontier 5.5-Cyber model combined with the /goal feature is what let it execute end-to-end without hand-holding. /goal forced the objective to live across multiple turns and compactions so the model held scope, and 5.5-Cyber was smart enough to reject weak findings, expand coverage when a line of investigation died, and keep running until it had workable proof-of-concepts backed by sanitizer output.
Over the next several hours, it built the campaign out one piece at a time:
It used ASan and UBSan builds so memory errors became observable.
It repurposed existing edge-case tests as guidance for the fuzz seed corpus.
It wrote C/C++ harnesses across a dozen entrypoints, including inflate, inflateBack, uncompress2, gzFile, MiniZip, puff, blast, infback9, gzjoin, gzappend, and several contrib stream wrappers.
It used compile-time variant builds (INFLATE_STRICT, BUILDFIXED, PKZIP_BUG_WORKAROUND, etc.) to reach code that the default zlib build hides.
Each of these decisions is routine on its own, but stringing them together in the right order across a dozen entrypoints, without being handed the steps, is a relatively large shift in how capable frontier models are.
While zlib already has fuzzing coverage from its OSS-Fuzz harness, GPT-5.5-Cyber went beyond the default harness shape, which passes random inputs to the gz* APIs. Instead of directly fuzzing the gz* APIs, its most successful harness found bugs in valid gz* states that could only be constructed by operating system backpressure.
Reporting discipline is the hard part
In general, models tend to struggle with deciding when a finding is severe enough to justify escalating it into reporting. Weaker models tend to escalate bugs that cause the program to crash, but are not reachable under real-world conditions. Early on, GPT-5.5-Cyber hit a null callback crash in inflateBack. The crash was real, but reaching it required a caller to set up a state that was extraordinarily unlikely in real-world conditions, so the model logged it as unreachable and moved on. This agent kept going without human intervention and found several higher-impact issues.
That discipline is the whole game. The value of the zlib harness came from automation plus a strict definition of what counted as a reportable finding. Without strong validity rules baked into the goal and a model truly capable of evaluating those rules, the agent will generate mountains of noise with high confidence: invalid uses of the public API, expected parser errors, internal API misuse, etc.
The moat is gone
Setting up a bespoke fuzzing campaign used to mean finding someone who could write harnesses, reason about valid API state, and differentiate between a bug and a crash that can’t happen in practice. This asymmetry kept casual attackers out of the game for most targets.
That moat is mostly gone now, and it shifts the threat model in two directions at the same time. For a skilled researcher, it is a force multiplier: the weeks-long tax on every new target drops to a day or less, so the same person can audit far more code. For a low-skill attacker, the floor rises: the tedious, expertise-heavy work of getting a harness off the ground can now be driven by starting a goal and supervising the loop.
For anyone shipping security-critical code, the practical takeaway is clear. Bespoke fuzzing is no longer a luxury reserved for projects with mature OSS-Fuzz coverage, and it is no longer expensive for the people whom you would rather not have running it. The defensive move is to do it first, with the validity rules that turn agent output into a high-signal source you can act on.
Lessons learned
The fuzzing lab answered the question we came in with and left us a much bigger one. We didn’t ask GPT-5.5-Cyber to build a fuzzing campaign; it decided that was the job and did it. The thing worth watching for now is what else these new models will reach for once you hand them a goal and step back, especially the approaches we would never have thought to ask for before.
That is also why the front-running work being done by Patch the Planet matters. Every new capability that helps us find bugs faster is just as available to an attacker, so the advantage goes to whoever finds the bugs and fixes them first.
Post-quantum cryptography is now one pip-install away for the entire Python ecosystem. With funding from the Sovereign Tech Agency, we implemented support for ML-KEM, the NIST-standard key-establishment primitive, and ML-DSA, the NIST-standard digital-signature primitive, in pyca/cryptography.
On June 22, 2026, the White House ordered the U.S. government to accelerate its transition to post-quantum cryptography. The order says large-scale quantum computers, especially in adversarial hands, will threaten widely used cryptographic systems, and that attackers may already be collecting encrypted data now so they can decrypt it later. It also sets concrete migration deadlines: high-value and high-impact federal systems must use post-quantum key establishment by December 31, 2030, and post-quantum digital signatures by December 31, 2031. And even if you don’t care about quantum resistance, that’s not a problem because quantum resistance isn’t the main benefit of post-quantum crypto.
That transition cannot happen only at the policy layer. Every application that signs packages, validates certificates, establishes secure channels, or protects long-lived secrets depends on cryptographic libraries. If those libraries do not expose post-quantum algorithms, the software stack cannot migrate.
Almost every Python program that touches cryptography goes through pyca/cryptography. It’s currently the eleventh most-downloaded package on PyPI, pulling 1.2 billion downloads in the last month alone. The pyca/cryptography package handles the cryptographic operations of projects like Ansible, Certbot (the Let’s Encrypt client), Apache Airflow, paramiko (the Python-only SSH client), and many others. If pyca/cryptography doesn’t ship post-quantum primitives, the Python ecosystem can’t begin to migrate.
Post-quantum support is now one pip install away
As of cryptography>=48, support for post quantum algorithms is just a pip install away. The version 48 release includes our Rust bindings for ML-KEM and ML-DSA, the cross binding API and tests, and support for AWS-LC as a cryptographic backend. It also includes work from pyca/cryptography’s maintainers to support the other cryptographic backends. Sadly, this is not enough for a post-quantum migration drop-in swap. These primitives have different size, performance, and integration tradeoffs than the classical algorithms they replace.
PQ algorithm tradeoffs
Post-quantum primitives keep the same security strength, but they change the size of the data on the wire. Public keys, signatures, and ciphertexts are often 1–2 orders of magnitude larger than the classical values they replace. The operations are also more complex and therefore slower, but on modern hardware they are still imperceptible for regular use, and are likely to get faster with improved hardware and algorithms.
For signatures, here’s how the classical primitive (Ed25519) compares to its post-quantum equivalent (ML-DSA-65):
Algorithm
Public key
Private key
Output
Ed25519
32 B
32 B
64 B sig
ML-DSA-65
1,952 B
32 B
3,309 B sig
And for key exchange and encryption, here’s how X25519 compares to its post-quantum equivalent (ML-KEM-768):
Algorithm
Public key
Private key
Output
X25519
32 B
32 B
32 B shared
ML-KEM-768
1,184 B
64 B
1,088 B ciphertext
If you maintain a protocol or wire format that hardcodes Ed25519-sized signatures or X25519-sized public keys, the post-quantum migration involves more than a primitive swap. The surrounding fields, length prefixes, and chunking assumptions need to grow with it.
Using ML-DSA (FIPS 204): Quantum-resistant signatures
ML-DSA is the lattice-based signature scheme that replaces RSA, ECDSA, and Ed25519. The Python API mirrors the existing asymmetric primitives:
fromcryptography.hazmat.primitives.asymmetricimportmldsaprivate_key=mldsa.MLDSA65PrivateKey.generate()public_key=private_key.public_key()signature=private_key.sign(b"message")public_key.verify(signature,b"message")# raises InvalidSignature on failure
Using ML-KEM (FIPS 203): Key encapsulation for the post-quantum era
ML-KEM is a key encapsulation mechanism (KEM) for establishing shared secrets. The construction is different, though. ML-KEM is a key encapsulation mechanism, not a Diffie-Hellman exchange. Instead of both parties combining key shares to derive a shared secret, one party encapsulates a fresh shared secret to the receiver’s public key, and the receiver decapsulates it with the matching private key. These operations allow both parties to exchange a secret but in a manner fundamentally different from Diffie-Hellman, and resistant to quantum factoring attacks.
fromcryptography.hazmat.primitives.asymmetricimportmlkem# Receiver generates a keypair and publishes the public key.private_key=mlkem.MLKEM768PrivateKey.generate()public_key=private_key.public_key()# Sender encapsulates a fresh shared secret to that public key.shared_secret_sender,ciphertext=public_key.encapsulate()# Receiver decapsulates the same shared secret from the ciphertext.shared_secret_receiver=private_key.decapsulate(ciphertext)assertshared_secret_sender==shared_secret_receiver
The road ahead: SLH-DSA and protocol integration
Two areas are still in progress: a third NIST standard, and the work of integrating these primitives into real protocols.
SLH-DSA
SLH-DSA (FIPS 205) is NIST’s hash-based digital signature standard. Like ML-DSA, it is meant to replace classical signature schemes such as RSA, ECDSA, and Ed25519. Its tradeoff is different: SLH-DSA has very large signatures and slow signing, but it relies only on the security properties of hash functions, which have been studied for decades. That makes it a conservative backstop if future cryptanalysis weakens lattice-based signatures. SLH-DSA is not supported in pyca/cryptography 48, but we’ve started working on it.
Post-quantum in protocols
Primitives are the foundation, but the post-quantum migration will be complete only when protocols use the post-quantum resistant algorithms. You’re unlikely to use PQ algorithms directly in tools like Certbot or Ansible until common protocols add support for them. While well-designed to replace existing implementations, algorithm changes require cautious development, testing, and auditing. We are actively working on helping maintainers integrate PQ algorithms into applications.
Acknowledgments
This work was funded by the Sovereign Tech Agency, whose mission is to support the open-source infrastructure that public digital systems depend on.
We’re also indebted to pyca/cryptography’s maintainers, Paul Kehrer and Alex Gaynor, who offered constant feedback and review throughout the development process, and continue to steward this critical piece of open-source software.
What happens when you clear dozens of Trail of Bits engineers’ schedules, pair them with every open-source maintainer they can contact, and unleash the latest frontier models like GPT-5.5-Cyber on critical open-source targets? Thanks to our partnership with OpenAI and its Daybreak initiative, we can report that the impact is hundreds of discovered bugs, 64 pull requests, and 51 issues filed across 19 projects (with many more still undergoing coordinated disclosure). That was just the first week of Patch the Planet.
Frontier models like GPT-5.5-Cyber are producing a firehose of security findings, and already-stretched maintainers must sift through all of it to separate real vulnerabilities from plausible-sounding false positives. Patch the Planet is different: with our experts orchestrating and triaging findings, we handle the work of fixing and hardening the code alongside the people who maintain it.
The first week of Patch the Planet covered 19 projects across cryptography, networking, language infrastructure, and software supply chain. Among these 19 projects were cURL, NATS, pyca, Sigstore, aiohttp, the Go project, freenginx, Python and python.org, urllib3, PyPI, SimpleX, Valkey, and RustCrypto. Over 30 projects have joined the initiative so far, and we’re rapidly expanding it to include more; if you maintain an open-source project, apply to join!
Live look at the Trail of Bits engineering teams
Anyone can file an issue, flex, and walk away. We showed up with the patches: 37 are already merged, and many more are in flight. These merges go beyond just fixing bugs: we’re adding new tests and fuzzing harnesses, CI security scanning, supply-chain tooling, correctness fixes, and features maintainers had been meaning to get to. The goal of Patch the Planet is to leave essential open-source projects measurably better off.
We brought patches, not just bug reports
We’re reporting public findings on GitHub, including 64 total pull requests. We also filed 51 issues, 19 of which are already closed with a fix. This public tally undercounts the work, since several projects take reports through private channels like HackerOne, GitHub security advisories, mailing lists, and private forks, and most of these have not been released publicly yet.
What’s in those pull requests matters more than the count. At python.org, we added a CI workflow built on zizmor, an open-source GitHub Actions static analyzer, fixed all of the issues it flagged, and integrated it into their CI. In RustCrypto, we contributed correctness fixes to the big-integer library that higher-level cryptography is built on, alongside genuine feature work in review: serde encoding support and HPKE DHKEM suite IDs. Other patches were plain engineering help: storage-accounting and service-restart fixes in SimpleX, a clearer admin-quarantine confirmation in PyPI’s Warehouse, and supply-chain improvements like SBOM sidecars for Python’s Windows artifacts. We will also be upstreaming many testing improvements and new testing campaigns. Arguably, our best contributions are not even bug or security fixes.
Keeping track of all of this is a bot we call Patchy. Patchy monitors every project, posts each new finding and merged patch to our Slack, and, for reasons we consider scientifically sound, reintroduces the common use of goblins, gremlins, and assorted creatures. Here’s Patchy’s description of an issue that has been patched:
Patchy’s description of an issue that has been patched
When a patch lands, Patchy celebrates with a triumphant PATCHY HAPPY. Making Patchy happy is really what drives us.
Bug patched, Patchy happy
A few highlights from the week
The week produced more than we can fit in this post, but here are some quick highlights.
A fuzzing lab built in a day. Given a narrow goal (find remotely exploitable bugs) and no instructions on how, GPT-5.5-Cyber decided that reading the source of one of the most-reviewed C libraries in existence was a poor use of tokens. Instead, it stood up a full fuzzing lab in under a day: sanitizer and variant builds, a seed corpus drawn from existing tests, and harnesses across a dozen entry points. Instead of simply fuzzing exposed APIs, it successfully built a harness that injected operating system backpressure to identify novel issues by reaching previously unexplored buggy states. We estimate all of that effort likely would’ve taken one of our fuzzing experts two to three weeks to do manually. Just as important, it showed judgment about what to test, what to report (and not report), and where to find higher-impact findings. We’ll publish the full details in a standalone field report.
A pipeline for variant testing historical CVEs built in a day. Codex was also adept at building simple but effective pipelines, such as the CVE variant analysis pipeline shown below. Codex’s /goal feature combined with frontier models like GPT-5.5-Cyber for this type of variant analysis produced novel issues with almost exclusively high-signal output.
Pipeline for historical CVE variant analysis
A release-pipeline improvement at python.org. We reported multiple security issues for python.org, including some issues closing a legacy-API authorization gap. But we’re most proud of the work that produced long-term improvements to python.org’s release infrastructure: the new zizmor CI scanning, tightened release-file and metadata validation, deletion scoping fixed so bulk operations can’t reach beyond their target, and release-tooling patches in review that quote remote command arguments, fail safely on partial uploads, and add SBOM sidecars.
The aiohttp maintainers fixed their issues almost immediately. We privately reported a cluster of issues across aiohttp’s client and server paths, including cookies that could regain broader scope after a save and reload, digest credentials that could answer a challenge from the wrong origin, and resource limits that ran after attacker-controlled buffering rather than before. The maintainers authored and merged all eight fixes within hours, seven of them inside a single five-hour window. We were impressed and appreciate the maintainers’ prompt and collaborative work on these issues!
Differentially testing major cryptographic libraries against each other. Many of our projects implement the same logic, protocols, and algorithms. In particular, multiple projects implement the same cryptographic algorithms and standards like X.509 certificates. Therefore, we used Codex to point these projects at each other, and identify any relevant behavioral differences. This proved to be a high-signal approach that uncovered several issues, including this AES-GCM issue in PyCA and several X.509 issues, which we plan to upstream to x509-limbo.
Finding the bugs is now the easy part
If it wasn’t already clear from the last several months of security news, this week makes one thing clear: the expensive part of security work has moved. Arming Codex with fuzzing campaigns, variant analysis, differential testing, agentic searching, and similar techniques produces real vulnerabilities and compresses weeks or months of manual effort into hours. The advantage is no longer in finding bugs, but everything after: confirming a finding, getting its severity right, writing a patch a maintainer will accept, hardening the surrounding code, making long-term improvements to prevent similar issues in the future, and coordinating a disclosure. That is the work that floods of AI-generated reports threaten to bury.
Guidance for maintainers
If you’re a maintainer managing an unsustainable number of AI-generated bug reports, the core challenges you need to solve are deduplication, false-positive filtering, and severity correction.
Deduplication is the easiest problem to solve technically. Even simple AI-based tools that compare new reports against open issues perform well, especially when grounded in affected code lines. Automating this step eliminates most of the noise.
False-positive filtering and severity correction are harder, but they can be managed. Without explicit guidance, models default to rating everything as critical.
Patchy without threat model and severity guidance
Generic approaches like our fp-check tool help, but only to a point. The best improvements require project-specific documentation, threat models, and severity criteria. PyCA’s security documentation, for example, was dramatically effective at reducing false positives in our bug candidates. Files like AGENTS.md that explicitly tell models which documentation to consult produced the most consistent and effective results. If security researchers are armed with this documentation, especially AGENTS.md for AI-based research, more noise will be filtered out before reaching the maintainers.
What’s next and how to get involved
This was just our first week. Over 30 projects have committed to join Patch the Planet, with a growing waitlist. As more findings clear coordinated disclosure, we’ll publish more results and deeper field reports, including full fuzzing lab details, the variant-analysis and differential-testing pipelines, and the tooling we’re building to help maintainers triage AI-generated reports themselves. Our Patch the Planet gist contains the full public list of our week one output.
What happens when the bits of an RSA private key are heavily biased toward 0 instead of being randomly generated? The public key’s bits could be biased enough for us to detect these incorrectly generated keys in the wild. Together with Hanno Böck of the badkeys project, we found hundreds of unique keys that not only have this property, but can be quickly factored. We also found the bug that led to many of these keys and analyzed historical data to track the issue over time. Surprisingly, the pattern of 0 bits is often highly structured, allowing us to develop a powerful polynomial-based cryptanalytic technique that exploits the pattern.
Figure 1: Two patterns of RSA moduli with repeated blocks of 0 bits seen in real-world examples.
These “short-sleeve” keys, named for how the 0 bits don’t fully cover the limbs of the big integers, largely fell into two patterns. Pattern 1 remains unexplained, but we traced pattern 2 to a type mismatch in big-integer code from old versions of the CompleteFTP file transfer software. The CompleteFTP bug also generated vulnerable short-sleeve DSA keys, and we recovered 603 unique RSA private keys and 74 DSA keys from internet scans. If you used CompleteFTP to generate host keys between December 2016 and December 2023, CompleteFTP has released a tool to check whether your keys need to be regenerated.
How we found the weak keys
The badkeys project is an open-source service that checks public keys for known vulnerabilities. While developing this tool, Hanno collected a massive number of real-world keys from public sources, including Certificate Transparency logs, internet-wide TLS and SSH scans, PGP keys, and many others. By searching this dataset for unexpectedly sparse RSA moduli, we uncovered a large number of keys in the wild with the patterns in Figure 1.
Both patterns include several regularly spaced blocks of all zeros interleaved with seemingly random data. Pattern 1 appears in CT logs for certificates issued to several large organizations, including Yahoo and Verizon, and on some devices running NetApp software. Fortunately, these certificates have already expired, but we still shared our findings with these companies. We wanted to learn more about which product could be responsible for generating these keys, but we did not hear back. Pattern 2 appears on SSH hosts running the CompleteFTP software from EnterpriseDT. The underlying vulnerability affects RSA keys generated using versions 10.0.0–12.0.0 (Dec 2016–Mar 2019) and DSA keys generated with v10.0.0–23.0.4 (Dec 2016–Dec 2023).
These vulnerabilities affect a small minority of hosts on the internet, but the more interesting takeaway is that independent cryptographic implementations failed in similar ways. More implementations may include the same bugs, and so it’s worth tailoring cryptanalytic algorithms for this particular type of failure.
Factoring with polynomials
Cryptographic algorithms often need integers hundreds or thousands of bits long, and they represent these “big integers” using an array of smaller machine-sized values, called limbs. If we interpret pattern 1 as a sequence of 128-bit limbs, or 32-bit limbs in pattern 2, the repeated blocks of zeros correspond to a single block of zeros in each limb. Only a small contiguous subset of the limb is filled with random bits, and the rest of the limb is uncovered, hence the nickname “short-sleeve keys.”
By exploiting this mathematical structure in the limbs of these moduli, we replace the hard problem of factoring integers with the easy problem of factoring polynomials. That is, we take the modulus $n$ with unknown factors $p$ and $q$, express it as a polynomial $f_n(x)$ with small coefficients, factor $f_n(x)$ into $f_p(x)$ and $f_q(x)$, and convert these factors into $p$ and $q$. The technique of converting between integers and polynomials is common, including doing fast polynomial multiplication, but sadly, few resources describe how to use it for fast integer factorization.
In particular, we use the digits in the base-$B$ representation of the integer to set the coefficients of the polynomial. In the normal base-10 representation, this involves replacing powers of 10 with powers of $x$, and then converting a polynomial back to an integer involves replacing powers of $x$ with powers of 10. Mathematically, the base-$B$ representation of an integer $a = \sum_i a_i B^i$ corresponds to the polynomial $f_a(x) = \sum_i a_i x^i$, and the polynomial evaluation $a = f_a(B)$ converts back to an integer. For short-sleeve keys, the base corresponds to the limb size, and the extra zero bits in each limb will lead to polynomials with exceptionally small coefficients.
Figure 2: Integers with blocks of 0 bits can be represented as polynomials with small coefficients.
This method of representing integers with polynomials is useful because the product of evaluations $f_a(B) * f_c(B)$ equals the evaluation of the product $(f_a*f_c)(B)$. All evaluation does is replace $x$ with $B$, so it doesn’t matter if this happens before or after multiplication. The same is true of addition.1
For a short-sleeve RSA modulus $n$ with $w$-bit limbs, we can use the base-$2^w$ representation to find a polynomial $f_n(x)$ with exceptionally small coefficients. If $f_p(x)$ and $f_q(x)$ also have exceptionally small coefficients, then $f_n(x) = f_p(x) * f_q(x)$. Note that for correctly generated prime factors, $f_p(x)$ and $f_q(x)$ will typically have $w$-bit coefficients; that’s why this attack doesn’t work in general.
Factoring polynomials is easy, so we can factor $f_n(x)$ to get $f_p(x)$ and $f_q(x)$, then evaluate these factors at $2^w$ to get $p$ and $q$. This is the basic version of the attack, but I’m intentionally omitting a key insight needed to factor these real-world moduli. A full explanation is at the end of this blog.
Figure 3: Special-form polynomials can be factored to reveal the RSA private key.
The correspondence between integers and polynomials makes it easy to factor these special form moduli, but interestingly, it helps factor general RSA moduli as well. The General Number Field Sieve (GNFS) algorithm has the best known asymptotic performance, and the first step is defining a number field by selecting a polynomial $f_n(x)$ and evaluation point $m$ such that $f_n(m) = n$.2
Reverse engineering the CompleteFTP vulnerability
After applying this technique to the keys that Hanno found, we found that the private factors are indeed short-sleeved: the prime factors have large, regularly spaced blocks of unset bits. The SSH banners for the hosts with the second pattern indicate they use the CompleteFTP software, so we reverse-engineered a trial version to determine what caused the vulnerable keys.
Dynamically generated RSA keys did not have the short-sleeve pattern3, so we used the ILSpy tool to decompile the .NET code in the demo binary. After some reverse engineering, we found the bug that generated the short-sleeve keys. The following function fills the big integer represented by bignumLimbs with a randomly generated value of the desired bit length. See if you can spot the problem.
publicvoidgenRandomBits(intbits){// Calculate the number of limbsintnumLimbs=bits/32;// Allocate space for the RNG outputbyte[]array=newbyte[numLimbs];// Call the system RNGrngProvider.GetNonZeroBytes(array);// Copy to the limbs of the big numberArray.Copy(array,0,bignumLimbs,0,numLimbs);// Set the top bit to ensure proper bit lengthbignumLimbs[numLimbs-1]|=0x80000000;// Store the lengthdataLength=numLimbs;}
Figure 4: Decompiled code for the vulnerable genRandomBits in CompleteFTP. Several branches have been removed for clarity, and comments are added.
There’s a mismatch between the size of the limbs and the size of the RNG output! Each limb requires 32 bits of random material, but Array.Copyimplicitly casts each 8-bit element of the RNG output to its own element of the big-integer limbs. The repeating structure in the short-sleeve keys is because the issue affects each limb, and the 0 bits are because too small of a value is copied to each limb. This exactly matches the pattern of the cryptanalyzed keys.
We also figured out why our dynamic testing did not generate broken keys: the genRandomBits function was compiled in but unreachable in the latest version. Older versions used custom-written key-generation code that called this vulnerable function, which was later refactored to use standard .NET crypto APIs.
We reverse-engineered an older version of the CompleteFTP software to look for other calls to genRandomBits and found that DSA key generation was also affected. The 160-bit DSA private key $x$ was previously generated by this function, and the public key and parameters include a generator $g$ and target $y = g^x$. The private key is easily recoverable, and once we knew what to look for, we found vulnerable DSA keys in the wild as well.4
Since v12.1.0, CompleteFTP generates RSA keys using .NET’s RSACryptoServiceProvider, and since v23.1.0, it generates DSA keys using the DSA.Create API.
How the vulnerability spread, and how it was contained
The decision to refactor key-generation code to use standard libraries significantly mitigated the scope of the impact. This is actually reflected in the data. Prof. Nadia Heninger has a large collection of historical and contemporary SSH scans that we used to find broken SSH RSA signatures, so I checked to see whether it included CompleteFTP hosts. There were typically hundreds of CompleteFTP hosts in each IPv4-wide scan, and after aligning the historical scans to the release history, the trend is clear.
Figure 5: Over time, fewer CompleteFTP hosts run the vulnerable software, but a significant fraction still use vulnerable keys.
Starting with the introduction of the RSA vulnerability in December 2016, there was a consistent increase in the number of hosts with vulnerable keys, and once the rewritten RSA code was released in March 2019, this trend immediately stopped. However, even though the number of hosts running an affected version has steadily decreased since then, the proportion of affected keys has plateaued, consistent with customers who regularly update their software but generate their keys only once.
The EnterpriseDT team was very responsive throughout disclosure. To help these users, EnterpriseDT released v26.1.0 of CompleteFTP on May 8, 2026; this update automatically checks if the system is using a vulnerable RSA or DSA key and alerts the user if the key needs to be regenerated. They also released a standalone tool that does the same. In addition, the badkeys website and standalone tool now support the detection of vulnerable short-sleeve RSA keys.
In total, we recovered private keys for 603 unique RSA public keys and 74 DSA keys generated by vulnerable versions of CompleteFTP, and 26 RSA keys with the unidentified short-sleeve pattern. Our data sources are heavily biased toward RSA SSH keys, so these numbers do not reflect the actual prevalence.
The search for more short-sleeve keys
Unfortunately, we do not have more information about short-sleeve pattern 1, nor do we know whether that vulnerability extends to other key types. It’s common for cryptanalytic algorithms to exploit knowledge of irregularly spaced blocks of known bits (including ECDSA5 and RSA6), but the regular spacing of short-sleeve leakage adds new structure, and there may be powerful variants of these algorithms that can exploit this property. If this type of leakage appears in two independent implementations of RSA, there are likely to be even more examples of short-sleeve keys out there.
In this instance, the impact of the vulnerabilities is fortunately limited, but it illustrates the power of practical research. The process of using known vulnerabilities to inspire more capable algorithms and using these algorithms to uncover new vulnerabilities generates a powerful feedback loop in cryptanalysis. It helps us understand how real cryptographic systems fail in practice, and it is only by observing how systems break that we learn how to make them more secure.
Acknowledgments
Thank you to Nadia Heninger for introducing me to Hanno and for letting me use the SSH scans for this project. Those scans consist of historical data from Censys and the University of Michigan provided by Zakir Durumeric and contemporary data and analysis scripts from Kevin He and George Sullivan.
Appendix
This final section is intended for those who want to implement the attack or write a proof that the attack works. I left out key details from the main post, but the following guided questions will help you close that gap. First, here are the full moduli for you to factorize. They are synthetically generated, but follow the same pattern as keys in the wild. The factors of $n_2$ were generated by calling genRandomBits(1024) in a loop until the result was prime.
If you compute $f_{n_2}(x)$ using $B=2^{32}$, some of the coefficients are large. Why is that? Is it true that all of the coefficients of $f_p(x)$ and $f_q(x)$ are small?
Is there a bit shift $p \ll i$ such that $f_{2^i p}(x)$ has small coefficients? This is the key trick needed to turn arbitrary short-sleeve values into polynomials with small coefficients.
If $f_{2^i p}(x)$ and $f_{2^j q}(x)$ have small coefficients, can you still compute $f_{2^i p}(x)*f_{2^j q}(x)$ from public information? Can you still recover $p$ and $q$?
If this polynomial factorization technique worked for every $p$ and $q$, then RSA would be broken. Why is the short-sleeve property important, and why doesn’t this factorization method work in general? What are the limits?
The short-sleeve property allows us to construct the product $f_{2^i p}(x)*f_{2^j q}(x)$, but unless $f_{2^i p}(x)$ and $f_{2^j q}(x)$ are irreducible, factorization may split this into more than two terms. Prove that there is always an efficient way to recover $p$ and $q$ from the polynomial factorization.
In math terms, the evaluation map is a ring homomorphism. ↩︎
More accurately, modern factoring implementations use a generalization of this technique. They search for a pair of polynomials $f_0, f_1$ where $f_1$ is linear and $Resultant(f_0, f_1)$ is a small multiple of $n$. In the special case where $f_1$ is monic, then $Resultant(f_0, x - m) = n \Leftrightarrow f_0(m) = n$. ↩︎
CompleteFTP RSA key generation on Linux had a separate issue where the private exponent was set to 65537 and the public exponent was large. We disclosed, and this issue was fixed in v26.0.2. The Linux version of the tool offers different features and is less popular than Windows. According to license data from EnterpriseDT, they believe no production users are affected by this issue. Our scans corroborate this claim, as we found no keys in the wild with this property. ↩︎
Diffie-Hellman key exchange also used the vulnerable function, but with a 2048-bit exponent. This is not vulnerable, and we believe that DH key exchanges that used this function are still cryptographically secure. ↩︎

 Login