Today, in most countries around the world, virtually every reasonably large city is packed with video cameras. On the one hand, the idea, of course, is to “keep us safe”: to monitor security in the streets, improve road safety and enforce traffic rules, and so on. But there’s the other side of the coin — ubiquitous video surveillance creates both privacy risks and opportunities for unauthorized surveillance We’ve repeatedly posted on our blog about how to protect yourself from surveillance involving IP cameras.
There’s another problem, too: relying too heavily on video surveillance systems can also be dangerous. If your cameras aren’t adequately cyber-secure, attackers may be able to disable them remotely to be able to then enter physical areas supposedly protected by video surveillance without being detected. This issue is especially relevant to home and privately managed surveillance systems — large companies generally do a better job of securing their devices (although there are exceptions there as well).
Disabling or replacing a camera feed is an almost obligatory plot device in heist movies. But unfortunately, this isn’t just a screenwriter’s invention: our recent research uncovered a vulnerability that makes it possible to remotely disable IP cameras made by Intelbras — a popular camera manufacturer. Read on to learn what the problem is, and how to protect your surveillance systems; a detailed technical analysis of the vulnerability is available on our expert blog, Securelist.
When an update does more harm than good
A surveillance camera is essentially a fully-fledged mini-computer, and its firmware needs to be updated regularly. In this case, however, the vulnerability was hidden in the firmware update procedure itself.
Intelbras provides firmware update files on its official website. The firmware can be updated manually from an SD card, or over the local network via the web interface or mobile app. However, during a firmware update, the camera neither required (past tense; a patch has since been issued – see below) authentication nor validated the firmware file before starting the update. As a result, anyone connected to the same Wi-Fi network as the camera could send it an update request. When an update is initiated, the camera reboots, taking it offline for about a minute before it becomes available again. But if the requests are sent repeatedly in a loop, the camera can be kept offline indefinitely.
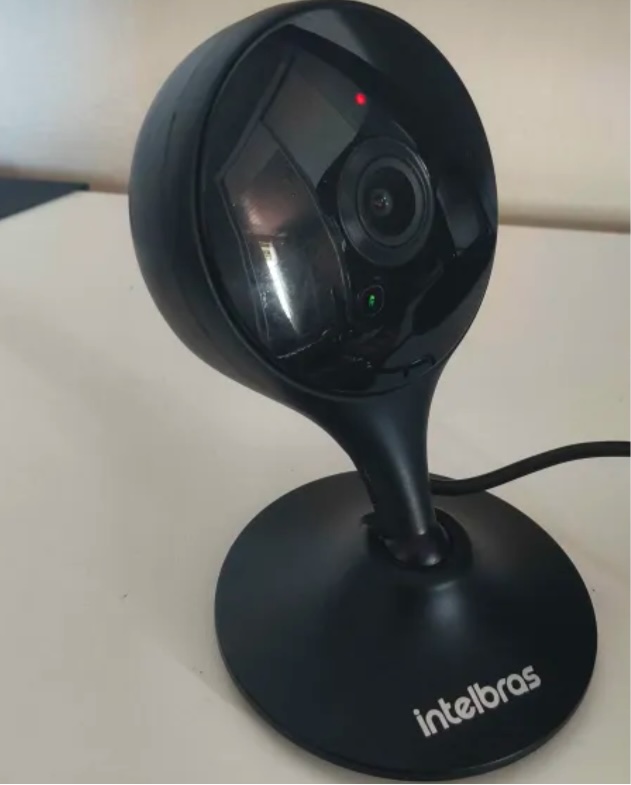
We investigated this vulnerability on an Intelbras iM3 C (iM3B-C) camera running firmware version v240927 — the latest available at the time of our research. The iM3 C is a smart Full-HD Wi-Fi camera designed for both home surveillance and as a baby monitor. According to Intelbras, the firmware for the iM3 C is also compatible with the iMX C, iM4 C, iM5 SC, iME 360 C, and iM7+ FC models.
Intelbras iM3 C smart Wi-Fi camera used for the investigation. Its firmware is also compatible with the iMX C, iM4 C, iM5 SC, iME 360 C, and iM7+ FC models. Source
This vulnerability has a medium severity rating. However, because of the large number of potentially affected users, the impact of successful exploitation could be significant. Intelbras Mibo Smart — Intelbras’s app for setting up and managing these camera models — has been downloaded more than four million times, with most of its users based in Brazil and elsewhere in Latin America.
How to secure your cameras and other smart devices
First and foremost, all Intelbras owners should update their camera firmware as soon as possible — and continue to do so regularly. More generally, it’s a good idea to secure your smart-home infrastructure in advance to reduce the risk posed by other potential vulnerabilities.
One of the simplest yet most important steps is to change the default settings on both your smart devices and your home network. Be sure to replace the factory-default passwords on all smart devices and on your router — default username/password combinations such as admin/admin or root/admin provide no meaningful protection.
Protect your home Wi-Fi with a strong password; otherwise, attackers could easily gain access to your local network.
Disable WPS on your router. WPS is designed to simplify network setup and authentication: you can connect by pressing dedicated buttons on the router and respective device, or by entering an eight-digit PIN. The problem is that this PIN can be brute-forced relatively easily, allowing an attacker to recover the key to your Wi-Fi network fairly quickly.
Use a strong, unique password for every account that can be used to manage your smart devices through official apps or websites. Where possible, enable two-factor authentication (2FA); the most secure option is generally to use one-time codes generated by authenticator apps. For generating and storing passwords, as well as creating one-time codes, it’s most convenient to use a password manager.
Put your IP cameras and other smart devices on a separate Wi-Fi network — isolating them from phones, laptops, tablets, NAS devices, and so on. Most modern routers can create at least two Wi-Fi networks (a primary and a guest network). Use the guest network for smart-home devices, but make sure it’s protected with a strong password. If your router supports multiple Wi-Fi networks, consider putting the cameras on a dedicated network of their own. That way, even if the cameras are compromised, attackers won’t be able to reach your other devices.
Use Smart Home Monitor, available in Kaspersky Plus and Kaspersky Premium. This feature shows all devices connected to your home network, lets you check their security status, and alerts you if an unknown device joins your home Wi-Fi.
More camera-security and smart-device tips and stories:
Picture your computer keeping a diary — the kind kids used to keep logging their daily activities, or the kind travelers, merchants, and nobles kept centuries before that. Here’s what it might look like.
Thursday, September 10.
8:00 AM. User read the news on cnn.com and bbc.co.uk (Safari).
8:10 AM. User replied to John Kaufman’s email about delivery dates, then sent the same question to the logistics team (Gmail).
8:20 AM. User checked his to-do list, reviewed recent updates, and planned out the day’s priorities (Todo).
We’re not exaggerating. This is exactly what your Mac’s new diary looks like. It’s a set of text files that any app on your computer can read — as can anyone sitting at the keyboard. The feature responsible is called Computer History, and it was released by OpenAI in mid-August. At the moment, it only works in the ChatGPT app for Mac, requires a Pro subscription or higher, and is disabled by default. According to its developers, the idea behind History is to let the AI assistant quickly get up to speed on your work context, so it can answer even vague requests, like “send a reminder to whoever I was emailing about last week’s deliveries”. Of course, that convenience comes at a price, ranging from your data being processed on OpenAI’s servers, to the risk of it leaking off your Mac — whether to a nosy family member or straight into the hands of cybercriminals.
How ChatGPT Computer History works
If this sounds a lot like Microsoft’s similar Recall feature, or Chronicle, which OpenAI itself announced earlier, that’s no coincidence. Both were built with the same goal in mind, just using different methods. Having watched Recall turn into the PR disaster it was, the team behind Computer History decided against constantly taking and analyzing screenshots. Instead, ChatGPT relies on macOS’s Accessibility features to read the text on your screen and track your actions: mouse clicks, text typed into fields, switching between apps, and the like. All of this gets stored as a stream of raw activity data inside the ChatGPT container (app group), which only the ChatGPT app itself, or other apps you’ve specifically given permission, can access. In tests run by digital forensics researchers, just two hours of normal computer use generated around 3500 of these logged events.
That raw data remains on your computer for up to 48 hours. During this time, the ChatGPT app periodically runs hidden chat sessions behind the scenes, where it asks the AI to summarize related events into a single recap. Essentially diary entries, these summaries get saved as plain text files in a folder that any app on your Mac can open: ~/.codex/memories/extensions/skysight/.
When you chat with the assistant, or when certain automated features kick in, these notes can be pulled into the conversation for more context-aware responses. OpenAI is especially keen on pointing out that the assistant can spot patterns in your workflows and offer to automate them, creating what it calls “skills” that replicate your actions for you.
Once a summary is ready, the raw activity data behind it is deleted. OpenAI says it won’t keep those hidden background chats or use them to train its AI, except where required by law. The diary-style summaries that get pulled into your conversations, though, are stored on OpenAI’s servers under the exact same rules as your regular chats and the assistant’s memory, so your preexisting privacy settings will apply to them too.
What Computer History can see, and what you can turn off
Since the whole feature runs on accessibility tools, ChatGPT only picks up what your operating system is already willing to share with those tools. That includes window titles, blocks of text, image captions in your browser, text you’re typing into a field as you type it, and the names of interface elements you click on. Watching a video? The AI can’t see the video itself, but it can read the window title, the site name, and the video description. Browsing photos? It sees file and folder names, not the actual images. Audio is never recorded or saved in any situation. All that gets logged from a video call is the meeting window title, unless the call itself has live captions turned on. Password fields that are masked (shown as dots) aren’t read at all and, according to OpenAI, private browsing windows are never scanned.
One thing that sets this apart from Microsoft Recall is the clearly spelled out step-by-step procedure the user needs to go through to turn it on. Computer History never activates itself. You have to navigate to the settings menu, then Integrations → Computer History and turn it on manually after reading through the warnings and explanations. You’ll also need access to the agent’s memory enabled for the feature to work. From there, you choose which apps and websites you want it to track, and confirm a series of macOS permission prompts.
For companies using a business subscription, this requires approval at two levels: an administrator first has to enable Computer History for the whole organization, and then each employee has to turn it on individually.
At any point, you can go to Computer History → Permissions and either list specific apps and sites to exclude from tracking, or, conversely, set ChatGPT to only watch a limited list you choose (Include only these apps, Include only these websites).
To see what your own computer’s diary looks like, check Computer History → History. From there, you can delete individual entries or disable the tracking of specific apps directly from the list.
The risks of using ChatGPT Computer History
We covered the risks of centralized storage of someone’s entire activity in our earlier piece on Microsoft Recall, and most of what we said there applies to ChatGPT Computer History.
You might assume your chats and emails are private, protected by passwords and encryption. But a copy of the most important parts of those conversations is sitting in plain text files that anyone with access to your computer, and plenty of other apps, can open.
The people you’re messaging have no idea this extra copy exists. If they’ve turned on, say, a self-destructing chat feature, but the messaging app’s window itself isn’t marked as private, that precaution does nothing to protect them.
Even if you trust OpenAI completely and take its privacy promises at face value, your data can still be stolen directly off your computer by an infostealer. Mac-targeting infostealers have exploded over the past two years, so this isn’t a hypothetical risk. And the people who write this type of malware move fast, quickly updating it to grab whatever new type of data looks promising. OpenAI’s files are a boon for them: everything you’ve done, already summarized by AI into something easy to read. While there are no passwords or credit card numbers in there, the available details are likely enough to craft a convincing targeted urgent email from the boss.
And if a nosy coworker or family member gets their hands on your computer, reading through the diary of your work and life would take them all of five minutes.
Computer History: turn it off, or just configure it?
We’d recommend limiting or fully disabling Computer History if your work involves sensitive information. This especially applies to doctors, lawyers, and anyone else bound by professional confidentiality, or handling personal or medical data. The same goes for anyone living with an overly controlling family member, or working in an office with nosy coworkers.
If none of that applies to you and you’d like to try out how useful the AI’s search and auto-generated skills actually are, here’s how to set things up safely.
Lock down your Mac’s login. Turn off auto-login, and set your Mac to require a password immediately after the screensaver kicks in or it wakes from sleep. Use a strong password along with Touch ID, and make sure FileVault disk encryption is turned on.
Set up your exclusions. Manually add every messaging app you use for private conversations, along with any finance apps or sites, and anywhere else you keep sensitive information, to Computer History’s exclusion list.
Check in regularly. At least a couple of times a week, visit Computer History settings to see which apps and sites it’s been tracking. This helps you catch and remove any sources of private information you forgot to exclude earlier.
No matter how you configure Computer History, the two most common ways your data could end up in the wrong hands — on any Mac — are a macOS infostealer snatching it directly from your computer, and typing your information into a fake website. To guard against both, make sure you’re running full-featured security software on your Mac, such as Kaspersky Premium for macOS.
AI can create privacy risks you might never think to look for. You can read about more of them in our other posts:
Flock Safety’s cameras are automated license plate readers (ALPRs) designed to help police find stolen cars or wanted suspects.
A joint investigation by 404 Media and WIRED, based on data recovered from a physically removed Flock camera, found that its on-device software explicitly detects people as well as vehicles, bicycles, and license plates.
Separately, Washington DC’s police union says the Metropolitan Police Department used Flock data to track officers under Internal Affairs investigation without their knowledge.
Together, these reports illustrate a privacy problem: A network built to record the movements of vehicles can readily be used to follow almost anyone.
The latest reporting adds an important technical detail to that debate.
What Flock cameras collect
A group of hackers reportedly removed a Flock camera from a roadway, copied its storage, and recovered an encryption key stored on the device. That allowed them to unlock videos of thousands of vehicle detections despite Flock’s claim that its devices are protected by on-device encryption. Flock said it could not assess the claims without more detail.
The recovered camera files reportedly contained software models that detect people, even though public discussion of Flock has usually focused on cars and license plates. The researchers found no evidence that face-recognition features were actively used. Reassuring, but it should not be mistaken for a clean privacy bill of health.
Even without facial recognition, a system that records repeated sightings can potentially reveal sensitive patterns of movement, including where someone lives, works, worships, seeks healthcare, attends protests, visits family, or spends time with other people. When a person is matched to a vehicle, vehicle-based tracking can become person-based tracking in practice.
As an example of how widely the data can be shared, WIRED found that records from the city of Alpharetta, Georgia:
“were accessible to more than 2,000 agencies, including police departments, colleges, airports, and, inexplicably, the Office of Inspector General for the federal General Services Administration.”
Targeted tracking of people
The Washington DC dispute shows what happens when the power to follow people is turned inward.
The DC Police Union says it learned in July that MPD’s Internal Affairs investigators had used Flock license-plate-reader data to track sworn officers under investigation without their knowledge. The union filed a complaint and asked the department to stop, arguing that MPD lacked adequate controls for a system with such extensive surveillance capabilities.
MPD defended the use, saying its position is that the use of license-plate-reader data in the misconduct investigation was appropriate. It said the labor dispute is headed to arbitration.
If police officers themselves are concerned that the system can be used to monitor them without transparent rules, the public should ask an obvious follow-up question: What prevents the same tools from being used to follow residents, employees, journalists, activists, former partners, or other people with no meaningful ability to challenge the search?
The recovered camera software and the DC dispute make the same point from different directions. Flock’s network is not merely a collection of roadside plate readers. It is a distributed system for recording movement, identifying patterns, and making those records available for search.
Meaningful safeguards should include:
Public approval before cameras are deployed, with clear maps showing their locations and stated purposes.
Strict limits on collection, retention, searches, and cross-jurisdictional sharing.
A requirement for documented investigative justification before a search, with elevated approval for sensitive investigations.
Independently reviewable audit logs, regular public transparency reports, and meaningful penalties for misuse.
Clear bans on searches related to protected activity, immigration enforcement where local law forbids cooperation, abortion-related investigations, political surveillance, and personal purposes.
Independent security assessments covering the cameras, cloud services, identity controls, key management, and third-party integrations.
Automatic deletion that cannot be overridden merely because data could someday be useful.
Privacy cannot depend on authorized users always following rules, vendors configuring every setting correctly, or abuses being discovered the hard way. The first safeguard should be limiting the system’s ability to build a searchable record of ordinary people’s lives at all.
Browse like no one’s watching.
Malwarebytes Privacy VPN encrypts your connection and never logs what you do, so the next story you read doesn’t have to feel personal. Try it free →
In May 2026, we discovered a new cyber-espionage campaign by the Armored Likho group, also known as Eagle Werewolf, that targets private individuals and organizations across various industries in Russia, including major corporations, the public sector, IT, and education. The attackers used a fake app as bait that mimics a service for donations. However, the most interesting part of this campaign isn’t the initial infection method – it’s the malicious implants the attackers use for cyber-espionage.
We’ve written previously about recent Armored Likho attacks, but our analysis shows that the campaign discussed below has more in common with the group’s activity from February. That said, the attackers have significantly expanded their arsenal.
During our research, we found a new cyber-espionage toolkit written in Rust: the Still Toolkit. One of its components, Still Sync, steals Telegram session data to gain ongoing access to the victim’s account. With this stolen data, attackers can leverage the Telegram API to automatically pull chat logs, media files, and other information from the account.
The second component, Still Audio, is an implant for covert audio surveillance. It analyzes the incoming audio stream, automatically detects speech, records conversations, and sends the recordings to a command-and-control server.
In this article, we’ll look at the initial infection method, how the new Still Toolkit components are built, and the technical details of how they operate.
Kaspersky products detect this threat as Trojan.Win64.Agent.* and HEUR:Backdoor.Win32.Generic.
Background
Armored Likho’s malicious activity has been documented several times before: in November 2024, and in February and July 2026. The current campaign shows significant overlap with the November and February campaigns, which used malicious droppers disguised as documents and applications related to Starlink activation or fundraising efforts as the initial infection vector. This campaign also uses fundraising as its lure. At the same time, our research uncovered a number of new tools that point to the attackers expanding their capabilities.
Initial infection
The infection chain starts with an app that mimics a donation service. As of this writing, the app distribution method remains unknown. During our research, however, we obtained several samples posing as apps from different Russian foundations.
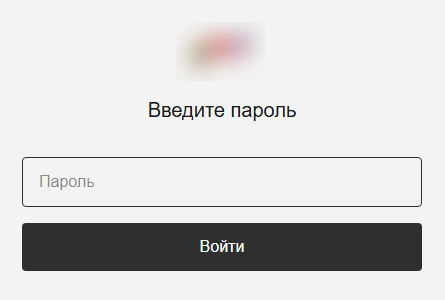
In reality, the app is a dropper. Its developers wrote it in Rust on top of the popular Tauri framework, and it has a graphical interface designed to deceive the user. After launch, it displays a login form that asks for a password, presumably one the attackers supplied.
The login form
After the user enters a valid password, they see a catalog of donatable items. The app pulls item and category information from orderapiserver[.]info through the public/categories and public/products endpoints. A clickable catalog makes the app look legitimate. While the user browses the items, the dropper quietly decrypts and launches the payload for the next stage in the background.
Our analysis shows that the mechanism for decrypting the payload and launching subsequent stages hasn’t changed since the February campaign. However, we found a new cyber-espionage toolkit – the Still Toolkit – made up of two components: Still Sync and Still Audio.
Still Sync
Still Sync is a stealer written in Rust that steals Telegram session data. However, its capabilities don’t stop there. With this stolen data, Sync can log in to the victim’s account and pull messages and media files through the Telegram API.
Architecturally, Sync is an asynchronous application based on the Tokio library. It talks to the server over gRPC and serializes messages with FlatBuffers. It supports both HTTP and HTTPS as transport protocols; the URL of the command-and-control server determines which one it uses.
How it works
When Sync launches, the attackers set several environment variables. Before starting any malicious activity, the implant pulls configuration parameters from these:
STILL_SYNC_ADDR: the address of the command-and-control server. By default, this is https://tg4service[.]com:443.
STILL_SEND_PATH: the path to the tdata
STILL_TELEGRAM_PASSCODE: the password for decrypting the tdata folder, if Telegram data encryption is enabled on the victim’s device.
Sync also supports several command-line arguments:
--console: runs as a console application. If this parameter is absent, the implant creates a TReload service to keep running in the background.
--version: prints version information and exits.
--firefly: launches a trace thread that monitors the program’s operation. It writes error messages to a hidden file, bin, located in the same folder as the main executable.
--db: turns on debug mode with detailed logging.
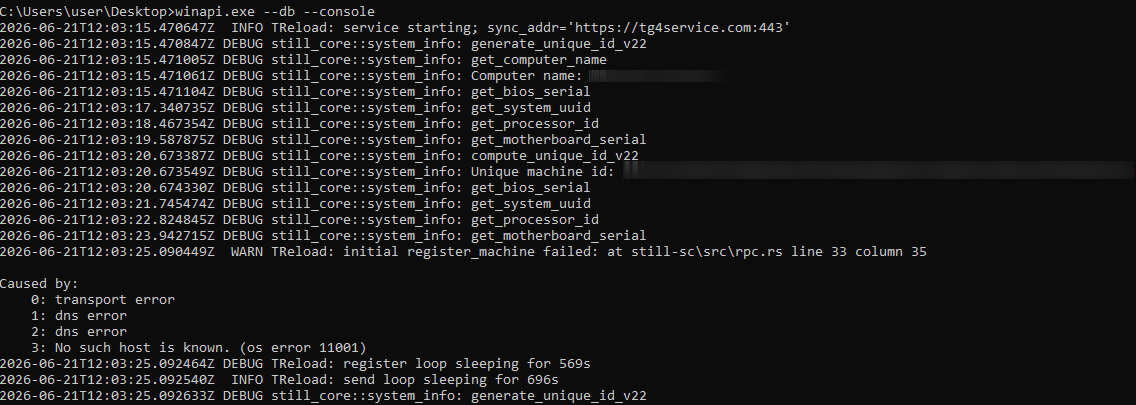
Example Still Sync logs
Once it launches, the malware begins registering the device with the C2 server. To do this, Sync collects the following information about the victim’s system:
Motherboard serial number
CPU ID
System UUID
BIOS serial number
Computer domain name
The malware combines the collected data into a single string with a colon as the separator. It then hashes that string with SHA-256 and stores the resulting hash under the key sysmarker. Worth noting: other Armored Likho tools, AquilaRAT included, use this same hashing algorithm.
Sync then serializes a package containing all the collected information and the agent version, and sends it in a POST request to /still.rpc.Sync/RegisterMachine. The response contains a machine_id value, which Sync uses to identify itself in subsequent requests.
Once registration succeeds, Sync sends a POST request with the machine_id parameter to /still.rpc.Sync/GetMachineSettings. The server responds with the following settings:
enabled: triggers malicious activity on the infected device.
scan_portable: turns on extended scanning when searching for the tdata We’ll cover this feature in more detail below.
fetch_telegram: if this parameter is on, Sync attempts to log in to Telegram and extract data. We’ll cover this feature in more detail below.
download_channels: if this parameter is off, Sync skips channel dialogs when exfiltrating Telegram data.
These parameters have no default values, so Sync doesn’t perform any malicious actions until the registration and settings-retrieval processes both complete successfully.
Telegram data collection
Before stealing a Telegram session, Sync searches for the tdata folder, unless the STILL_SEND_PATH variable is already set. The list of search paths includes both standard and nonstandard directories, if the scan_portable option is turned on:
C:\Users\<username>\AppData\Roaming\Telegram Desktop\: the standard Telegram Desktop installation directory.
C:\Users\<username>\AppData\Local\Packages\<package_folder>\LocalCache\Roaming\: the installation directory for the Microsoft Store version. Sync identifies the package folder by a name that contains the string TelegramMessenge.
C:\: used for the extended search (if the scan_portable option is on).
Sync then sends a POST request with a list of files from the tdata folder to the /still.rpc.Sync/CheckFiles endpoint. The server responds with the following values:
snapshot_id: an identifier the server assigns to the current data snapshot.
present: a list of file paths that are already present on the server.
This lets the C2 server avoid re-receiving files it already has. In addition, if Sync can’t access files on disk through standard methods, it falls back on three mechanisms that abuse the SeBackupPrivilege privilege:
Opening files with the CreateFileW function using the FILE_FLAG_BACKUP_SEMANTICS parameter
Creating a backup copy through the Shadow Copy service and reading files from there
If the previous methods all fail, attempting to copy the file using the Robocopy utility in backup mode
Beyond stealing Telegram session data, Sync can carry out full-scale collection of user information from the messaging app. When the fetch_telegram option is on, it launches a separate thread that authenticates to the chat app using the previously obtained tdata. Once authentication succeeds, Sync gains access to the account data and sends the following collected information to the server:
User details, such as username, phone number, first and last name
Information about private chats, groups, or channels, such as chat name and ID, the member list, and so on
Dialogs from private chats, groups, and channels (if the download_channels option is on)
Media files under 250MB: photos, documents, stickers, and contacts
Still Audio
Still Audio is an audio surveillance implant written in Rust. Its main job is to analyze the incoming audio stream and start recording voice when certain conditions are met – we’ll cover those in the next section. Architecturally, Still Audio largely mirrors Sync and uses the same mechanisms for communicating with the C2 server.
On launch, Still Audio performs a sequence of actions:
It extracts libmp3lame.dll, a file stored inside the executable. This is a library used to encode audio data.
If the --console command-line argument is absent, the implant creates a service named auxhost, connects to it, and continues running in the background.
While running in the background, it creates a file, logfile.log, to write logs to.
Next, Still Audio retrieves the C2 server address. As with Sync, it stores the URL in an environment variable – in this case, STILL_AUDIO_SYNC_ADDR. If that variable isn’t set, it falls back to STILL_SYNC_ADDR, which shows the two modules are compatible with each other. If neither variable is set, it uses the default URL, https://srwinservice[.]com.
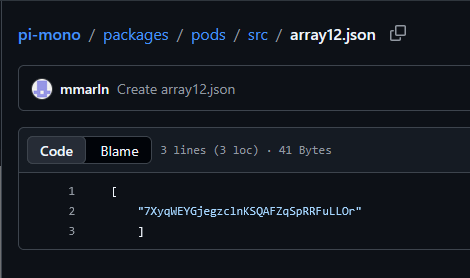
Still Audio also uses the Dead Drop Resolver technique as a fallback mechanism for obtaining the C2 address. If the current server stays unreachable for three days, the tool tries to pull the current C2 URL from a GitHub repository. In the sample under analysis, we found the following URL for the page containing C2 information: hxxps://raw.githubusercontent[.]com/mmarln/pi-mono/refs/heads/main/packages/pods/src/array12.json
Encrypted C2 address inside the GitHub repository
The repository, a fork of a popular project, contains the server URL Base64-encoded and encrypted with the Blowfish algorithm in ECB mode, using the key 5c8e153228edd3c6cbf75684 (lowercase string). Older AquilaRAT samples use this exact same algorithm and key.
Once it obtains the current C2 address, the Audio module starts a registration process similar to Sync’s, but through a different endpoint:
/still.rpc.Audio/RegisterAudioMachine. Also, unlike Sync, Audio sends a list of available audio input devices along with the system information.
The server responds with settings for the implant:
machine_id: a unique identifier for the current device.
vad_threshold: the threshold value for the VAD (Voice Activity Detection) algorithm. Expressed as a decimal fraction, it represents a proportion of the maximum sound level the input device can pick up. Sound above this threshold counts as voice activity. The default vad_threshold is 02.
max_silence_duration: the number of audio samples with a VAD value below the set threshold after which the implant considers the recording finished.
max_buffer_size: the maximum buffer size for recorded audio data.
active_device: the name of the input device selected for recording, from the list of available devices.
The eavesdropping process
Still Audio works with raw audio samples it captures directly from the input device. To detect voice activity, it implements an algorithm based on Root Mean Square (RMS), a lightweight signal-processing method that distinguishes speech from silence by measuring the audio signal’s average power over time. The implant doesn’t rely on any third-party libraries here; it implements all the calculations itself.
The implant compares the calculated RMS value against the vad_threshold parameter. If RMS meets or exceeds this threshold, recording starts. To avoid losing the beginning of the recording, Still Audio uses a pre-buffer, a size-limited buffer that stores samples from just before the current recording moment. A sequence of max_silence_duration samples (320 by default) with RMS values below the threshold signals the end of the recording. For example, with a standard headset running at a 44.1kHz sampling rate, recording stops after roughly 7ms of silence.
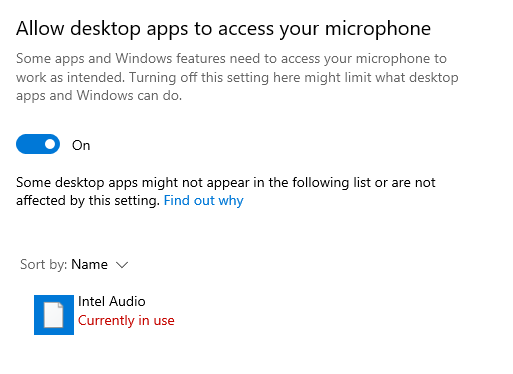
Interestingly, the Audio module makes no attempt to hide its use of the microphone: its name shows up in Windows settings. In the sample we examined, the file was saved to disk as IntAudio.exe, and it appeared in the list of apps using the microphone as “Intel Audio”:
The malicious module in the list of apps using the microphone
Before sending recordings to the server, the implant uses the libmp3lame library to encode the raw audio samples. It sends the recording files via a POST request to /tgfrg, adding a Client-Id header containing the machine_id obtained during registration to identify the device.
Infrastructure
This campaign draws on a broad set of hosting providers and domains registered at different points in time, which suggests the attackers are trying to make their infrastructure harder to detect. We found no direct overlap in domains or IP addresses with the February campaign. Even so, the two infrastructures share some similarities:
They use the same hosting providers, with the ASNs 149440, 202448, and 215311.
Their domain names follow similar naming patterns that mimic Windows system services and update mechanisms.
Domain
IP address
Registration date
ASN
orderapiserver[.]info
187.127.153[.]38
April 18, 2026
47583
tg4service[.]com
159.198.37[.]74
October 4, 2025
22612
srwinservice[.]com
213.252.244[.]123
March 19, 2026
61272
screenserv[.]com
23.26.237[.]250
February 13, 2026
149440
windowserv[.]net
23.27.24[.]30
February 10, 2026
149440
managementapiservice[.]com
188.212.124[.]178
May 1, 2026
202448
service8date[.]com
145.223.69[.]143
January 13, 2026
215311
updateservs[.]com
145.223.68[.]66
December 23, 2025
215311
Victims
In this campaign, we’ve determined that the attackers’ primary targets are users in Russia. Most victims are private individuals, though the corporate sector, government organizations, IT companies, and educational institutions are also affected.
Attribution
This campaign has been using both new tools and malware families documented in BI.ZONE’s February report. While some components turned up for the first time, they show significant code-level overlap with malicious tools seen in earlier Armored Likho campaigns. Based on these overlaps, along with additional technical artifacts, we’re highly confident the Armored Likho group is behind the campaign. The overlaps we identified include:
Identical dropper architecture in the February and current campaigns, which includes the use of the Tauri library to build the graphical interface, a similar user-input handler, a payload with the ICRYPTMP header, and the same multi-part encryption format.
The same encryption algorithm and key used in AquilaRAT from the previous campaign and in the Still Audio module from the current campaign, both implementing the Dead Drop Resolver technique.
Identical logic for generating the sysmarker value in older AquilaRAT samples and in the Still toolkit from the current campaign. The algorithms match down to the PowerShell commands used to collect system information.
Substantial infrastructure overlap, which includes the hosting providers and domain-naming patterns described in the Infrastructure section.
Takeaways
The campaign described in this post shows Armored Likho’s toolkit evolving, with the group steadily expanding its cyber-espionage capabilities. Beyond the components we already knew about, the attackers rolled out new modules that let them not only access Telegram data but also conduct audio surveillance on victims. Together, these capabilities significantly widen the range of information attackers can collect in a single compromise.
One point deserves particular attention: the new tools form a cohesive set, sharing similar architecture, C2 communication mechanisms, and common implementation elements. This points to the group building out its own tool ecosystem, designed for long-term use and further expansion.
The emergence of new, specialized modules shows the attackers aren’t just trying to preserve their existing capabilities – they’re working to make intelligence-gathering more effective by controlling multiple communication channels at once.
Virtually every website selling products or services features a live chat widget. It usually appears as a small window in the corner of your screen, complete with an agent’s name and picture.
Sometimes these chats simply collect tickets for tech support or sales to process. But often there’s a real person on the other end of the screen. And here’s where many users get an unwelcome surprise: agents can see absolutely everything you type into the chat box, even if you have no intention of sending it. In this article, we break down why this happens and what you can do about it.
All in the name of customer experience
It’s all thanks to a feature known as live typing preview, or real-time typing view, which exists under one name or another in almost every popular customer chat platform. Here’s how the developer of LiveAgent, a customer support system used by more than 40 000 companies, describes it in its blog: “This live chat typing preview allows agents to anticipate questions and deliver faster responses. Additionally, real-time chat monitoring enables supervisors to oversee chat interactions, ensuring quality and timeliness.”
While that might sound helpful and harmless to some, having their unsent messages watched without their permission can trigger outright panic for others. To make matters worse, it’s almost impossible to tell whether the website uses the feature. That is, unless the chat agent admits it to you directly… or replies to a message you decided not to send.
As an alternative, you can run a quick test: type out a message in the chat box, wait 15 seconds, and see if the agent starts typing a response. If they do, you’re almost certainly dealing with real-time typing view. Whether to continue that conversation is up to you. Most importantly, never type personal information into a chat box — even if you are doing so from a Kaspersky Premium device.
Real-time typing view is just the tip of the iceberg. In reality, websites collect far more information than you might think. You’re likely already familiar with cookies, and have probably asked yourself at least once, “Should I accept these or not?” We answer that and other questions in our post Taking the biscuit: why hackers like cookies so much.
Tracking techniques that use web beacons and tracking pixels are not as widely known. To learn why they’re a concern and how to turn them off, check out our post Who is tracking you on the web and how.
Another technology that remains largely unknown to the general public is session replay scripts. These tools allow website owners to watch a recording of your visit: how fast you moved your cursor, where you clicked, which pages you browsed, and what you added to your shopping cart.
Of course, the primary goal of session replay is the same as real-time typing view: improving customer and user experience. It helps companies analyze your behavior, identify friction points, and make improvements. If a customer fails to complete a checkout or encounters a technical issue, developers can review the recording of their session to pinpoint what went wrong.
In theory, it sounds helpful enough: “We will collect a small amount of data about you to make the site better for you.” In practice, however, this approach comes with significant risks for users.
What’s the catch?
The primary risk here lies in whether websites collect this data legally, how they store it, and whether they share it with anyone. While you can usually gauge legality by reading their privacy policy, the terms of data storage and sharing are often described vaguely.
On top of that, users rarely realize an agent can read their message before it’s actually sent. If you change your mind about asking a question, edit a sentence, or delete your text entirely, that doesn’t mean no one saw the draft. Unlike cookies, opting out of this technology is practically impossible. Most chat widgets simply don’t offer a setting to disable typing previews.
As for tracking pixels, web beacons, and session replays, they’re essentially a form of digital surveillance. Beyond collecting vast amounts of data, they can also slow down your device’s performance. Even worse, if attackers compromise a website’s analytics system, they can gain access to this data, reconstruct your path through the site, and uncover details that can be leveraged in future attacks. To learn more about how scammers pull off these tricks and how social engineering works, check out our post They’re reading you like a book: scammers’ favorite tricks.
While you can’t prevent a potential breach on a third-party website, you can — and should — take steps to secure your own browsing session.
What you can do about it
First and foremost, pay close attention to what you type in a chat box. It’s critical never to share personal data, credit card numbers, logins, passwords, or any other sensitive information with live chat agents.
Beyond that, there’s always a risk of landing on a phishing site and entering your account credentials there. To prevent this, we recommend using our security solutions, which block visits to malicious and suspicious websites. We also suggest storing your credentials in Kaspersky Password Manager — our password manager won’t let you auto-fill saved logins and passwords on a fake site.
Users of Kaspersky Standard, Kaspersky Plus, and Kaspersky Premium have access to our Private Browsing feature (on Windows and macOS). It prevents third-party services from tracking your online activity and collecting real-time information about what you do on websites.
To minimize the risk of data leaks, keep these tips in mind:
Never type anything into a chat box that you aren’t prepared to send. On almost every website, the agent can see your text while you type, so deleting a message is no guarantee it stays private.
Keep in mind that your activity on a website may be recorded. These recordings can capture your clicks, page navigation, and form inputs. Treat every website as if your actions are being watched.
Pay attention to privacy policies. Reputable companies typically state whether they use analytics tools, session recording, or third-party support services.
Approach chat interactions with caution. Real-life rules apply here as well: never share verification codes, passwords, phone numbers, or other sensitive details in a chat.
Be smart about accepting cookies. Taking a moment to check what information a website collects is well worth the effort — it helps you make an informed choice about whether you’re comfortable sharing that data.
Tired of endless digital tracking? Here’s how you can protect yourself and your data:

 Login